Share
Embed
Tree Based Classification Approaches
Techniques which are considered as panacea of all data science problems.
Mayank Mishra
March 25, 2018
Transcript
41 slides
-
Line - Up ➔ Prerequisites ➔ Ideation ➔ Theory ➔
Consolidation ➔ Cases Study ➔ Future Studies ➔ References -
Prerequisites What is this?? This is one of a type
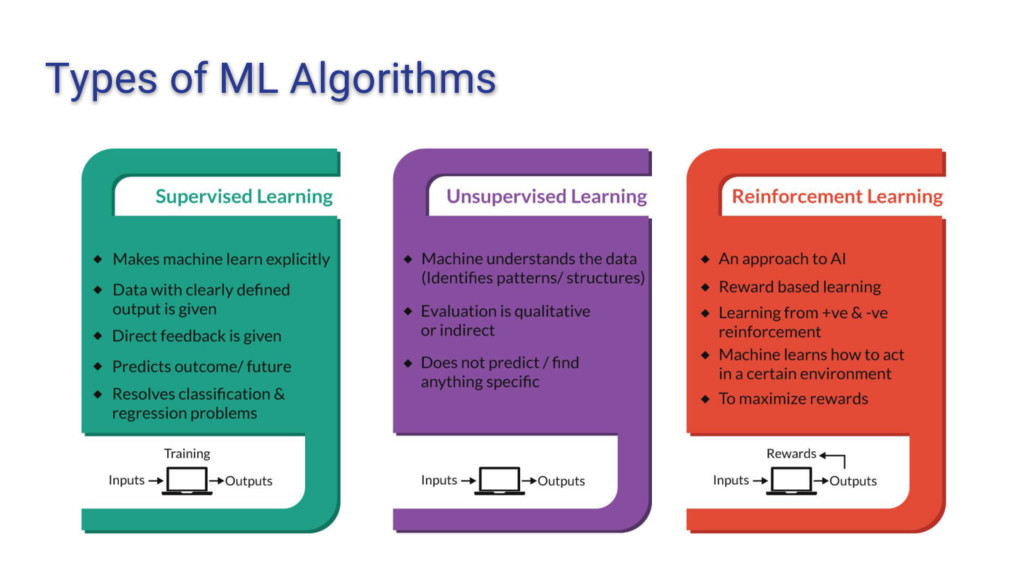
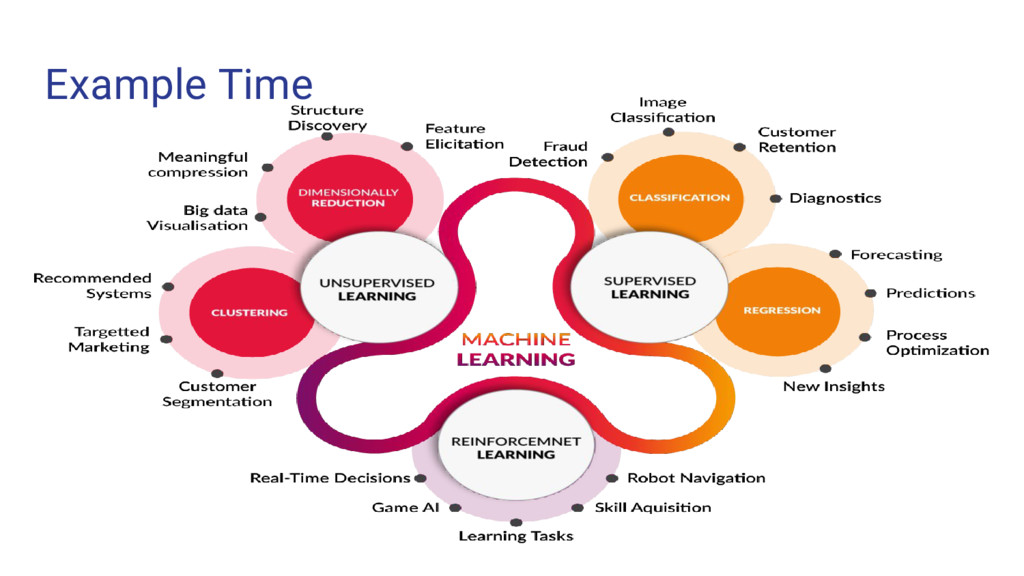
of ML (Machine Learning) Algorithm. What is Machine Learning? What are other type of ML algorithms? What is the use of them? -
Machine Learning • A subfield of computer science and artificial
intelligence (AI) that focuses on the design of systems that can learn from and make decisions and predictions based on data. • Machine learning enables computers to act and make data-driven decisions rather than being explicitly programmed to carry out a certain task. • In this we make machines to learn from the dataset and then test the machine on the new dataset. • On the basis if training of machine we want some intelligence from the machines on the new dataset. -
Ideation What is Classification?? The art of classifying a set
of observations on the basis of their properties (feature vector) to one or more from the set of the target variables or classes. -
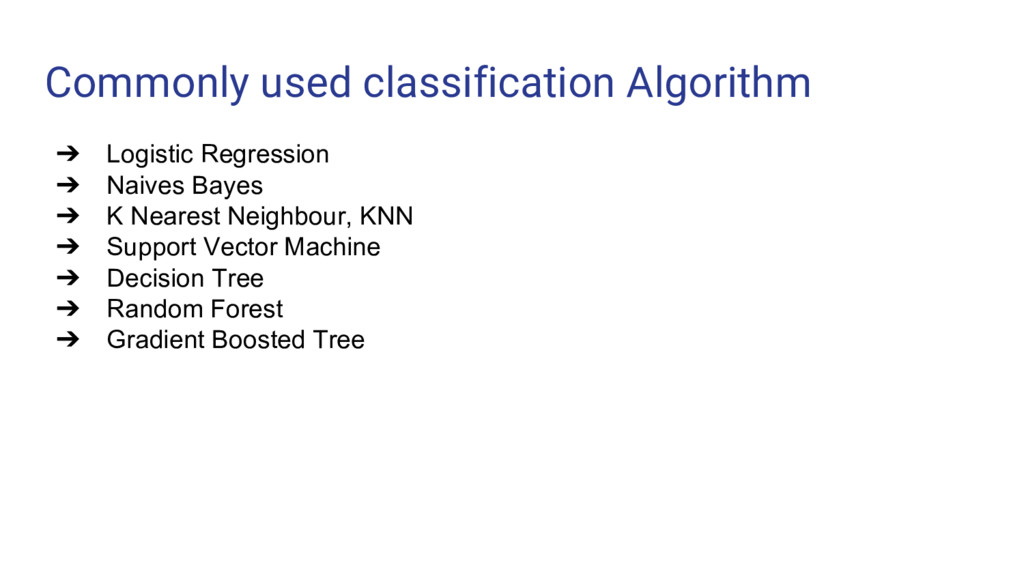
Commonly used classification Algorithm ➔ Logistic Regression ➔ Naives Bayes
➔ K Nearest Neighbour, KNN ➔ Support Vector Machine ➔ Decision Tree ➔ Random Forest ➔ Gradient Boosted Tree -
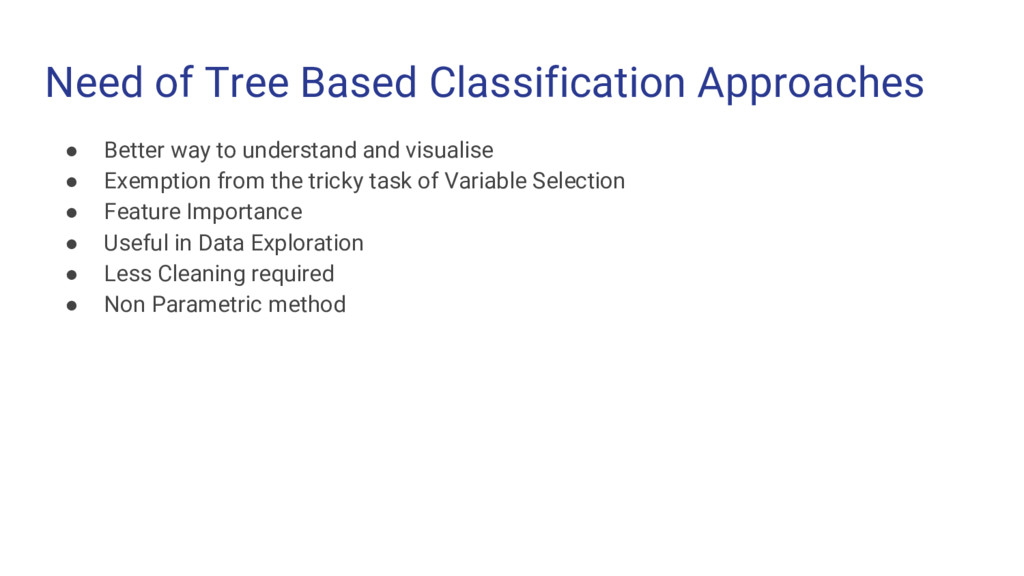
Need of Tree Based Classification Approaches • Better way to
understand and visualise • Exemption from the tricky task of Variable Selection • Feature Importance • Useful in Data Exploration • Less Cleaning required • Non Parametric method -
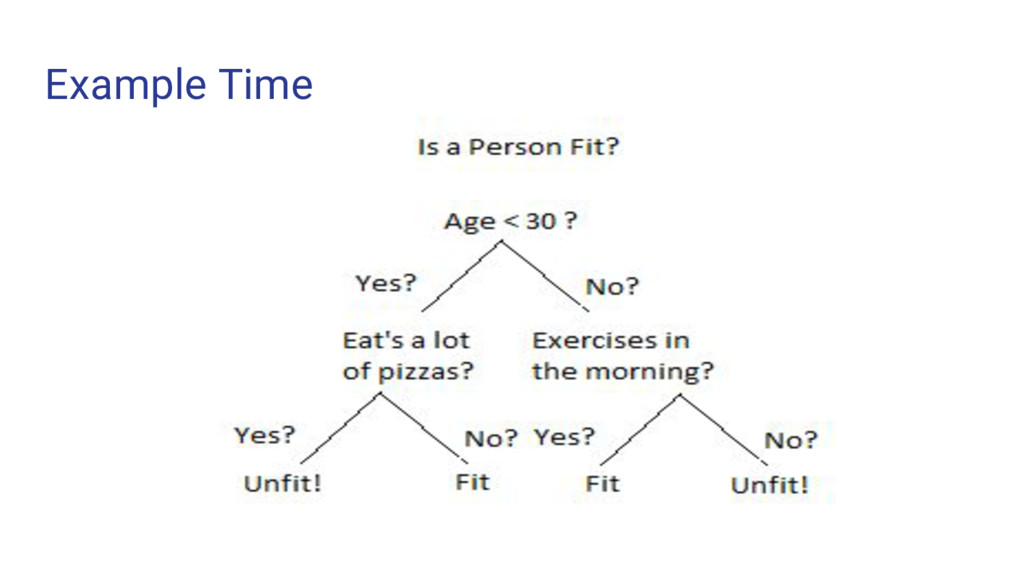
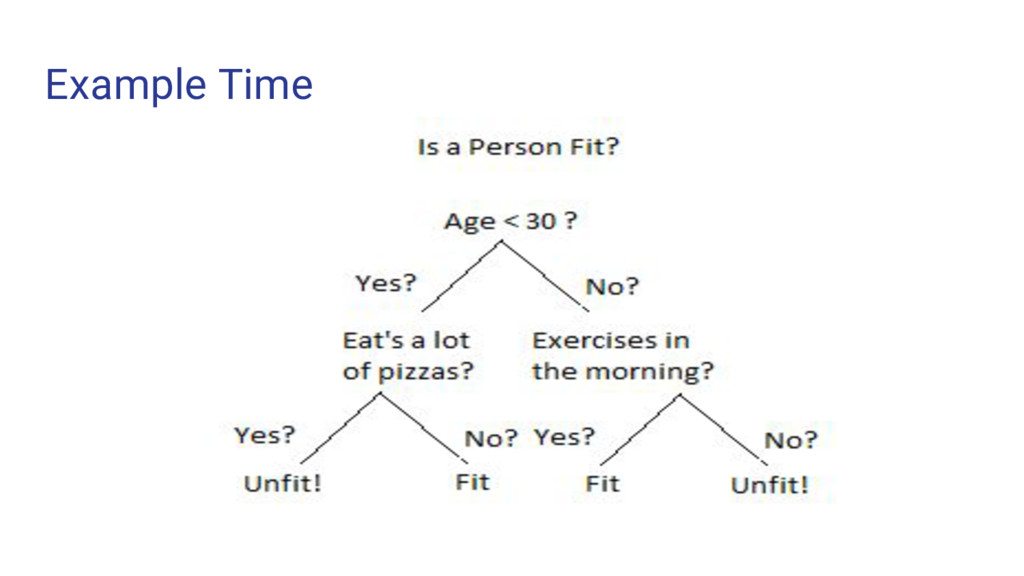
Decision Tree • Type of supervised learning algorithm • Split
the population into two or more homogeneous sets based on most significant criterion or splitter in input variable • Here we will be talking about categorical Variable Decision Tree i.e., the target variable is categories • Follows a Top - Down Greedy approach. • Top Down in a sense because it begins from top where all observations are present. • Greedy because it cares about the current split only -
Gini Index • If we select two item from a
population then they must be of same class and their probability is 1 if the class is pure. • Works with categorical target “success” and “failure” • Performs only binary splitting • Higher the val of Gini Index, higher the homogeneity • CART (Classification and Regression Tree) uses Gini Index Steps: • Calculate the sum of square of probability for success and failure • Calculate the Gini for split using weighted Gini Score for each node for that split -
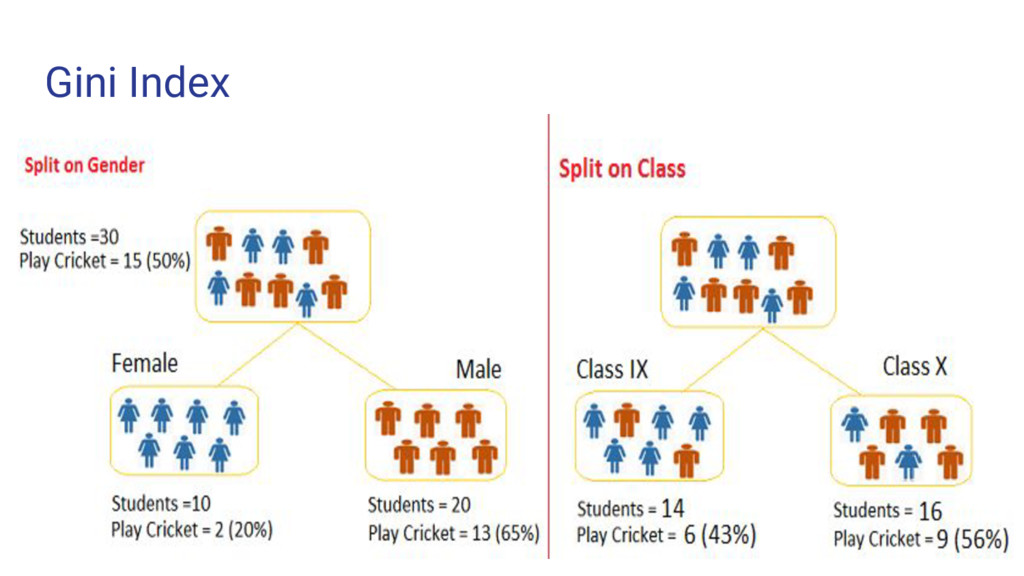
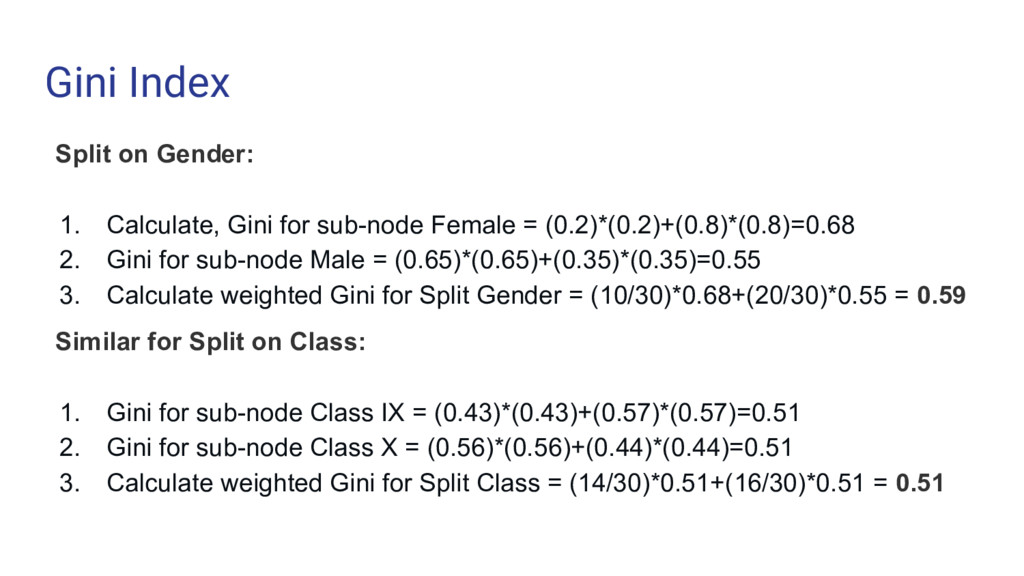
Gini Index Split on Gender: 1. Calculate, Gini for sub-node
Female = (0.2)*(0.2)+(0.8)*(0.8)=0.68 2. Gini for sub-node Male = (0.65)*(0.65)+(0.35)*(0.35)=0.55 3. Calculate weighted Gini for Split Gender = (10/30)*0.68+(20/30)*0.55 = 0.59 Similar for Split on Class: 1. Gini for sub-node Class IX = (0.43)*(0.43)+(0.57)*(0.57)=0.51 2. Gini for sub-node Class X = (0.56)*(0.56)+(0.44)*(0.44)=0.51 3. Calculate weighted Gini for Split Class = (14/30)*0.51+(16/30)*0.51 = 0.51 -
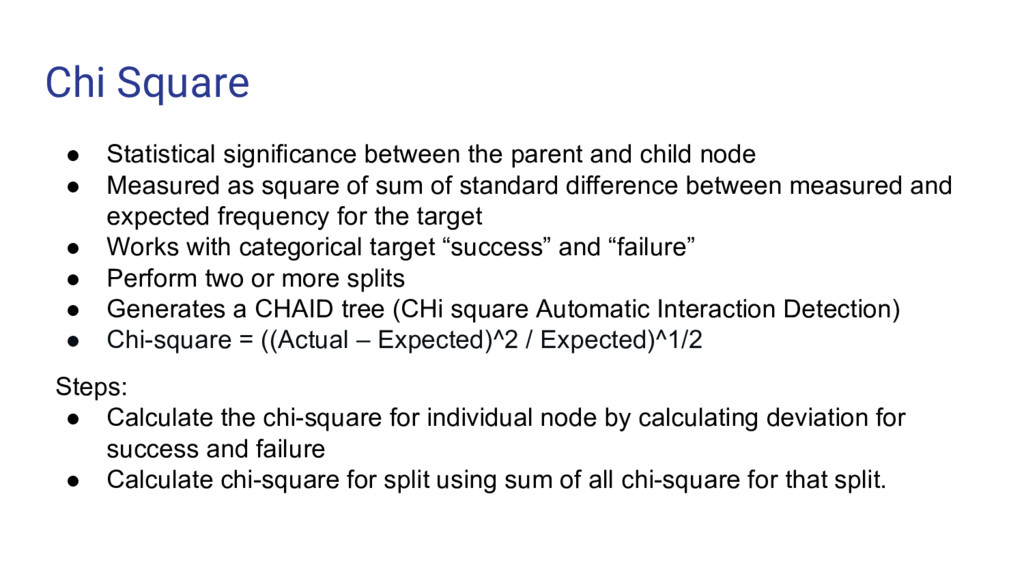
Chi Square • Statistical significance between the parent and child
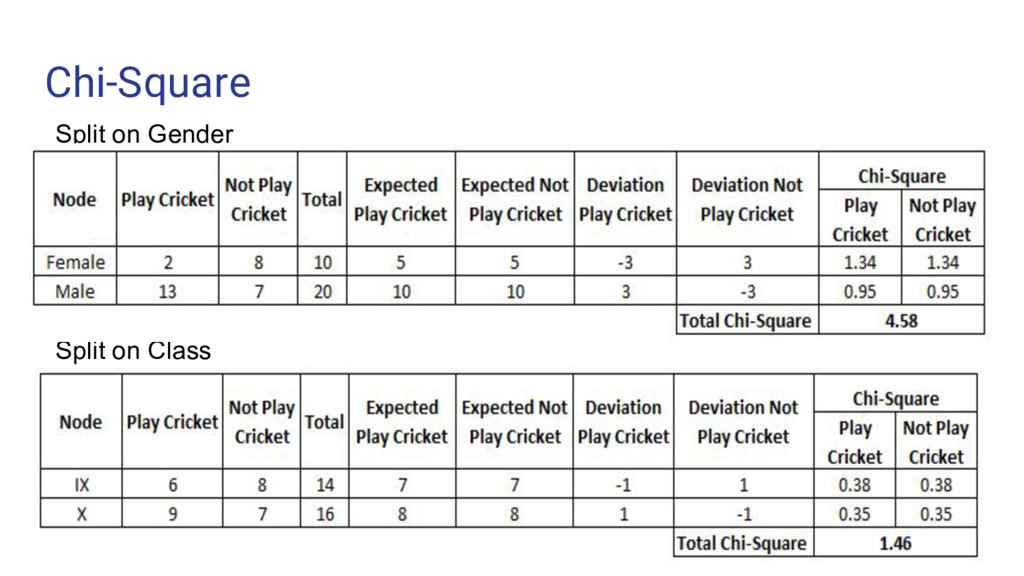
node • Measured as square of sum of standard difference between measured and expected frequency for the target • Works with categorical target “success” and “failure” • Perform two or more splits • Generates a CHAID tree (CHi square Automatic Interaction Detection) • Chi-square = ((Actual – Expected)^2 / Expected)^1/2 Steps: • Calculate the chi-square for individual node by calculating deviation for success and failure • Calculate chi-square for split using sum of all chi-square for that split. -
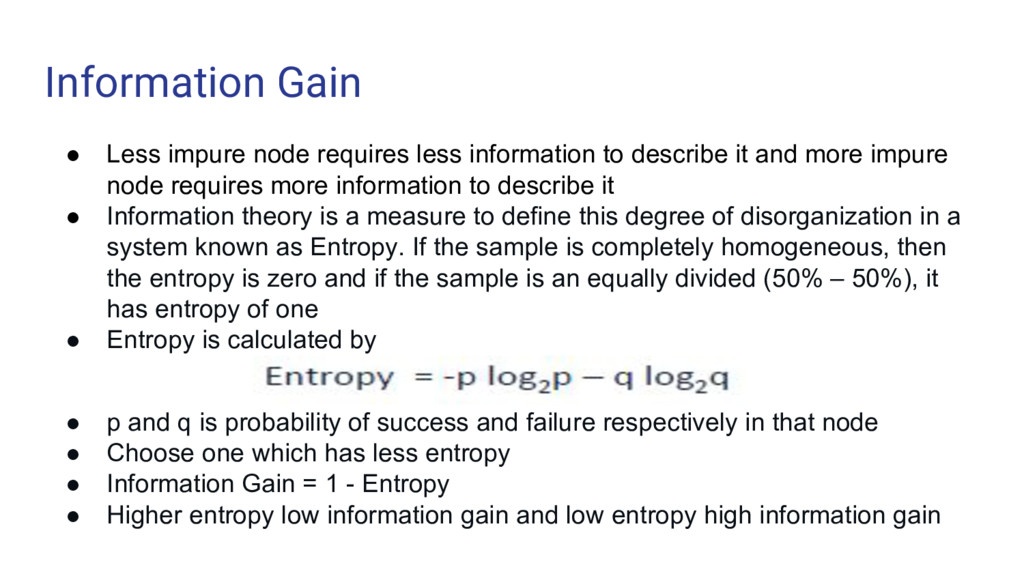
Information Gain • Less impure node requires less information to
describe it and more impure node requires more information to describe it • Information theory is a measure to define this degree of disorganization in a system known as Entropy. If the sample is completely homogeneous, then the entropy is zero and if the sample is an equally divided (50% – 50%), it has entropy of one • Entropy is calculated by • p and q is probability of success and failure respectively in that node • Choose one which has less entropy • Information Gain = 1 - Entropy • Higher entropy low information gain and low entropy high information gain -
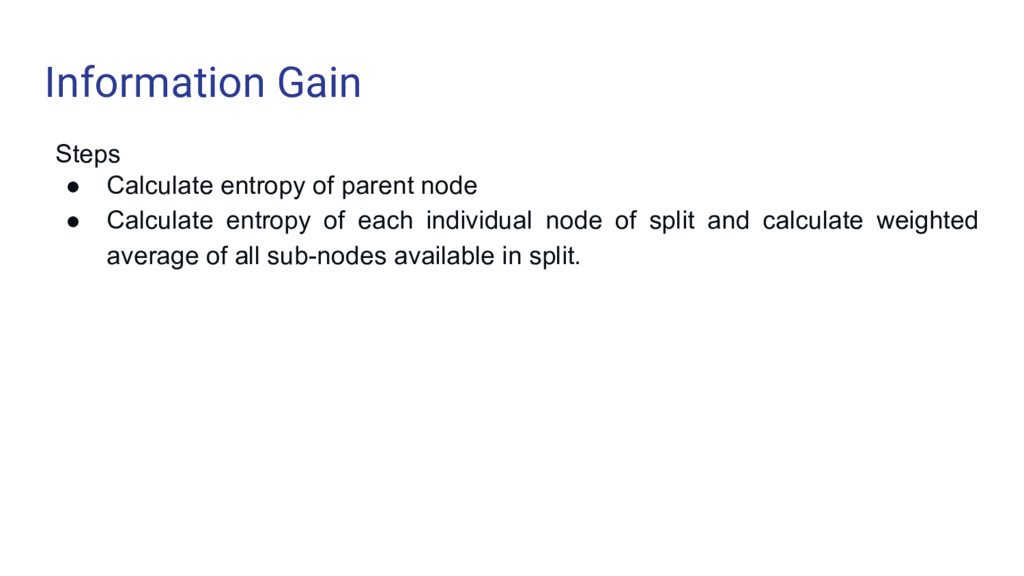
Information Gain Steps • Calculate entropy of parent node •
Calculate entropy of each individual node of split and calculate weighted average of all sub-nodes available in split. -
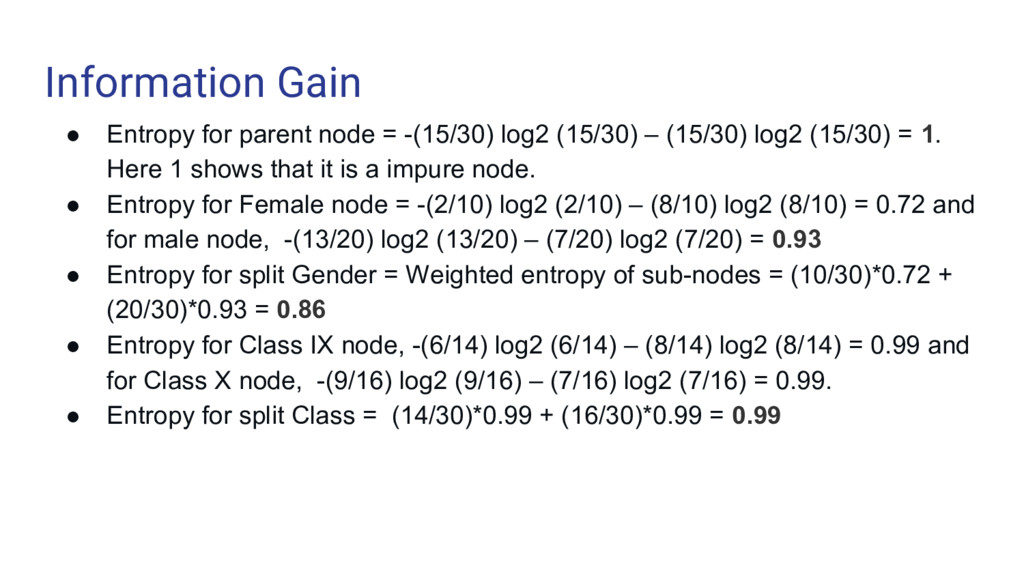
Information Gain • Entropy for parent node = -(15/30) log2
(15/30) – (15/30) log2 (15/30) = 1. Here 1 shows that it is a impure node. • Entropy for Female node = -(2/10) log2 (2/10) – (8/10) log2 (8/10) = 0.72 and for male node, -(13/20) log2 (13/20) – (7/20) log2 (7/20) = 0.93 • Entropy for split Gender = Weighted entropy of sub-nodes = (10/30)*0.72 + (20/30)*0.93 = 0.86 • Entropy for Class IX node, -(6/14) log2 (6/14) – (8/14) log2 (8/14) = 0.99 and for Class X node, -(9/16) log2 (9/16) – (7/16) log2 (7/16) = 0.99. • Entropy for split Class = (14/30)*0.99 + (16/30)*0.99 = 0.99 -
The problem : Overfitting What? Overfitting is one of the
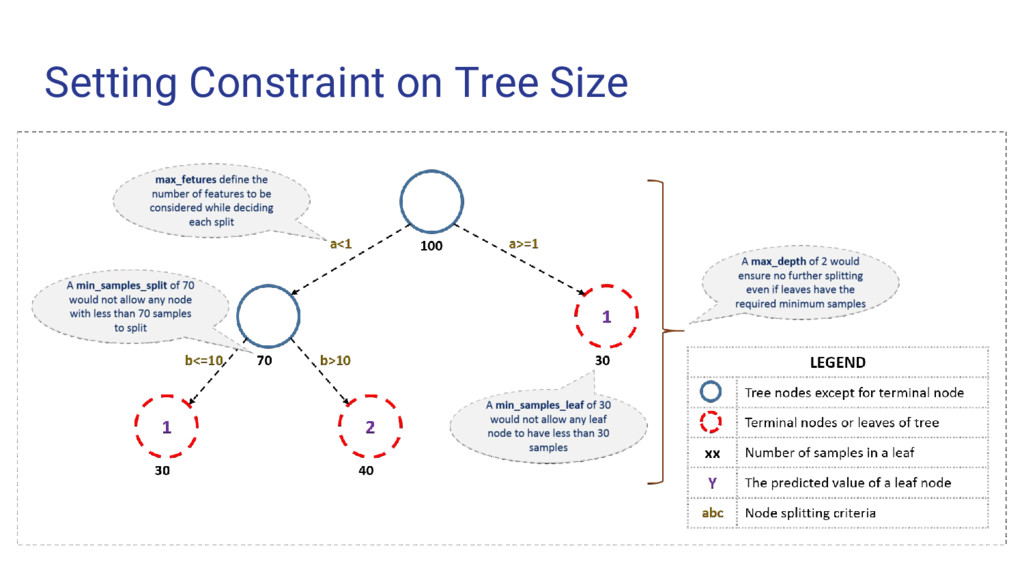
key challenge. If there is no limit set on tree modeling then it give 100% accuracy on train data but might not give impressive accuracy on test data. Why? Because while training it end up leaving one leaf for each observation. Which may not be the scenario in test data. Preventing Overfitting 1. Setting Constraint on tree size 2. Tree Pruning -
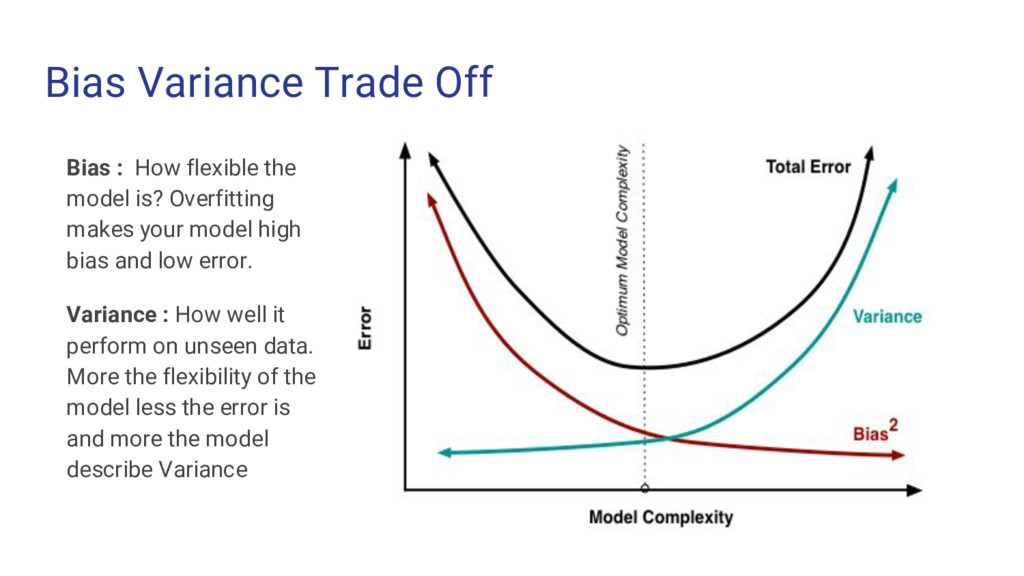
Bias Variance Trade Off Bias : How flexible the model
is? Overfitting makes your model high bias and low error. Variance : How well it perform on unseen data. More the flexibility of the model less the error is and more the model describe Variance -
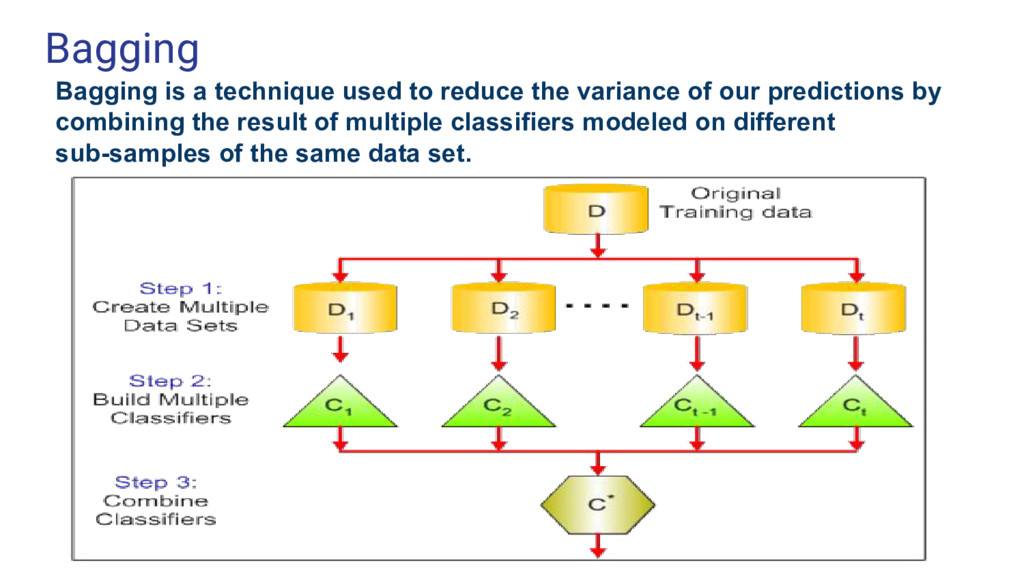
Bagging Bagging is a technique used to reduce the variance
of our predictions by combining the result of multiple classifiers modeled on different sub-samples of the same data set. -
Random Forest • Considered to be a panacea of all
data science problems • Also undertakes dimensional reduction methods, treats missing values, outlier values • We grow multiple trees as opposed to a single tree in CART model • Each tree gives a classification and we say the tree “votes” for that class. • The forest chooses the classification having the most votes -
Boosting The term ‘Boosting’ refers to a family of algorithms
which converts weak learner to strong learners. • Boosting pays higher focus on examples which are mis-classified or have higher errors by preceding weak rules. • For this purpose, it uses a base learner algorithm whose task is to provide high weightage to misclassified observations -
How it works Step 1: The base learner takes all
the distributions and assign equal weight or attention to each observation. Step 2: If there is any prediction error caused by first base learning algorithm, then we pay higher attention to observations having prediction error. Then, we apply the next base learning algorithm. Step 3: Iterate Step 2 till the limit of base learning algorithm is reached or higher accuracy is achieved. Finally it combine the output of week learner and makes a strong learner which eventually improves the power of the model -
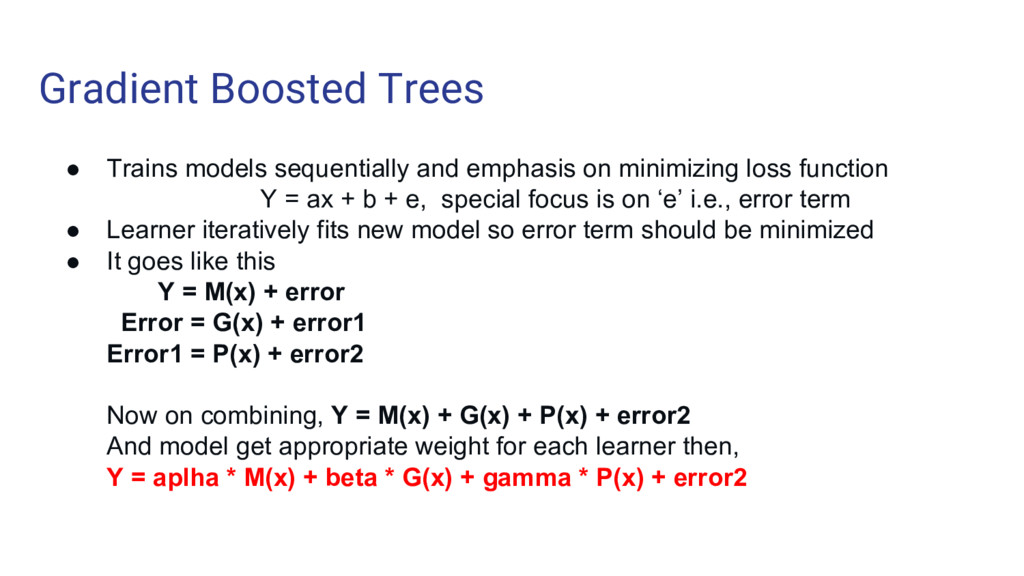
Gradient Boosted Trees • Trains models sequentially and emphasis on
minimizing loss function Y = ax + b + e, special focus is on ‘e’ i.e., error term • Learner iteratively fits new model so error term should be minimized • It goes like this Y = M(x) + error Error = G(x) + error1 Error1 = P(x) + error2 Now on combining, Y = M(x) + G(x) + P(x) + error2 And model get appropriate weight for each learner then, Y = aplha * M(x) + beta * G(x) + gamma * P(x) + error2 -
Consolidation Let’s Summarise Ensemble Learning is an ML paradigm where
multiple learner are trained to solve a problem. -
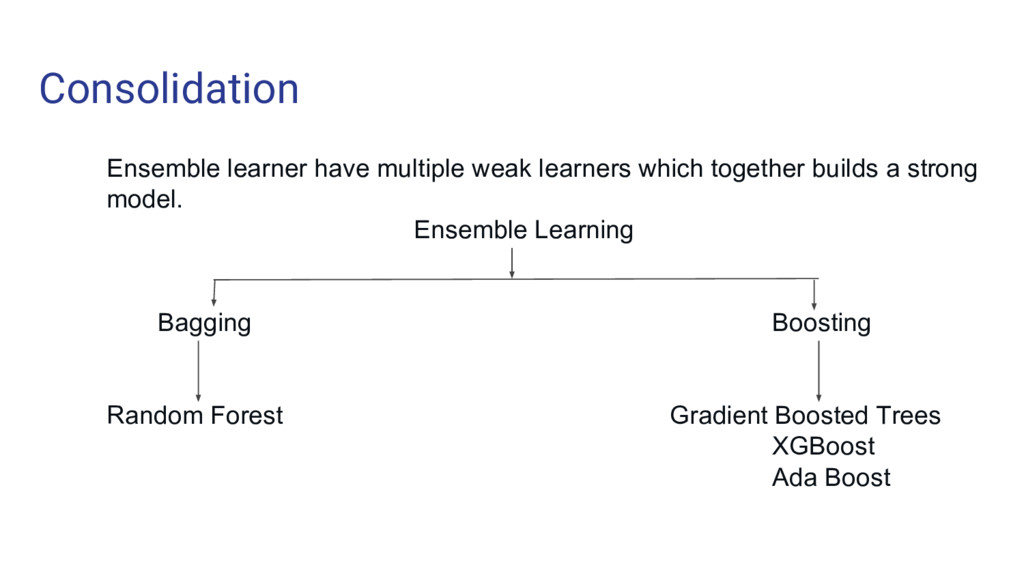
Consolidation Ensemble learner have multiple weak learners which together builds
a strong model. Ensemble Learning Bagging Boosting Random Forest Gradient Boosted Trees XGBoost Ada Boost