Share
Embed
Dask - Pythonic way of parallelizing scientific computation
Dask provides pythonic implementation for doing scalable and parallel scientific computation. It also facilitates orchestrating of jobs and parallel execution for them.
Mayank Mishra
November 26, 2018
Transcript
19 slides
-
Presented By Mayank Mishra A Data Science and Machine Learning
Enthusiast @mayank_skb -
Line Up 1. What we have?? 2. What we need??
3. Integration with Existing Scientific Stack 4. Scaling it to Cluster 5. Scheduling in Dask 6. Why Dask?? -
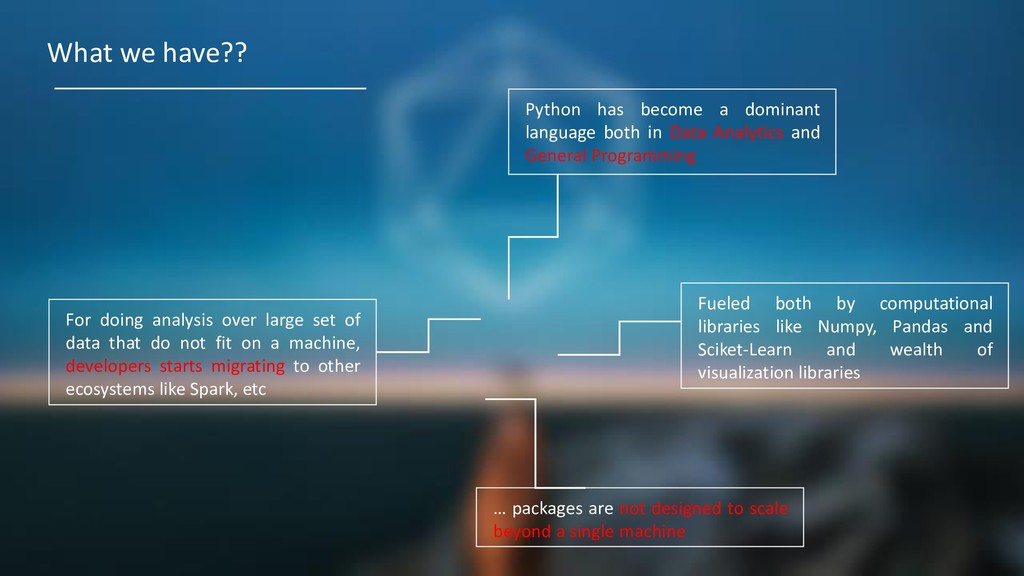
What we have?? Python has become a dominant language both
in Data Analytics and General Programming Fueled both by computational libraries like Numpy, Pandas and Sciket-Learn and wealth of visualization libraries … packages are not designed to scale beyond a single machine For doing analysis over large set of data that do not fit on a machine, developers starts migrating to other ecosystems like Spark, etc -
What we Need?? A parallel computing library . . .
Flexible Enough . . . Familiar Enough . . . Can be used to parallelize a desperate ecosystem -
Dask Dask provides advanced parallelism for analytics, enabling performance at
scale for the tools you love Dask natively scales Python -
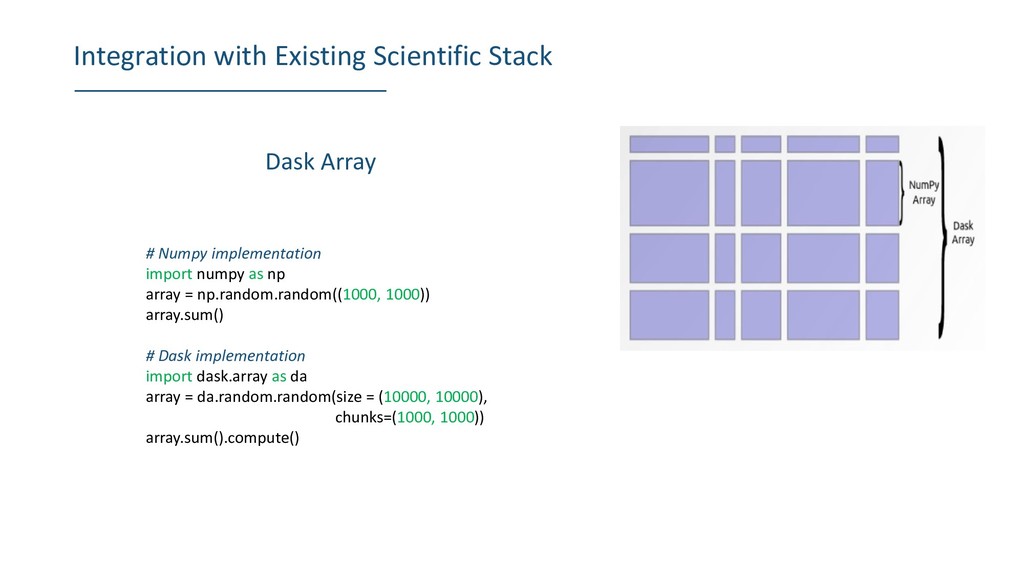
Integration with Existing Scientific Stack Dask Array # Numpy implementation
import numpy as np array = np.random.random((1000, 1000)) array.sum() # Dask implementation import dask.array as da array = da.random.random(size = (10000, 10000), chunks=(1000, 1000)) array.sum().compute() -
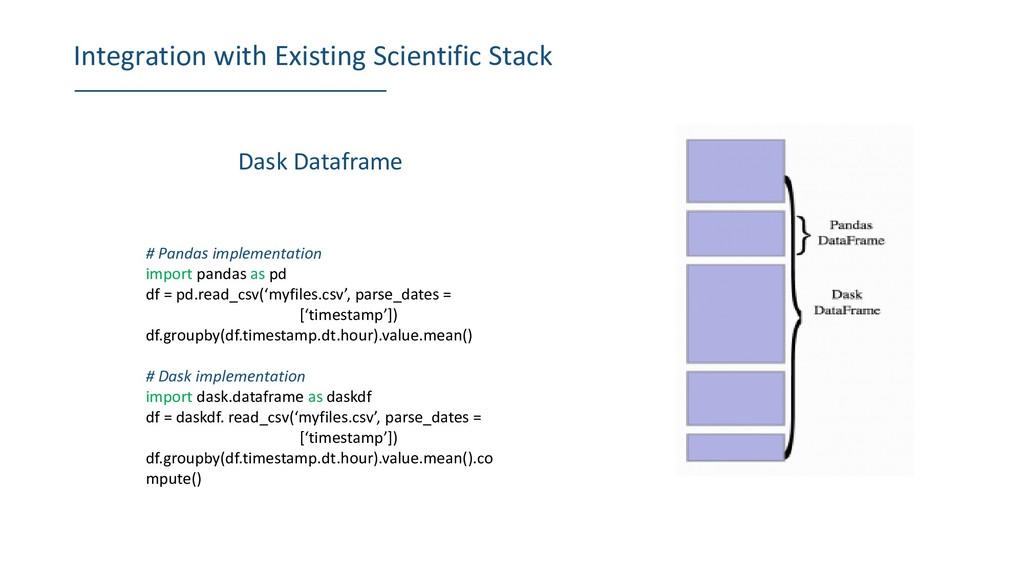
Integration with Existing Scientific Stack Dask Dataframe # Pandas implementation
import pandas as pd df = pd.read_csv(‘myfiles.csv’, parse_dates = [‘timestamp’]) df.groupby(df.timestamp.dt.hour).value.mean() # Dask implementation import dask.dataframe as daskdf df = daskdf. read_csv(‘myfiles.csv’, parse_dates = [‘timestamp’]) df.groupby(df.timestamp.dt.hour).value.mean().co mpute() -
Integration with Existing Scientific Stack Dask ML # Pandas implementation
from sklearn.linear_model import LinearRegression Lr = LinearRegression() Lr.fit() # Dask implementation from dask_ml.linear_model import LinearRegression Lr = LinearRegression() Lr.fit() -
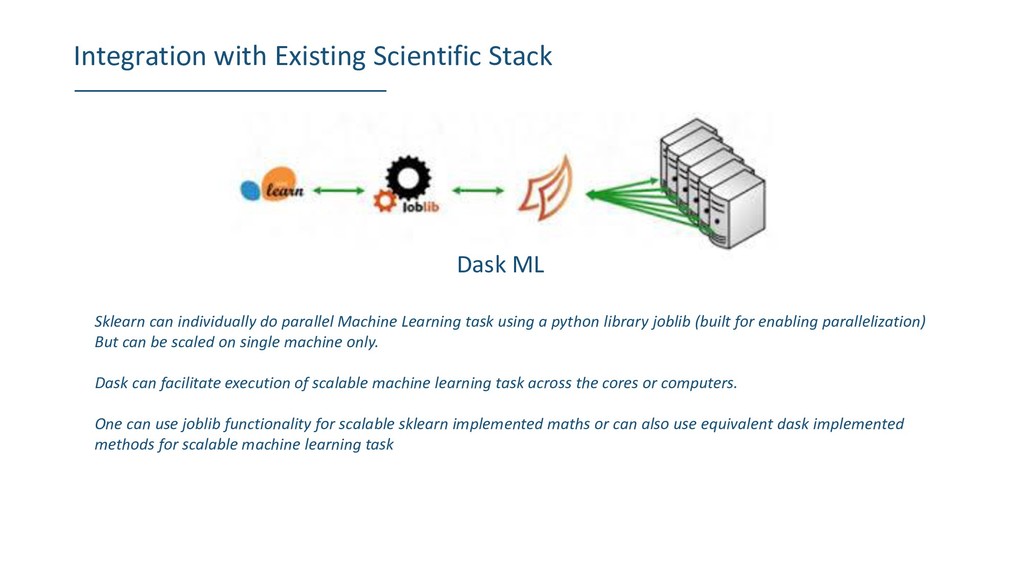
Integration with Existing Scientific Stack Dask ML Sklearn can individually
do parallel Machine Learning task using a python library joblib (built for enabling parallelization) But can be scaled on single machine only. Dask can facilitate execution of scalable machine learning task across the cores or computers. One can use joblib functionality for scalable sklearn implemented maths or can also use equivalent dask implemented methods for scalable machine learning task -
But … Many problems are not just big arrays and
dataframes Python community writes clever algorithms Through dask one can address them . . . -
Scaling it to Clusters Or just use it on your
laptop Dask runs on thousand-machine clusters to process hundreds of terabytes of data efficiently Can be Deployed in-house, on cloud or on HPC super-computer Supports authentication and encryption using TLS/SSL certificates Resilient, can handle failure of work nodes gracefully Can take advantage of new-node added-on-fly -
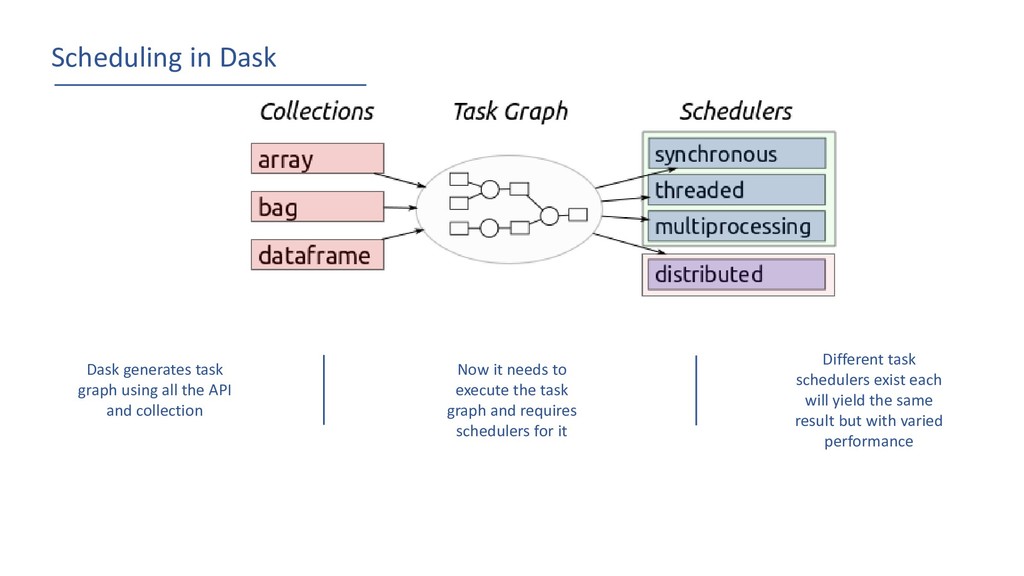
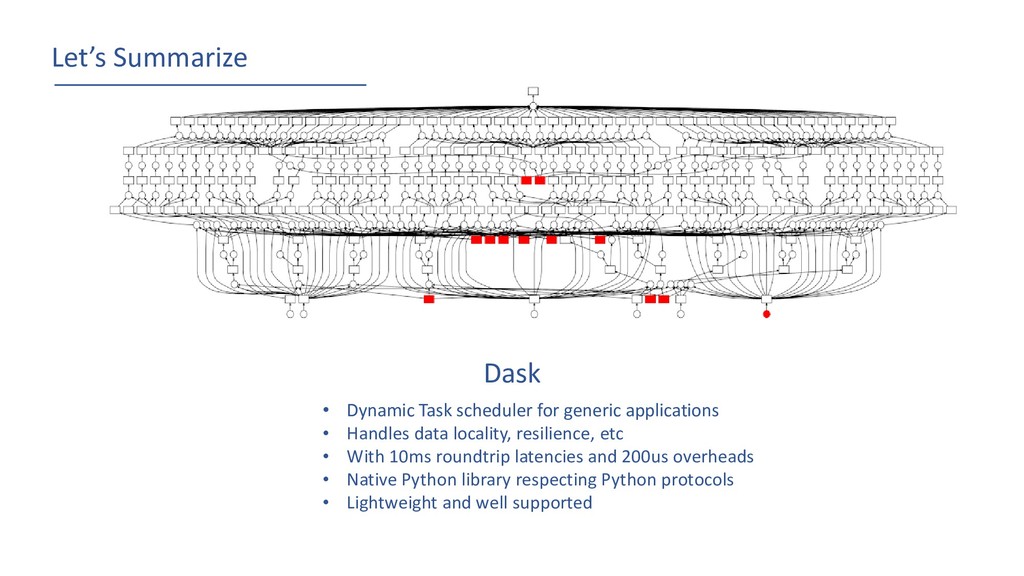
Scheduling in Dask Dask generates task graph using all the
API and collection Now it needs to execute the task graph and requires schedulers for it Different task schedulers exist each will yield the same result but with varied performance -
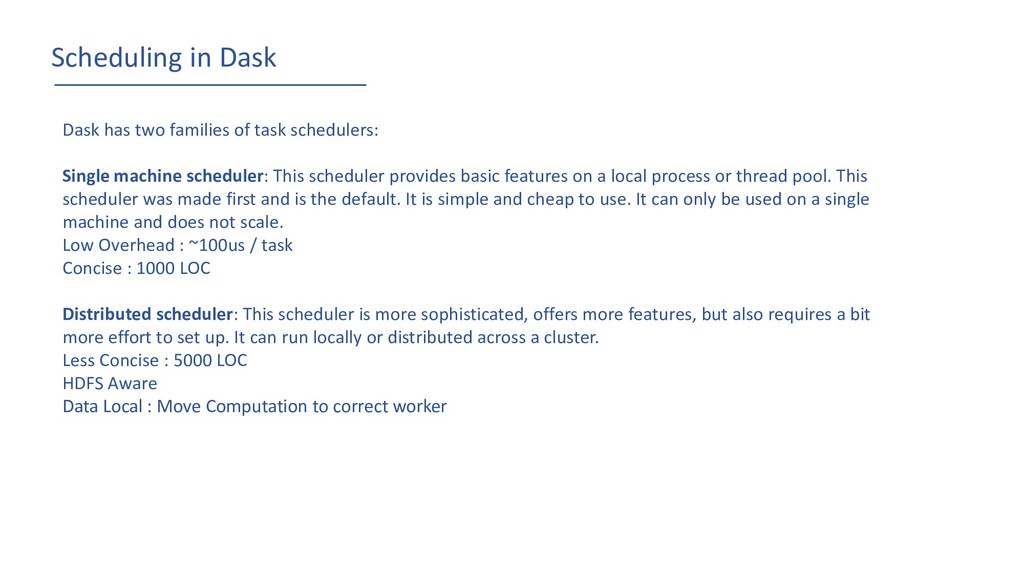
Scheduling in Dask Dask has two families of task schedulers:
Single machine scheduler: This scheduler provides basic features on a local process or thread pool. This scheduler was made first and is the default. It is simple and cheap to use. It can only be used on a single machine and does not scale. Low Overhead : ~100us / task Concise : 1000 LOC Distributed scheduler: This scheduler is more sophisticated, offers more features, but also requires a bit more effort to set up. It can run locally or distributed across a cluster. Less Concise : 5000 LOC HDFS Aware Data Local : Move Computation to correct worker -
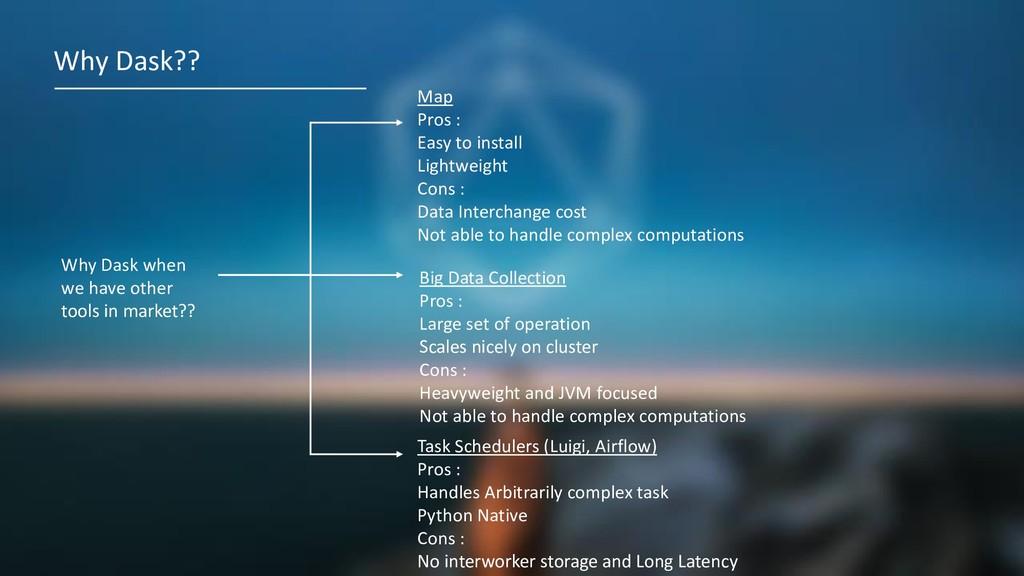
Why Dask?? Why Dask when we have other tools in
market?? Map Pros : Easy to install Lightweight Cons : Data Interchange cost Not able to handle complex computations Big Data Collection Pros : Large set of operation Scales nicely on cluster Cons : Heavyweight and JVM focused Not able to handle complex computations Task Schedulers (Luigi, Airflow) Pros : Handles Arbitrarily complex task Python Native Cons : No interworker storage and Long Latency -
Why Dask?? TASK SCHEDULER LIKE AIRFLOW, LUIGI BUILT FOR COMPUTATIONAL
LOAD LIKE SPARK, FLINK -
Let’s Summarize • Dynamic Task scheduler for generic applications •
Handles data locality, resilience, etc • With 10ms roundtrip latencies and 200us overheads • Native Python library respecting Python protocols • Lightweight and well supported Dask -
References • Dask Documentation • Matthew Rocklin’ talk on Dask
Python Distribution framework at PyCon 2017 • Matthew Rocklin Blog • Analytics Vidya • Talk on Scalable Machine Learning with Dask at SciPy 2018 by Augspurger & Grisel -
Thank you for listening me ☺ You can found me
here : Twitter : Mayank_skb