*This session was presented at AMD Advancing AI Seoul 2026 on November 4, 2026.
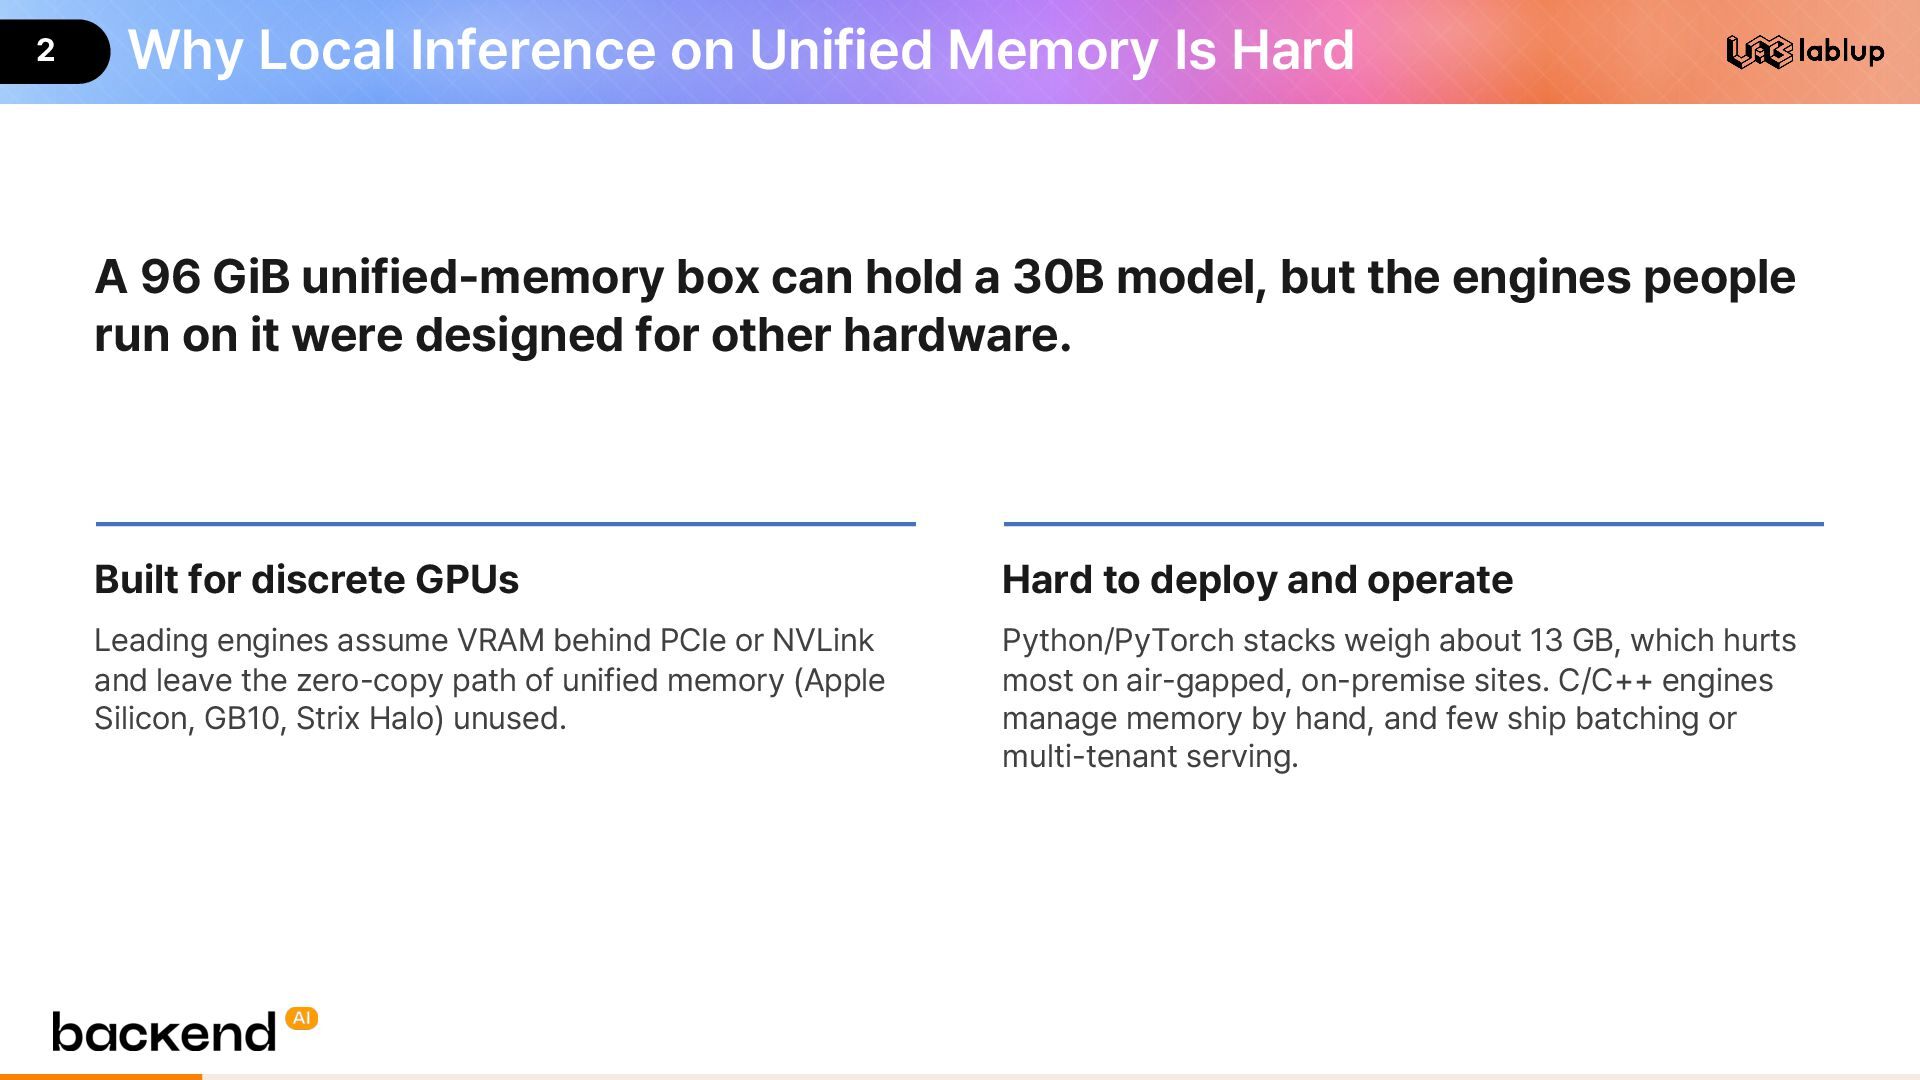
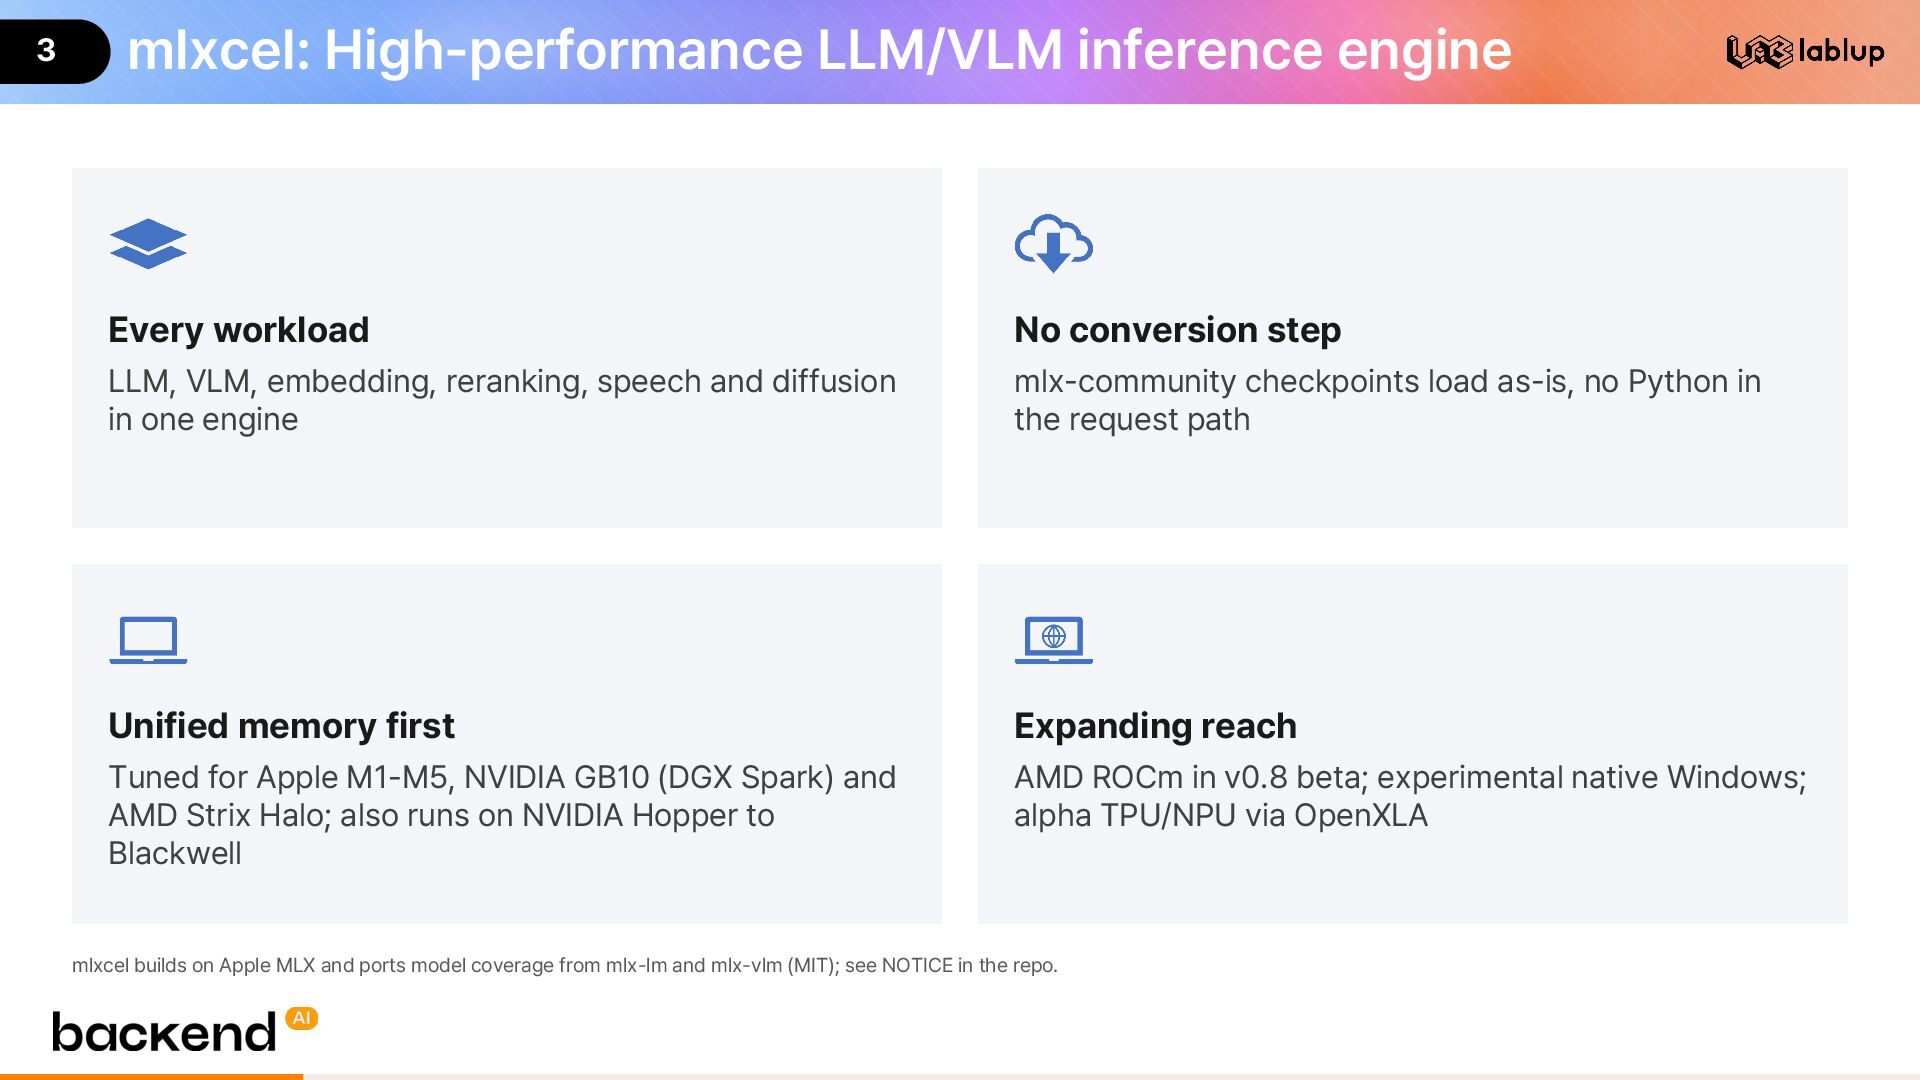
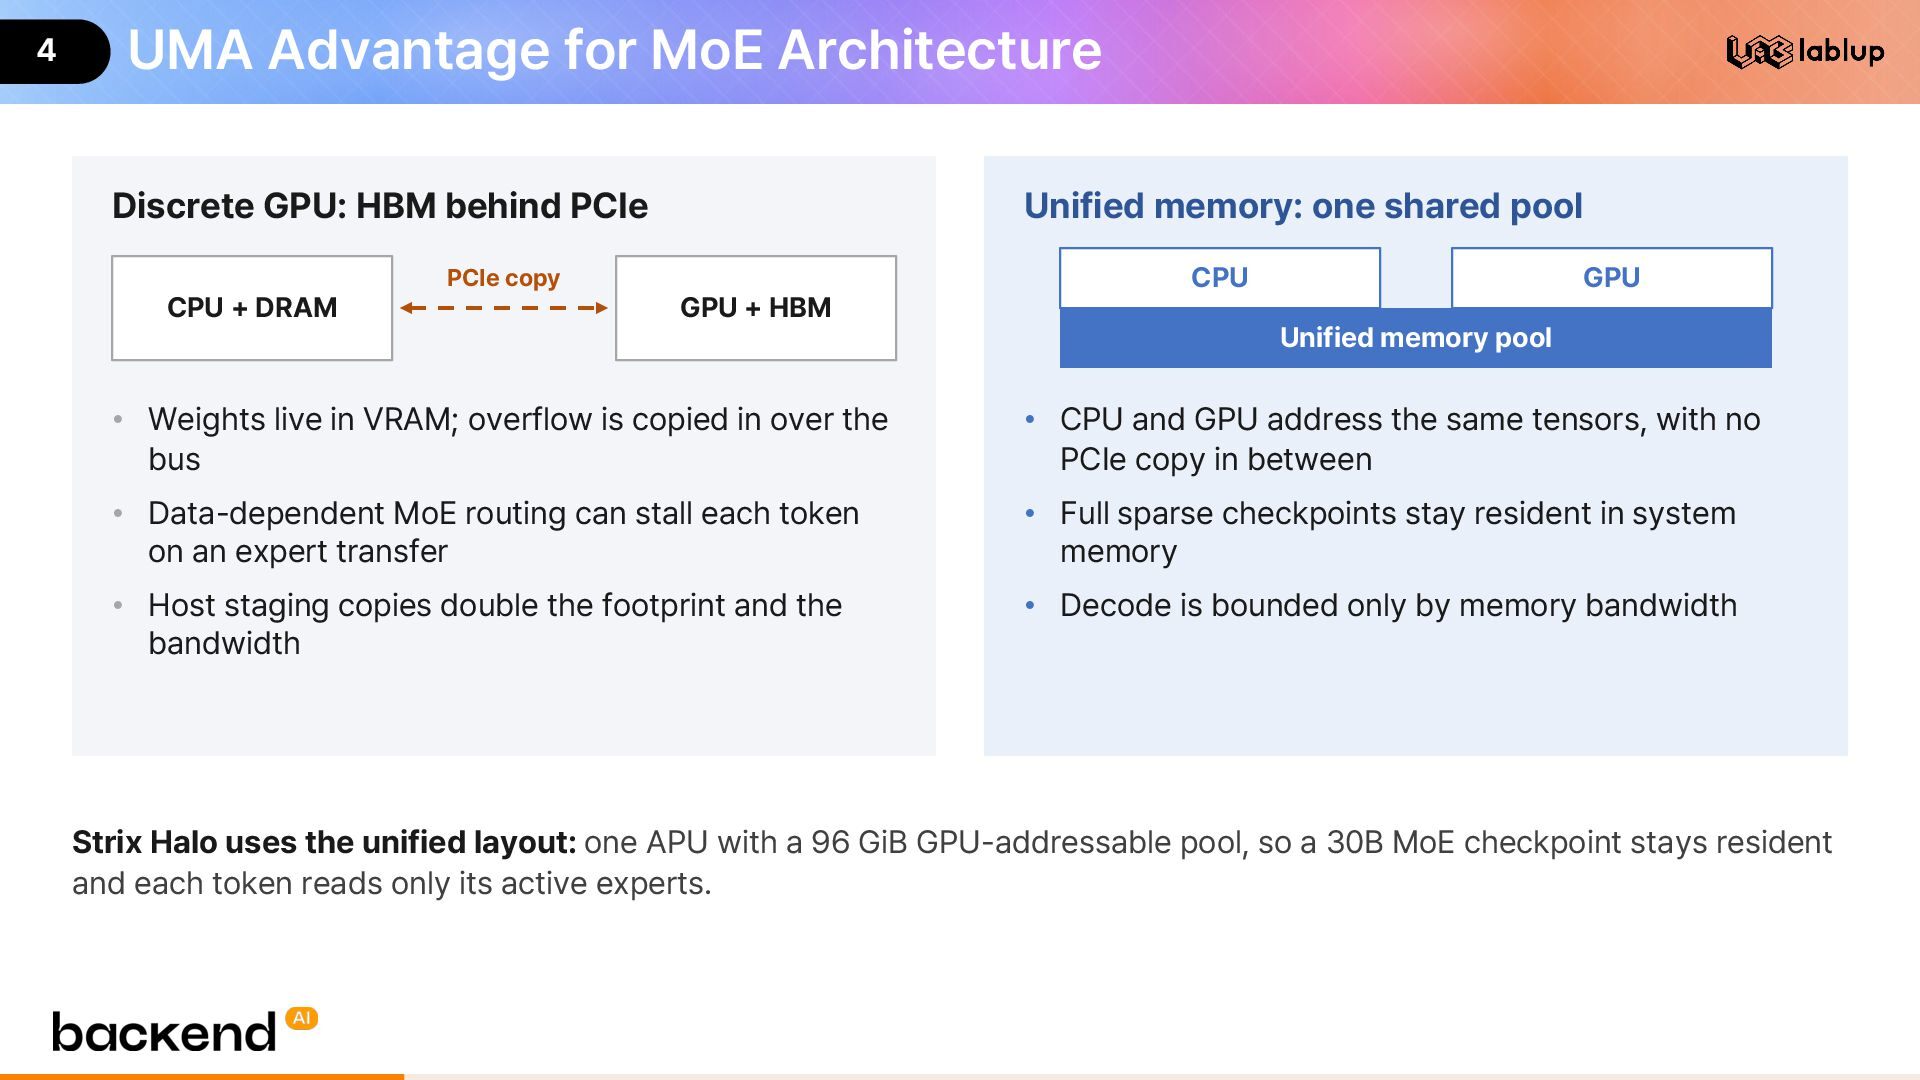
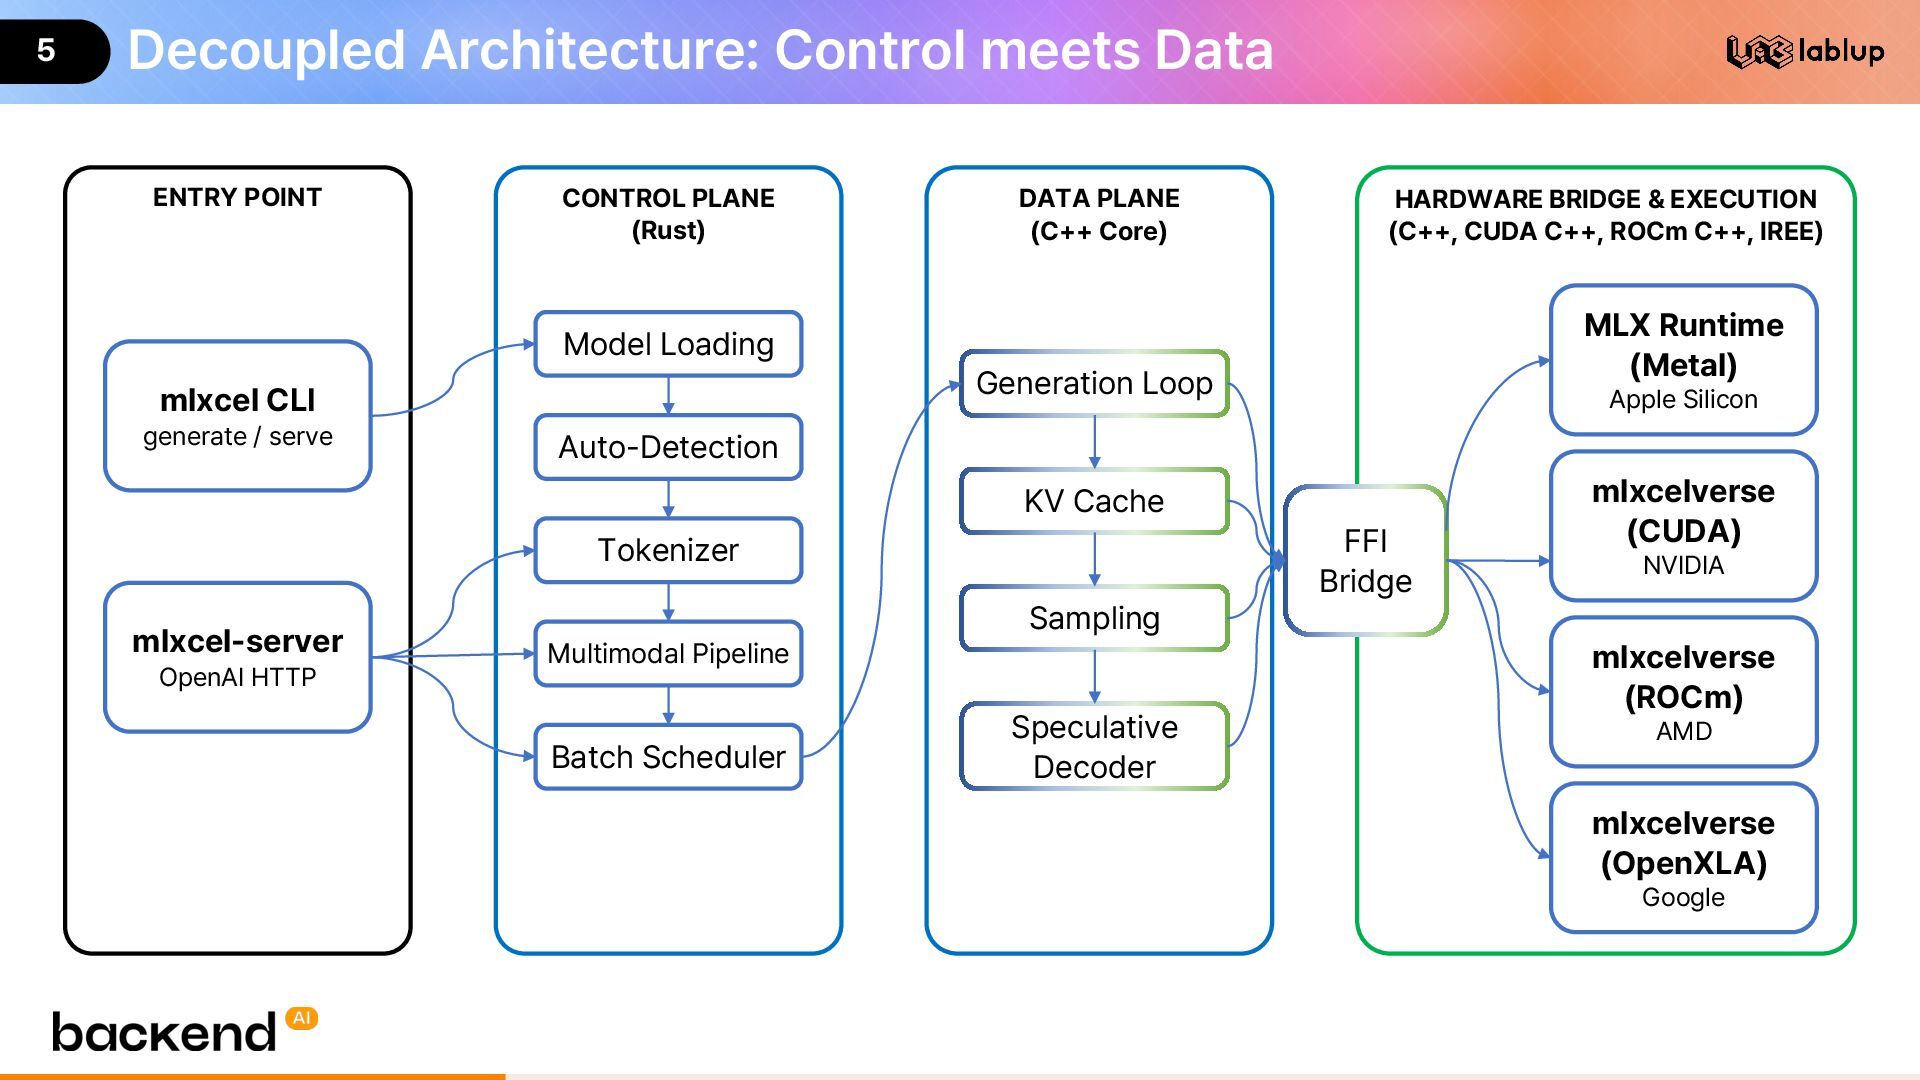
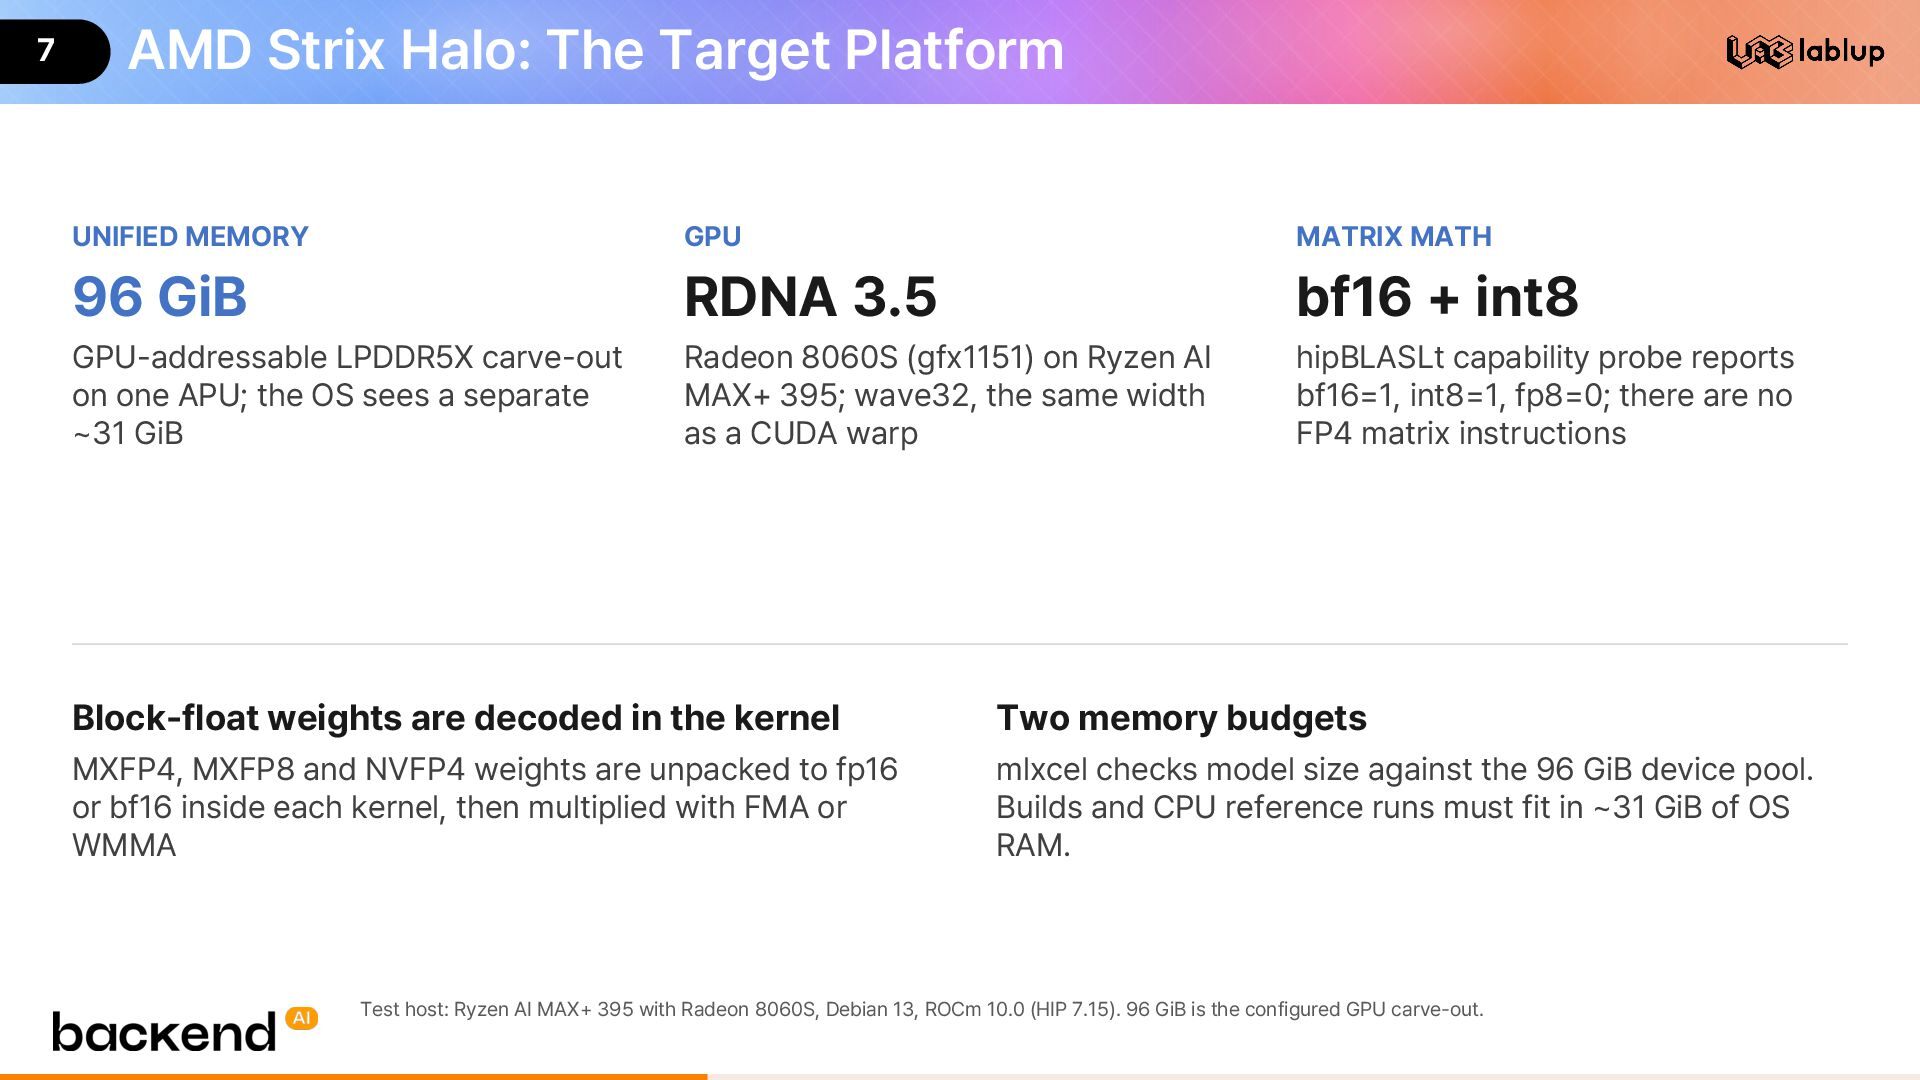
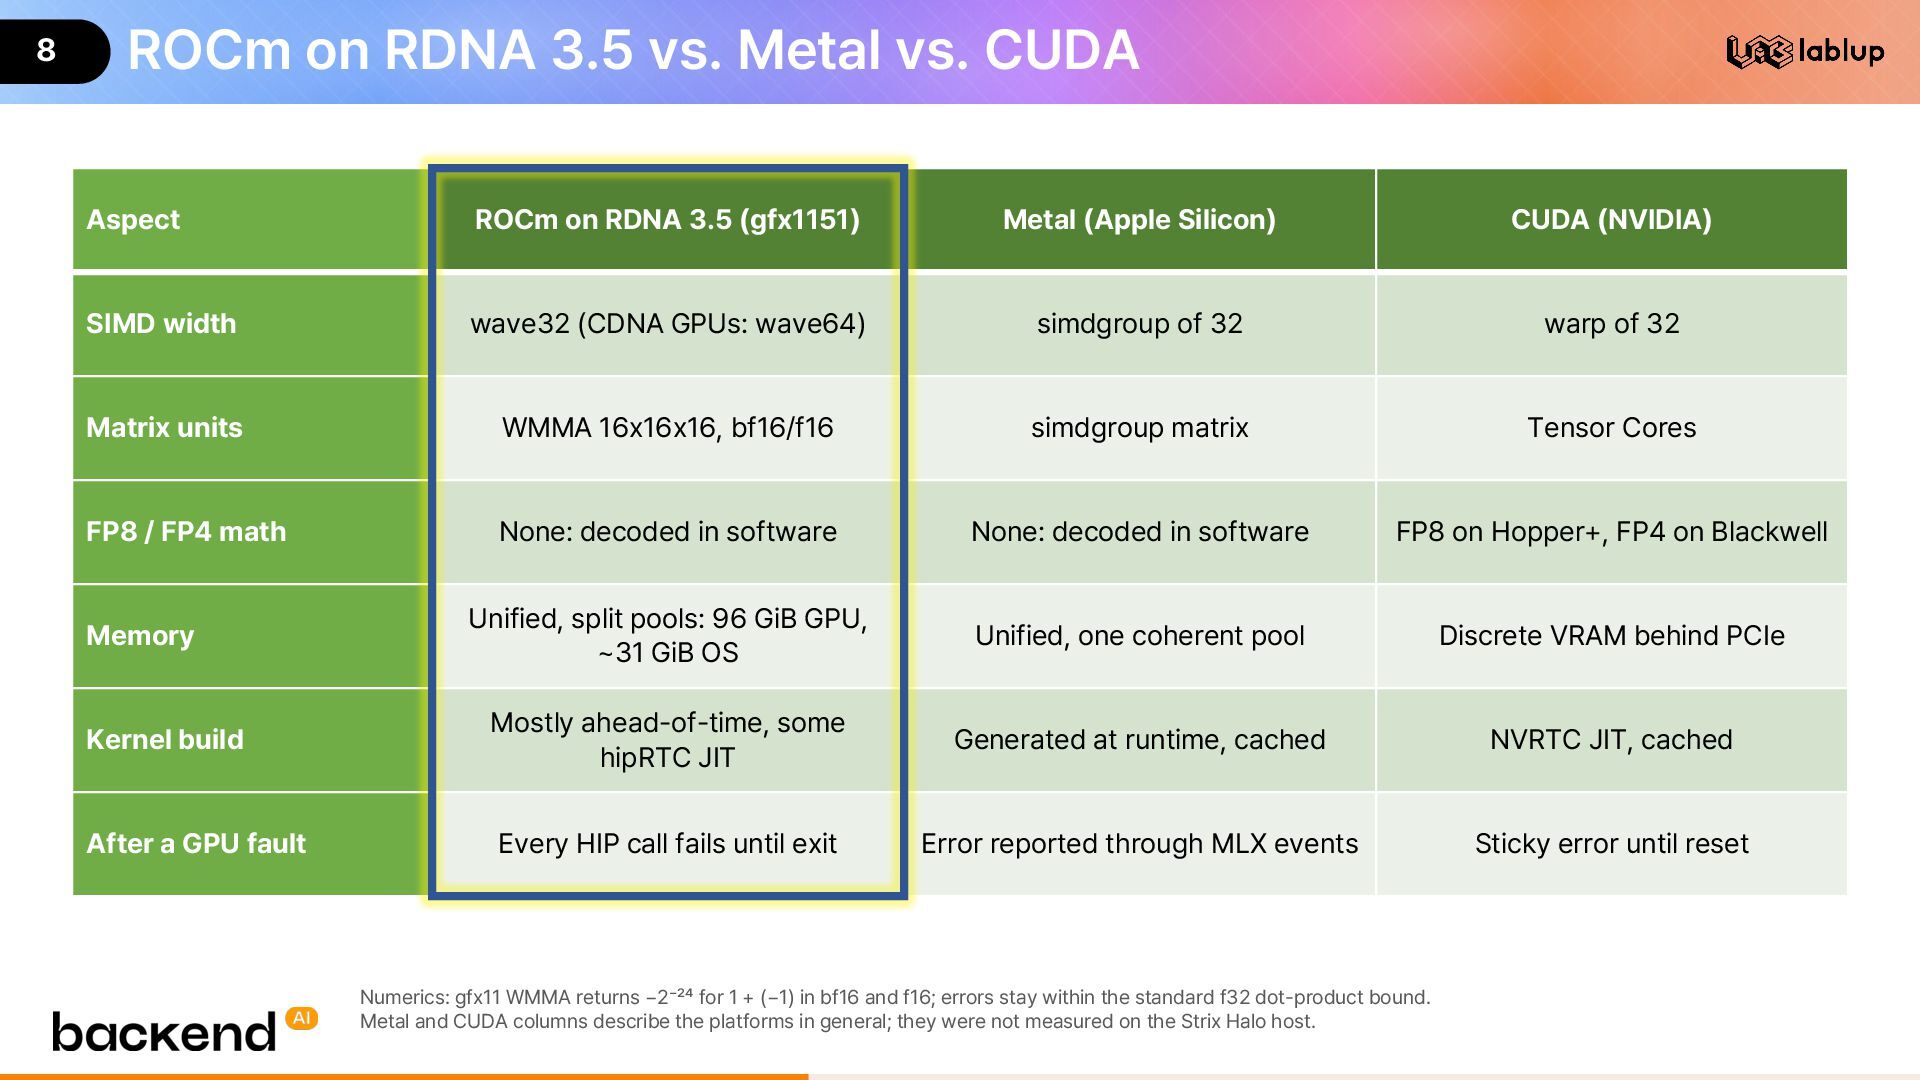
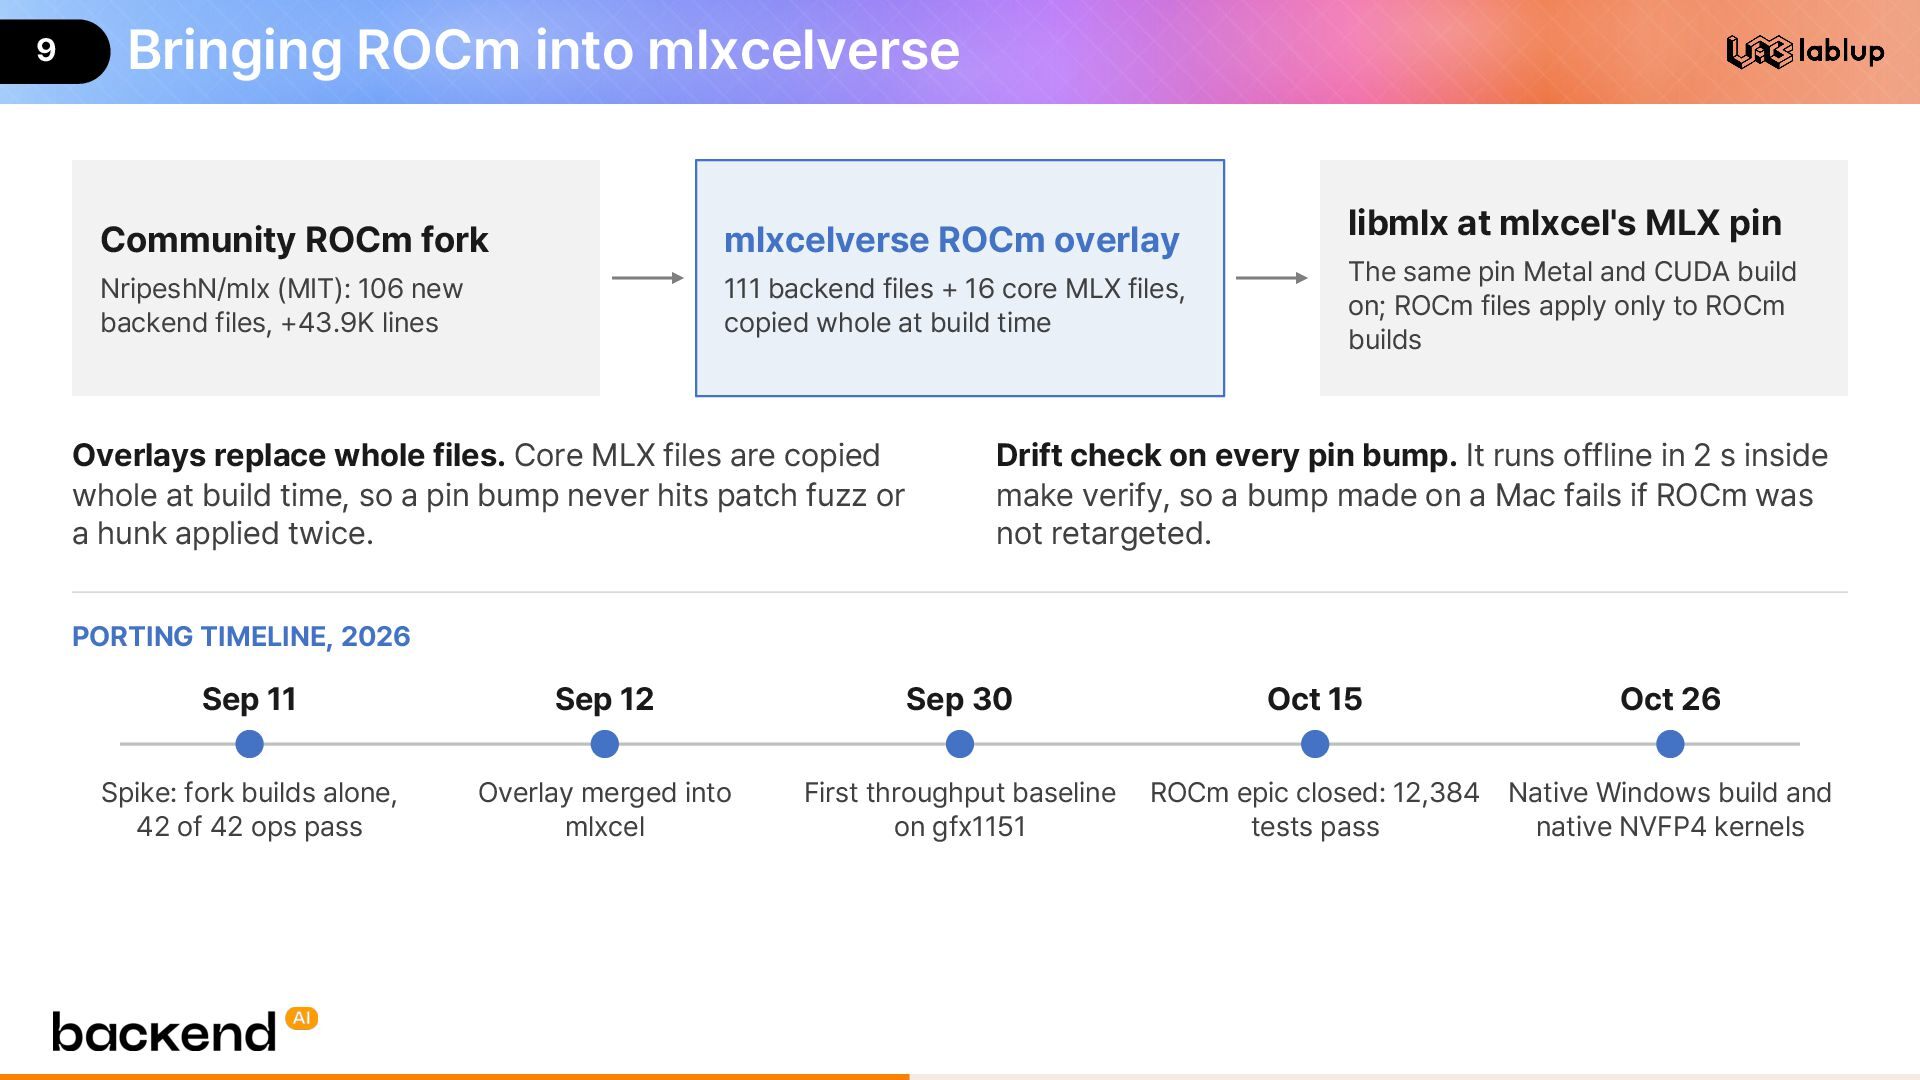
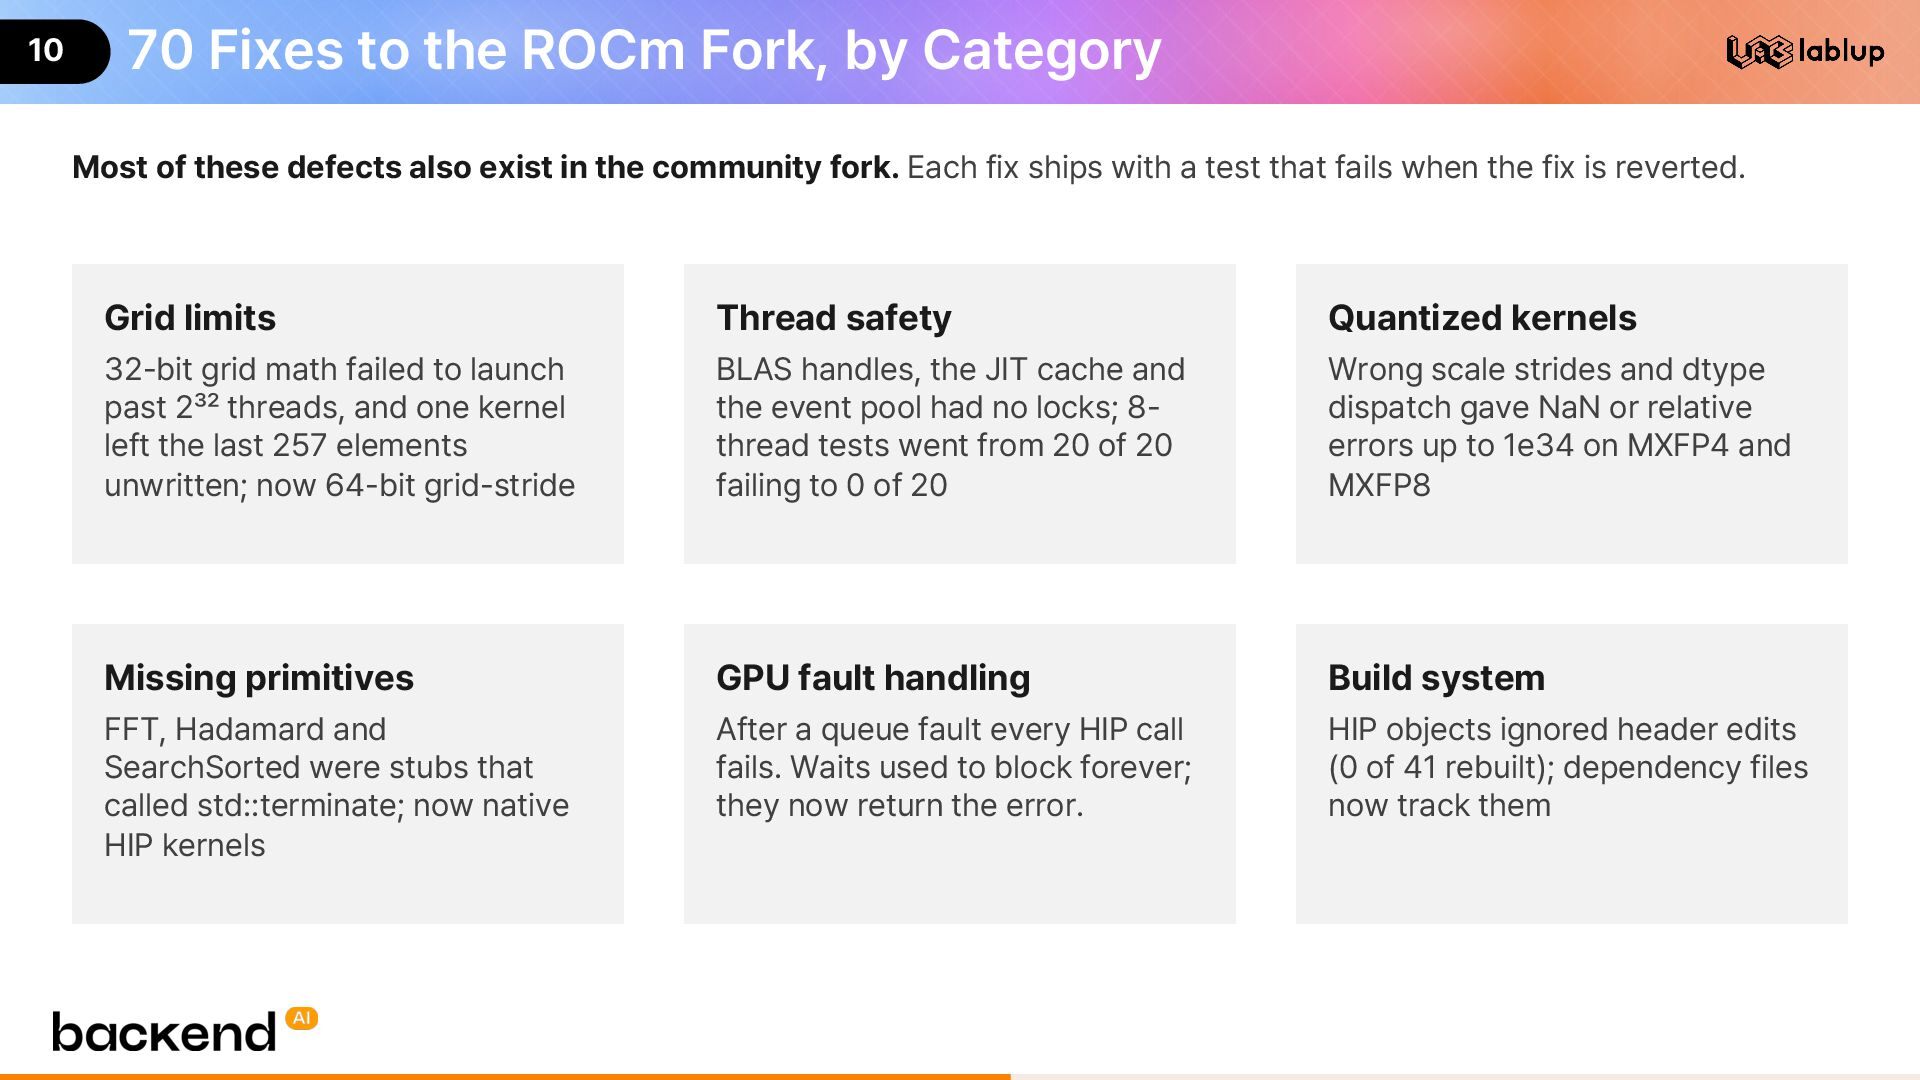
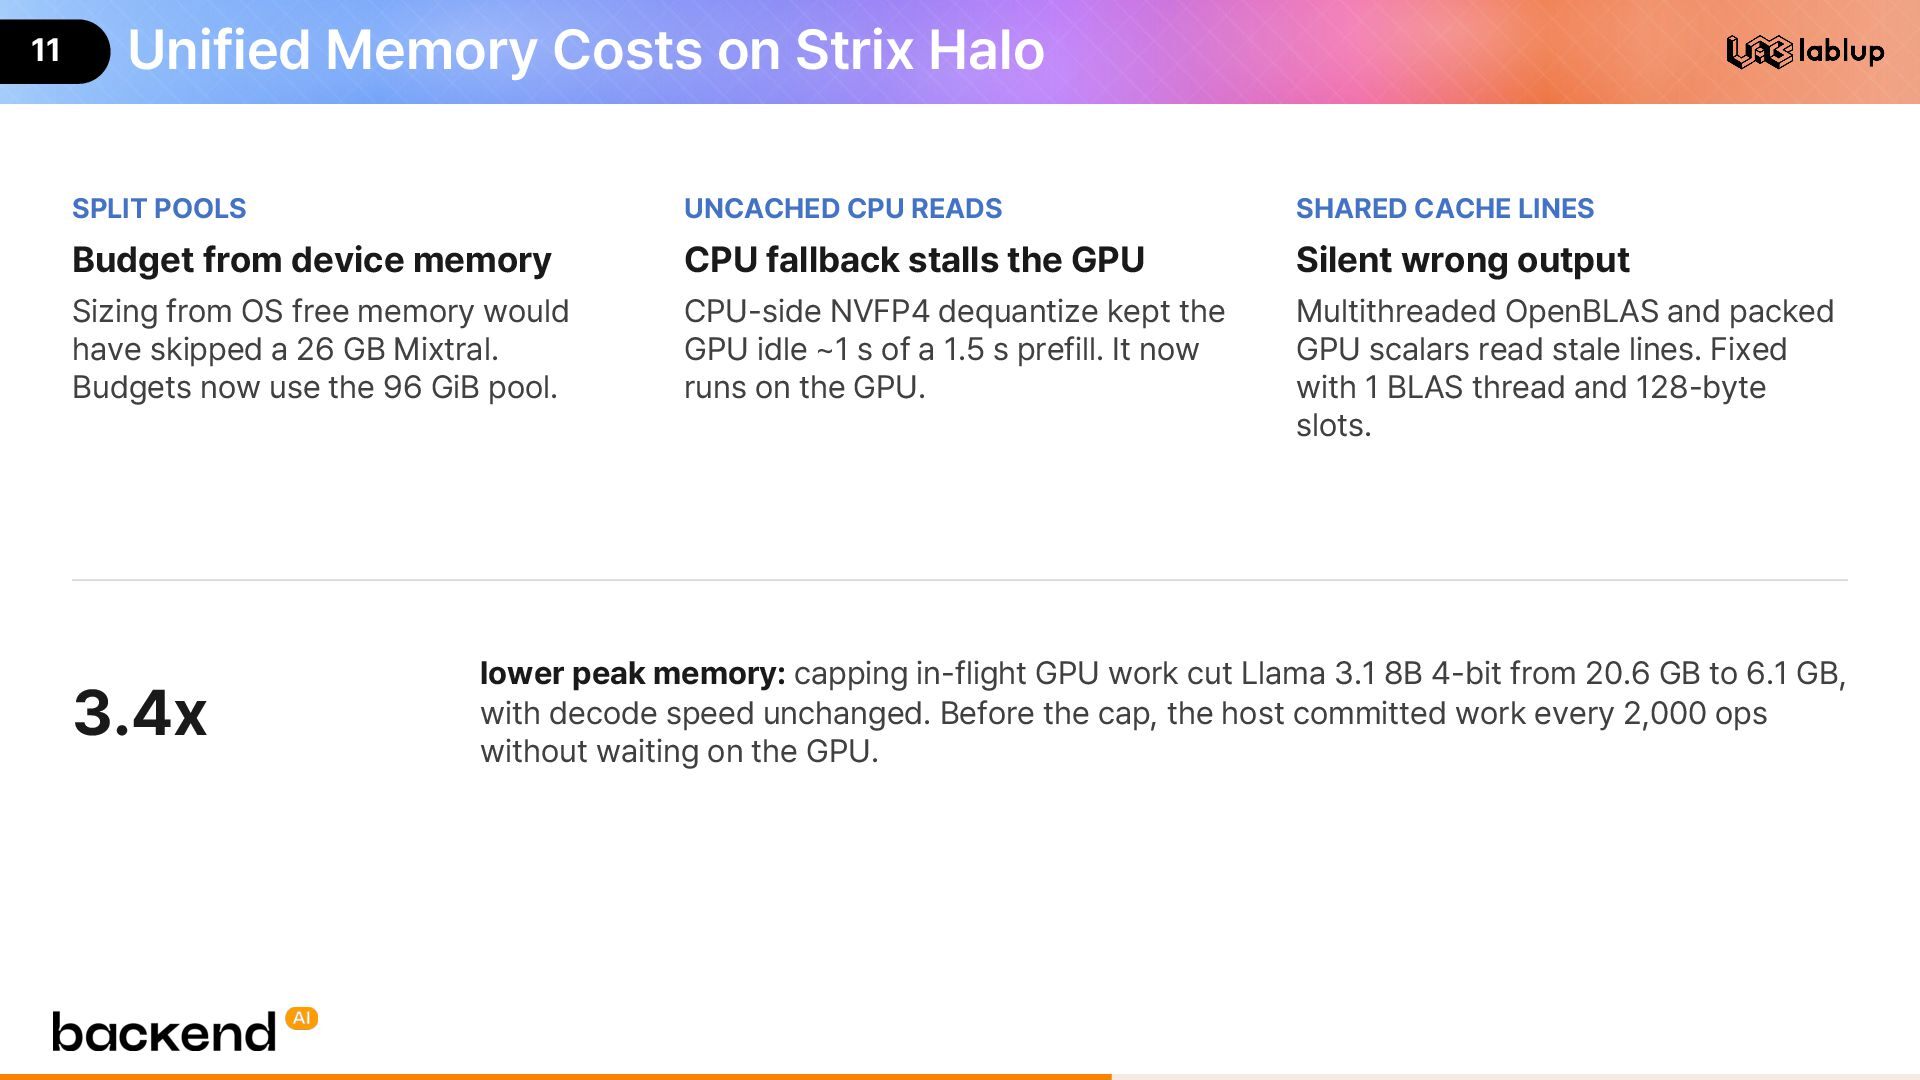
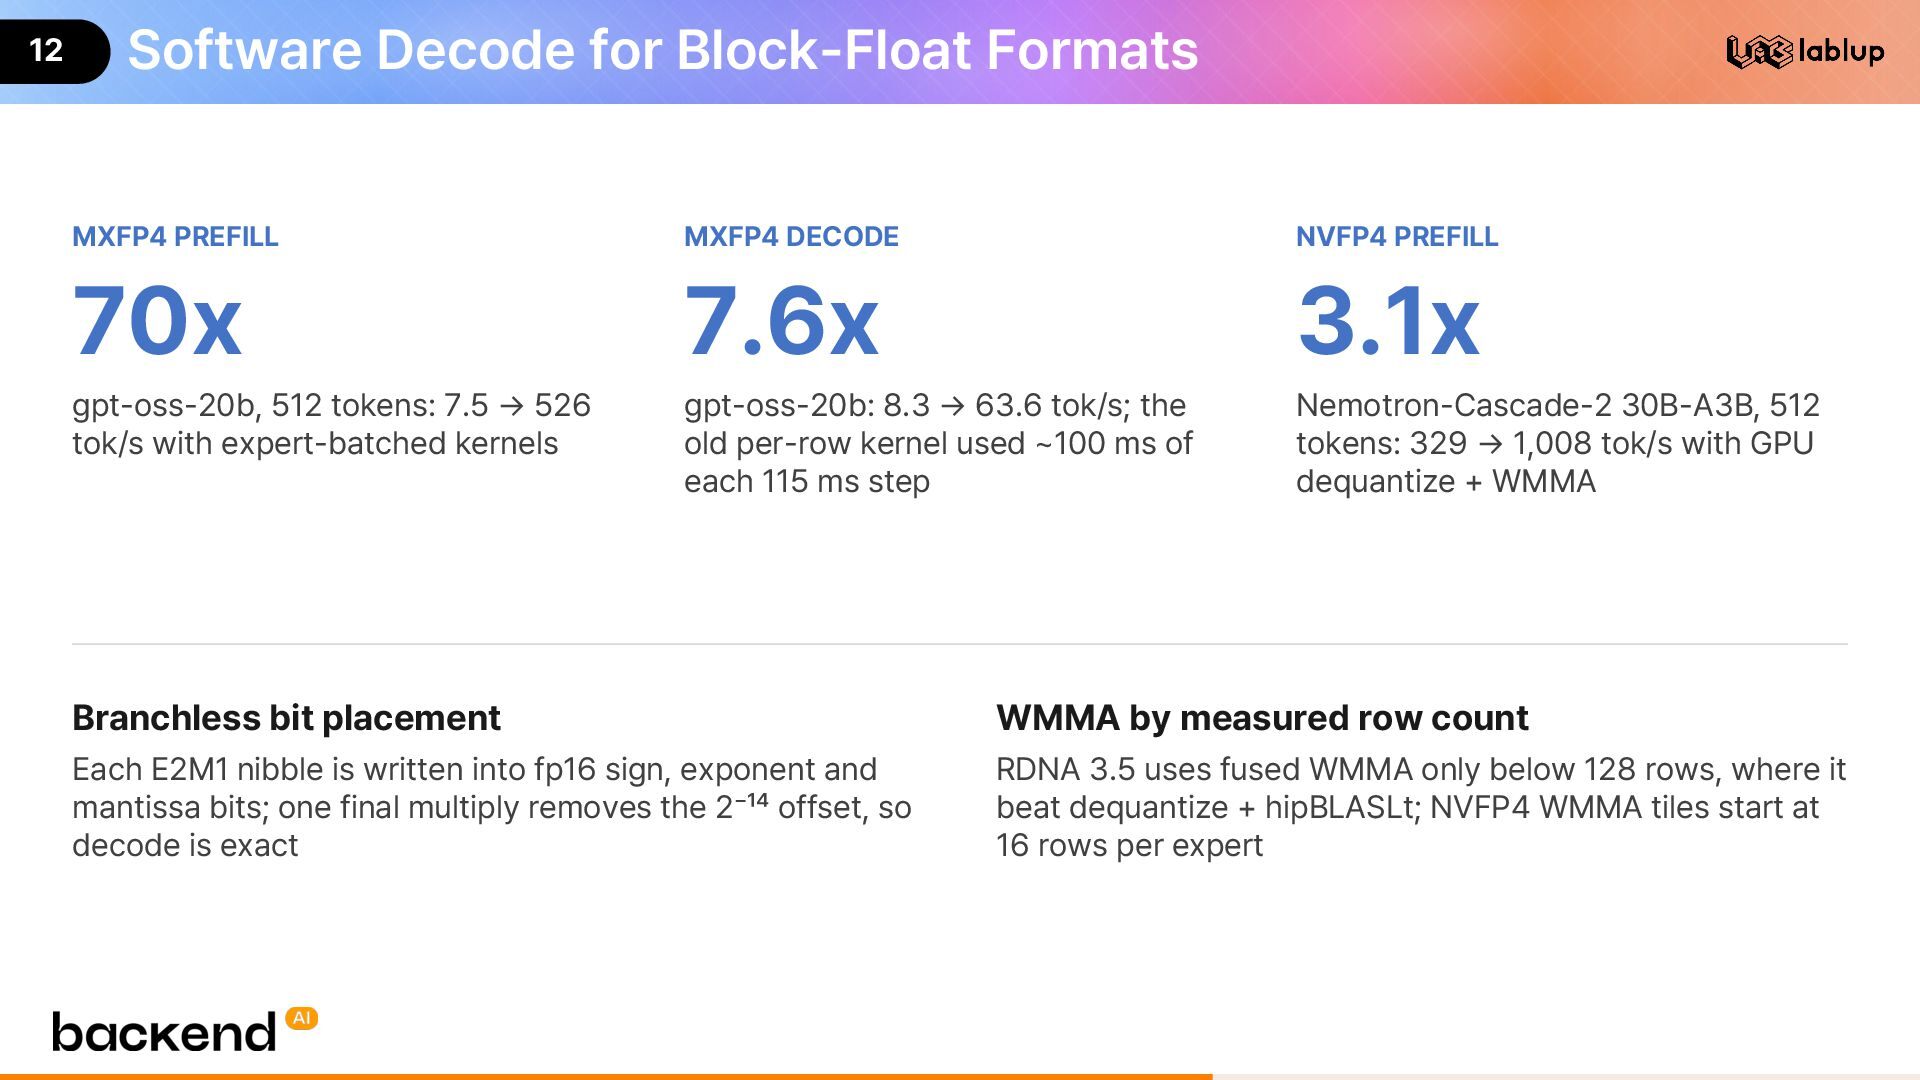
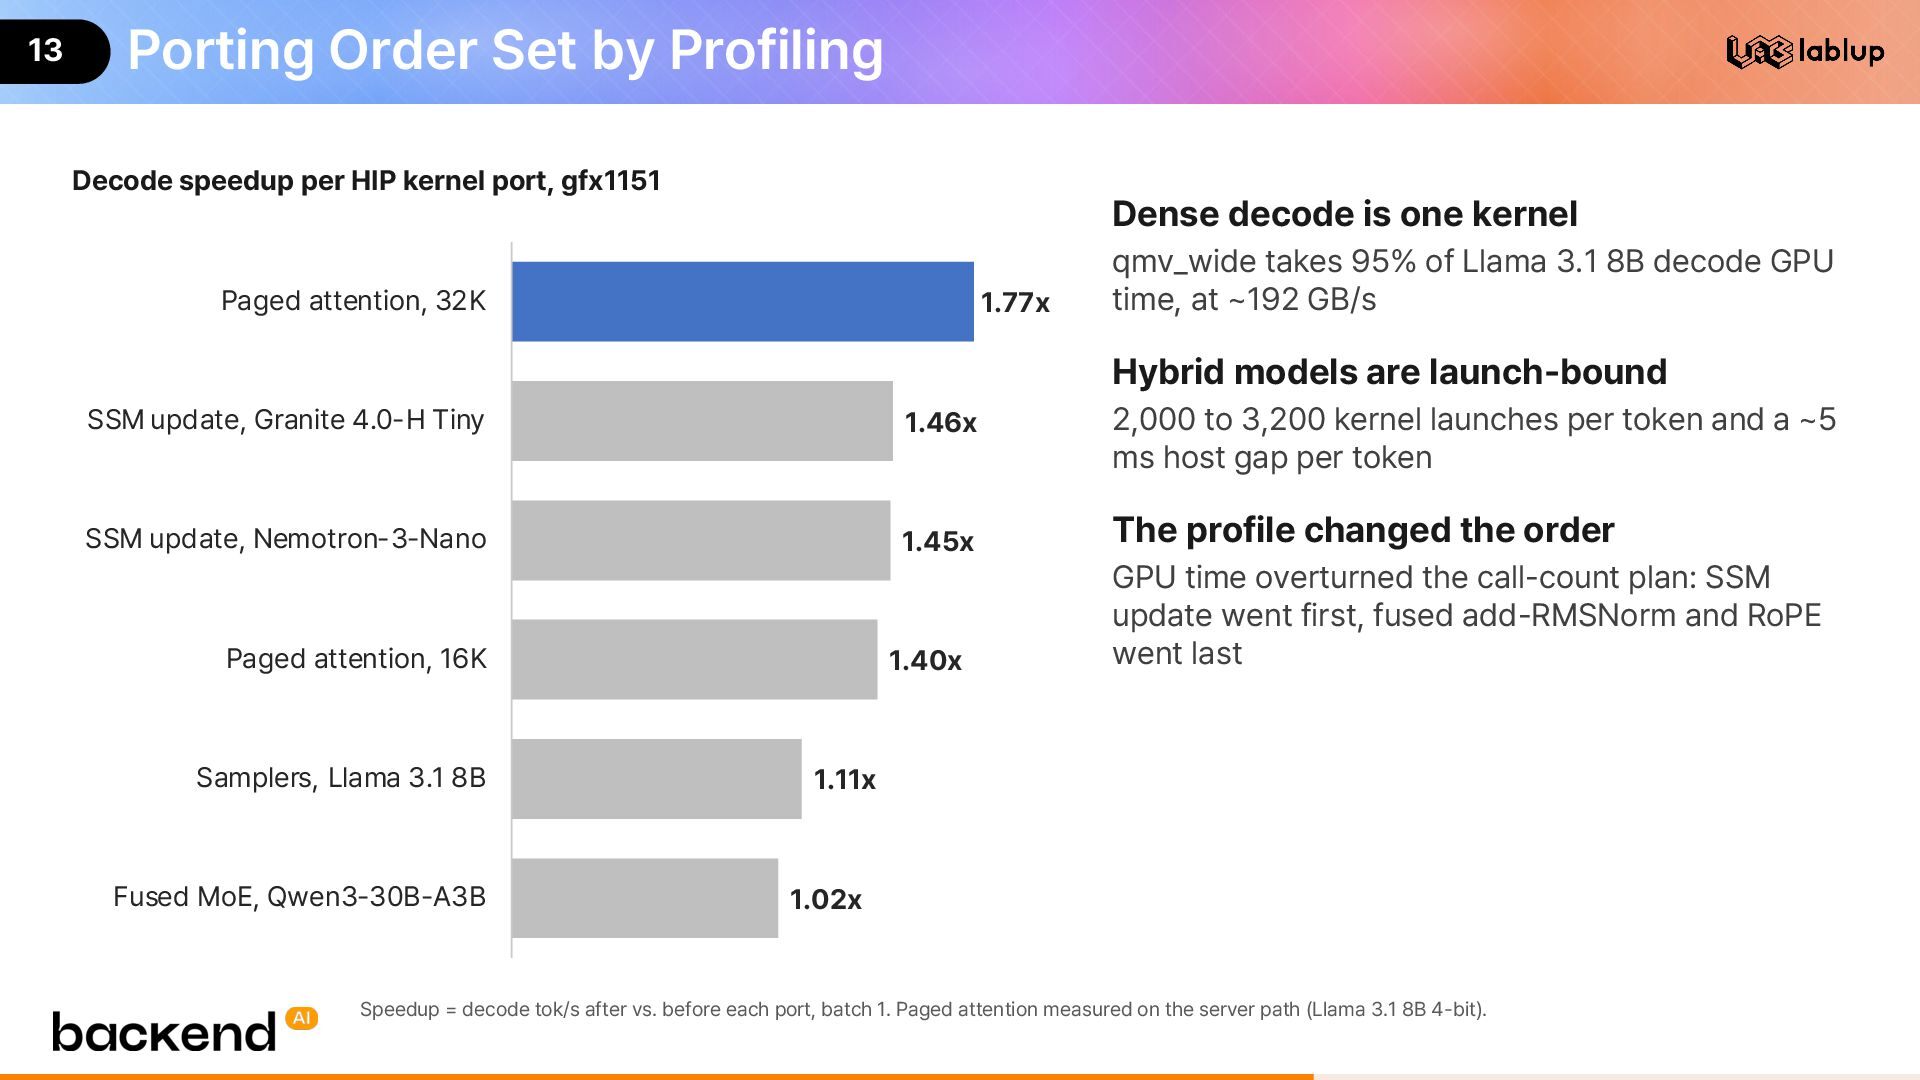
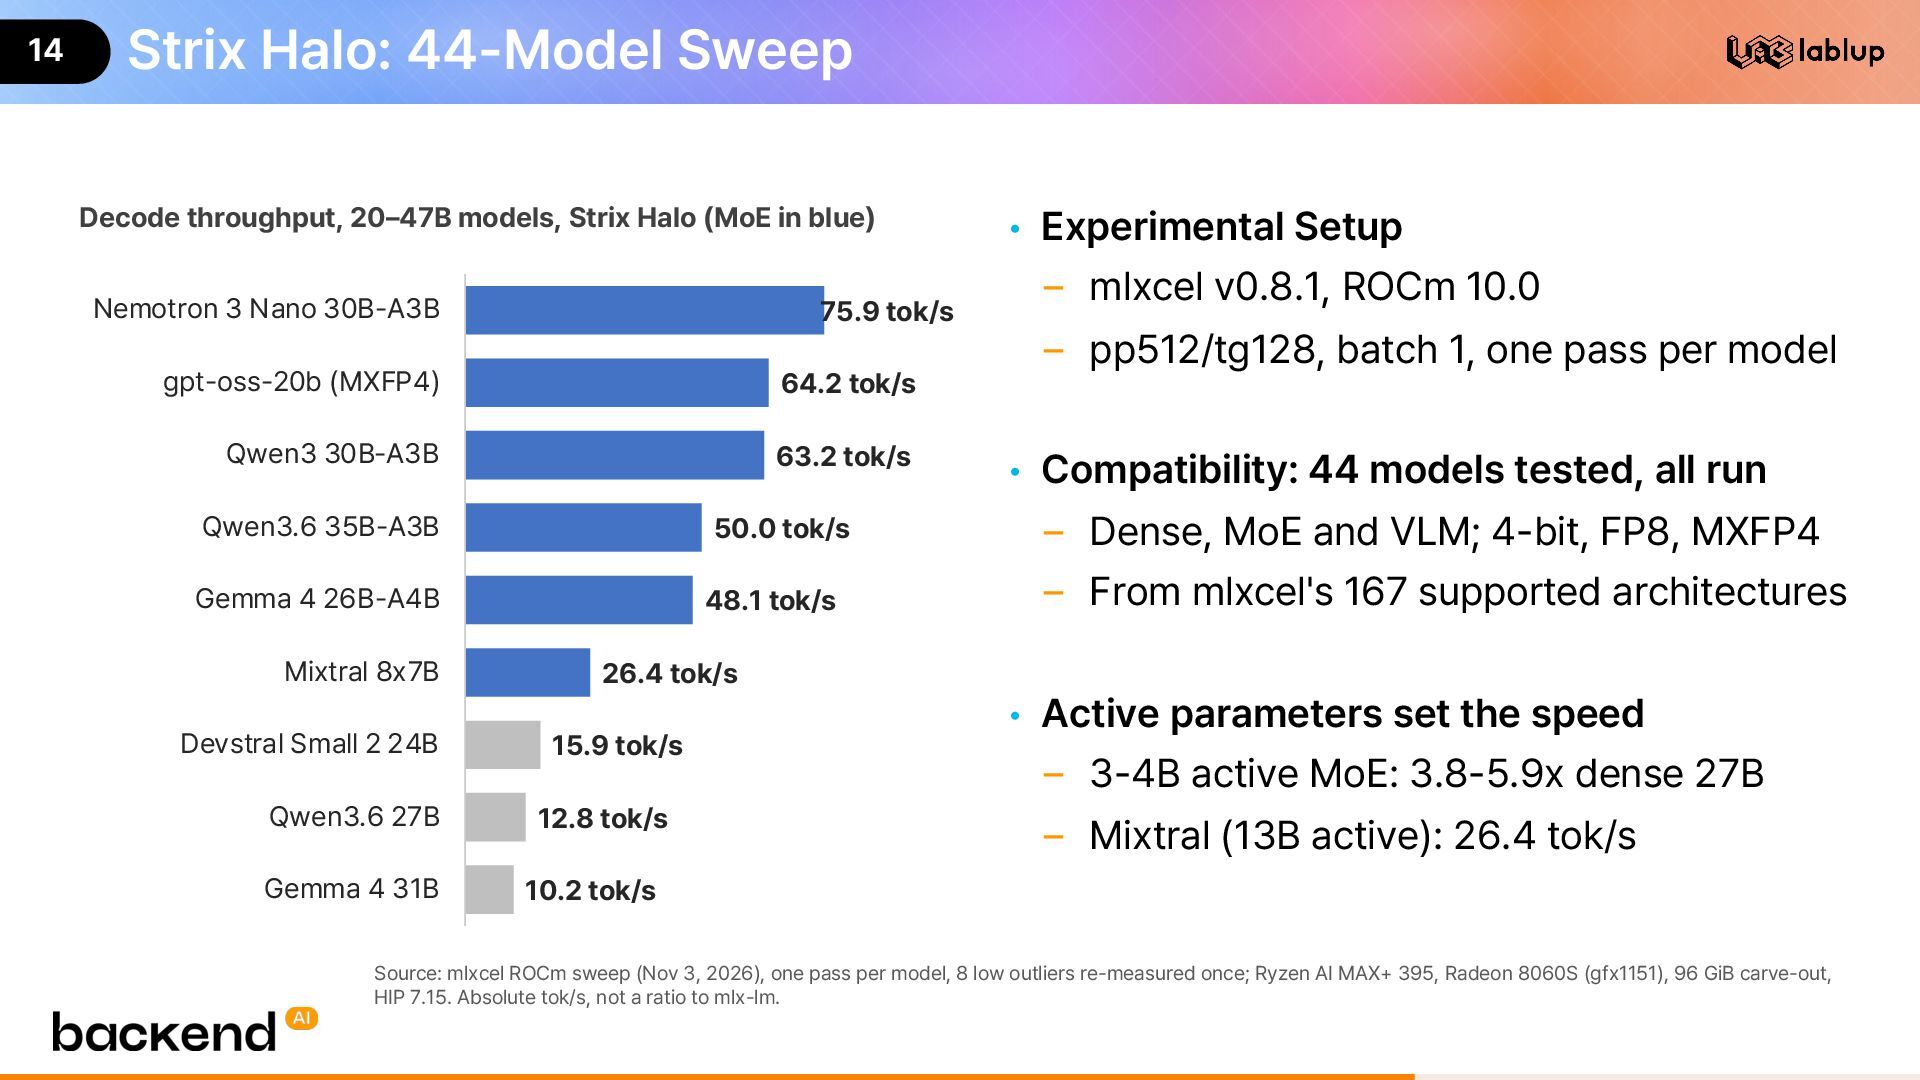
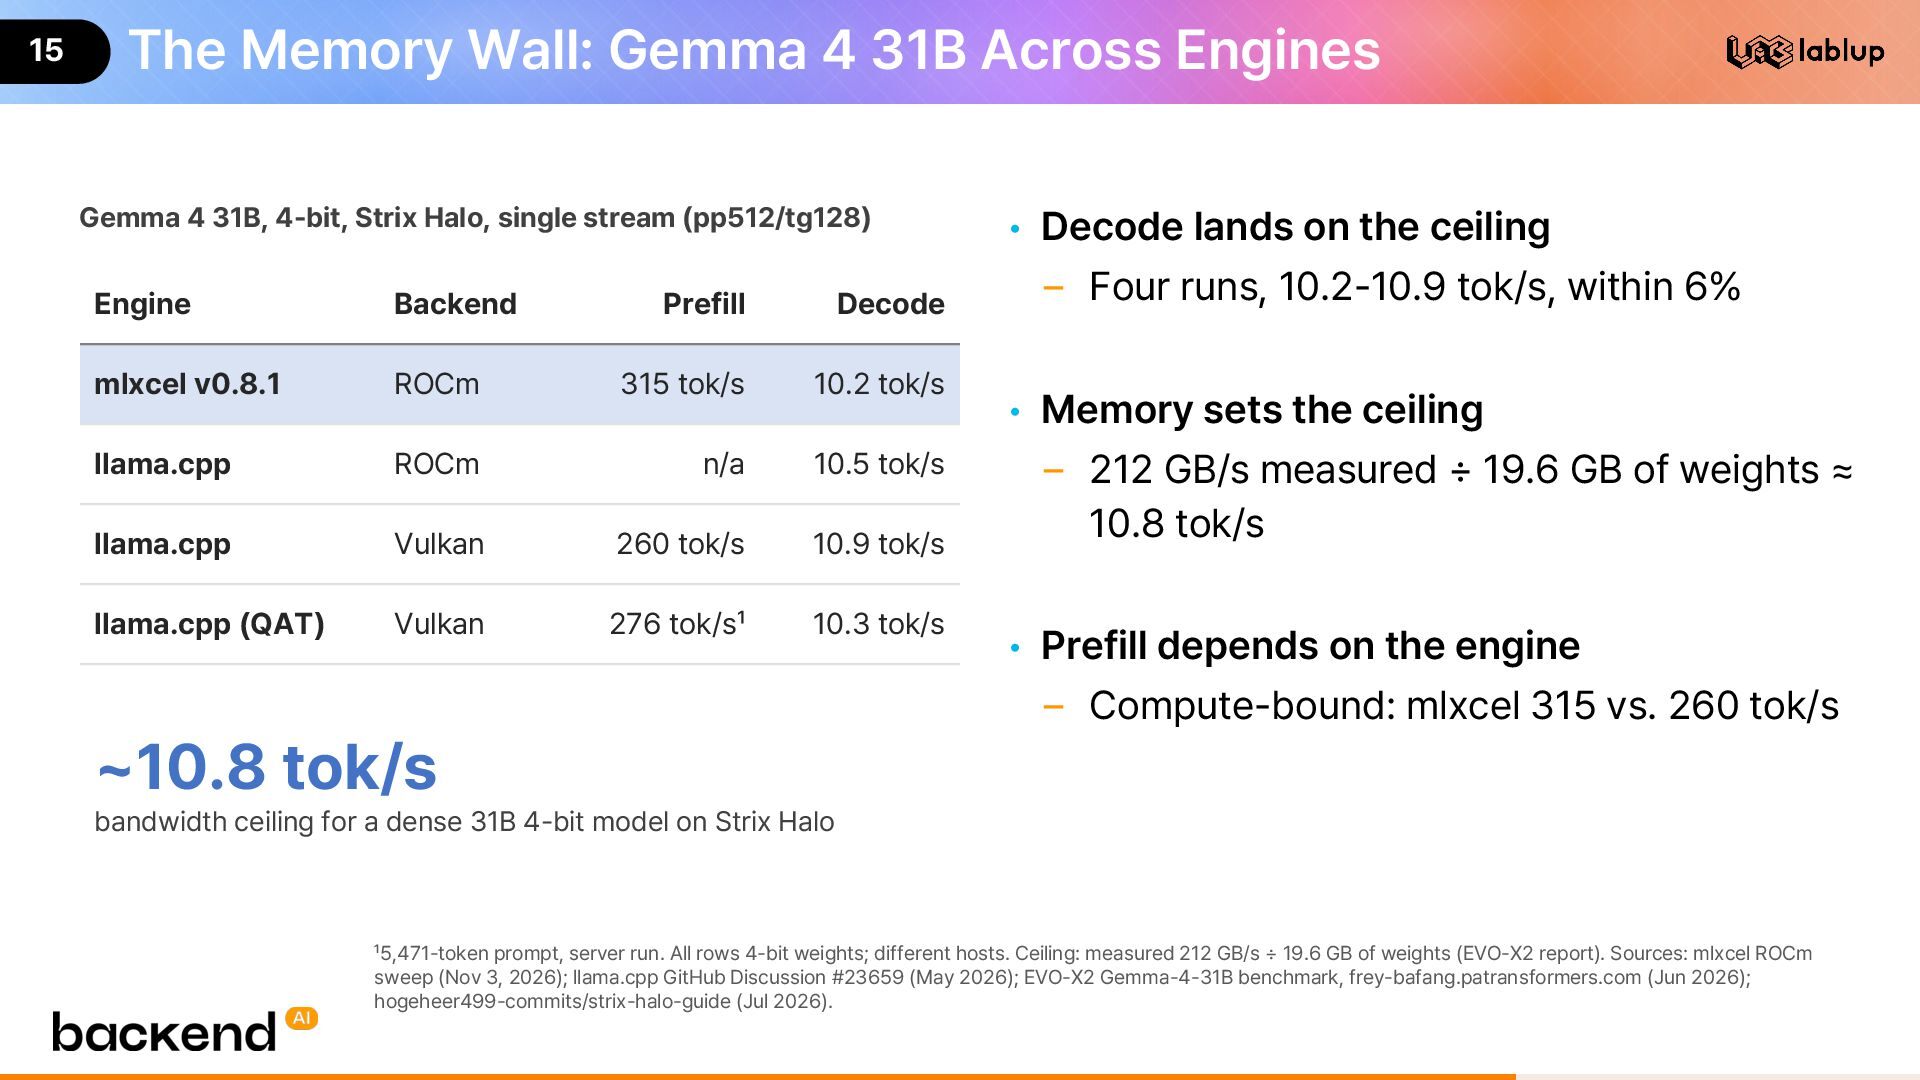
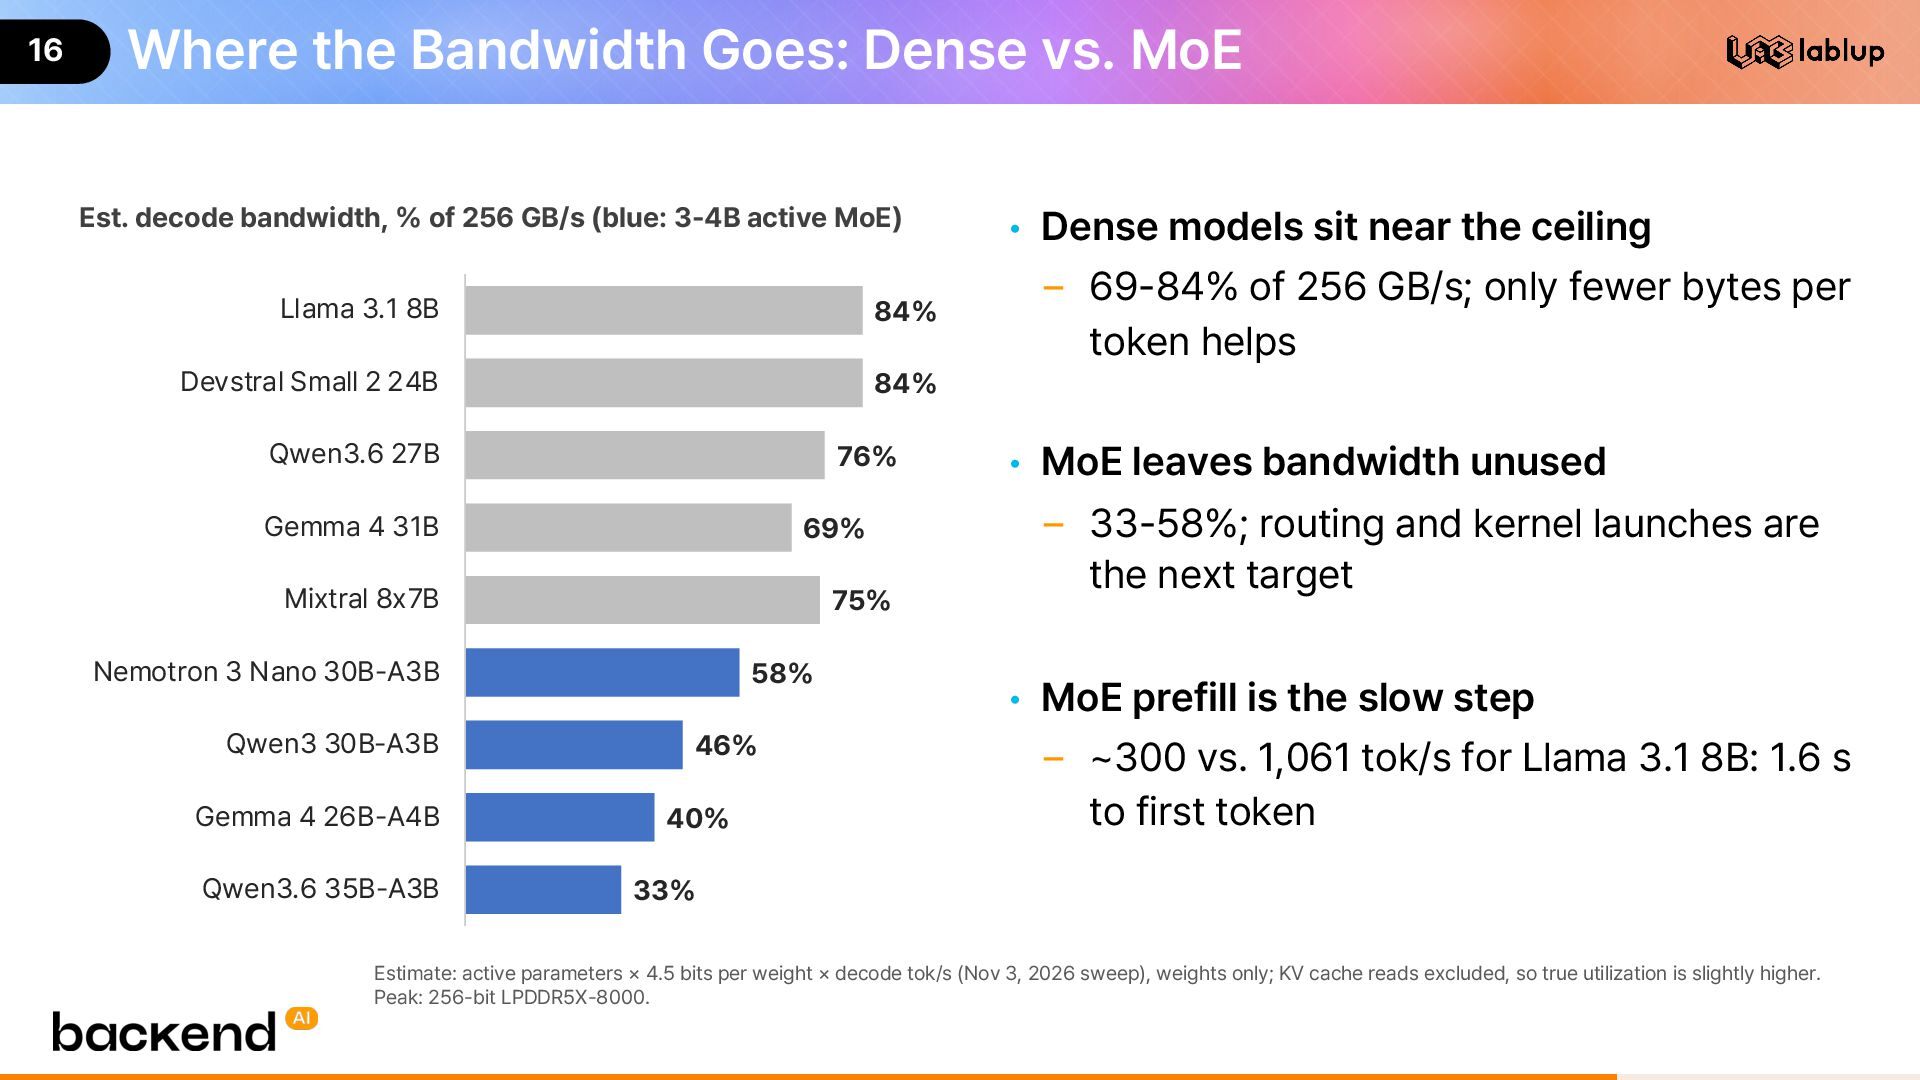
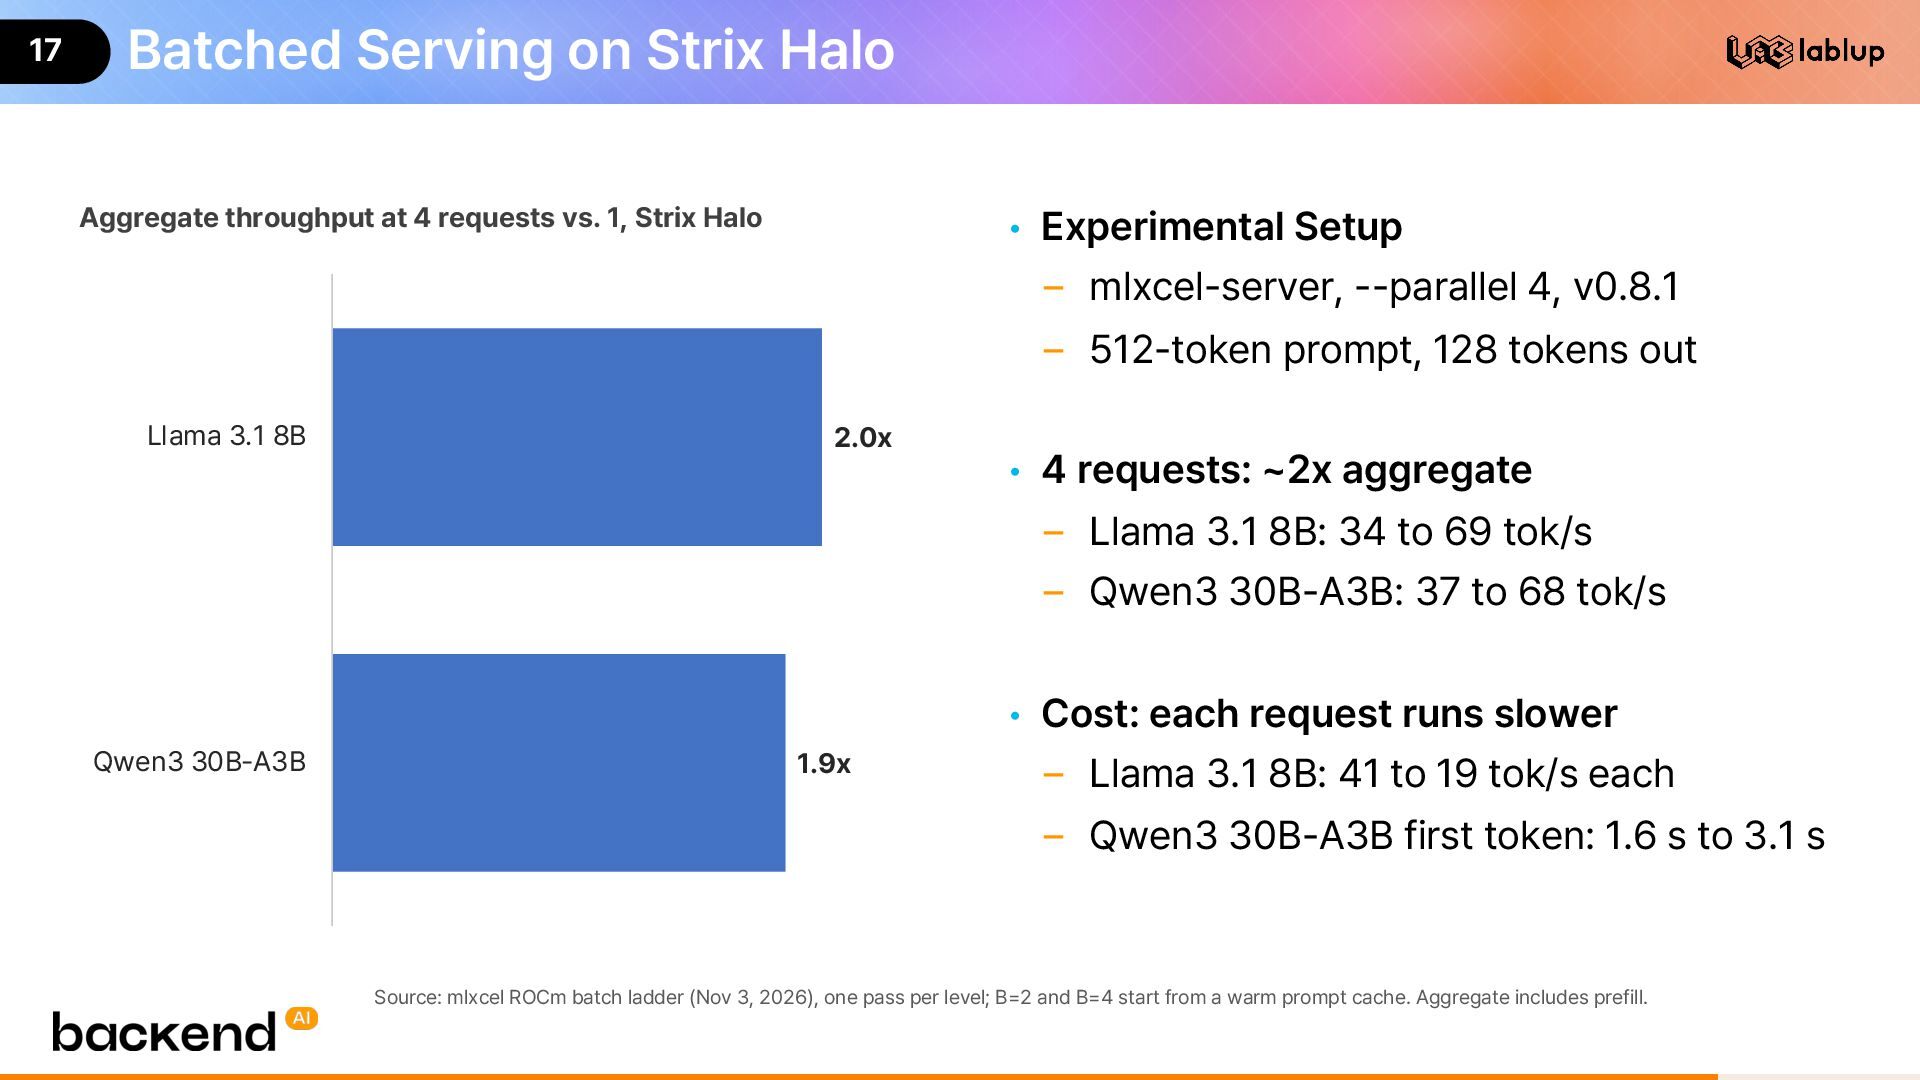
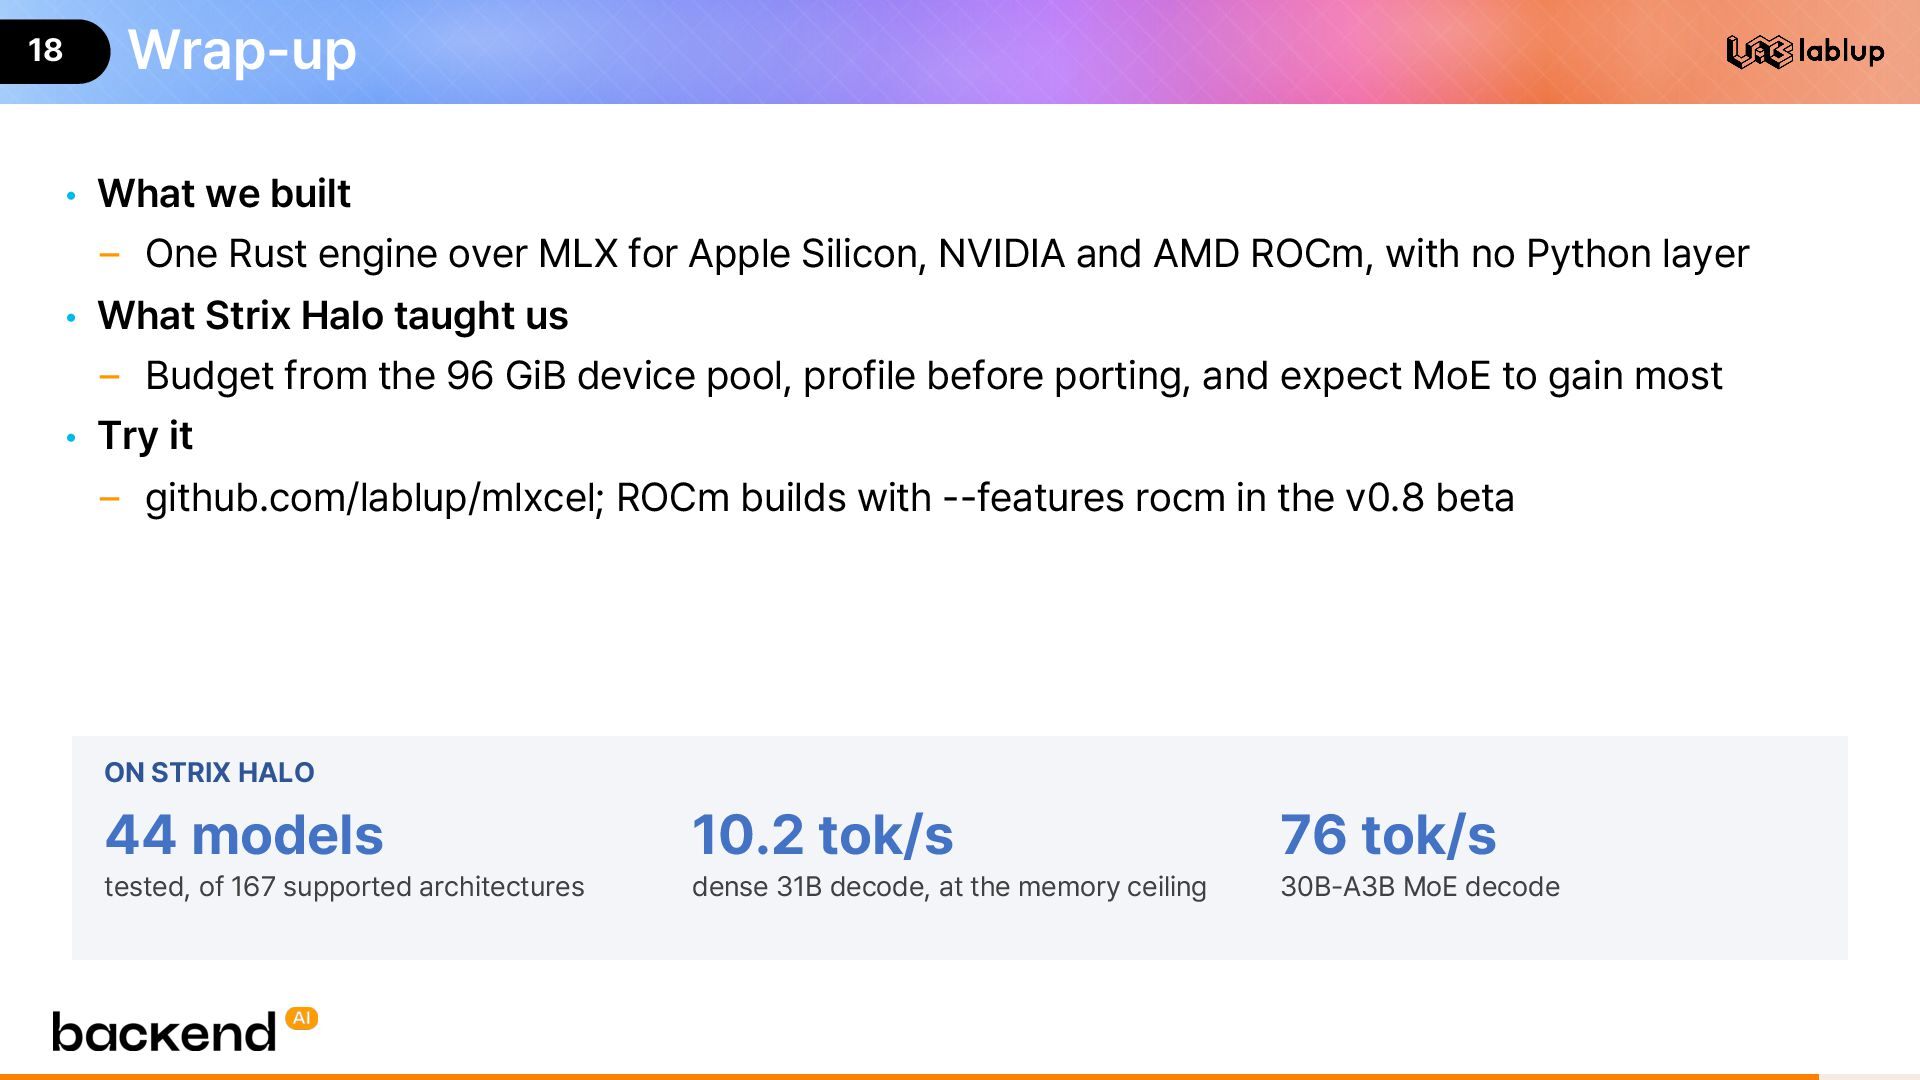
A 96 GiB unified-memory machine like AMD Strix Halo can hold a 30B model in GPU-addressable memory, but most inference engines were built for discrete GPUs and leave the zero-copy path unused. This talk presents mlxcel, a Rust inference engine built on Apple MLX. It serves LLM, VLM, embedding, speech and diffusion workloads with no Python in the request path, and its ROCm backend is now in v0.8 beta. We cover the 70 fixes we made to the community ROCm fork of MLX, the unified-memory problems we hit on RDNA 3.5, and how profiling set the order in which we ported kernels. Decoding block-float weights in software raised MXFP4 prefill on gpt-oss-20b by 70x, and capping in-flight GPU work cut peak memory 3.4x. Across 44 models, dense models reach 69-84% of the memory bandwidth limit: Gemma 4 31B decodes at 10.2 tok/s against a ceiling of about 10.8 tok/s, and a 30B-A3B MoE model reaches 76 tok/s. MoE models still leave a third or more of the bandwidth unused, and that is the next target.


 inureyes
 subroh0508
 masayukisuda
 nori_shinoda
 miu_crescent
 yuukiyo
 hokkai7go
 cmusudakeisuke
 freee
 tatsuyashiraishi
 shunghsiyu
 okamototakuyasr2
 myohei
 katiecoart
 sugarenia
 rasmusluckow
 yeseniaperezcruz
 ryanjones
 techseoconnect
 varn
 marketingsoph
 gurzu
 thekraken
 3n
 emna__ayadi