Share
Embed
[Journal club] AdaMatch: A Unified Approach to Semi-Supervised Learning and Domain Adaptation
Semantic Machine Intelligence Lab., Keio Univ. PRO
May 23, 2023
Transcript
27 slides
-
AdaMatch: A Unified Approach to Semi-Supervised Learning and Domain Adaptation
David Berthelot†∗, Rebecca Roelofs†∗, Kihyuk Sohn†, Nicholas Carlini†, Alex Kurakin† † Google Research, (∗ Equal contribution) 慶應義塾大学 杉浦孔明研究室 小槻誠太郎 ICLR22 Poster D. Berthelot, R. Roelofs, K. Sohn, N. Carlini, and A. Kurakin, “AdaMatch: A Unified Approach to Semi-Supervised Learning and Domain Adaptation,” in ICLR, 2022. -
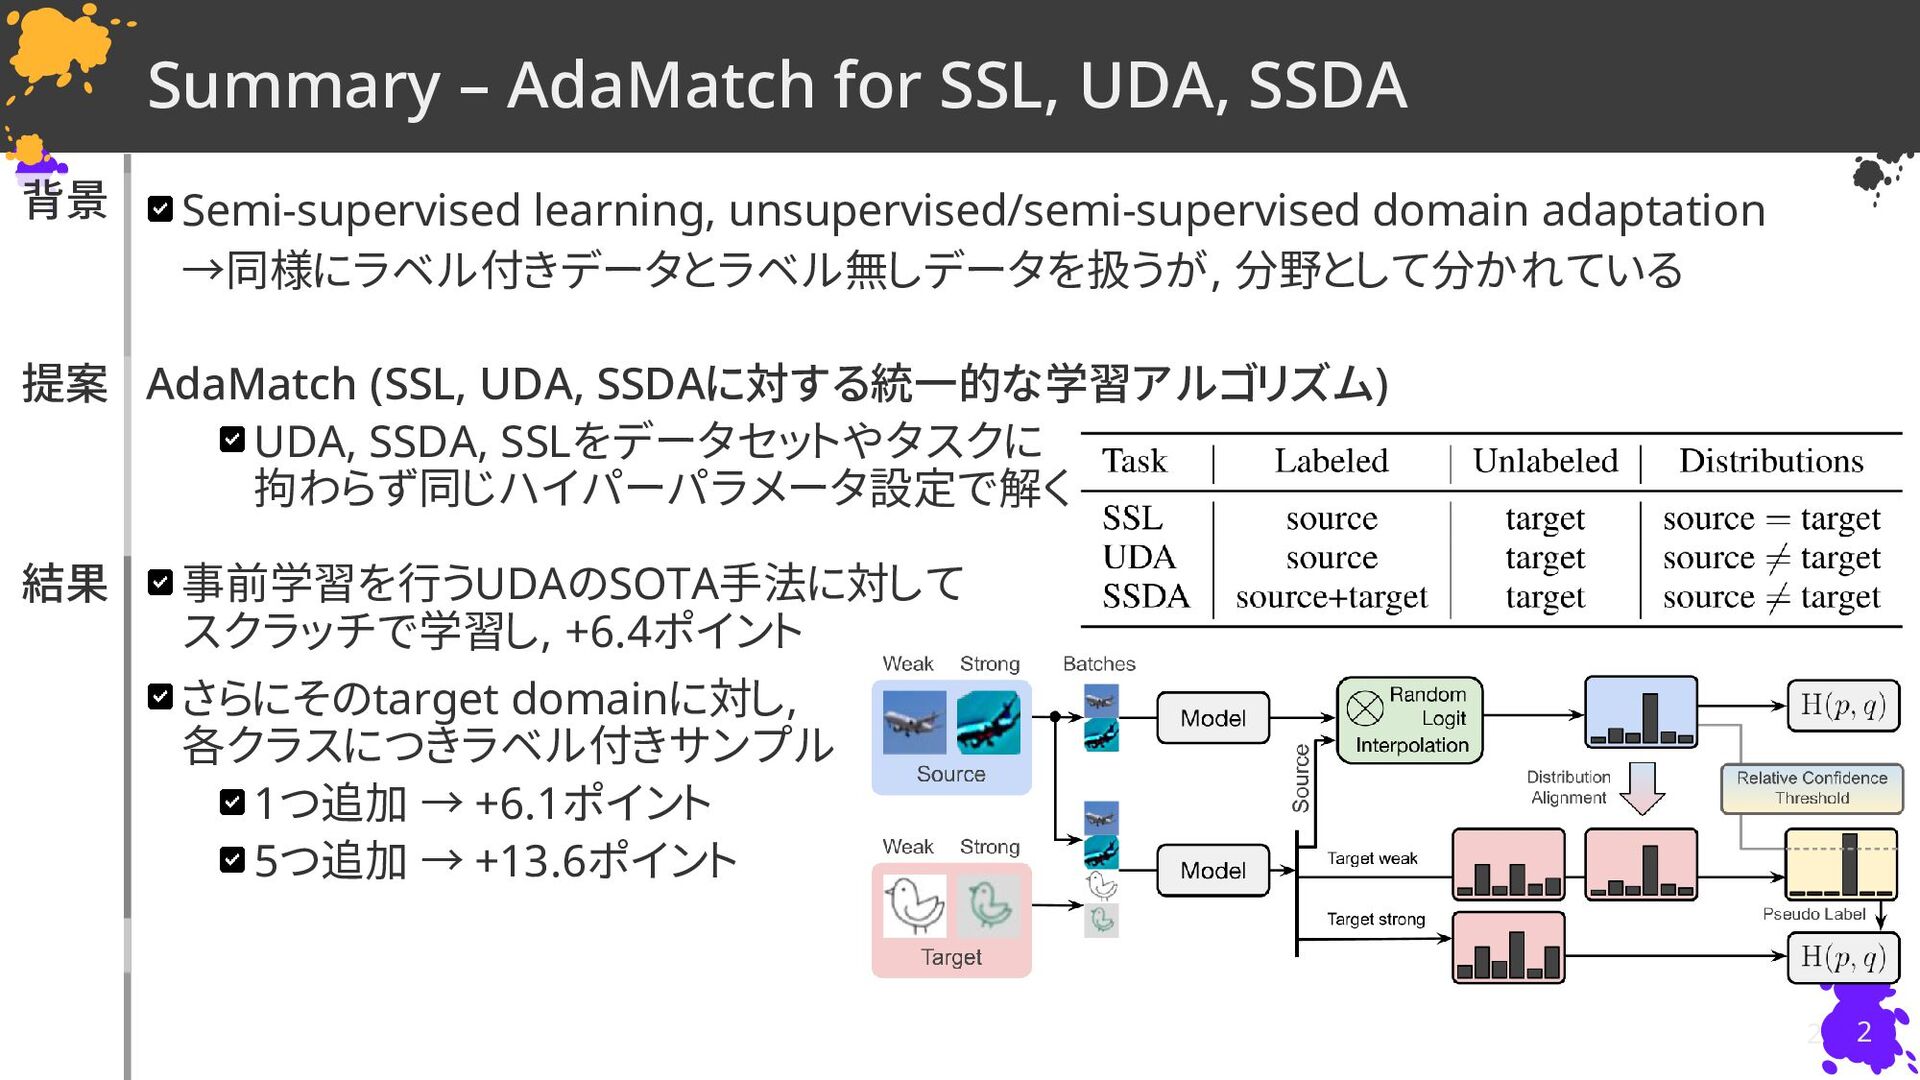
2 Semi-supervised learning, unsupervised/semi-supervised domain adaptation →同様にラベル付きデータとラベル無しデータを扱うが, 分野として分かれている 背景 提案
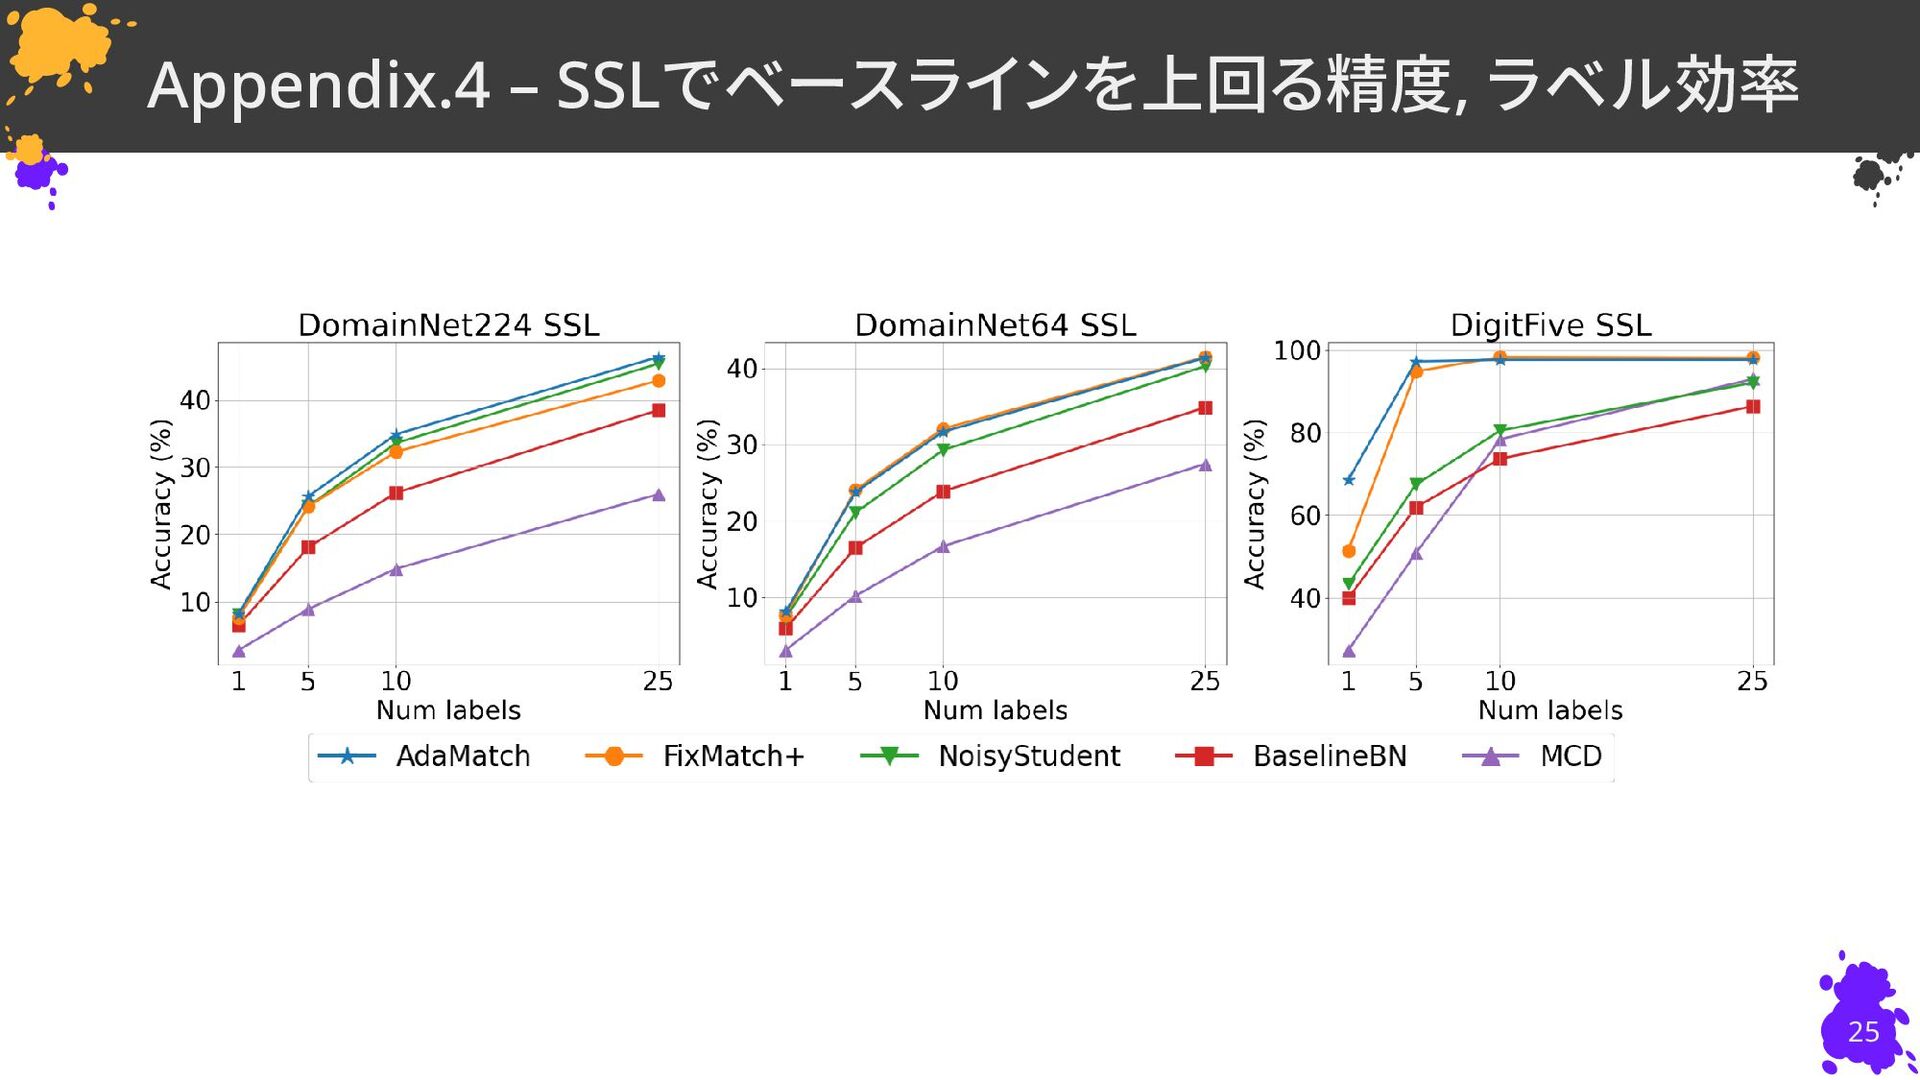
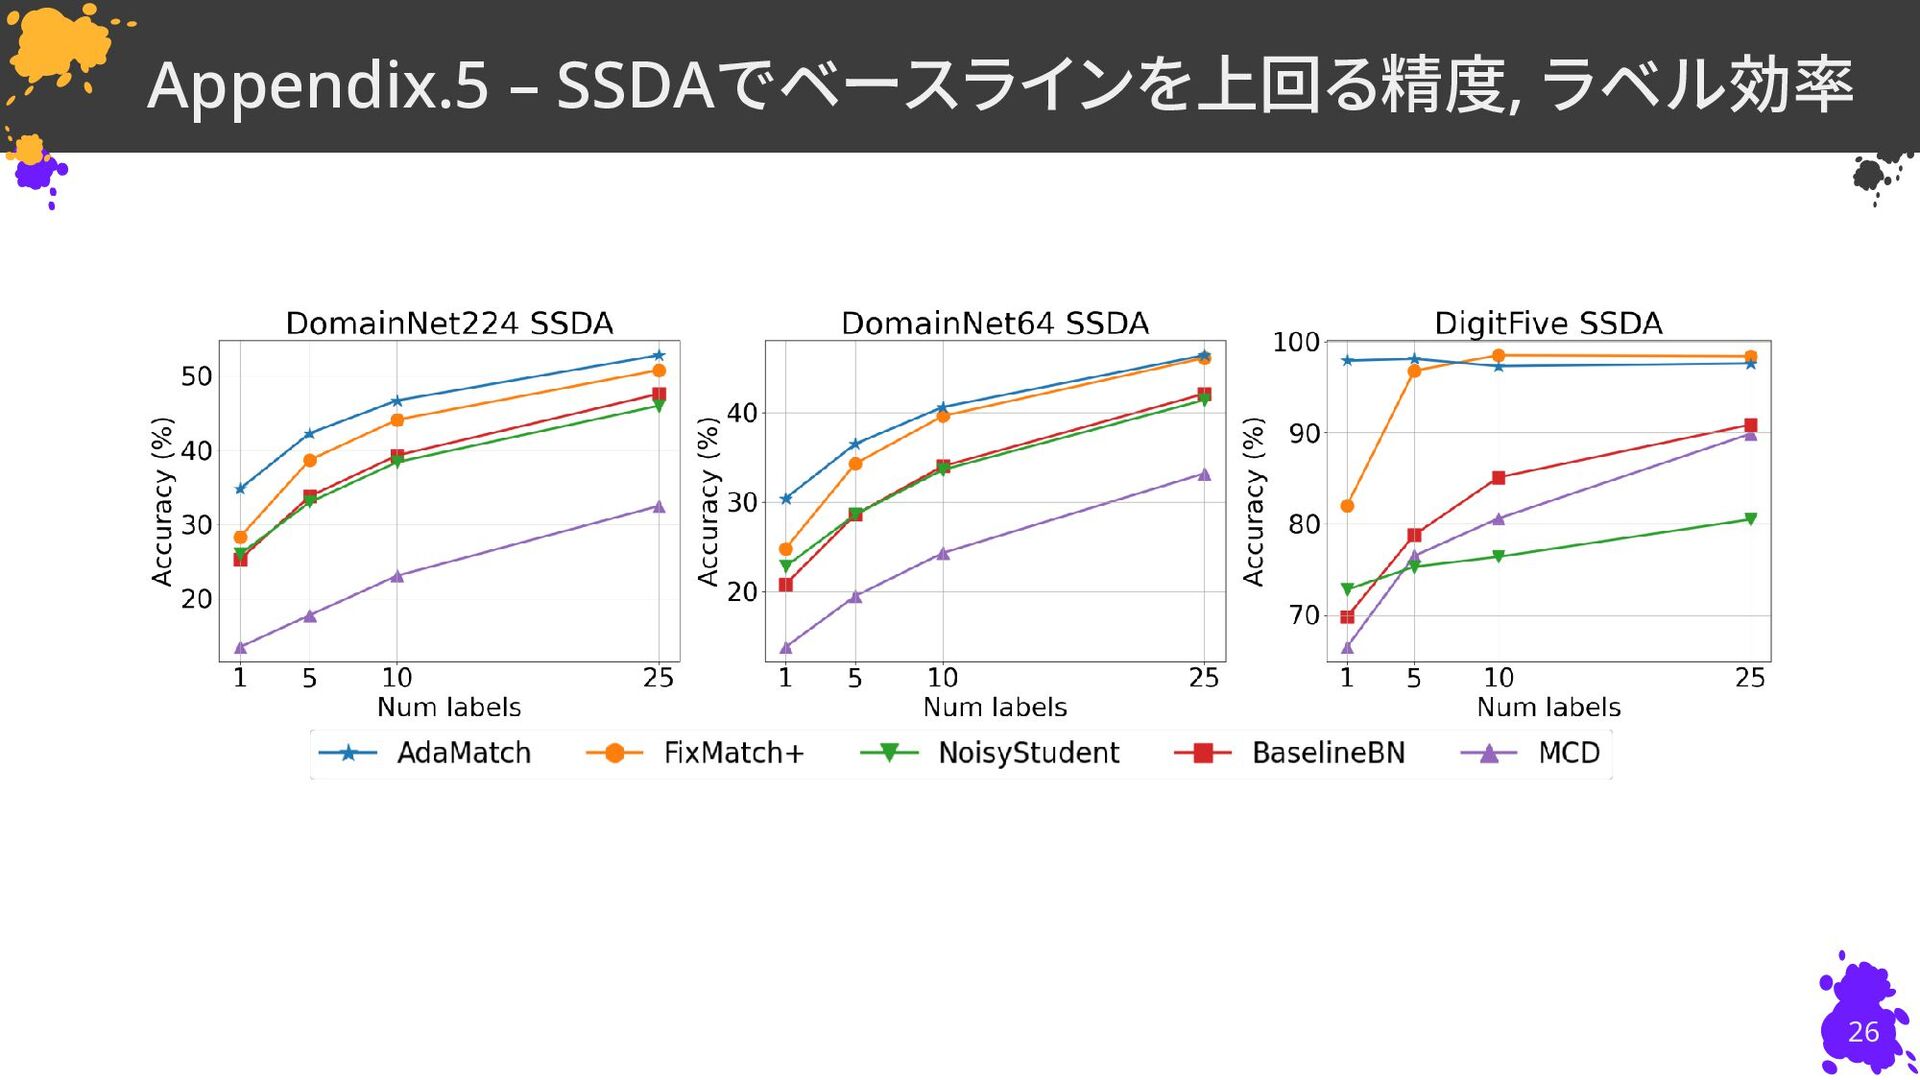
結果 AdaMatch (SSL, UDA, SSDAに対する統一的な学習アルゴリズム) UDA, SSDA, SSLをデータセットやタスクに 拘わらず同じハイパーパラメータ設定で解く 事前学習を行うUDAのSOTA手法に対して スクラッチで学習し, +6.4ポイント さらにそのtarget domainに対し, 各クラスにつきラベル付きサンプル 1つ追加 → +6.1ポイント 5つ追加 → +13.6ポイント Summary – AdaMatch for SSL, UDA, SSDA 2 -
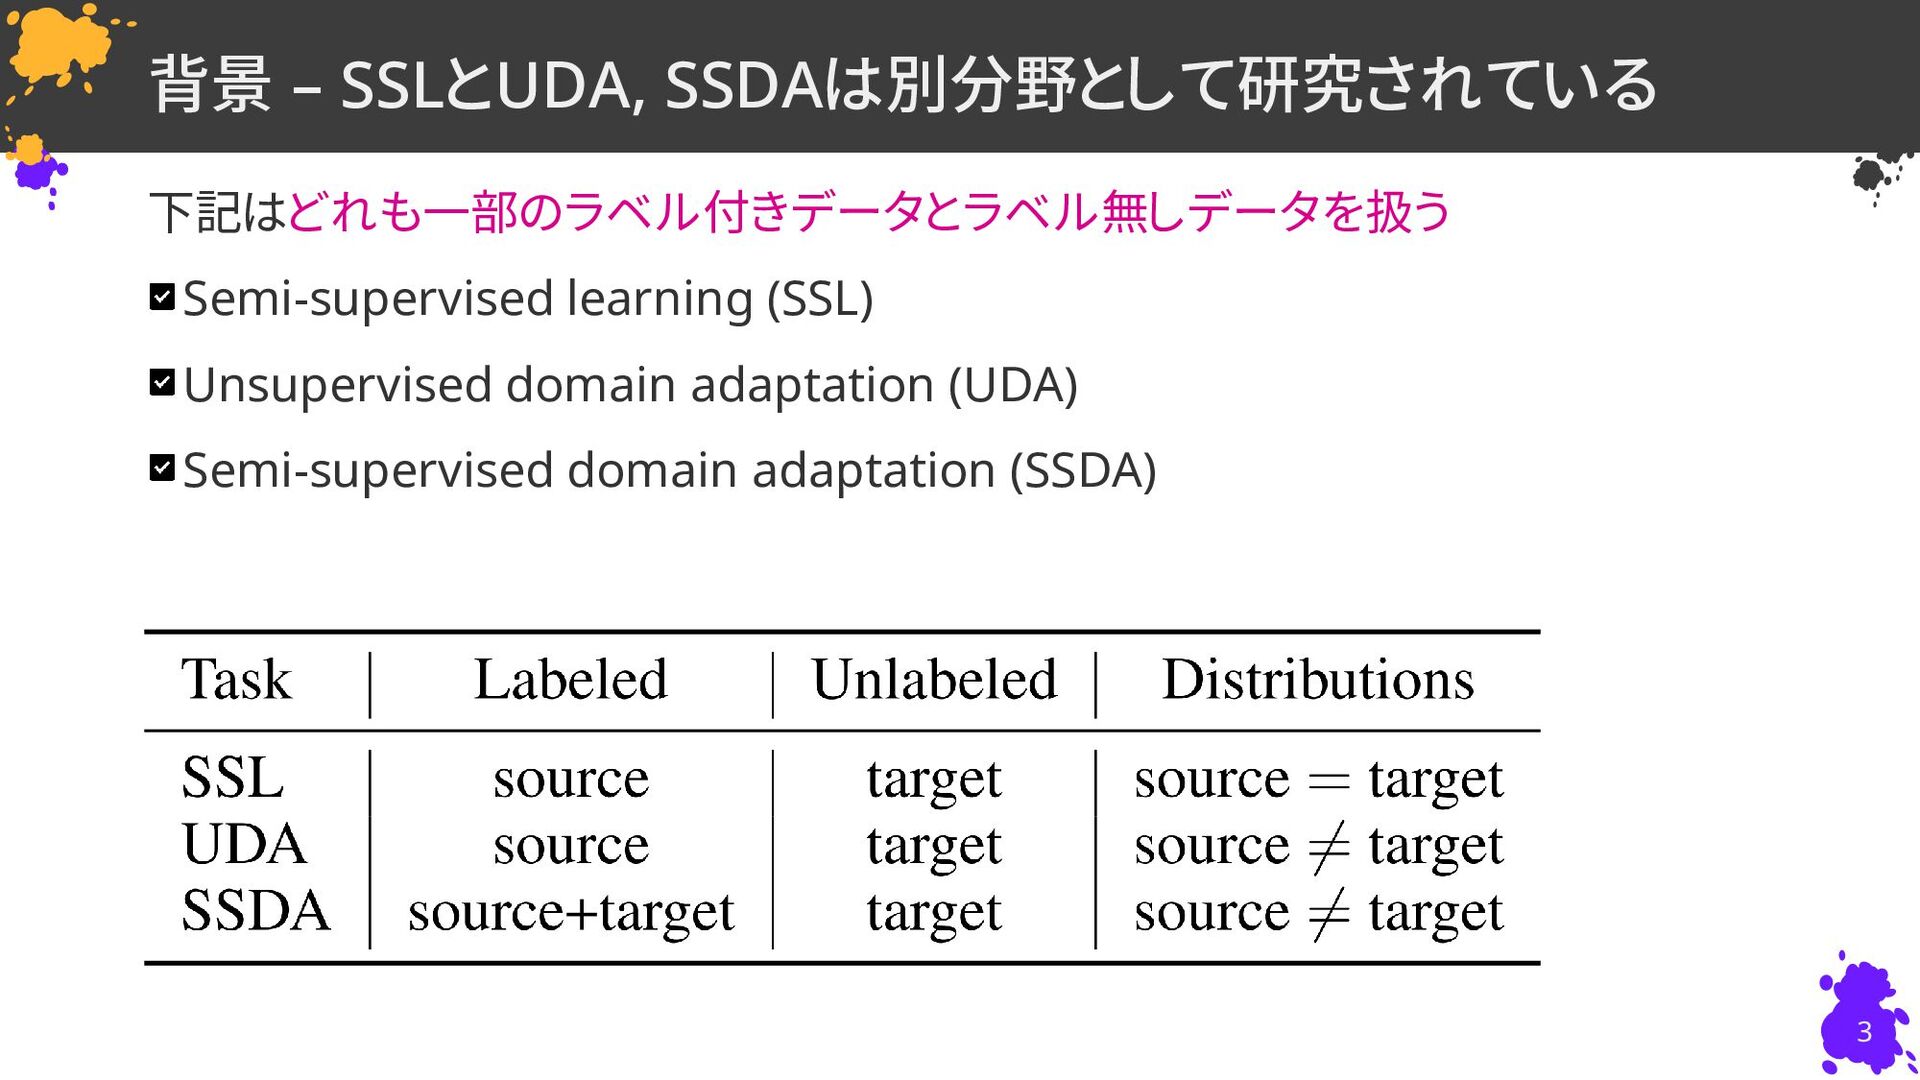
背景 – SSLとUDA, SSDAは別分野として研究されている 下記はどれも一部のラベル付きデータとラベル無しデータを扱う Semi-supervised learning (SSL) Unsupervised domain
adaptation (UDA) Semi-supervised domain adaptation (SSDA) 3 -
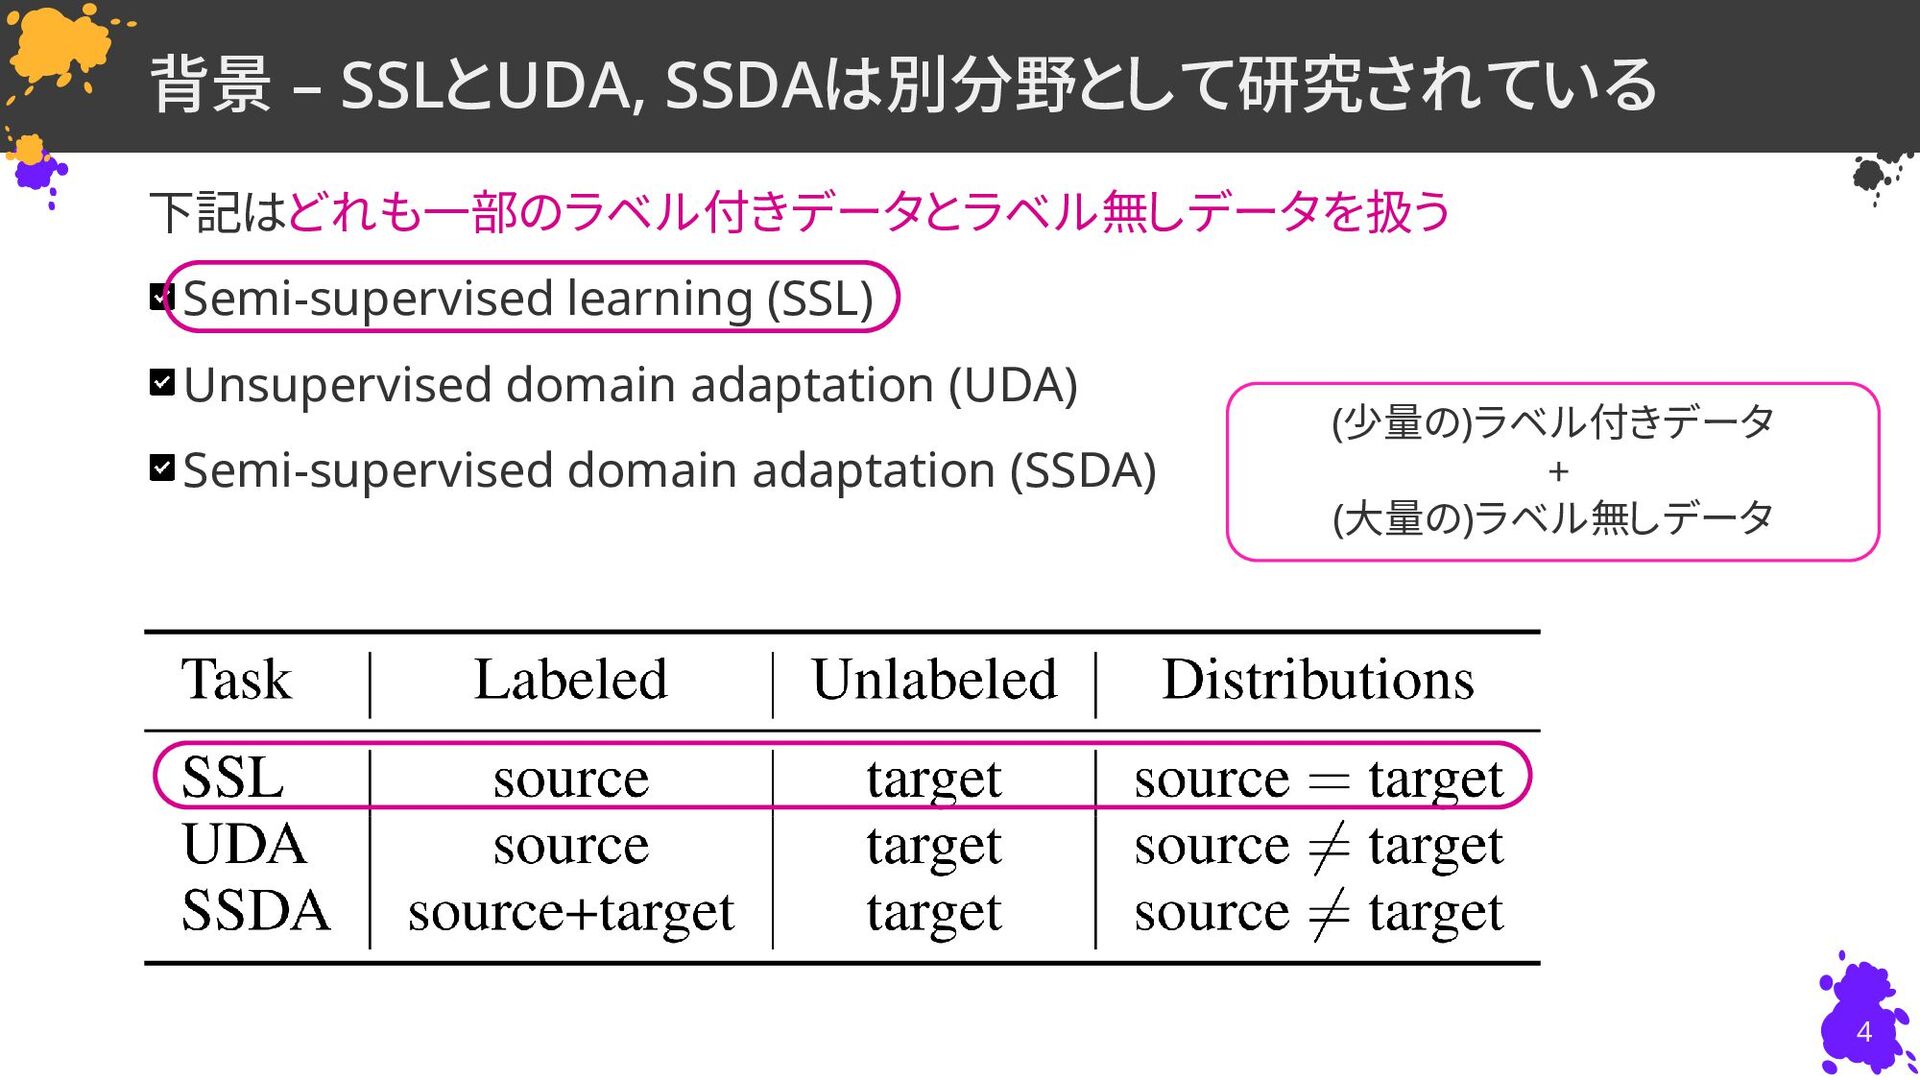
背景 – SSLとUDA, SSDAは別分野として研究されている 下記はどれも一部のラベル付きデータとラベル無しデータを扱う Semi-supervised learning (SSL) Unsupervised domain
adaptation (UDA) Semi-supervised domain adaptation (SSDA) 4 (少量の)ラベル付きデータ + (大量の)ラベル無しデータ -
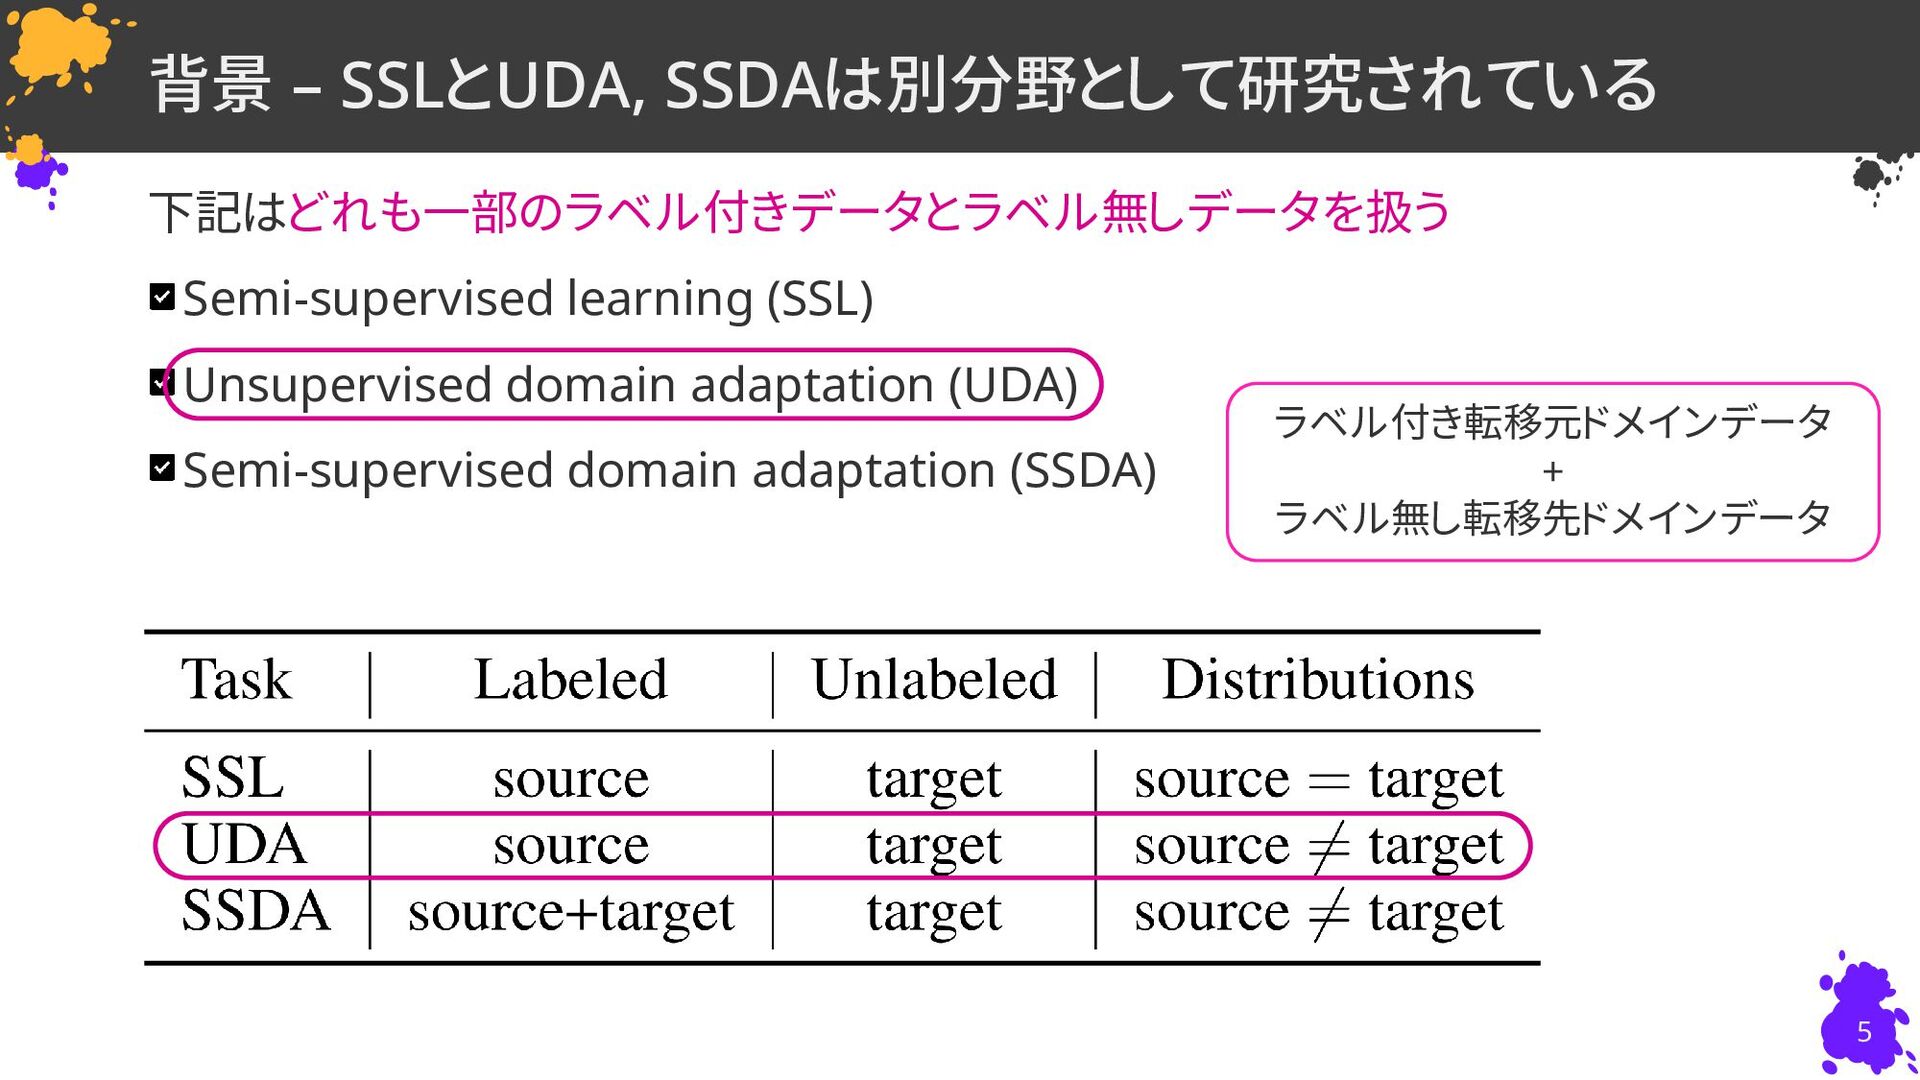
背景 – SSLとUDA, SSDAは別分野として研究されている 下記はどれも一部のラベル付きデータとラベル無しデータを扱う Semi-supervised learning (SSL) Unsupervised domain
adaptation (UDA) Semi-supervised domain adaptation (SSDA) 5 ラベル付き転移元ドメインデータ + ラベル無し転移先ドメインデータ -
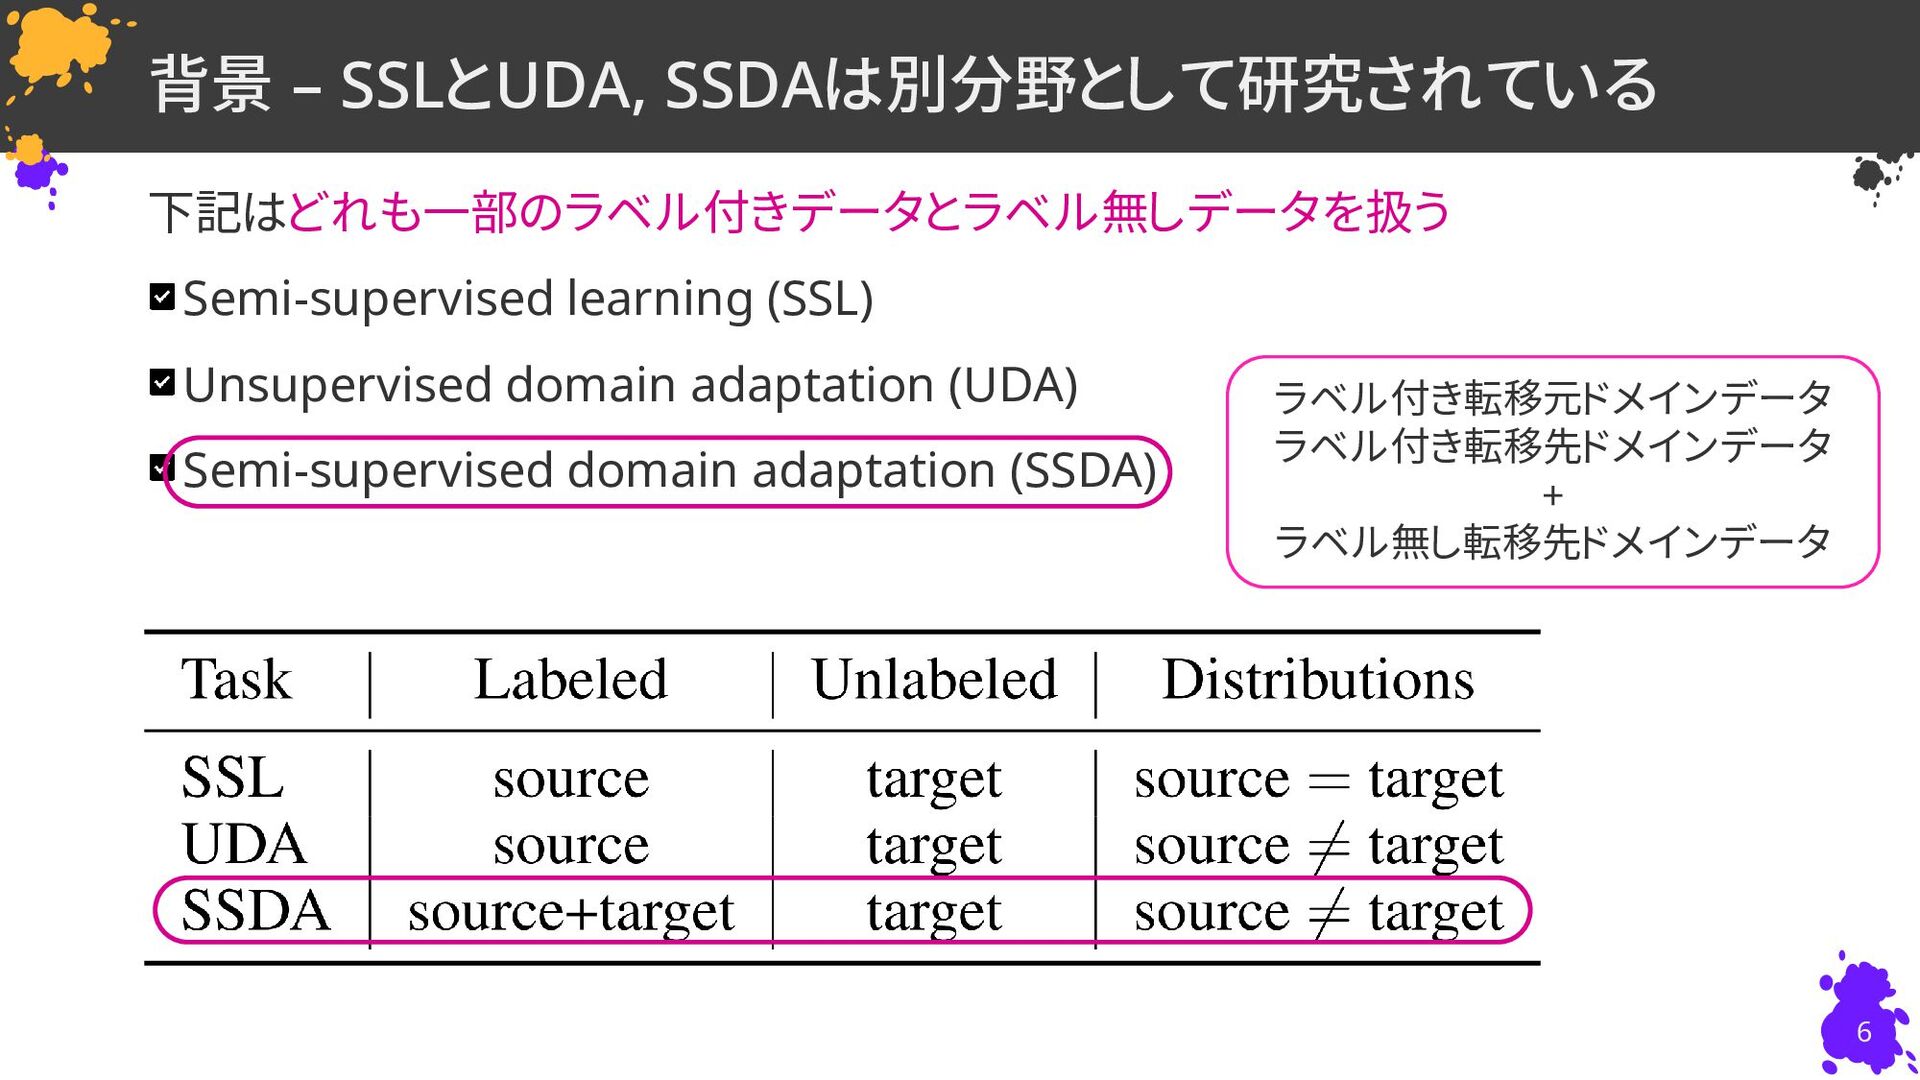
背景 – SSLとUDA, SSDAは別分野として研究されている 下記はどれも一部のラベル付きデータとラベル無しデータを扱う Semi-supervised learning (SSL) Unsupervised domain
adaptation (UDA) Semi-supervised domain adaptation (SSDA) 6 ラベル付き転移元ドメインデータ ラベル付き転移先ドメインデータ + ラベル無し転移先ドメインデータ -
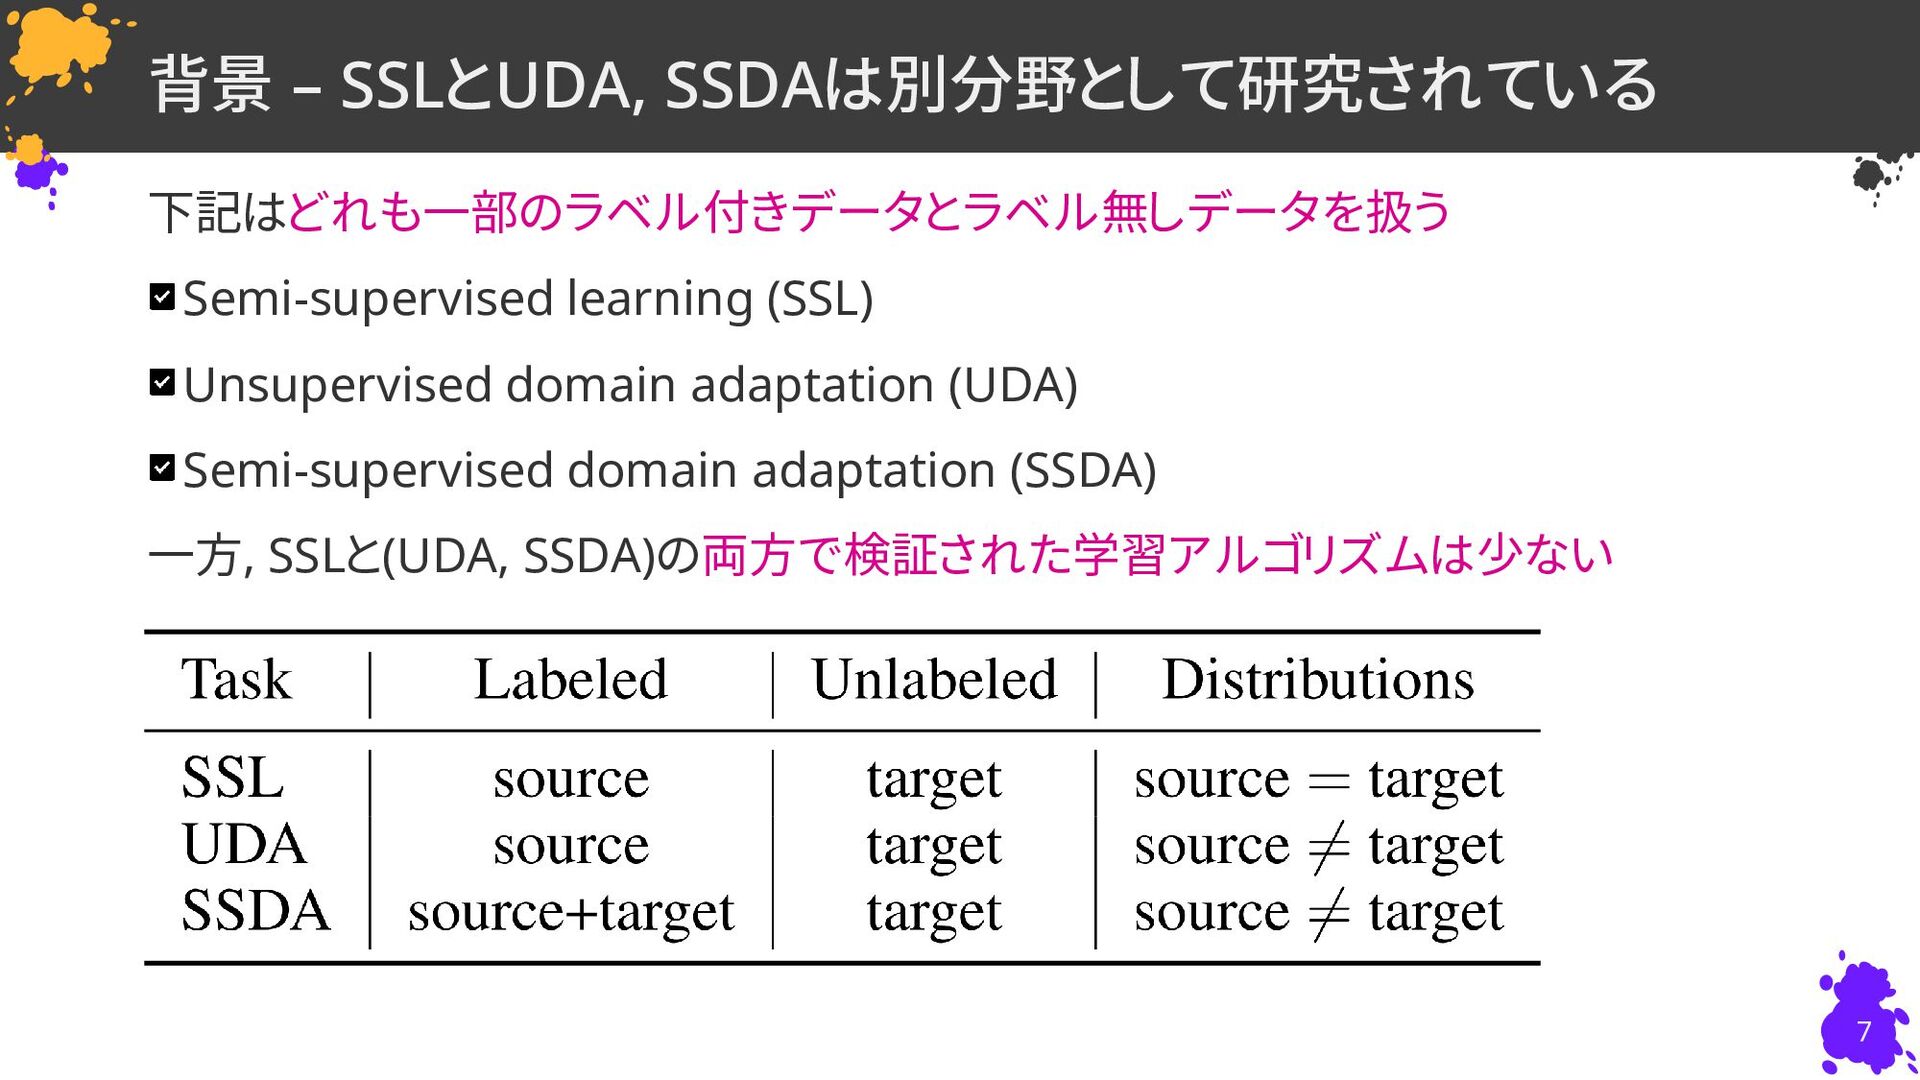
背景 – SSLとUDA, SSDAは別分野として研究されている 下記はどれも一部のラベル付きデータとラベル無しデータを扱う Semi-supervised learning (SSL) Unsupervised domain
adaptation (UDA) Semi-supervised domain adaptation (SSDA) 一方, SSLと(UDA, SSDA)の両方で検証された学習アルゴリズムは少ない 7 -
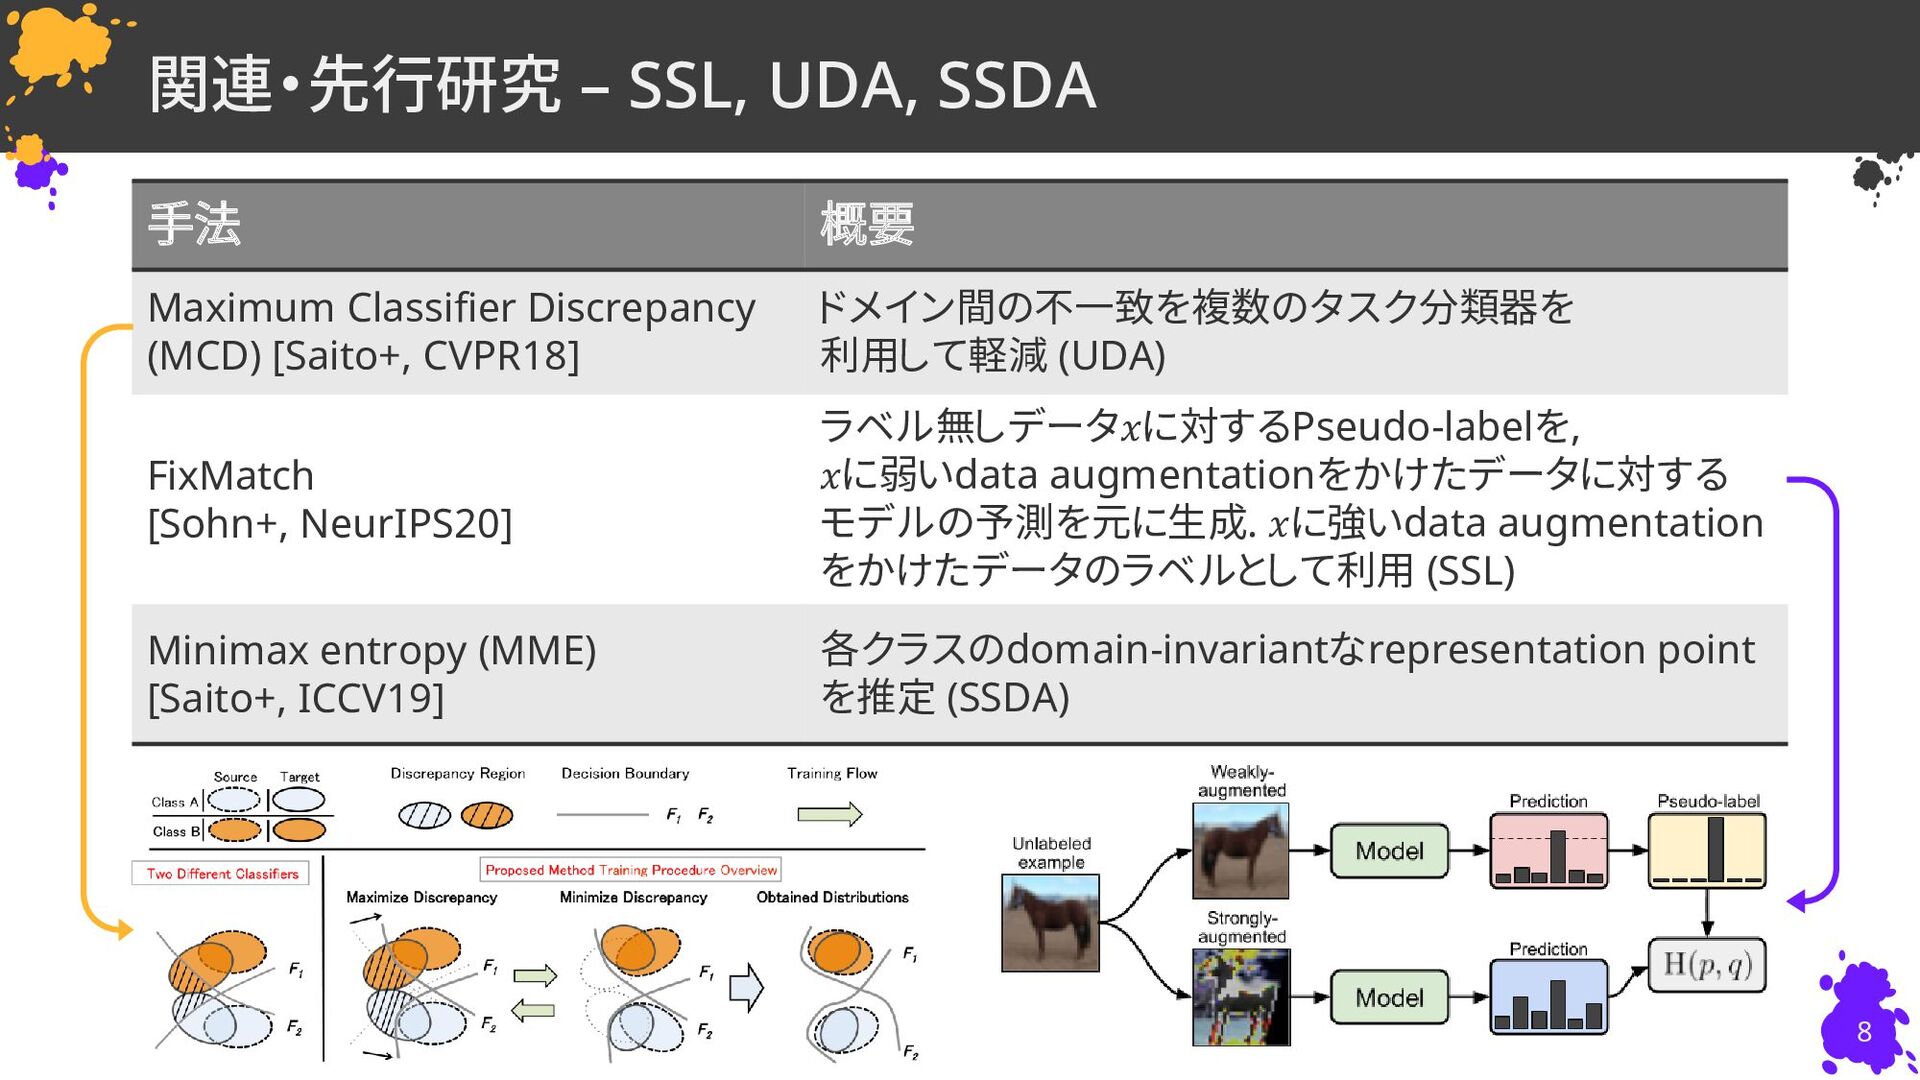
関連・先行研究 – SSL, UDA, SSDA 8 手法 概要 Maximum Classifier
Discrepancy (MCD) [Saito+, CVPR18] ドメイン間の不一致を複数のタスク分類器を 利用して軽減 (UDA) FixMatch [Sohn+, NeurIPS20] ラベル無しデータ𝑥に対するPseudo-labelを, 𝑥に弱いdata augmentationをかけたデータに対する モデルの予測を元に生成. 𝑥に強いdata augmentation をかけたデータのラベルとして利用 (SSL) Minimax entropy (MME) [Saito+, ICCV19] 各クラスのdomain-invariantなrepresentation point を推定 (SSDA) -
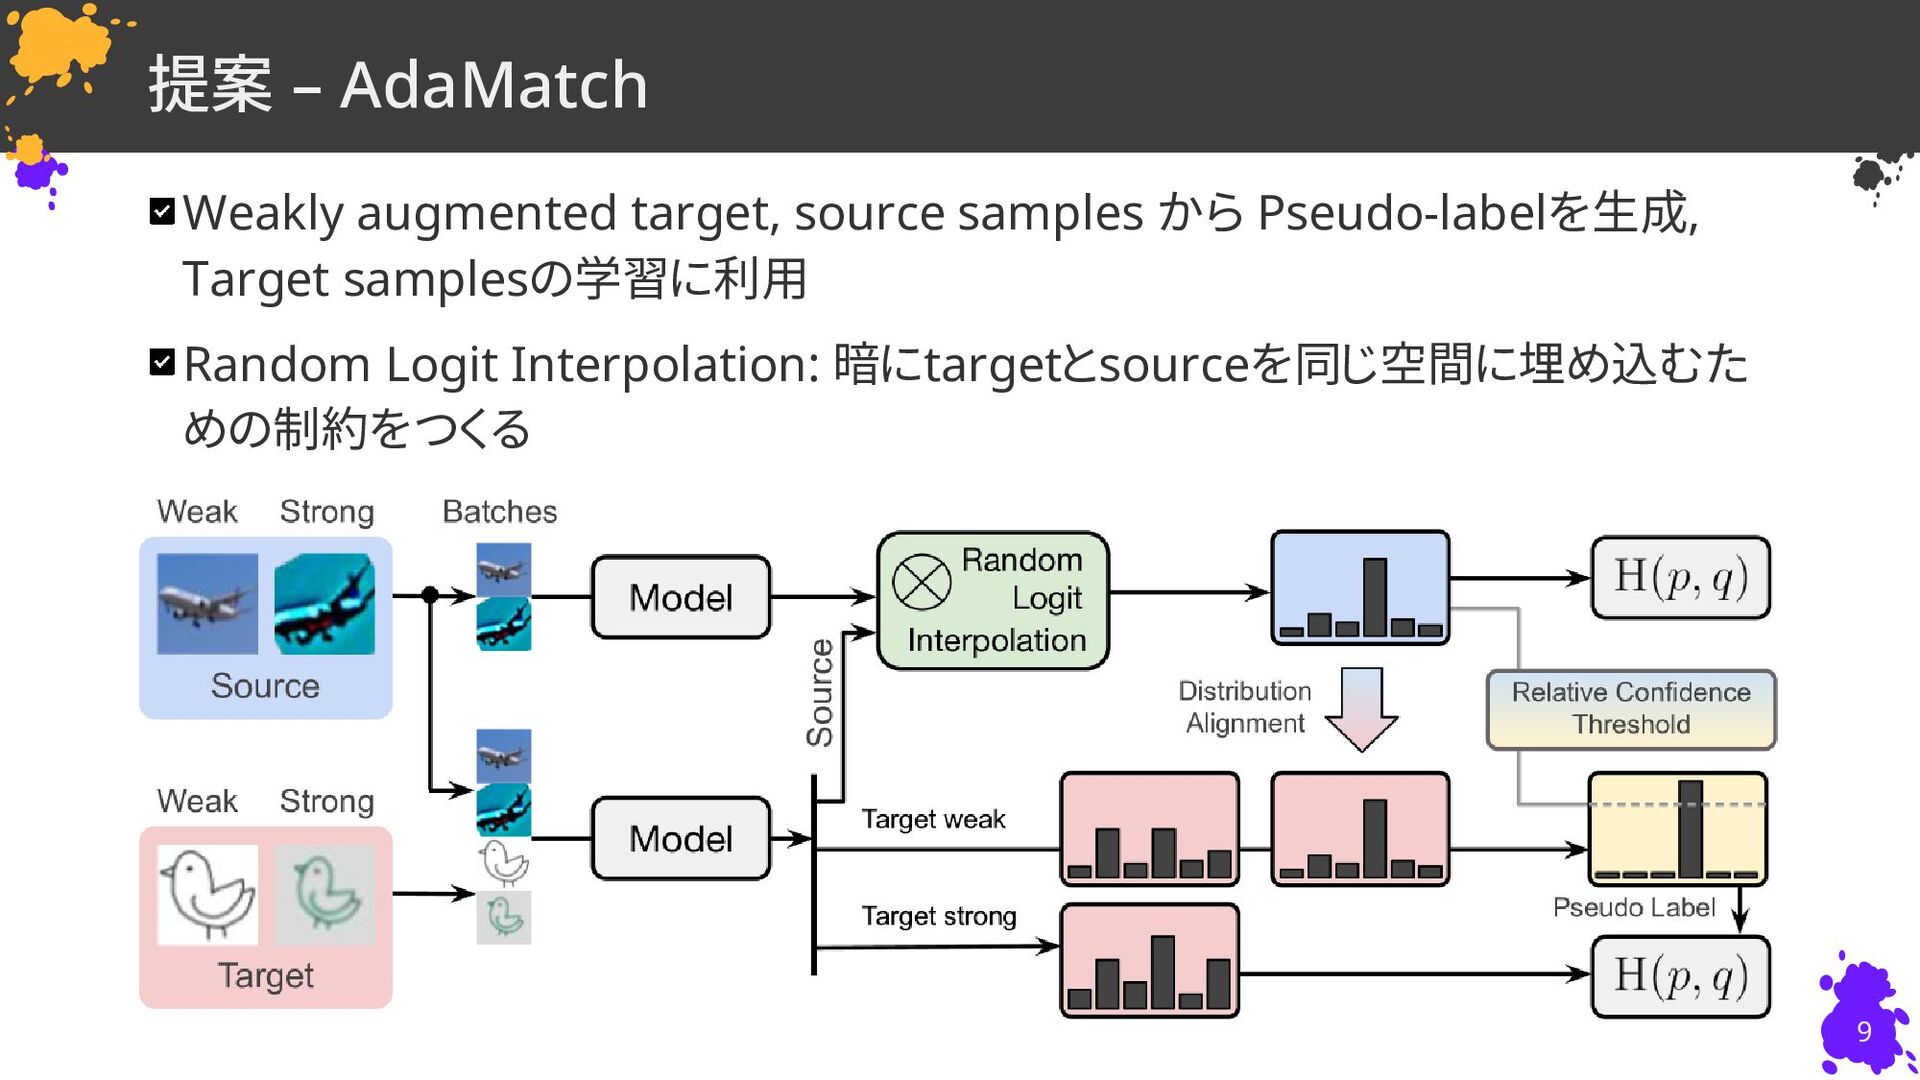
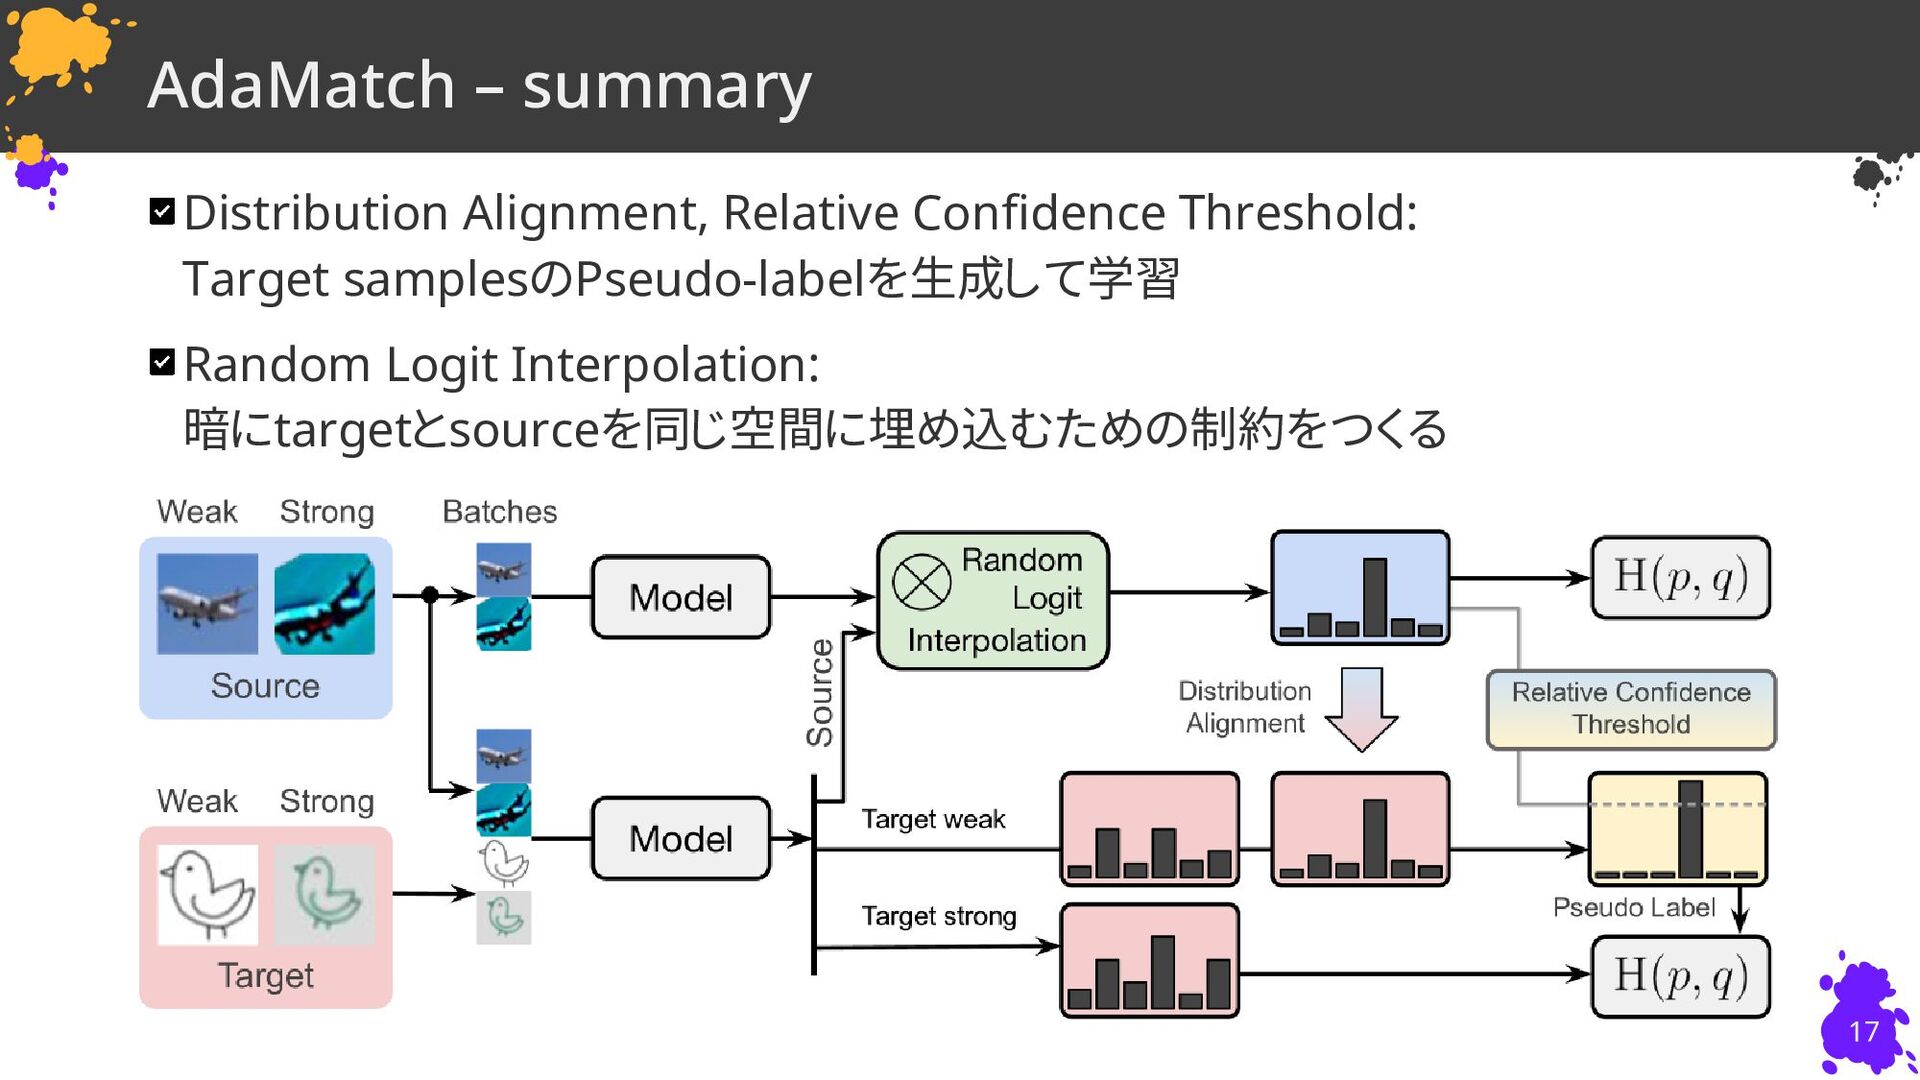
提案 – AdaMatch Weakly augmented target, source samples から Pseudo-labelを生成,
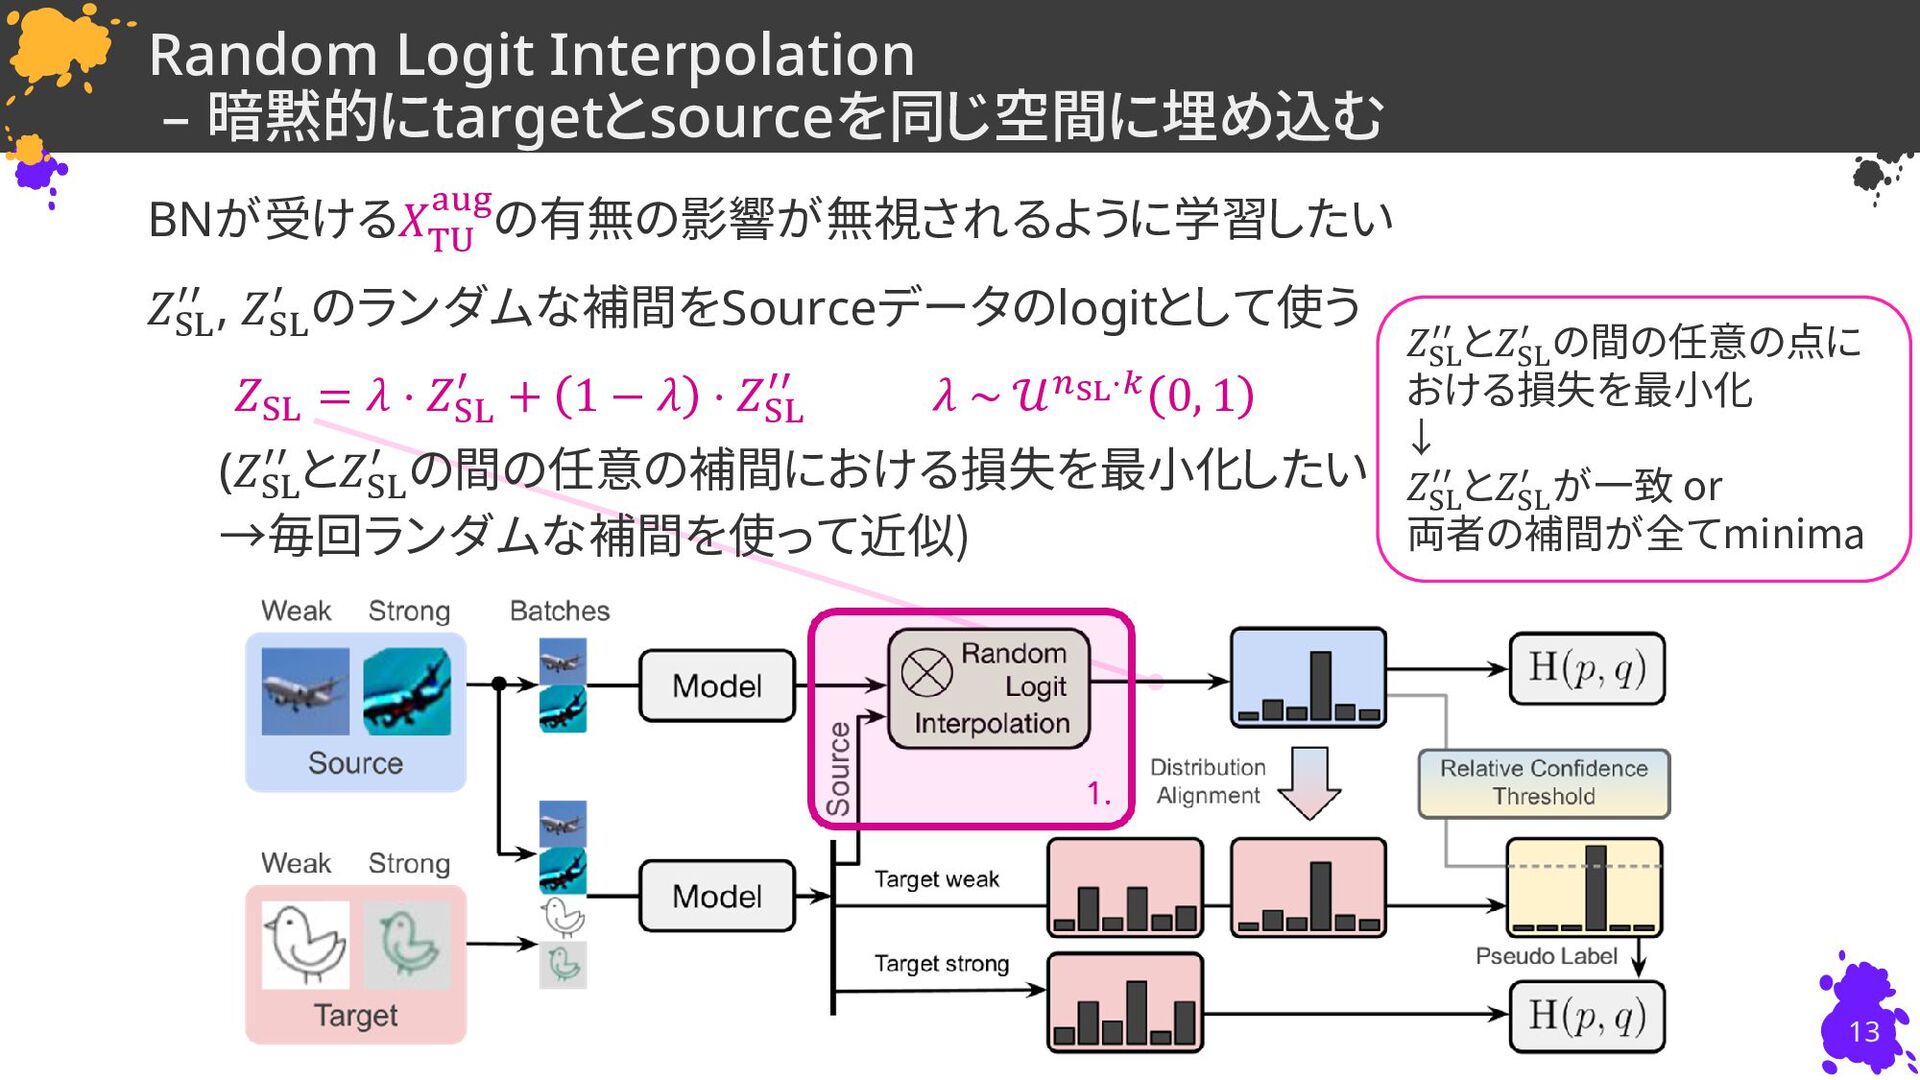
Target samplesの学習に利用 Random Logit Interpolation: 暗にtargetとsourceを同じ空間に埋め込むた めの制約をつくる 9 -
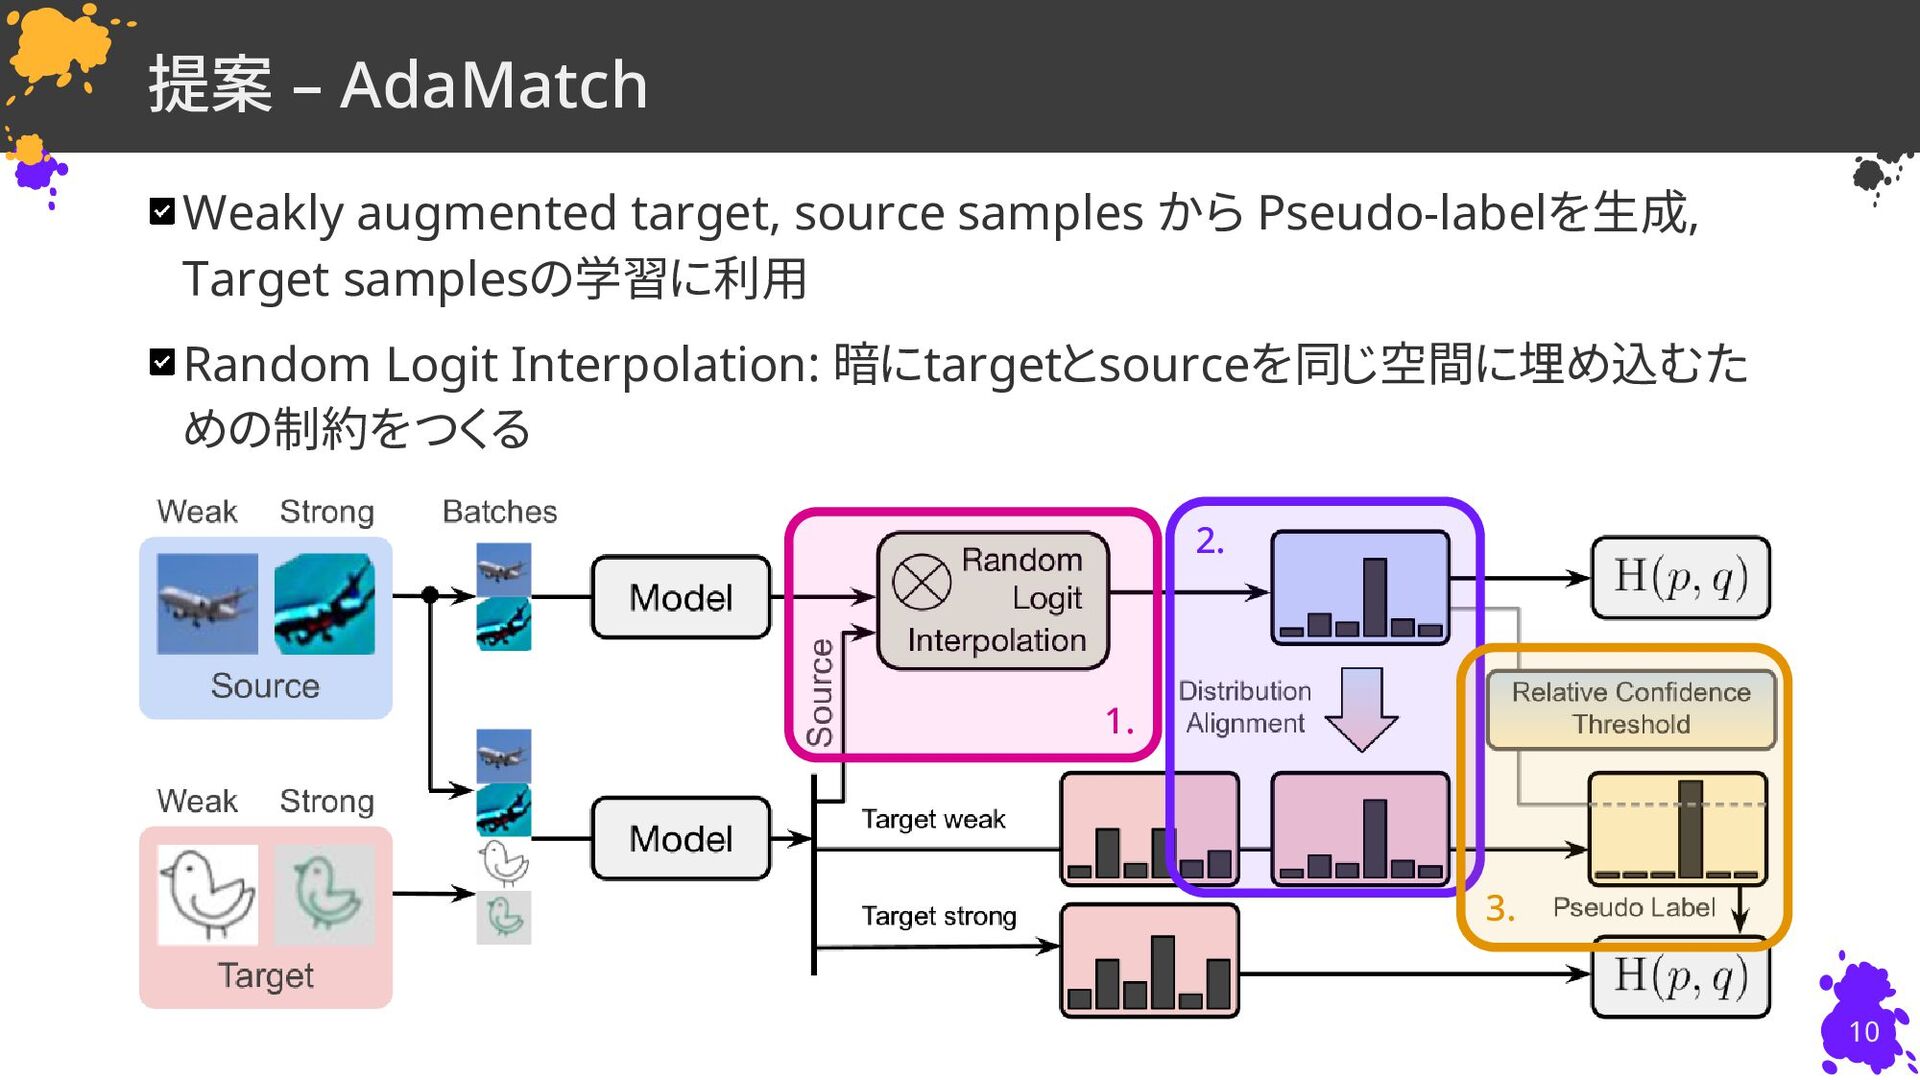
提案 – AdaMatch Weakly augmented target, source samples から Pseudo-labelを生成,
Target samplesの学習に利用 Random Logit Interpolation: 暗にtargetとsourceを同じ空間に埋め込むた めの制約をつくる 10 1. 2. 3. -
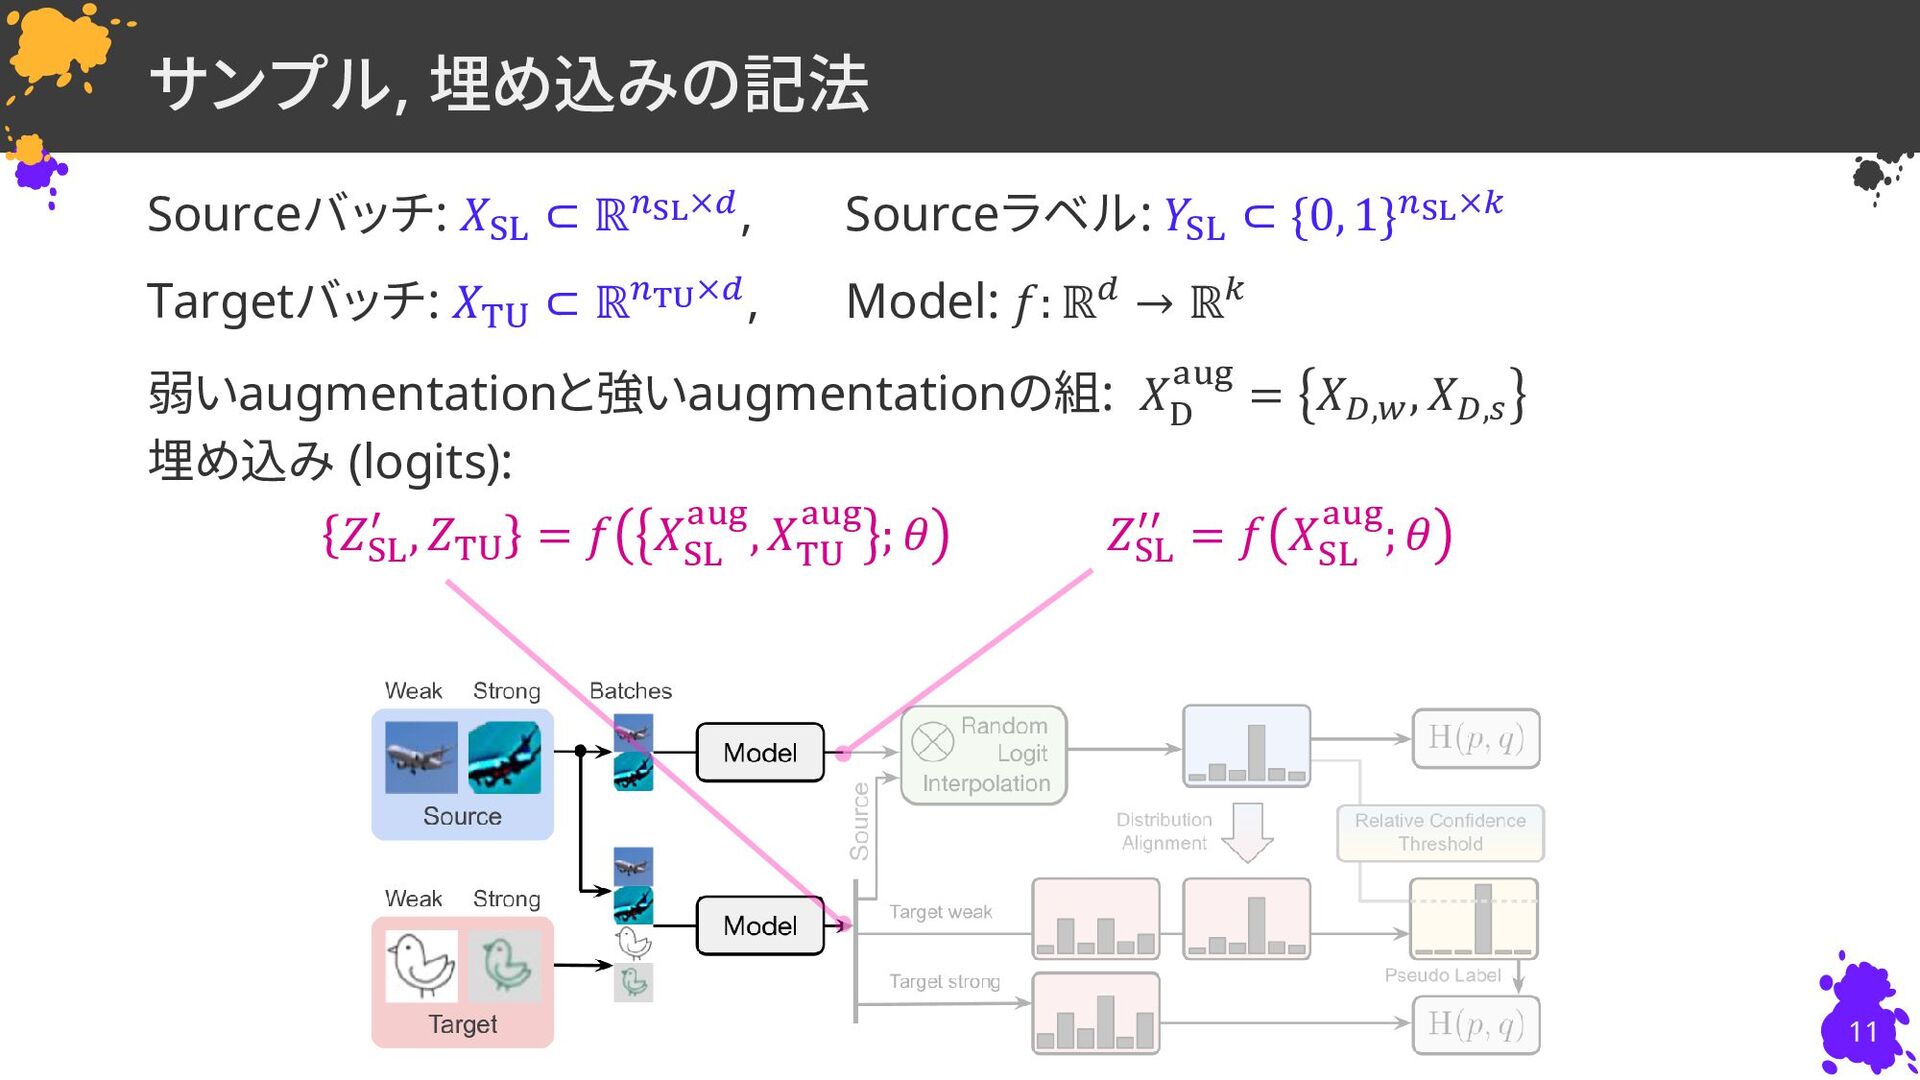
サンプル, 埋め込みの記法 Sourceバッチ: 𝑋SL ⊂ ℝ𝑛SL×𝑑, Sourceラベル: 𝑌SL ⊂ {0,
1}𝑛SL×𝑘 Targetバッチ: 𝑋TU ⊂ ℝ𝑛TU×𝑑, Model: 𝑓: ℝ𝑑 → ℝ𝑘 弱いaugmentationと強いaugmentationの組: 𝑋 D aug = 𝑋𝐷,𝑤 , 𝑋𝐷,𝑠 埋め込み (logits): 𝑍SL ′ , 𝑍TU = 𝑓 𝑋 SL aug, 𝑋 TU aug ; 𝜃 𝑍SL ′′ = 𝑓 𝑋 SL aug; 𝜃 11 -
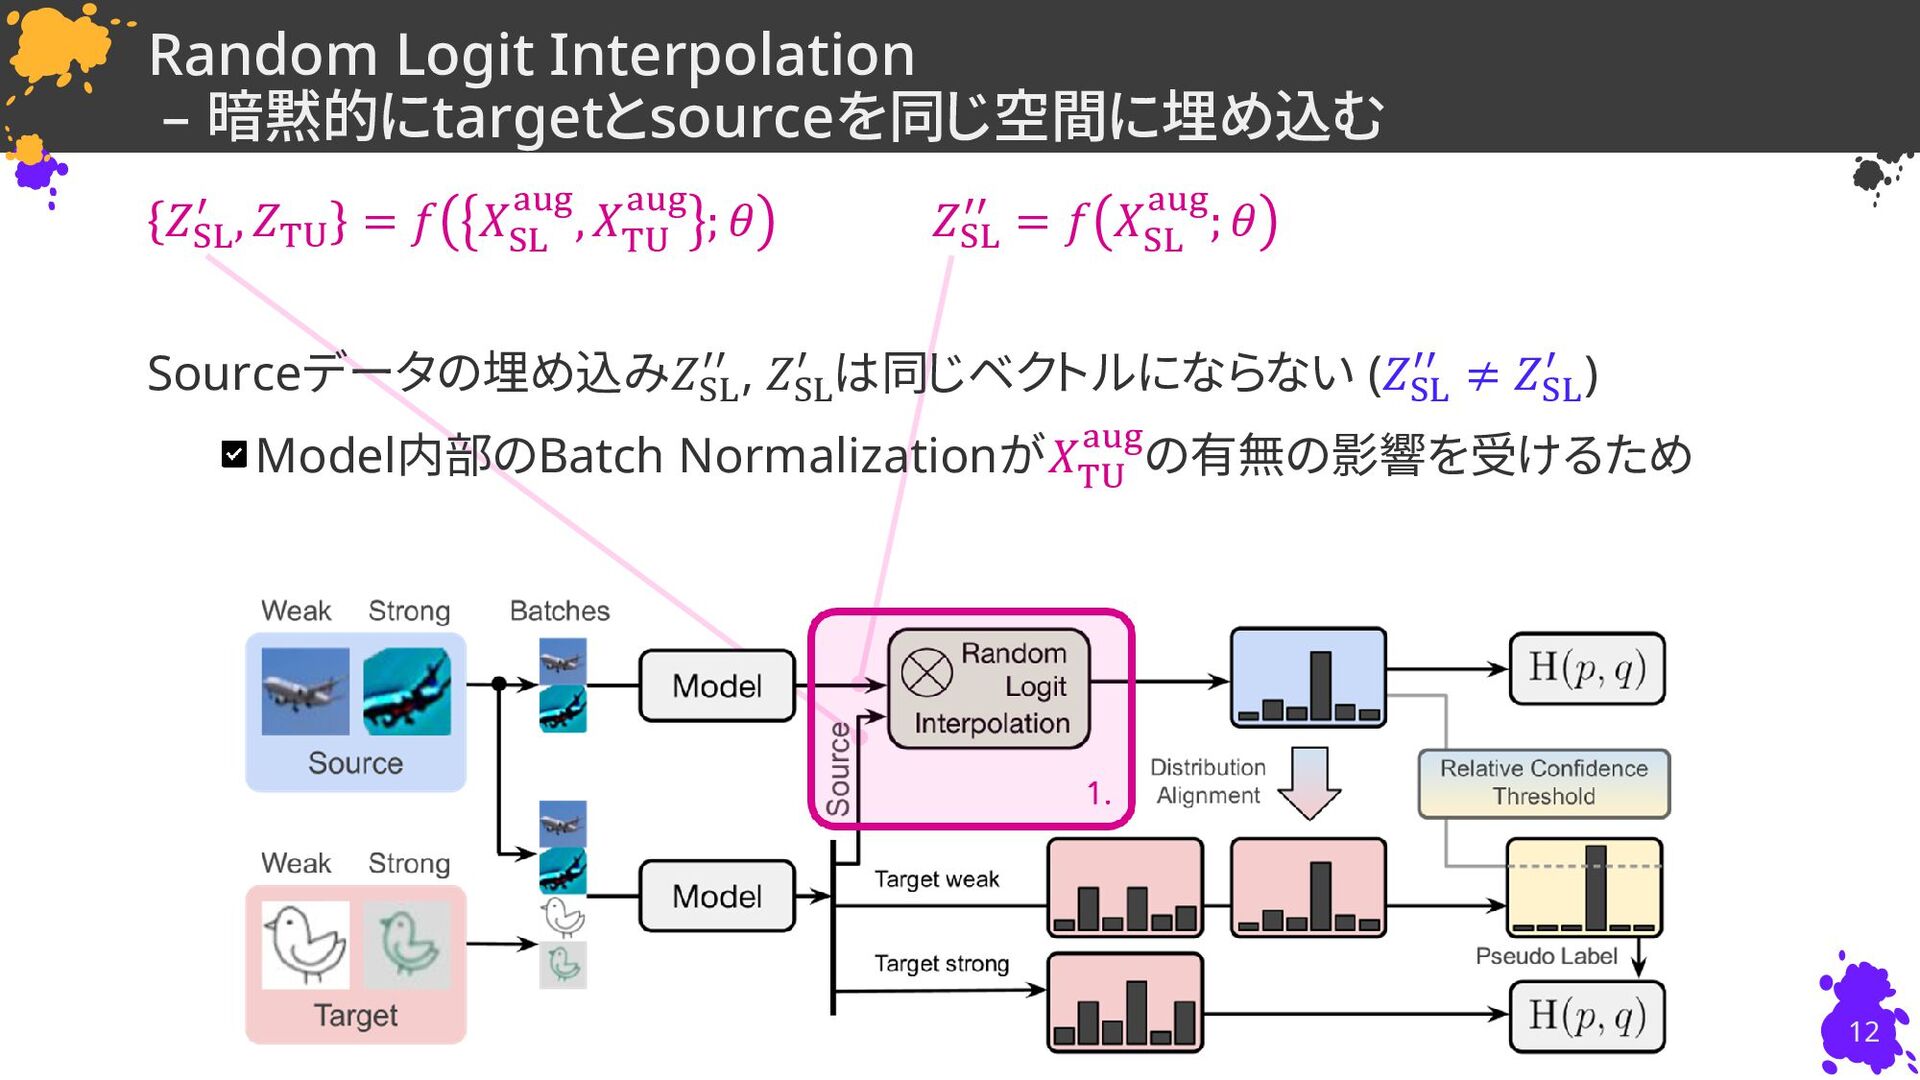
Random Logit Interpolation – 暗黙的にtargetとsourceを同じ空間に埋め込む 𝑍SL ′ , 𝑍TU =
𝑓 𝑋 SL aug, 𝑋 TU aug ; 𝜃 𝑍SL ′′ = 𝑓 𝑋 SL aug; 𝜃 Sourceデータの埋め込み𝑍SL ′′ , 𝑍SL ′ は同じベクトルにならない (𝑍SL ′′ ≠ 𝑍SL ′ ) Model内部のBatch Normalizationが𝑋 TU augの有無の影響を受けるため 12 -
Random Logit Interpolation – 暗黙的にtargetとsourceを同じ空間に埋め込む BNが受ける𝑋 TU augの有無の影響が無視されるように学習したい 𝑍SL ′′
, 𝑍SL ′ のランダムな補間をSourceデータのlogitとして使う 𝑍SL = 𝜆 ⋅ 𝑍SL ′ + 1 − 𝜆 ⋅ 𝑍SL ′′ 𝜆 ~ 𝒰𝑛SL⋅𝑘 0, 1 (𝑍SL ′′ と𝑍SL ′ の間の任意の補間における損失を最小化したい →毎回ランダムな補間を使って近似) 13 𝑍SL ′′ と𝑍SL ′ の間の任意の点に おける損失を最小化 ↓ 𝑍SL ′′ と𝑍SL ′ が一致 or 両者の補間が全てminima -
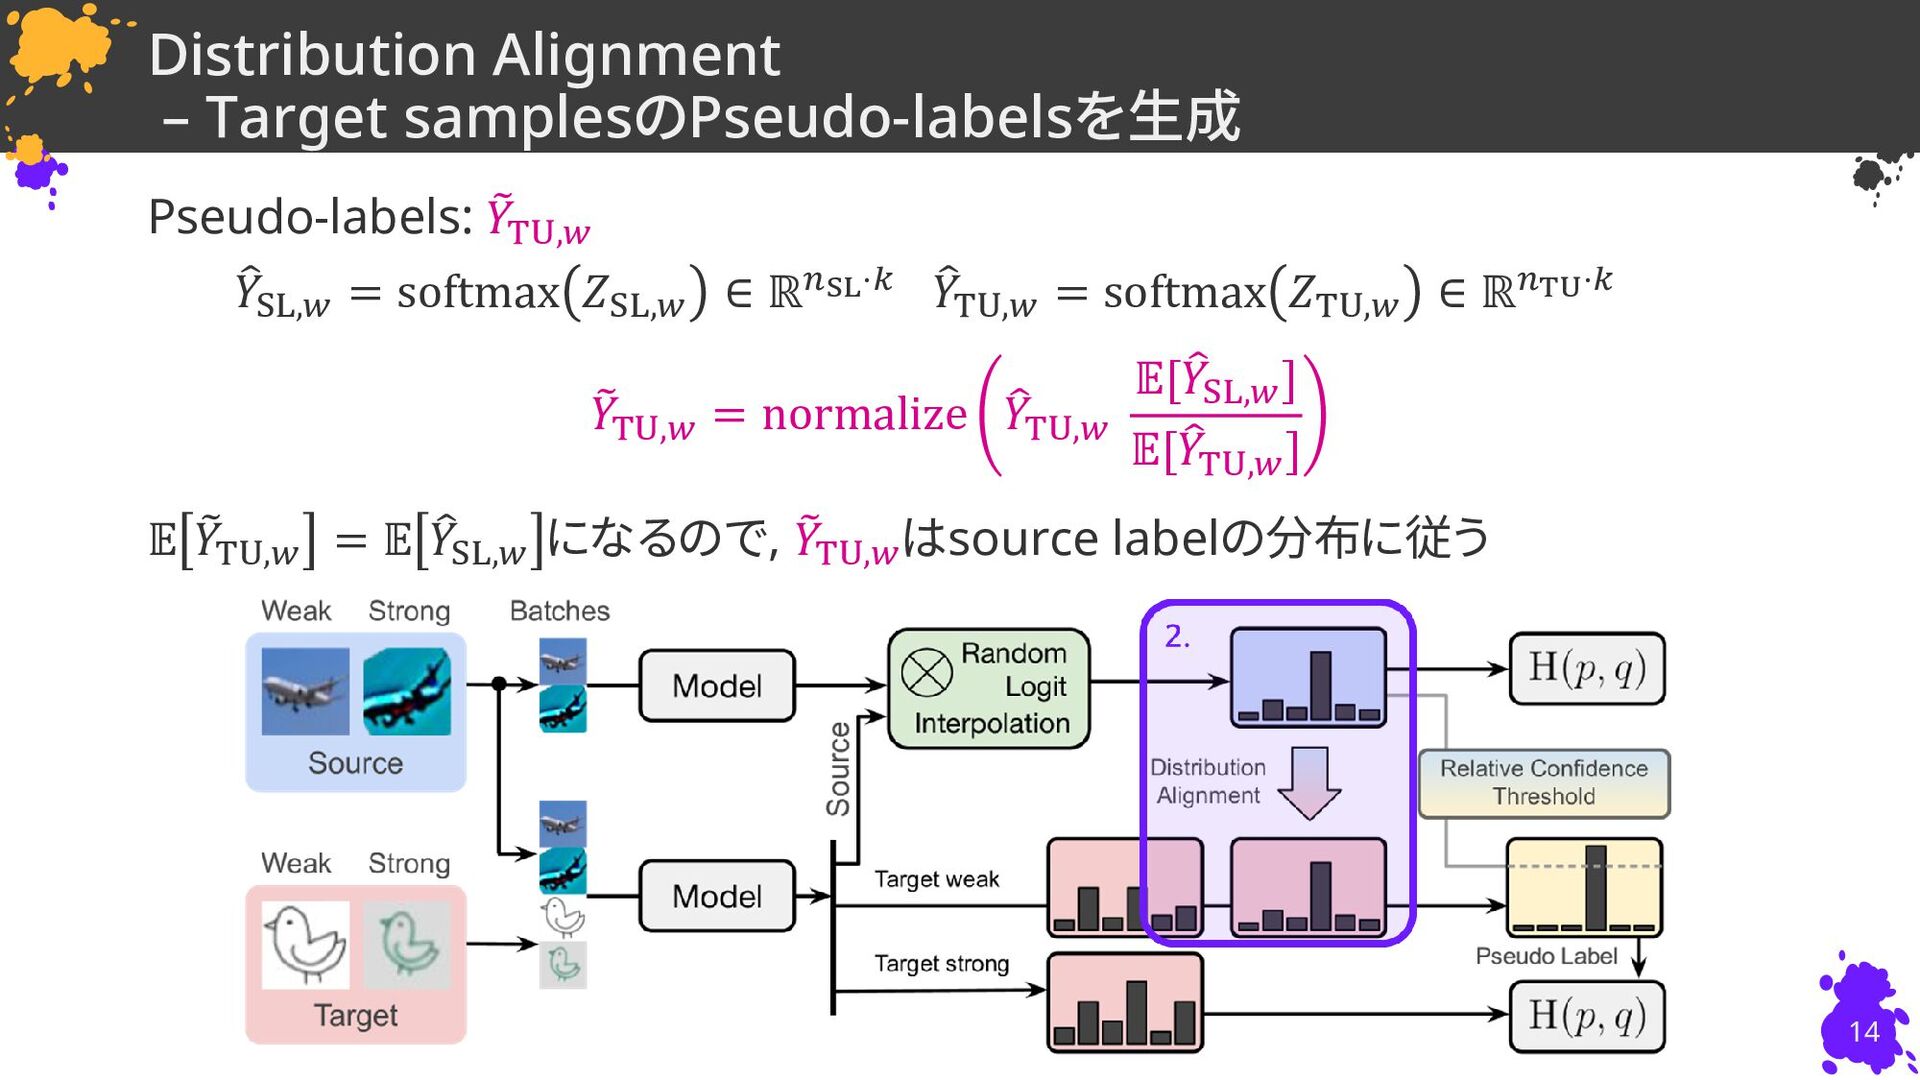
Distribution Alignment – Target samplesのPseudo-labelsを生成 Pseudo-labels: ෨ 𝑌TU,𝑤 𝑌SL,𝑤
= softmax 𝑍SL,𝑤 ∈ ℝ𝑛SL⋅𝑘 𝑌TU,𝑤 = softmax 𝑍TU,𝑤 ∈ ℝ𝑛TU⋅𝑘 ෨ 𝑌TU,𝑤 = normalize 𝑌TU,𝑤 𝔼[ 𝑌SL,𝑤 ] 𝔼[ 𝑌TU,𝑤 ] 𝔼 ෨ 𝑌TU,𝑤 = 𝔼 𝑌SL,𝑤 になるので, ෨ 𝑌TU,𝑤 はsource labelの分布に従う 14 -
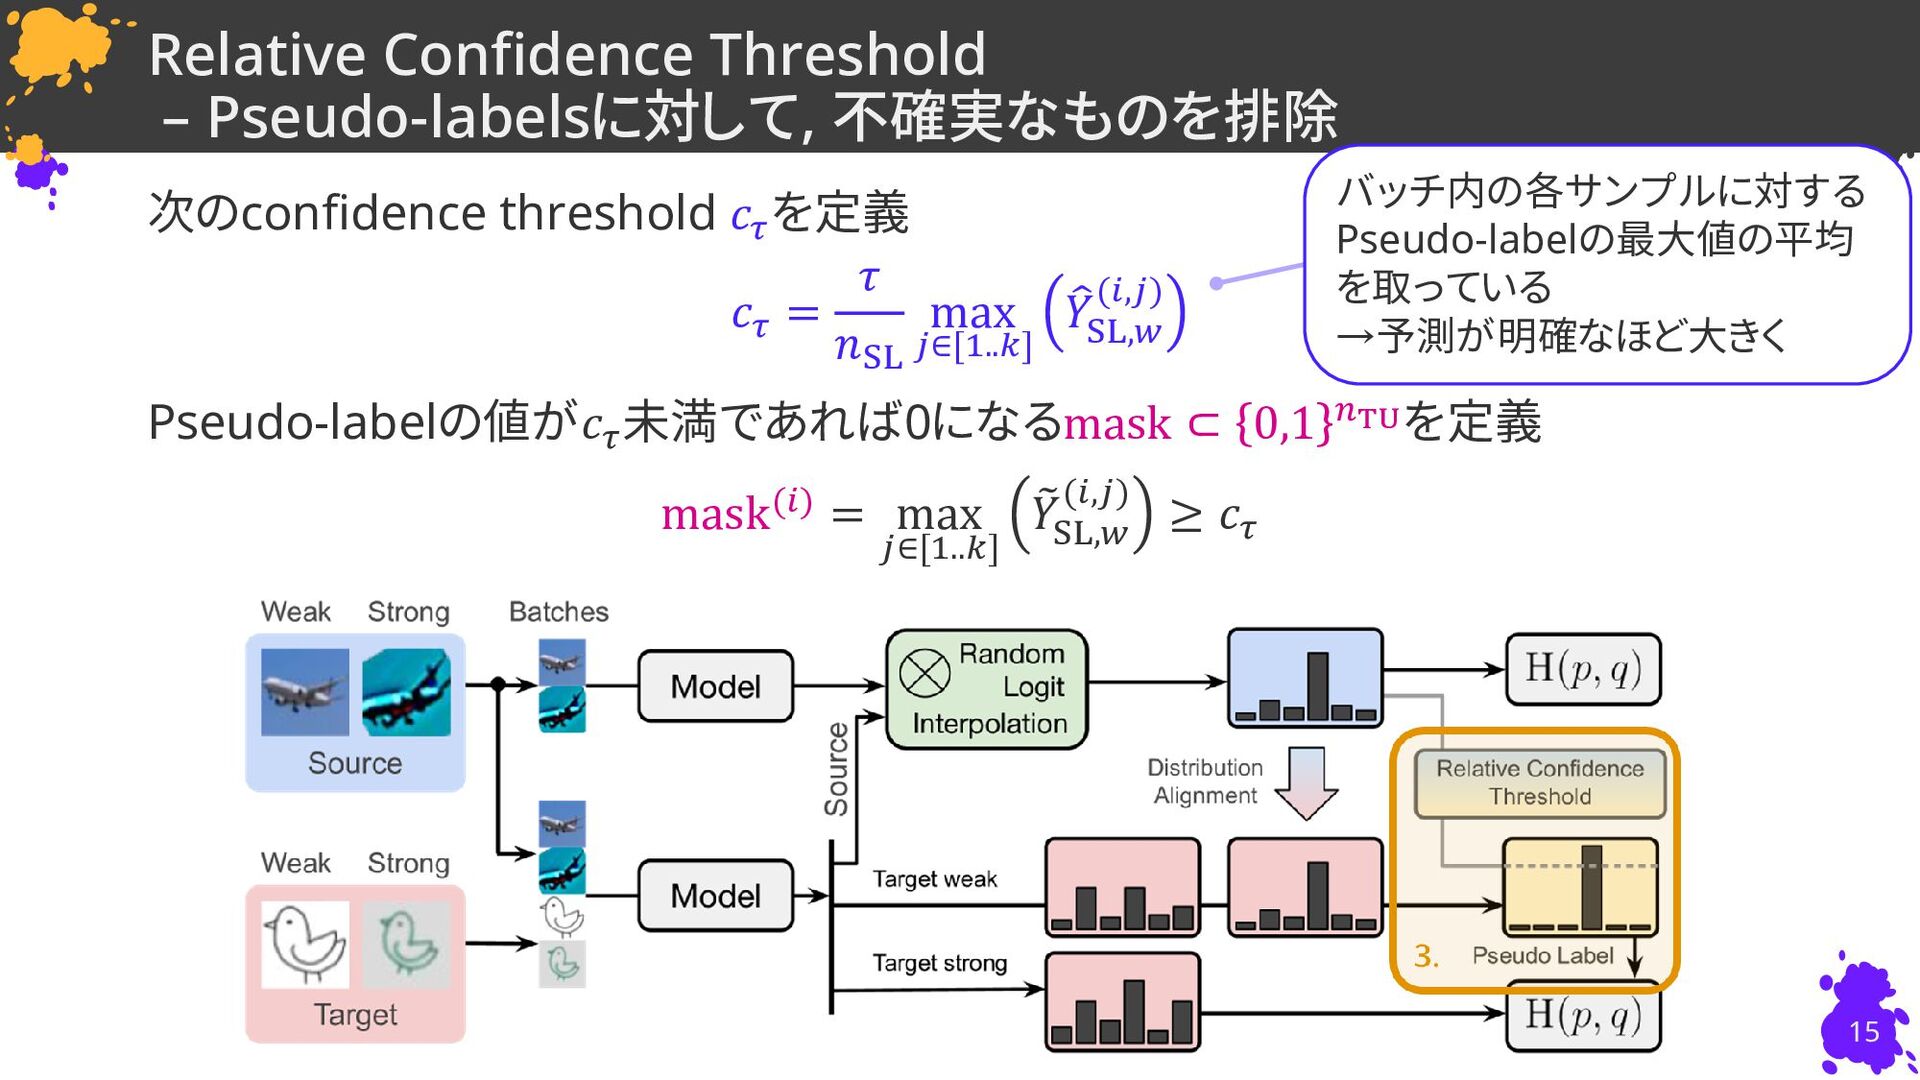
Relative Confidence Threshold – Pseudo-labelsに対して, 不確実なものを排除 次のconfidence threshold 𝑐𝜏 を定義
𝑐𝜏 = 𝜏 𝑛SL max 𝑗∈[1..𝑘] 𝑌 SL,𝑤 (𝑖,𝑗) Pseudo-labelの値が𝑐𝜏 未満であれば0になるmask ⊂ 0,1 𝑛TUを定義 mask(𝑖) = max 𝑗∈[1..𝑘] ෨ 𝑌 SL,𝑤 (𝑖,𝑗) ≥ 𝑐𝜏 15 バッチ内の各サンプルに対する Pseudo-labelの最大値の平均 を取っている →予測が明確なほど大きく -
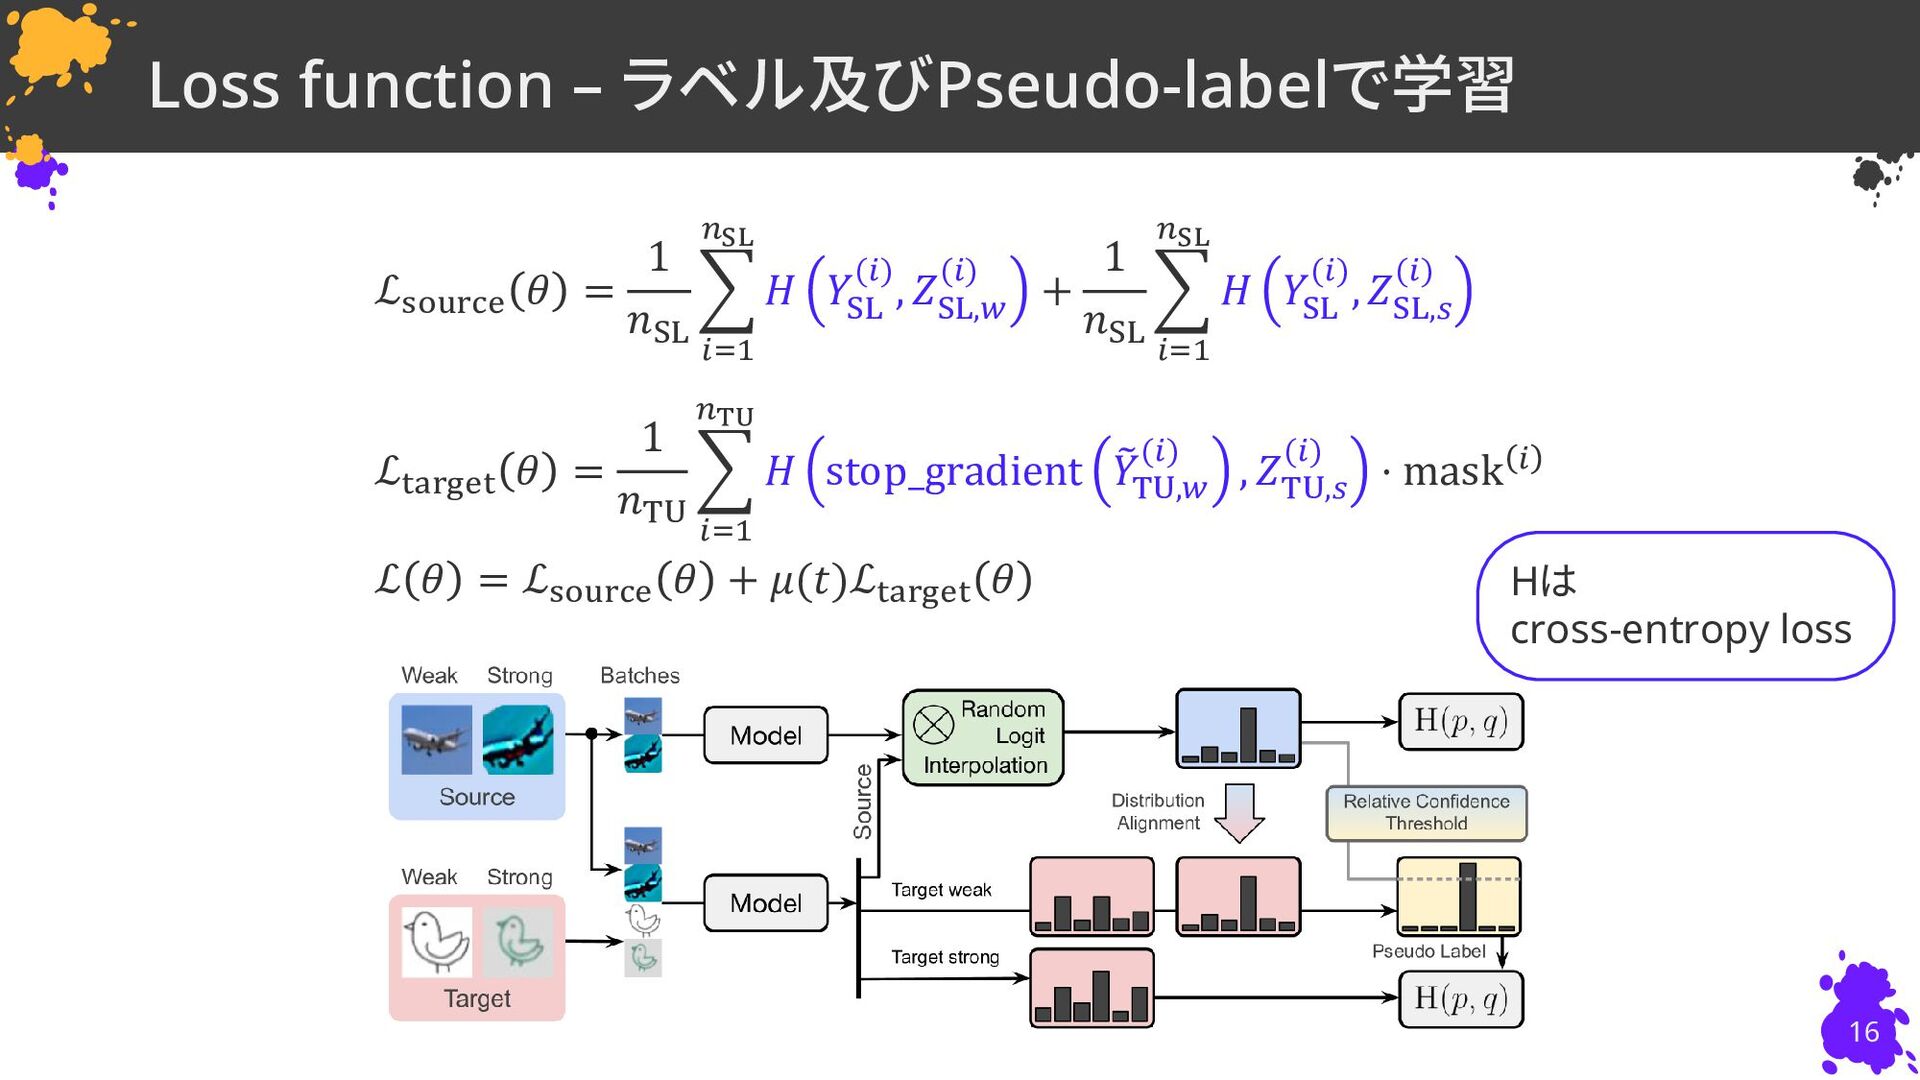
Loss function – ラベル及びPseudo-labelで学習 ℒsource 𝜃 = 1 𝑛SL
𝑖=1 𝑛SL 𝐻 𝑌 SL (𝑖), 𝑍 SL,𝑤 (𝑖) + 1 𝑛SL 𝑖=1 𝑛SL 𝐻 𝑌 SL (𝑖), 𝑍 SL,𝑠 (𝑖) ℒtarget 𝜃 = 1 𝑛TU 𝑖=1 𝑛TU 𝐻 stop_gradient ෨ 𝑌 TU,𝑤 (𝑖) , 𝑍 TU,𝑠 (𝑖) ⋅ mask 𝑖 ℒ 𝜃 = ℒsource 𝜃 + 𝜇(𝑡)ℒtarget 𝜃 16 Hは cross-entropy loss -
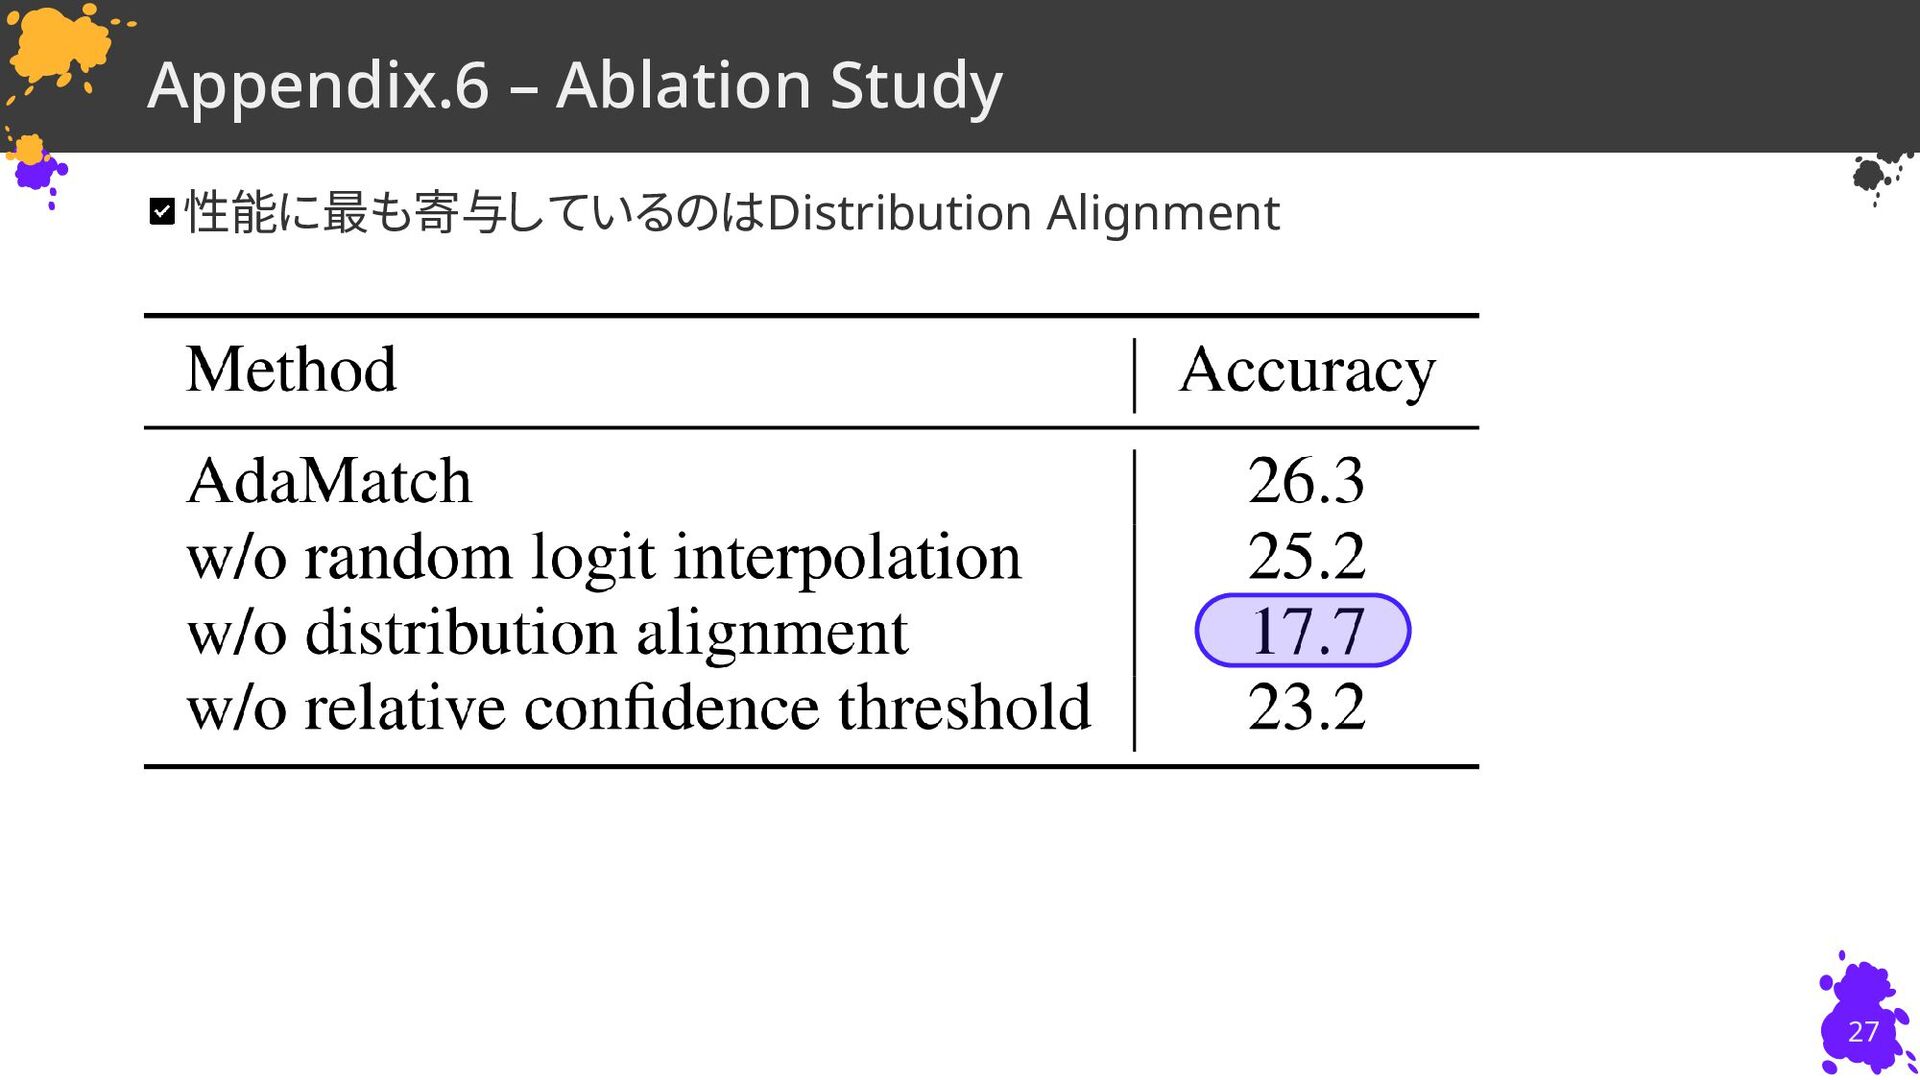
AdaMatch – summary Distribution Alignment, Relative Confidence Threshold: Target samplesのPseudo-labelを生成して学習
Random Logit Interpolation: 暗にtargetとsourceを同じ空間に埋め込むための制約をつくる 17 -
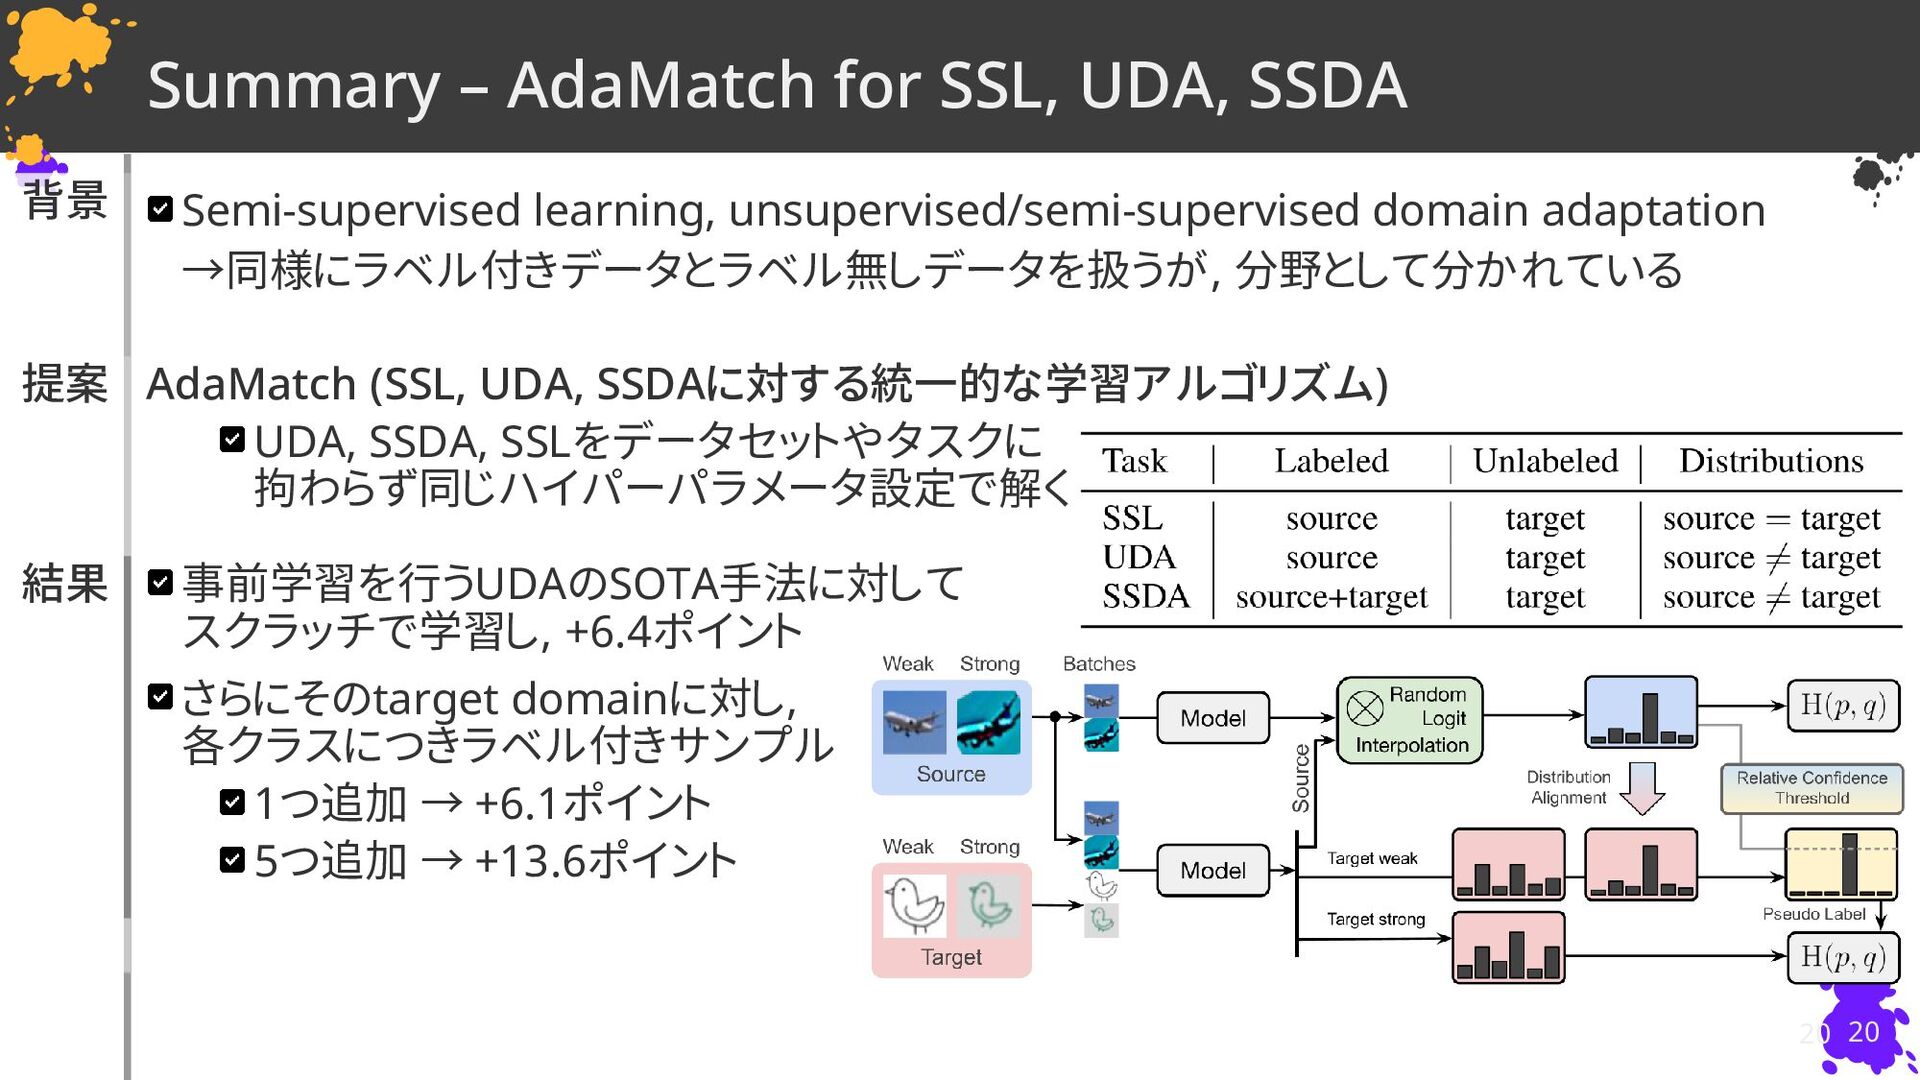
20 Semi-supervised learning, unsupervised/semi-supervised domain adaptation →同様にラベル付きデータとラベル無しデータを扱うが, 分野として分かれている 背景 提案
結果 AdaMatch (SSL, UDA, SSDAに対する統一的な学習アルゴリズム) UDA, SSDA, SSLをデータセットやタスクに 拘わらず同じハイパーパラメータ設定で解く 事前学習を行うUDAのSOTA手法に対して スクラッチで学習し, +6.4ポイント さらにそのtarget domainに対し, 各クラスにつきラベル付きサンプル 1つ追加 → +6.1ポイント 5つ追加 → +13.6ポイント Summary – AdaMatch for SSL, UDA, SSDA 20 -
所感 Strength Motivationが面白い, 実際に成果もかなり強そう 網羅的な実験がAppendixにまとめられている Weakness 数式ちょっと雑だったりする..? 微誤植が多い気がする E.g., replace
the term 𝔼[ 𝑌SL,𝑤 ] → replace the term 𝔼[ 𝑌TU,𝑤 ] ? Jax実装なのだが, 現在0.x.xにあるjax, jaxlibなどのversion管理がされていな いので再現に苦労する 21 -
Appendix.2 – DomainNet https://paperswithcode.com/dataset/domainnet > DomainNet is a dataset of
common objects in six different domain. All domains include 345 categories (classes) of objects such as Bracelet, plane, bird and cello. > The domains include clipart: collection of clipart images; real: photos and real world images; sketch: sketches of specific objects; … 23 -
Appendix.3 – DigitFive https://paperswithcode.com/dataset/digit-five > Digit-Five is a collection of
five most popular digit datasets, MNIST (mt) (55000 samples), MNIST-M (mm) (55000 samples), Synthetic Digits (syn) (25000 samples), SVHN (sv)(73257 samples), and USPS (up) (7438 samples). Each digit dataset includes a different style of 0-9 digit images. 24