Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[Journal club] Shifting More Attention to Visua...
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
Semantic Machine Intelligence Lab., Keio Univ.
PRO
September 13, 2022
Technology
160
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[Journal club] Shifting More Attention to Visual Backbone: Query-modulated Refinement Networks for End-to-End Visual Grounding
Semantic Machine Intelligence Lab., Keio Univ.
PRO
September 13, 2022
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
[EMNLP26] RIGEL: Self-Distilled Score Adaptation for Image and Video Captioning Evaluation
keio_smilab
PRO
0
40
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
210
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
keio_smilab
PRO
0
180
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
250
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
240
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
keio_smilab
PRO
1
200
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
240
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
73
[MIRU26] To What Extent Does MLLM-as-a-Judge Exhibit Cross-Model Preference Bias?
keio_smilab
PRO
0
330
Other Decks in Technology
See All in Technology
DGX Spark でどこまでハッキングができるのか?
kash1064
3
1.3k
初海外で注意すべきこと12選!!!安全快適なre:invent生活にするために
yuuuuuuu168
1
160
Rustuna: Rustによる高速なOptuna実装
pfn
PRO
0
190
go-sqletch
moznion
0
140
フロントエンドカンファレンス関西2026 - 速すぎるUIに、待ち時間を
teamlab
PRO
0
130
NDIでApple Vision Proにリアルタイム映像送信
jyouryuusui
0
120
Tofu-Controller lightning talk @ Containerday 2026
gionn
0
110
実体験から学ぶ分析エージェントの開発と運⽤
recruitengineers
PRO
8
2.4k
AIカンパニーへの転換を支えた、エンジニアの仕事の再定義
kworkdev
PRO
2
1.2k
夫婦で子育てするための育児標準化
codmoninc
PRO
0
330
無理せず続ける、子育てエンジニアの学び
codmoninc
PRO
0
860
M5Stackで作る BLEマウス GPSログの世界
tomokusaba
0
420
Featured
See All Featured
Designing for Performance
lara
612
70k
[RailsConf 2023] Rails as a piece of cake
palkan
59
7.1k
Public Speaking Without Barfing On Your Shoes - THAT 2023
reverentgeek
1
600
Paper Plane (Part 1)
katiecoart
PRO
2
12k
Building Better People: How to give real-time feedback that sticks.
wjessup
370
20k
It's Worth the Effort
3n
188
29k
So, you think you're a good person
axbom
PRO
2
2.2k
Navigating Algorithm Shifts & AI Overviews - #SMXNext
aleyda
1
1.7k
The agentic SEO stack - context over prompts
schlessera
0
970
[RailsConf 2023 Opening Keynote] The Magic of Rails
eileencodes
31
10k
KATA
mclloyd
PRO
35
16k
Ecommerce SEO: The Keys for Success Now & Beyond - #SERPConf2024
aleyda
1
2.2k
Transcript
Shifting More Attention to Visual Backbone: Query-modulated Refinement Networks for
End-to-End Visual Grounding Jiabo Ye1, Jumfemg Tian2, Ming Yan2, Xiaoshan Yang3, Xuwu Wang4, Ji Zhang2, Liang He1, Xin Lin1 1East China Normal University, 2Alibaba Group, 3NLPR, 4Fudan University CVPR 2022 杉浦孔明研究室 神原 元就 Ye, J., Tian, J., Yan, M., Yang, X., Wang, X., Zhang, J., et al. (2022). Shifting More Attention to Visual Backbone: Query-modulated Refinement Networks for End-to-End Visual Grounding. In CVPR (pp. 15502-15512).
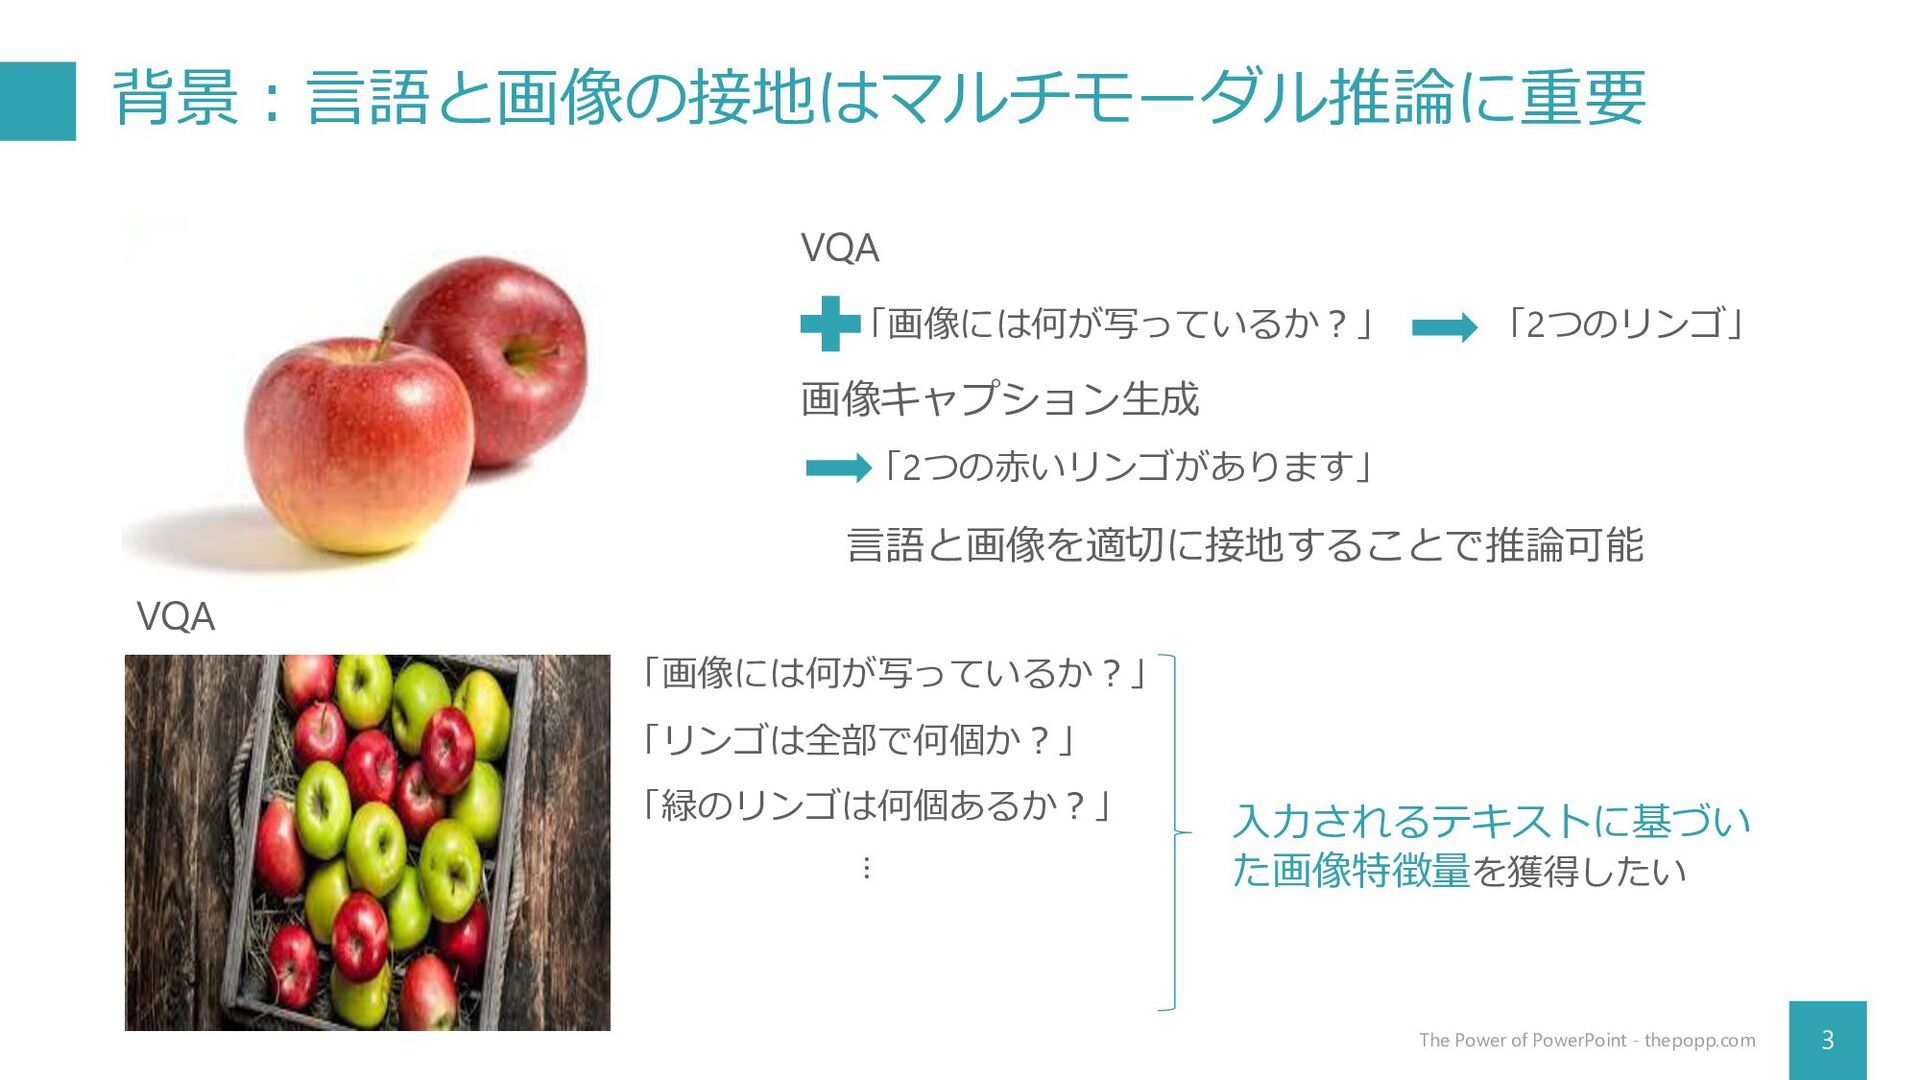
背景:言語と画像の接地はマルチモーダル推論に重要 3 The Power of PowerPoint - thepopp.com VQA 画像キャプション生成
「画像には何が写っているか?」 「2つのリンゴ」 「2つの赤いリンゴがあります」 言語と画像を適切に接地することで推論可能 「画像には何が写っているか?」 「リンゴは全部で何個か?」 「緑のリンゴは何個あるか?」 … 入力されるテキストに基づい た画像特徴量を獲得したい VQA
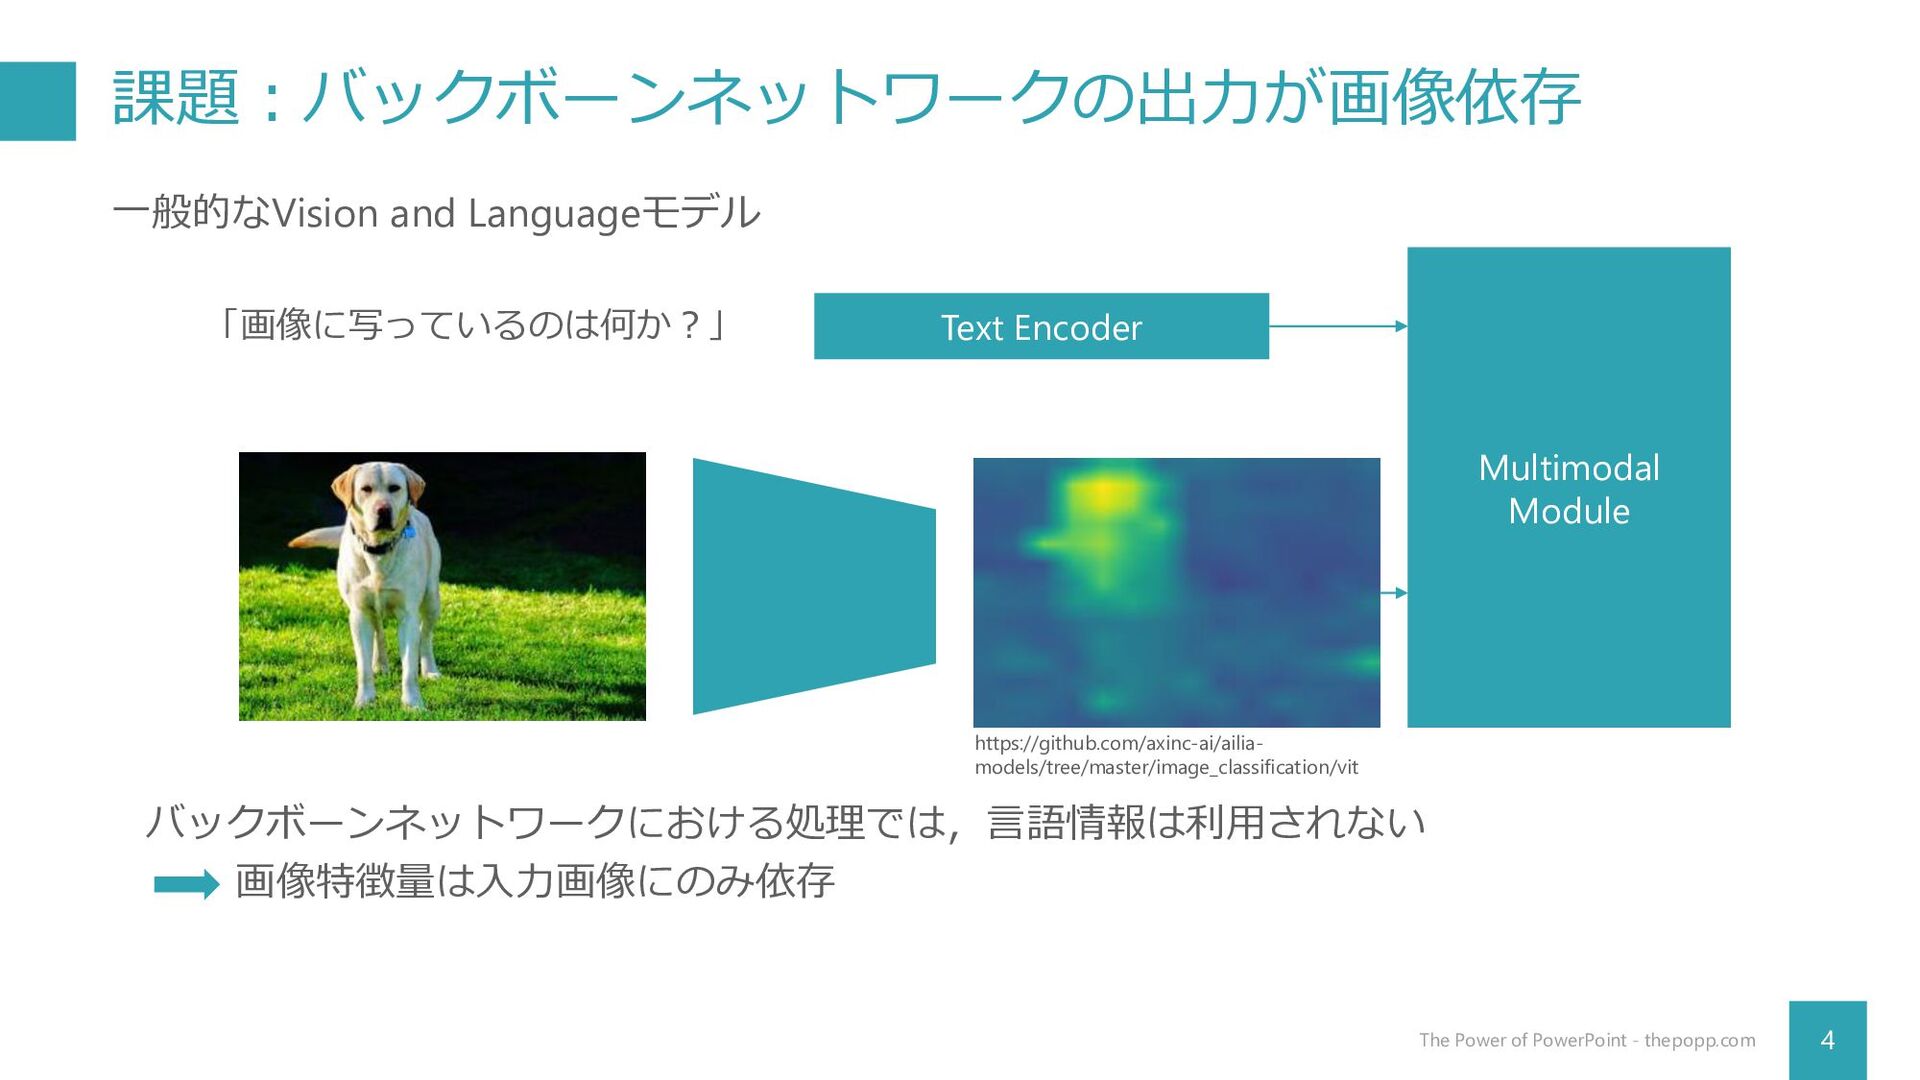
課題:バックボーンネットワークの出力が画像依存 4 The Power of PowerPoint - thepopp.com https://github.com/axinc-ai/ailia- models/tree/master/image_classification/vit
画像特徴量は入力画像にのみ依存 「画像に写っているのは何か?」 Multimodal Module Text Encoder 一般的なVision and Languageモデル バックボーンネットワークにおける処理では,言語情報は利用されない
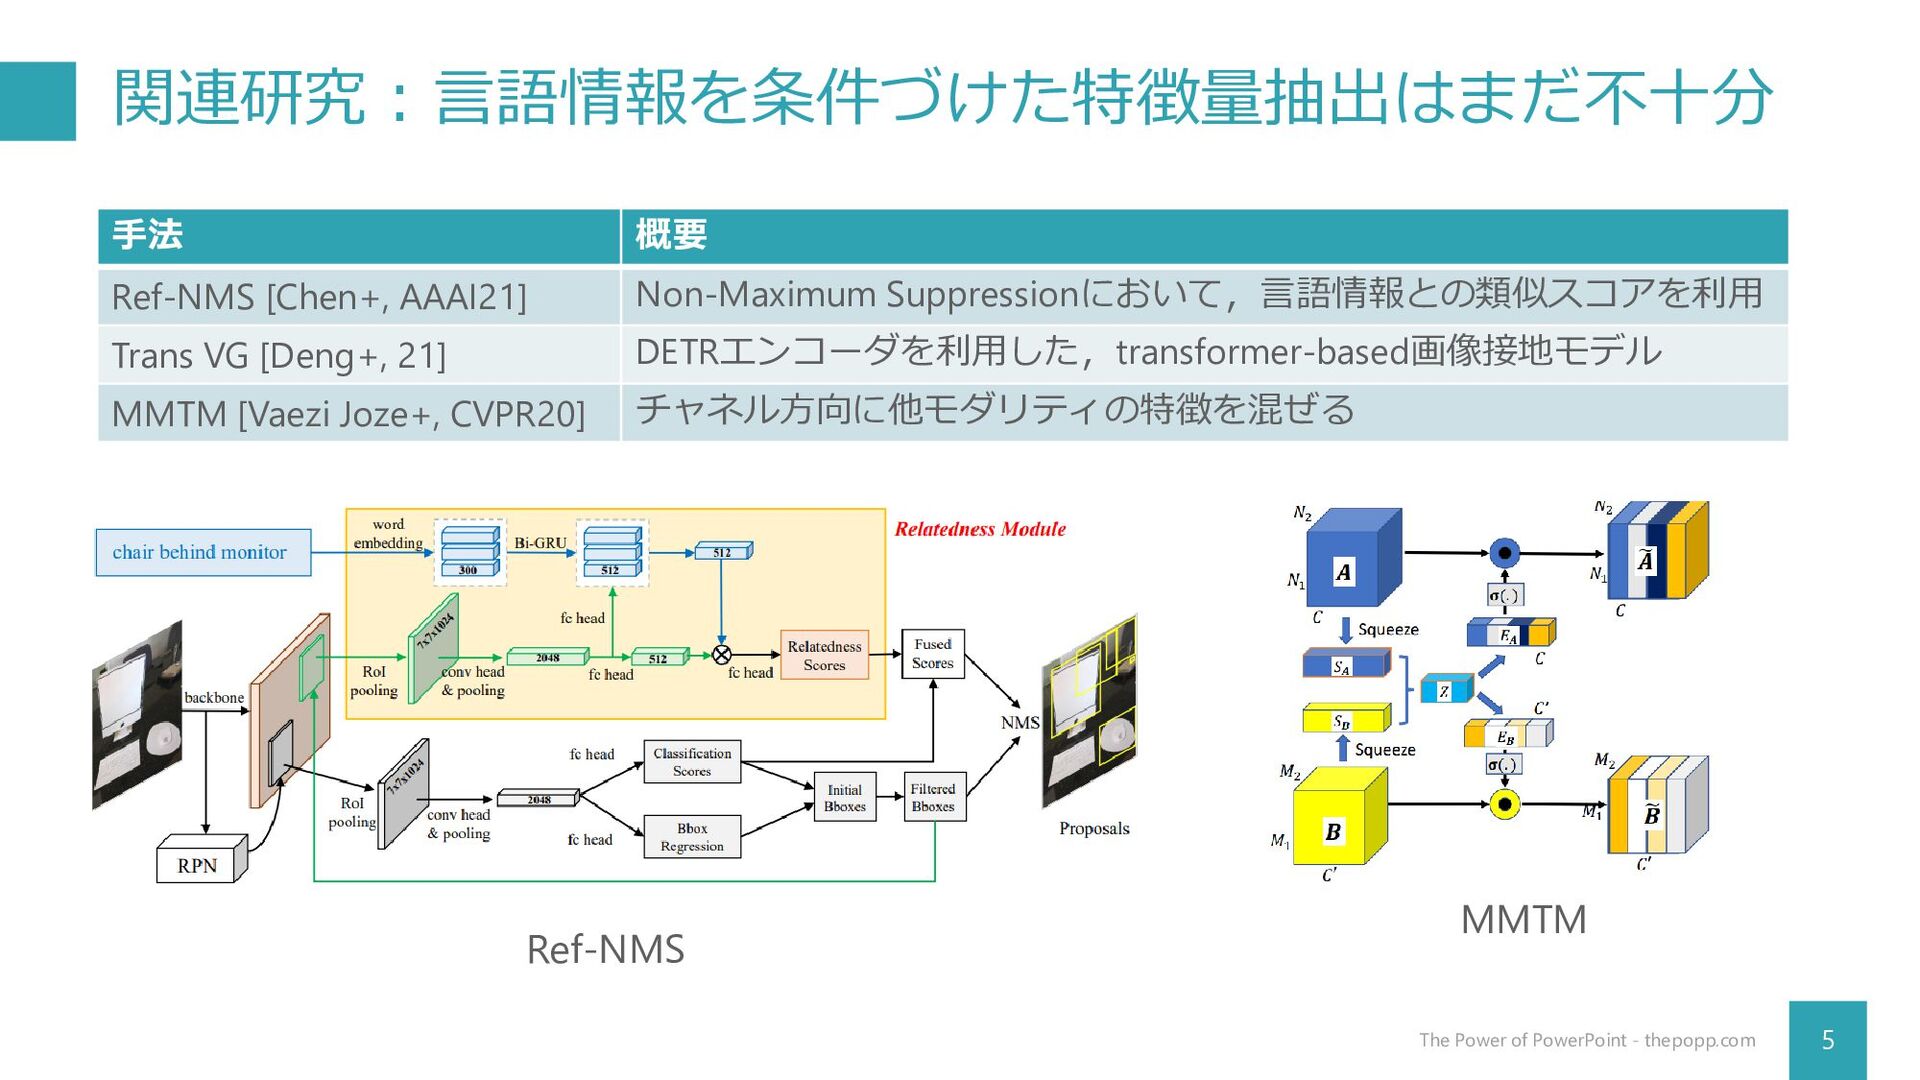
関連研究:言語情報を条件づけた特徴量抽出はまだ不十分 5 The Power of PowerPoint - thepopp.com 手法 概要
Ref-NMS [Chen+, AAAI21] Non-Maximum Suppressionにおいて,言語情報との類似スコアを利用 Trans VG [Deng+, 21] DETRエンコーダを利用した,transformer-based画像接地モデル MMTM [Vaezi Joze+, CVPR20] チャネル方向に他モダリティの特徴を混ぜる Ref-NMS MMTM
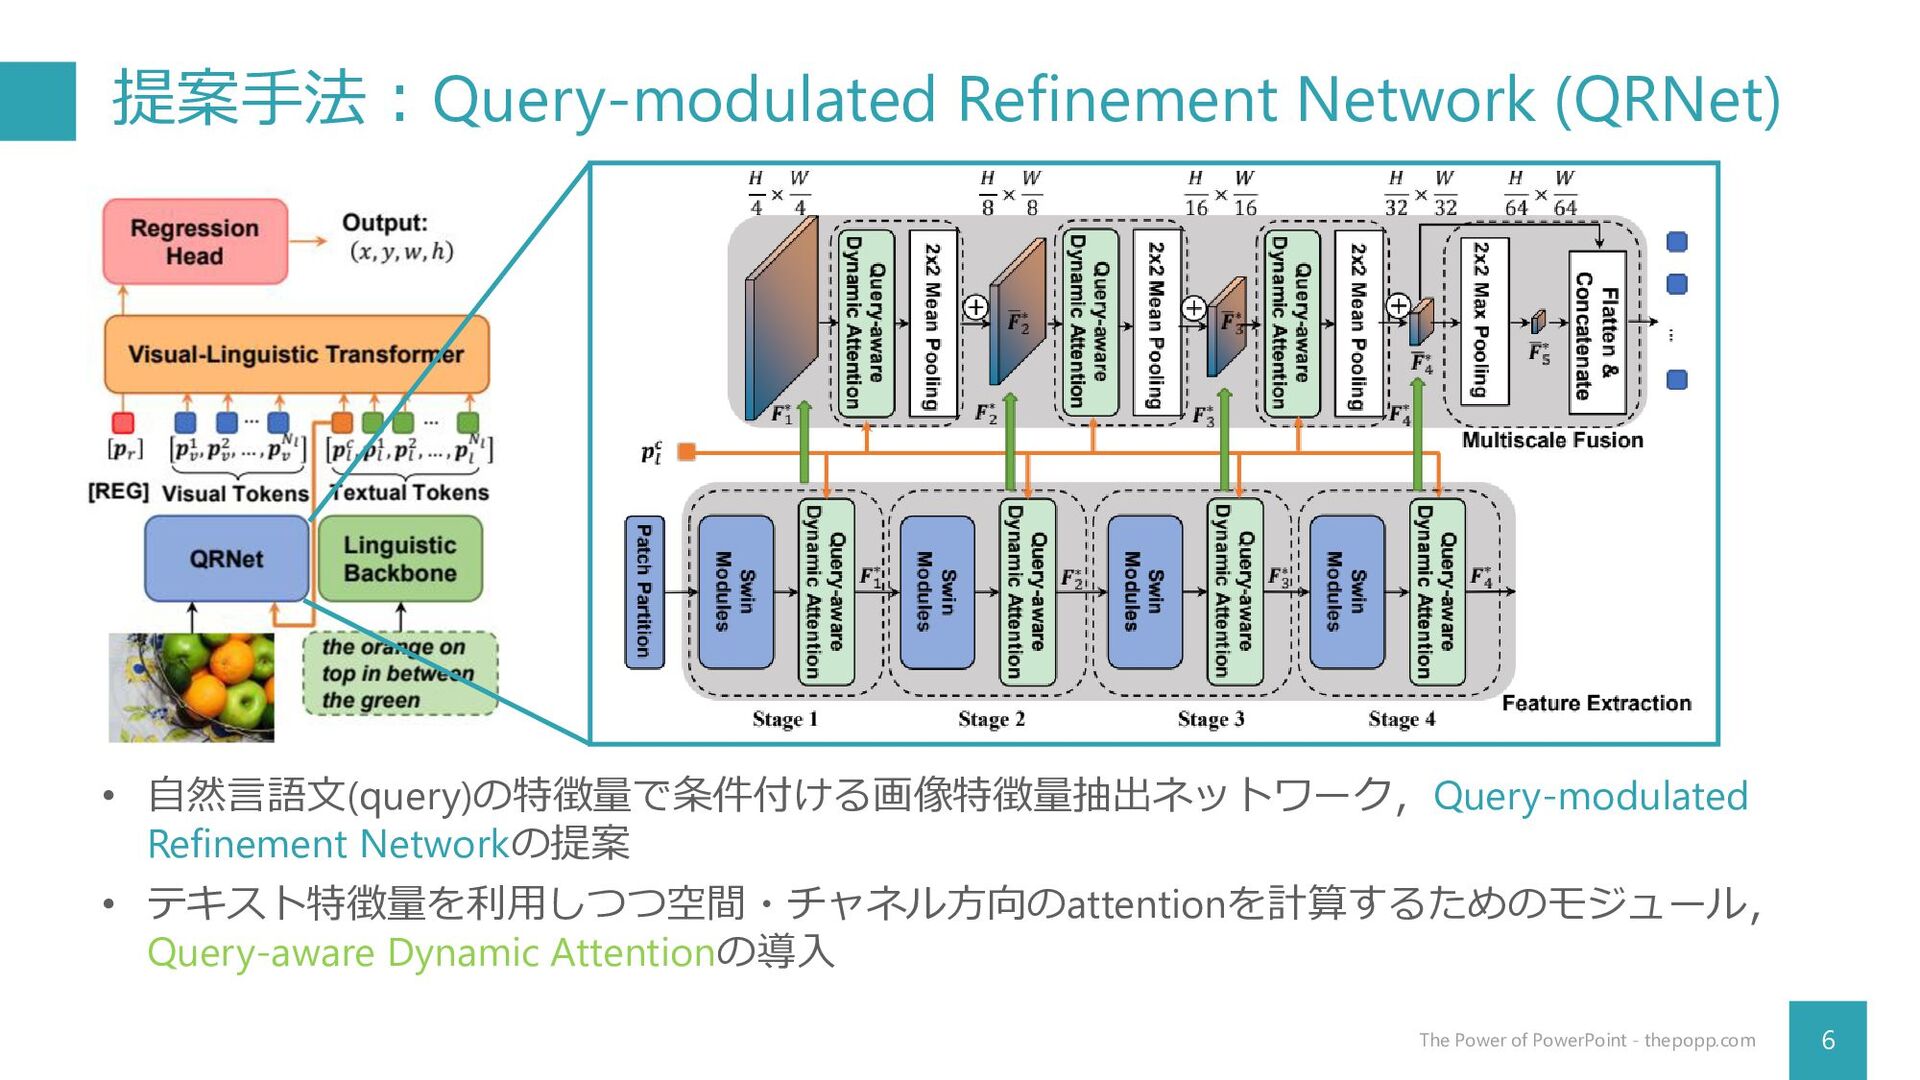
提案手法:Query-modulated Refinement Network (QRNet) 6 The Power of PowerPoint -
thepopp.com • 自然言語文(query)の特徴量で条件付ける画像特徴量抽出ネットワーク,Query-modulated Refinement Networkの提案 • テキスト特徴量を利用しつつ空間・チャネル方向のattentionを計算するためのモジュール, Query-aware Dynamic Attentionの導入
QRNet:自然言語文から獲得した[CLS]トークンを利用 7 The Power of PowerPoint - thepopp.com 画像 𝐼,自然言語文
𝑞 𝑻 = 𝑓BERT 𝑞 = {𝒑𝑙 𝑐, 𝒑𝑙 1, … , 𝒑 𝑙 𝑁𝑣} Linguistic Backbone:BERT Embedder ネットワーク入力 QRNetの入出力 𝑽 = 𝑓QRNet 𝐼, 𝒑𝑙 𝑐
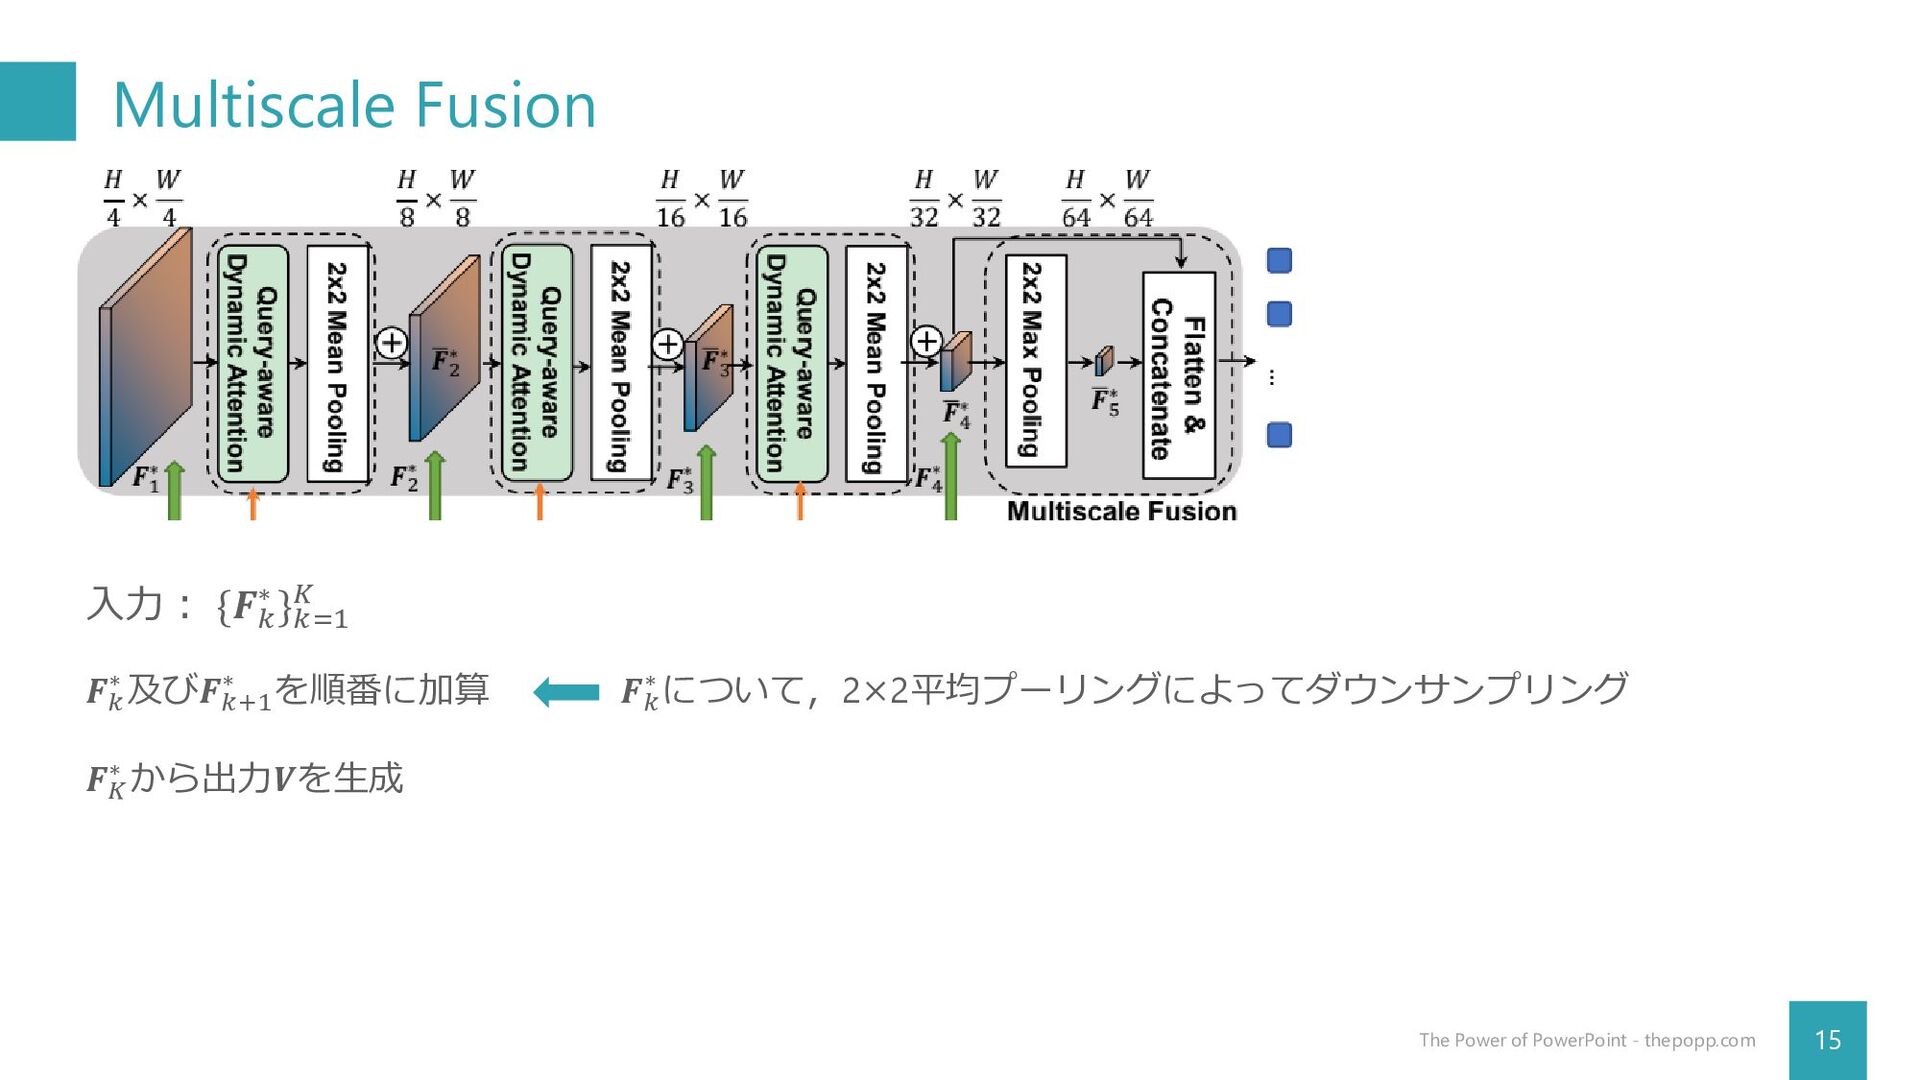
QRNet:2つのモジュールから構成 8 The Power of PowerPoint - thepopp.com Multiscale Fusion
Feature Extraction • 異なる解像度で計算されたattentionを 混ぜ合わせる • 出力𝑽を生成 • Swin-Transformer[Liu+, ICCV21]を拡張 • 言語情報を利用しつつ画像特徴を抽出 • 特徴量はMultiscale Fusionで利用
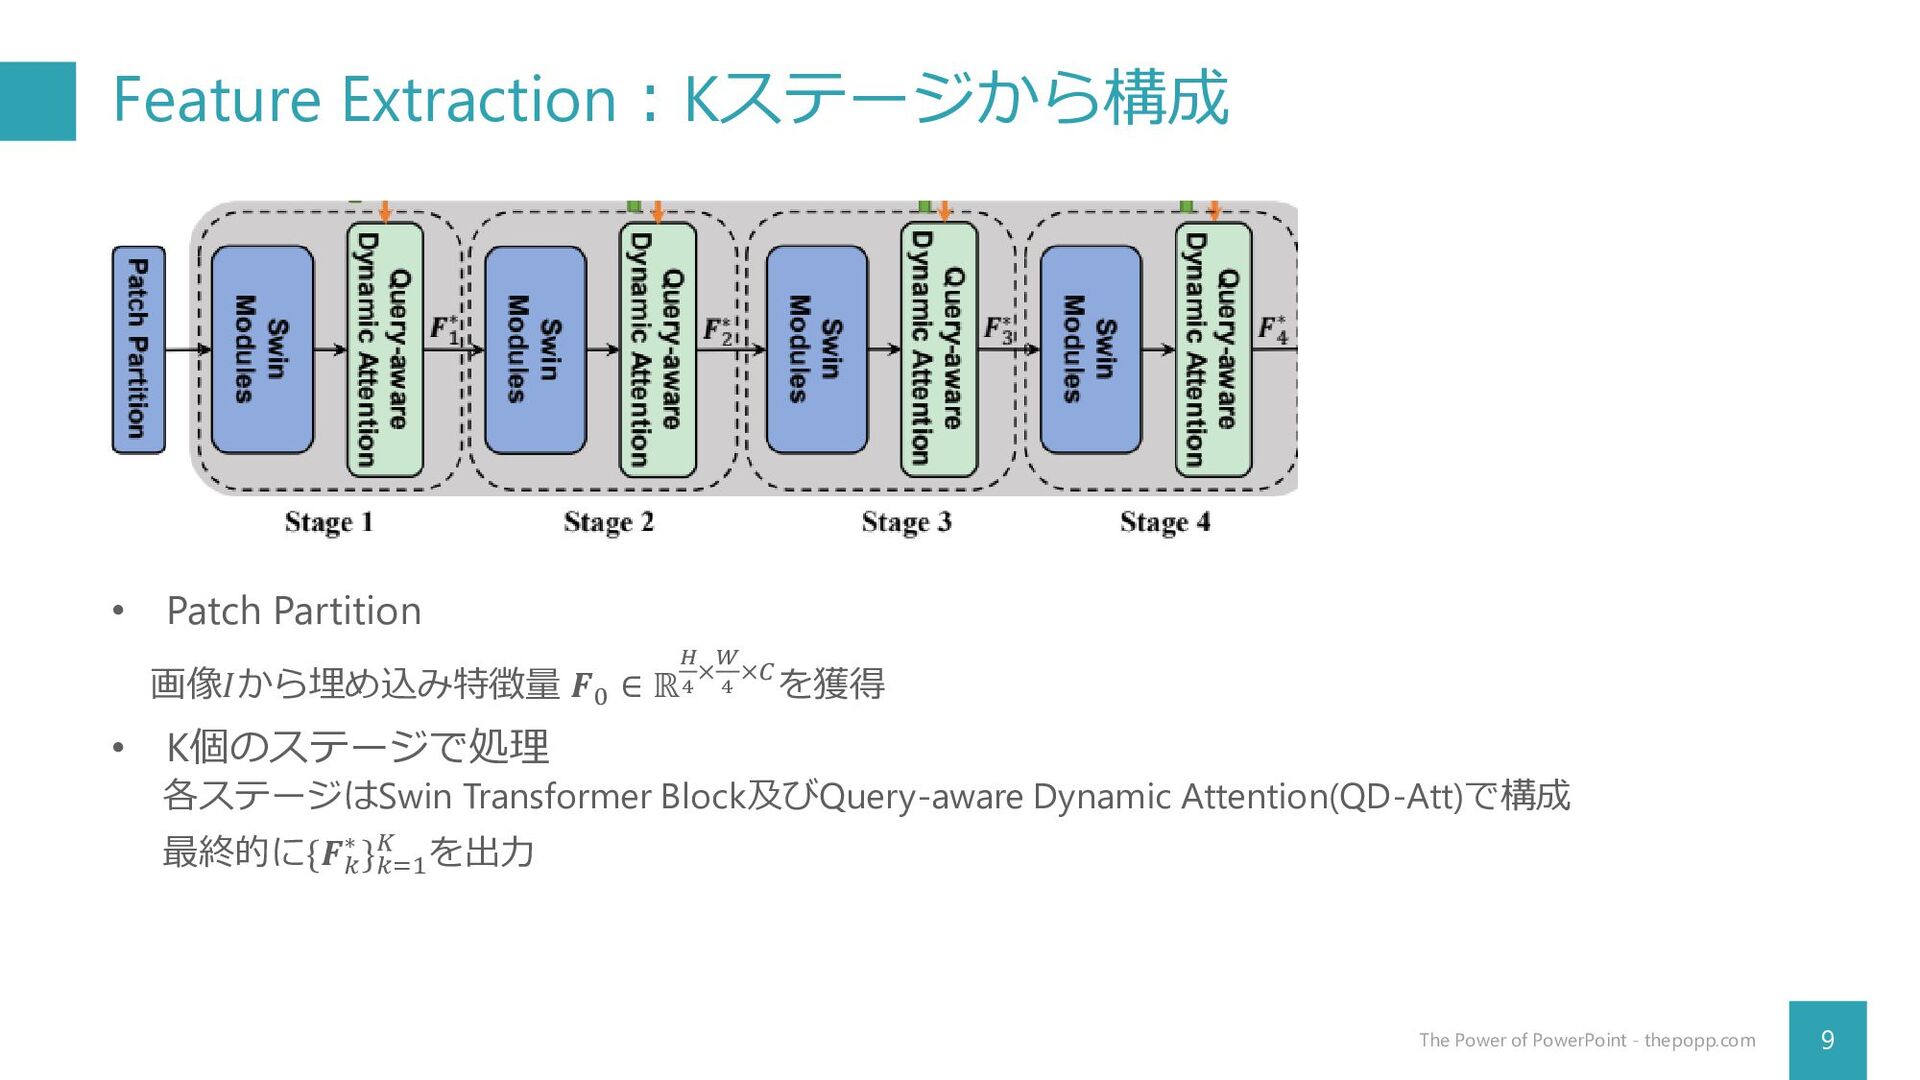
Feature Extraction:Kステージから構成 9 The Power of PowerPoint - thepopp.com •
Patch Partition 画像𝐼から埋め込み特徴量 𝑭0 ∈ ℝ 𝐻 4 ×𝑊 4 ×𝐶を獲得 • K個のステージで処理 各ステージはSwin Transformer Block及びQuery-aware Dynamic Attention(QD-Att)で構成 最終的に{𝑭𝑘 ∗ }𝑘=1 𝐾 を出力
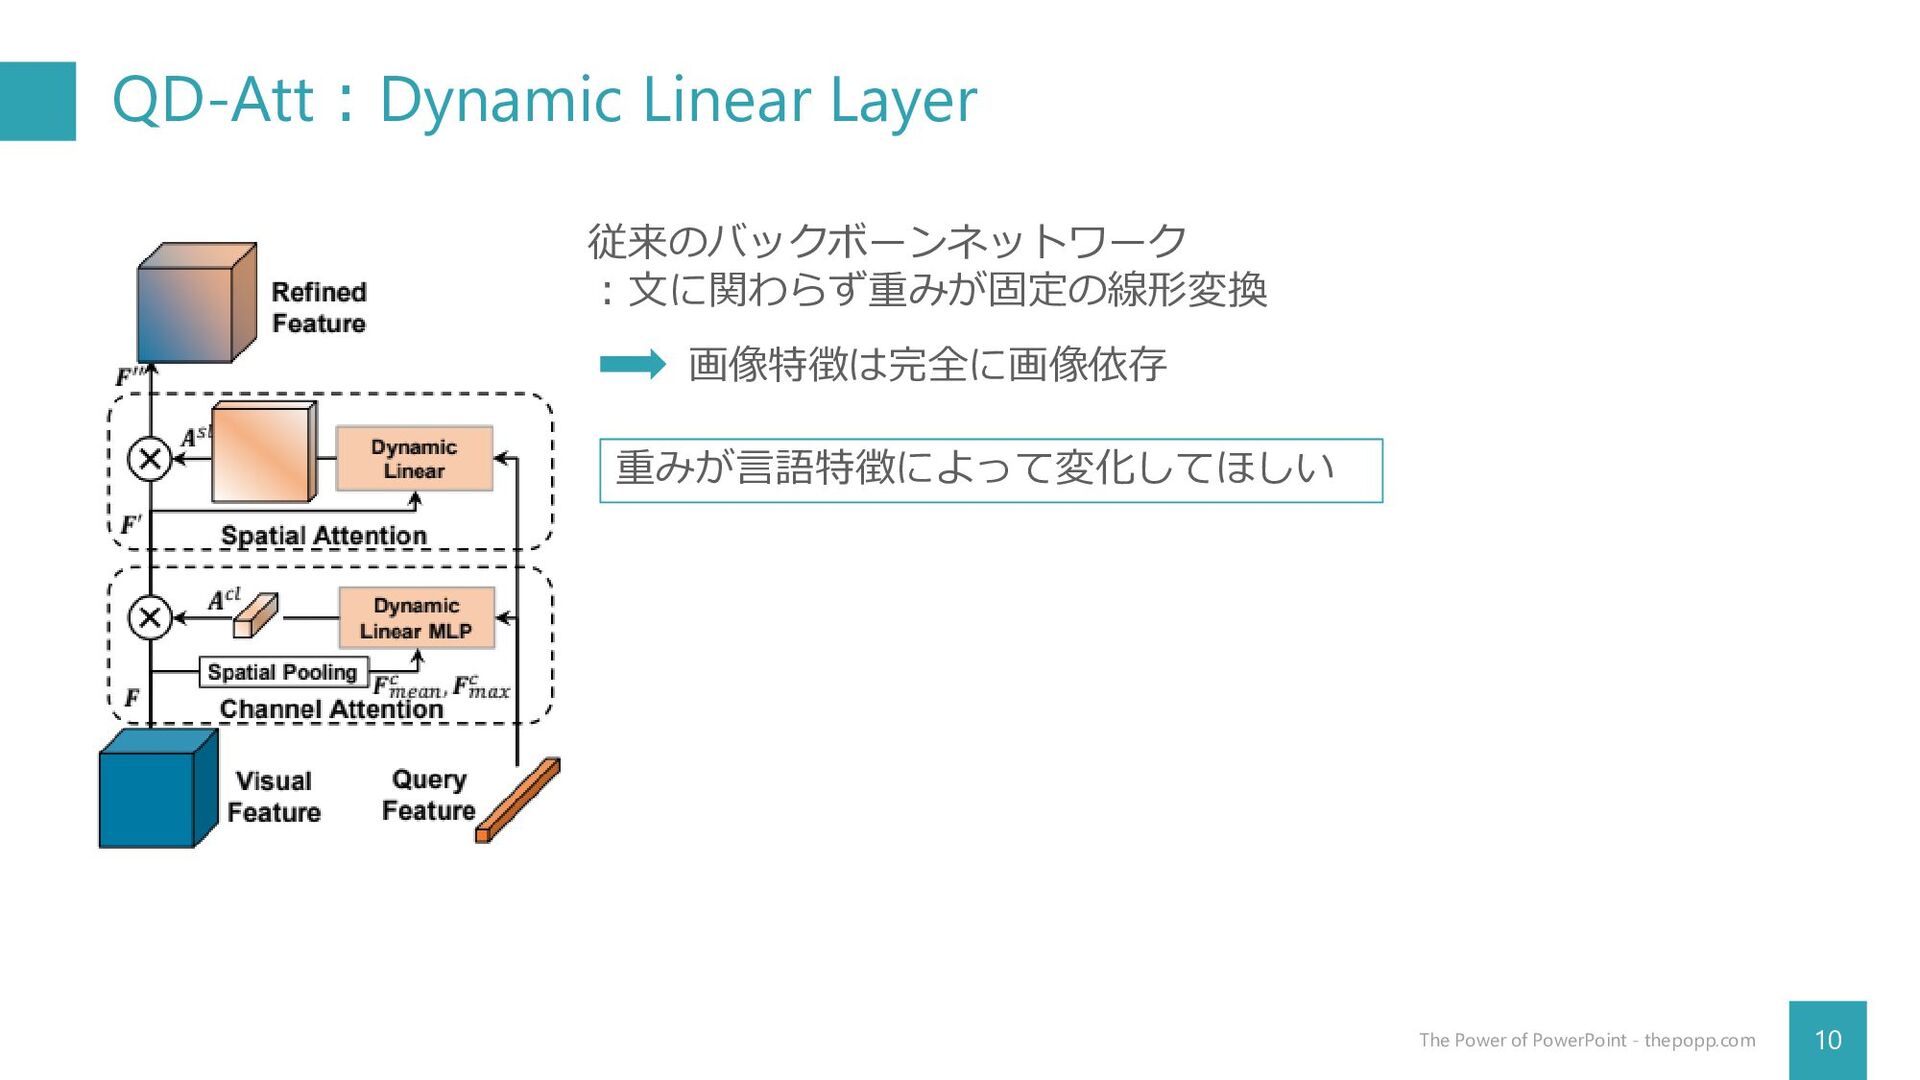
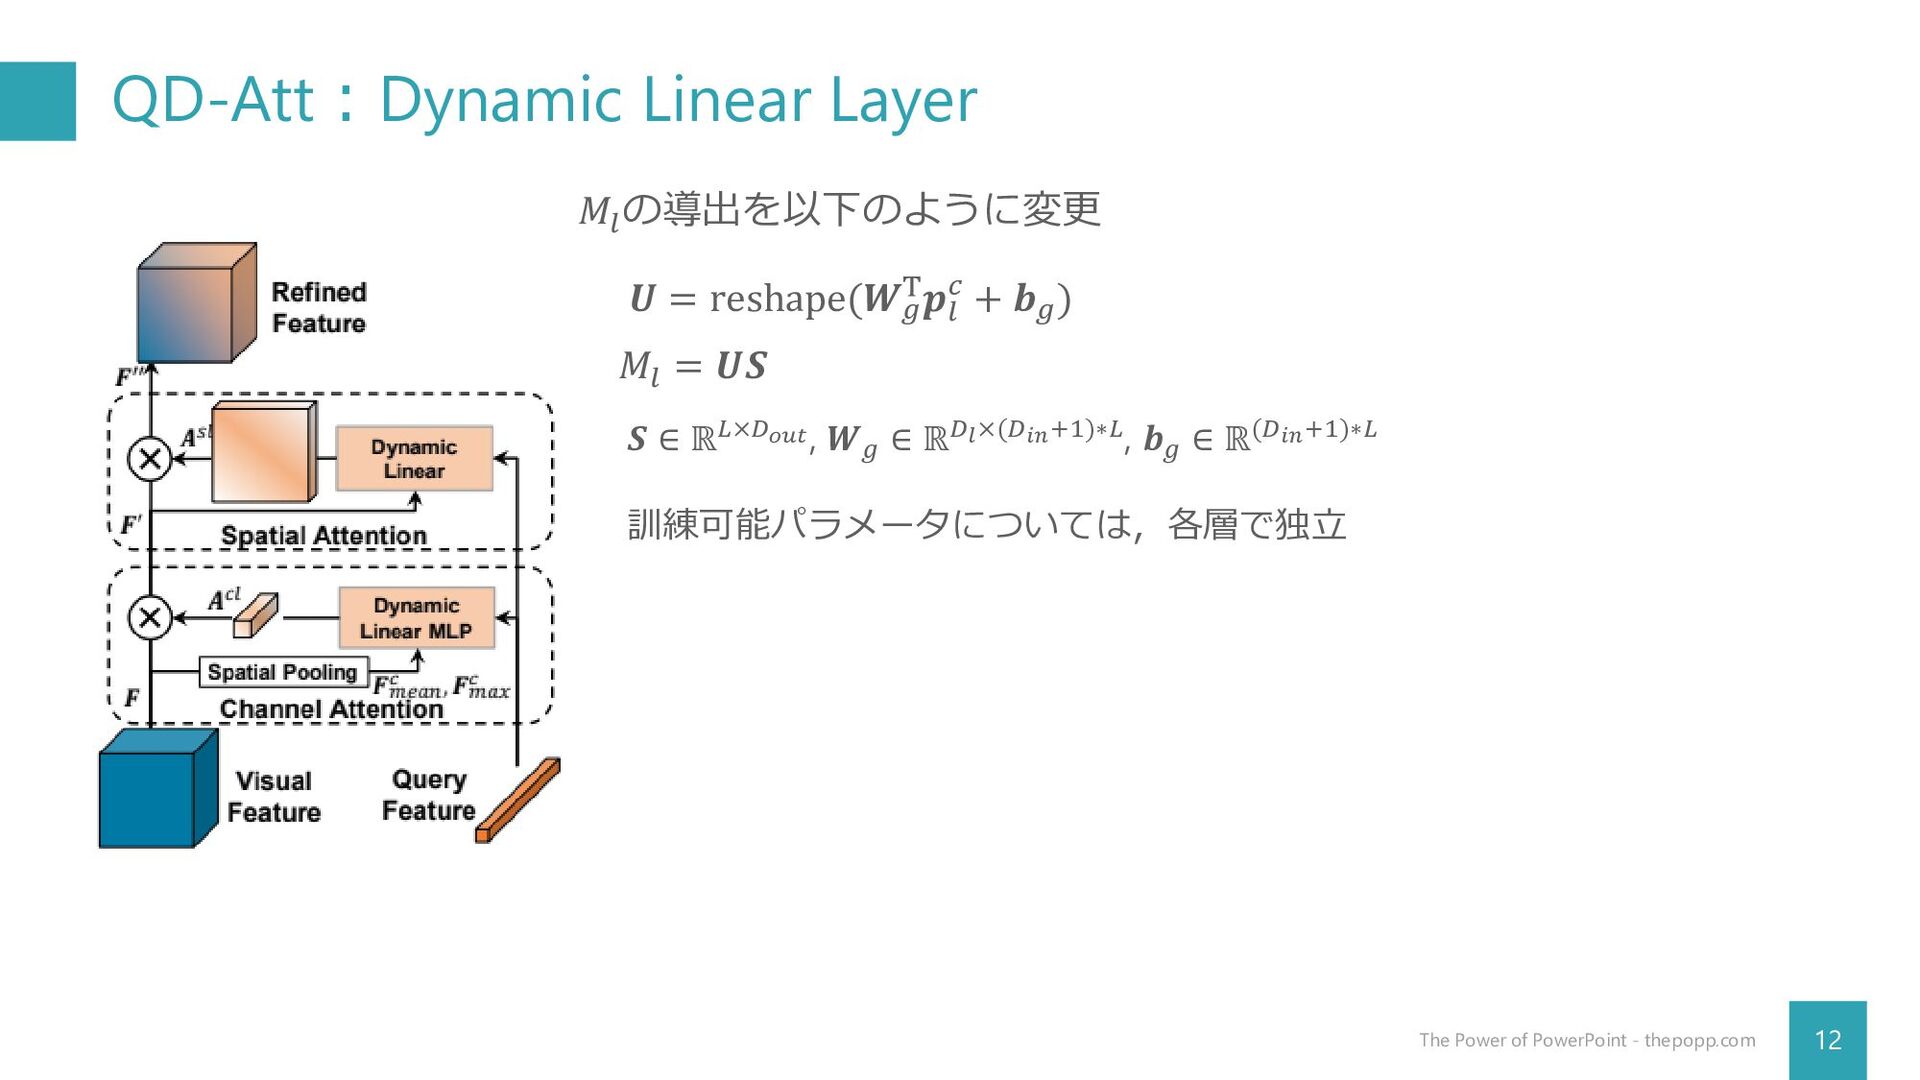
QD-Att:Dynamic Linear Layer 10 The Power of PowerPoint - thepopp.com
従来のバックボーンネットワーク :文に関わらず重みが固定の線形変換 重みが言語特徴によって変化してほしい 画像特徴は完全に画像依存
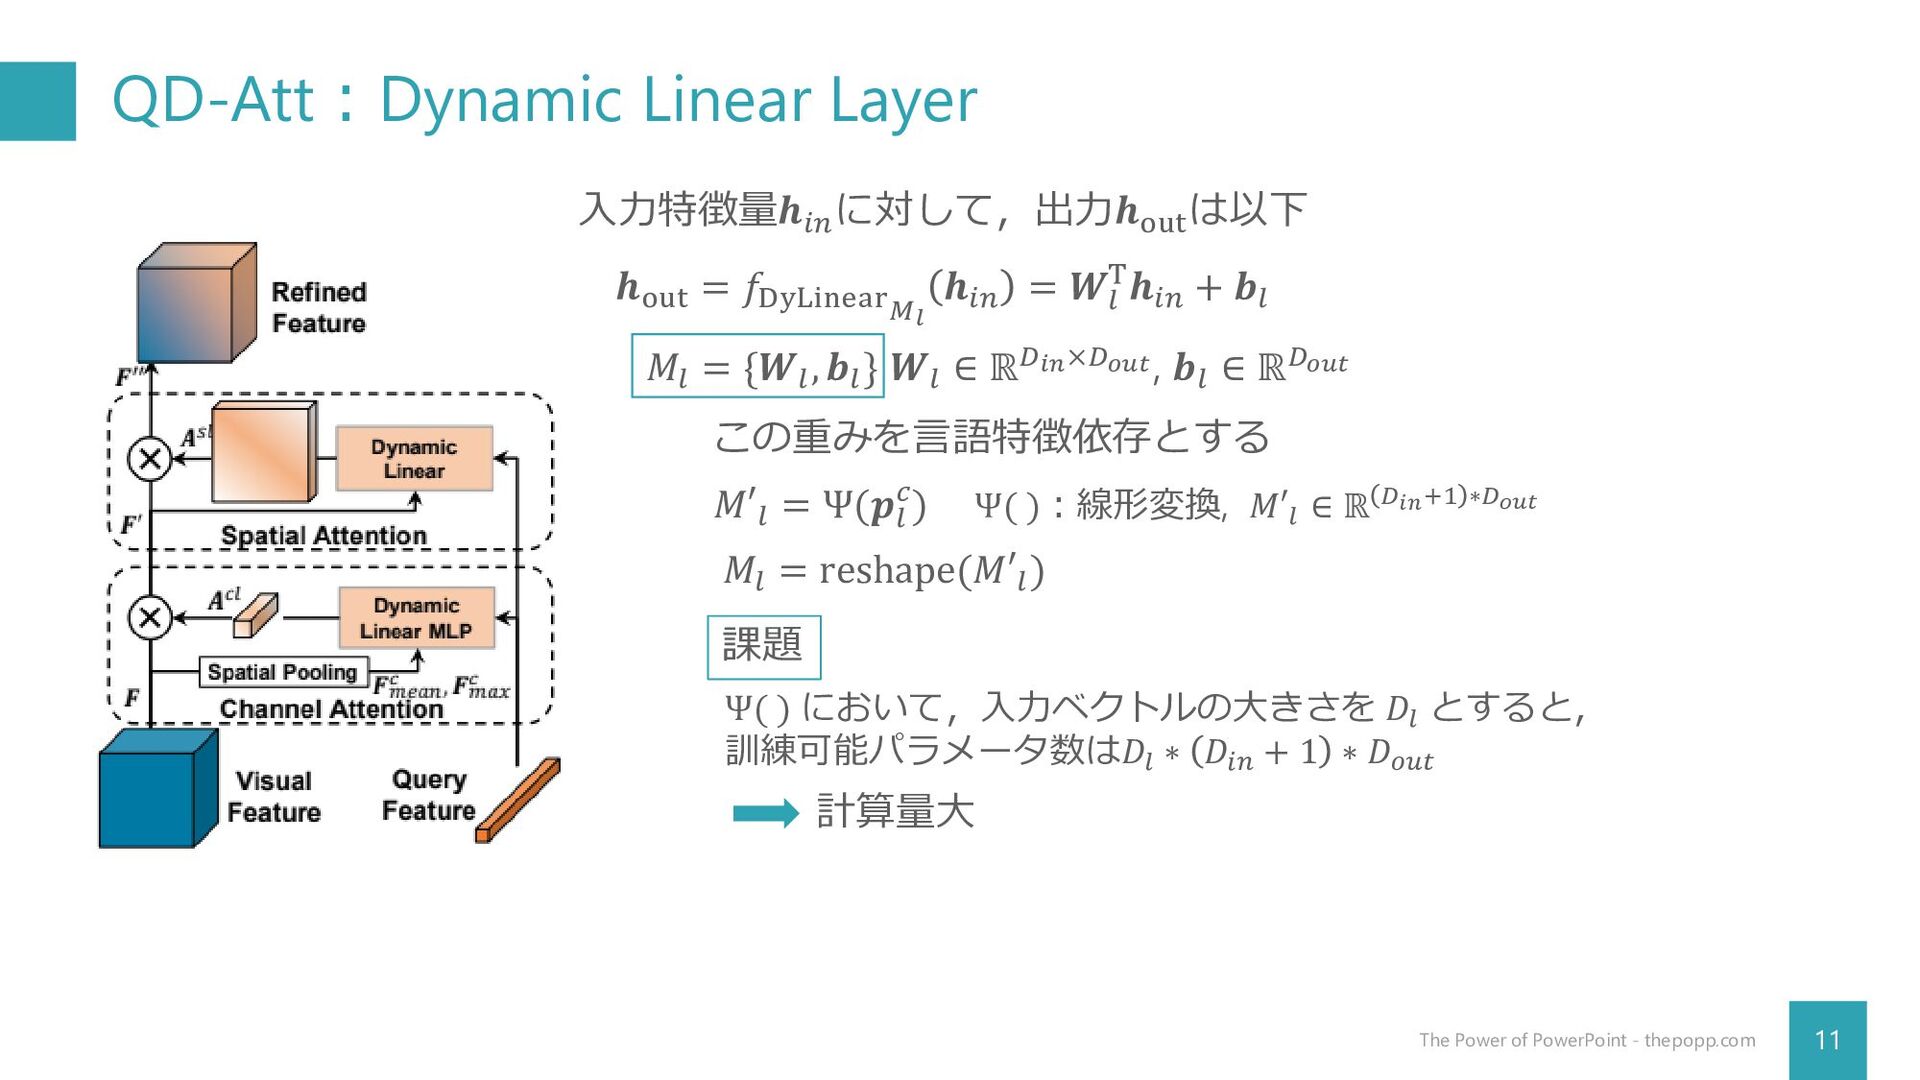
QD-Att:Dynamic Linear Layer 11 The Power of PowerPoint - thepopp.com
𝒉out = 𝑓DyLinear𝑀𝑙 𝒉𝑖𝑛 = 𝑾𝑙 T𝒉𝑖𝑛 + 𝒃𝑙 入力特徴量𝒉𝑖𝑛 に対して,出力𝒉out は以下 𝑀𝑙 = {𝑾𝑙 , 𝒃𝑙 } 𝑾𝑙 ∈ ℝ𝐷𝑖𝑛×𝐷𝑜𝑢𝑡, 𝒃𝑙 ∈ ℝ𝐷𝑜𝑢𝑡 この重みを言語特徴依存とする 𝑀′𝑙 = Ψ(𝒑𝑙 𝑐) Ψ( ):線形変換, 𝑀′𝑙 ∈ ℝ 𝐷𝑖𝑛+1 ∗𝐷𝑜𝑢𝑡 課題 Ψ( ) において,入力ベクトルの大きさを 𝐷𝑙 とすると, 訓練可能パラメータ数は𝐷𝑙 ∗ 𝐷𝑖𝑛 + 1 ∗ 𝐷𝑜𝑢𝑡 計算量大 𝑀𝑙 = reshape(𝑀′𝑙 )
QD-Att:Dynamic Linear Layer 12 The Power of PowerPoint - thepopp.com
𝑀𝑙 の導出を以下のように変更 𝑼 = reshape(𝑾𝑔 T𝒑𝑙 𝑐 + 𝒃𝑔 ) 𝑀𝑙 = 𝑼𝑺 𝑺 ∈ ℝ𝐿×𝐷𝑜𝑢𝑡, 𝑾𝑔 ∈ ℝ𝐷𝑙×(𝐷𝑖𝑛+1)∗𝐿, 𝒃𝑔 ∈ ℝ(𝐷𝑖𝑛+1)∗𝐿 訓練可能パラメータについては,各層で独立
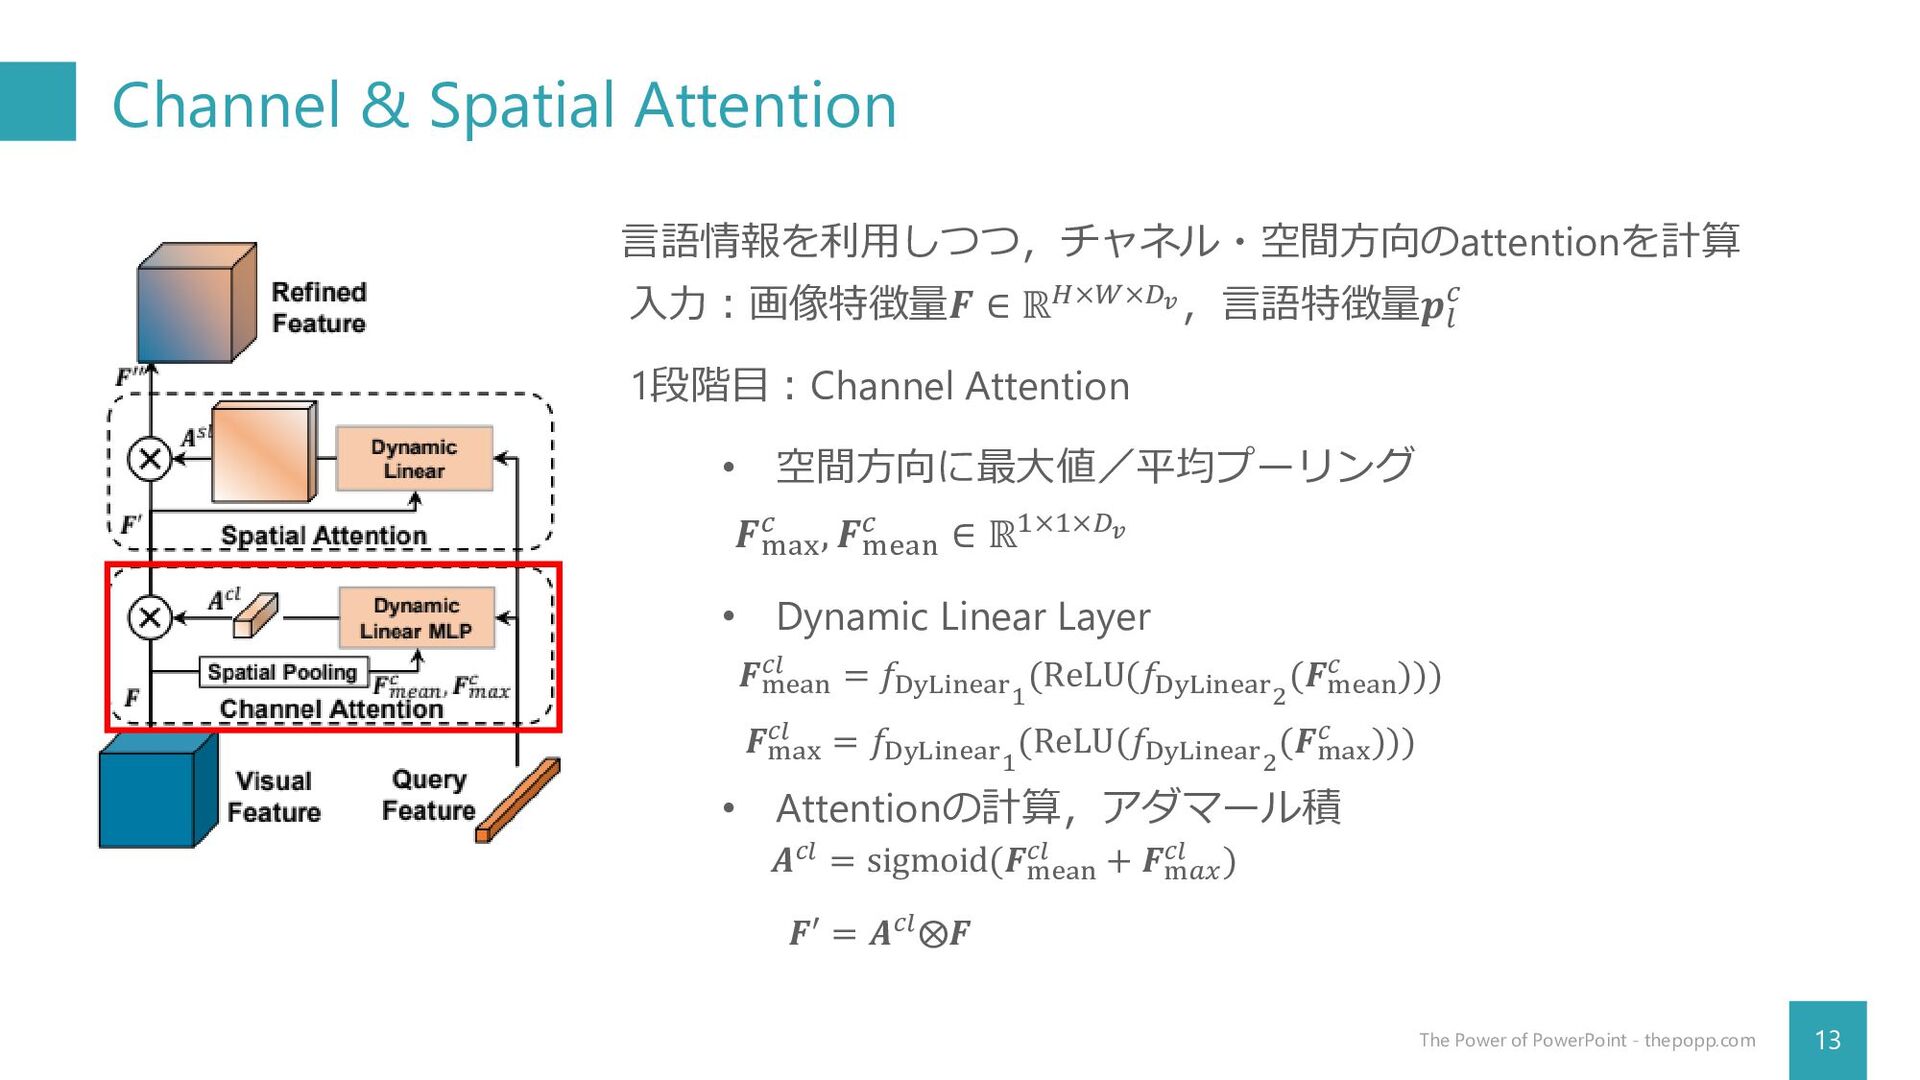
Channel & Spatial Attention 13 The Power of PowerPoint -
thepopp.com 言語情報を利用しつつ,チャネル・空間方向のattentionを計算 1段階目:Channel Attention • 空間方向に最大値/平均プーリング 𝑭max 𝑐 , 𝑭mean 𝑐 ∈ ℝ1×1×𝐷𝑣 • Dynamic Linear Layer 入力:画像特徴量𝑭 ∈ ℝ𝐻×𝑊×𝐷𝑣,言語特徴量𝒑𝑙 𝑐 𝑭mean 𝑐𝑙 = 𝑓DyLinear1 (ReLU(𝑓DyLinear2 (𝑭mean 𝑐 ))) 𝑭max 𝑐𝑙 = 𝑓DyLinear1 (ReLU(𝑓DyLinear2 (𝑭max 𝑐 ))) • Attentionの計算,アダマール積 𝑨𝑐𝑙 = sigmoid(𝑭mean 𝑐𝑙 + 𝑭m𝑎𝑥 𝑐𝑙 ) 𝑭′ = 𝑨𝑐𝑙⨂𝑭
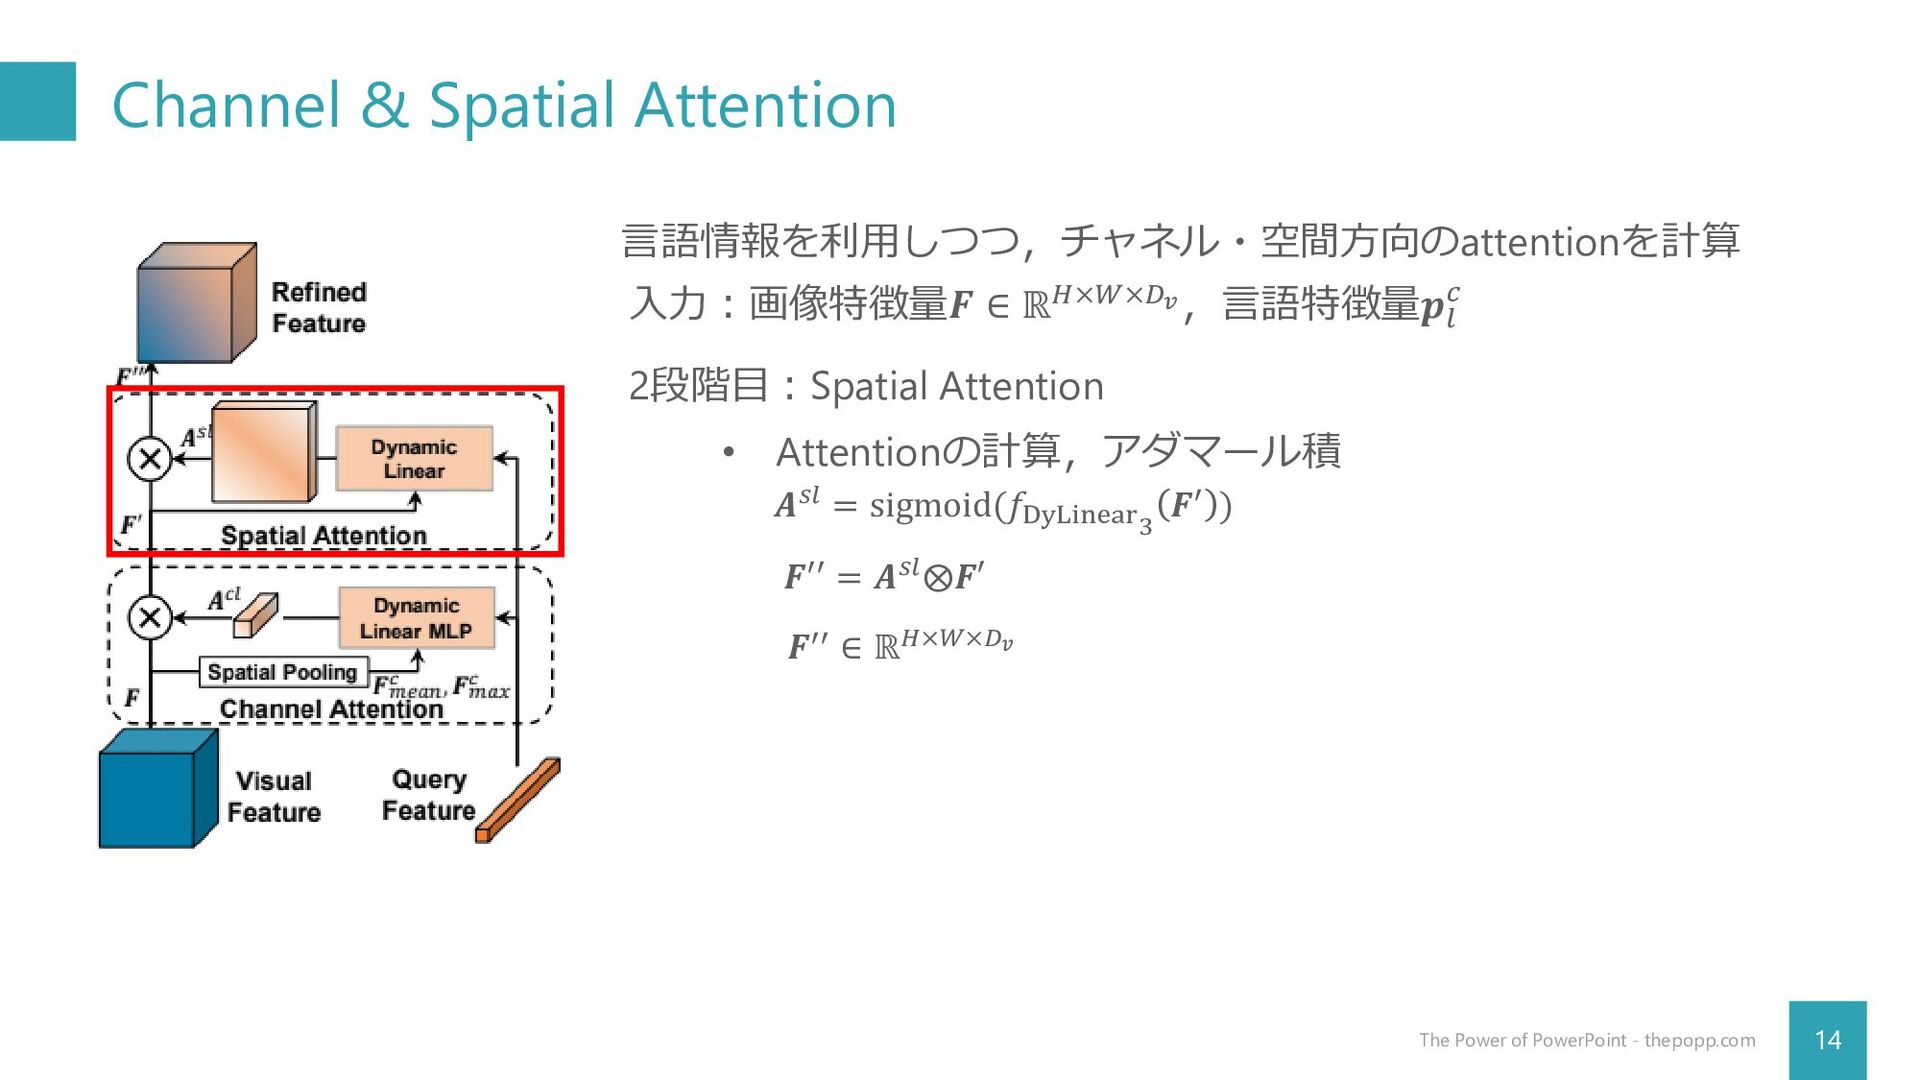
Channel & Spatial Attention 14 The Power of PowerPoint -
thepopp.com 言語情報を利用しつつ,チャネル・空間方向のattentionを計算 2段階目:Spatial Attention 入力:画像特徴量𝑭 ∈ ℝ𝐻×𝑊×𝐷𝑣,言語特徴量𝒑𝑙 𝑐 • Attentionの計算,アダマール積 𝑨𝑠𝑙 = sigmoid(𝑓DyLinear3 𝑭′ ) 𝑭′′ = 𝑨𝑠𝑙⨂𝑭′ 𝑭′′ ∈ ℝ𝐻×𝑊×𝐷𝑣
Multiscale Fusion 15 The Power of PowerPoint - thepopp.com 入力:
{𝑭𝑘 ∗ }𝑘=1 𝐾 𝑭𝑘 ∗ 及び𝑭𝑘+1 ∗ を順番に加算 𝑭𝑘 ∗ について,2×2平均プーリングによってダウンサンプリング 𝑭𝐾 ∗ から出力𝑽を生成
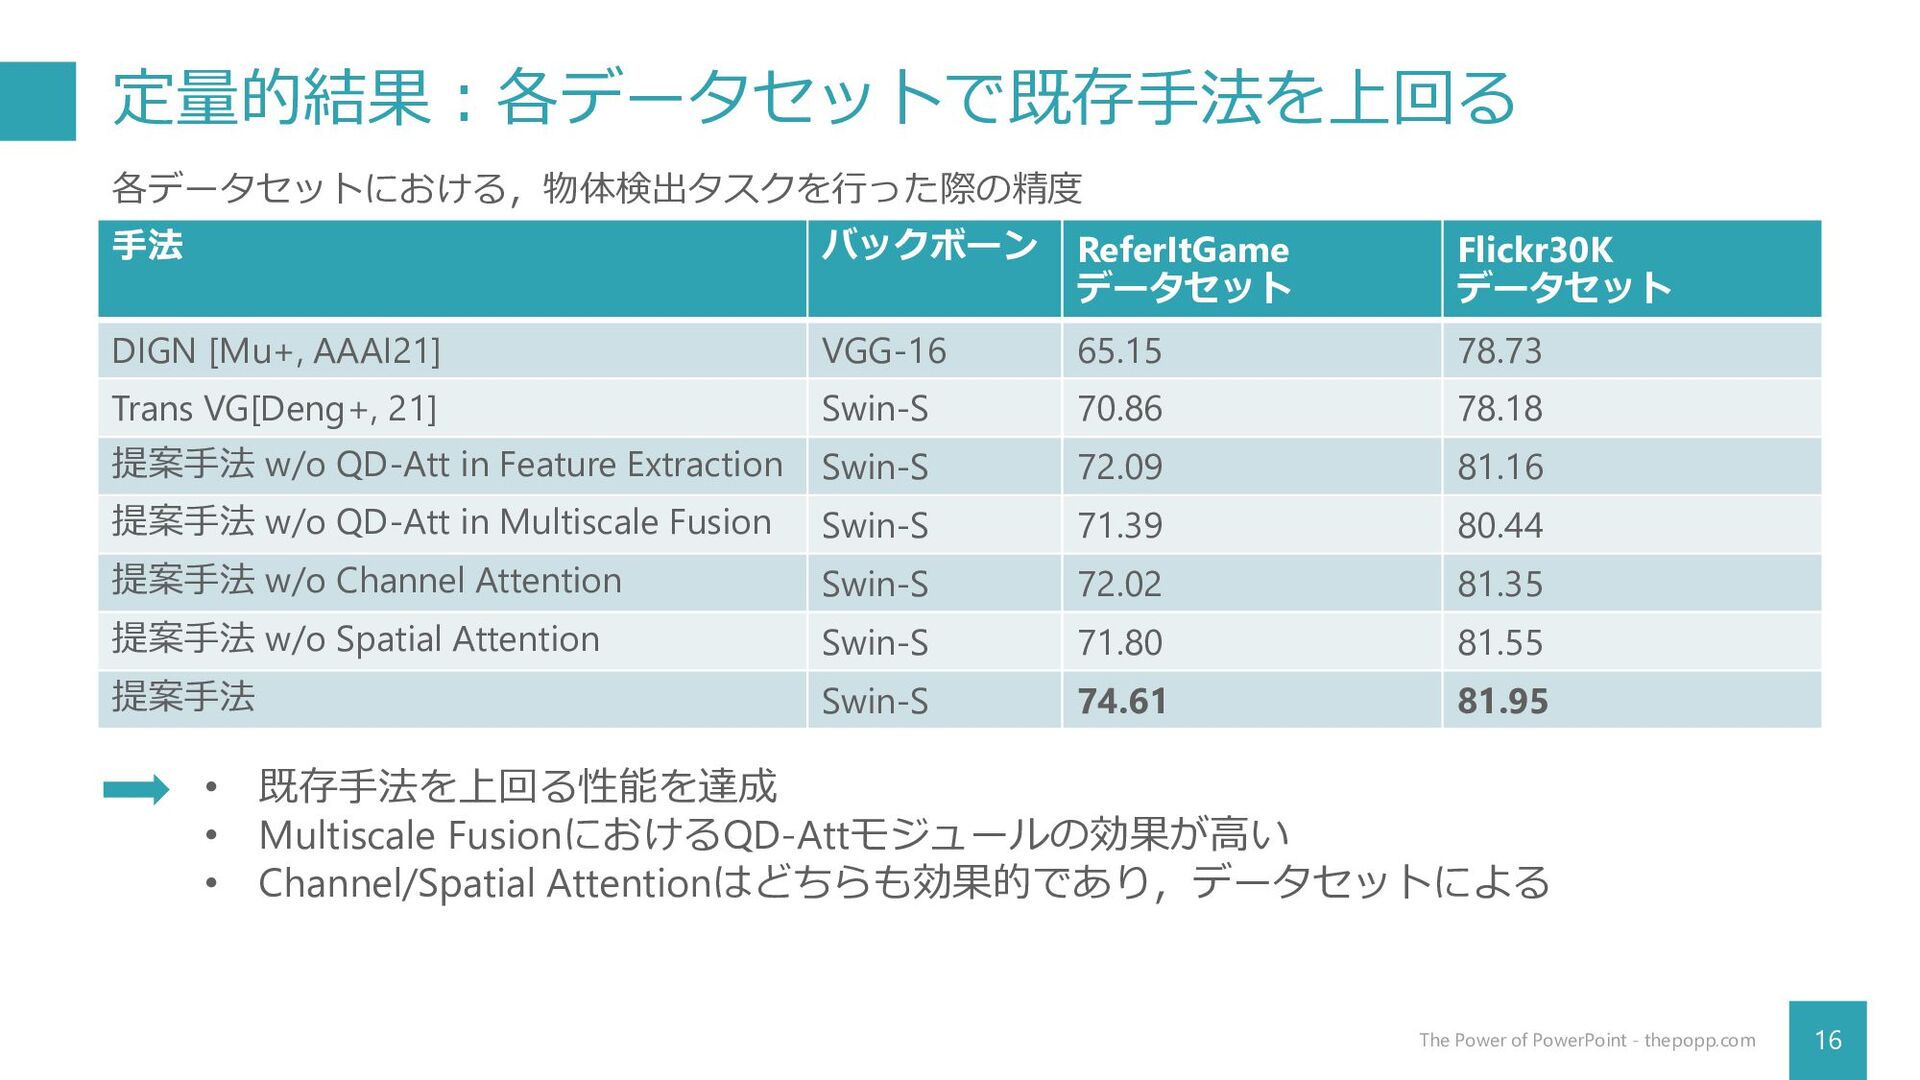
定量的結果:各データセットで既存手法を上回る 16 The Power of PowerPoint - thepopp.com 手法 バックボーン
ReferItGame データセット Flickr30K データセット DIGN [Mu+, AAAI21] VGG-16 65.15 78.73 Trans VG[Deng+, 21] Swin-S 70.86 78.18 提案手法 w/o QD-Att in Feature Extraction Swin-S 72.09 81.16 提案手法 w/o QD-Att in Multiscale Fusion Swin-S 71.39 80.44 提案手法 w/o Channel Attention Swin-S 72.02 81.35 提案手法 w/o Spatial Attention Swin-S 71.80 81.55 提案手法 Swin-S 74.61 81.95 各データセットにおける,物体検出タスクを行った際の精度 • 既存手法を上回る性能を達成 • Multiscale FusionにおけるQD-Attモジュールの効果が高い • Channel/Spatial Attentionはどちらも効果的であり,データセットによる
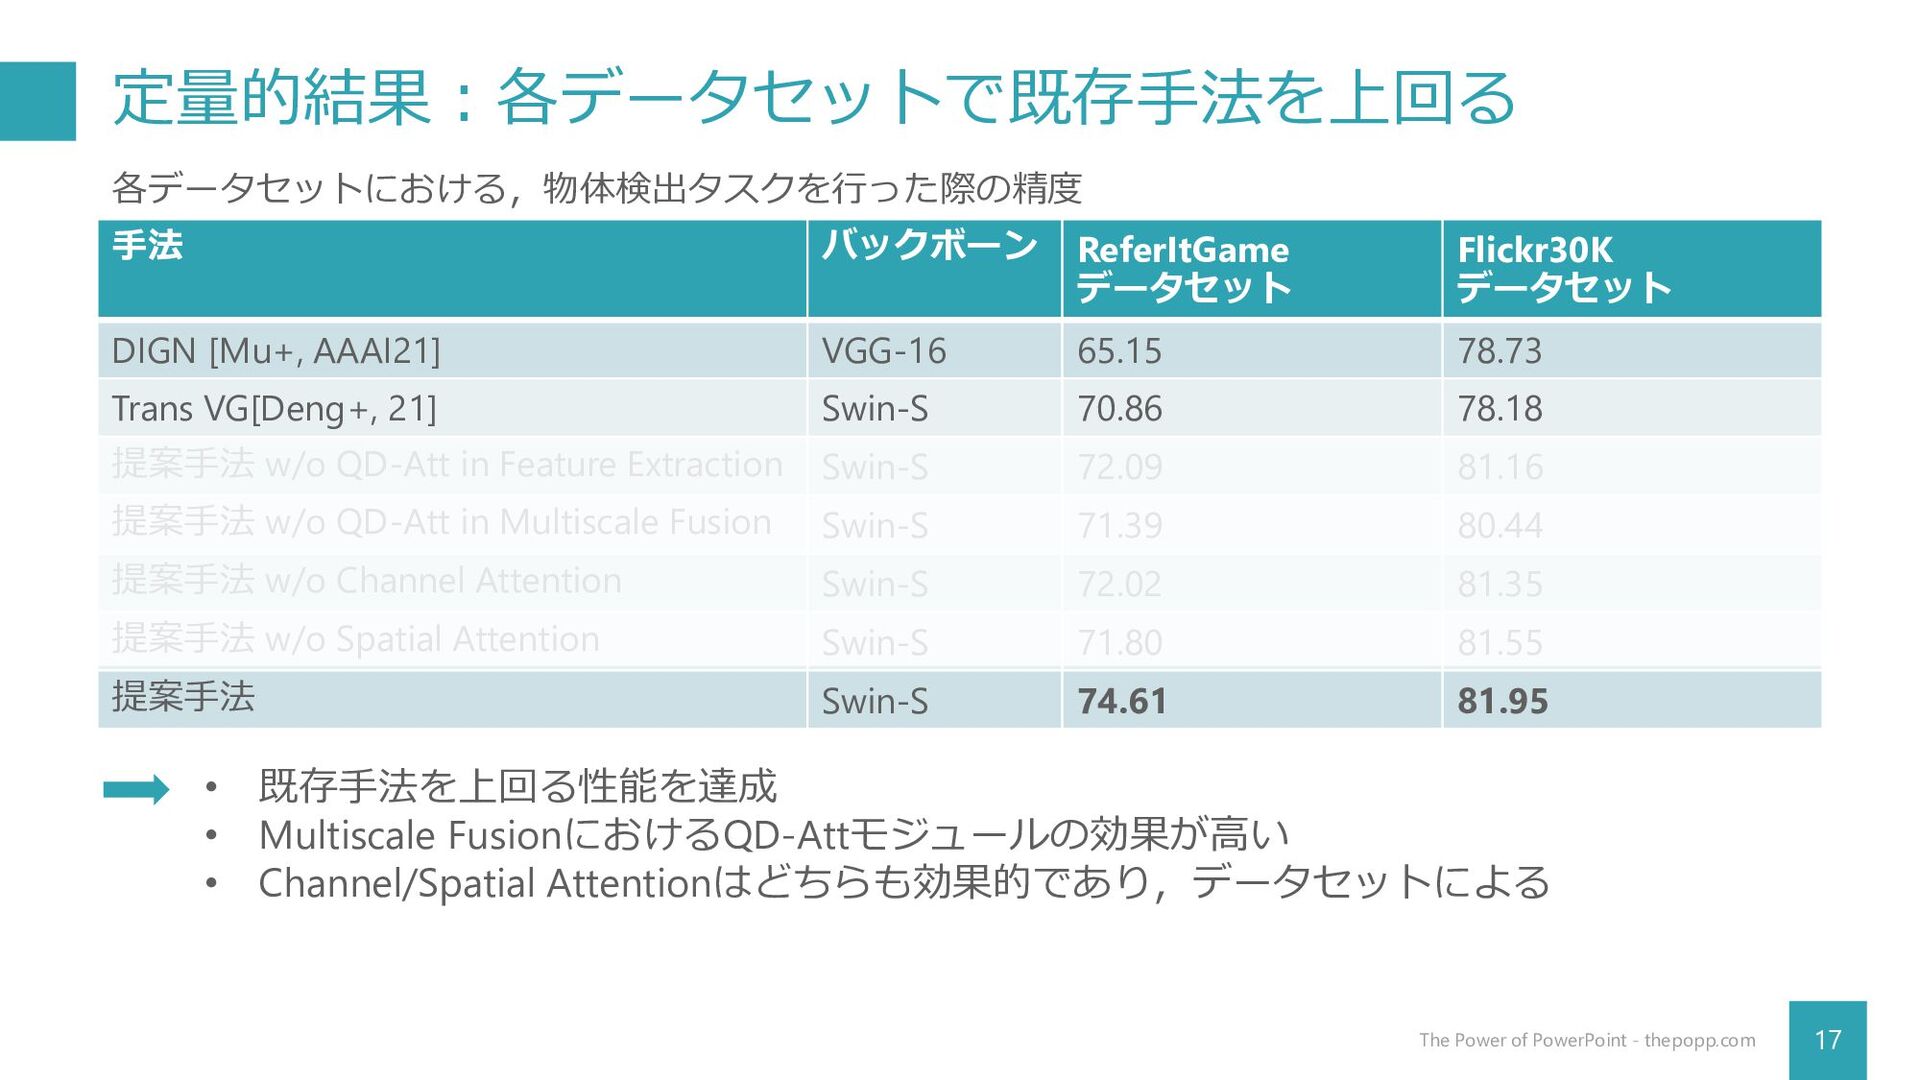
定量的結果:各データセットで既存手法を上回る 17 The Power of PowerPoint - thepopp.com 手法 バックボーン
ReferItGame データセット Flickr30K データセット DIGN [Mu+, AAAI21] VGG-16 65.15 78.73 Trans VG[Deng+, 21] Swin-S 70.86 78.18 提案手法 w/o QD-Att in Feature Extraction Swin-S 72.09 81.16 提案手法 w/o QD-Att in Multiscale Fusion Swin-S 71.39 80.44 提案手法 w/o Channel Attention Swin-S 72.02 81.35 提案手法 w/o Spatial Attention Swin-S 71.80 81.55 提案手法 Swin-S 74.61 81.95 各データセットにおける,物体検出タスクを行った際の精度 • 既存手法を上回る性能を達成 • Multiscale FusionにおけるQD-Attモジュールの効果が高い • Channel/Spatial Attentionはどちらも効果的であり,データセットによる
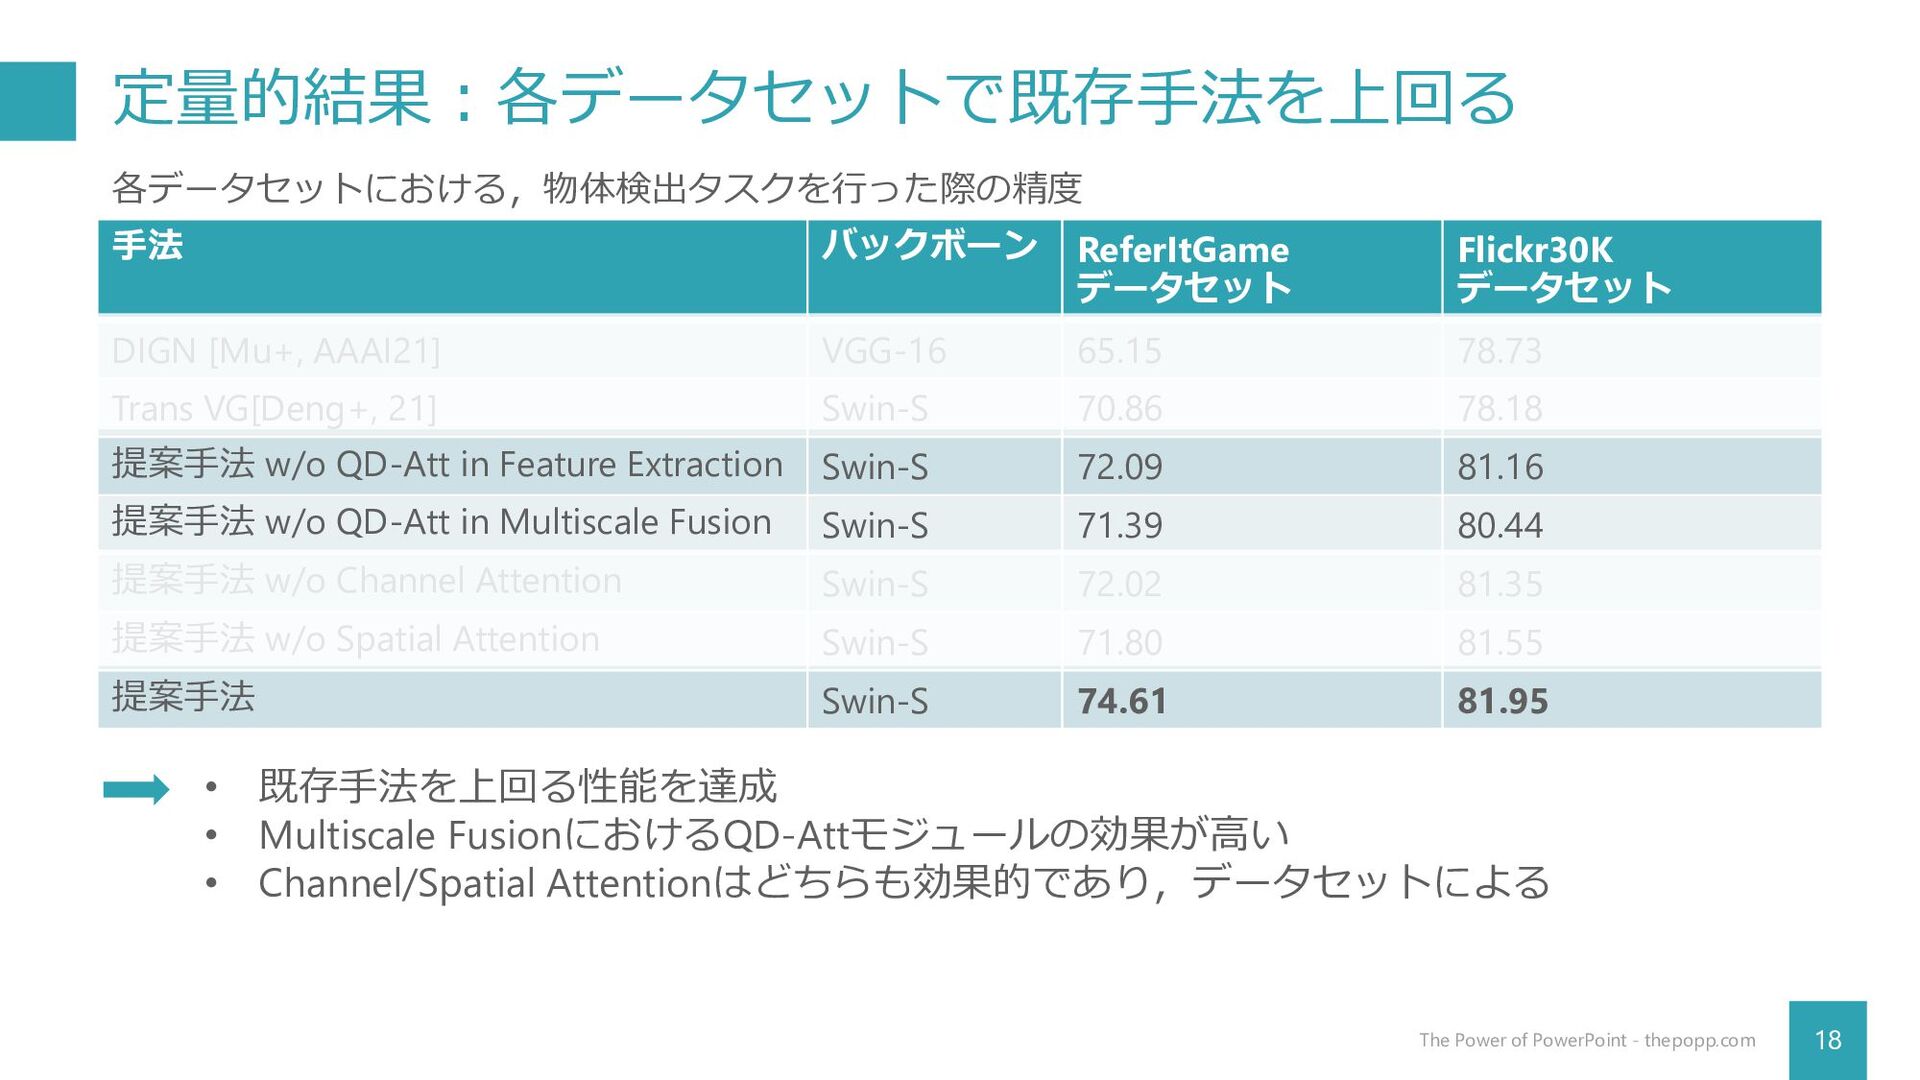
定量的結果:各データセットで既存手法を上回る 18 The Power of PowerPoint - thepopp.com 手法 バックボーン
ReferItGame データセット Flickr30K データセット DIGN [Mu+, AAAI21] VGG-16 65.15 78.73 Trans VG[Deng+, 21] Swin-S 70.86 78.18 提案手法 w/o QD-Att in Feature Extraction Swin-S 72.09 81.16 提案手法 w/o QD-Att in Multiscale Fusion Swin-S 71.39 80.44 提案手法 w/o Channel Attention Swin-S 72.02 81.35 提案手法 w/o Spatial Attention Swin-S 71.80 81.55 提案手法 Swin-S 74.61 81.95 各データセットにおける,物体検出タスクを行った際の精度 • 既存手法を上回る性能を達成 • Multiscale FusionにおけるQD-Attモジュールの効果が高い • Channel/Spatial Attentionはどちらも効果的であり,データセットによる
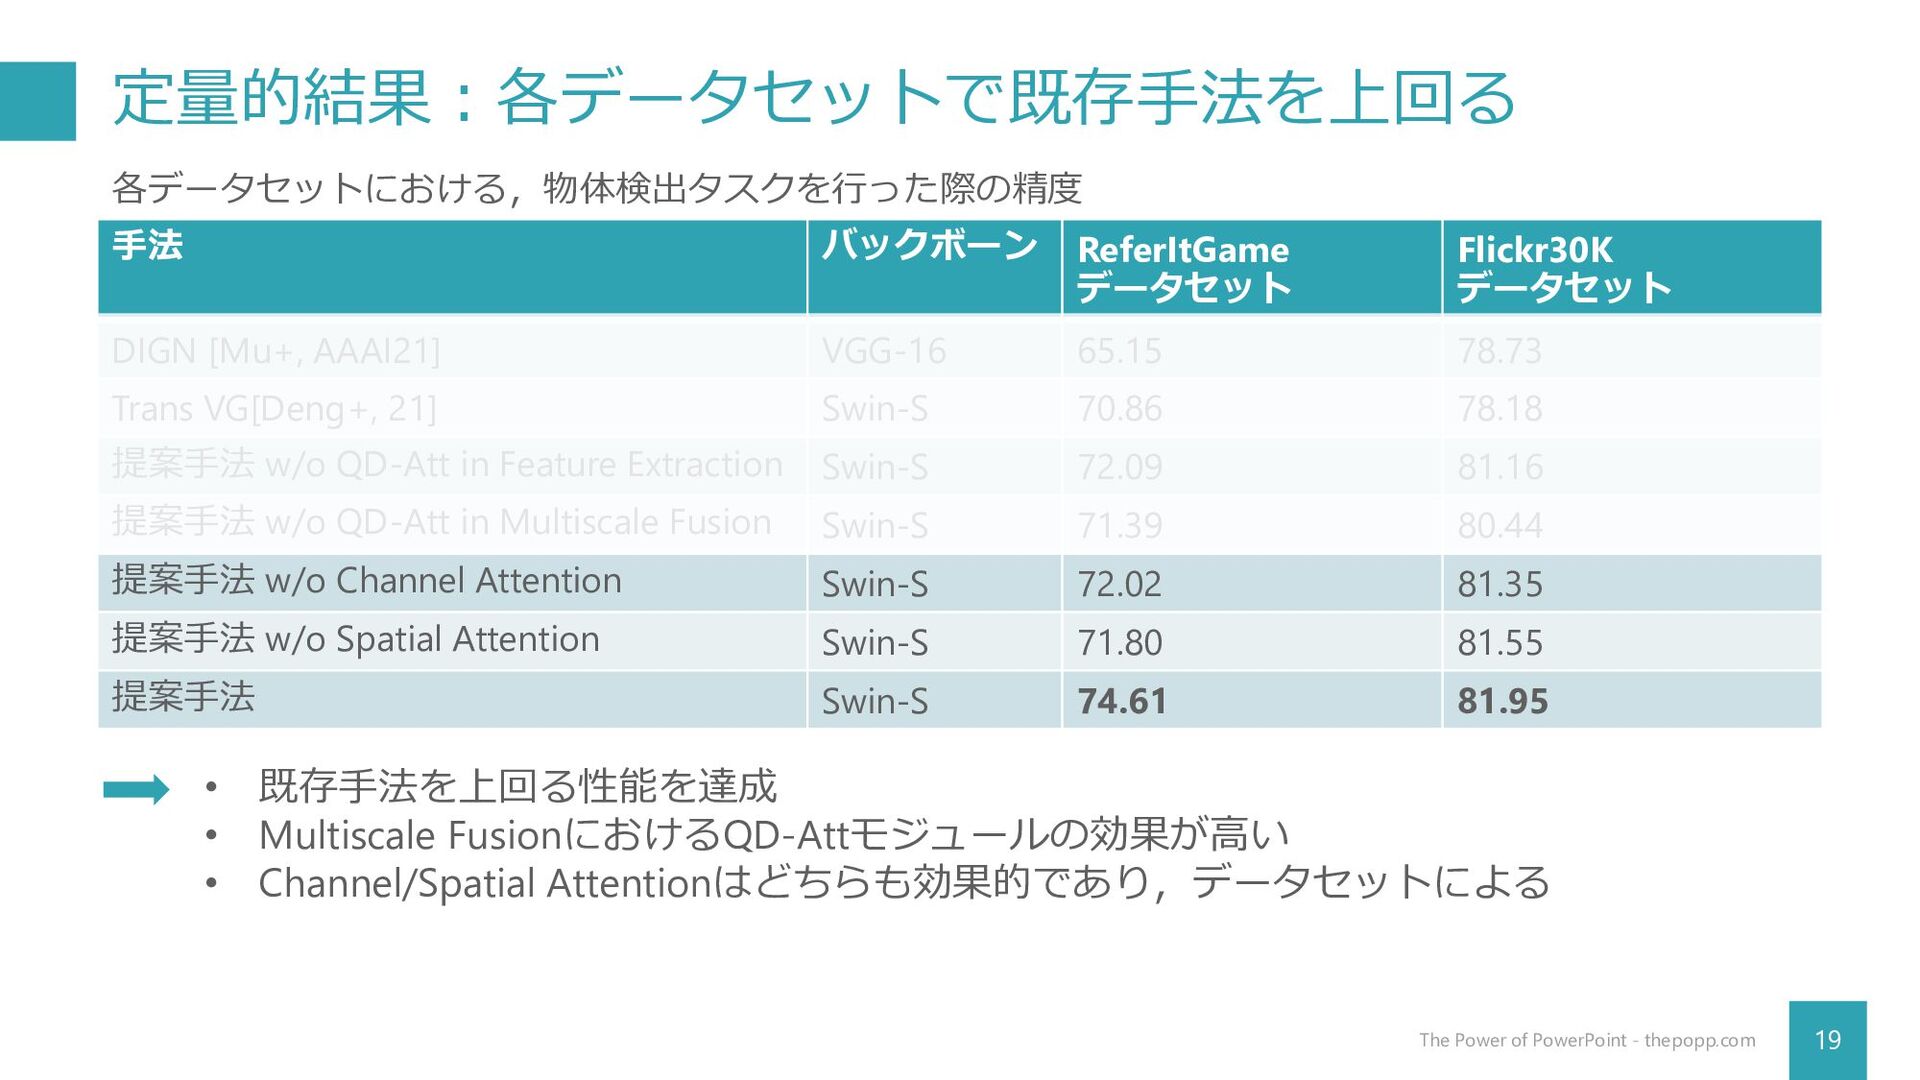
定量的結果:各データセットで既存手法を上回る 19 The Power of PowerPoint - thepopp.com 手法 バックボーン
ReferItGame データセット Flickr30K データセット DIGN [Mu+, AAAI21] VGG-16 65.15 78.73 Trans VG[Deng+, 21] Swin-S 70.86 78.18 提案手法 w/o QD-Att in Feature Extraction Swin-S 72.09 81.16 提案手法 w/o QD-Att in Multiscale Fusion Swin-S 71.39 80.44 提案手法 w/o Channel Attention Swin-S 72.02 81.35 提案手法 w/o Spatial Attention Swin-S 71.80 81.55 提案手法 Swin-S 74.61 81.95 各データセットにおける,物体検出タスクを行った際の精度 • 既存手法を上回る性能を達成 • Multiscale FusionにおけるQD-Attモジュールの効果が高い • Channel/Spatial Attentionはどちらも効果的であり,データセットによる
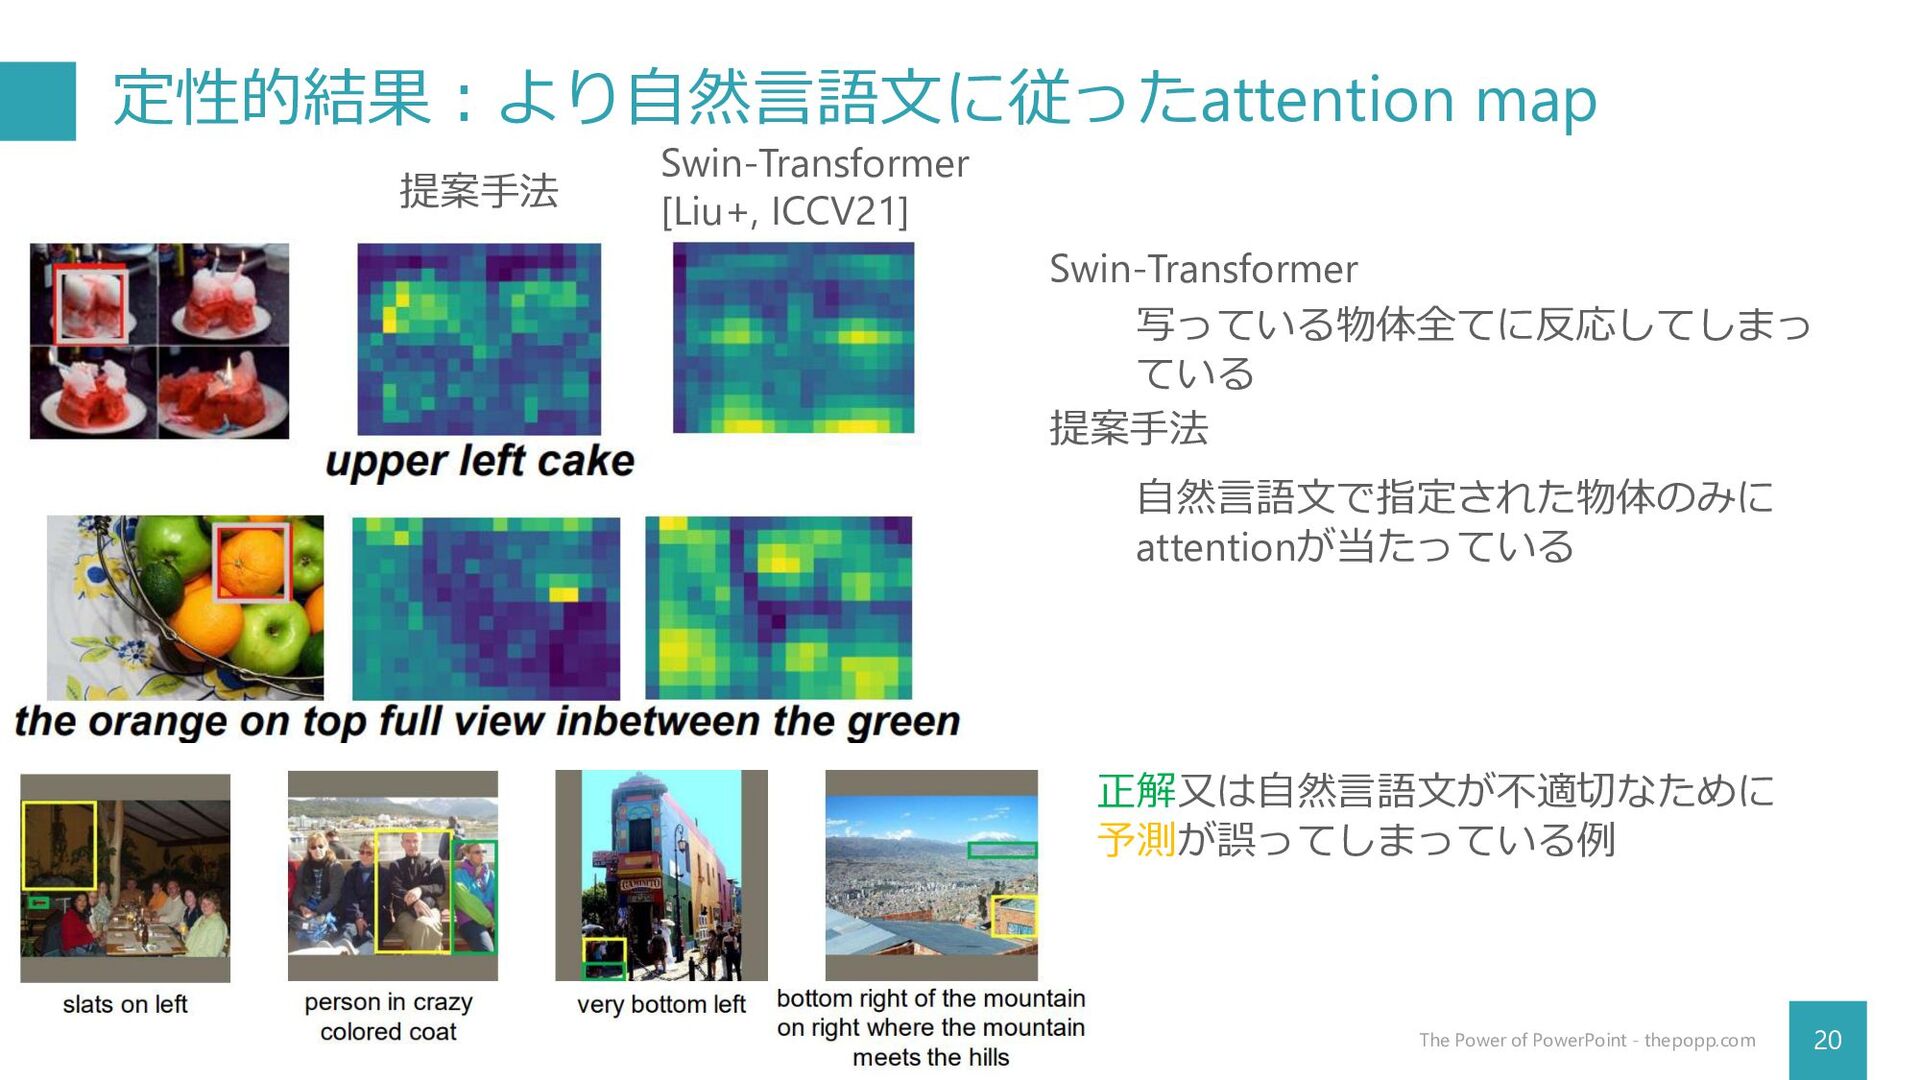
定性的結果:より自然言語文に従ったattention map 20 The Power of PowerPoint - thepopp.com 提案手法
Swin-Transformer [Liu+, ICCV21] Swin-Transformer 提案手法 写っている物体全てに反応してしまっ ている 自然言語文で指定された物体のみに attentionが当たっている 正解又は自然言語文が不適切なために 予測が誤ってしまっている例
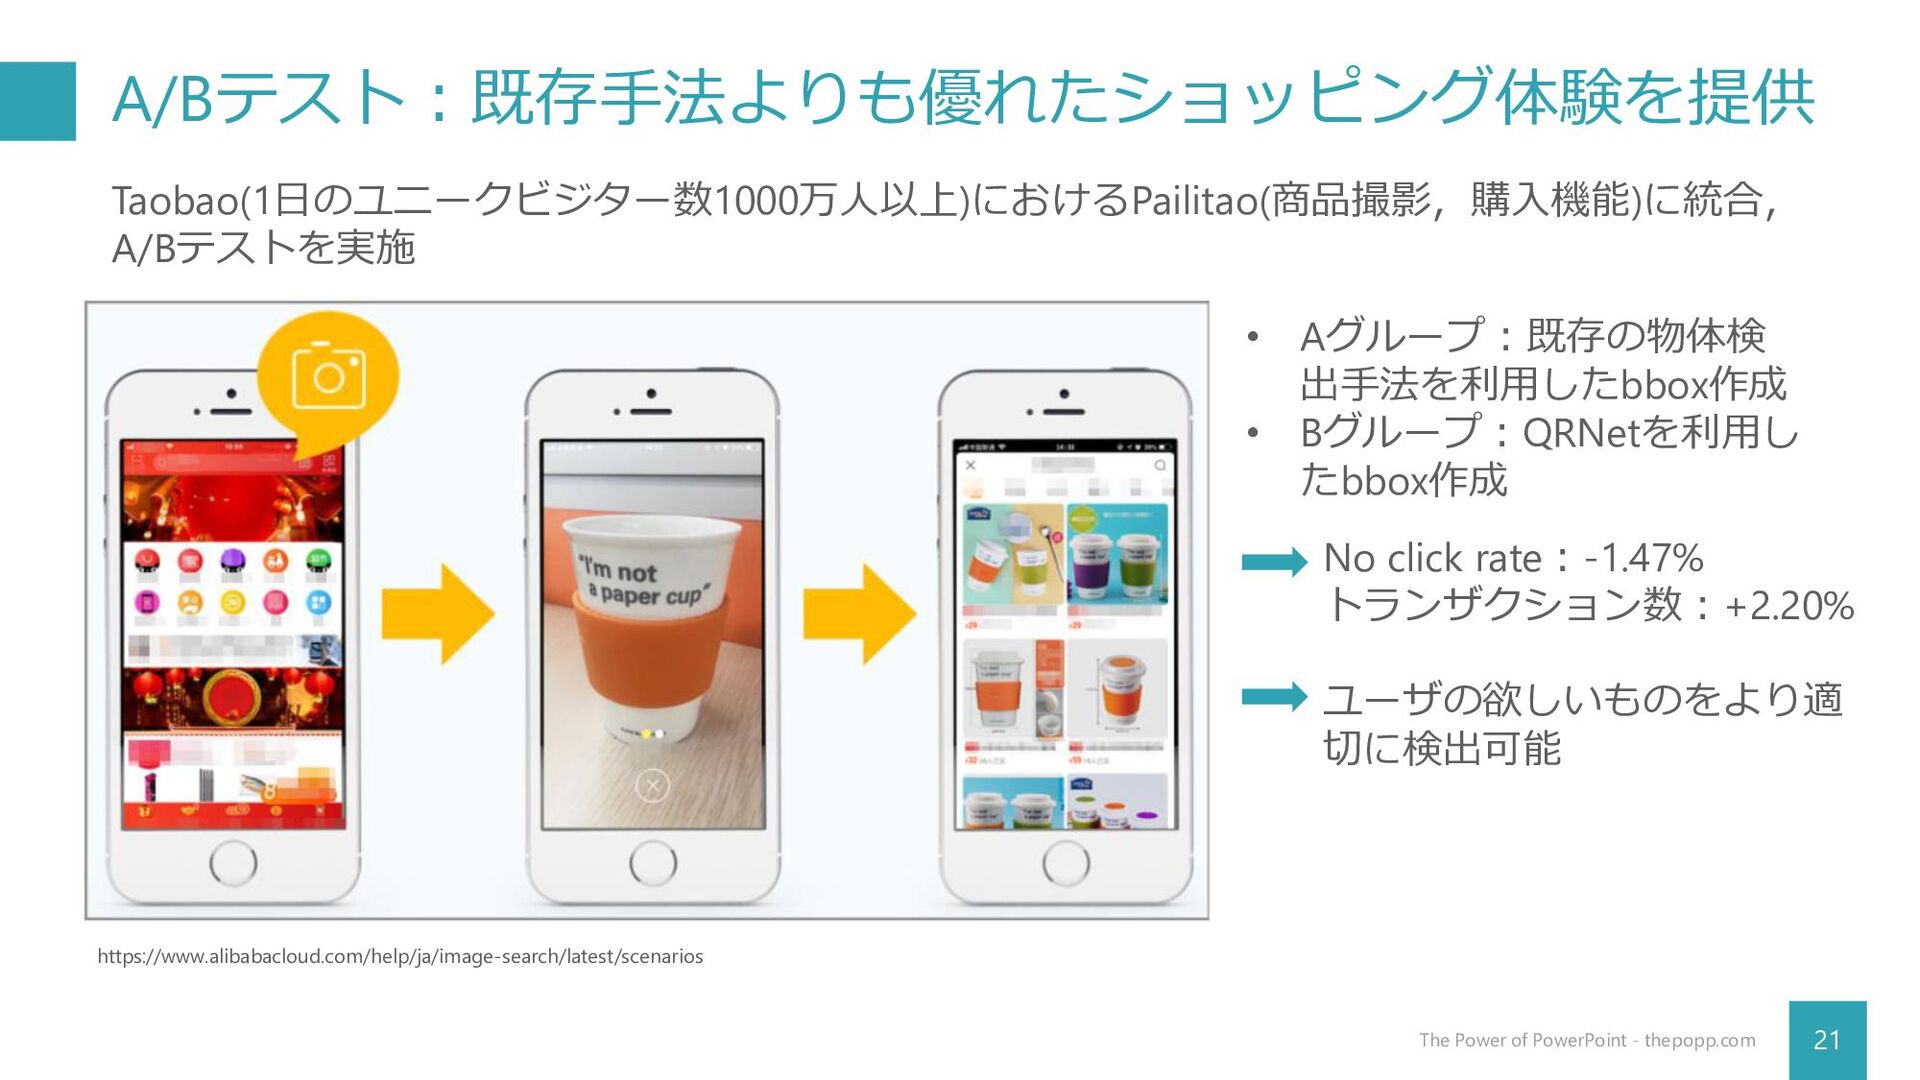
A/Bテスト:既存手法よりも優れたショッピング体験を提供 21 The Power of PowerPoint - thepopp.com Taobao(1日のユニークビジター数1000万人以上)におけるPailitao(商品撮影,購入機能)に統合, A/Bテストを実施
https://www.alibabacloud.com/help/ja/image-search/latest/scenarios • Aグループ:既存の物体検 出手法を利用したbbox作成 • Bグループ:QRNetを利用し たbbox作成 No click rate:-1.47% トランザクション数:+2.20% ユーザの欲しいものをより適 切に検出可能
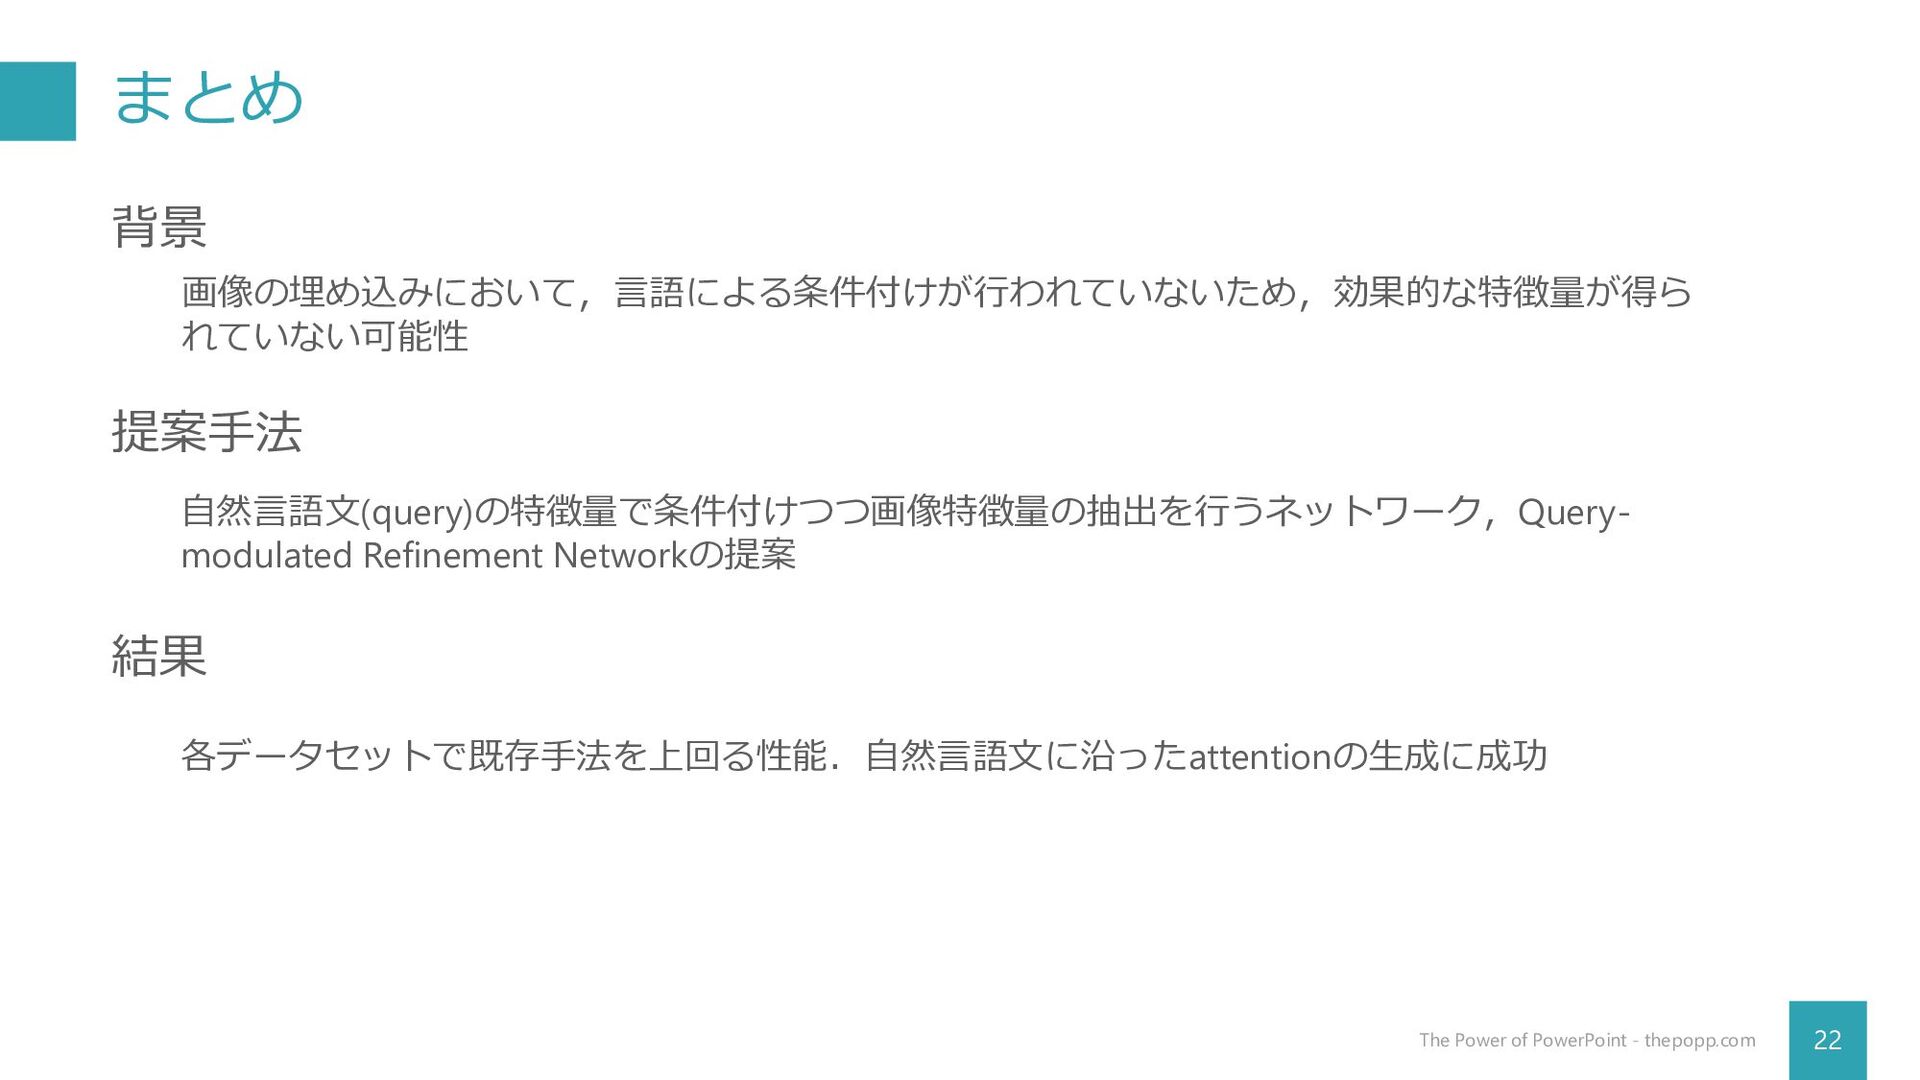
まとめ 22 The Power of PowerPoint - thepopp.com 背景 提案手法
結果 画像の埋め込みにおいて,言語による条件付けが行われていないため,効果的な特徴量が得ら れていない可能性 自然言語文(query)の特徴量で条件付けつつ画像特徴量の抽出を行うネットワーク,Query- modulated Refinement Networkの提案 各データセットで既存手法を上回る性能.自然言語文に沿ったattentionの生成に成功


 keio_smilab
 kash1064
 yuuuuuuu168
 pfn
 moznion
 teamlab
 jyouryuusui
 gionn
 recruitengineers
 kworkdev
 codmoninc
 tomokusaba
 lara
 palkan
 reverentgeek
 katiecoart
 wjessup
 3n
 axbom
 aleyda
 schlessera
 eileencodes
 mclloyd