Share
Embed
Environmental sound recognition with machine learning
Tatsuya Komatsu
LINE Speech Team Senior Researcher
https://linedevday.linecorp.com/2020/jp/sessions/5825
https://linedevday.linecorp.com/2020/en/sessions/5825
LINE DevDay 2020
November 25, 2020
Transcript
46 slides
-
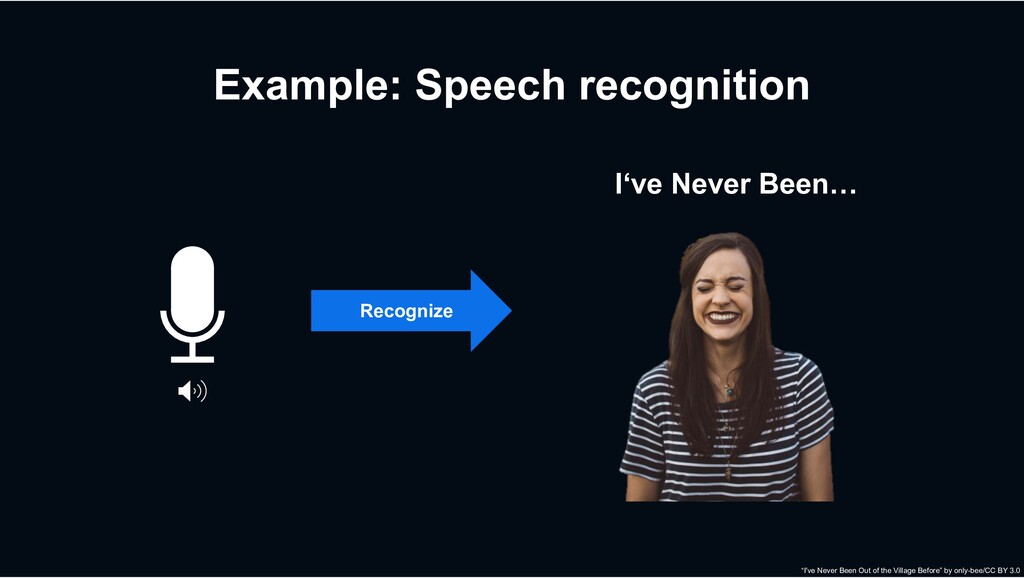
Example: Speech recognition Recognize “I've Never Been Out of the
Village Before” by only-bee/CC BY 3.0 I‘ve Never Been… -
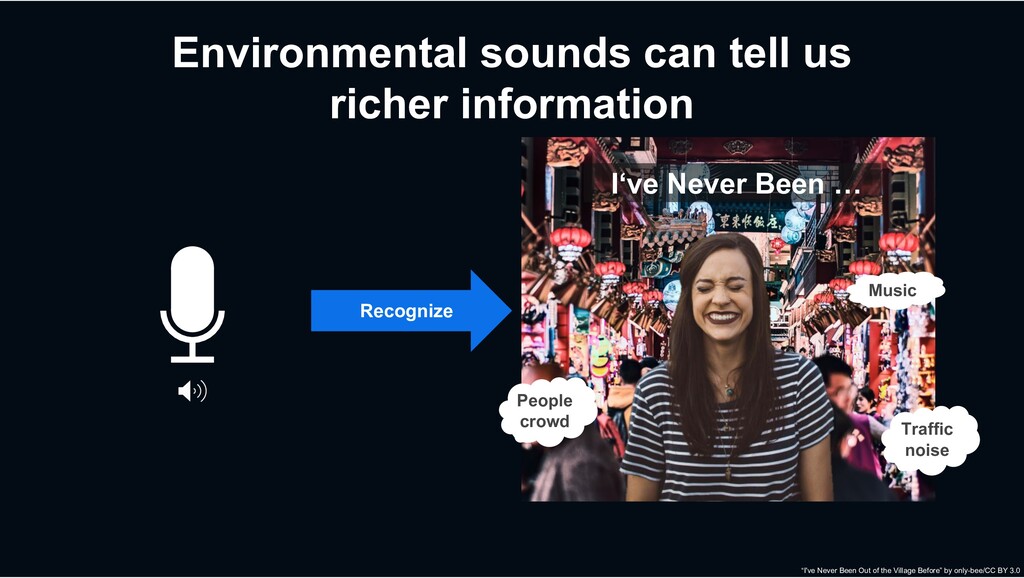
Environmental sounds can tell us richer information Traffic noise Music
People crowd I‘ve Never Been … Recognize “I've Never Been Out of the Village Before” by only-bee/CC BY 3.0 -
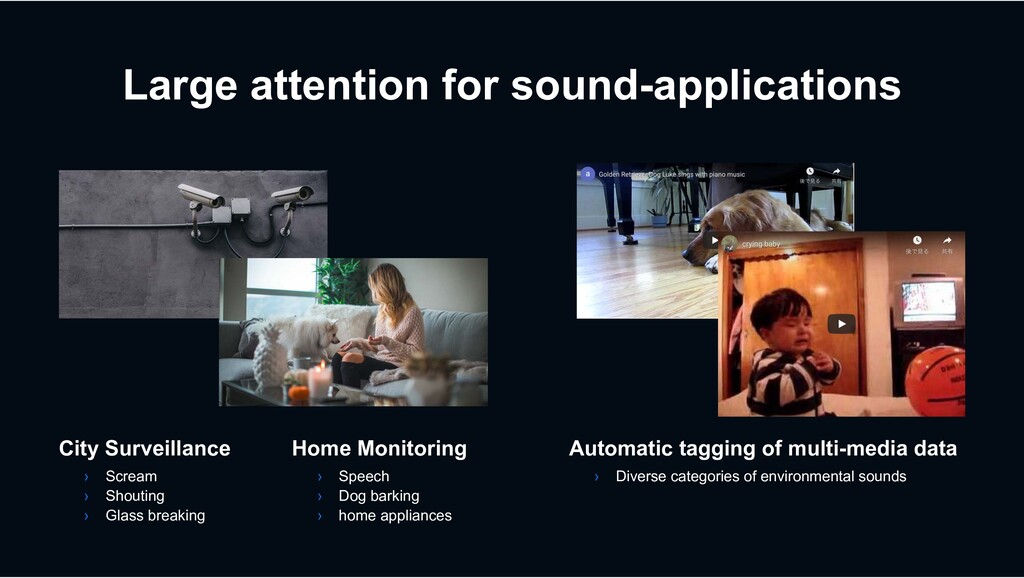
Large attention for sound-applications Automatic tagging of multi-media data ›
Diverse categories of environmental sounds City Surveillance › Scream › Shouting › Glass breaking Home Monitoring › Speech › Dog barking › home appliances -
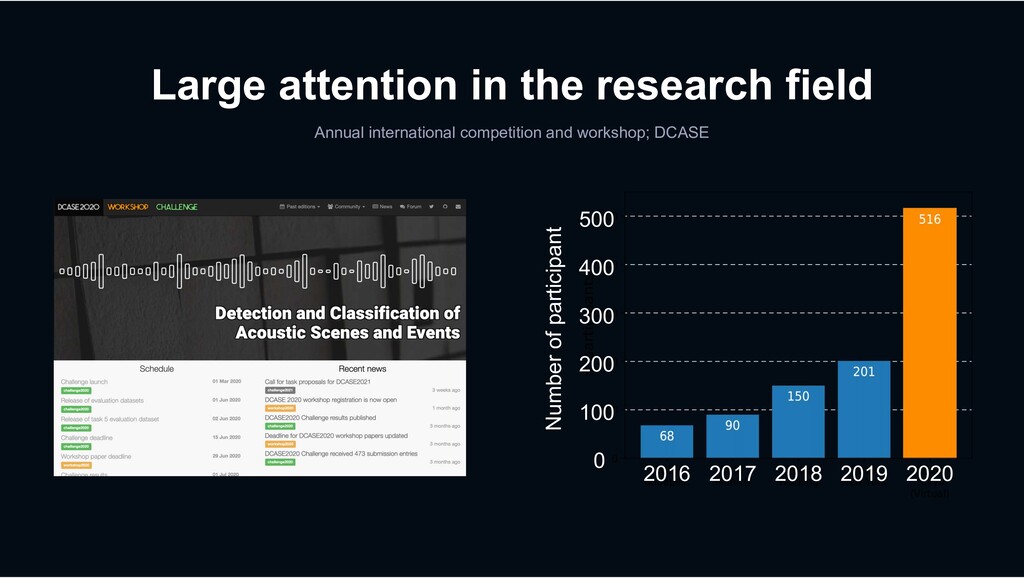
Large attention in the research field Annual international competition and
workshop; DCASE 2020 2019 2018 2017 2016 0 100 200 300 400 500 Number of participant -
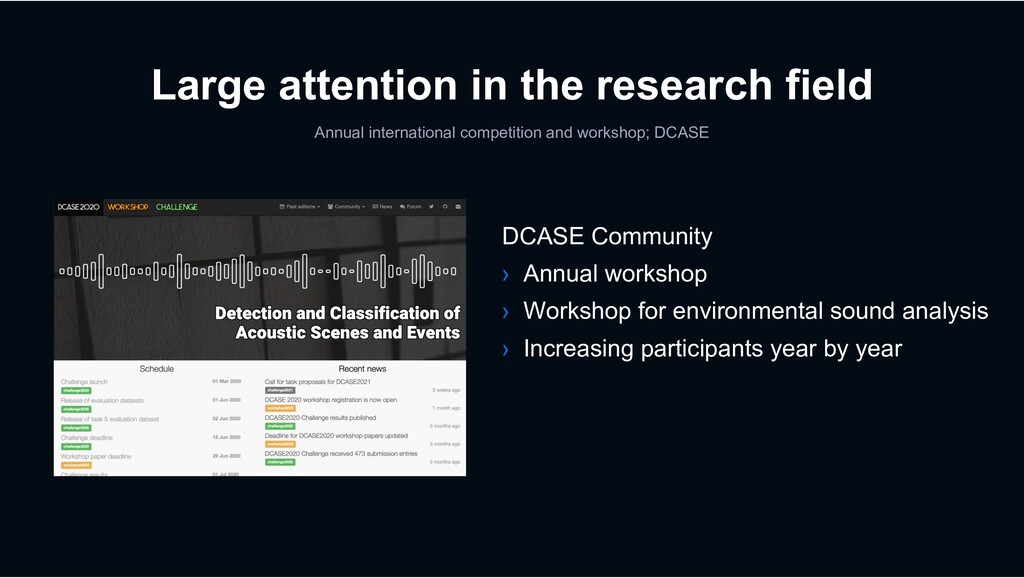
Large attention in the research field Annual international competition and
workshop; DCASE DCASE Community › Annual workshop › Workshop for environmental sound analysis › Increasing participants year by year -
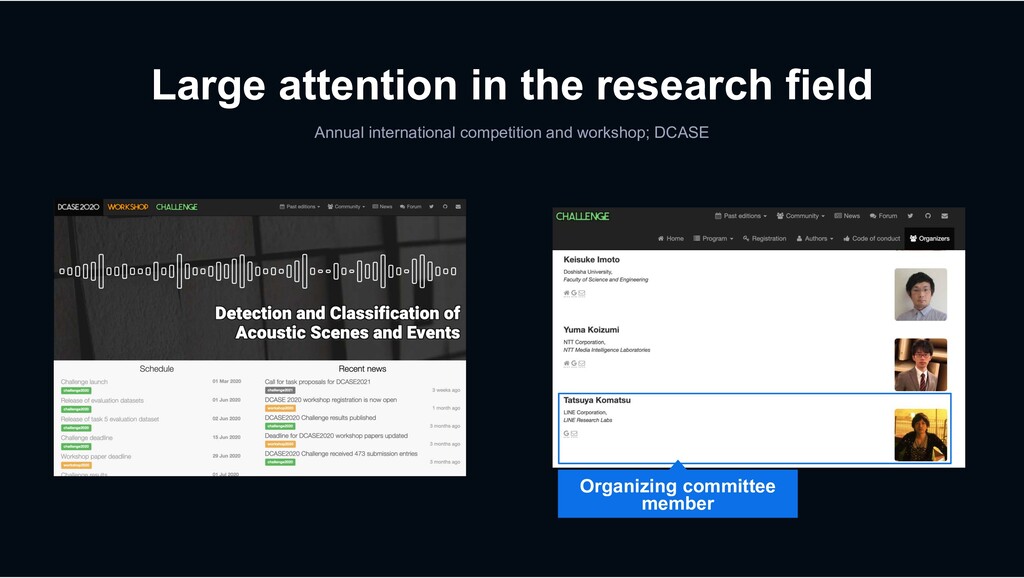
Large attention in the research field Annual international competition and
workshop; DCASE Organizing committee member -
DCASE Challenge: Annual international competition › An annual public evaluation
event to accelerate the development of the research field › Open dataset › Open baseline method › Public benchmark -
DCASE Challenge: Annual international competition › An annual public evaluation
event to accelerate the development of the research field › LINE joined the challenge as the joint team with Nagoya Univ. and Johns Hopkins Univ. LINE Internship Student 2019 -
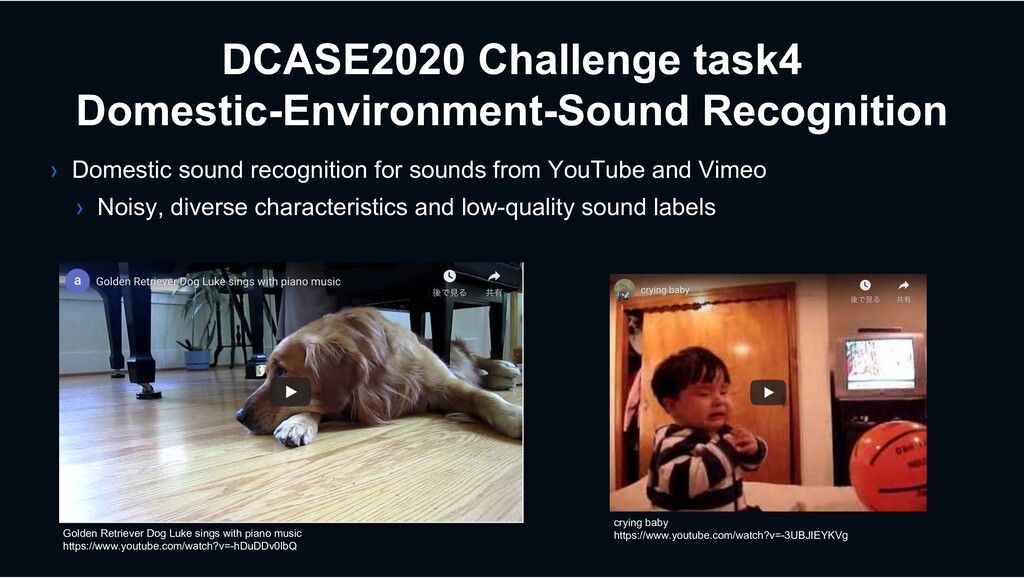
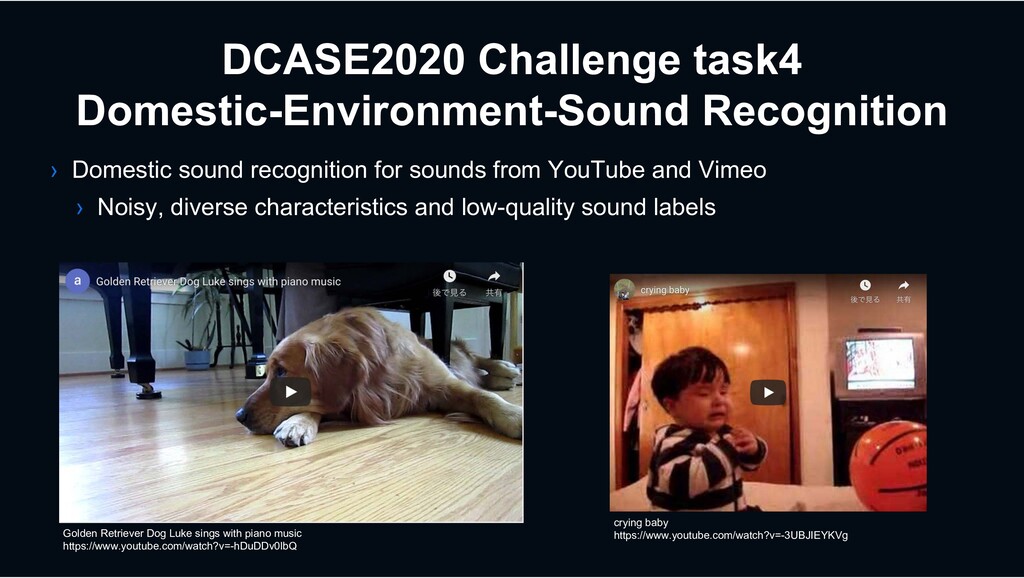
› Domestic sound recognition for sounds from YouTube and Vimeo
› Noisy, diverse characteristics and low-quality sound labels DCASE2020 Challenge task4 Domestic-Environment-Sound Recognition Golden Retriever Dog Luke sings with piano music https://www.youtube.com/watch?v=-hDuDDv0lbQ crying baby https://www.youtube.com/watch?v=-3UBJIEYKVg -
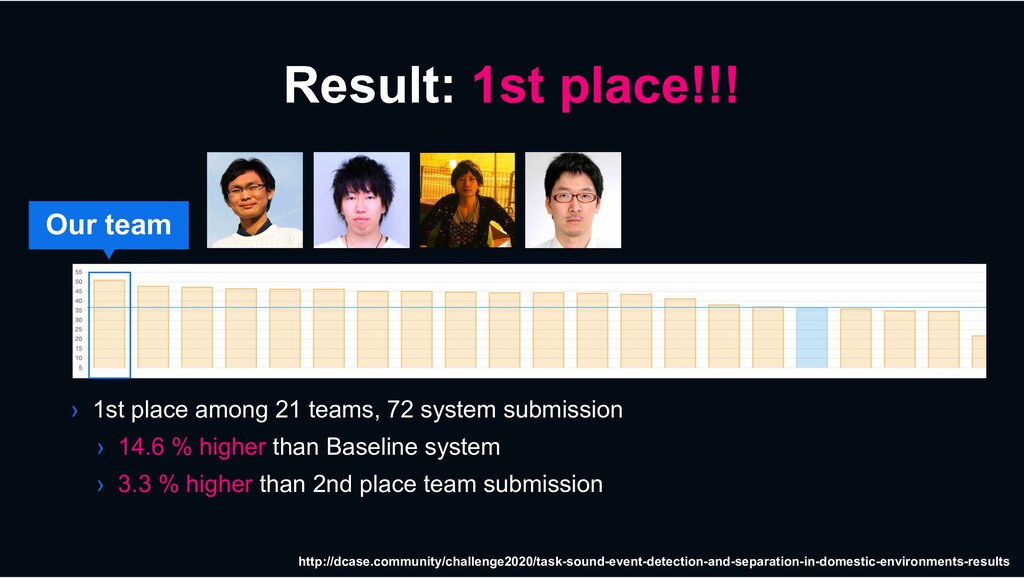
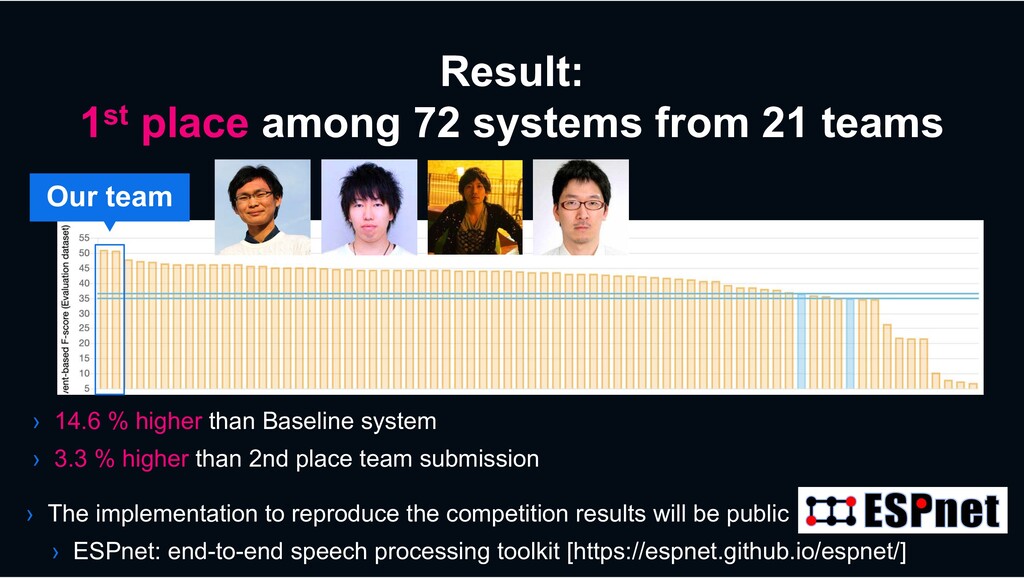
Result: 1st place!!! › 1st place among 21 teams, 72
system submission › 14.6 % higher than Baseline system › 3.3 % higher than 2nd place team submission Our team http://dcase.community/challenge2020/task-sound-event-detection-and-separation-in-domestic-environments-results -
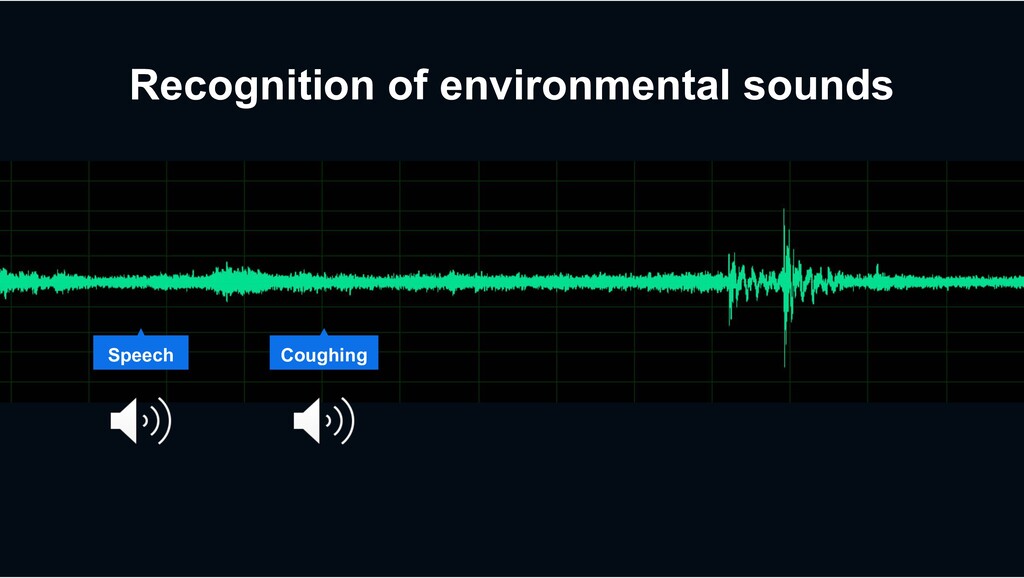
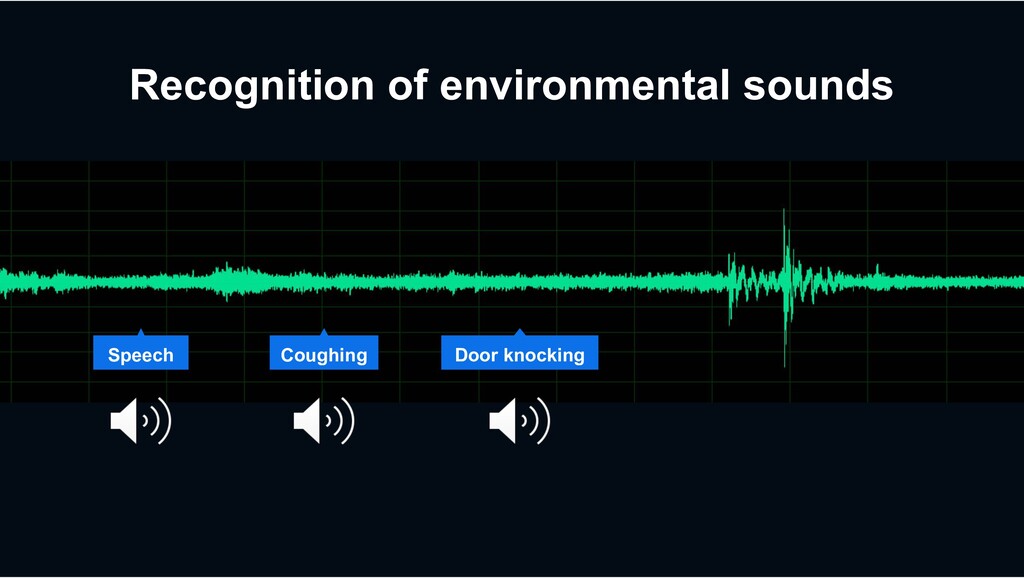
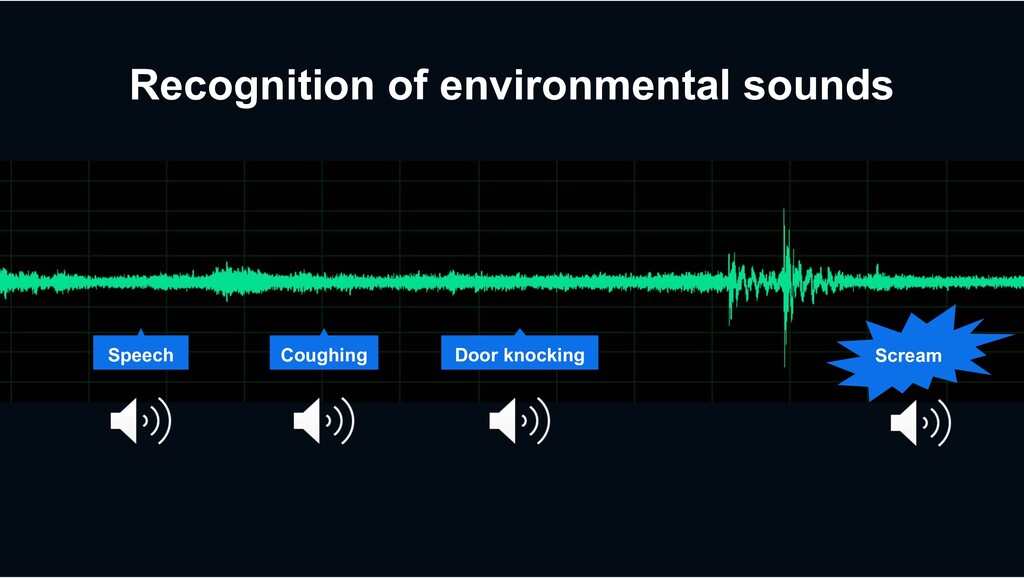
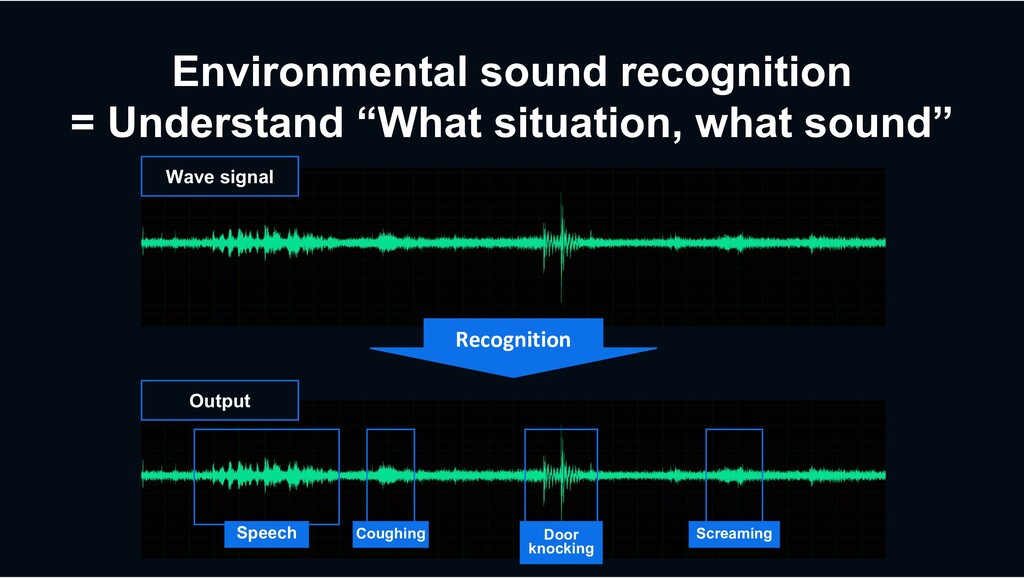
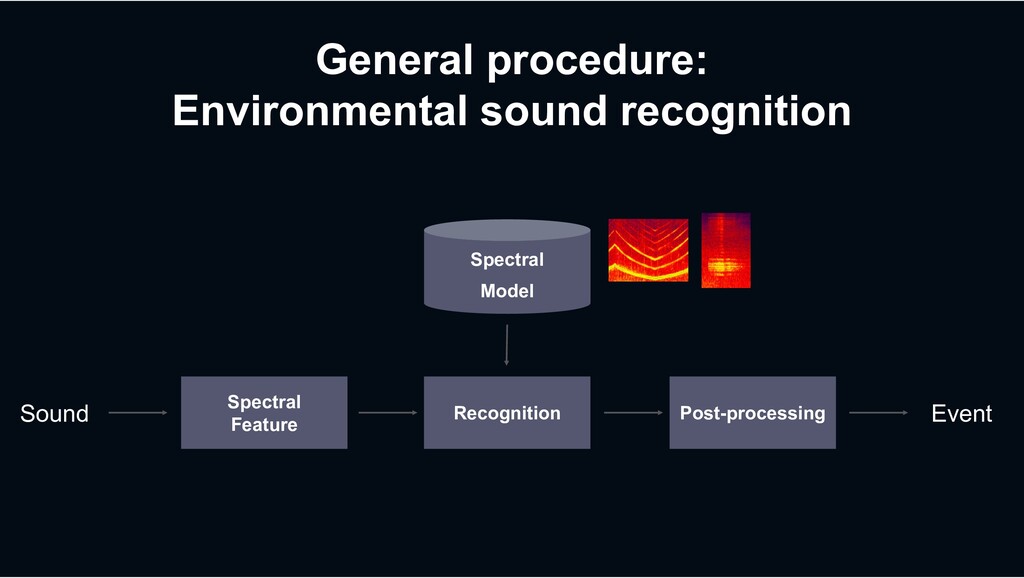
Environmental sound recognition = Understand “What situation, what sound” Wave
signal Recognition Output Speech Coughing Door knocking Screaming -
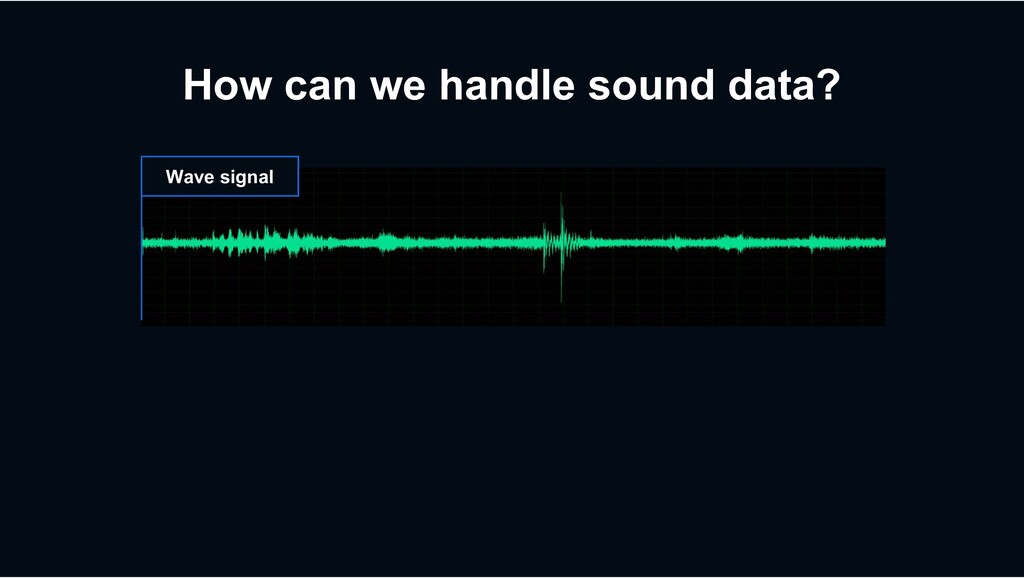
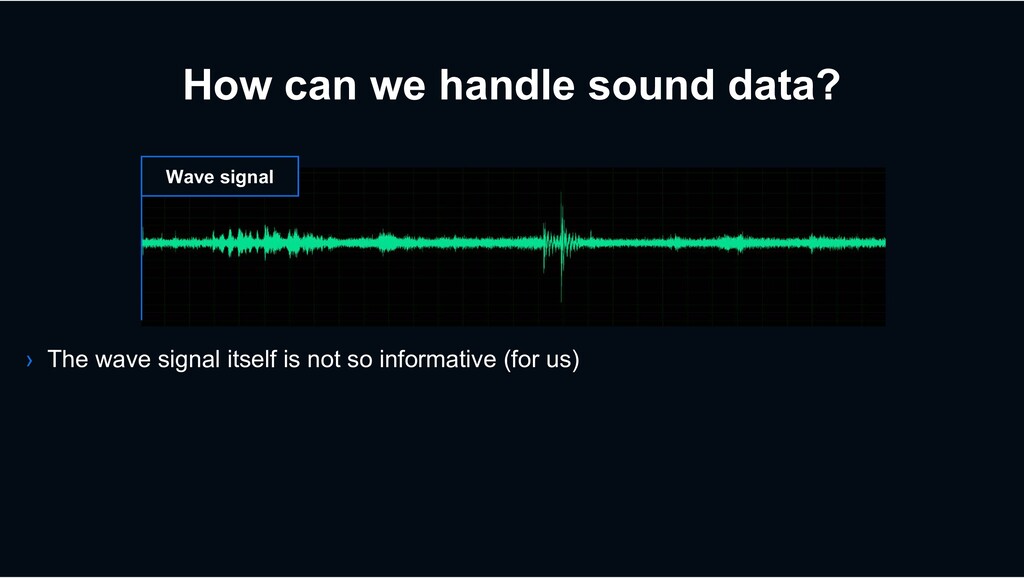
How can we handle sound data? Wave signal › The
wave signal itself is not so informative (for us) -
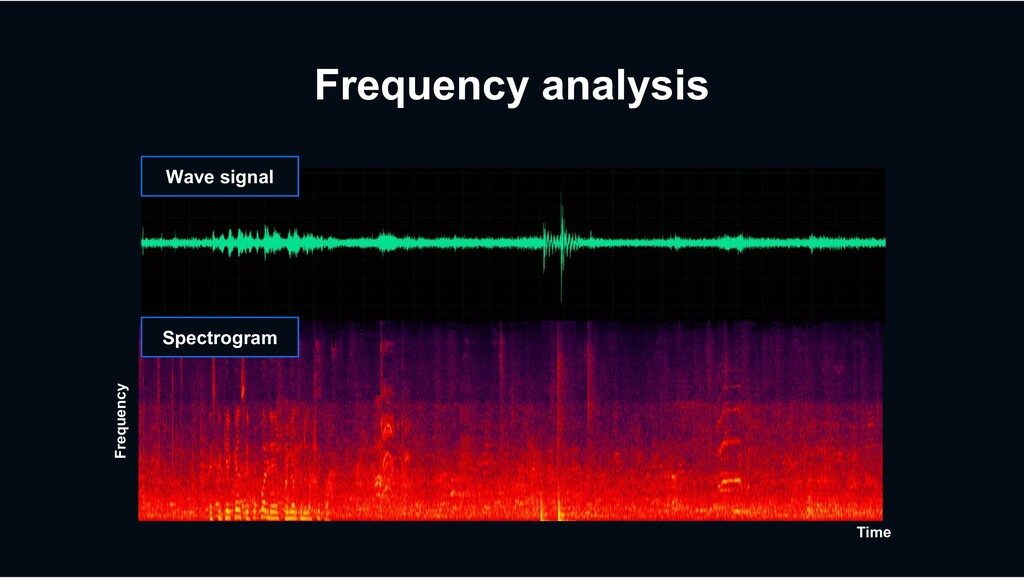
Frequency analysis Wave signal Spectrogram Can be handled like images
Speech Coughing Door knocking Screaming Time Frequency -
Characteristic of sound data 振幅 周波数 › Both spectral (local)
and temporal (global) information are important › Sounds occur simultaneously, i.e. Overlapping → One of the key solution = Source separation Global information Local information Next Session -
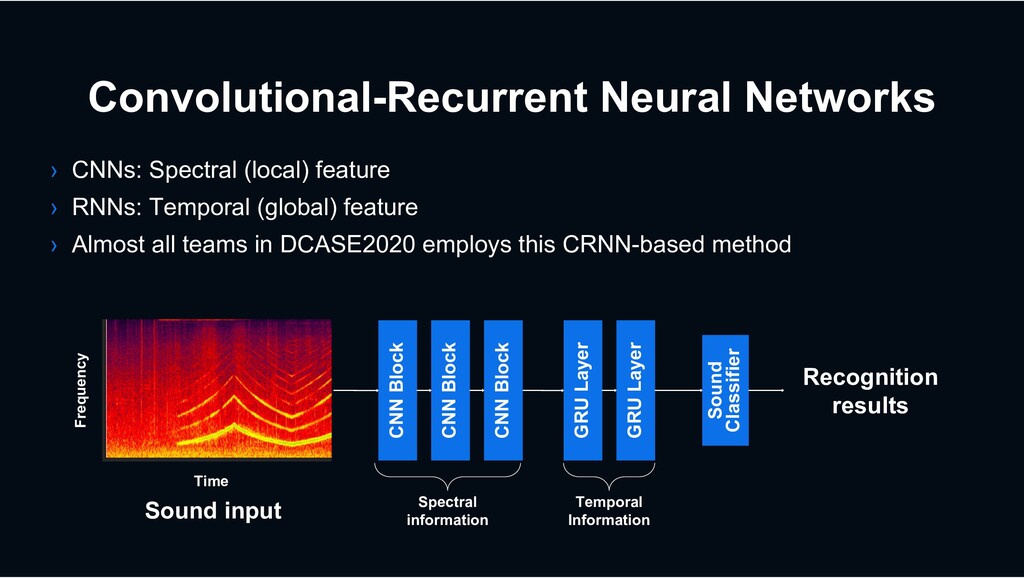
Convolutional-Recurrent Neural Networks › CNNs: Spectral (local) feature › RNNs:
Temporal (global) feature › Almost all teams in DCASE2020 employs this CRNN-based method GRU Layer GRU Layer Sound input Time Frequency CNN Block CNN Block CNN Block Sound Classifier Recognition results Spectral information Temporal Information -
› Domestic sound recognition for sounds from YouTube and Vimeo
› Noisy, diverse characteristics and low-quality sound labels DCASE2020 Challenge task4 Domestic-Environment-Sound Recognition Golden Retriever Dog Luke sings with piano music https://www.youtube.com/watch?v=-hDuDDv0lbQ crying baby https://www.youtube.com/watch?v=-3UBJIEYKVg -
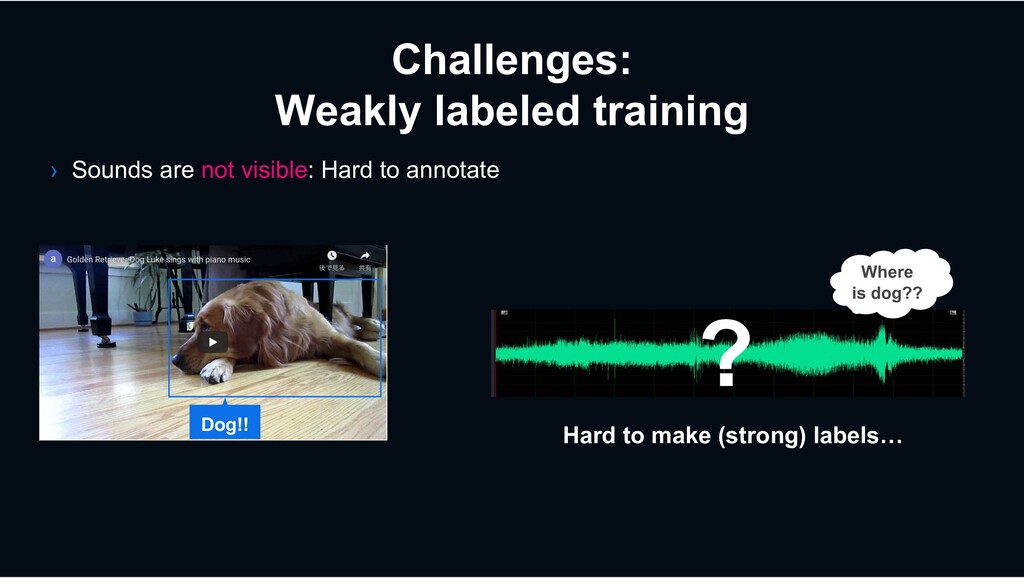
› Sounds are not visible: Hard to annotate Challenges: Weakly
labeled training Dog!! ? Where is dog?? Hard to make (strong) labels… -
› Sounds are not visible: Hard to annotate Challenges: Weakly
labeled training Dog!! Weak label ‘Dog is somewhere in this sound’ -
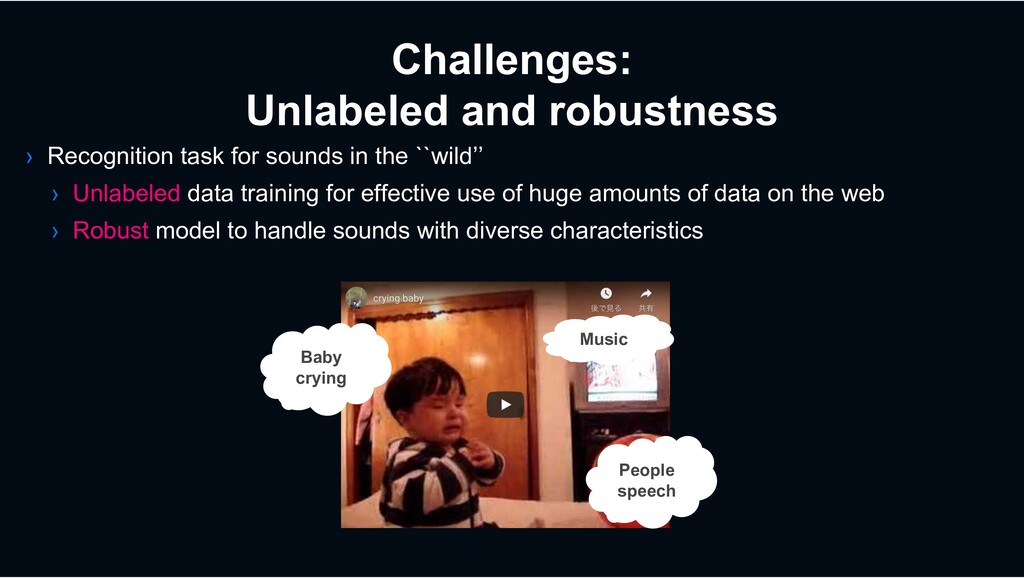
Challenges: Unlabeled and robustness › Recognition task for sounds in
the ``wild’’ › Unlabeled data training for effective use of huge amounts of data on the web › Robust model to handle sounds with diverse characteristics Baby crying Music People speech -
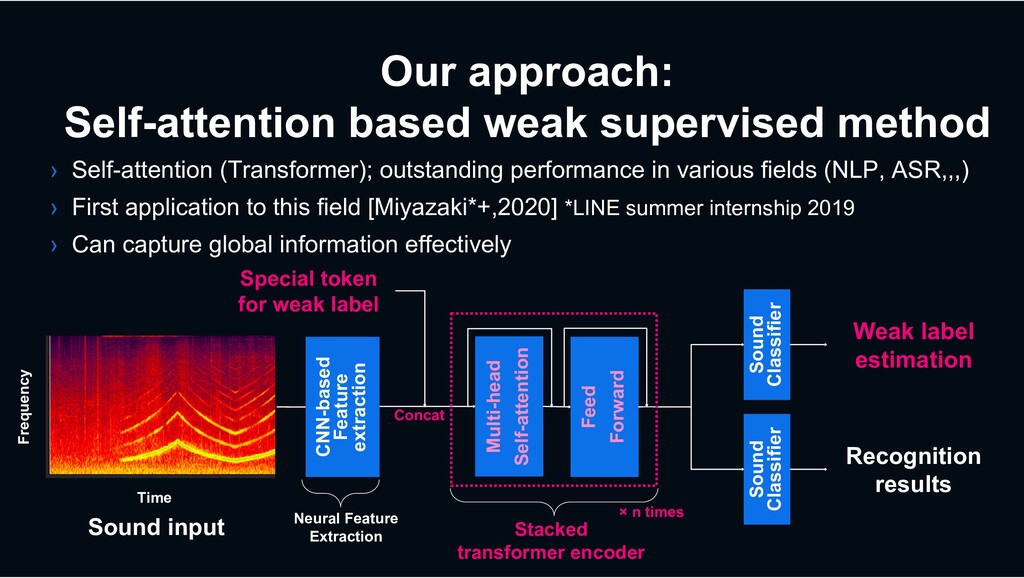
Our approach: Self-attention based weak supervised method › Self-attention (Transformer);
outstanding performance in various fields (NLP, ASR,,,) › First application to this field [Miyazaki*+,2020] *LINE summer internship 2019 › Can capture global information effectively Multi-head Self-attention Sound input Time Frequency Sound Classifier Weak label estimation Neural Feature Extraction Stacked transformer encoder Feed Forward Sound Classifier Recognition results Special token for weak label × n times Concat CNN-based Feature extraction -
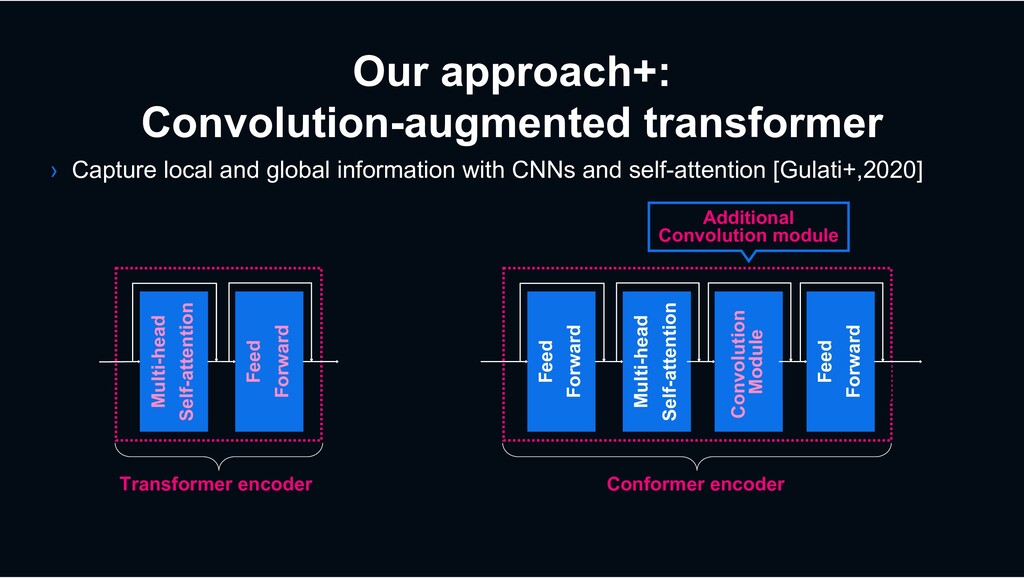
Our approach+: Convolution-augmented transformer › Capture local and global information
with CNNs and self-attention [Gulati+,2020] Feed Forward Conformer encoder Multi-head Self-attention Convolution Module Feed Forward Multi-head Self-attention Transformer encoder Feed Forward Additional Convolution module -
For improvement of the performance: Unlabeled data training › Mean
teacher [Tarvainen+, NIPS2017] Tarvainen et al., "Mean teachers are better role models: Weight-averaged consistency targets improve semi-supervised deep learning results." in NIPS 2017. Teacher model Student model Recognition results Recognition results Sound input Parameter θ Moving average θ* < add noise/augment < add noise/augment Consistency loss -
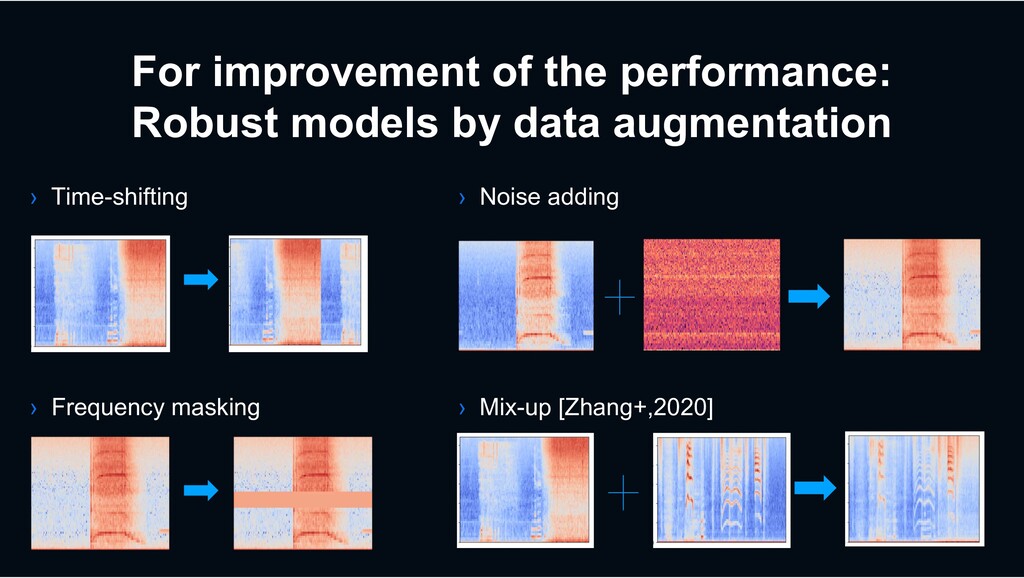
For improvement of the performance: Robust models by data augmentation
› Time-shifting › Noise adding › Mix-up [Zhang+,2020] › Frequency masking -
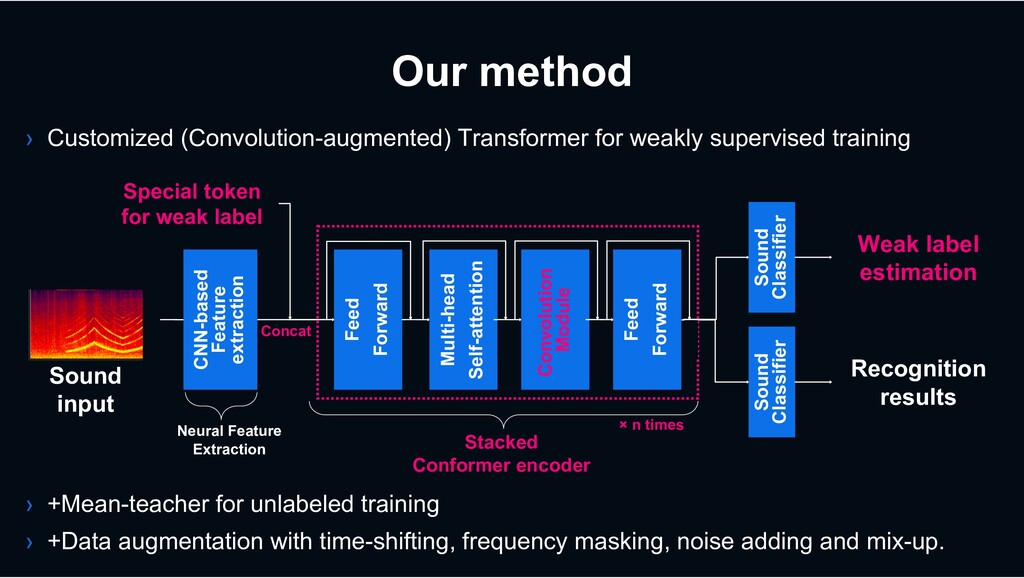
› Customized (Convolution-augmented) Transformer for weakly supervised training › +Mean-teacher
for unlabeled training › +Data augmentation with time-shifting, frequency masking, noise adding and mix-up. Our method Sound input Sound Classifier Weak label estimation Neural Feature Extraction Stacked Conformer encoder Sound Classifier Recognition results Special token for weak label × n times Concat CNN-based Feature extraction Feed Forward Multi-head Self-attention Convolution Module Feed Forward -
Result: 1st place among 72 systems from 21 teams ›
The implementation to reproduce the competition results will be public › ESPnet: end-to-end speech processing toolkit [https://espnet.github.io/espnet/] › 14.6 % higher than Baseline system › 3.3 % higher than 2nd place team submission Our team -
Barriers to Practical Applications › Data mismatch by recorded devices:
diverse characteristics › ‘Meaning of sounds’ depends on scene › Richer information; want to know where the sounds come from. -
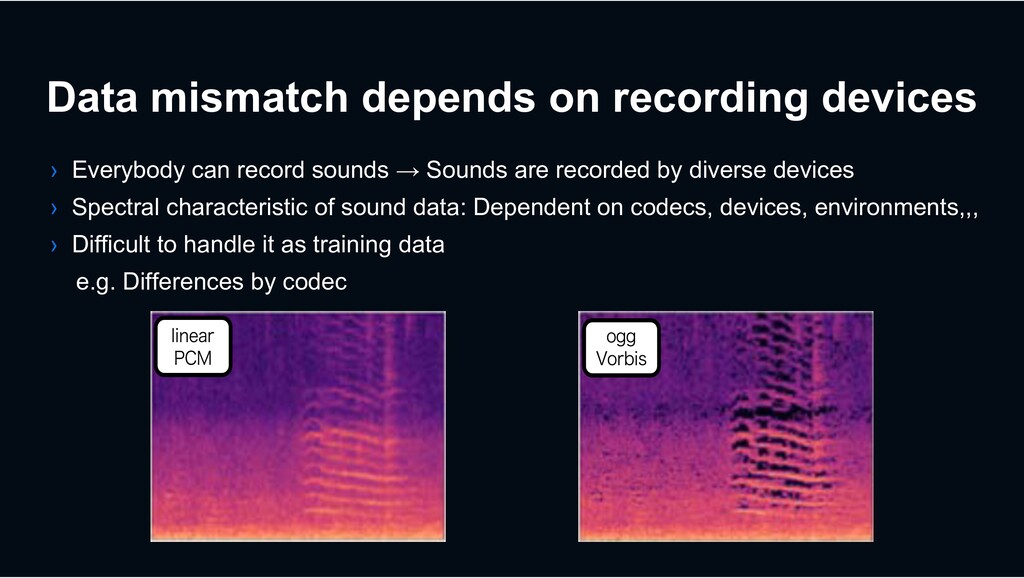
Data mismatch depends on recording devices › Everybody can record
sounds → Sounds are recorded by diverse devices › Spectral characteristic of sound data: Dependent on codecs, devices, environments,,, › Difficult to handle it as training data e.g. Differences by codec Airport - London 0 1 5 2 3 4 Frequency [kHz] 10 5 0 MJOFBS 1$. Airport - London 0 1 5 2 3 4 Frequency [kHz] 10 5 0 0 1 5 2 3 4 Time [sec] Frequency [kHz] 10 5 0 MJOFBS 1$. PHH 7PSCJT -
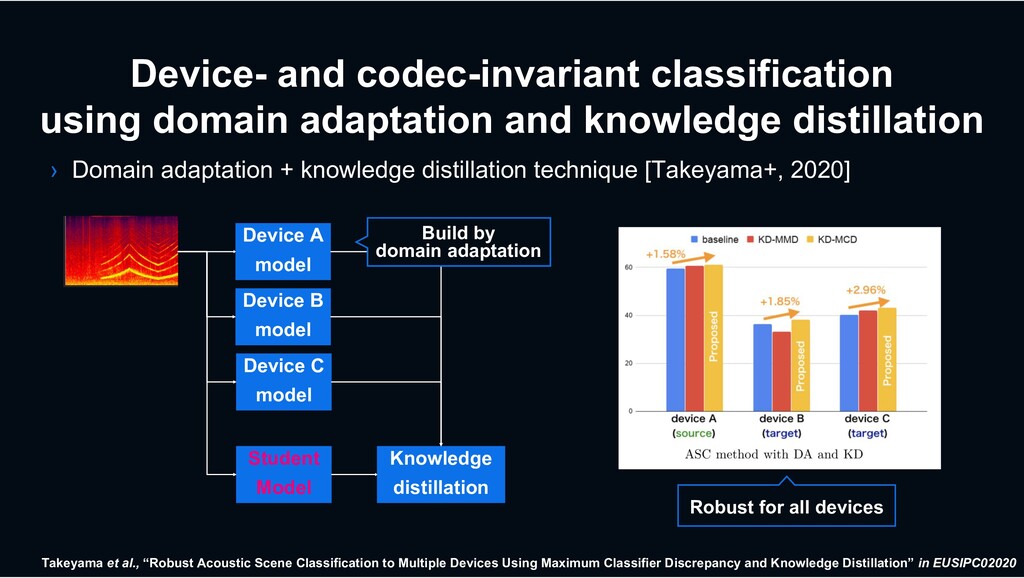
Device- and codec-invariant classification using domain adaptation and knowledge distillation
› Domain adaptation + knowledge distillation technique [Takeyama+, 2020] Takeyama et al., “Robust Acoustic Scene Classification to Multiple Devices Using Maximum Classifier Discrepancy and Knowledge Distillation” in EUSIPC02020 Device A model Device C model Device B model Student Model Knowledge distillation Robust for all devices Build by domain adaptation -
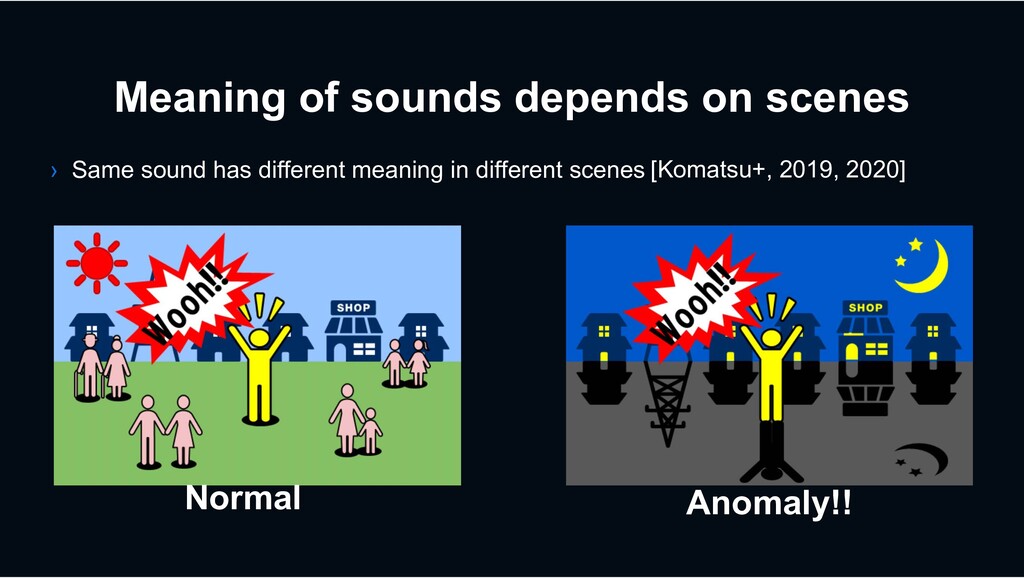
Meaning of sounds depends on scenes Normal Anomaly!! › Same
sound has different meaning in different scenes [Komatsu+, 2019, 2020] -
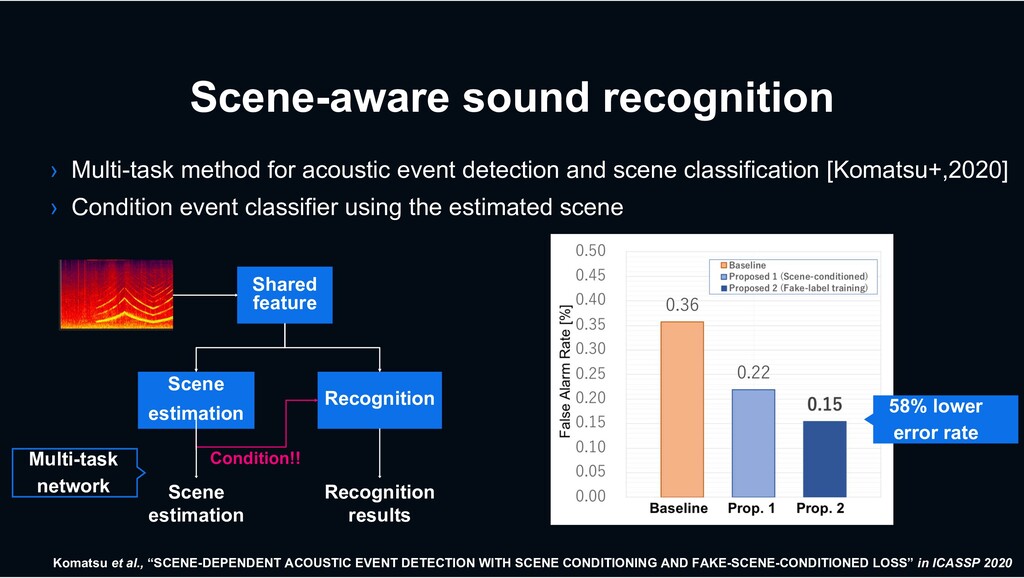
Scene-aware sound recognition › Multi-task method for acoustic event detection
and scene classification [Komatsu+,2020] › Condition event classifier using the estimated scene Multi-task network 58% lower error rate Komatsu et al., “SCENE-DEPENDENT ACOUSTIC EVENT DETECTION WITH SCENE CONDITIONING AND FAKE-SCENE-CONDITIONED LOSS” in ICASSP 2020 Shared feature Scene estimation Recognition Scene estimation Recognition results Condition!! -
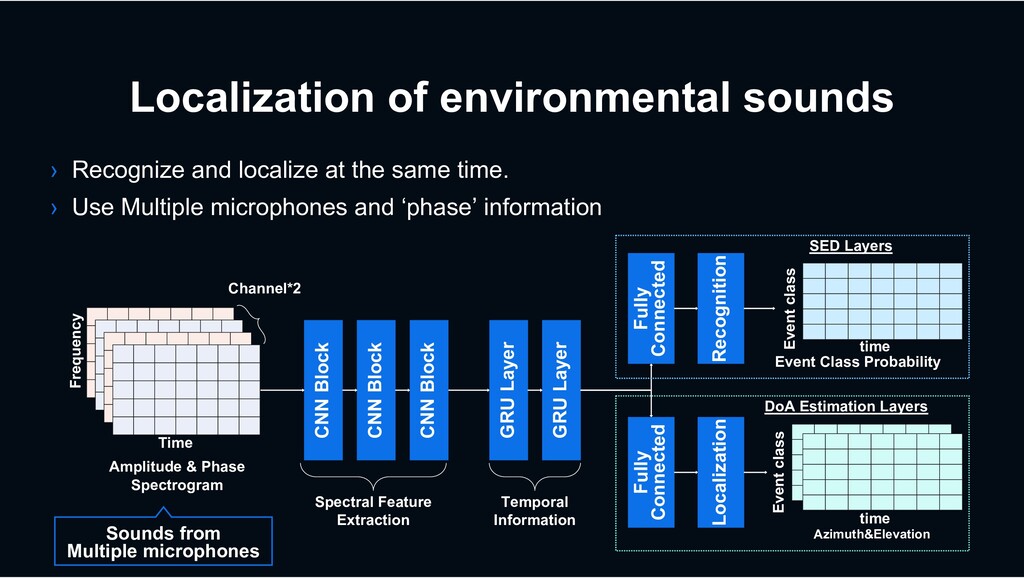
Localization of environmental sounds › Recognize and localize at the
same time. › Use Multiple microphones and ‘phase’ information Sounds from Multiple microphones GRU Layer GRU Layer Amplitude & Phase Spectrogram Time Frequency Channel*2 CNN Block CNN Block CNN Block Fully Connected time Event class Event class time Recognition Fully Connected Localization Azimuth&Elevation Event Class Probability SED Layers DoA Estimation Layers Spectral Feature Extraction Temporal Information -
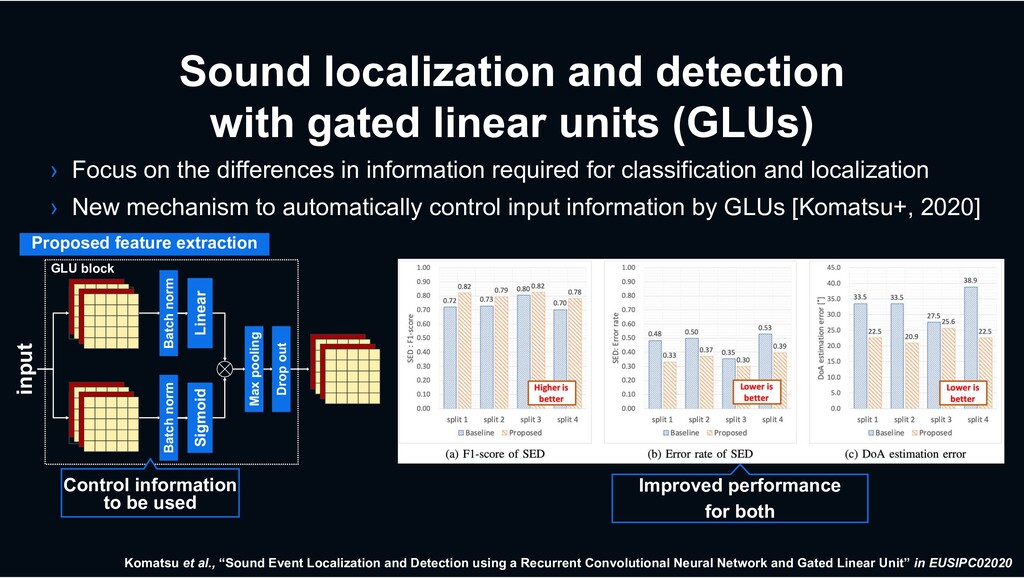
Sound localization and detection with gated linear units (GLUs) ›
Focus on the differences in information required for classification and localization › New mechanism to automatically control input information by GLUs [Komatsu+, 2020] Komatsu et al., “Sound Event Localization and Detection using a Recurrent Convolutional Neural Network and Gated Linear Unit” in EUSIPC02020 Improved performance for both Batch norm Max pooling Drop out Sigmoid Batch norm Linear input GLU block Control information to be used Proposed feature extraction -
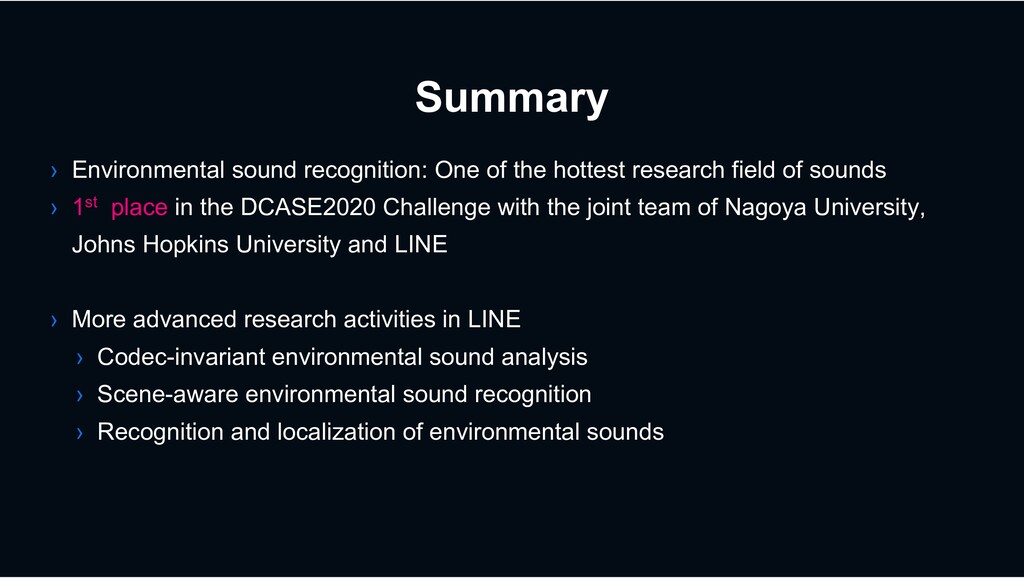
Summary › Environmental sound recognition: One of the hottest research
field of sounds › 1st place in the DCASE2020 Challenge with the joint team of Nagoya University, Johns Hopkins University and LINE › More advanced research activities in LINE › Codec-invariant environmental sound analysis › Scene-aware environmental sound recognition › Recognition and localization of environmental sounds