Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Community Over Code Glasgow 2026 + Lakehouse Da...

Community Over Code Glasgow 2026 + Lakehouse Day recap

ASFにおけるグローバル最大のカンファレンスである Community Over Code 2026 および、併催イベントである Lakehouse Day の概要について紹介し、データ基盤周りで面白かったセッションをいくつかとりあげるとともに、AI周りの進化を受けてASF自体がどのように変化、追従しているのかについても紹介します。また、8月に北京で開催されたCommunity Over Code Asiaにも参加・登壇してきたので雰囲気の違いについても紹介します。

More Decks by LINEヤフーTech (LY Corporation Tech)

Transcript

  1. Community Over Code Glasgow 2026 + Lakehouse Day recap 2026-11-04

    Open Table Formats Study Group Tokyo 番外編 Akira Ajisaka © LY Corporation
  2. Todayʼs Agenda • Community Over Code Glasgow + Lakehouse Day

    ◦ Event summary ◦ Session report • Community Over Code Asia © LY Corporation
  3. Community Over Code 2026 Glasgow Apache Software Foundation (ASF)ʼs global

    annual event • Alternately held in North America and Europe Summary • Date: 2026-10-10 ~ 2026-10-14 • 414 attendees in person • ~200 sessions • Co-located events ◦ Lakehouse Day ◦ Airflow Contributor Day ◦ Hackathon © LY Corporation
  4. Session report Agenda Data Infra and Data Engineering at OpenAI

    • Operating Apache Spark at OpenAIʼs Hyperscale Lakehouse • Beyond the Spark UI: Building Agent-Native Observability at OpenAI • Rhino Re-architecting Airflow at OpenAI Apache Spark session • Dynamic Resource Optimization with Heterogeneous Executors (Apple) Others • Apache Trusted Releases: Securing the Open Source Supply Chain (ASF Infra) © LY Corporation
  5. Apache Spark at OpenAI Hyperscale Lakehouse • Several EBs •

    Hundreds of thousands Spark jobs/day • Tens of millions K8s pods/day • Use both Azure and AWS, several TB/s datasync throughput between them Problems • Cloud throttling, quota ◦ Cross-zone traffic in S3 scan is hard • Rapid pod turnover → K8s control plane pressures © LY Corporation
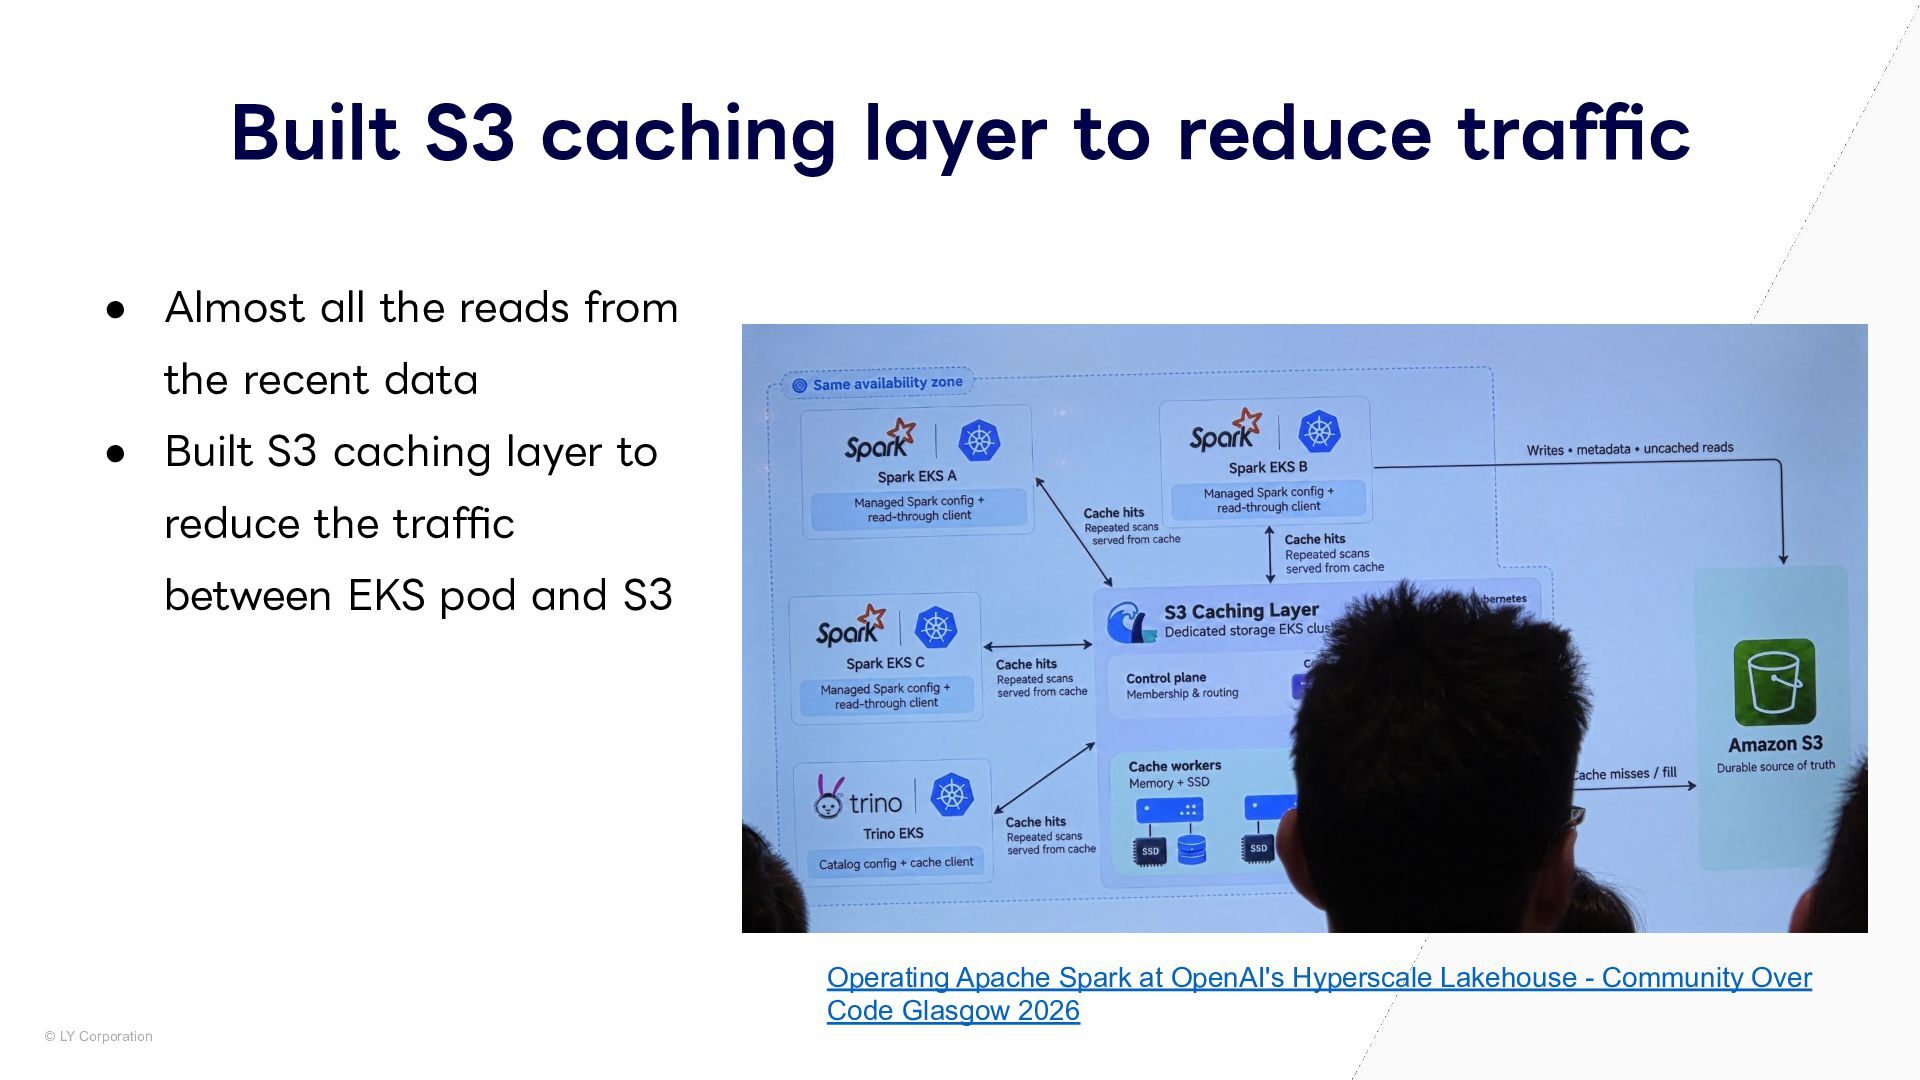
  6. Built S3 caching layer to reduce traffic • Almost all

    the reads from the recent data • Built S3 caching layer to reduce the traffic between EKS pod and S3 Operating Apache Spark at OpenAI's Hyperscale Lakehouse - Community Over Code Glasgow 2026 © LY Corporation
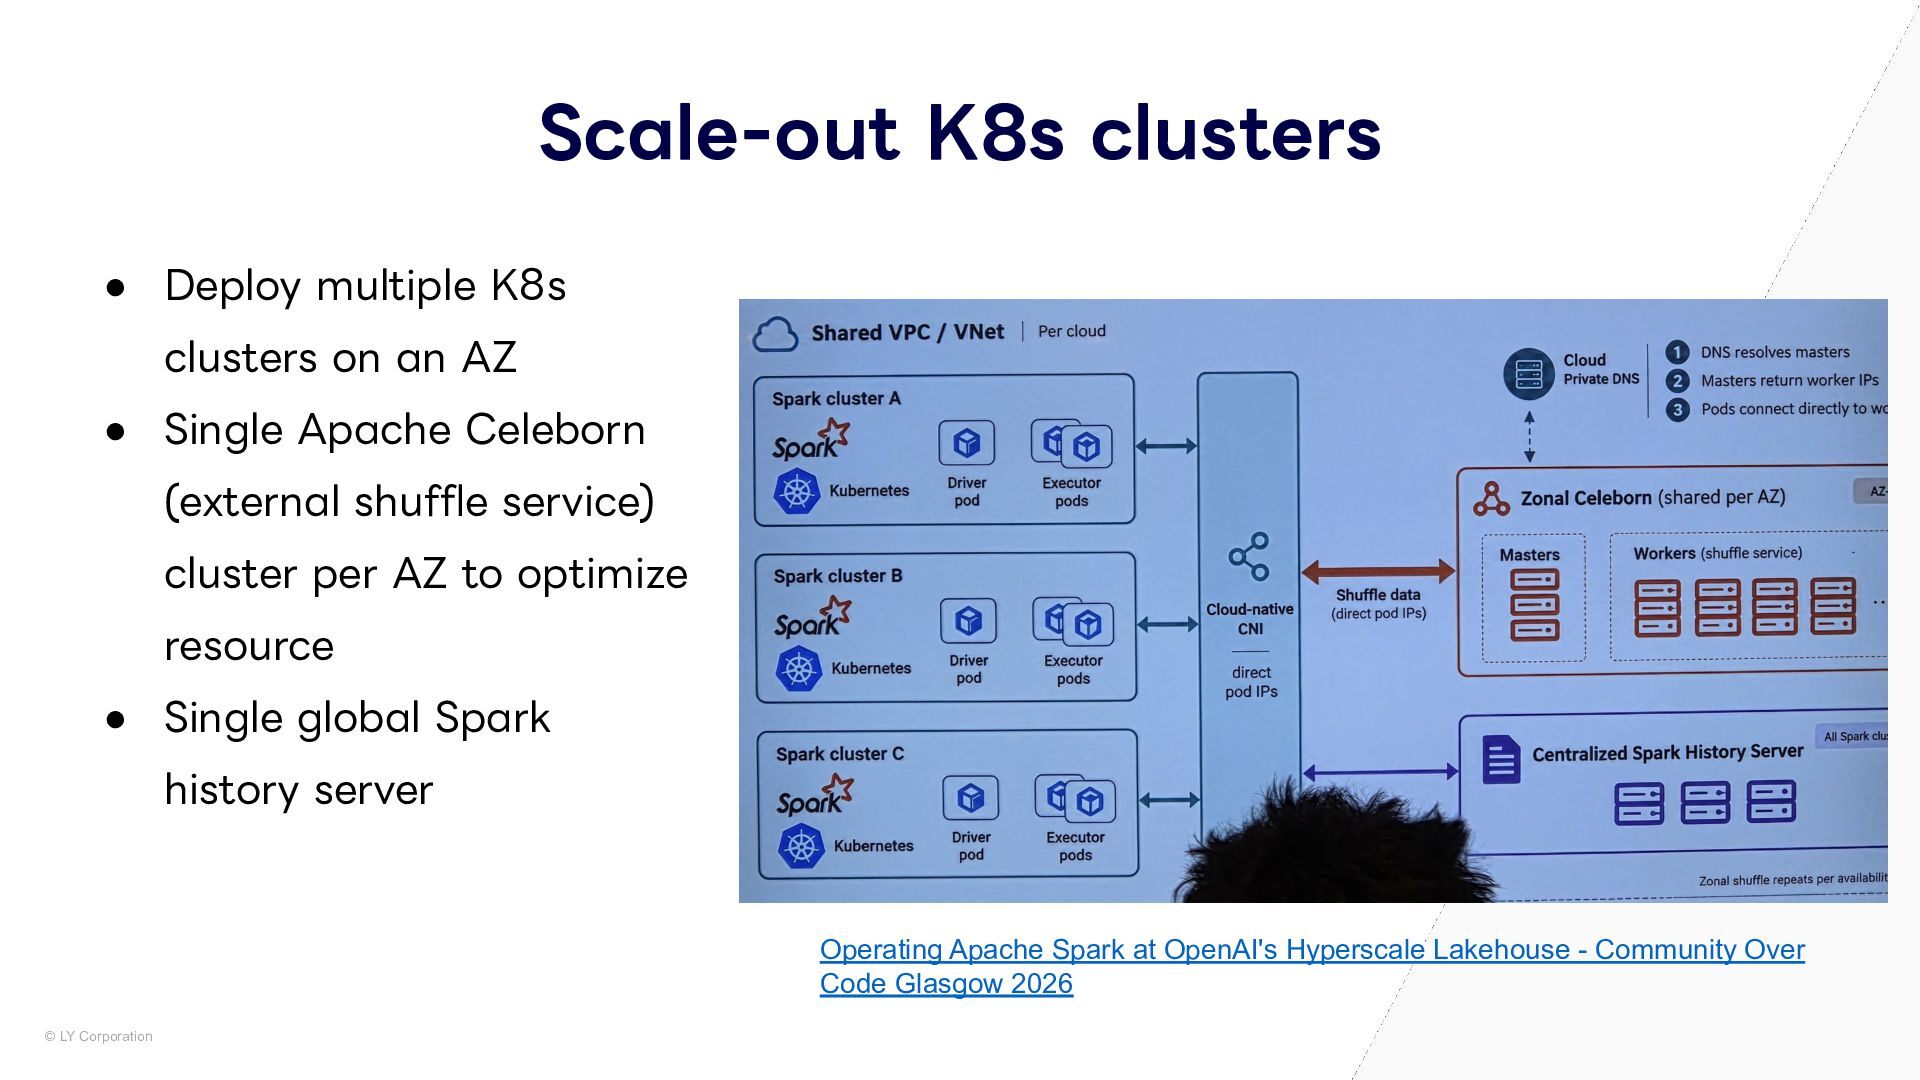
  7. Scale-out K8s clusters • Deploy multiple K8s clusters on an

    AZ • Single Apache Celeborn (external shuffle service) cluster per AZ to optimize resource • Single global Spark history server Operating Apache Spark at OpenAI's Hyperscale Lakehouse - Community Over Code Glasgow 2026 © LY Corporation
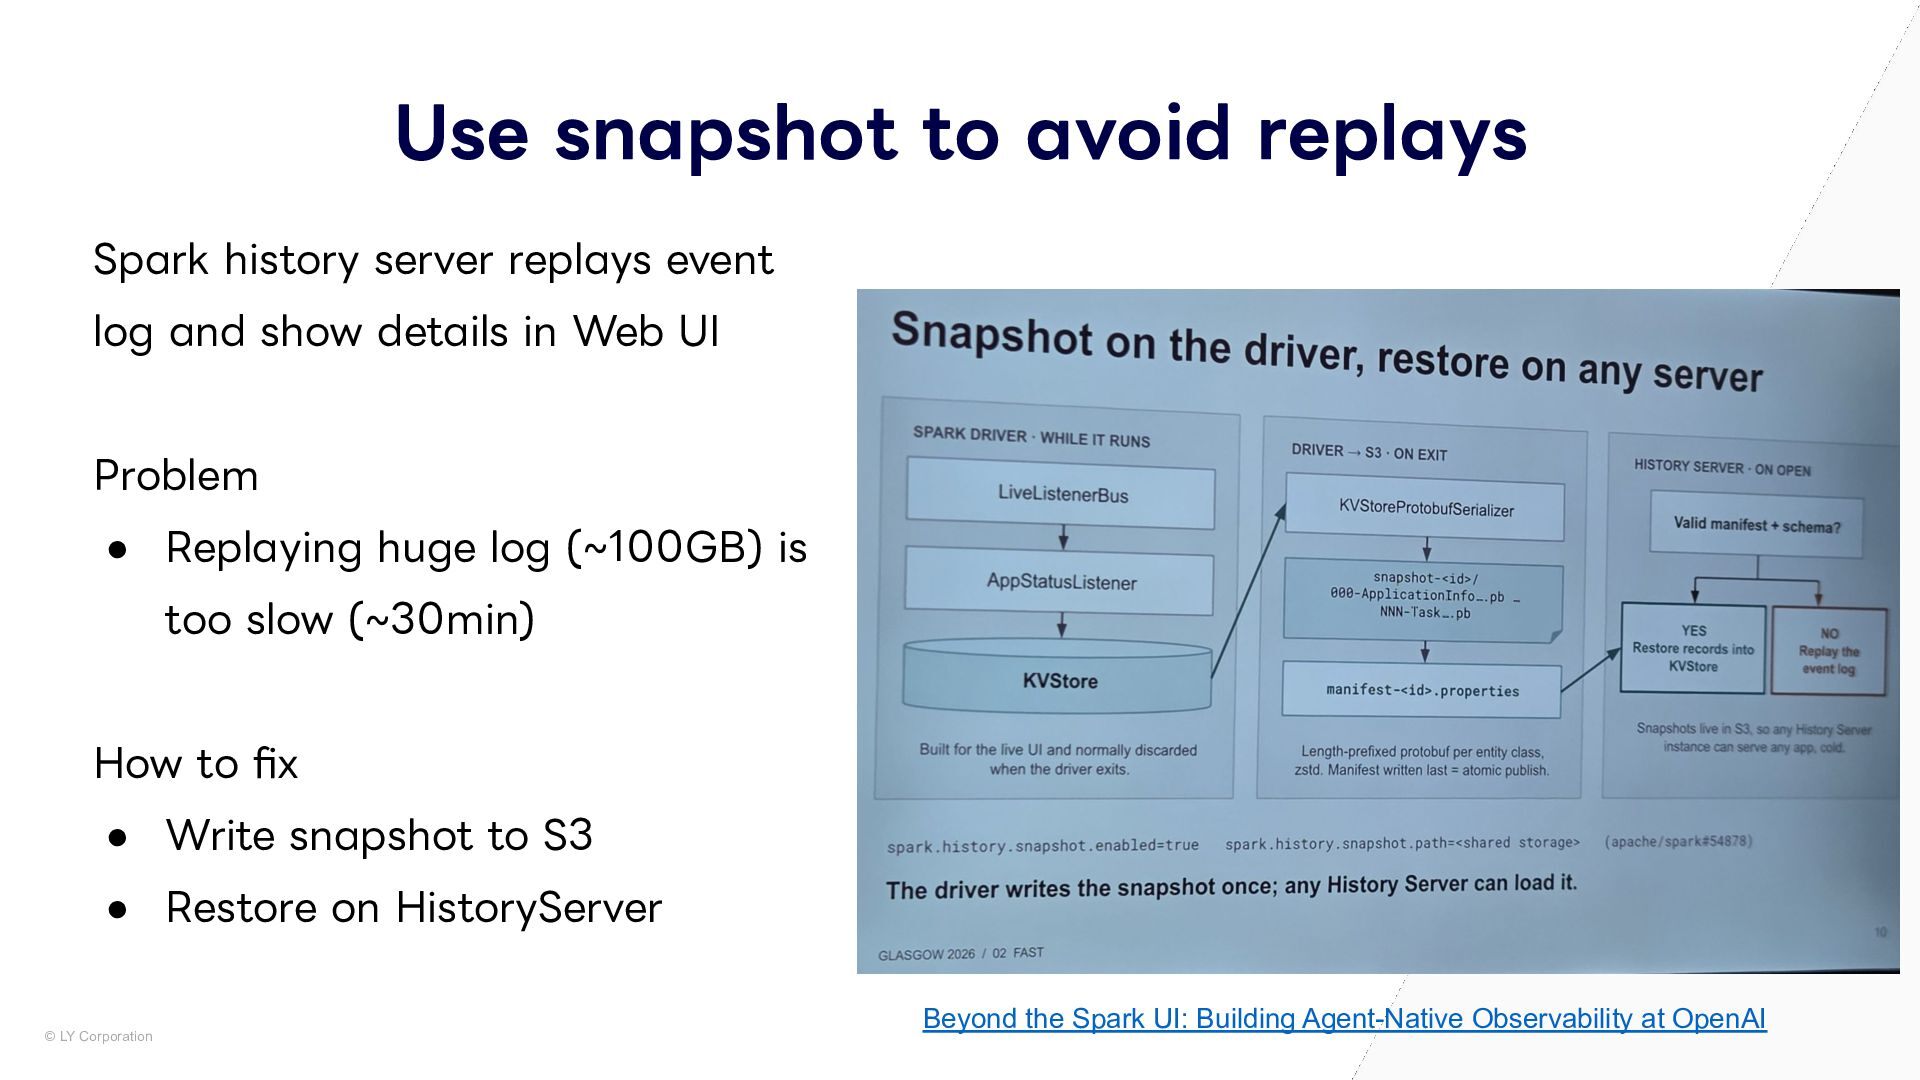
  8. Use snapshot to avoid replays Spark history server replays event

    log and show details in Web UI Problem • Replaying huge log (~100GB) is too slow (~30min) How to fix • Write snapshot to S3 • Restore on HistoryServer © LY Corporation Beyond the Spark UI: Building Agent-Native Observability at OpenAI
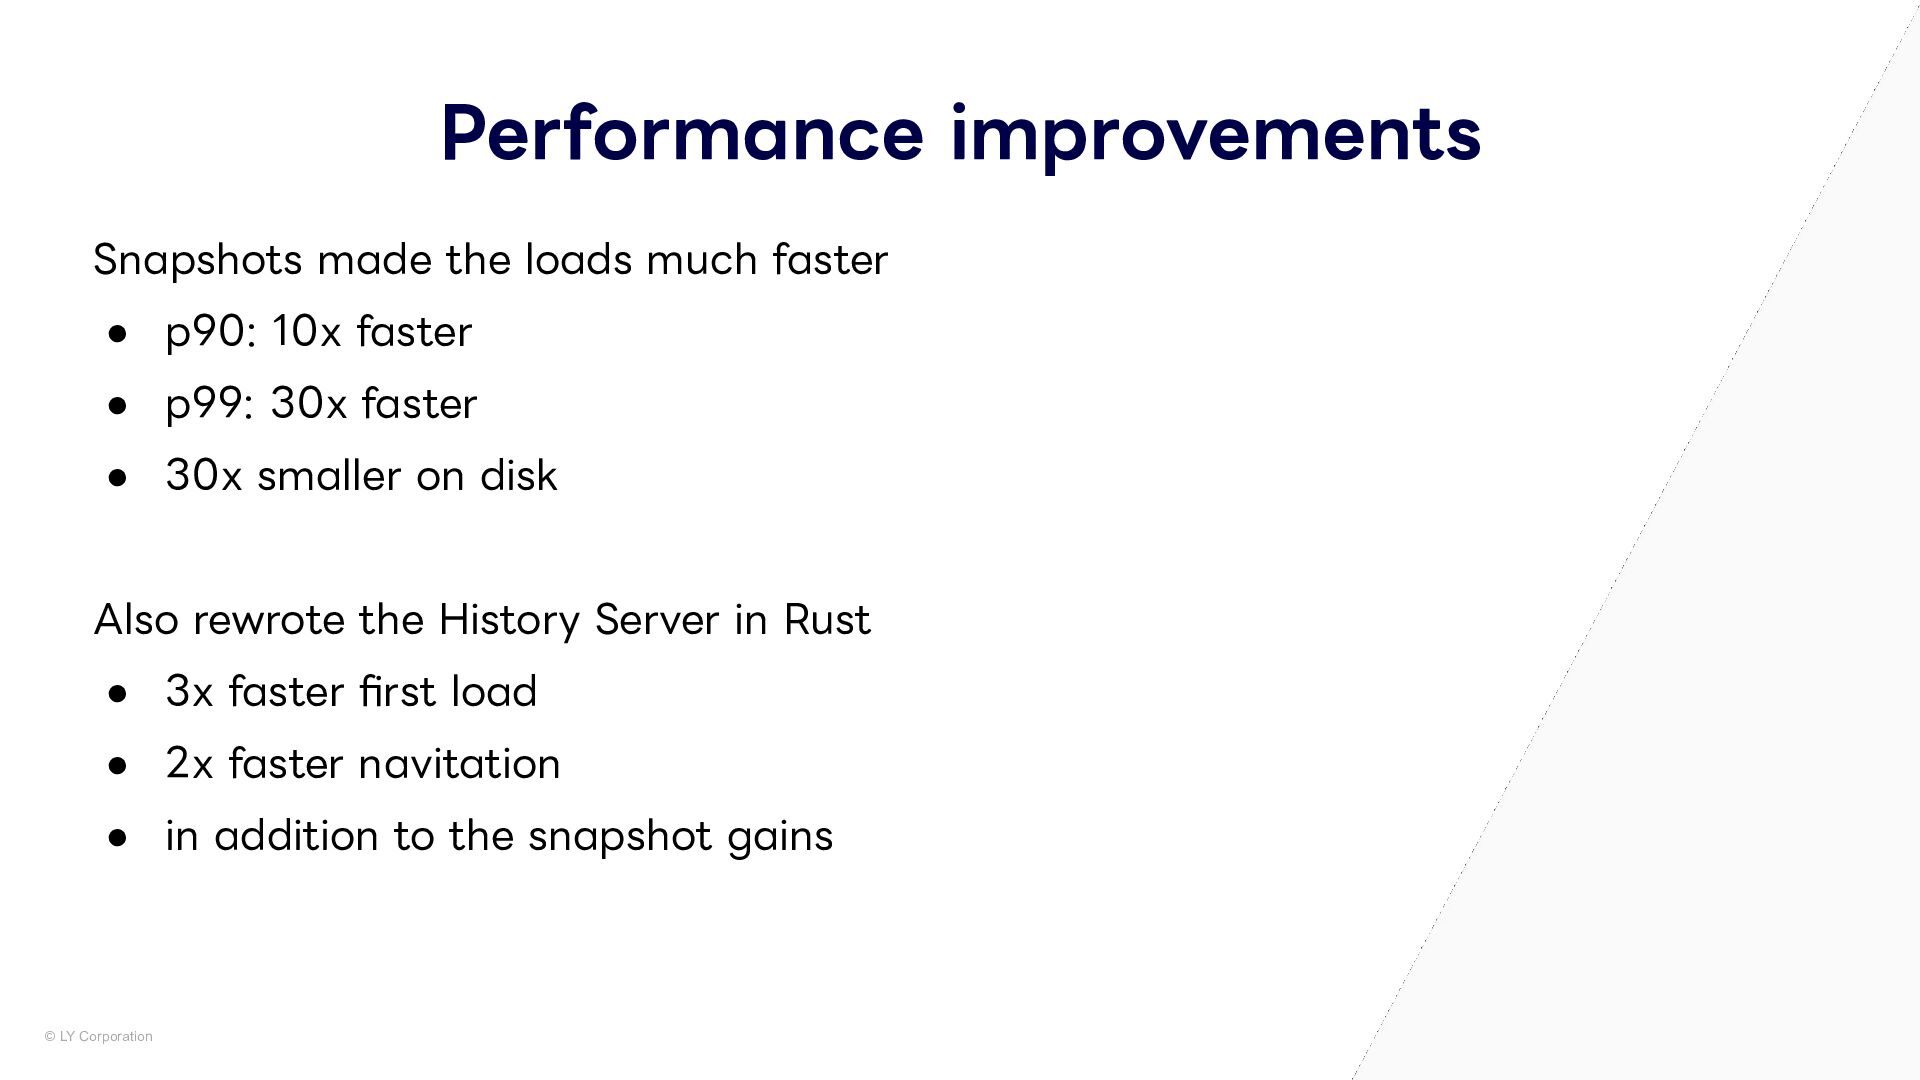
  9. Performance improvements Snapshots made the loads much faster • p90:

    10x faster • p99: 30x faster • 30x smaller on disk Also rewrote the History Server in Rust • 3x faster first load • 2x faster navitation • in addition to the snapshot gains © LY Corporation
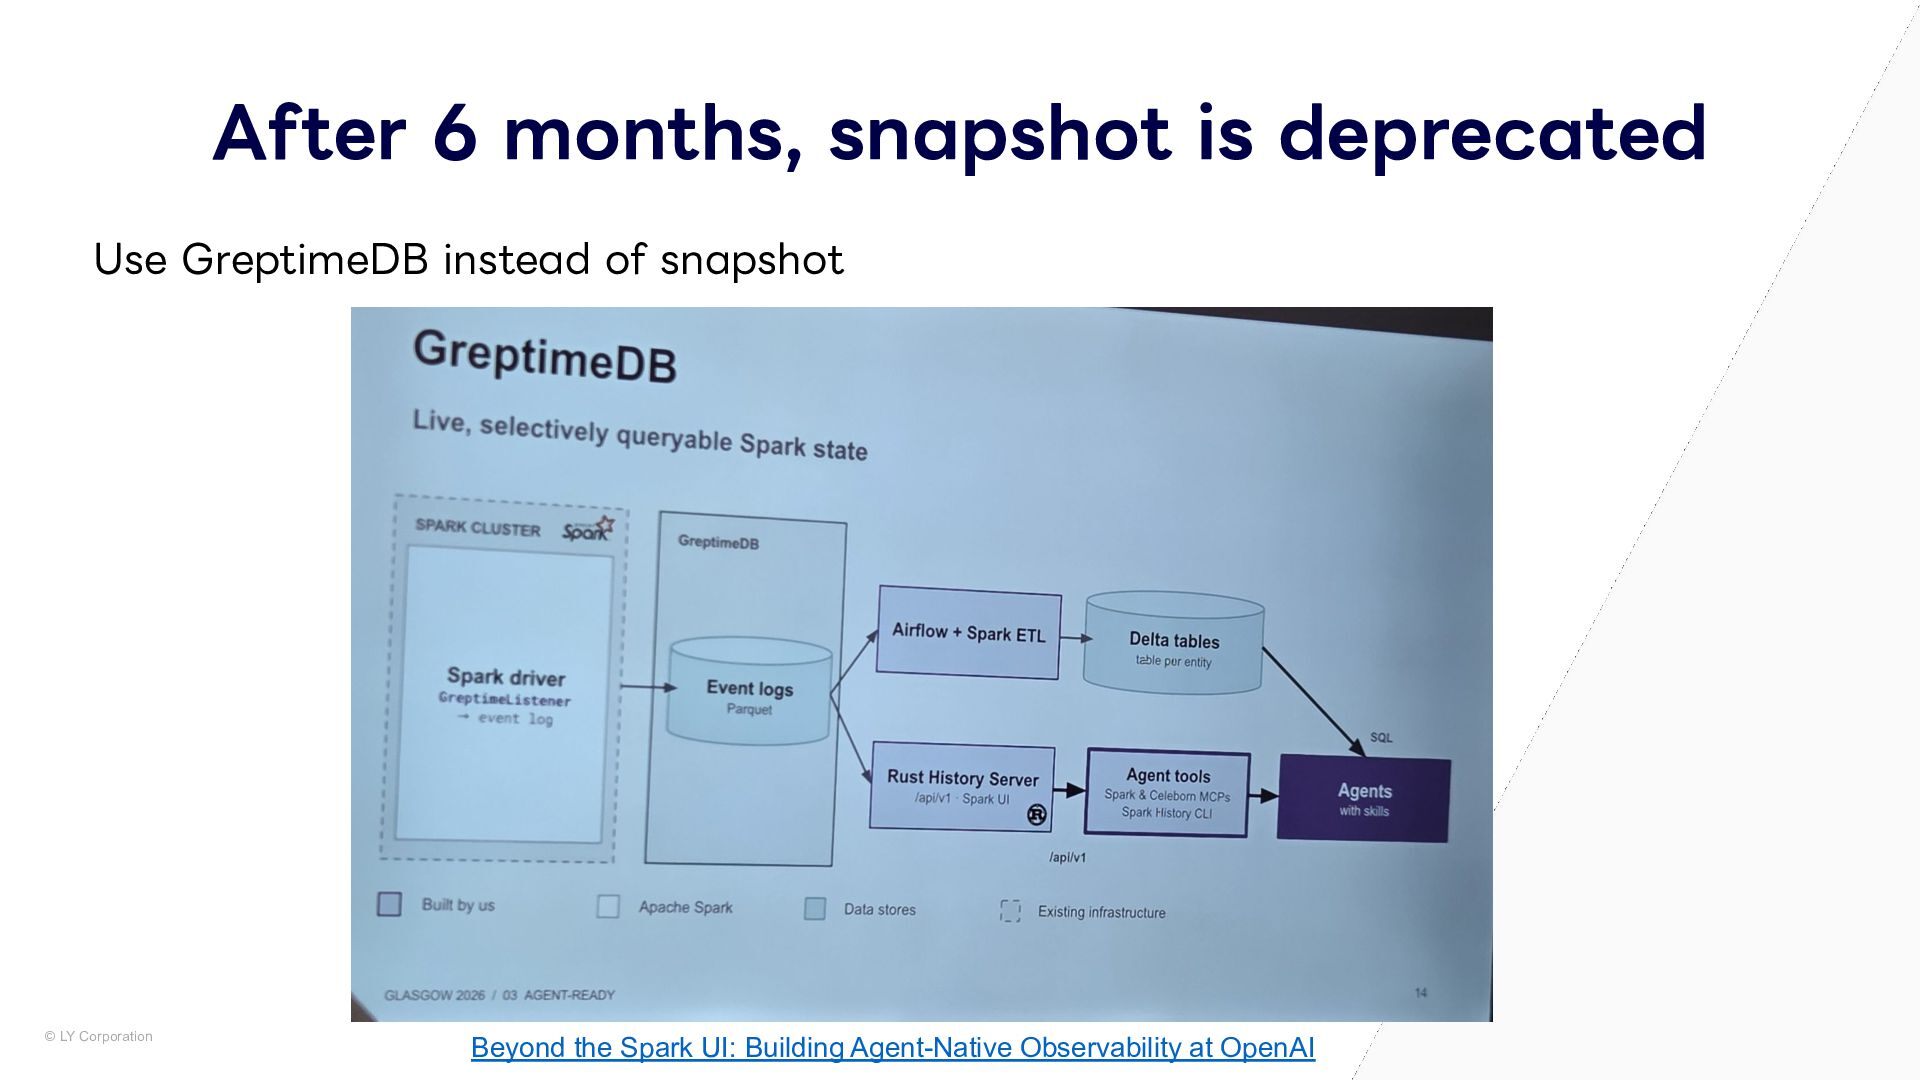
  10. After 6 months, snapshot is deprecated Use GreptimeDB instead of

    snapshot © LY Corporation Beyond the Spark UI: Building Agent-Native Observability at OpenAI
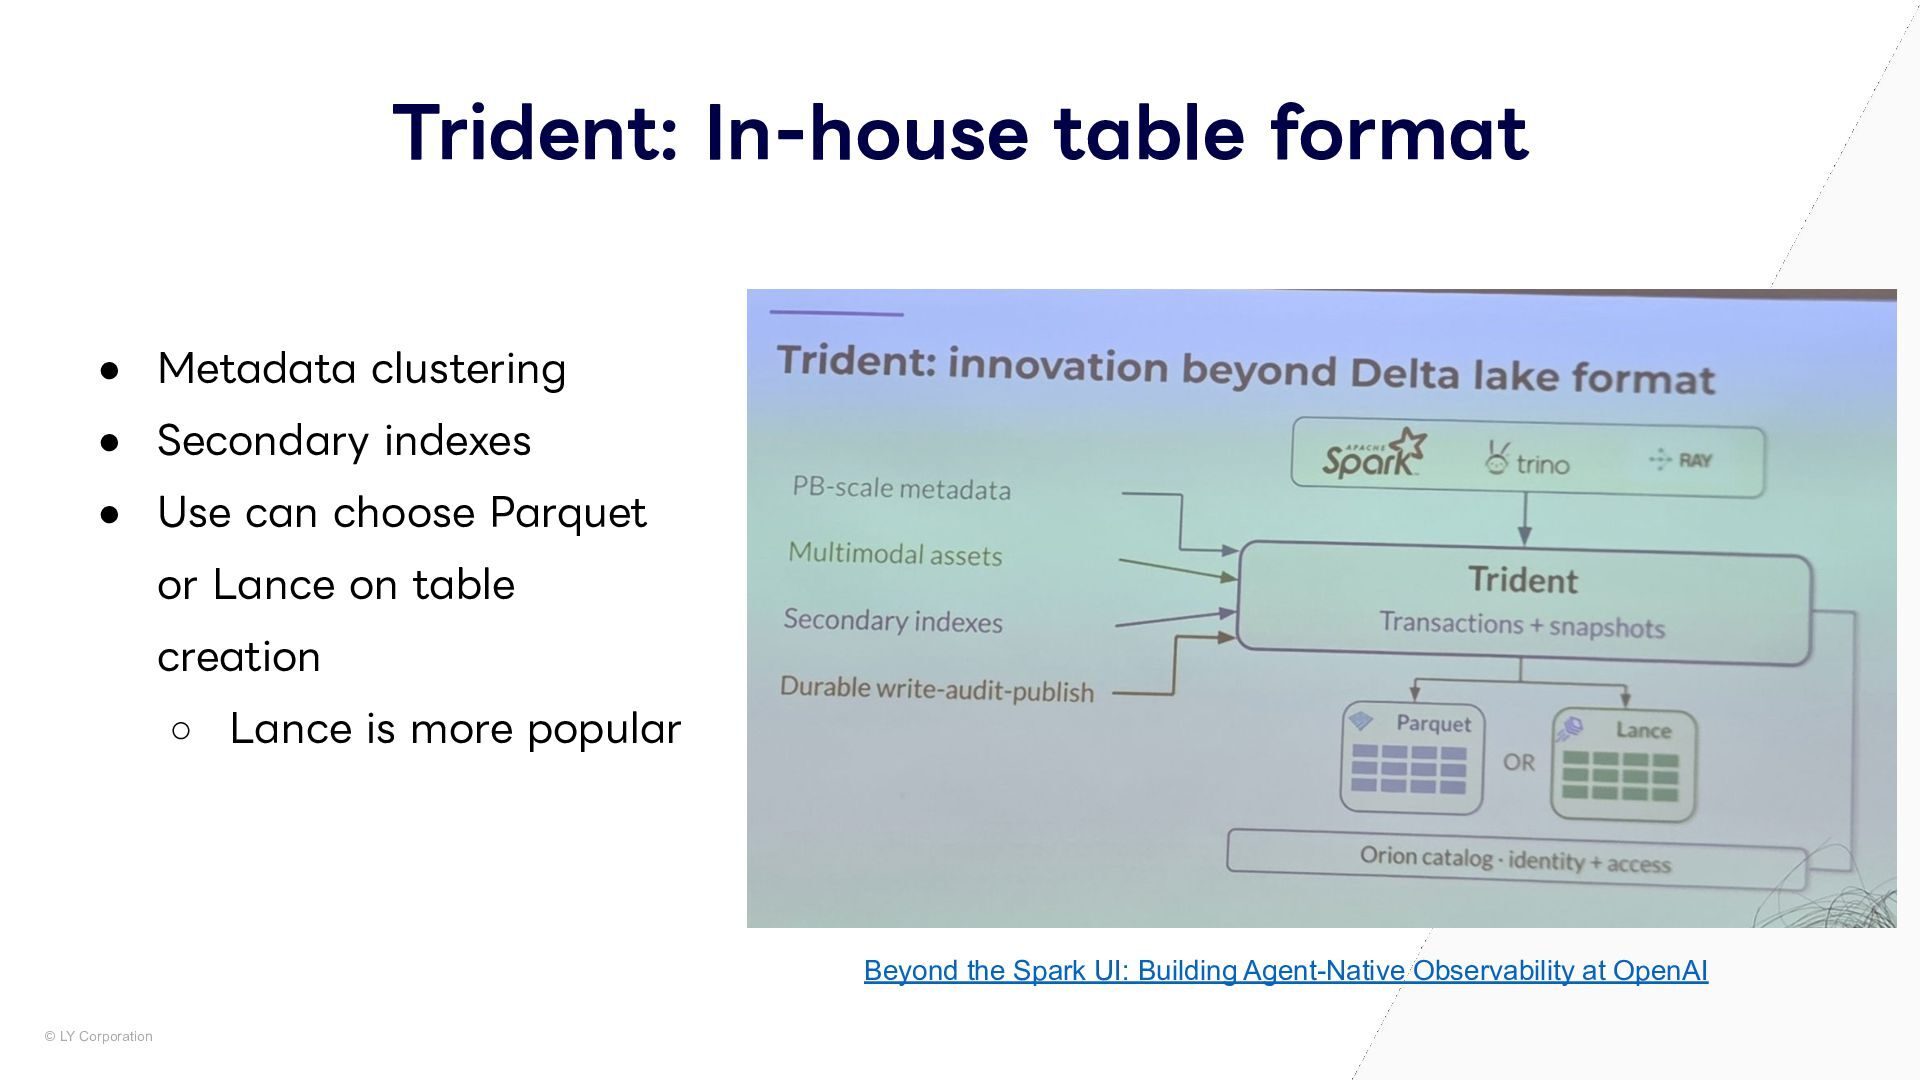
  11. Trident: In-house table format • Metadata clustering • Secondary indexes

    • Use can choose Parquet or Lance on table creation ◦ Lance is more popular Beyond the Spark UI: Building Agent-Native Observability at OpenAI © LY Corporation
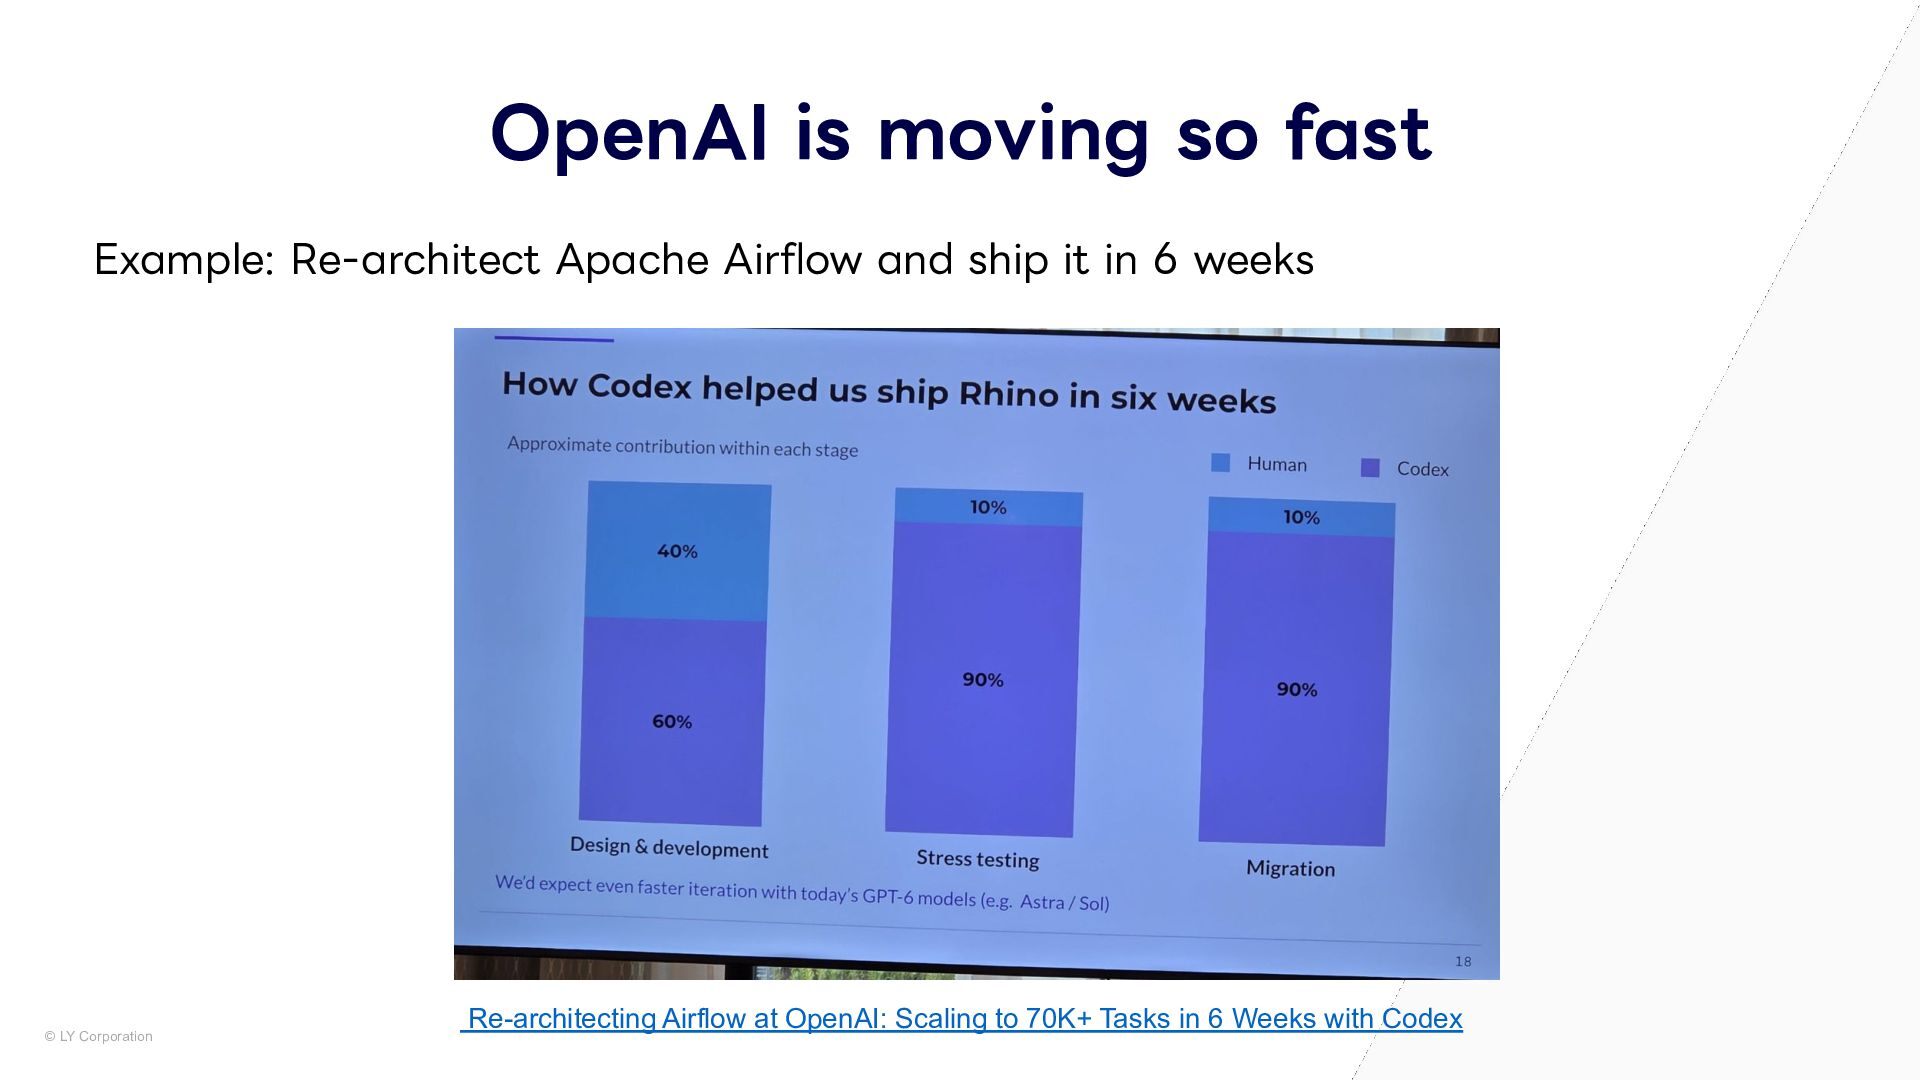
  12. OpenAI is moving so fast Example: Re-architect Apache Airflow and

    ship it in 6 weeks © LY Corporation Re-architecting Airflow at OpenAI: Scaling to 70K+ Tasks in 6 Weeks with Codex
  13. Dynamic Resource Optimization with Heterogeneous Executors [#SPARK-55555] Support heterogeneous K8s

    executor management - ASF Jira Background • In data skew, only an outlier task in a stage become OOM or Disk-full • If we increase the resource to accommodate the task, itʼs not efficient overall Pod restart is costly • JVM, Cached RDD/data, Shuffle files © LY Corporation
  14. Live executor resize (Spark 4.2+) Monitor the metrics and increase

    the resource automatically • PVC (Persistent Volume Claim) • Memory Limitations • Scale-up only • No guarantee of success ◦ Blocked by node capacity • JVM -Xmx flag cannot be updated © LY Corporation
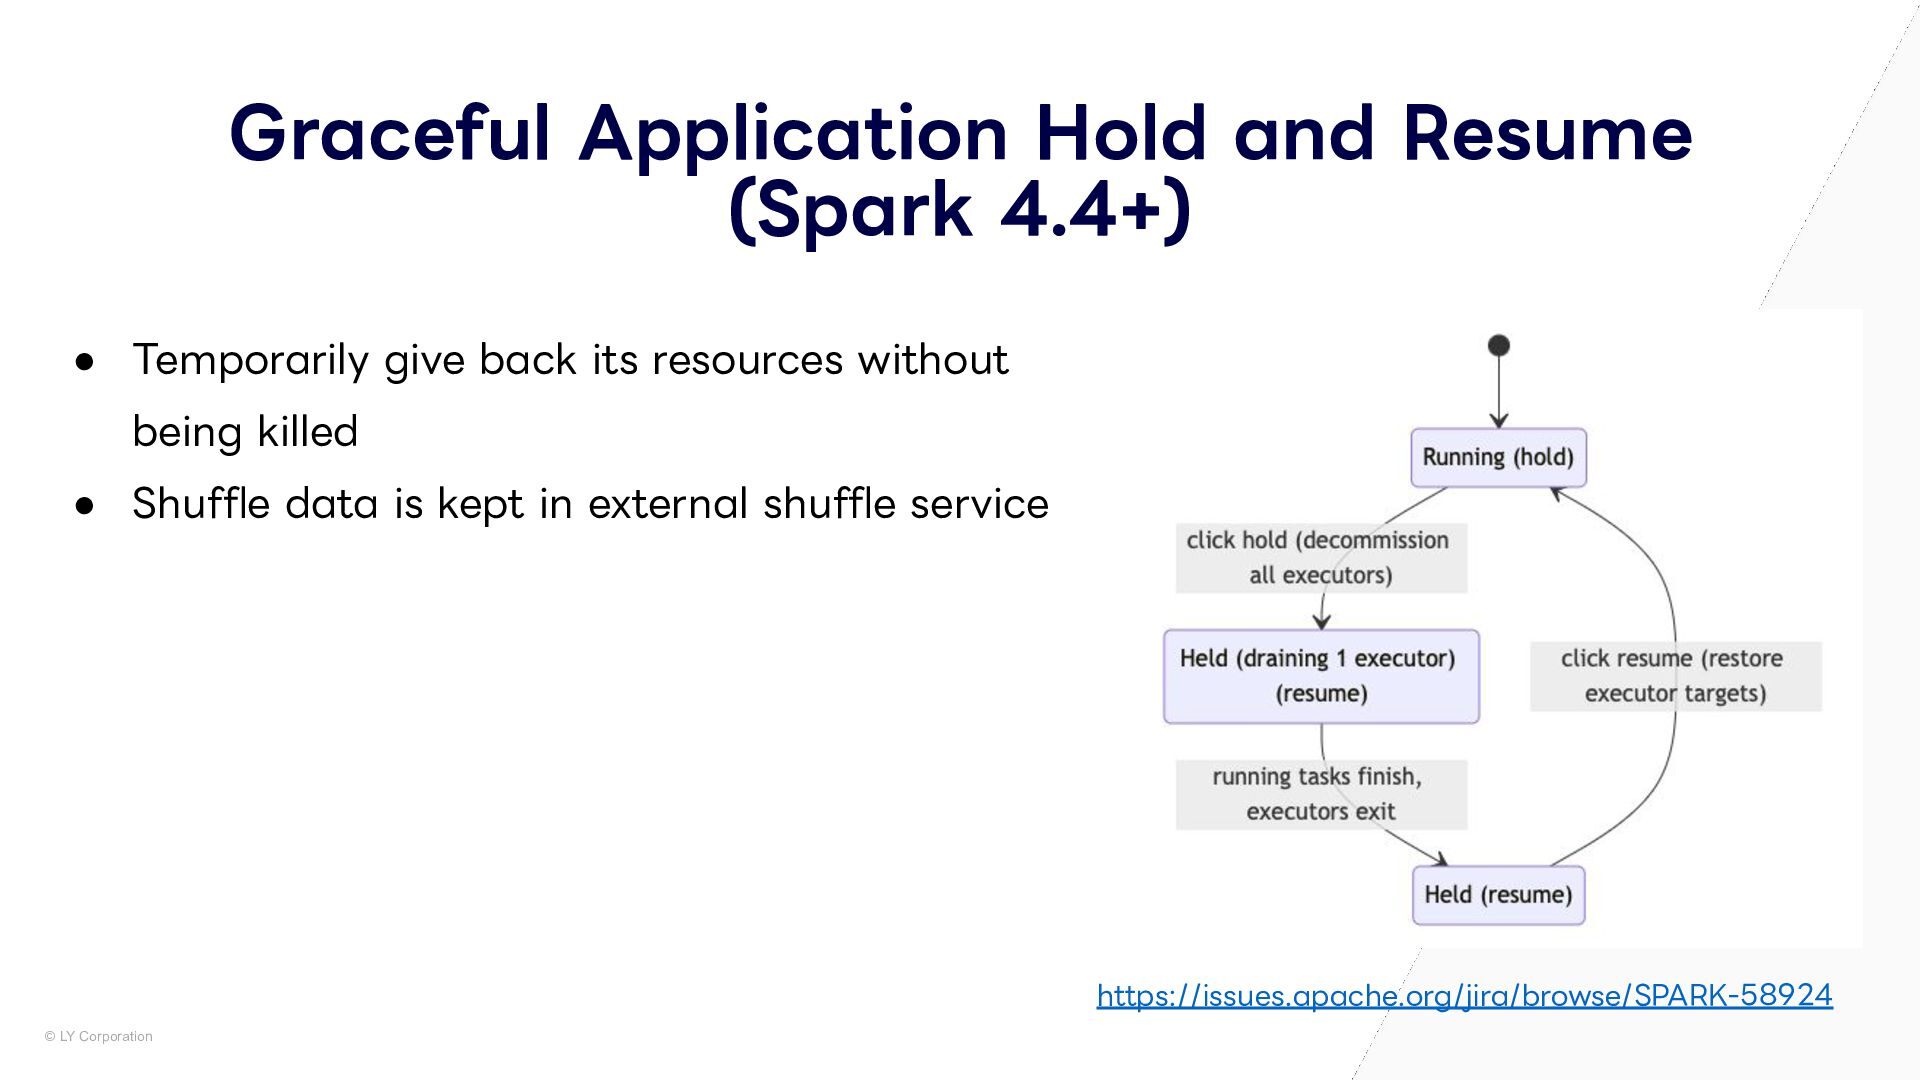
  15. Graceful Application Hold and Resume (Spark 4.4+) • Temporarily give

    back its resources without being killed • Shuffle data is kept in external shuffle service https://issues.apache.org/jira/browse/SPARK-58924 © LY Corporation
  16. Apache Trusted Releases (ATR) ASF-wide tool (beta) to 1. Automate

    the release process 2. Secure the supply chain 3. Record every release Automate mandatory manual checks • Checksum and GPG signature • License file and header It also provides SBOM (Software Bill of Materials) check • License and known vulnerabilities © LY Corporation
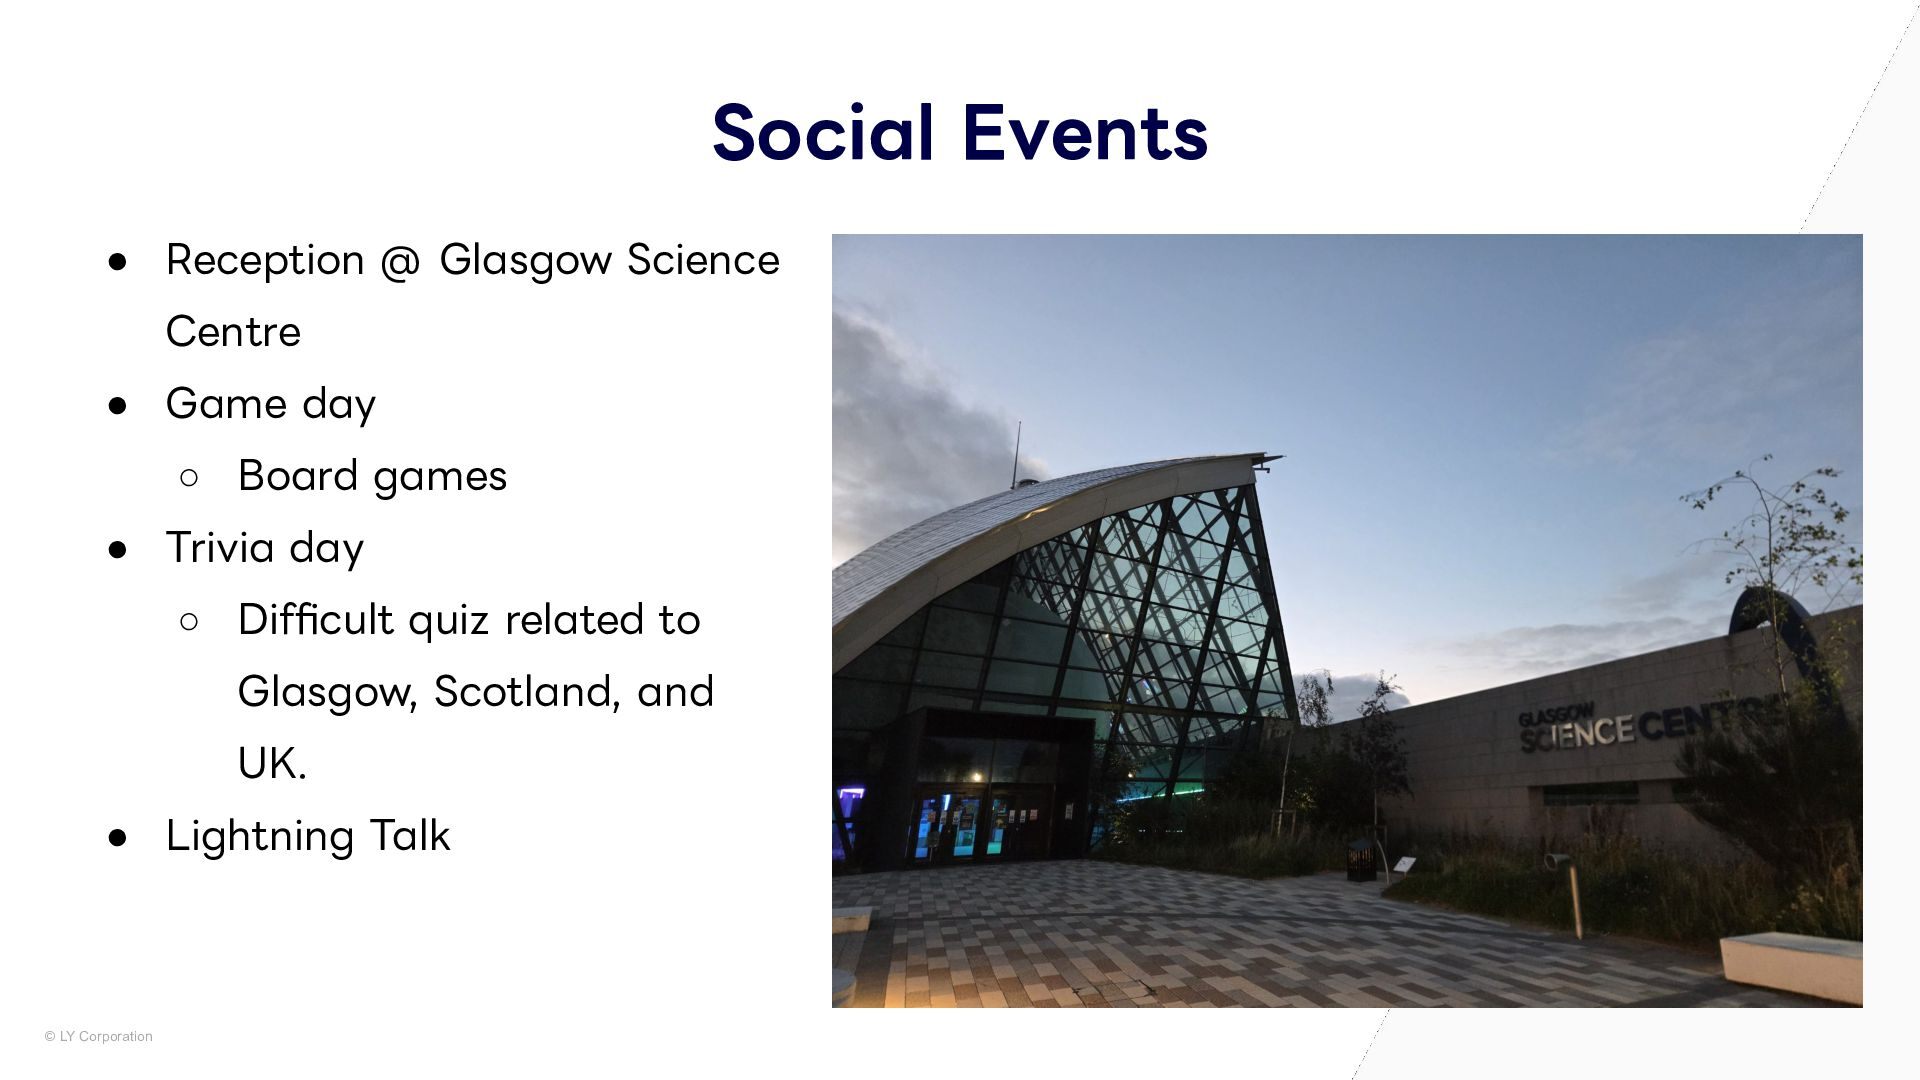
  17. Social Events • Reception @ Glasgow Science Centre • Game

    day ◦ Board games • Trivia day ◦ Difficult quiz related to Glasgow, Scotland, and UK. • Lightning Talk © LY Corporation
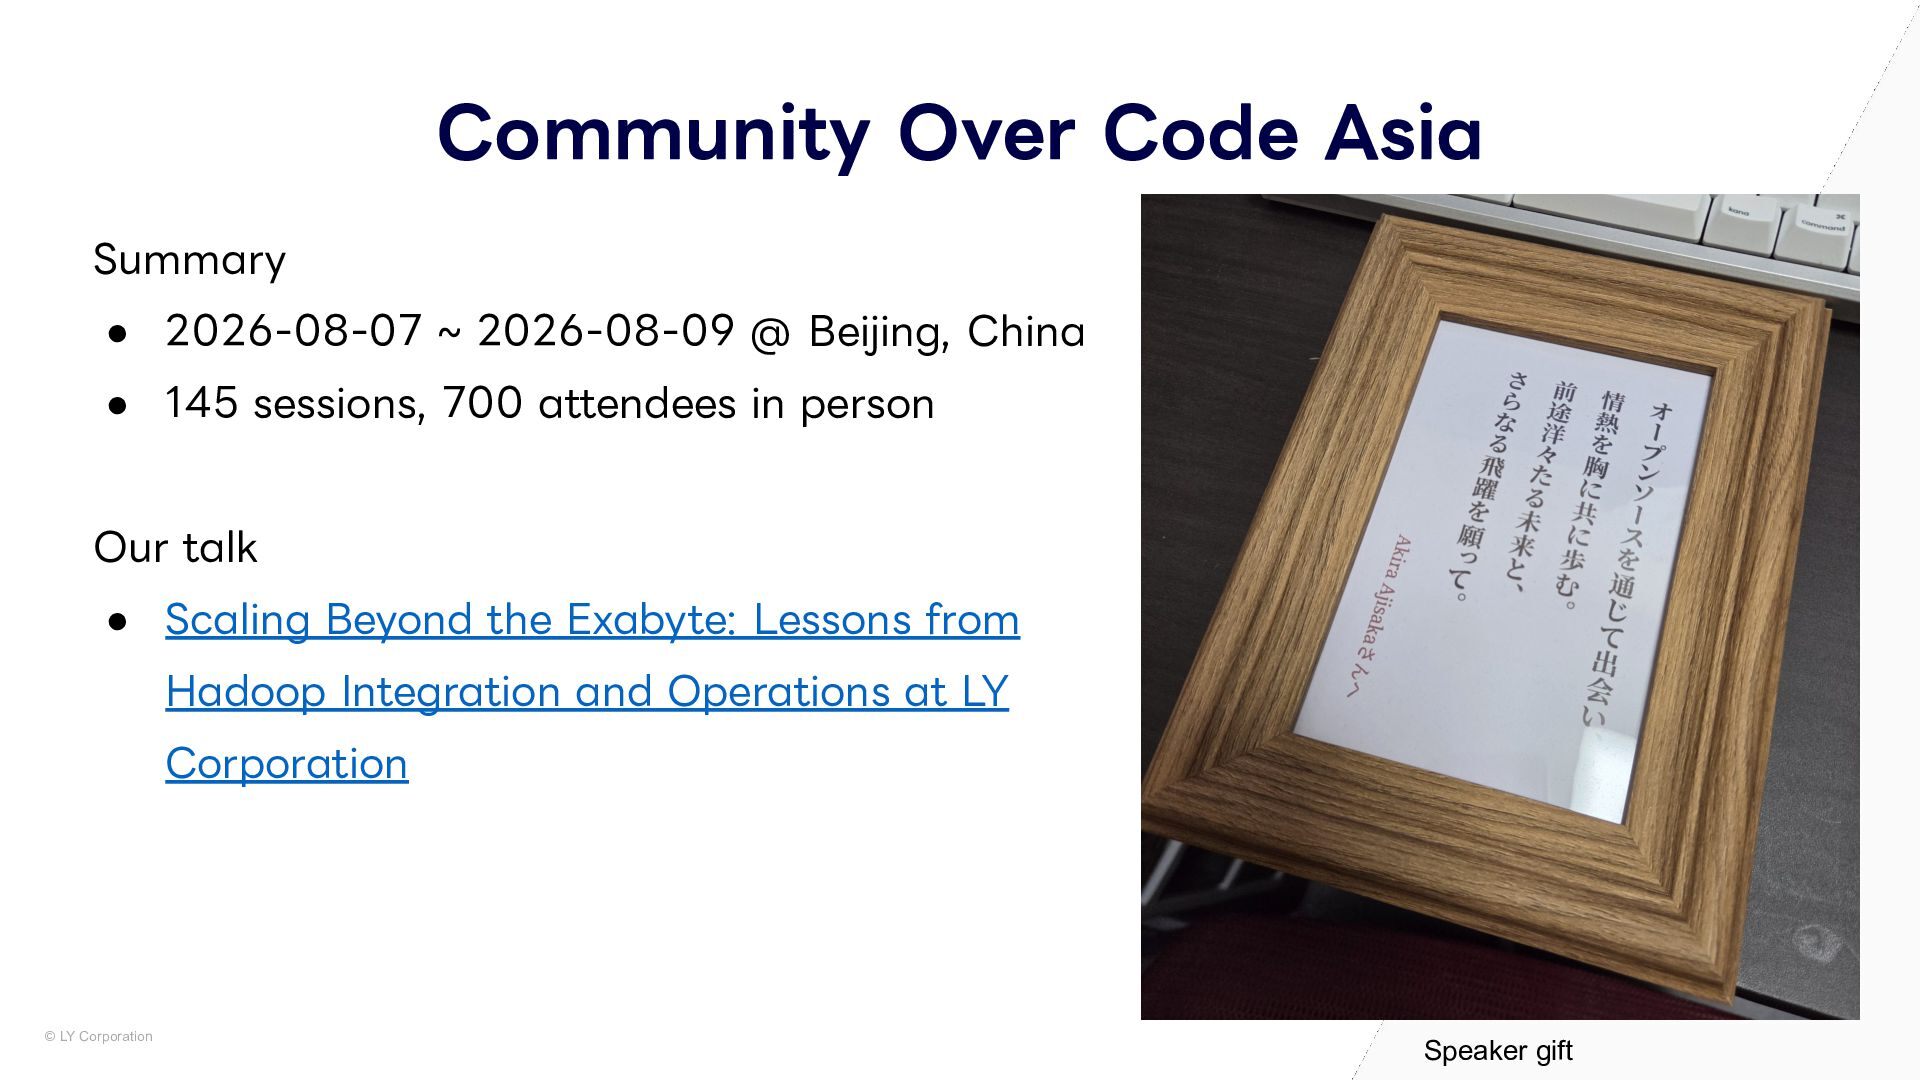
  18. Community Over Code Asia Summary • 2026-08-07 ~ 2026-08-09 @

    Beijing, China • 145 sessions, 700 attendees in person Our talk • Scaling Beyond the Exabyte: Lessons from Hadoop Integration and Operations at LY Corporation © LY Corporation Speaker gift
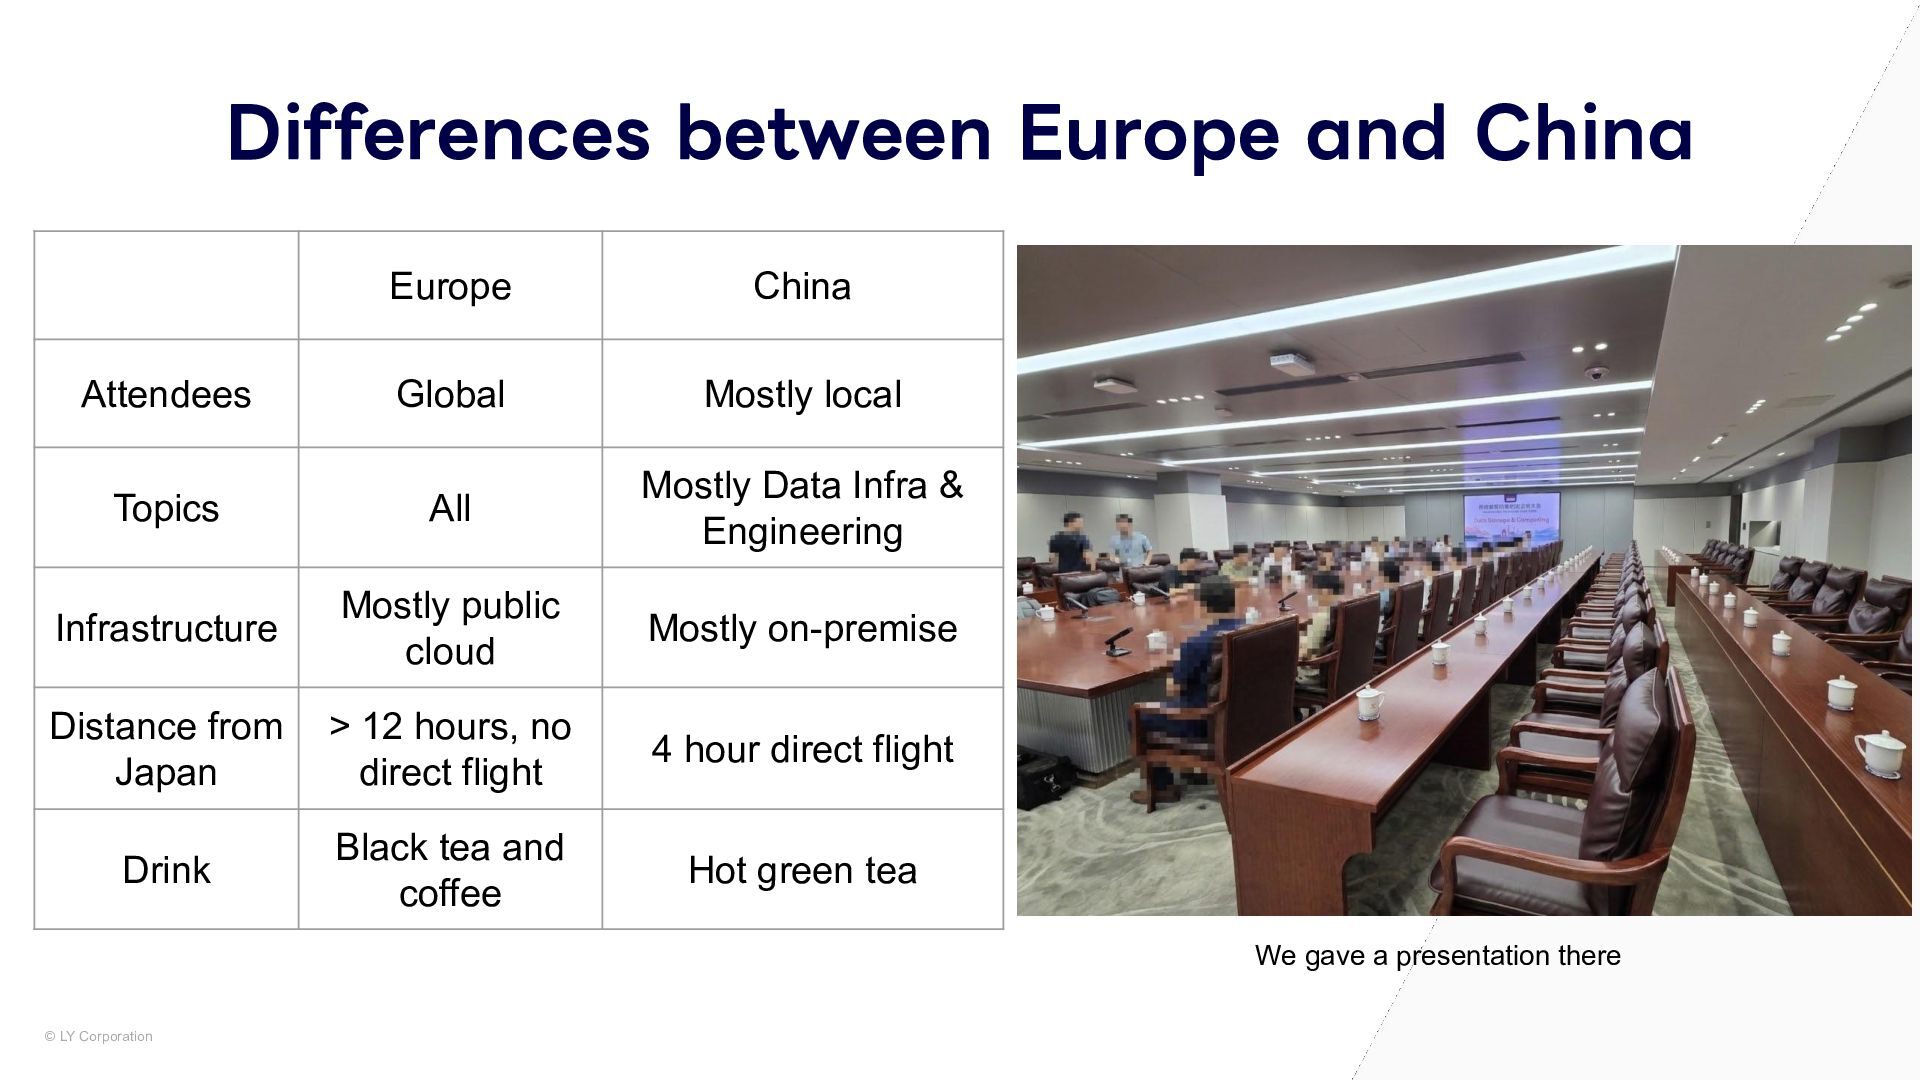
  19. Differences between Europe and China Europe China Attendees Global Mostly

    local Topics All Mostly Data Infra & Engineering Infrastructure Mostly public cloud Mostly on-premise Distance from Japan > 12 hours, no direct flight 4 hour direct flight Drink Black tea and coffee Hot green tea We gave a presentation there © LY Corporation