Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Hadoop Operations
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Marc Cluet
June 09, 2013
Technology
130
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Hadoop Operations
Marc Cluet
June 09, 2013
More Decks by Marc Cluet
See All by Marc Cluet
FOSDEM'14 - Autoscaling Best Practices
lynxman
1
130
A metadata ocean in Chef and Puppet
lynxman
0
72
Rackspace Hack Night - Vagrant & Packer
lynxman
0
170
Innovation in the Cloud - Rackspace Zurich Event
lynxman
0
110
Introduction to DevOps - Rackspace Tech Night
lynxman
1
97
Introduction To Hadoop
lynxman
1
140
SSH That Wonderful Thing
lynxman
1
120
Networking & DNS 101
lynxman
0
120
Juju and Puppet - Rapid Harmonious Deployment
lynxman
0
120
Other Decks in Technology
See All in Technology
Copilot Coworkで「みのるん式」やってみた
minorun365
PRO
1
750
Technical Project Manager の役割とやりがい、少しだけ AI
yoshiiryo1
0
550
Claude Codeから見る、エンジニアの世界の変容とその先
oikon48
8
5.1k
AI時代、つくる力を自分たちの手に。 ──電通×KAG、アジャイルとAI駆動開発で挑む開発の変革
yuukiyo
3
450
Patterns in AI Driven Software Development
akosma
PRO
0
430
AIに任せられるFlutterコードベースを作る 〜仕様をコードで表し、ハーネスで守る〜
myohei
1
610
AI Search (Foundry IQ) におけるRAGデータの準備と配置
ryomaru0825
1
130
You Have Agency(サンキュー、Ruby)
snoozer05
PRO
5
640
自律的なチームを作るためにTechPMがやらないこと
ny7760
0
450
SLOを阻む不安
sraku2159
0
200
攻撃 3 時間 vs 復旧 10 時間。アクセスキー流出の非対称性を体感するために CTF を作った話
kazzpapa3
1
130
詳解 never 型 - ボトム型の性質を深掘り
nealle
0
130
Featured
See All Featured
Exploring the relationship between traditional SERPs and Gen AI search
raygrieselhuber
PRO
4
4.4k
Build The Right Thing And Hit Your Dates
maggiecrowley
39
3.5k
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.6k
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
Six Lessons from altMBA
skipperchong
29
4.6k
We Analyzed 250 Million AI Search Results: Here's What I Found
joshbly
2
2.1k
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
Fireside Chat
paigeccino
43
4.1k
Tips & Tricks on How to Get Your First Job In Tech
honzajavorek
1
820
[Rails World 2023 - Day 1 Closing Keynote] - The Magic of Rails
eileencodes
38
3.1k
How to Align SEO within the Product Triangle To Get Buy-In & Support - #RIMC
aleyda
2
1.9k
Chasing Engaging Ingredients in Design
codingconduct
0
380
Transcript
Marc Cluet – Lynx Consultants How Hadoop Works
What we’ll cover? ¡ Understand Hadoop in detail ¡
See how Hadoop works operationally ¡ Be able to start asking the right questions from your data Lynx Consultants © 2013
Hadoop Distributions ¡ Cloudera CDH ¡ Hortonworks ¡
MapR Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase ¡ MapRed
¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS § Hadoop Distributed File System
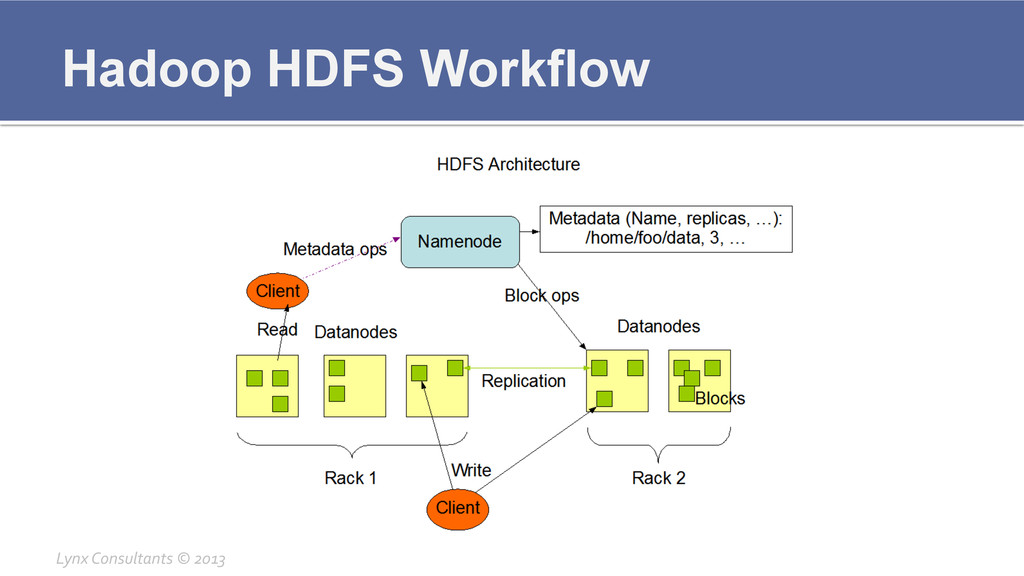
§ Everything sits on top of it § Has 3 copies by default of every block ¡ Hbase ¡ MapRed ¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase § Hadoop
Schemaless Database § Key value Store § Sits on top of HDFS ¡ MapRed ¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase ¡ MapRed
§ Hadoop Map/Reduce § Non-‐pluggable, archaic § Requires HDFS for temp storage ¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase ¡ MapRed
¡ YARN § Hadoop Map/Reduce version 2.0 § Pluggable, you can add your own § Fast and not so much memory hungry Lynx Consultants © 2013
Hadoop Component Breakdown ¡ All these components divide themselves in
§ client/server § master/slave scenarios ¡ We will now check each individual component breakdown Lynx Consultants © 2013
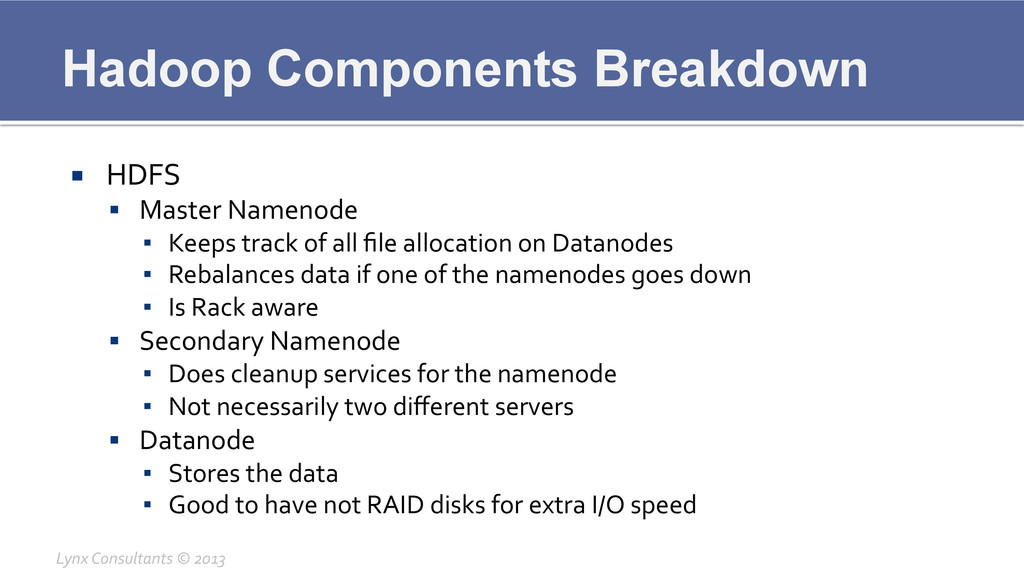
Hadoop Components Breakdown ¡ HDFS § Master Namenode
▪ Keeps track of all file allocation on Datanodes ▪ Rebalances data if one of the namenodes goes down ▪ Is Rack aware § Secondary Namenode ▪ Does cleanup services for the namenode ▪ Not necessarily two different servers § Datanode ▪ Stores the data ▪ Good to have not RAID disks for extra I/O speed Lynx Consultants © 2013
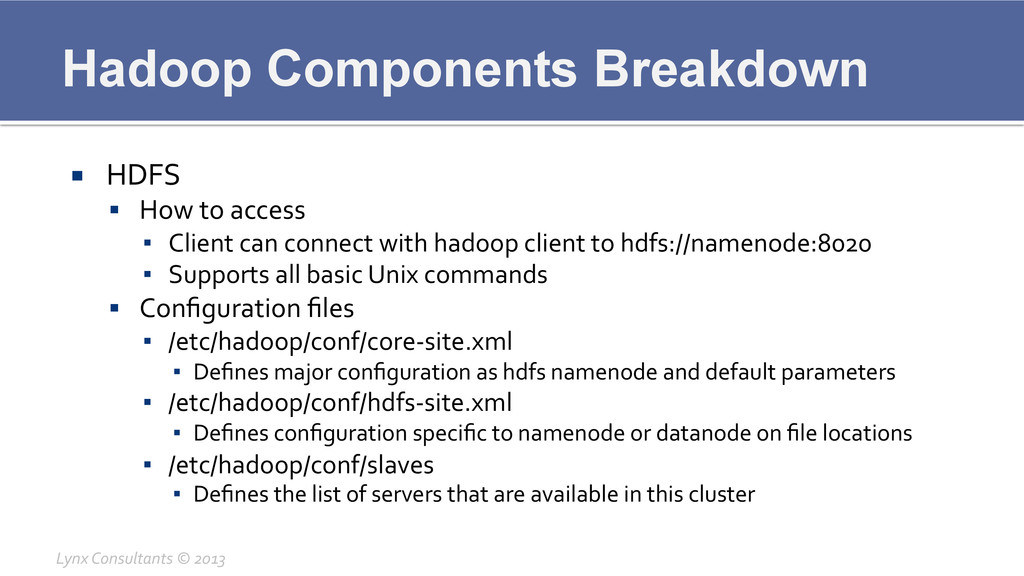
Hadoop Components Breakdown ¡ HDFS § How to access
▪ Client can connect with hadoop client to hdfs://namenode:8020 ▪ Supports all basic Unix commands § Configuration files ▪ /etc/hadoop/conf/core-‐site.xml ▪ Defines major configuration as hdfs namenode and default parameters ▪ /etc/hadoop/conf/hdfs-‐site.xml ▪ Defines configuration specific to namenode or datanode on file locations ▪ /etc/hadoop/conf/slaves ▪ Defines the list of servers that are available in this cluster Lynx Consultants © 2013
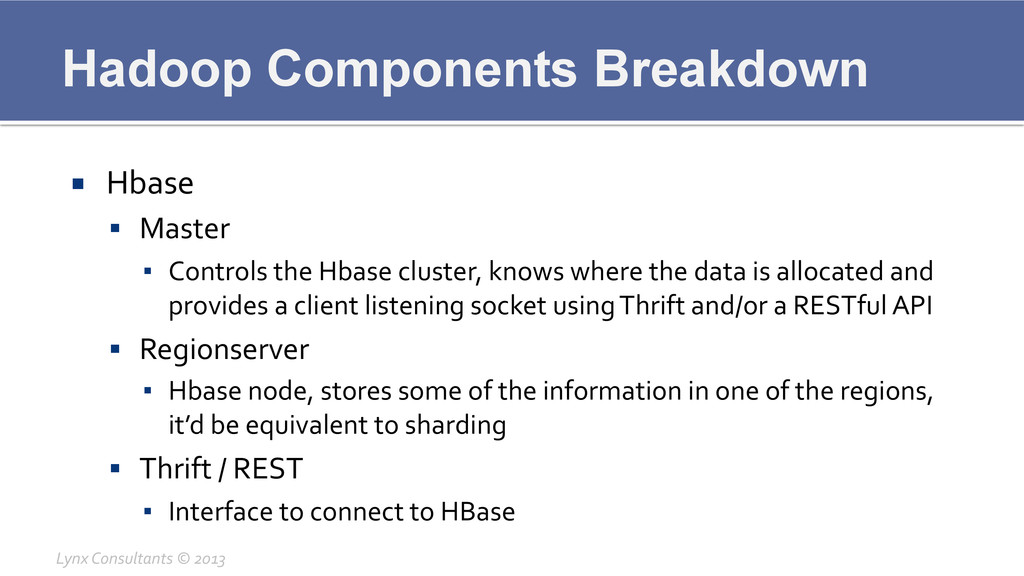
Hadoop Components Breakdown ¡ Hbase § Master ▪
Controls the Hbase cluster, knows where the data is allocated and provides a client listening socket using Thrift and/or a RESTful API § Regionserver ▪ Hbase node, stores some of the information in one of the regions, it’d be equivalent to sharding § Thrift / REST ▪ Interface to connect to HBase Lynx Consultants © 2013
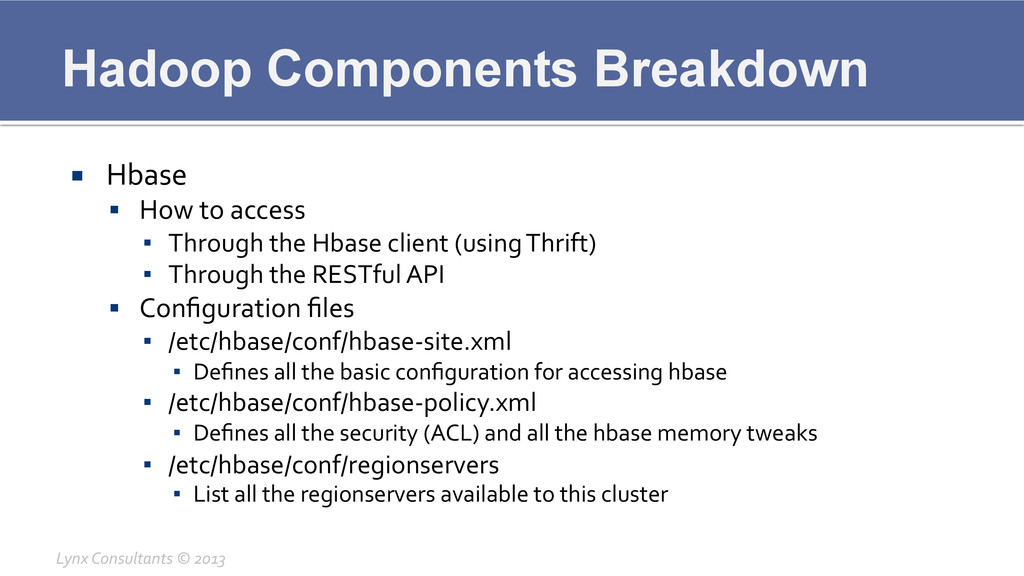
Hadoop Components Breakdown ¡ Hbase § How to access
▪ Through the Hbase client (using Thrift) ▪ Through the RESTful API § Configuration files ▪ /etc/hbase/conf/hbase-‐site.xml ▪ Defines all the basic configuration for accessing hbase ▪ /etc/hbase/conf/hbase-‐policy.xml ▪ Defines all the security (ACL) and all the hbase memory tweaks ▪ /etc/hbase/conf/regionservers ▪ List all the regionservers available to this cluster Lynx Consultants © 2013
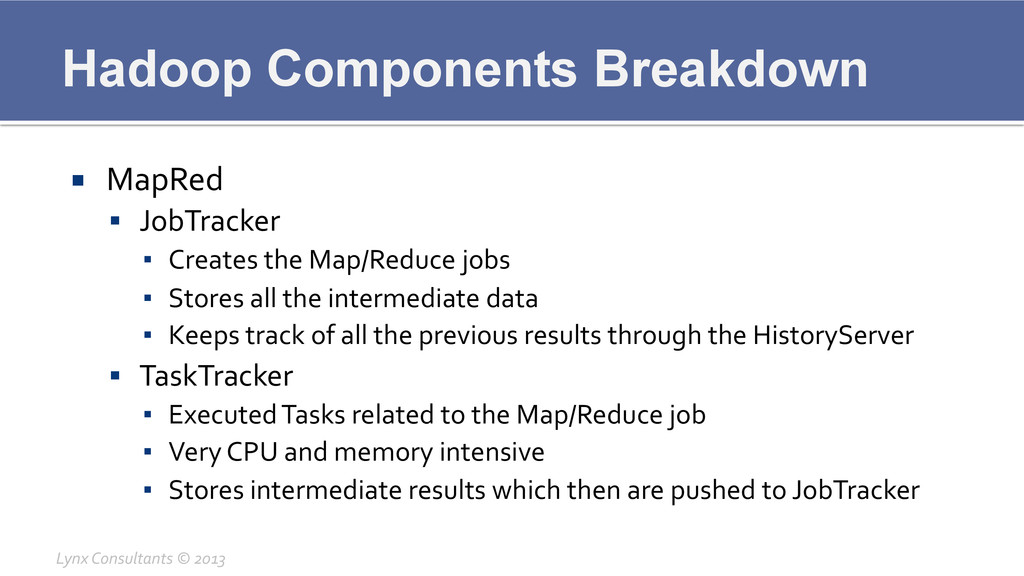
Hadoop Components Breakdown ¡ MapRed § JobTracker ▪
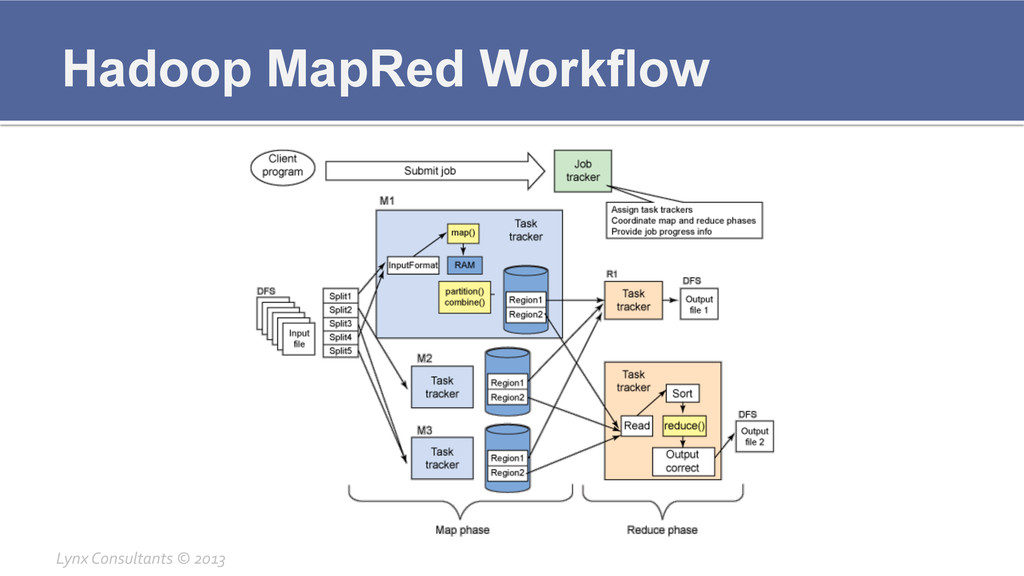
Creates the Map/Reduce jobs ▪ Stores all the intermediate data ▪ Keeps track of all the previous results through the HistoryServer § TaskTracker ▪ Executed Tasks related to the Map/Reduce job ▪ Very CPU and memory intensive ▪ Stores intermediate results which then are pushed to JobTracker Lynx Consultants © 2013
Hadoop Components Breakdown ¡ MapRed § How to access
▪ Through the Hadoop Client ▪ Through any MapRed client like Pig or Hive ▪ Own Java code § Configuration files ▪ /etc/hadoop/conf/mapred-‐site.xml ▪ Defines how to contact this MapRed Cluster ▪ /etc/hadoop/conf/mapred-‐queue-‐acls.xml ▪ Defines ACL structure for accessing MapRed, normally not necessary ▪ /etc/hadoop/conf/slaves ▪ Defines the list of TaskTrackers in this cluster Lynx Consultants © 2013
Hadoop Components Breakdown ¡ YARN § Same structure as
MapRed (lives on top of it) § Configuration files ▪ /etc/hadoop/conf/yarn-‐site.xml ▪ All required configuration for YARN Lynx Consultants © 2013
Hadoop Cluster Breakdown ¡ Namenode Server § HDFS Namenode
§ Hbase Master ¡ Secondary Namenode Server § HDFS Secondary Namenode ¡ JobTracker Server § MapRed JobTracker § MapRed History Server Lynx Consultants © 2013
Hadoop Cluster Breakdown ¡ Datanode Server § HDFS Datanode
§ Hbase RegionServer § MapRed TaskTracker Lynx Consultants © 2013
Hadoop Hardware Requirements ¡ Namenode Server § Redundant power
supplies § RAID1 Drives § Enough memory (16Gb) ¡ Secondary Namenode Server § Almost none Lynx Consultants © 2013
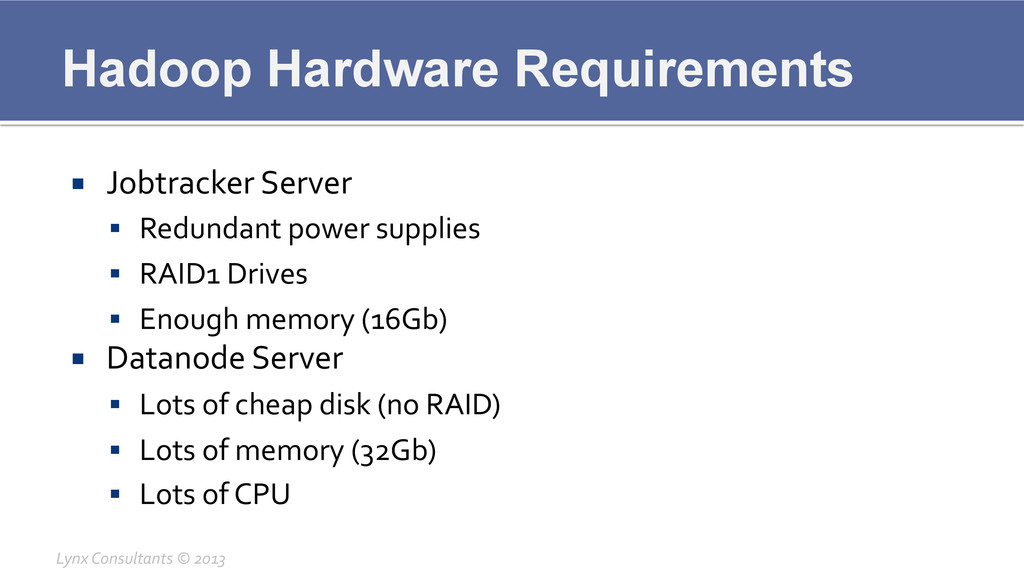
Hadoop Hardware Requirements ¡ Jobtracker Server § Redundant power
supplies § RAID1 Drives § Enough memory (16Gb) ¡ Datanode Server § Lots of cheap disk (no RAID) § Lots of memory (32Gb) § Lots of CPU Lynx Consultants © 2013
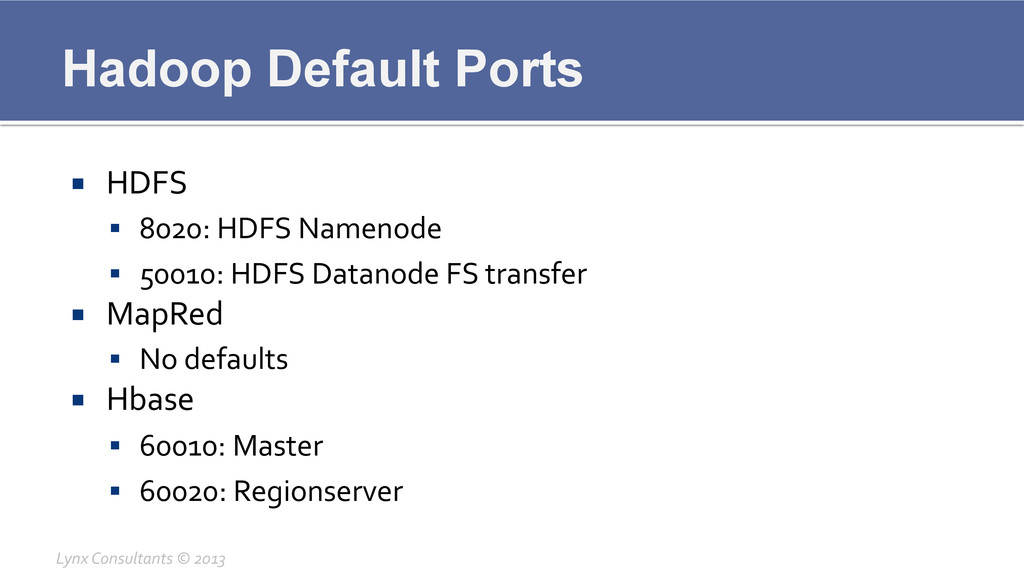
Hadoop Default Ports ¡ HDFS § 8020: HDFS Namenode
§ 50010: HDFS Datanode FS transfer ¡ MapRed § No defaults ¡ Hbase § 60010: Master § 60020: Regionserver Lynx Consultants © 2013
Hadoop HDFS Workflow Lynx Consultants © 2013
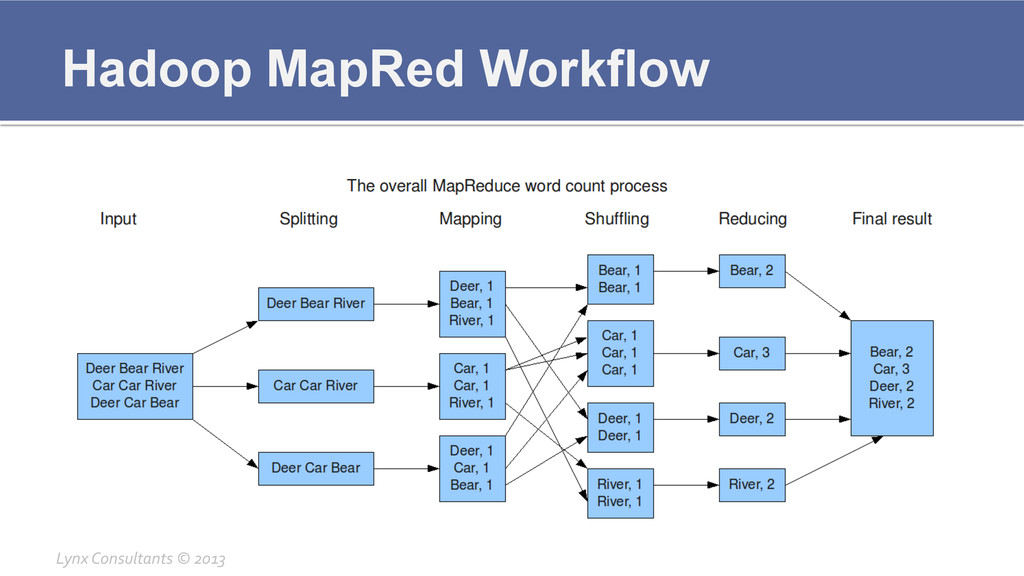
Hadoop MapRed Workflow Lynx Consultants © 2013
Hadoop MapRed Workflow Lynx Consultants © 2013
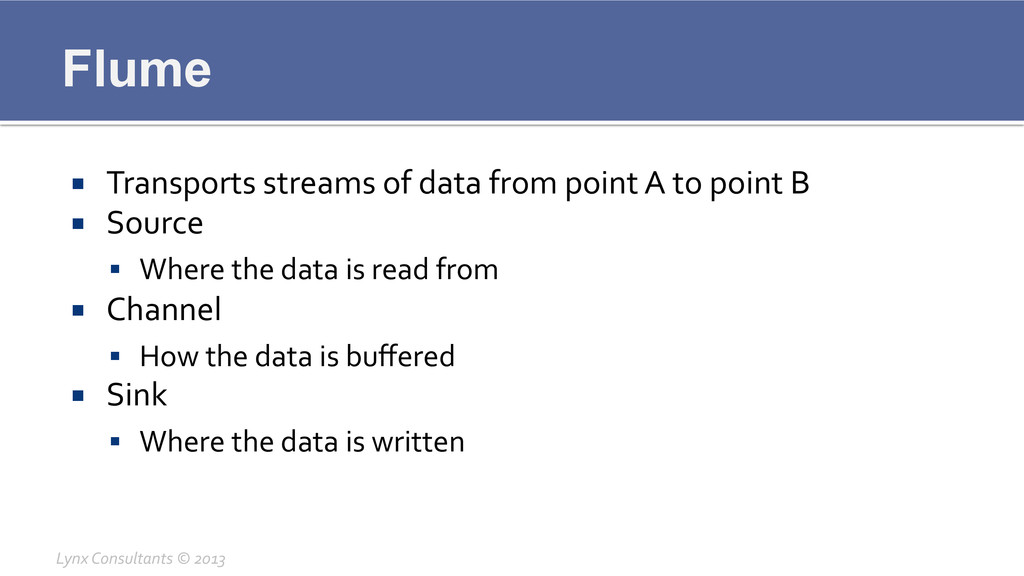
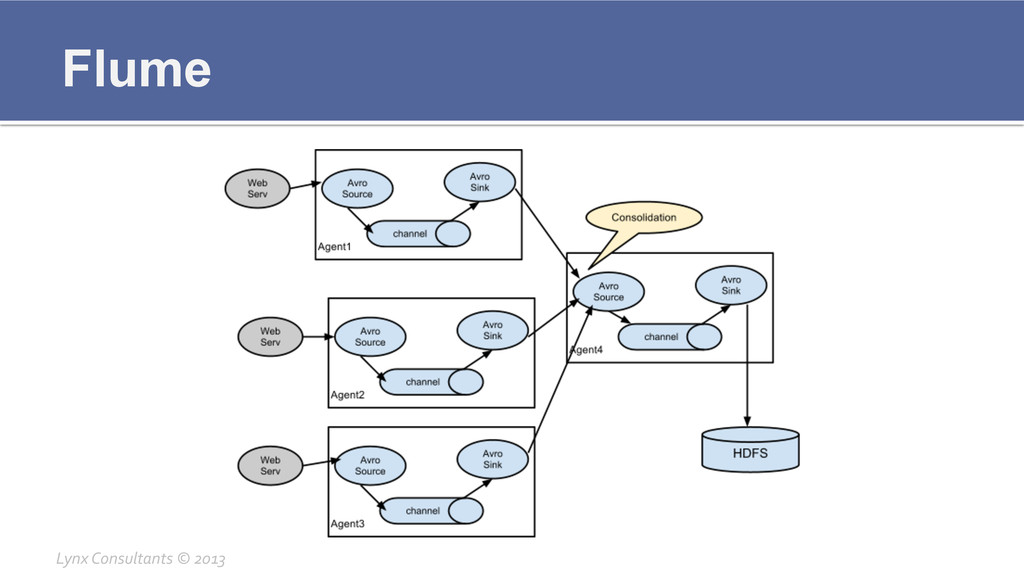
Flume ¡ Transports streams of data from point A to
point B ¡ Source § Where the data is read from ¡ Channel § How the data is buffered ¡ Sink § Where the data is written Lynx Consultants © 2013
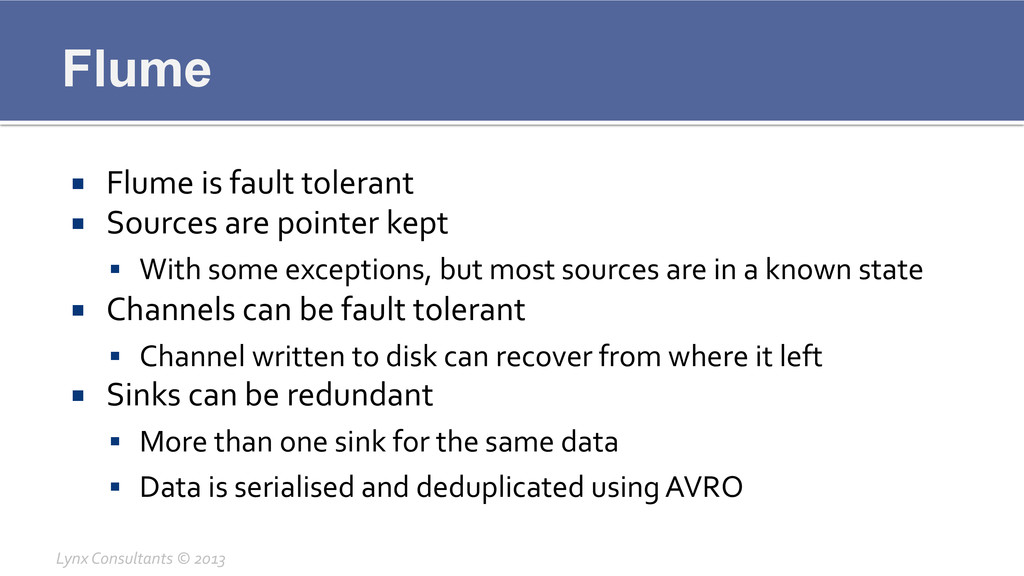
Flume ¡ Flume is fault tolerant ¡ Sources are
pointer kept § With some exceptions, but most sources are in a known state ¡ Channels can be fault tolerant § Channel written to disk can recover from where it left ¡ Sinks can be redundant § More than one sink for the same data § Data is serialised and deduplicated using AVRO Lynx Consultants © 2013
Flume Lynx Consultants © 2013
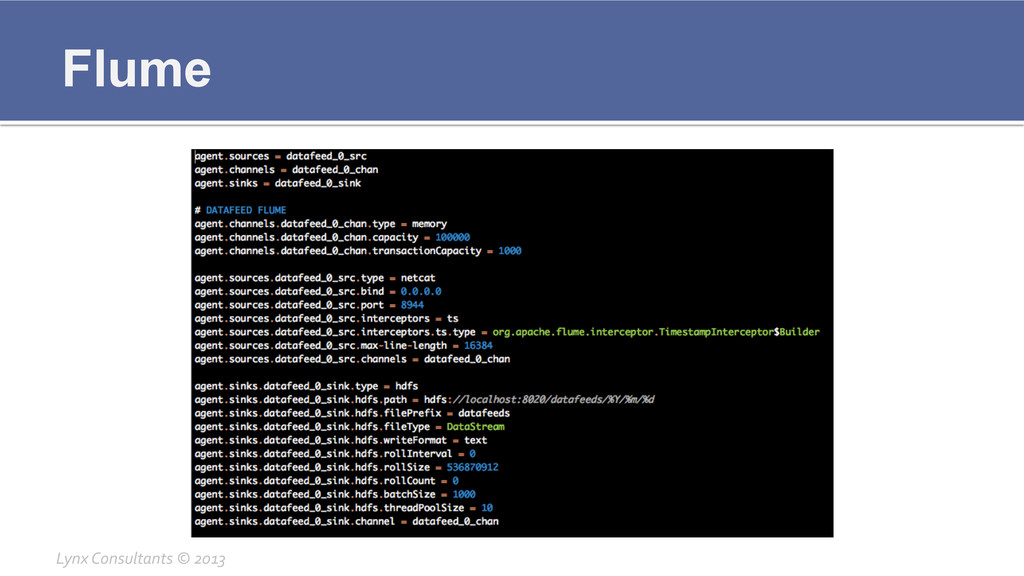
Flume ¡ Configuration files § /etc/flume-‐ng/conf/flume.conf ▪ Defines
the agent configuration with source, channel, sink Lynx Consultants © 2013
Flume Lynx Consultants © 2013
Hadoop Recommended Reads Lynx Consultants © 2013
Hadoop References ¡ Hadoop § http://hadoop.apache.org/docs/stable/cluster_setup.html § http://rc.cloudera.com/cdh/4/hadoop/hadoop-‐yarn/hadoop-‐yarn-‐site/
ClusterSetup.html § http://pig.apache.org/docs/r0.7.0/setup.html § http://wiki.apache.org/hadoop/NameNodeFailover ¡ Hbase § http://hbase.apache.org/book/book.html ¡ Flume § http://archive.cloudera.com/cdh4/cdh/4/flume-‐ng/ FlumeUserGuide.html Lynx Consultants © 2013
Questions? Lynx Consultants © 2013


 lynxman
 minorun365
 yoshiiryo1
 oikon48
 yuukiyo
 akosma
 myohei
 ryomaru0825
 snoozer05
 ny7760
 sraku2159
 kazzpapa3
 nealle
 raygrieselhuber
 maggiecrowley
 irinanazarova
 sstephenson
 skipperchong
 joshbly
 samlambert
 paigeccino
 honzajavorek
 eileencodes
 aleyda
 codingconduct