Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Improving Word Sense Disambiguation in Neural M...
Search
masaya82
July 25, 2018
160
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Improving Word Sense Disambiguation in Neural Machine Translation with Sense Embeddings
masaya82
July 25, 2018
More Decks by masaya82
See All by masaya82
文献紹介 : More is not always better: balancing sense distributions for all-words
masaya82
0
170
文献紹介:Enhancing Modern Supervised Word Sense Disambiguation Models
masaya82
0
180
文献紹介:The Word Sense Disambiguation Test Suite at WMT18
masaya82
0
120
文献紹介:Preposition Sense Disambiguation and Representation
masaya82
0
150
文献紹介:Word Sense Disambiguation Based on Word Similarity Calculation Using Word Vector Representation from a Knowledge-based Graph
masaya82
0
170
Distributional Lesk: Effective Knowledge-Based Word Sense Disambiguation
masaya82
0
140
Japanese all-words WSD system using the Kyoto Text Analysis ToolKit
masaya82
0
150
Learning_to_Identify_the_Best_Contexts_for_Knowledge-based_WSD
masaya82
0
170
Using Linked Disambiguated Distributional Networks for Word Sense Disambiguation
masaya82
0
120
Featured
See All Featured
Bash Introduction
62gerente
615
220k
Optimizing for Happiness
mojombo
378
71k
The untapped power of vector embeddings
frankvandijk
2
1.9k
The Cost Of JavaScript in 2023
addyosmani
55
10k
Ten Tips & Tricks for a 🌱 transition
stuffmc
1
230
How to Get Subject Matter Experts Bought In and Actively Contributing to SEO & PR Initiatives.
livdayseo
0
200
Odyssey Design
rkendrick25
PRO
2
810
Applied NLP in the Age of Generative AI
inesmontani
PRO
4
2.5k
Responsive Adventures: Dirty Tricks From The Dark Corners of Front-End
smashingmag
254
22k
実際に使うSQLの書き方 徹底解説 / pgcon21j-tutorial
soudai
PRO
203
76k
brightonSEO & MeasureFest 2025 - Christian Goodrich - Winning strategies for Black Friday CRO & PPC
cargoodrich
3
850
Why Our Code Smells
bkeepers
PRO
340
58k
Transcript
Improving Word Sense Disambiguation in Neural Machine Translation with Sense
Embeddings Annette Rios and Laura Mascarell and Rico Sennrich 2018 7/25 文献紹介 長岡技術科学大学 自然言語処理研究室 福嶋 真也 Proceedings of the Conference on Machine Translation (WMT), Volume 1: Research Papers, pages 11–19 Copenhagen, Denmark, September 711, 2017.
2 Abstract • NMTにおけるWSDの能力は定量化されていない。 • NMTにおけるWSDの能力を評価するための新しいcloss – lingual WSD task
をデザインした。 • German-English, German-Frenchでそれぞれテストデー タを作成し、評価を行った。
3 introduction • 機械翻訳において、正確な翻訳文を生成するためには与えら れた文脈から正確な意味を決定しなければならない。 • エラーは間違った翻訳や理解不能な翻訳を生み出すが、どの タイプのエラーが難しいかは定量化されていない。 →BLEUのような自動評価では詳細な解析が出来ないため •
機械翻訳のための語彙選択を評価する手法はいくつか提案されて いる。 しかし、同義語や言い換えなども罰されてしまう。
4 introduction • 提案するタスクではシステムに決められた翻訳セットから1つ の翻訳を選択するように制限。 • 大規模かつ再現可能な方法でWSDの評価を行いたい。 →NMTでは、文のペアに対して条件付き確率P(T|S)が割り 当てられることを利用する。 ※S:元の文、T:翻訳文
• 曖昧性によるエラーを含む文とリファレンスでNMTモデルの スコアを計算し、比較することでどのくらいうまく語義を区別で きているか評価する。
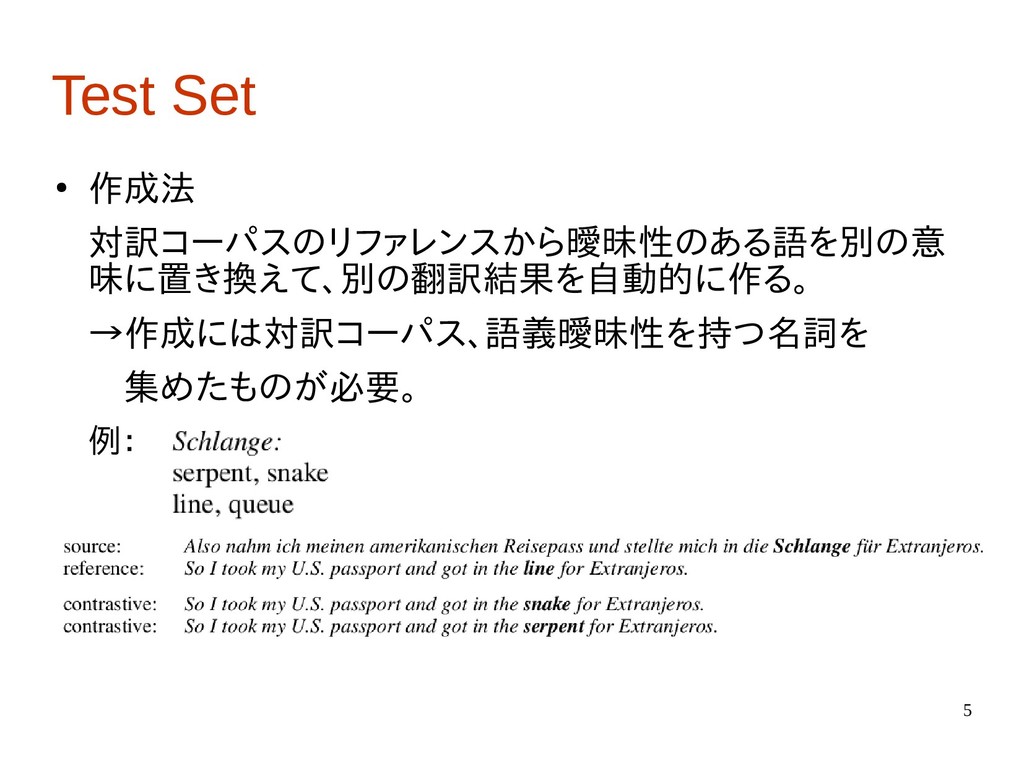
5 Test Set • 作成法 対訳コーパスのリファレンスから曖昧性のある語を別の意 味に置き換えて、別の翻訳結果を自動的に作る。 →作成には対訳コーパス、語義曖昧性を持つ名詞を 集めたものが必要。 例:
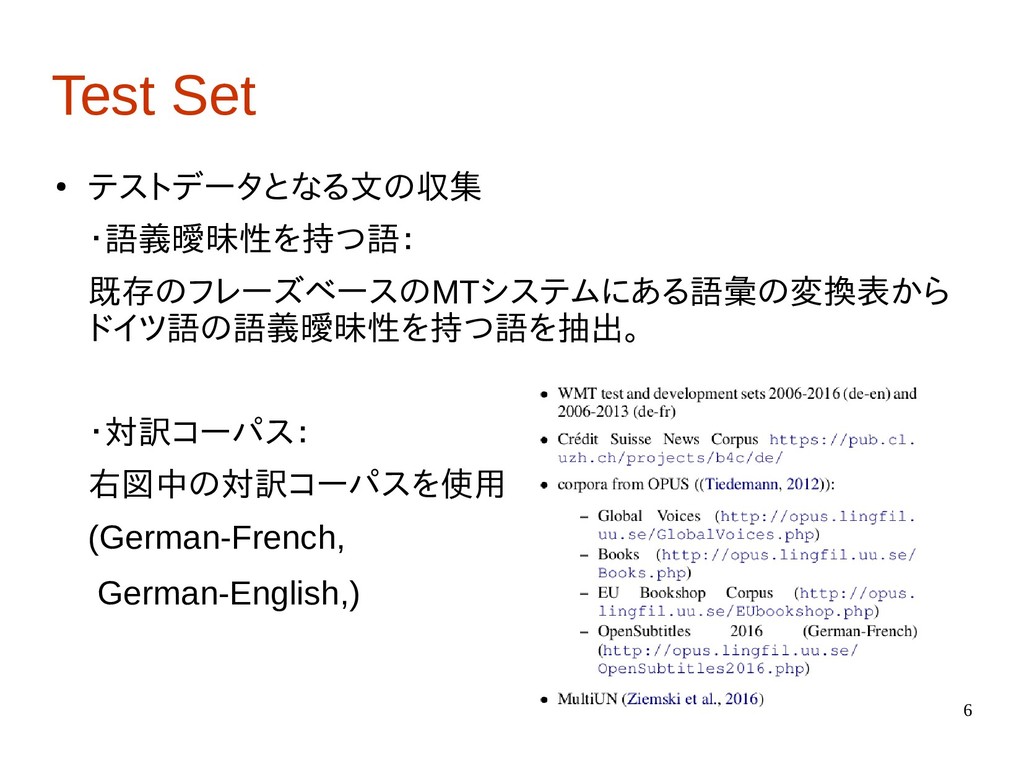
6 Test Set • テストデータとなる文の収集 ・語義曖昧性を持つ語: 既存のフレーズベースのMTシステムにある語彙の変換表から ドイツ語の語義曖昧性を持つ語を抽出。 ・対訳コーパス: 右図中の対訳コーパスを使用
(German-French, German-English,)
7 Approach • ベースラインと2つのWSDの手法を用いる。 ・ベースライン:最も頻出する意味を用いる。 ・Sense Embeddings: SenseGram(Pelevina et al.,
2016)を用いてSense Embeddingsを計算、学習して共起表現から語義を決定する手 法。 ・Lexical chain: SenseGramを用いて意味的に似ている語を集め、それぞれの embeddingを連結させたものを語のベクトル表現として用いる 手法。
8 Evaluation • 2つのNMTシステムを使用。 ・学習:210万文(EuroparlとNews Commentaryより) ・byte pair encoding(Sennrich et
al.,2016b)とNematus (Sennrich et al., 2017)を使用 ・Adam (Kingma and Ba, 2015)を使い、パラメータを更新 ・minibatch size : 80
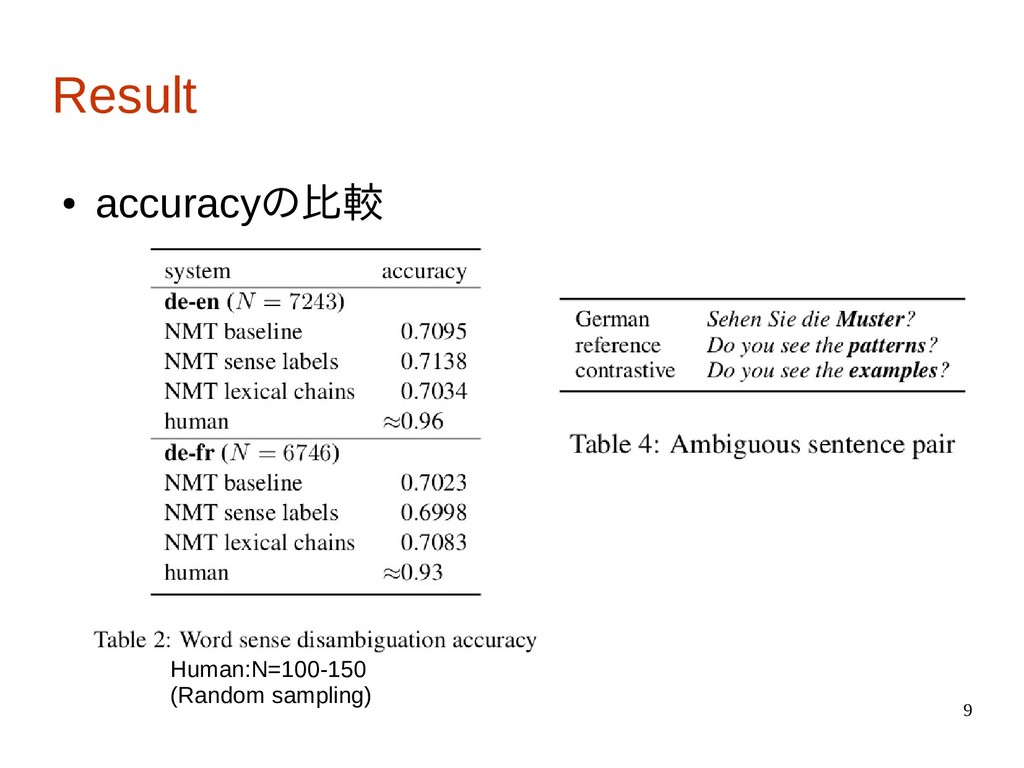
9 Result • accuracyの比較 Human:N=100-150 (Random sampling)
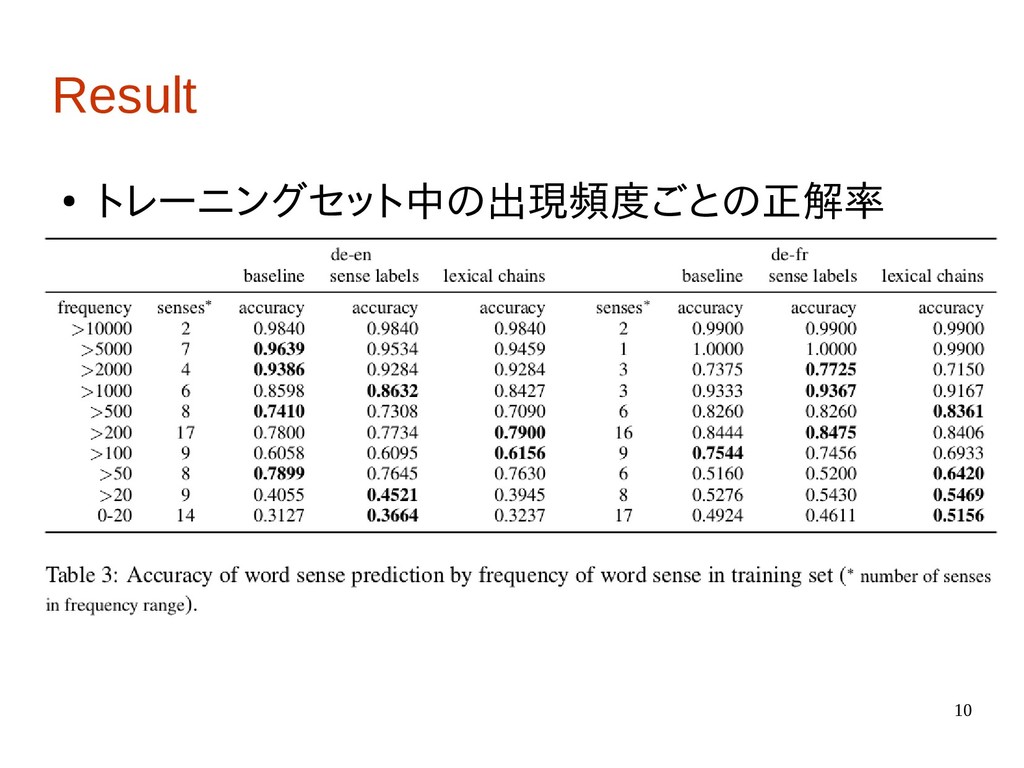
10 Result • トレーニングセット中の出現頻度ごとの正解率
11 Conclusion • NMTモデルを評価するための新たな語彙選択タスクを紹介 し、German-English、German-Frenchのテストセットを提示した。 • このタスクではNMTモデルにおける語彙の曖昧性解消についての能 力を自動的かつ定量的に解析できる。 • 実験では、ベースラインは学習データに頻出しない語義に弱いが、提
案した2つの手法ではそれに対して改善が見られた。 • 人間とNMTモデルの比較で、このタスクを解くためには文書の文脈 を広げる必要がある。


 masaya82
 62gerente
 mojombo
 frankvandijk
 addyosmani
 stuffmc
 livdayseo
 rkendrick25
 inesmontani
 smashingmag
 soudai
 cargoodrich
 bkeepers