Share
Embed
Writing Software for Modern Computers
Poul-Henning Kamp describes his experience with Varnish Software
Multicore World 2013
February 19, 2013
Transcript
56 slides
-
$ who am i 31 of 47 years in computing
Major FreeBSD kernel hacker Author of Varnish + Tons of other stuff Writes column for ACM Queue The man behind ”bikeshed.org” -
Outline: * What is Varnish anyway ? * The road
to Multicore * Algorithm vs. Architecture * Conclusion, such as it may be. * (That other dimension) -
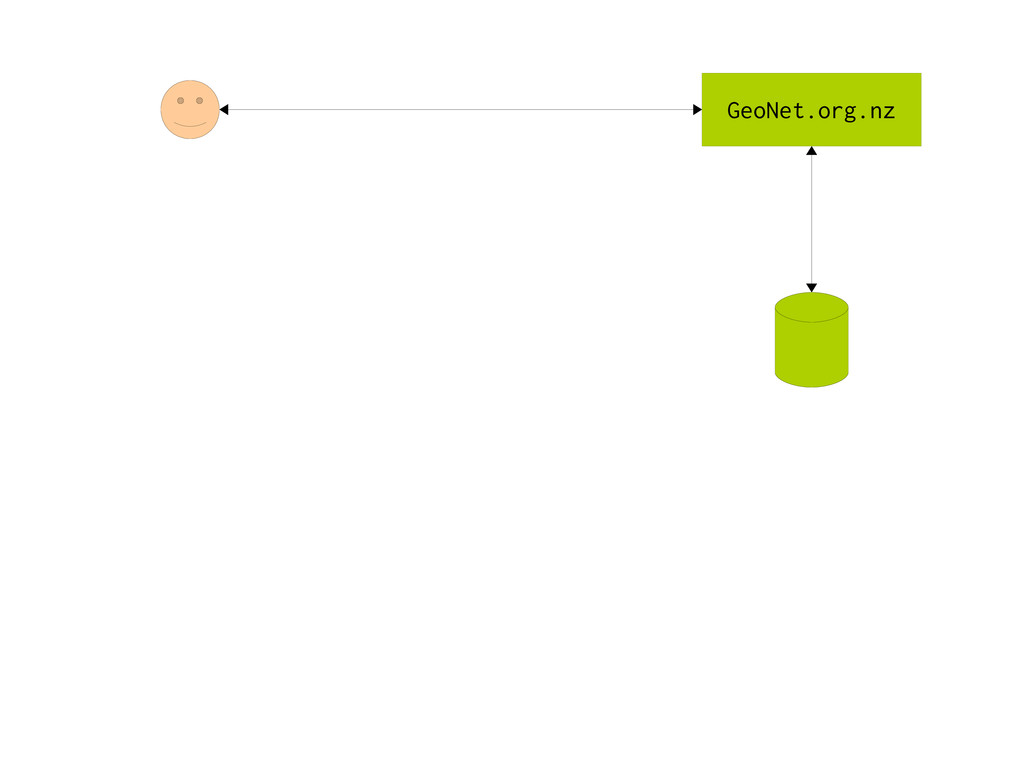
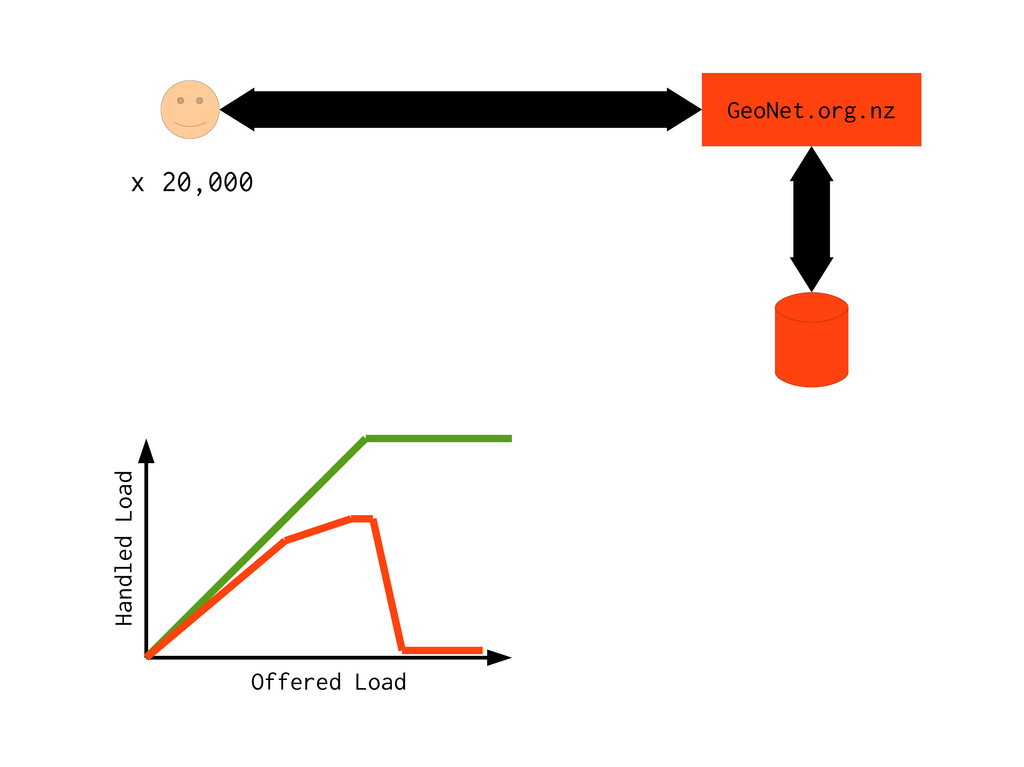
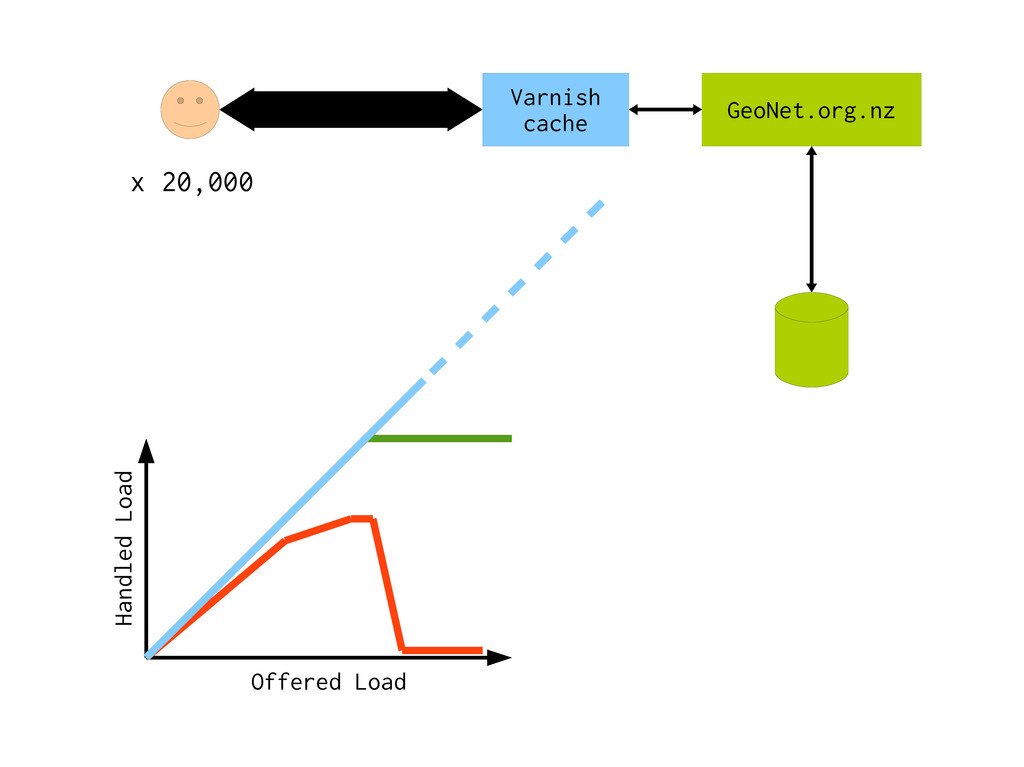
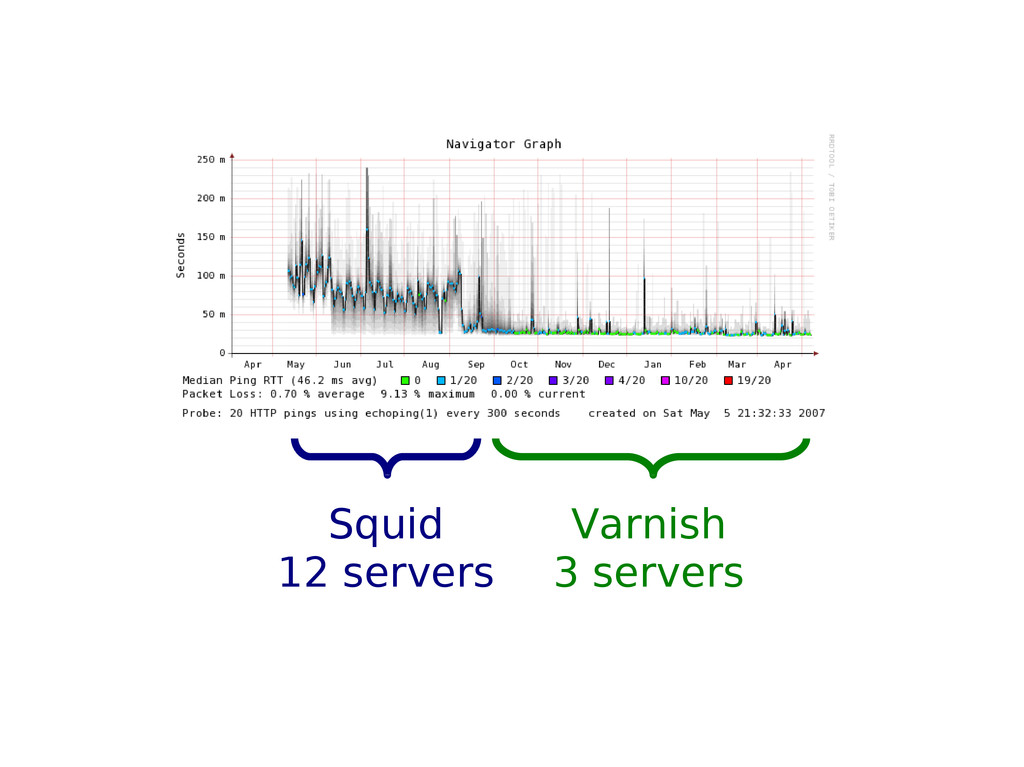
So what is Varnish anyway ? A HTTP/WEB frontend/afterburner *
Fast (>1 Mreq/s) * Flexible * Modular * Deployable See: Varnish-cache.org -
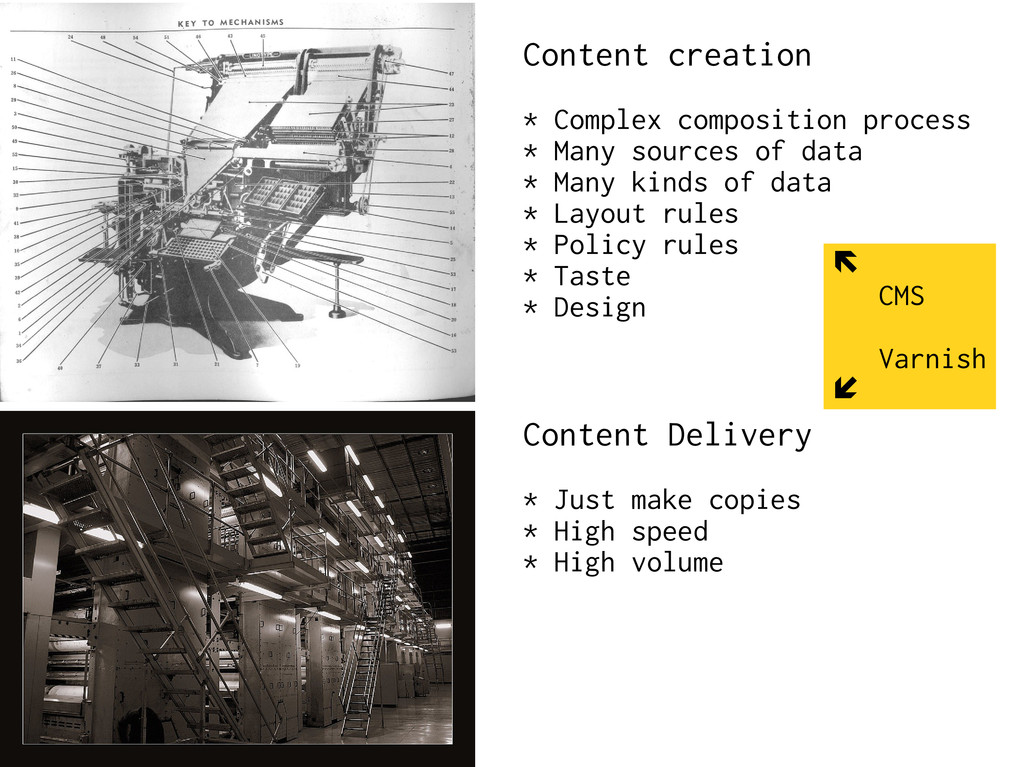
Content creation * Complex composition process * Many sources of
data * Many kinds of data * Layout rules * Policy rules * Taste * Design Content Delivery * Just make copies * High speed * High volume CMS Varnish -
Varnish-Cache coordinates: http://varnish.org Runs on any contemporary UNIX Ie: FreeBSD,
Linux, OS/X, Solaris We don't do Windows Free Open Source Software (FOSS) ← What you get What you pay → -
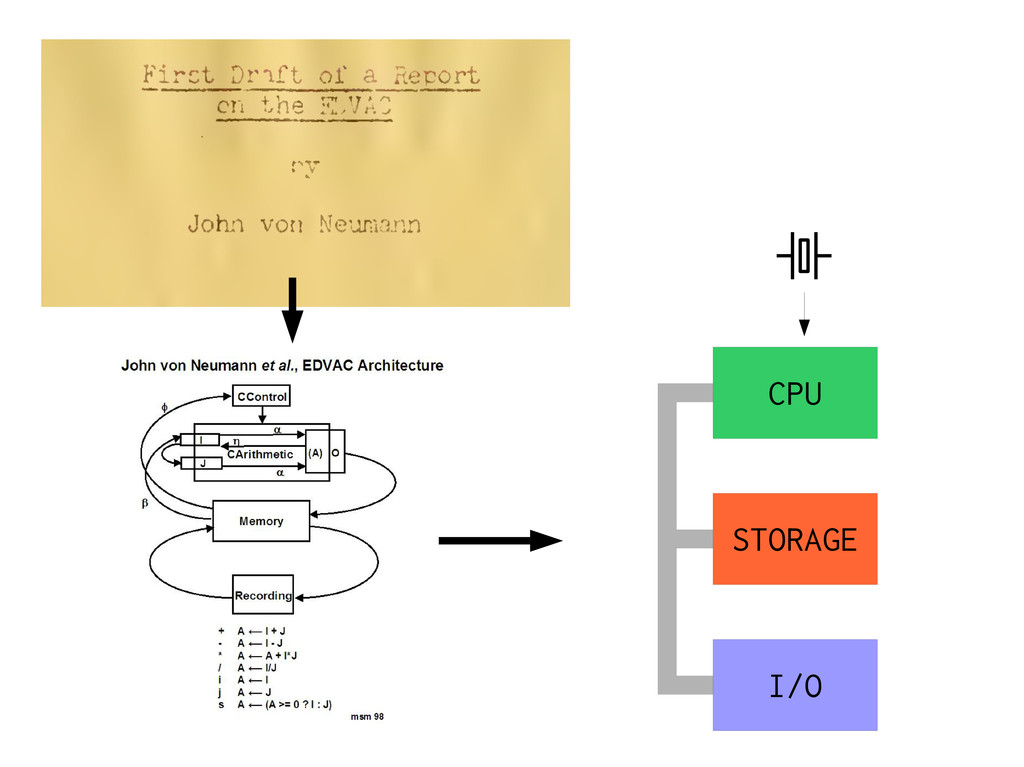
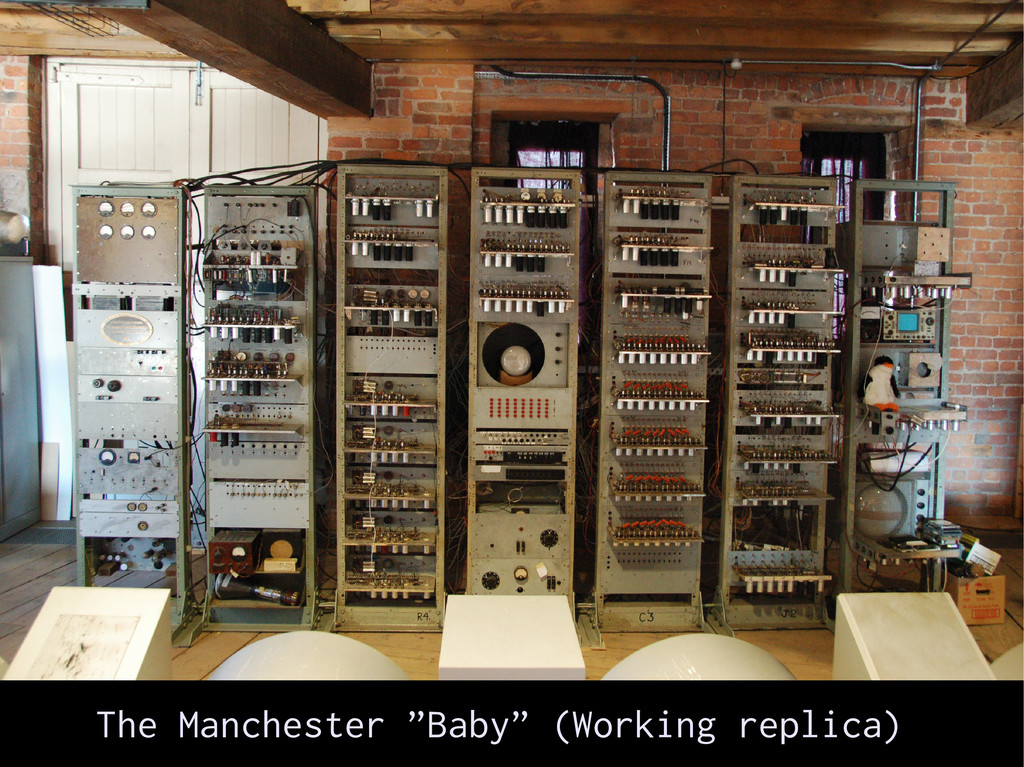
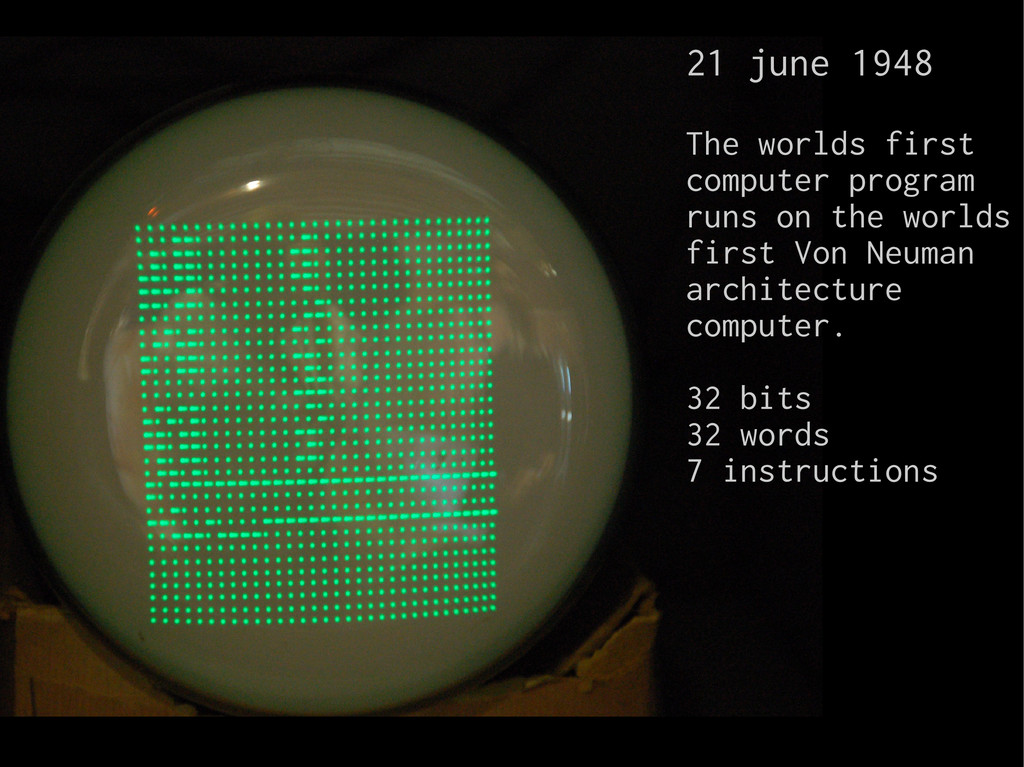
21 june 1948 The worlds first computer program runs on
the worlds first Von Neuman architecture computer. 32 bits 32 words 7 instructions -
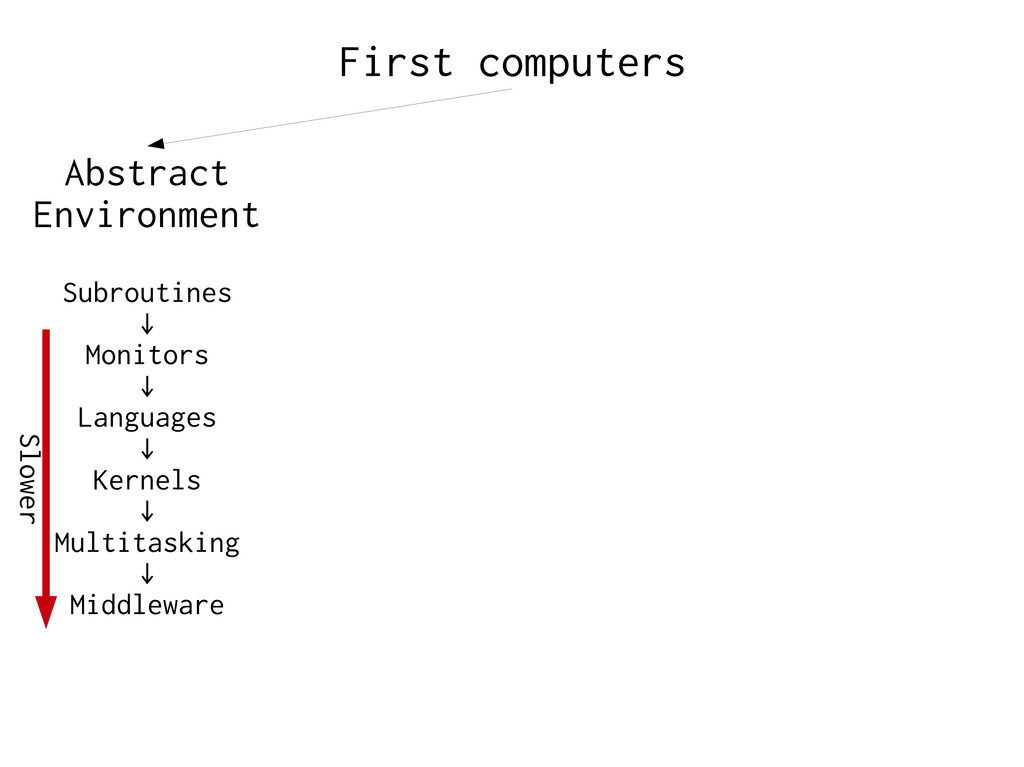
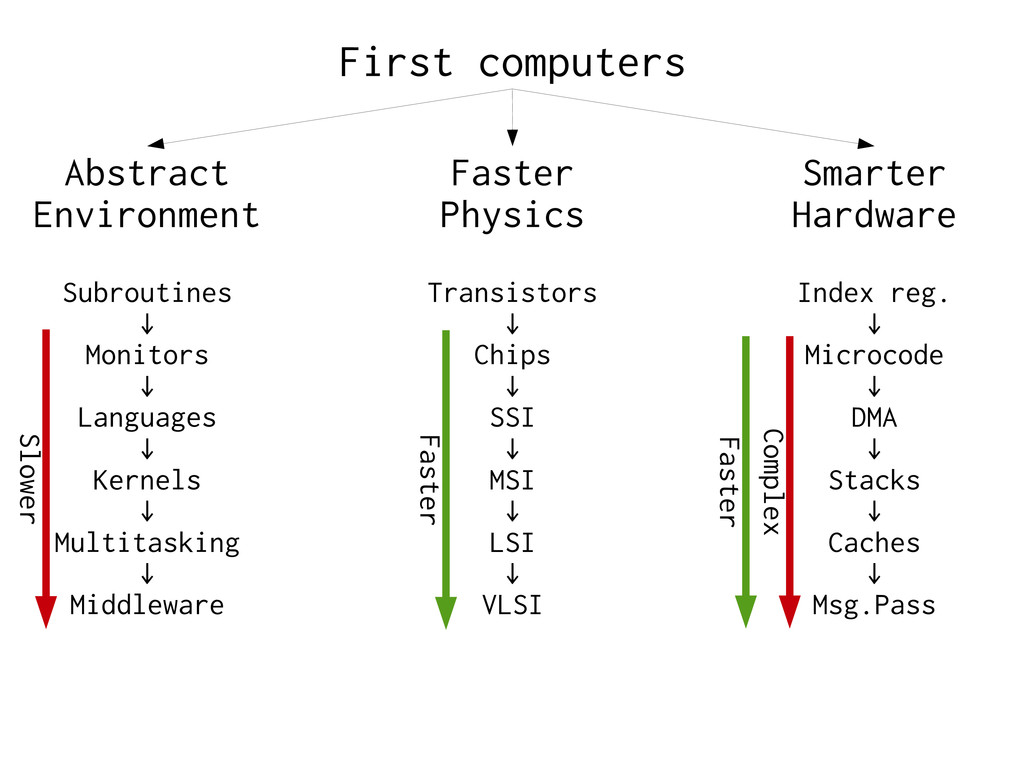
First computers Abstract Environment Subroutines ↓ Monitors ↓ Languages ↓
Kernels ↓ Multitasking ↓ Middleware Slower -
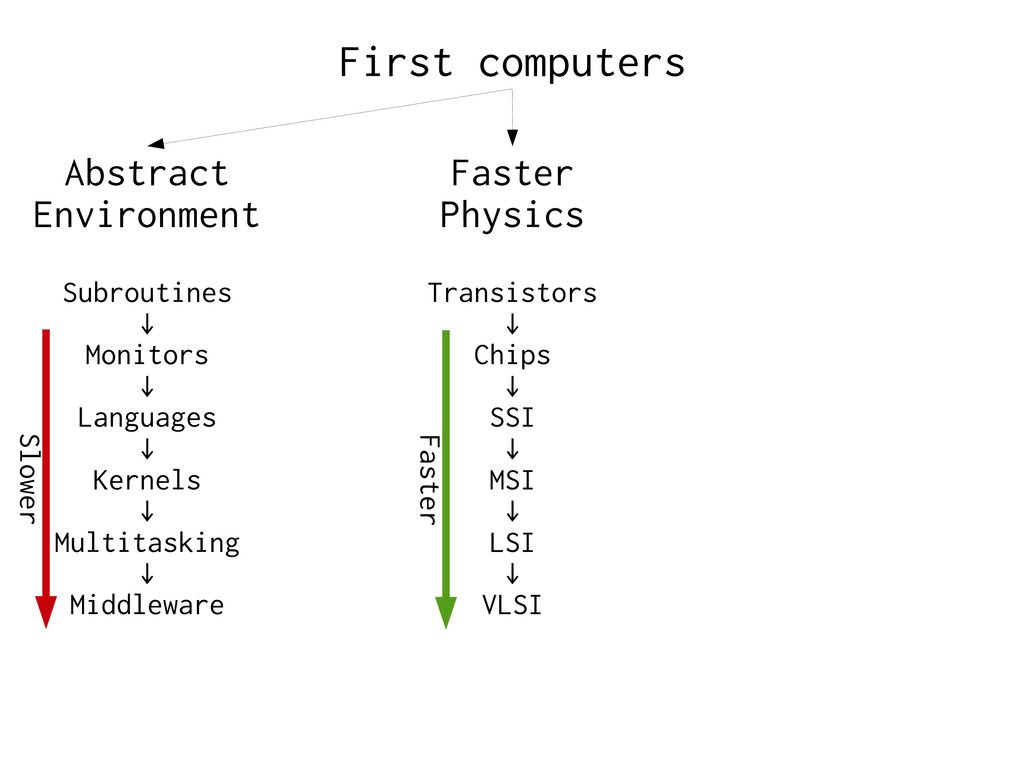
First computers Faster Physics Transistors ↓ Chips ↓ SSI ↓
MSI ↓ LSI ↓ VLSI Abstract Environment Subroutines ↓ Monitors ↓ Languages ↓ Kernels ↓ Multitasking ↓ Middleware Slower Faster -
First computers Faster Physics Transistors ↓ Chips ↓ SSI ↓
MSI ↓ LSI ↓ VLSI Smarter Hardware Index reg. ↓ Microcode ↓ DMA ↓ Stacks ↓ Caches ↓ Msg.Pass Abstract Environment Subroutines ↓ Monitors ↓ Languages ↓ Kernels ↓ Multitasking ↓ Middleware Faster Complex Slower Faster -
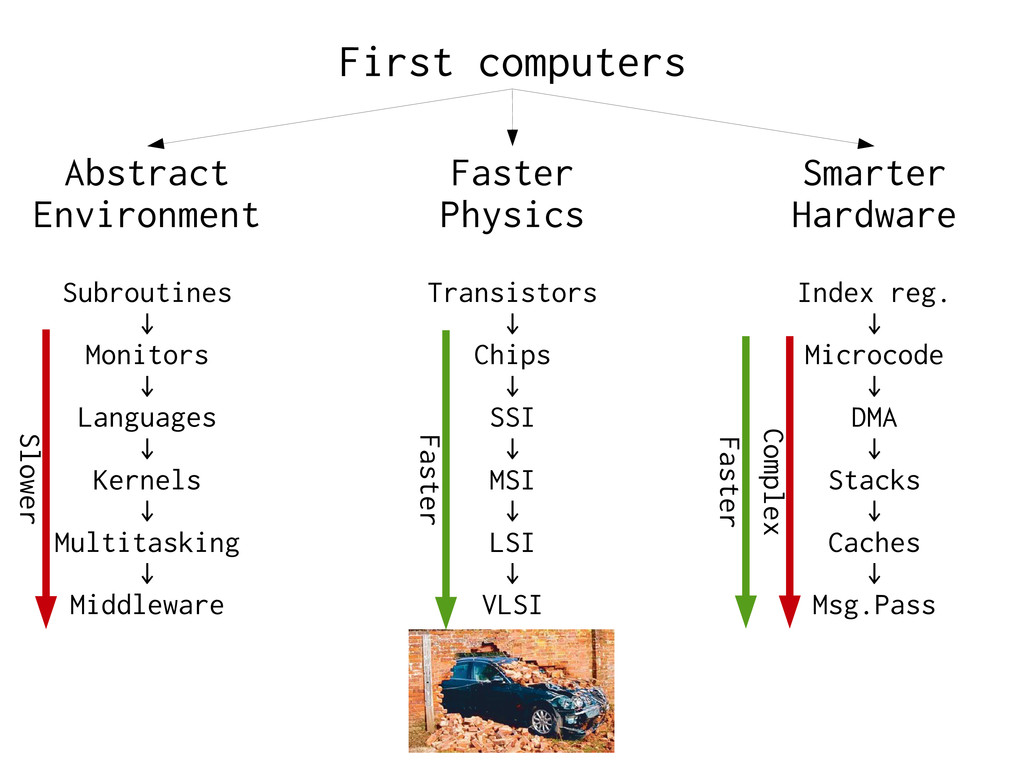
First computers Faster Physics Transistors ↓ Chips ↓ SSI ↓
MSI ↓ LSI ↓ VLSI Smarter Hardware Index reg. ↓ Microcode ↓ DMA ↓ Stacks ↓ Caches ↓ Msg.Pass Abstract Environment Subroutines ↓ Monitors ↓ Languages ↓ Kernels ↓ Multitasking ↓ Middleware Faster Complex Slower Faster -
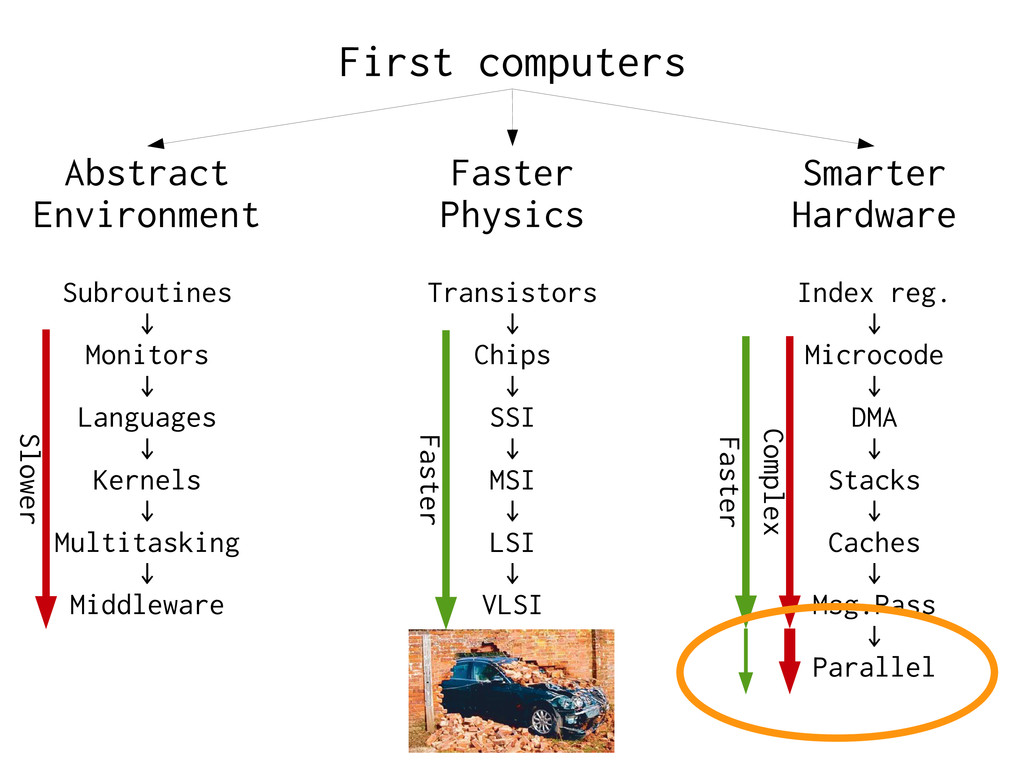
First computers Faster Physics Transistors ↓ Chips ↓ SSI ↓
MSI ↓ LSI ↓ VLSI Smarter Hardware Index reg. ↓ Microcode ↓ DMA ↓ Stacks ↓ Caches ↓ Msg.Pass ↓ Parallel Abstract Environment Subroutines ↓ Monitors ↓ Languages ↓ Kernels ↓ Multitasking ↓ Middleware Faster Complex Slower Faster -
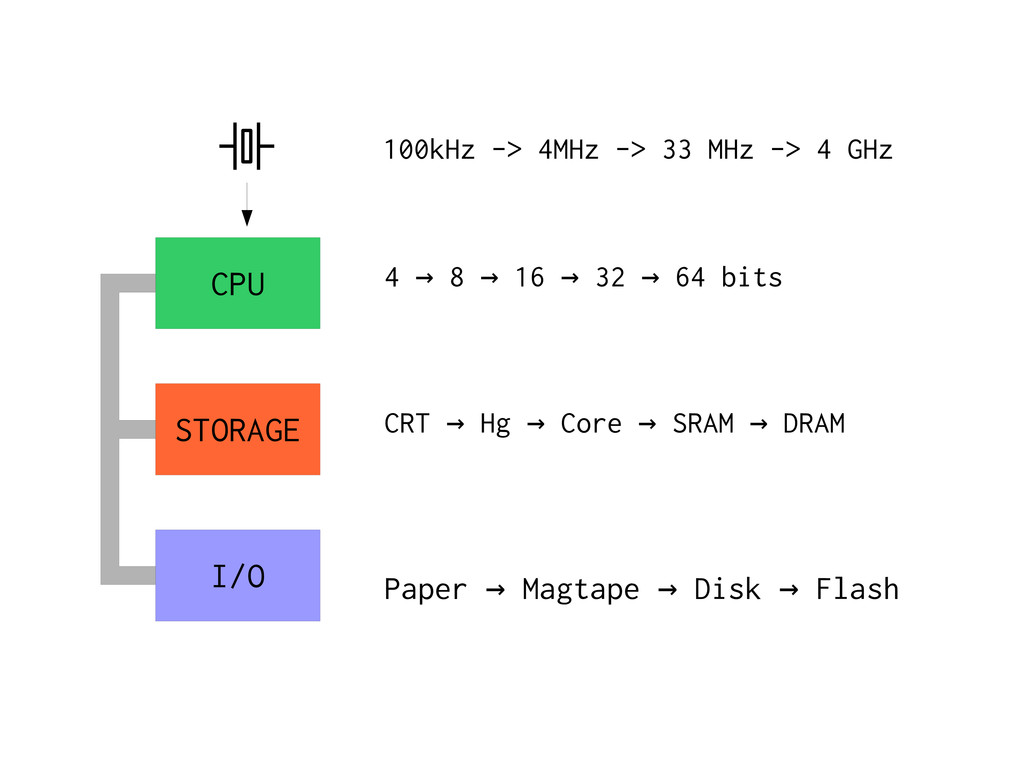
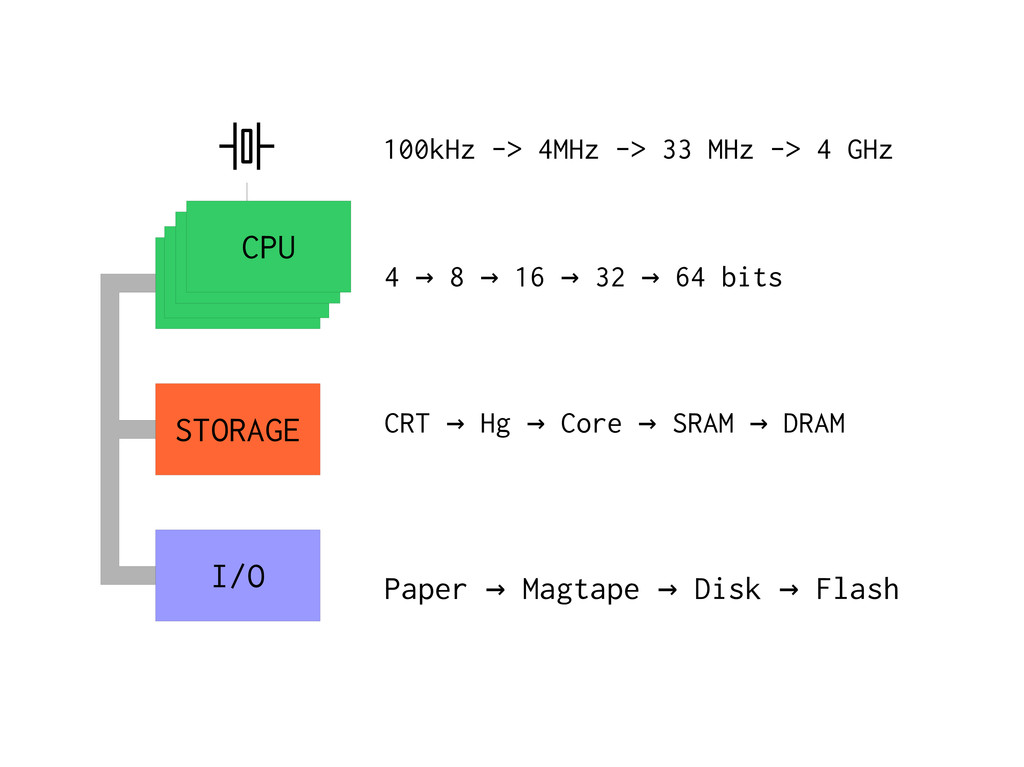
CPU STORAGE I/O 4 8 16 32 64 bits →
→ → → CRT Hg Core SRAM DRAM → → → → Paper Magtape Disk Flash → → → 100kHz -> 4MHz -> 33 MHz -> 4 GHz -
CPU STORAGE I/O 4 8 16 32 64 bits →
→ → → CRT Hg Core SRAM DRAM → → → → Paper Magtape Disk Flash → → → 100kHz -> 4MHz -> 33 MHz -> 4 GHz CPU CPU CPU -
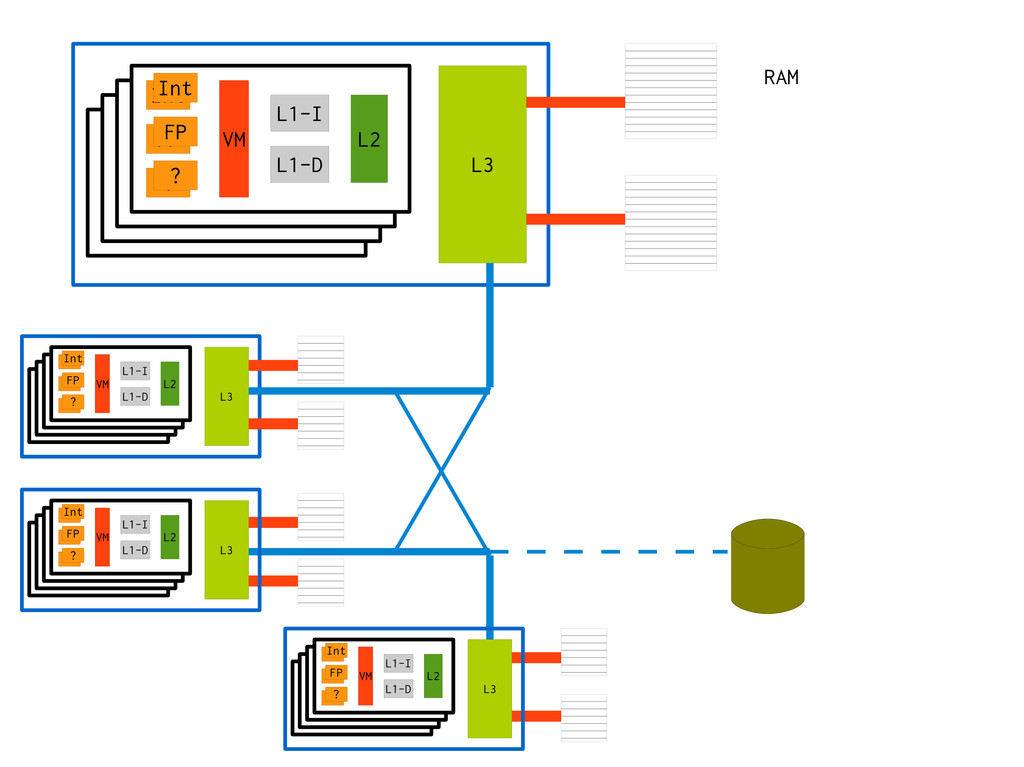
L3 L2 Int FP ? L1-I L1-D Int FP ?
VM L3 L2 L1-I L1-D Int FP ? VM RAM L3 L2 L1-I L1-D Int FP ? VM L3 L2 L1-I L1-D Int FP ? VM -
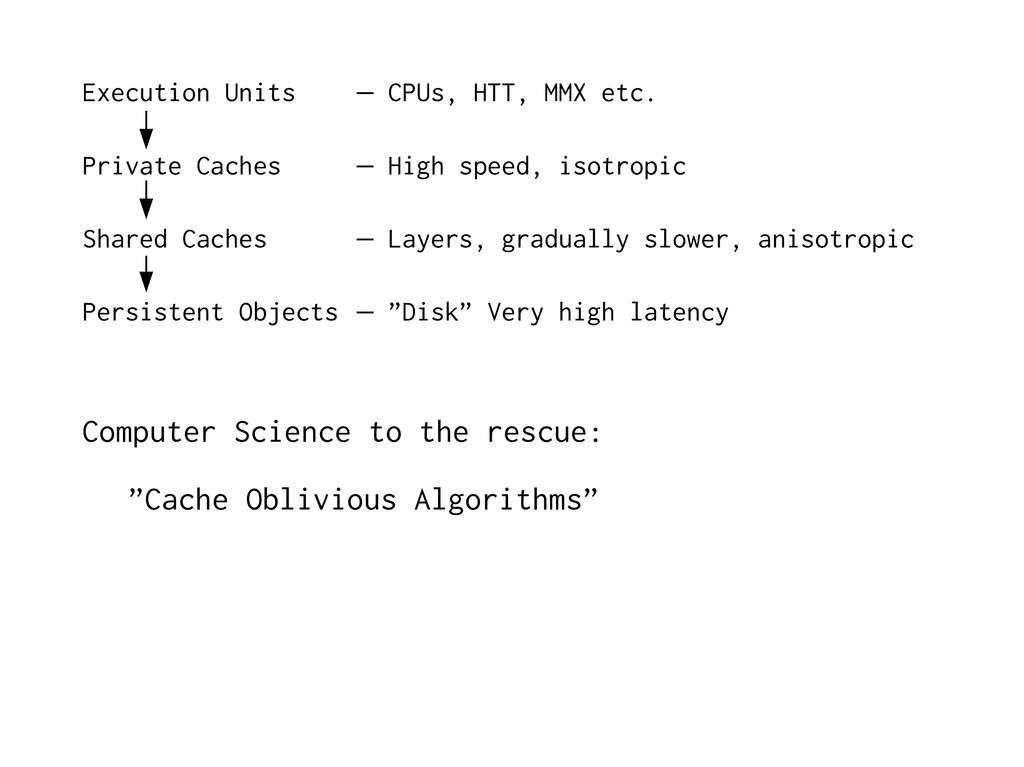
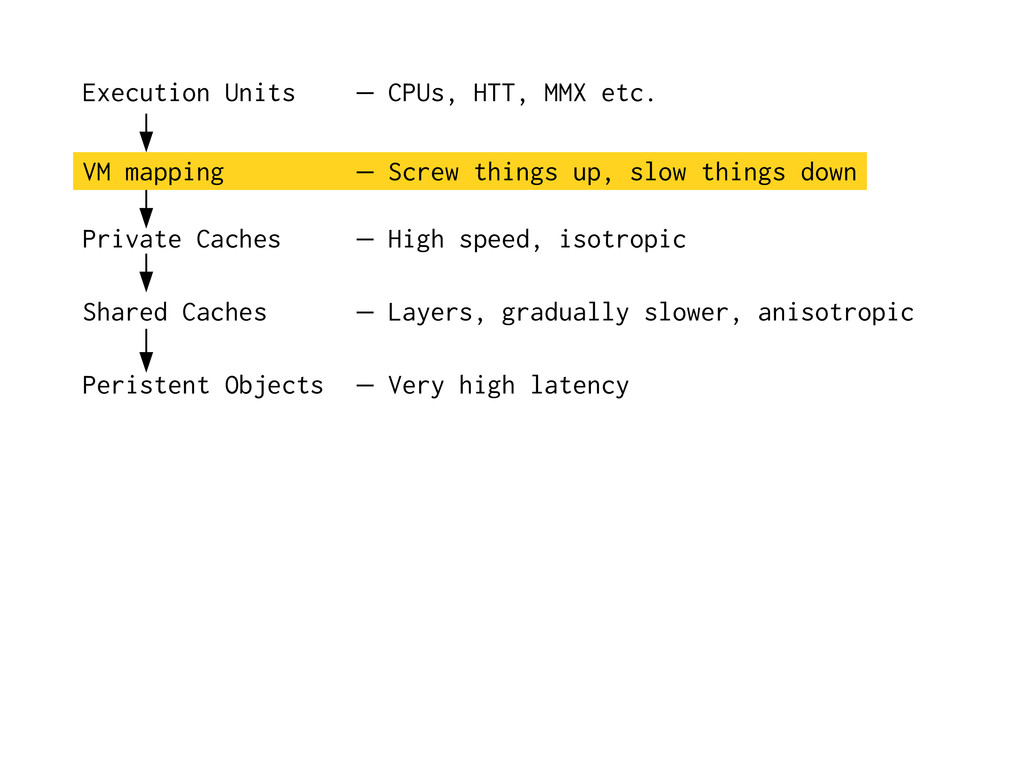
Execution Units CPUs, HTT, MMX etc. – Private Caches High
speed, isotropic – Shared Caches Layers, gradually slower, anisotropic – Persistent Objects ”Disk” Very high latency – Computer Science to the rescue: ”Cache Oblivious Algorithms” -
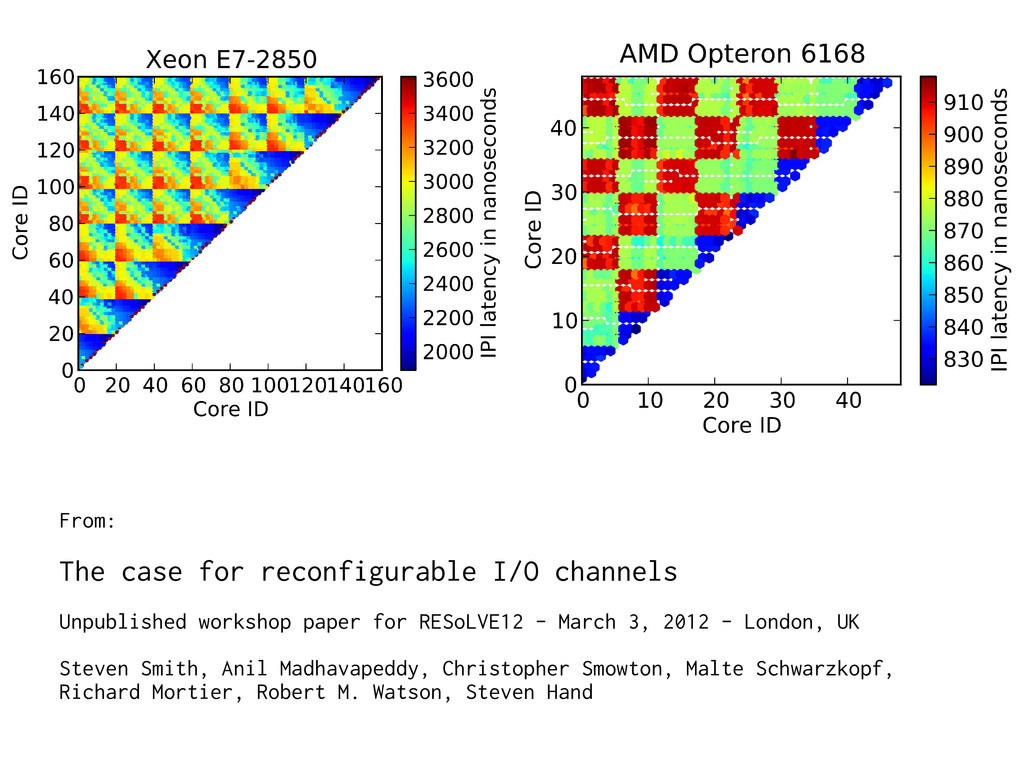
From: The case for reconfigurable I/O channels Unpublished workshop paper
for RESoLVE12 - March 3, 2012 - London, UK Steven Smith, Anil Madhavapeddy, Christopher Smowton, Malte Schwarzkopf, Richard Mortier, Robert M. Watson, Steven Hand -
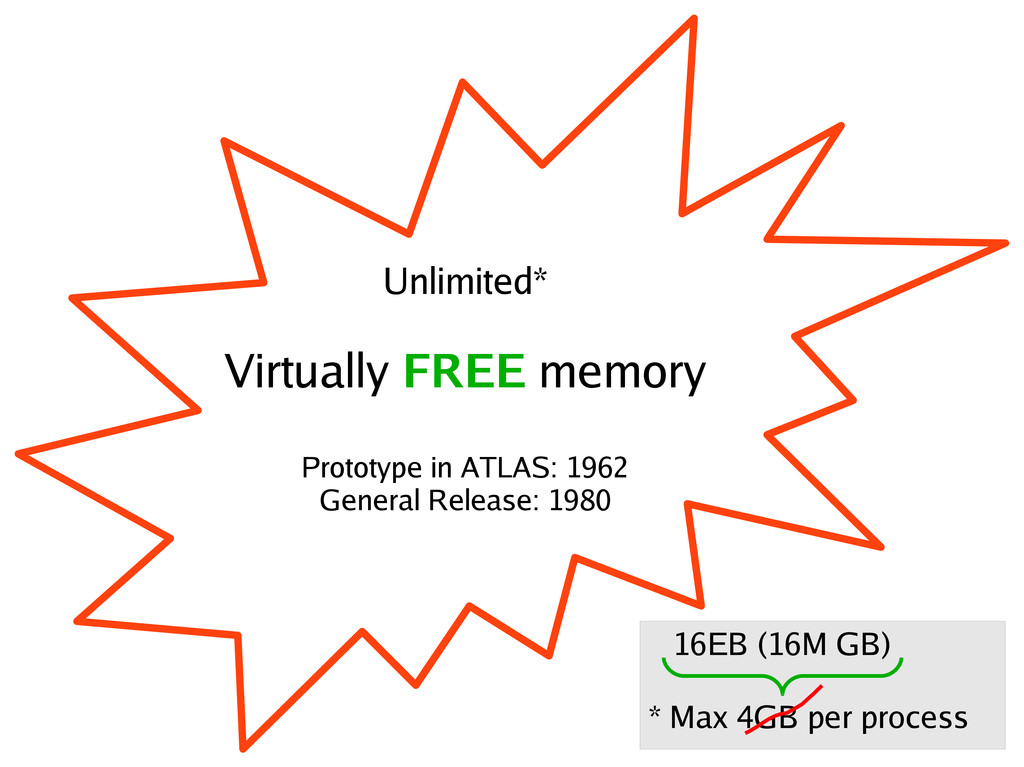
Unlimited* Virtually FREE memory Prototype in ATLAS: 1962 General Release:
1980 * Max 4GB per process 16EB (16M GB) -
Execution Units CPUs, HTT, MMX etc. – Private Caches High
speed, isotropic – Shared Caches Layers, gradually slower, anisotropic – Peristent Objects Very high latency – VM mapping Screw things up, slow things down – -
I know what you're thinking, proc: 'Did he send SIGTERM
or SIGKILL ?' Well, to tell you the truth, in all this excitement I kind of lost track myself... But being as this is SIGKILL, the most powerful signal in UNIX, and would blow your address space clean off, you've got to ask yourself one question: 'Do I feel lucky?' Well, do ya, proc? Go Ahead, Fight my Kernel... -
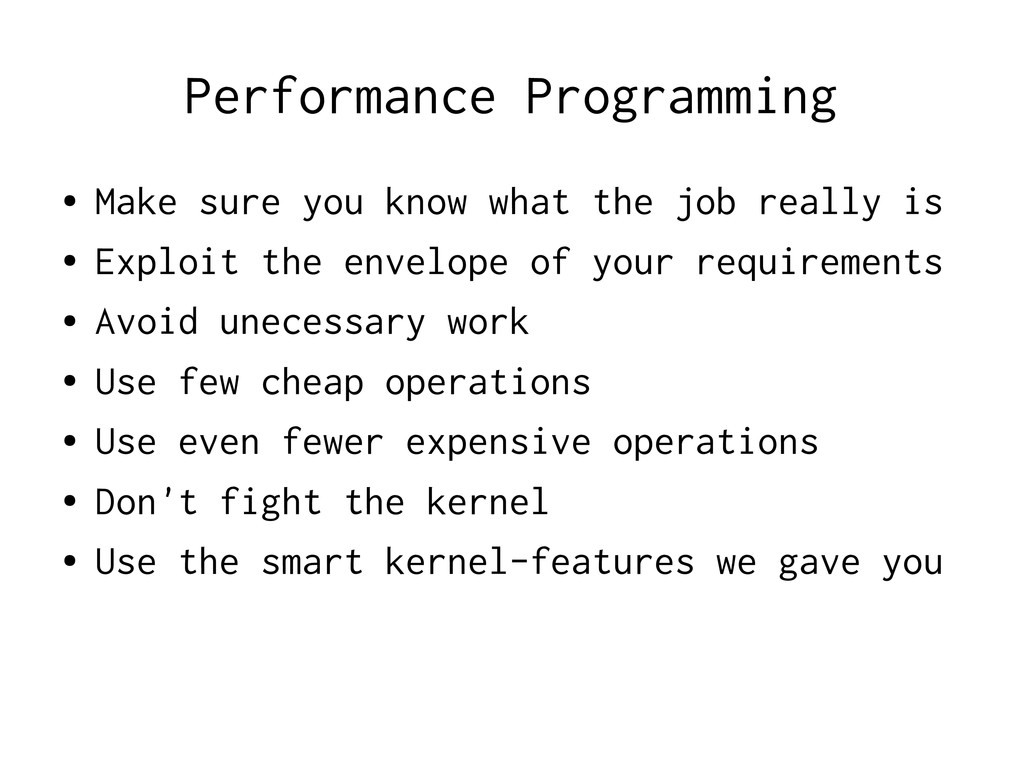
Performance Programming • Make sure you know what the job
really is • Exploit the envelope of your requirements • Avoid unecessary work • Use few cheap operations • Use even fewer expensive operations • Don't fight the kernel • Use the smart kernel-features we gave you -
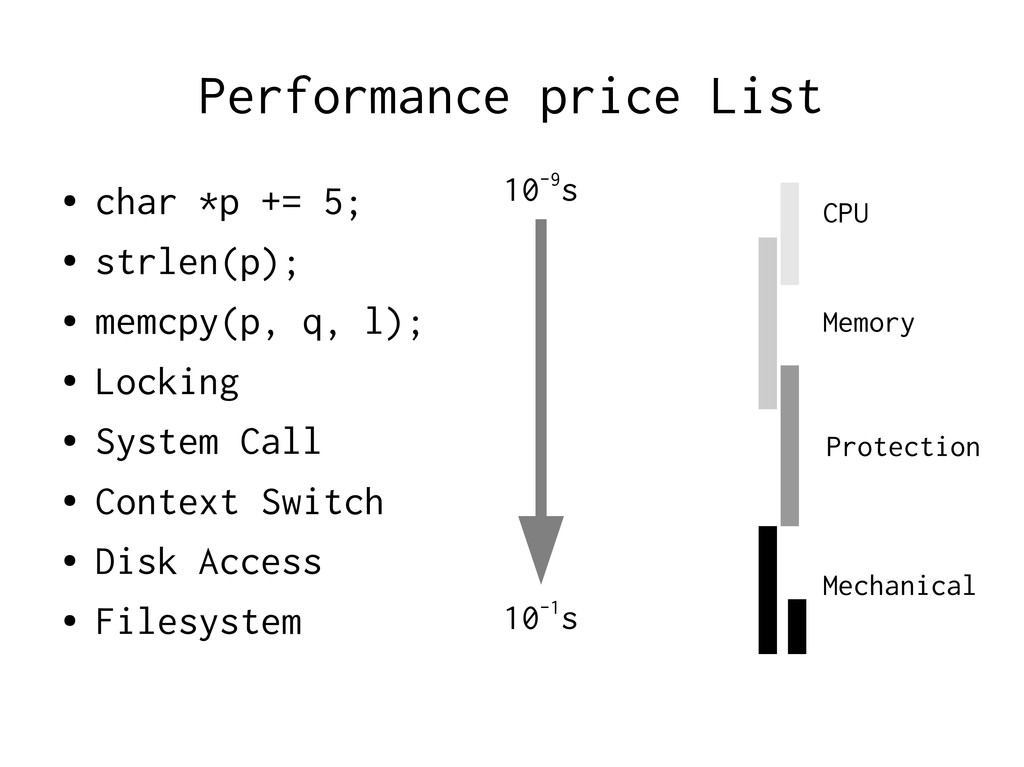
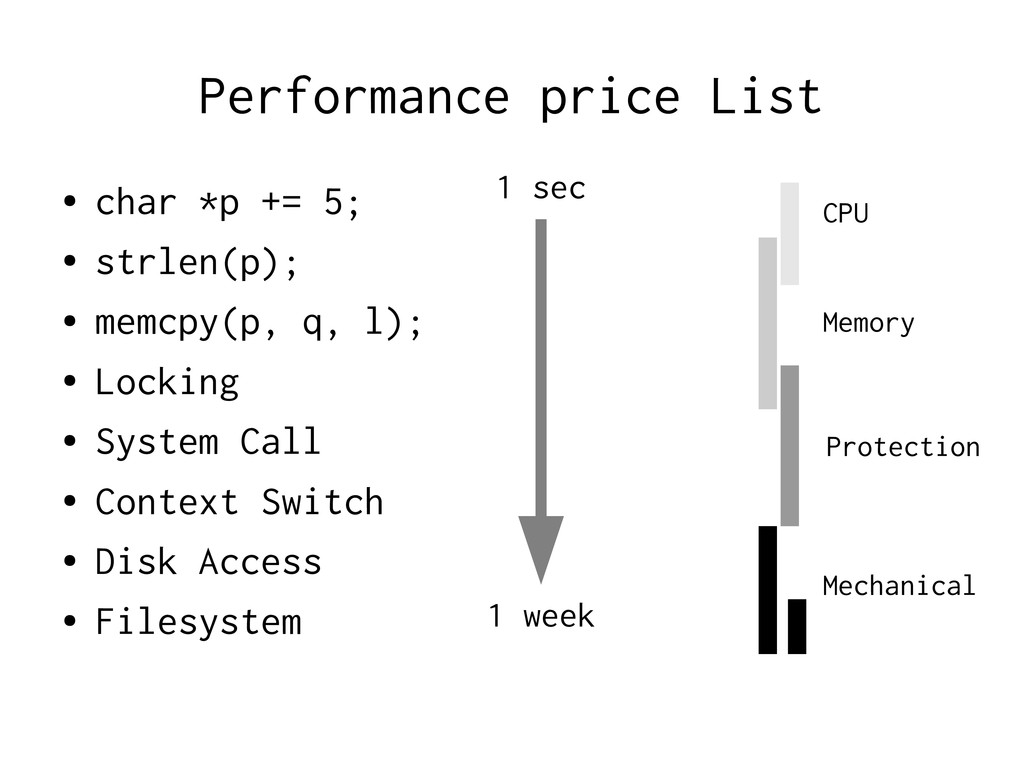
Performance price List • char *p += 5; • strlen(p);
• memcpy(p, q, l); • Locking • System Call • Context Switch • Disk Access • Filesystem 10-1s 10-9s CPU Memory Protection Mechanical -
Performance price List • char *p += 5; • strlen(p);
• memcpy(p, q, l); • Locking • System Call • Context Switch • Disk Access • Filesystem 1 week 1 sec CPU Memory Protection Mechanical -
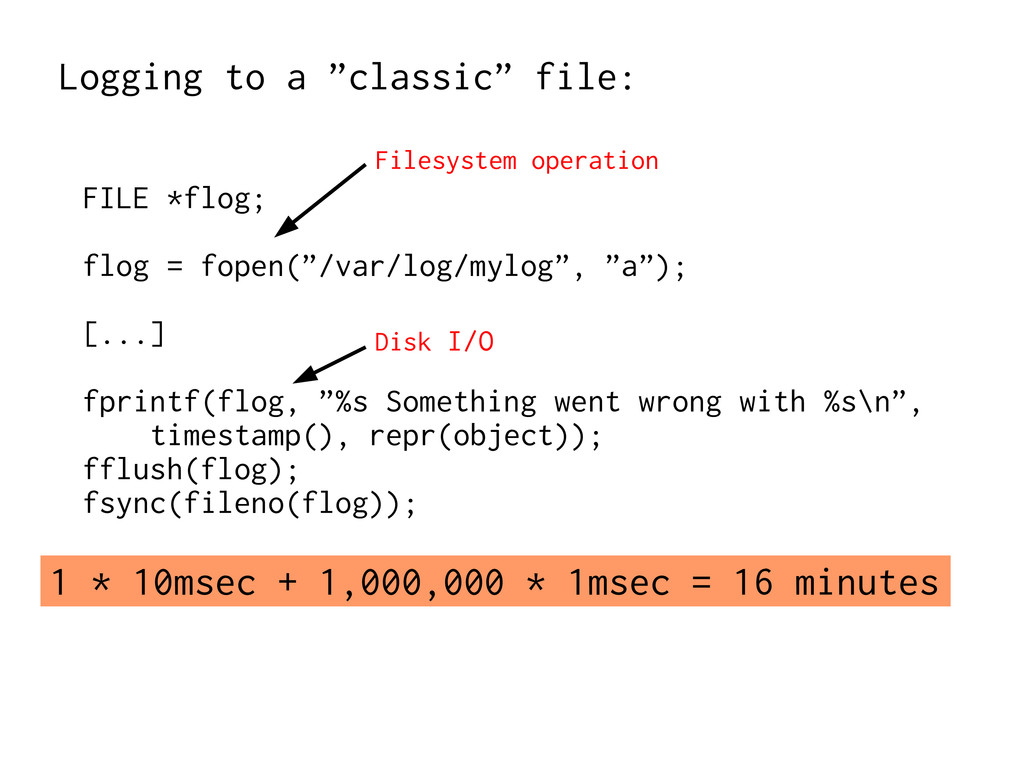
Logging to a ”classic” file: FILE *flog; flog = fopen(”/var/log/mylog”,
”a”); [...] fprintf(flog, ”%s Something went wrong with %s\n”, timestamp(), repr(object)); fflush(flog); fsync(fileno(flog)); Filesystem operation Disk I/O 1 * 10msec + 1,000,000 * 1msec = 16 minutes -
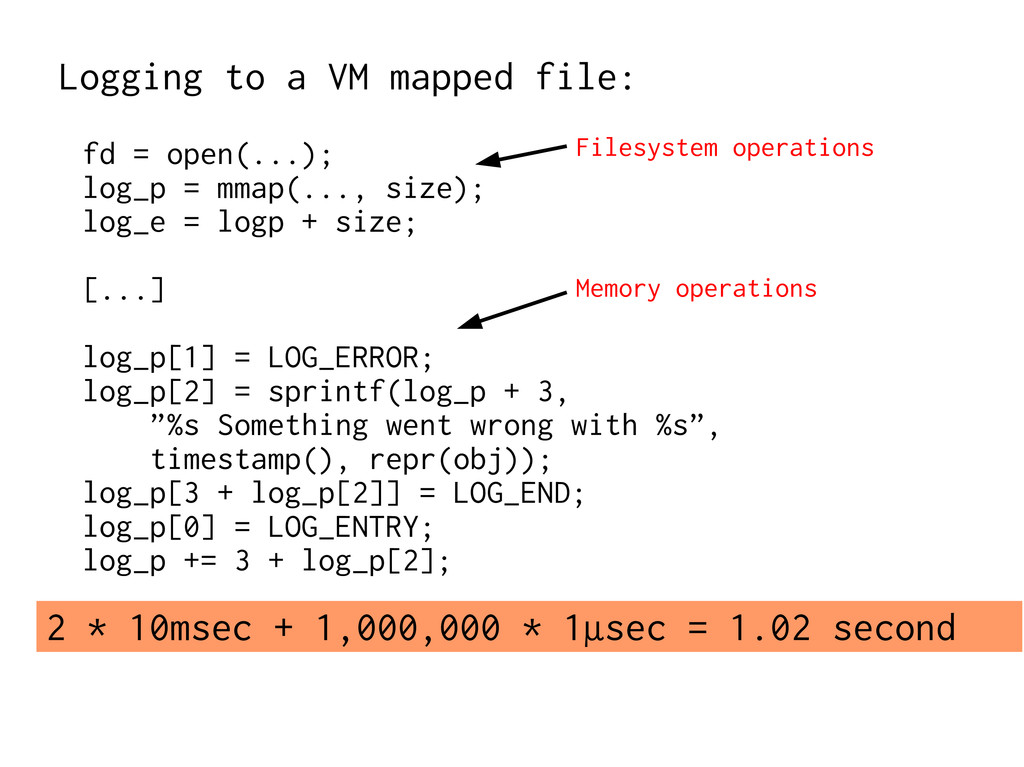
fd = open(...); log_p = mmap(..., size); log_e = logp
+ size; [...] log_p[1] = LOG_ERROR; log_p[2] = sprintf(log_p + 3, ”%s Something went wrong with %s”, timestamp(), repr(obj)); log_p[3 + log_p[2]] = LOG_END; log_p[0] = LOG_ENTRY; log_p += 3 + log_p[2]; Logging to a VM mapped file: Filesystem operations Memory operations 2 * 10msec + 1,000,000 * 1µsec = 1.02 second -
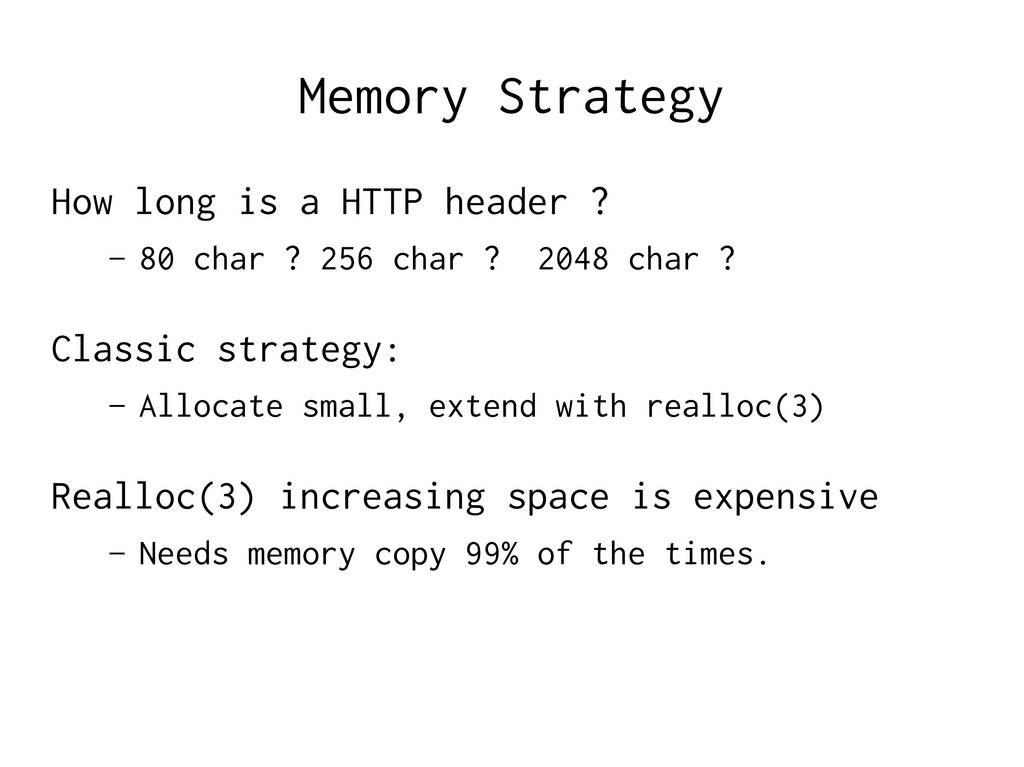
Memory Strategy How long is a HTTP header ? –
80 char ? 256 char ? 2048 char ? Classic strategy: – Allocate small, extend with realloc(3) Realloc(3) increasing space is expensive – Needs memory copy 99% of the times. -
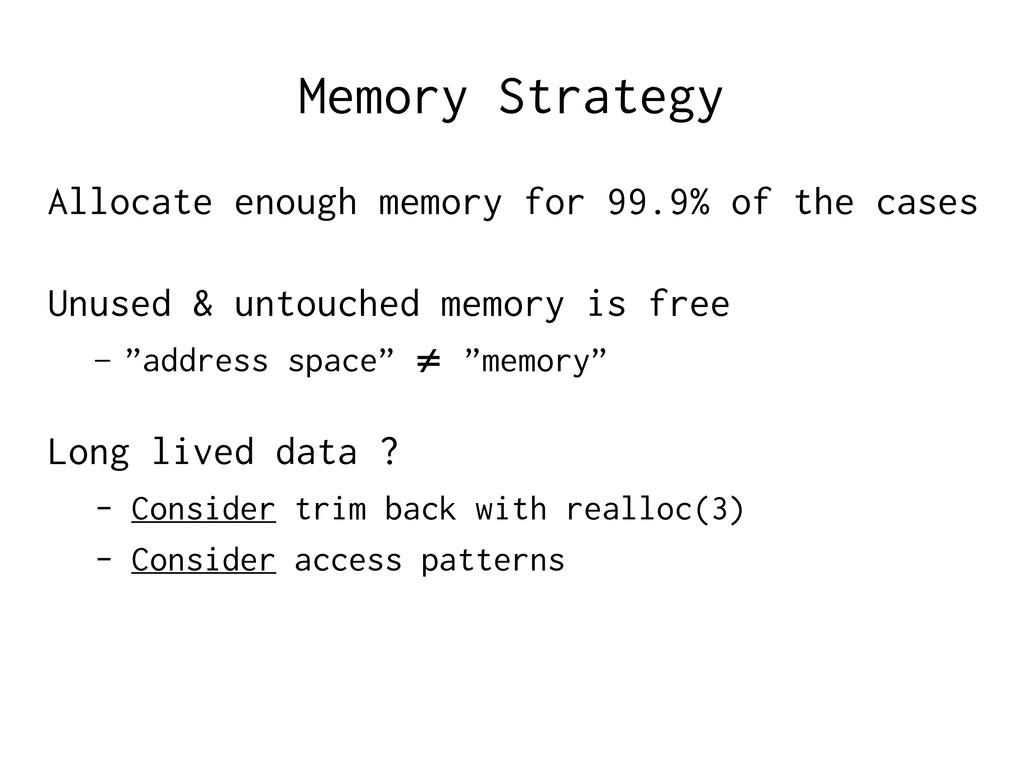
Memory Strategy Allocate enough memory for 99.9% of the cases
Unused & untouched memory is free – ”address space” ≠ ”memory” Long lived data ? - Consider trim back with realloc(3) - Consider access patterns -
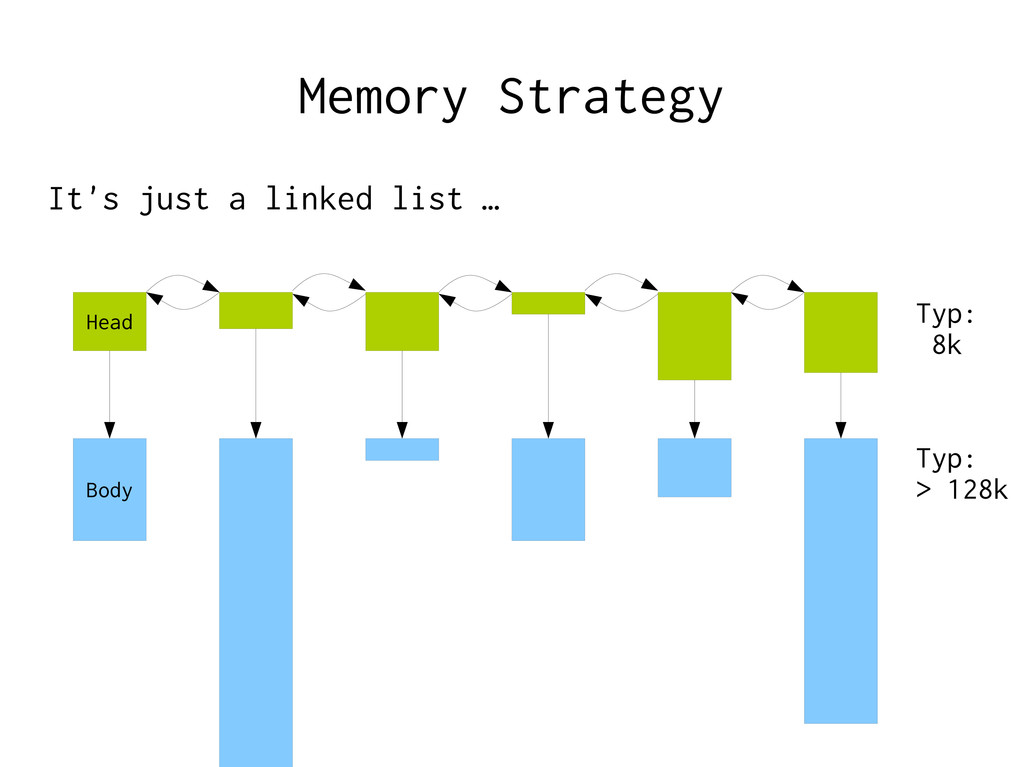
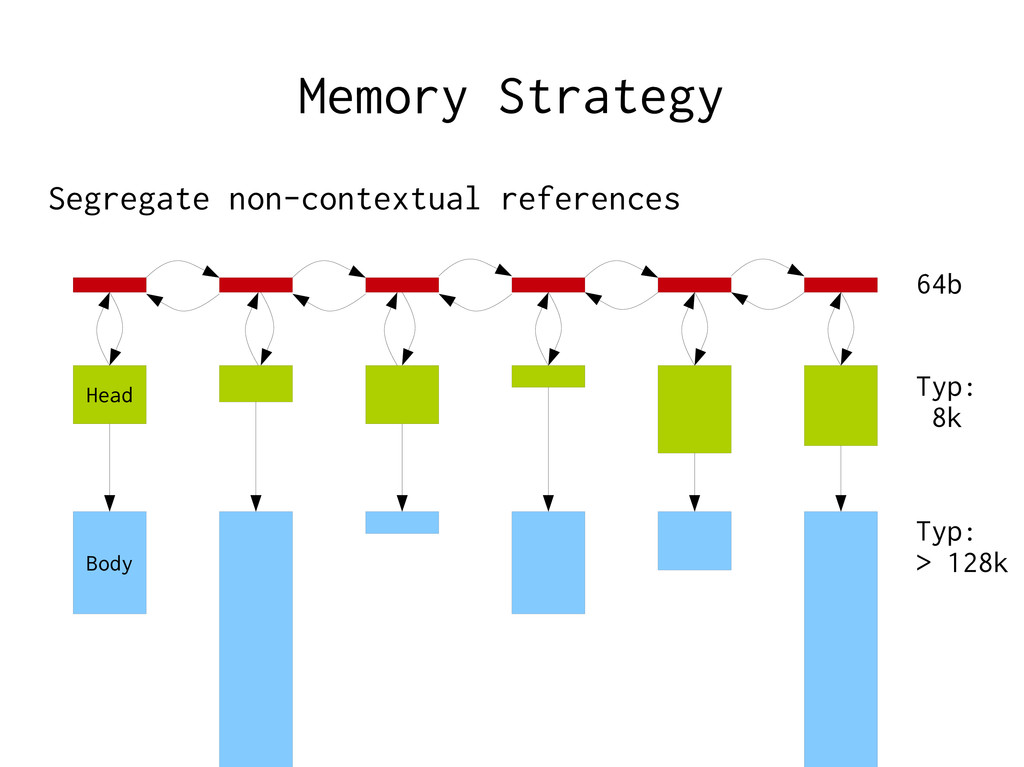
Memory Strategy It's just a linked list … Body Head
Typ: 8k Typ: > 128k -
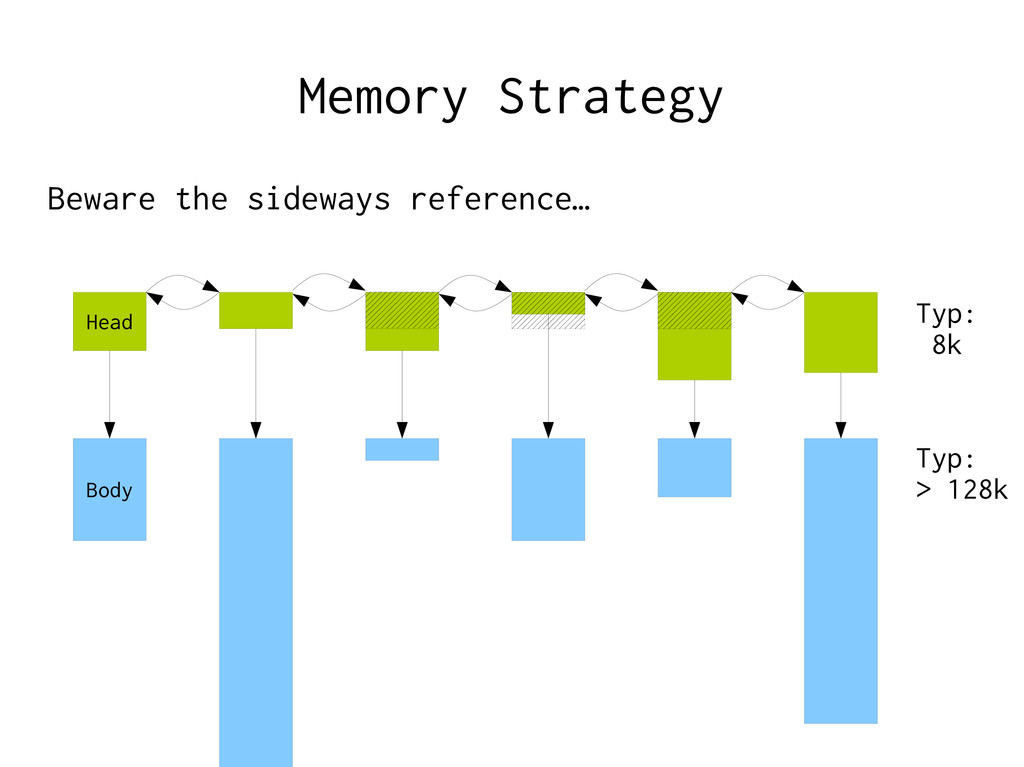
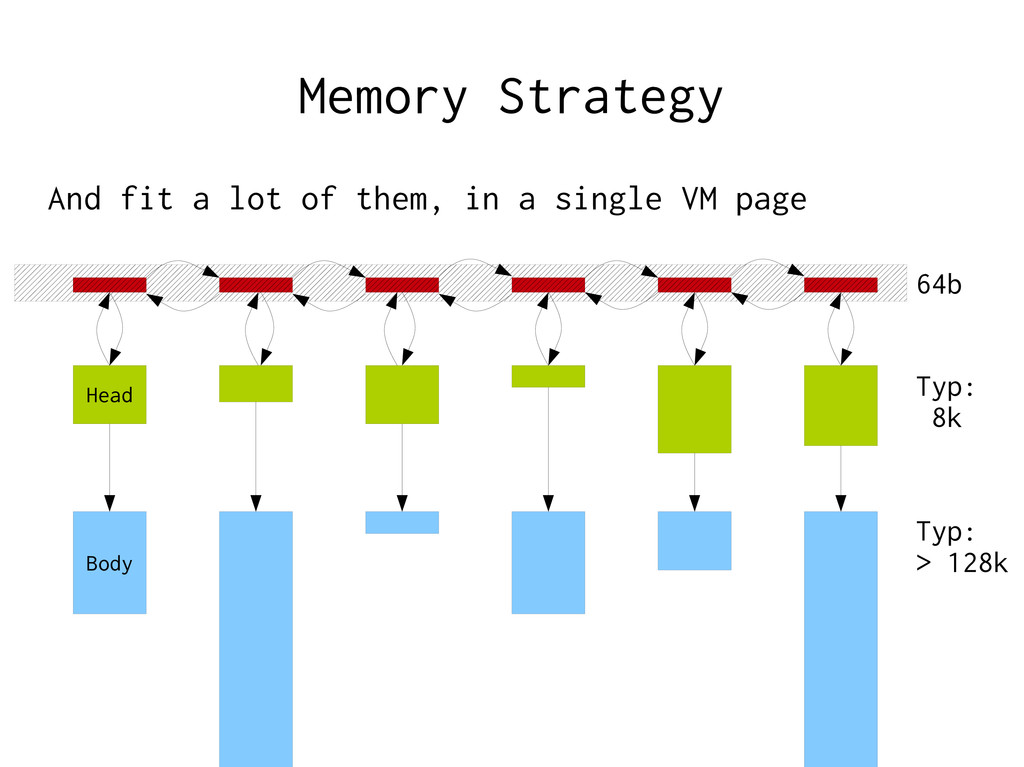
Memory Strategy And fit a lot of them, in a
single VM page Body Head Typ: 8k Typ: > 128k 64b -
Thread Strategy Keep threads away from each other Classical blunder:
Using malloc(3) – malloc(3) manipulates a global state Locking → Give each thread a local ”workspace” – Reset when request done, ready for next request -
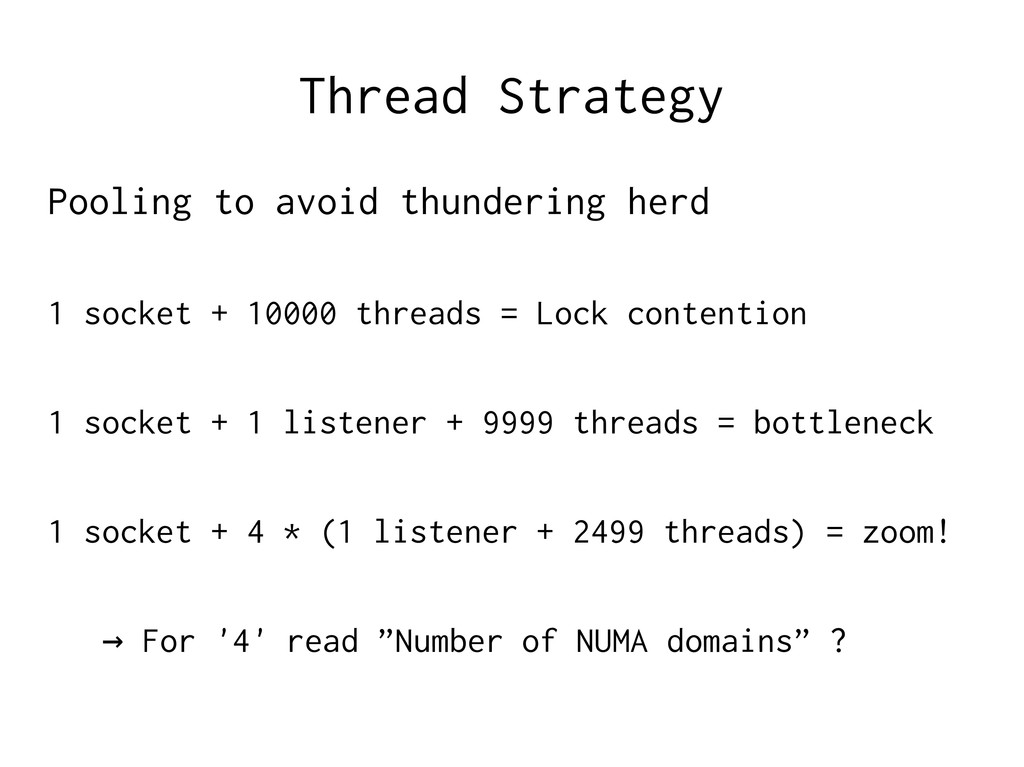
Thread Strategy Pooling to avoid thundering herd 1 socket +
10000 threads = Lock contention 1 socket + 1 listener + 9999 threads = bottleneck 1 socket + 4 * (1 listener + 2499 threads) = zoom! → For '4' read ”Number of NUMA domains” ? -
Thread scheduling You have N threads waiting for work –
Which one do you pick ? -
Thread scheduling You have N threads waiting for work –
Which one do you pick ? FIFO = Fairness, all threads get the same load -
How stupid is FIFO ? You get the thread which
… – Has been doing nothing for the longest time – Has nothing in L1 cache – Has nothing in L2 cache – Has nothing in L3 cache – May not even be in RAM at all = The guaranteed slowest thread you can pick -
LIFO for the win! Schedule everything LIFO order – Threads,
memory, buffers, sockets … – Maximizes chance something is in some cache Even better: LIFO on this NUMA domain -
MPP lessons learned Architecture is more important than algorithms →
Algorithm: Do something faster → Architecture: Do fewer slow things Virtual Memory is expensive to ignore → Most O(foo) estimates are invalid with VM. ” → Just add more RAM” does not help on MPP -
var·nish (värʹnĭsh) n. 1. a. A paint containing [...] tr.v.
var·nished, var·nish·ing, var·nish·es 1. To cover with varnish. 2. To give a smooth and glossy finish to. 3. To give a deceptively attractive appearance to; gloss over. -
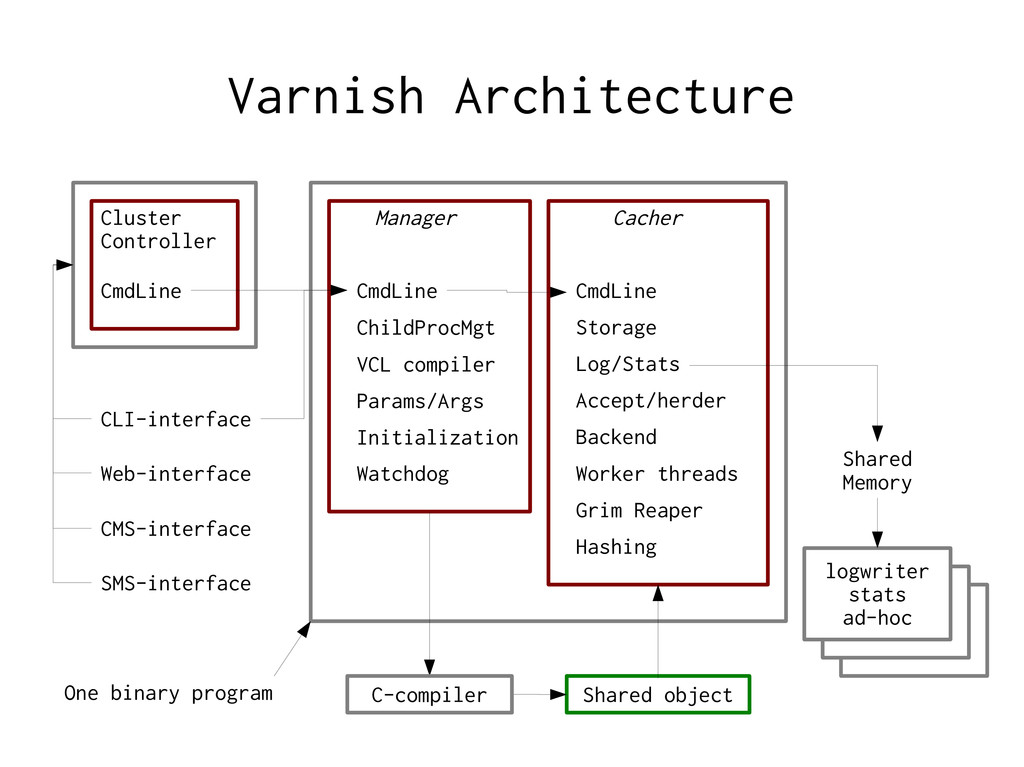
Varnish Architecture Cluster Controller Manager Cacher ChildProcMgt CmdLine Initialization Params/Args
CmdLine Storage Log/Stats Accept/herder Worker threads Grim Reaper C-compiler Shared object CmdLine Web-interface CMS-interface SMS-interface CLI-interface One binary program Shared Memory logwriter stats ad-hoc Backend Hashing VCL compiler Watchdog -
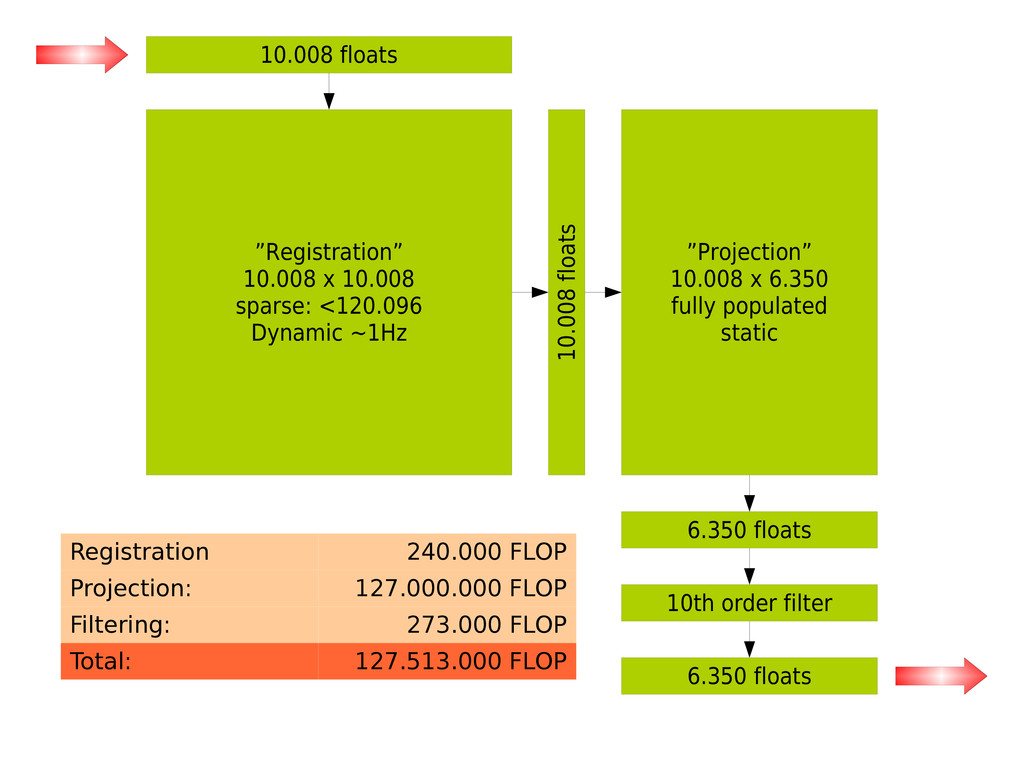
10.008 floats ”Registration” 10.008 x 10.008 sparse: <120.096 Dynamic ~1Hz
10.008 floats ”Projection” 10.008 x 6.350 fully populated static 6.350 floats 10th order filter 6.350 floats Registration 240.000 FLOP Projection: 127.000.000 FLOP Filtering: 273.000 FLOP Total: 127.513.000 FLOP -
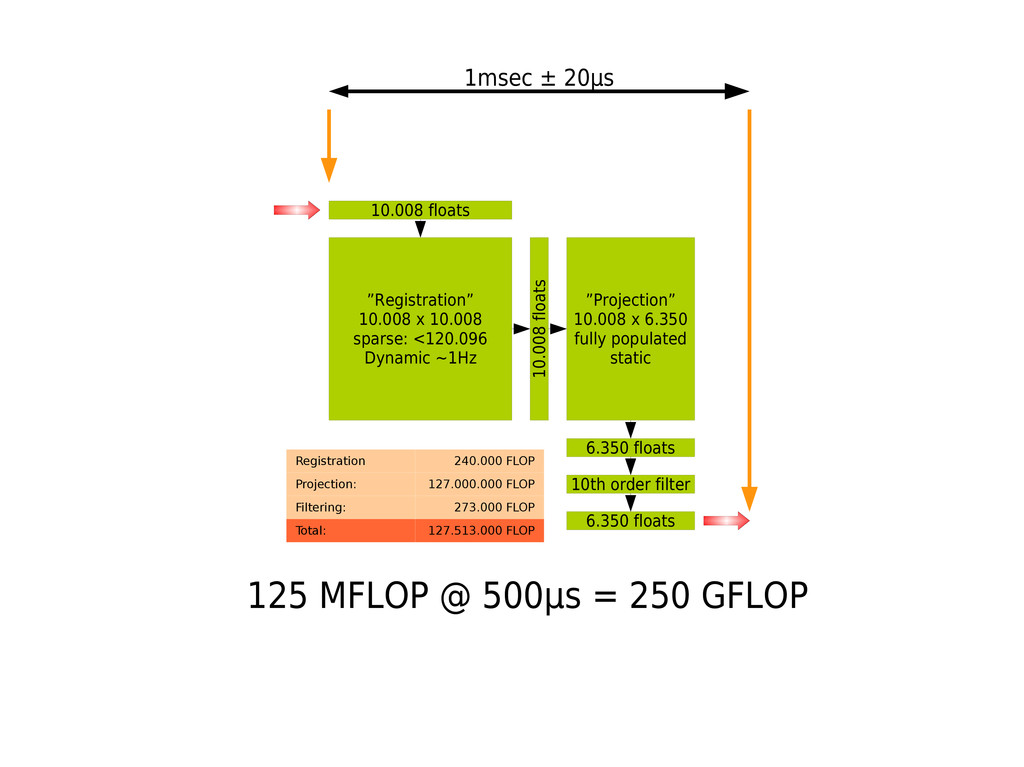
10.008 floats ”Registration” 10.008 x 10.008 sparse: <120.096 Dynamic ~1Hz
10.008 floats ”Projection” 10.008 x 6.350 fully populated static 6.350 floats 10th order filter 6.350 floats Registration 240.000 FLOP Projection: 127.000.000 FLOP Filtering: 273.000 FLOP Total: 127.513.000 FLOP 1msec ± 20µs 125 MFLOP @ 500µs = 250 GFLOP -
What can a movie-theater do over a TV ? Today
movie theaters are big TV's. -
What can a movie-theater do over a TV ? Today
movie theaters are big TV's. But imagine you gave them a compute cluster... -
What can a movie-theater do over a TV ? Today
movie theatres are big TV's. But imagine you gave them a compute cluster... Randomized battle-scenes ? Audience Cameos ? CGI approaching theaters ”unique each evening” ?