A short presentation introducing Apache Hadoop and describing what it is and some of the myths surrounding it. The talk is rounded off with a demonstration using Hadoop in the context of Microsoft HD Insight
Apache Foundation • Apache Hadoop is an open-source software framework for storage and large-scale processing of data-sets on clusters of commodity hardware. Further resources at http://hadoop.apache.org/
volumes of “unstructured data” All data has a structure, when talking about unstructured data people usually mean they want just part of the data, structured in a way they can make sense of. • Schema-on-Read not Schema-on-Write You can just load the data. You define a schema when you want to analyse it
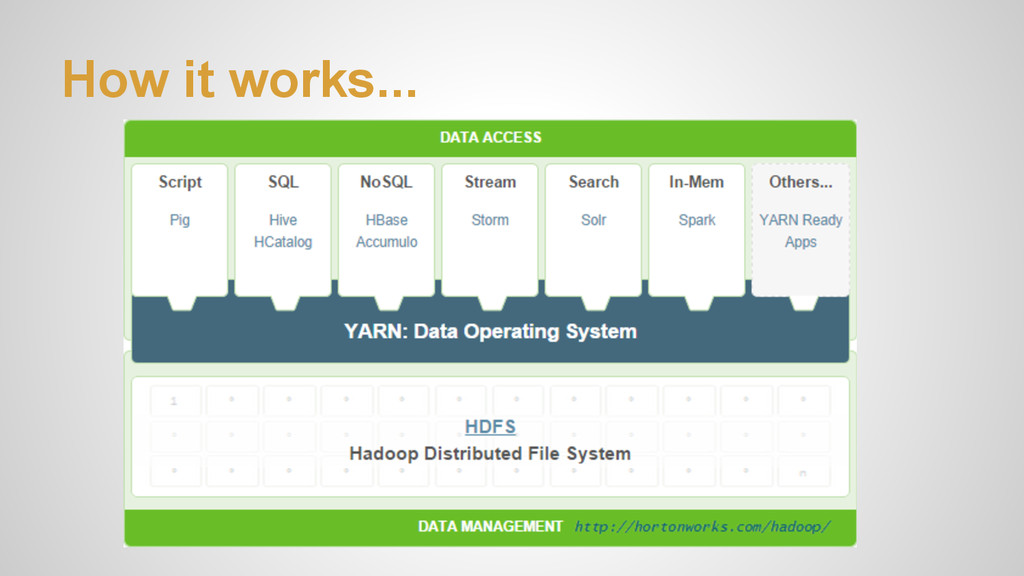
the processing load “Hadoop Distributed File System (HDFS) is designed to span large clusters of commodity servers. Data to be processed is spread across these servers. Jobs can then be distributed to crunch the data. Hadoop use the concept of a Name Node which controls and monitors the distribution and processing of data among any number of node servers • Allow you to extract the results of your processing Once you have crunched your data, you can view it in analysis and visualisation tools such as Power Query for Excel, Tableau and QlikView
what many Snake Oil Salesmen would have you believe, there is no magic button that will turn raw data into business decisions with no effort on your part. • Remove the tedium of patiently mapping data There is no magic button that will discover and map the structure of your data. • Create Unicorns There is no magic button that will create Unicorns.
Retailers interact with customers across multiple channels, yet customer interaction and purchase data is often isolated in data silos. Few retailers can accurately correlate eventual customer purchases with marketing campaigns and online browsing behavior. (true) • Apache Hadoop gives retailers a 360° view of customer behavior. It lets them store data longer and identify phases of the customer lifecycle. (untrue) Better customer analytics increase sales, reduce inventory expenses and retain the best customers.(true) From http://hortonworks.com/industry/retail/


 codmoninc
 maimyyym
 jtakeda
 nealle
 keeg
 carta_engineering
 yamanoku
 riyaamemiya
 kworkdev
 kizawa2020
 gionn
 terurou
 mayatellez
 axbom
 ivargrimstad
 geshan
 thirion
 tammyeverts
 twada
 swwweet
 konakalab
 uxyall
 inesmontani
 aleyda