Upgrade to Pro — share decks privately, control downloads, hide ads and more …

The Reboot, Reloaded

Sponsored · Ship Features Fearlessly Turn features on and off without deploys. Used by thousands of Ruby developers. →

The Reboot, Reloaded

"Have you tried turning it off and on again?" is one of the most common jokes in our industry. However, behind the comical aspect lies a fundamental architectural pattern - state encapsulation and recovery by clearing state data. This pattern is mostly used implicitly, but when used as a design principle unlocks a new paradigm of programming: Recovery Oriented Computing (ROC).
This talks indroduces ROC and fundamental techniques for this paradigm, which can also be applied individually to great effect: seperation of state, crash-only software, micro-reboots, single recovery path, redo logs and checkpoints, pre-emptive
reboots, and more.

Avatar for Avishai Ish-Shalom

Avishai Ish-Shalom

December 26, 2021

More Decks by Avishai Ish-Shalom

Other Decks in Technology

Transcript

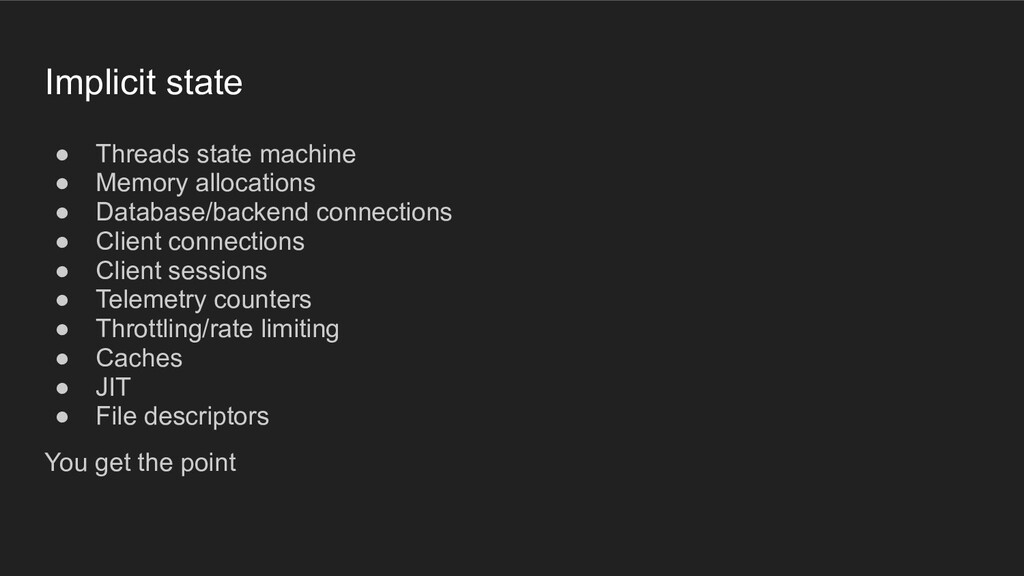
  1. Implicit state • Threads state machine • Memory allocations •

    Database/backend connections • Client connections • Client sessions • Telemetry counters • Throttling/rate limiting • Caches • JIT • File descriptors You get the point
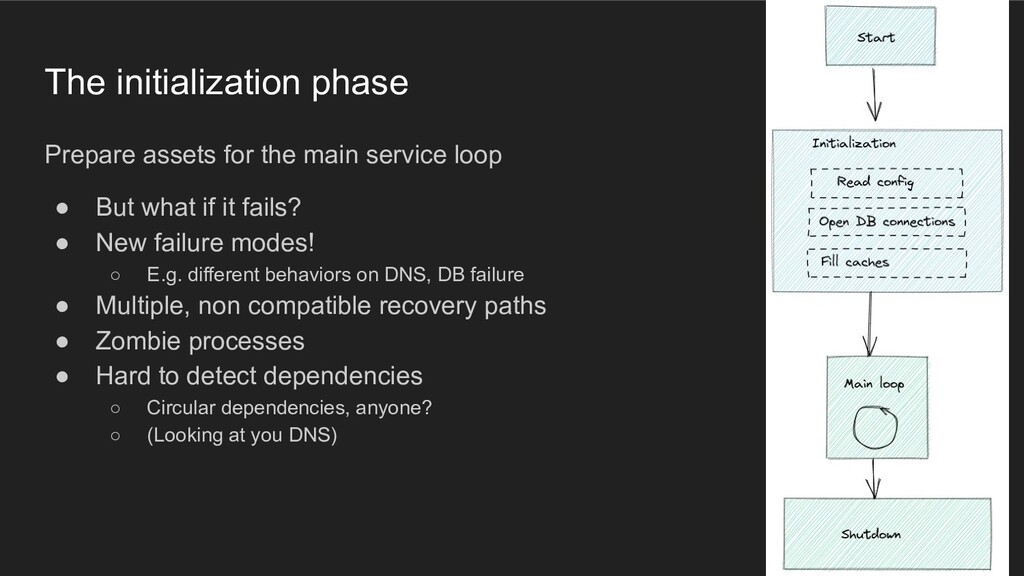
  2. The initialization phase Prepare assets for the main service loop

    • But what if it fails? • New failure modes! ◦ E.g. different behaviors on DNS, DB failure • Multiple, non compatible recovery paths • Zombie processes • Hard to detect dependencies ◦ Circular dependencies, anyone? ◦ (Looking at you DNS)
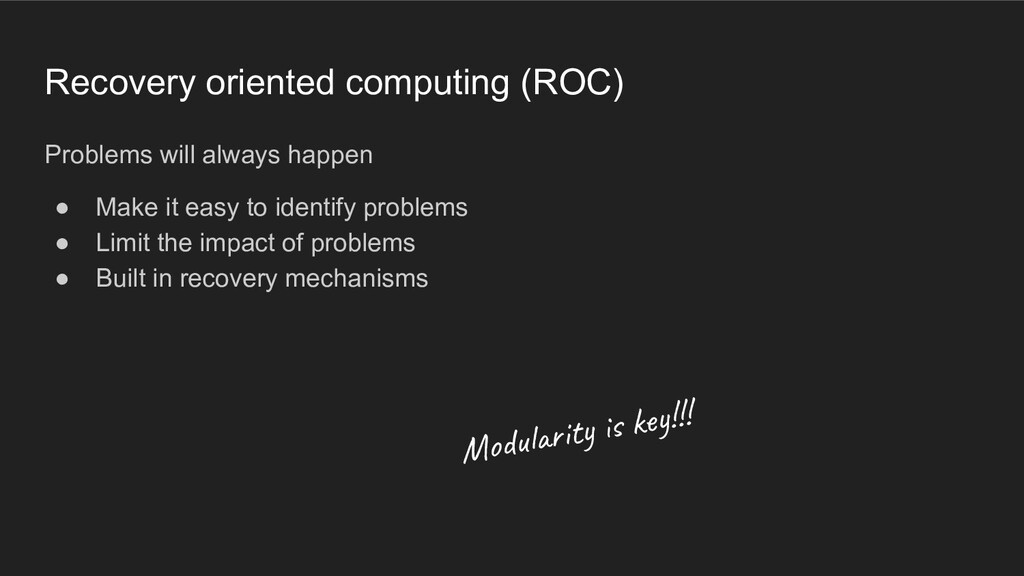
  3. Recovery oriented computing (ROC) Problems will always happen • Make

    it easy to identify problems • Limit the impact of problems • Built in recovery mechanisms Modularity is key!!!
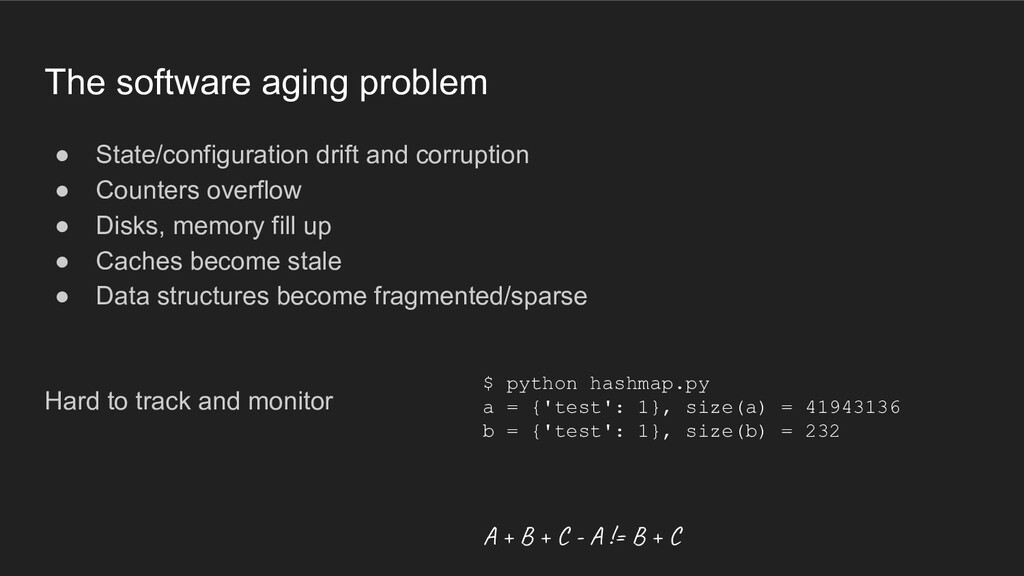
  4. The software aging problem • State/configuration drift and corruption •

    Counters overflow • Disks, memory fill up • Caches become stale • Data structures become fragmented/sparse Hard to track and monitor A + B + C - A != B + C $ python hashmap.py a = {'test': 1}, size(a) = 41943136 b = {'test': 1}, size(b) = 232
  5. Reboot as a software recovery mechanism • Return to known

    good config/state • Initialize connections, etc • Nuke unknown state from orbit • Make those hidden dependencies visible But, a reboot is expensive!
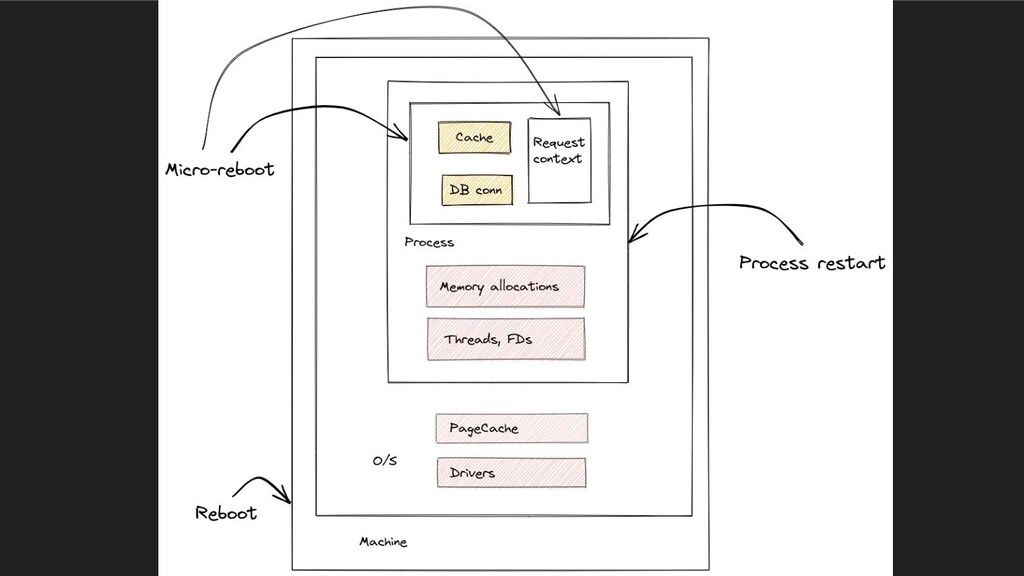
  6. State segregation • Each “state ring” owns some resources and

    data • Each “state ring” has its own reset procedure • Reset clears data, reinitialize resources • After reset, known good state or hard failure ◦ Makes the state ring easy to monitor • No impact on state in other state rings
  7. Macro reboot • How do you reboot a service? A

    whole system? • Some state must be preserved ◦ In particular, business state ◦ All useful systems are stateful to some degree • Some state is in transit ◦ The network itself has is state • Invalidate client sessions, backend sessions, etc ◦ Generation ID is your friend Rebooting a system does not mean rebooting its parts!
  8. Generation ID • UUID or counter • Reset on reboot

    • Invalidate sessions, connections
  9. “Crash only” software • Significant part of most software dedicated

    to error handling ◦ Complex ◦ Scattered ◦ Buggy • Single error handling mechanism, single exit point: a crash • Single recovery path, single entry point: boot • Crash report (state dump) for post-mortem debugging Crash, dump, reboot
  10. Single recovery path ⇒ Single optimization path • Routine reboots

    make boot profiling easier • Parallelization • Reducing the “initialization” phase • Lazy/optional dependencies
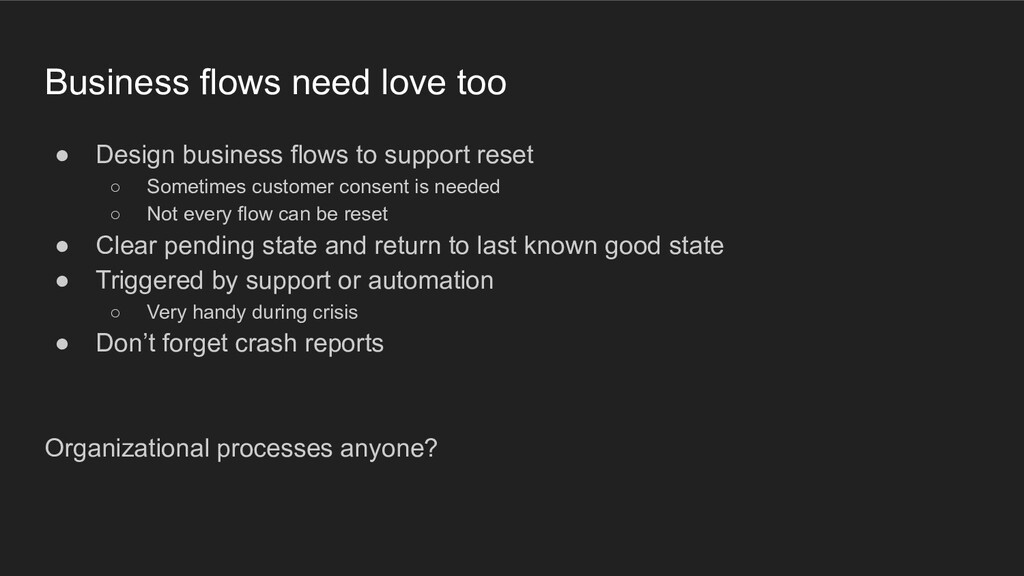
  11. Business flows need love too • Design business flows to

    support reset ◦ Sometimes customer consent is needed ◦ Not every flow can be reset • Clear pending state and return to last known good state • Triggered by support or automation ◦ Very handy during crisis • Don’t forget crash reports Organizational processes anyone?
  12. Preemptive reboots Everything breaks, eventually. Better it happens on your

    terms • Trigger reboot based on max lifetime, resource usage, errors or just random • Reboot becomes integral part of software lifecycle • Keeps components within known boundaries of “healthy” operation • Makes upgrades, deployments, etc easier • Flush out problem early; If it won’t boot, better you know now • Yes, there’s overhead - just like GC
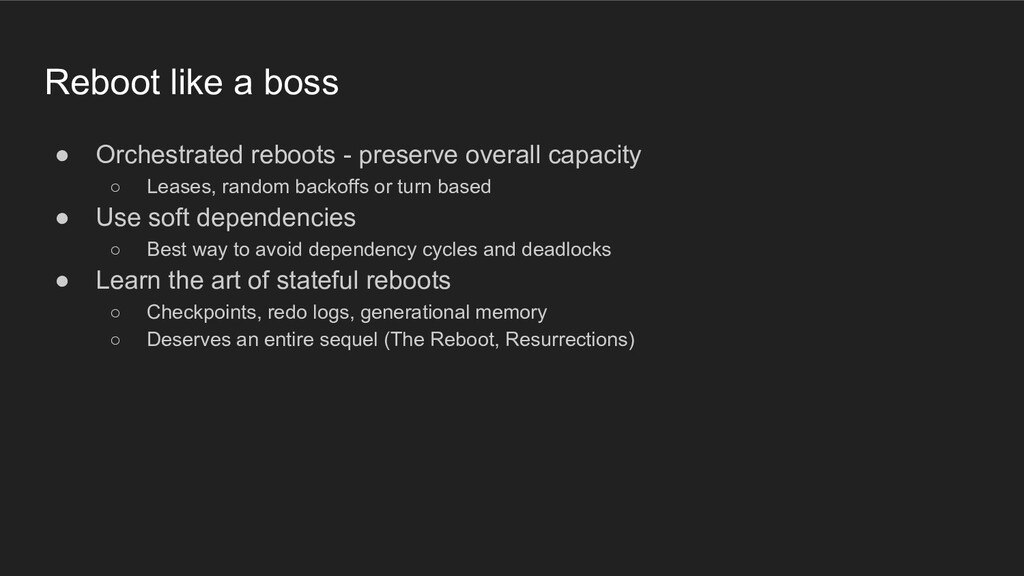
  13. Reboot like a boss • Orchestrated reboots - preserve overall

    capacity ◦ Leases, random backoffs or turn based • Use soft dependencies ◦ Best way to avoid dependency cycles and deadlocks • Learn the art of stateful reboots ◦ Checkpoints, redo logs, generational memory ◦ Deserves an entire sequel (The Reboot, Resurrections)
  14. The circle of life must continue • A reliable system

    is built of less reliable parts • The essential properties of the system survive, the parts don’t Are you still you when all your cells have been replaced?
  15. References Berkeley/Stanford ROC project homepage • Computer Immunology • Recursive

    Restartability: Turning the Reboot Sledgehammer into a Scalpel • Microreboot – A Technique for Cheap Recovery • Crash-Only Software