Upgrade to Pro — share decks privately, control downloads, hide ads and more …

[GDG Winnipeg] Build a Real-Time RAG System wit...

[GDG Winnipeg] Build a Real-Time RAG System with Gemini & the Multimodal Live API

[GDG Winnipeg] Build a Real-Time RAG System with Gemini & the Multimodal Live API

More Decks by Olayinka Peter Oluwafemi

Other Decks in Technology

Transcript

  1. Build a Real-Time RAG System with Gemini & the Multimodal

    Live API GDG Winnipeg May 2026 Olayinka Peter Oluwafemi Machine Learning GDE
  2. $whoami • • • • • ML Engineer @Kaart ML

    Google Developer Expert Gemini 󰙤 ❤ TensorFlow, anime & peanut butter Coordinates 󰗓 olayinkapeter.com Olayinka Peter Oluwafemi Machine Learning GDE
  3. Motivation — Why Real-Time RAG? • Traditional RAG → request-response

    cycle • Real-Time RAG → continuous streaming, instant grounding • Enables voice assistants, customer support, AI tutors, etc. • Gemini 2.0 Multimodal Live API enables real-time text+audio generation • Ideal for low-latency, multi-turn, context-aware apps
  4. What We’ll Cover • • • • • • Gemini

    2.0 Overview Multimodal Live API Retrieval Augmented Generation (RAG) Basics Building a Real-Time RAG pipeline Live Coding Demo 󰲐 Next Steps + Q&A
  5. Meet Gemini 2.0 Flash • • • • • Fastest

    Gemini model (⚡ 3× faster TTFT than 1.5 Flash) Multimodal (text, image, audio, video) New: Multimodal Live API Supports: Real-time text & audio output SDK: google-genai — integrates with Vertex AI
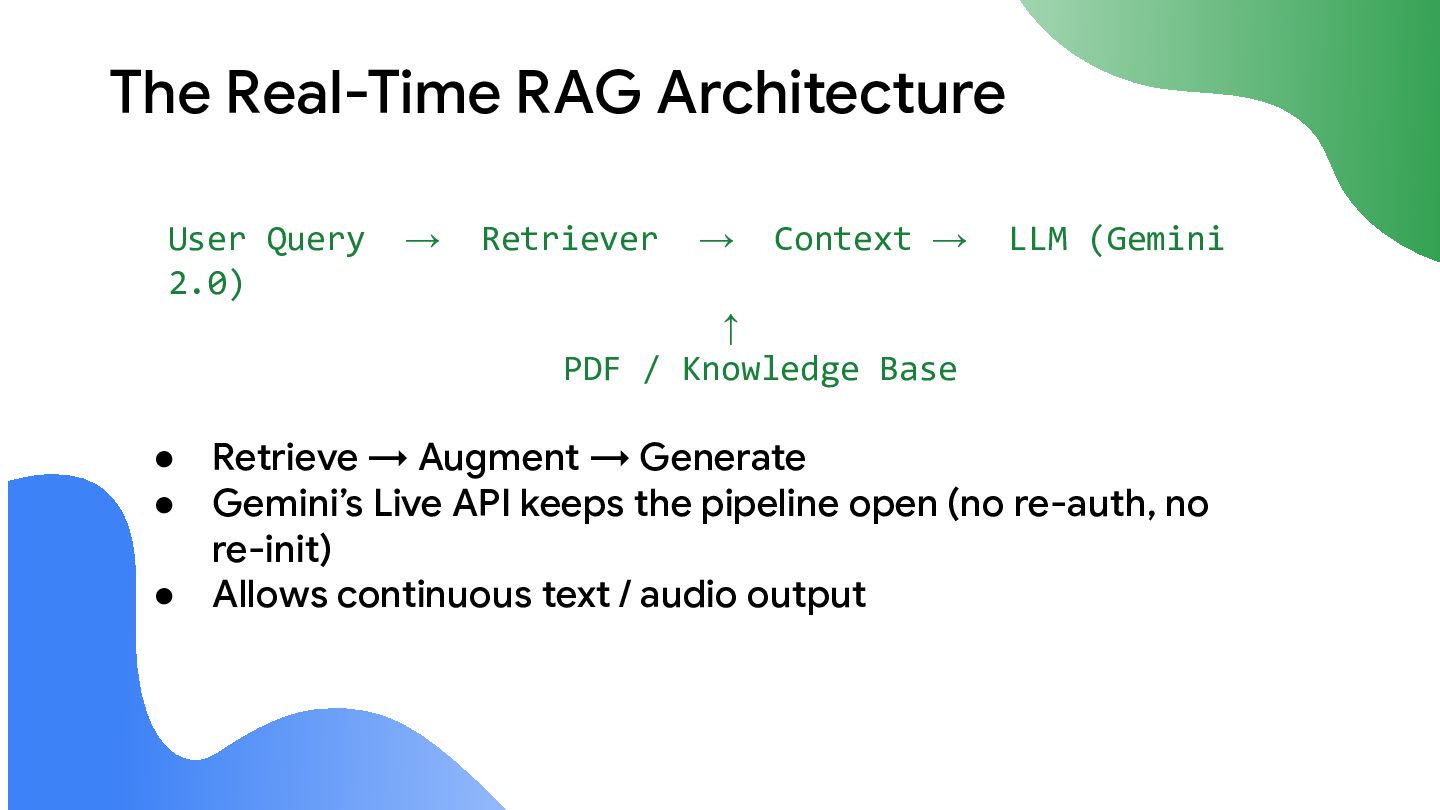
  6. The Real-Time RAG Architecture User Query 2.0) → Retriever →

    Context → LLM (Gemini ↑ PDF / Knowledge Base • Retrieve → Augment → Generate • Gemini’s Live API keeps the pipeline open (no re-auth, no re-init) • Allows continuous text / audio output
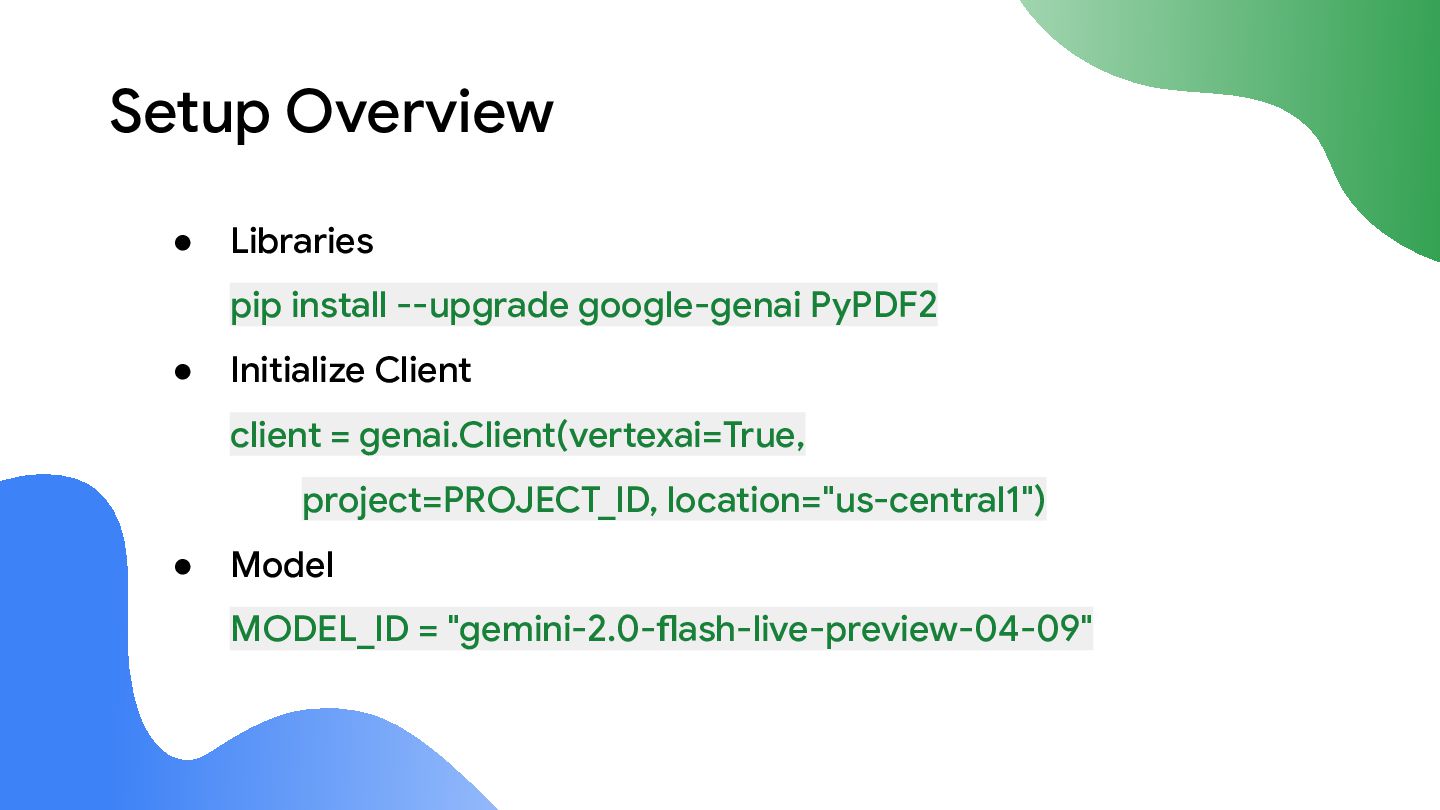
  7. Setup Overview • Libraries pip install --upgrade google-genai PyPDF2 •

    Initialize Client client = genai.Client(vertexai=True, project=PROJECT_ID, location="us-central1") • Model MODEL_ID = "gemini-2.0-flash-live-preview-04-09"
  8. Use Case — Cymbal Bikes (Retail Support) Goal → Build

    a customer support system that answers questions grounded in PDFs: • • CymbalBikesReturnPolicy.pdf CymbalBikesServices.pdf
  9. Step 1 — Without Grounding Prompt: “What is the price

    of a basic tune-up at Cymbal Bikes?” → ❌ Model guesses (hallucinates)
  10. Step 2 — Grounding with RAG RAG = Retrieval +

    Generation • • • • Extract text chunks from documents Embed with text-embedding-005 Search for semantically relevant context Feed to Gemini → grounded, accurate answers
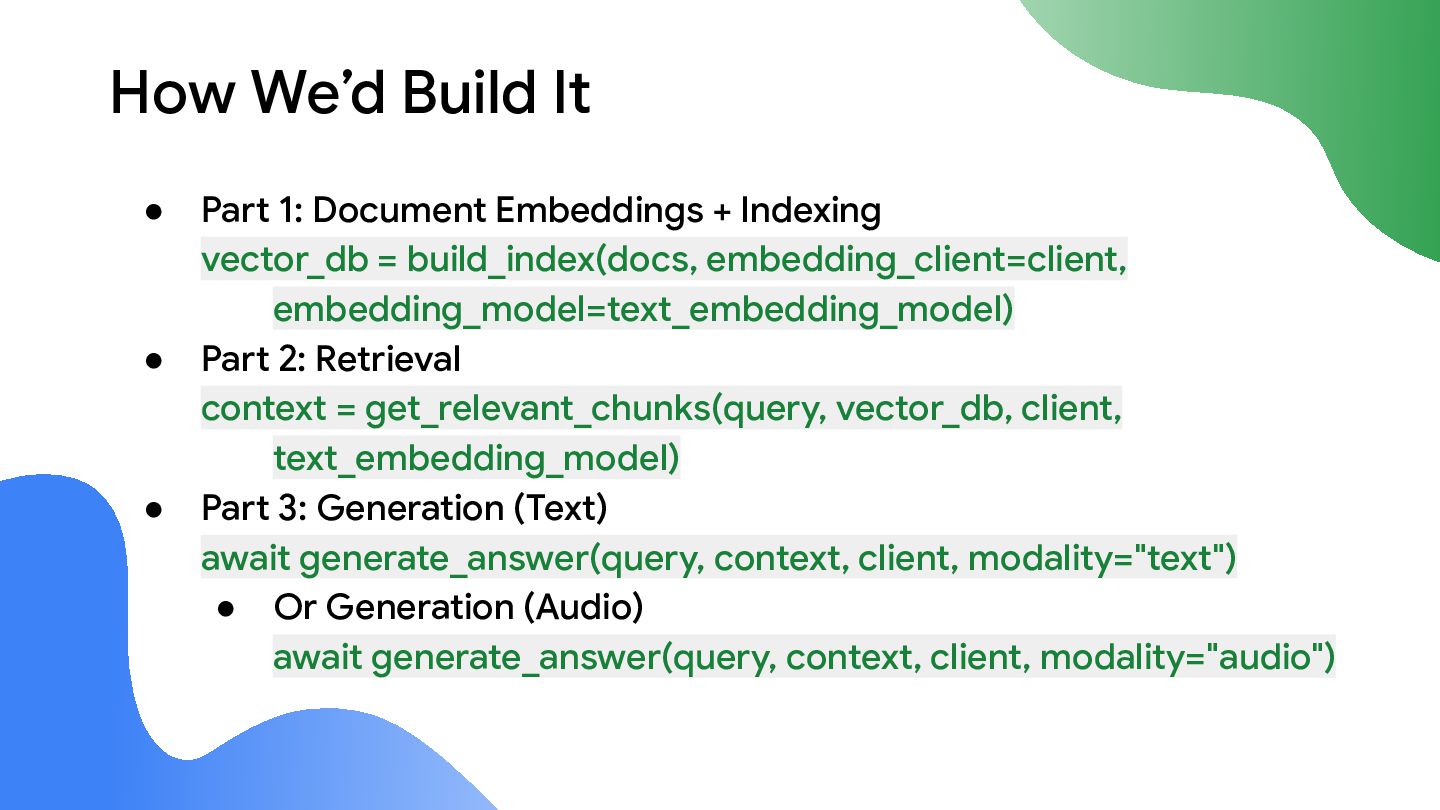
  11. How We’d Build It • • • Part 1: Document

    Embeddings + Indexing vector_db = build_index(docs, embedding_client=client, embedding_model=text_embedding_model) Part 2: Retrieval context = get_relevant_chunks(query, vector_db, client, text_embedding_model) Part 3: Generation (Text) await generate_answer(query, context, client, modality="text") • Or Generation (Audio) await generate_answer(query, context, client, modality="audio")
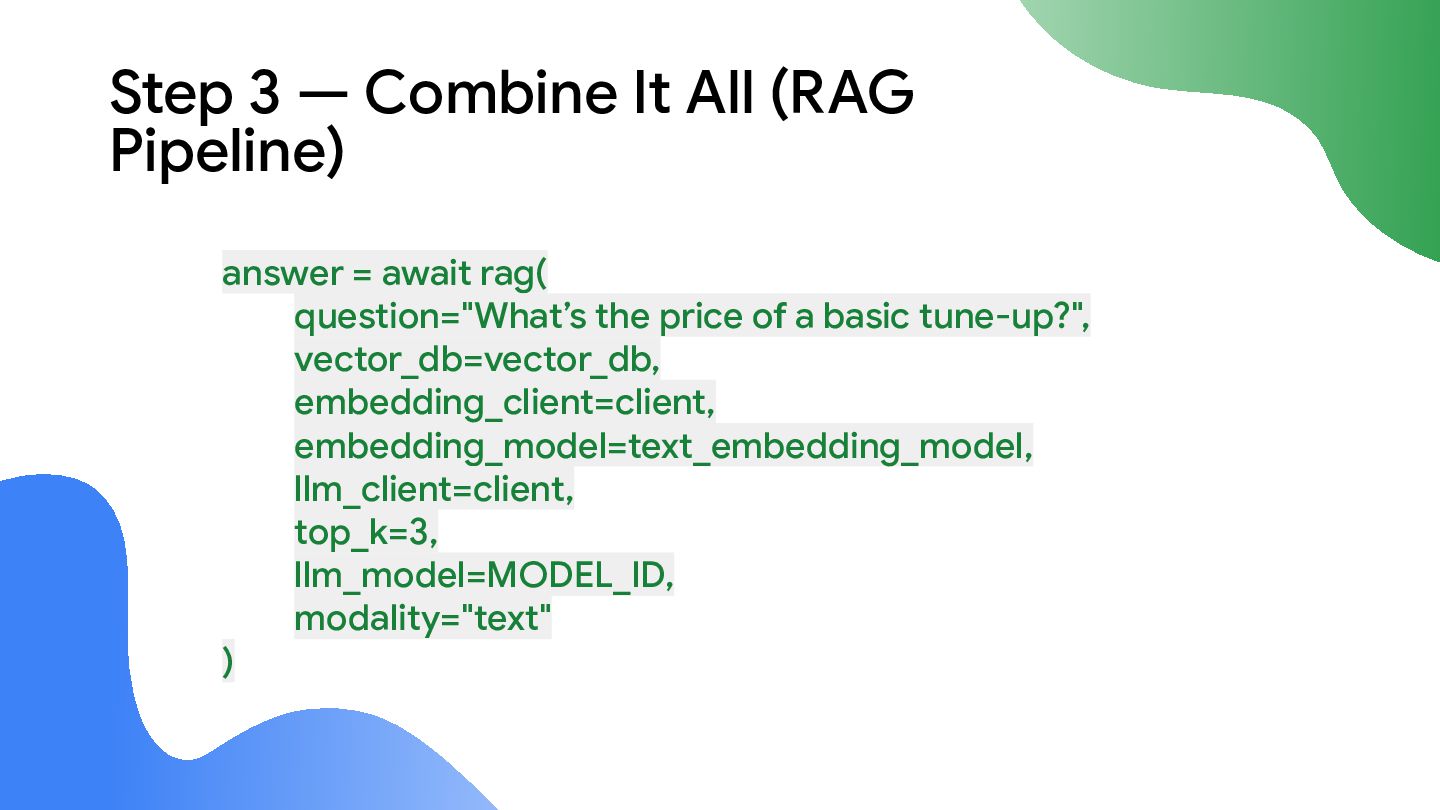
  12. Step 3 — Combine It All (RAG Pipeline) answer =

    await rag( question="What’s the price of a basic tune-up?", vector_db=vector_db, embedding_client=client, embedding_model=text_embedding_model, llm_client=client, top_k=3, llm_model=MODEL_ID, modality="text" )
  13. Multimodal Live API = Game Changer • • • Streamed

    text + audio responses Persistent connection (WebSockets) Perfect for: ◦ AI call agents ◦ Live tutoring ◦ Assistive AI companions
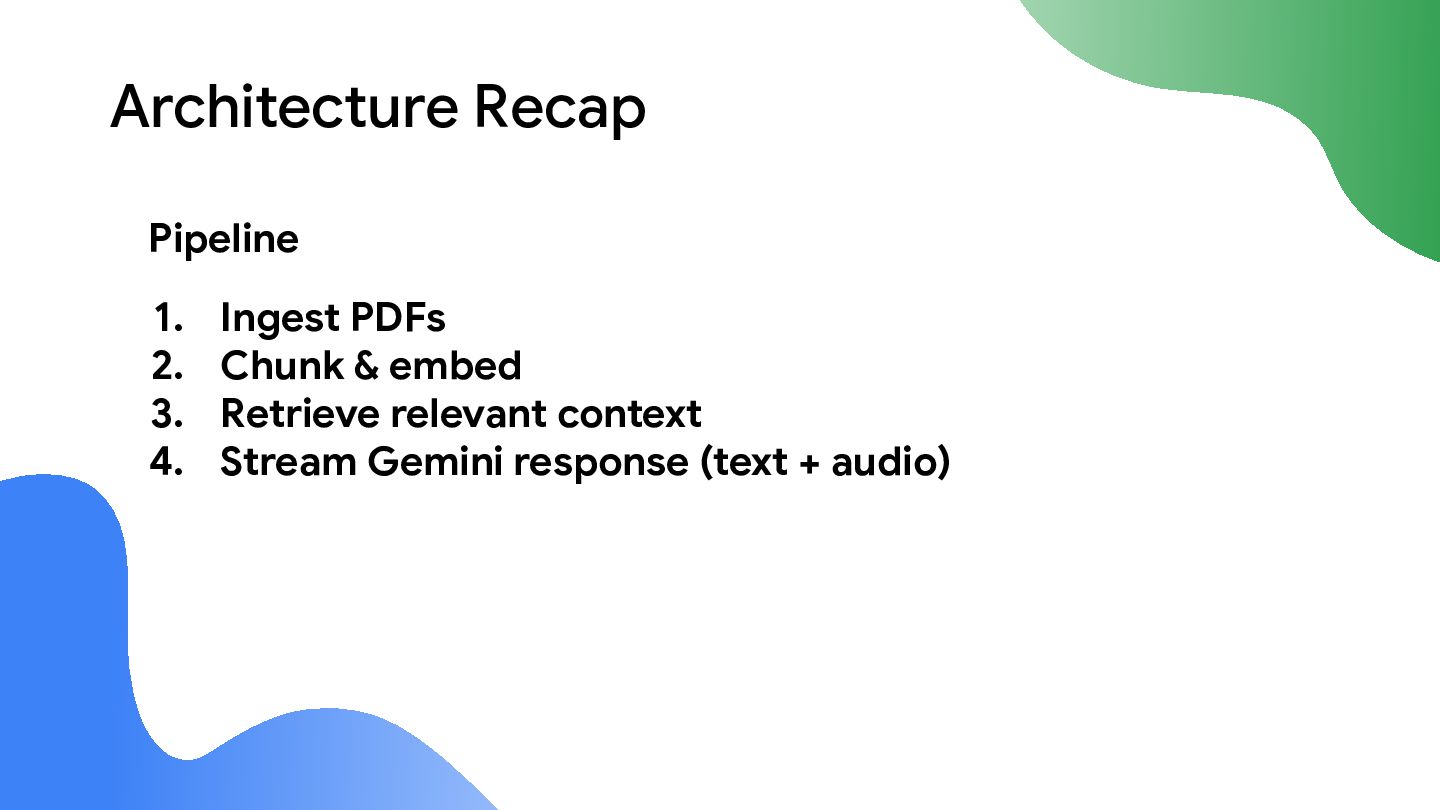
  14. Architecture Recap Pipeline 1. 2. 3. 4. Ingest PDFs Chunk

    & embed Retrieve relevant context Stream Gemini response (text + audio)
  15. What’s Next? • Scale to larger vector DBs (Vertex AI

    Search / LangChain) • Add speech input (full duplex streaming) • Integrate into Android / web apps
  16. 1. Build a real-time product recommendation engine You’re a digital

    retailer trying to grow basket size and customer loyalty, but traditional recommendation engines often fail to understand a shopper’s true intent or style beyond basic keywords. This leads to generic recommendations, poor product discovery, abandoned carts, and lost revenue.
  17. 2. Summarize commentary into podcasts You’re a broadcaster or sports

    league managing hours of live commentary, but manually turning them into highlight reels, summaries, or podcasts is slow and resource-intensive. This delays fan engagement opportunities and makes it harder to deliver timely content at scale.
  18. 3. Search data across tens of thousands of courses You're

    a large media or education company with tens of thousands of courses, articles, and learning materials. Your challenge is helping users find the specific information they need when it's buried across this massive and diverse content library.