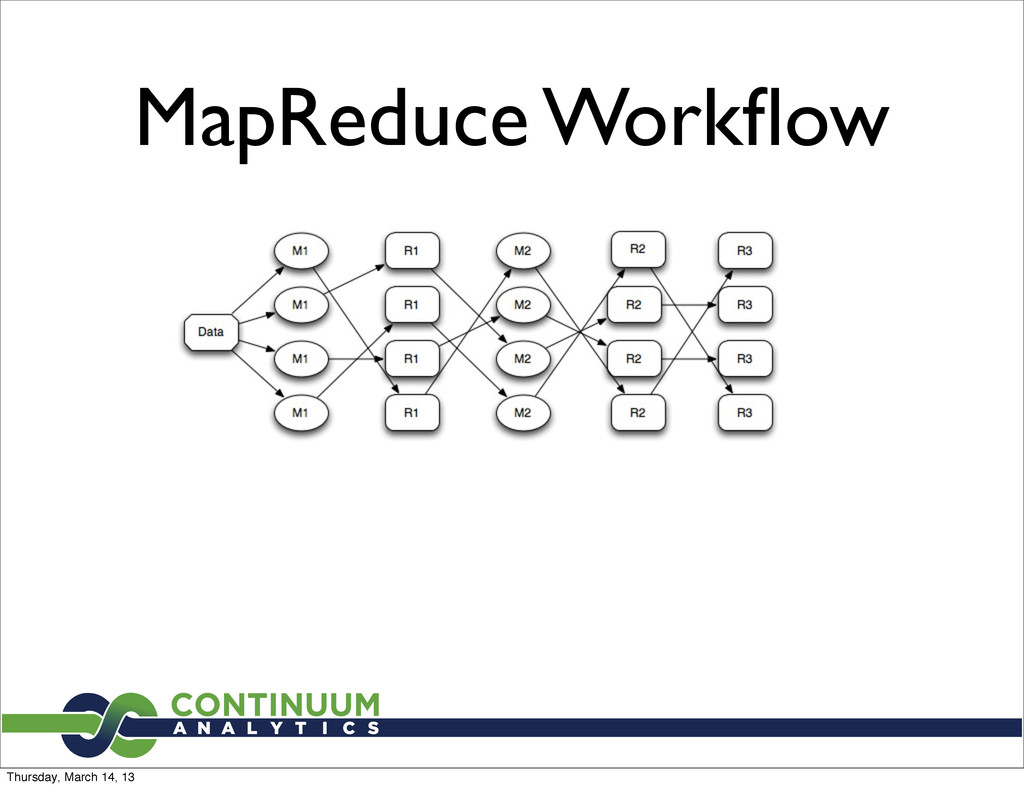
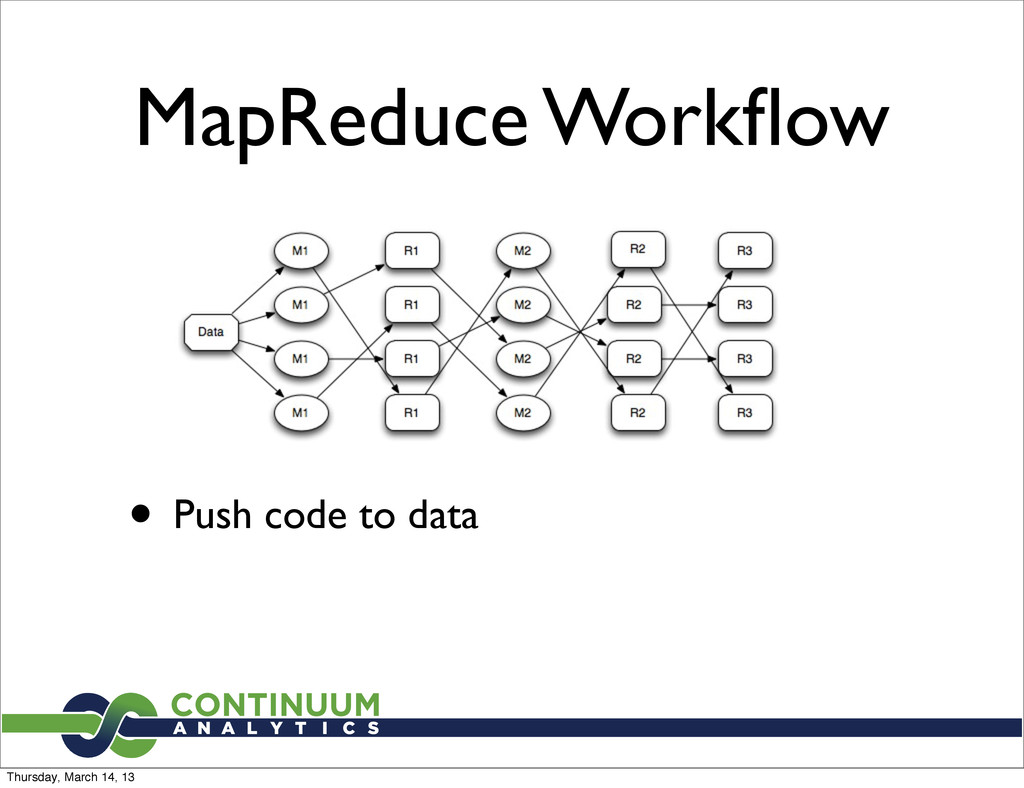
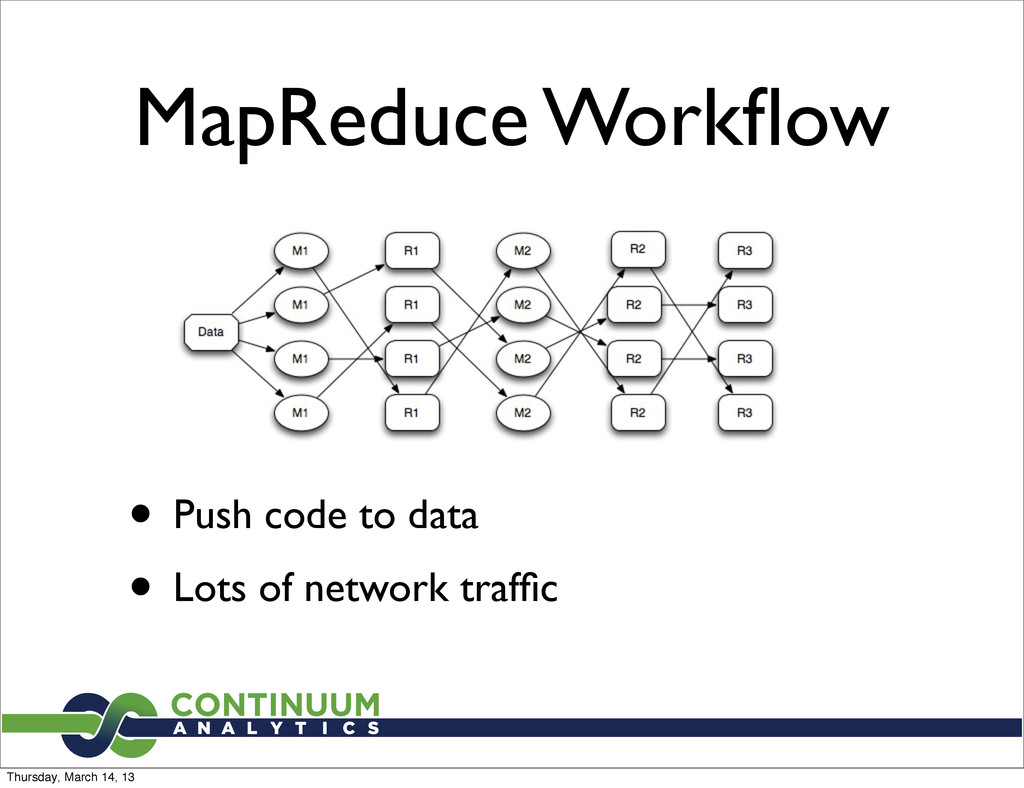
MapReduce disco/hadoop discussion and concluding thoughts and data analysis with humans and machines. Data and IPython notebooks at: https://github.com/ContinuumIO/tutorials
Increase Memory • Can’t fit into R • Increase Memory • Can’t fit into Memory • Increase Memory • Can’t fit on a single disk • Distributed Filesystem: SAN, HDFS/DDFS, AWS: S3, Redshift, etc. Thursday, March 14, 13
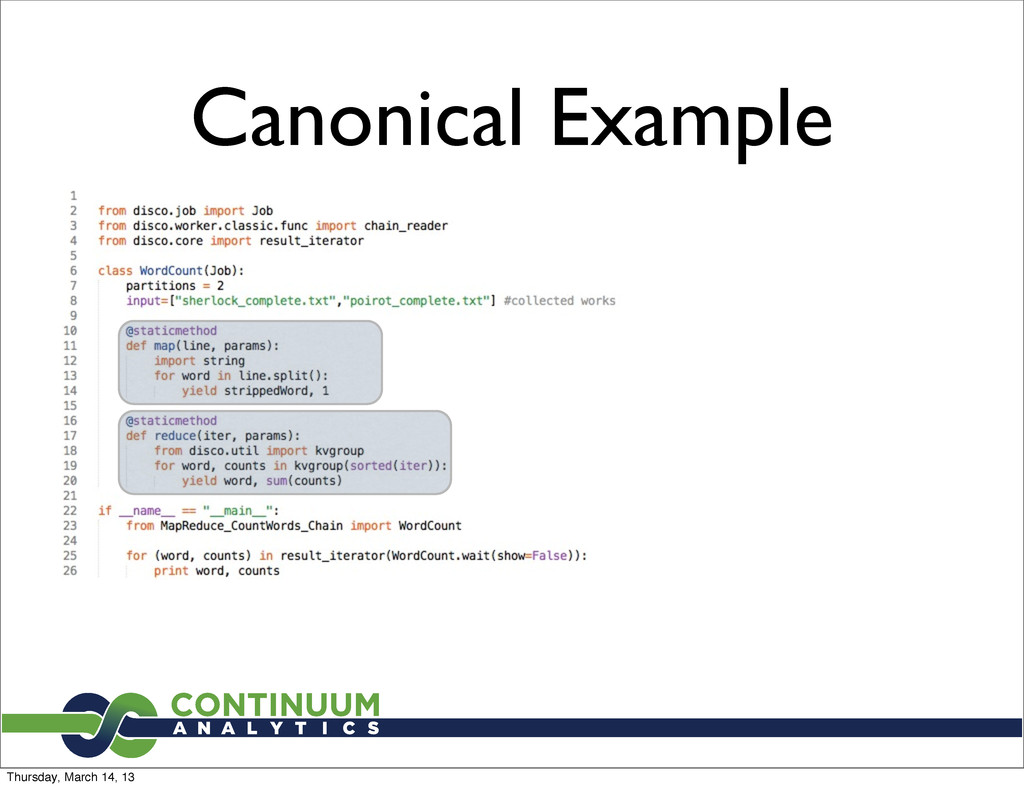
into key-values pairs • Collect/Partition kv pairs (Optional Sort) Framework to help solve the problem of distributed computation for distributed data Thursday, March 14, 13
into key-values pairs • Collect/Partition kv pairs (Optional Sort) • Buckets are passed to Reduce function Framework to help solve the problem of distributed computation for distributed data Thursday, March 14, 13
into key-values pairs • Collect/Partition kv pairs (Optional Sort) • Buckets are passed to Reduce function • Result is returned Framework to help solve the problem of distributed computation for distributed data Thursday, March 14, 13
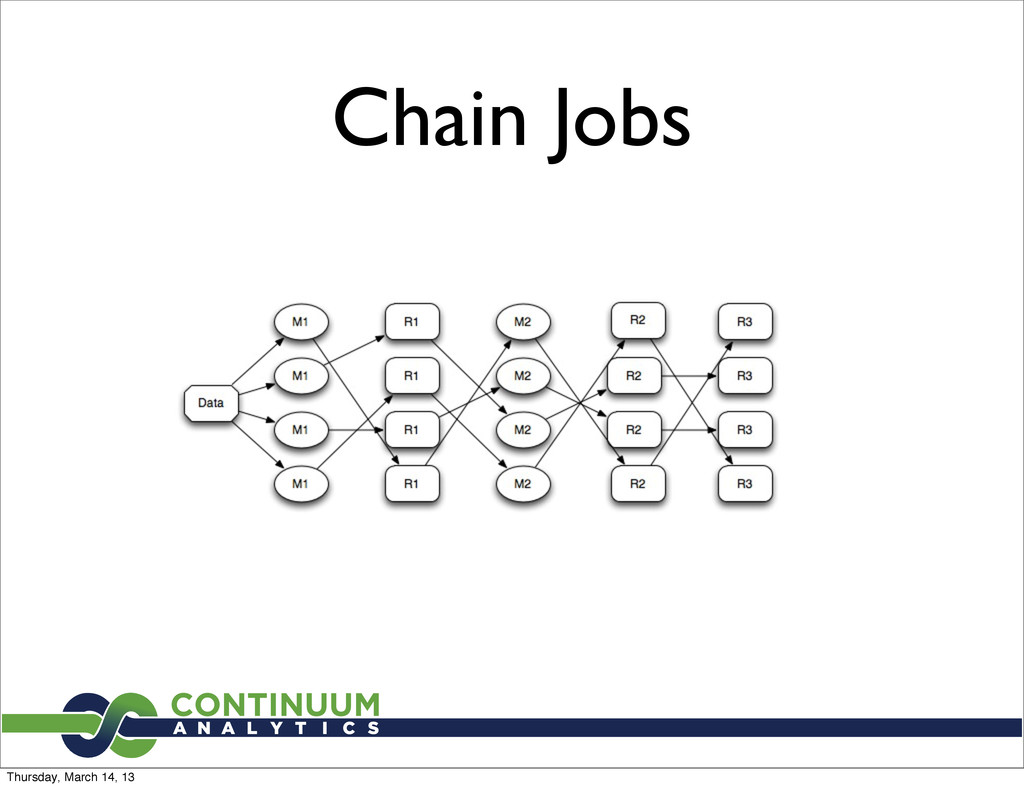
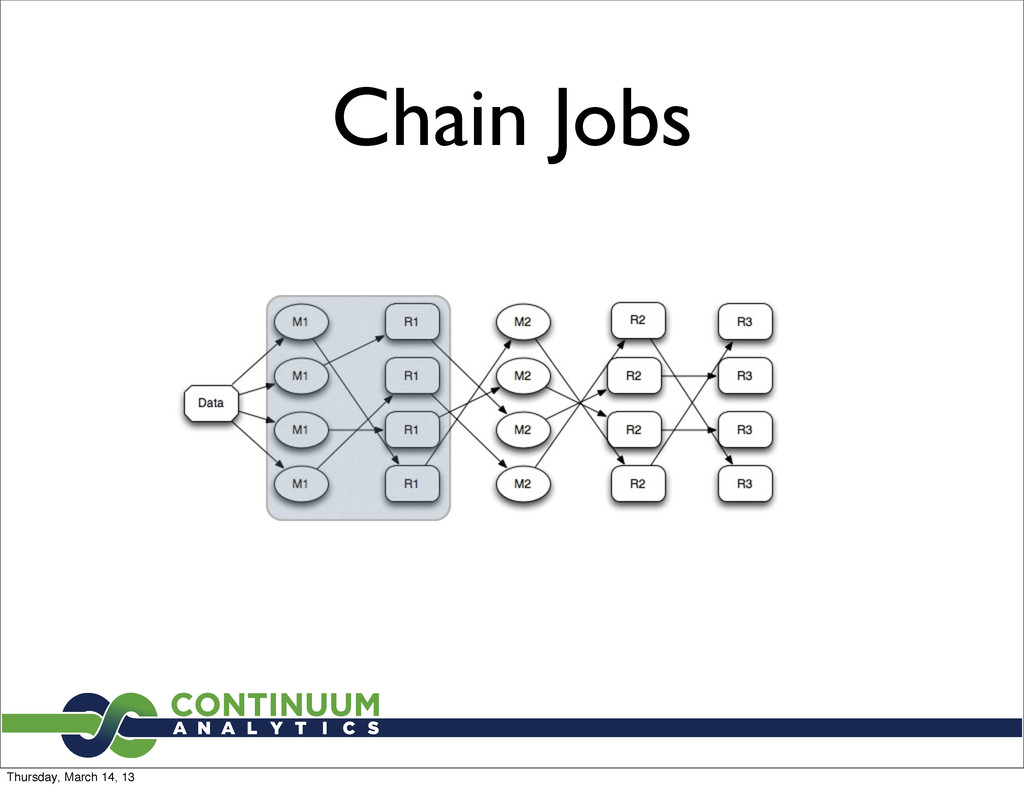
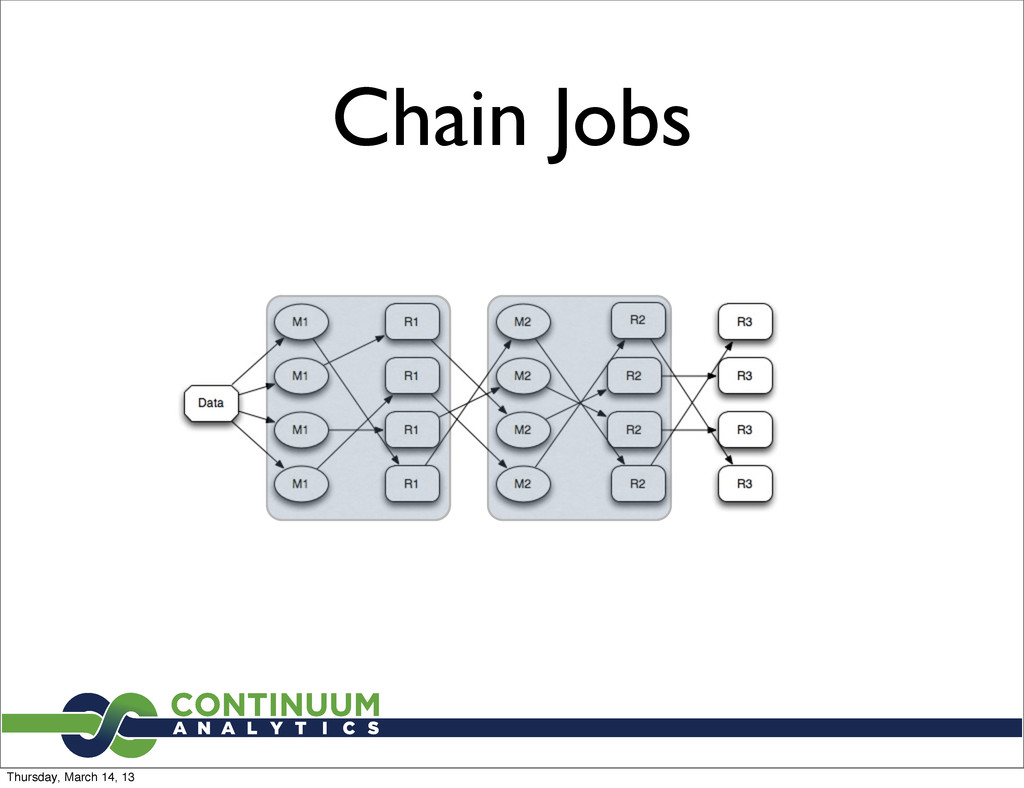
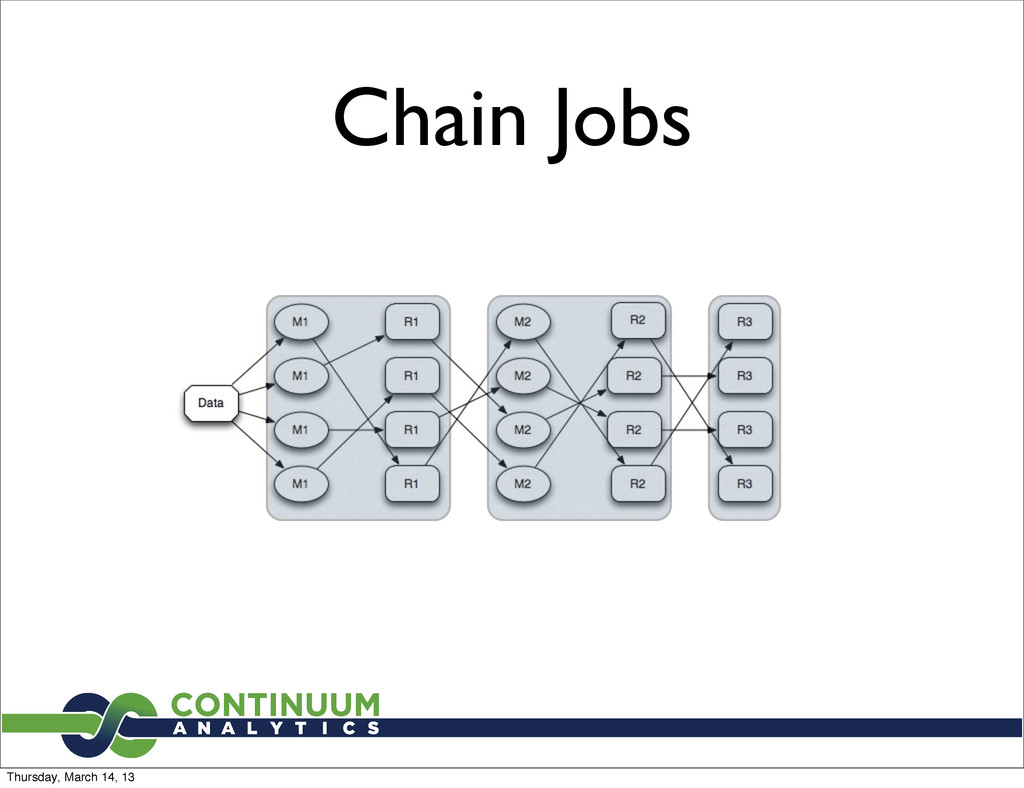
Task Deconstruction • Good for code management • Hides -- in a good way -- data management • Can Be Inefficient • Network traffic • Job organization Thursday, March 14, 13


 mofurune
 optim
 deka_morita
 jame2408
 o0h
 rollbear
 minodriven
 econanringo
 taiseiue
 yumnumm
 rshindo
 y0hgi
 destraynor
 inesmontani
 mfonobong
 gurzu
 honzajavorek
 mkilby
 eileencodes
 tamaranovitovic
 sergeychernyshev
 codingconduct
 techseoconnect
 keathley