Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
ndb
Search
spicyj
May 28, 2014
Technology
140
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
ndb
spicyj
May 28, 2014
More Decks by spicyj
See All by spicyj
React: What Lies Ahead
spicyj
6
410
Creating interactive learning interfaces at Khan Academy
spicyj
0
130
Understanding state in React
spicyj
1
140
css
spicyj
2
890
Other Decks in Technology
See All in Technology
AI臭い文章とは何なのか
nasuvitz
22
30k
Kiro Meetup #8 Kiro アップデート (2026/3/21〜2026/9/24)
katzueno
1
290
AI coding 整合正規方法
philipz
0
560
2026-09-26 Platform Engineering Kaigi 2026 インフラとアプリの境界線と委譲の設計 / Drawing the Infra and App Line
masasuzu
0
350
Making AI Agents Safe and Fast- Jev, Obsidian, and the Meta-Harness
x5gtrn
PRO
0
160
いちAWSエンジニアのAI活用を振り返る #devio2026 / devio osaka 2026 kawahara
masahirokawahara
1
240
【データ横丁主催】AI Agentがコンテキストを使って仕事をした後、何が残るのか― 組織の経験を次の判断に引き継ぐ「Agent Memory」
shisyu_gaku
2
120
Amazon Bedrock Agents ClassicからAmazon Bedrock AgentCoreへ移行した際、ガードレール設定が2箇所に割れた話
matsunobu
0
140
2026-09-08 そのJavaモダナイゼーション、AIに丸投げで大丈夫?IBM Bobで変わる品質と効率
yutanonaka
1
210
AIは推し活である。
kurazuuuuuu
2
990
音声コミュニティを守るAI監視基盤_ 90%以上の入力削減を支えたServerless設計と運用判断
shuheioka123
0
110
メルカリにおけるAI時代の高速プロトタイピング基盤「Arca」
ryotarai
16
13k
Featured
See All Featured
Joys of Absence: A Defence of Solitary Play
codingconduct
1
530
Amusing Abliteration
ianozsvald
1
320
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.7k
A brief & incomplete history of UX Design for the World Wide Web: 1989–2019
jct
2
510
Stewardship and Sustainability of Urban and Community Forests
pwiseman
0
530
Improving Core Web Vitals using Speculation Rules API
sergeychernyshev
21
1.6k
The Limits of Empathy - UXLibs8
cassininazir
1
690
Designing for Performance
lara
611
70k
The Curse of the Amulet
leimatthew05
3
15k
Technical Leadership for Architectural Decision Making
baasie
3
580
Ten Tips & Tricks for a 🌱 transition
stuffmc
1
240
Have SEOs Ruined the Internet? - User Awareness of SEO in 2025
akashhashmi
0
510
Transcript
ndb “NDB is a better datastore API for the Google
App Engine Python runtime.”
Part 1 of 2
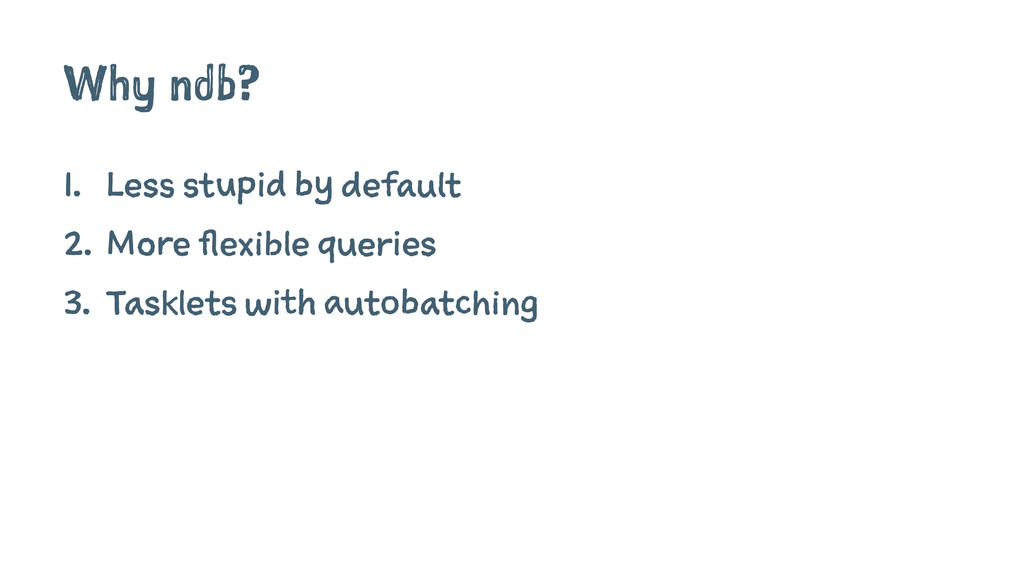
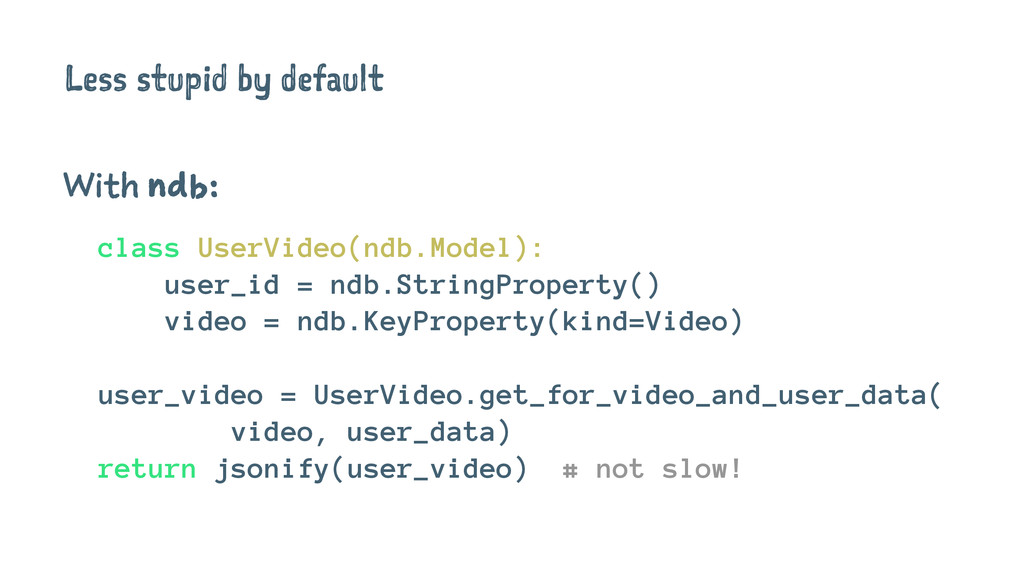
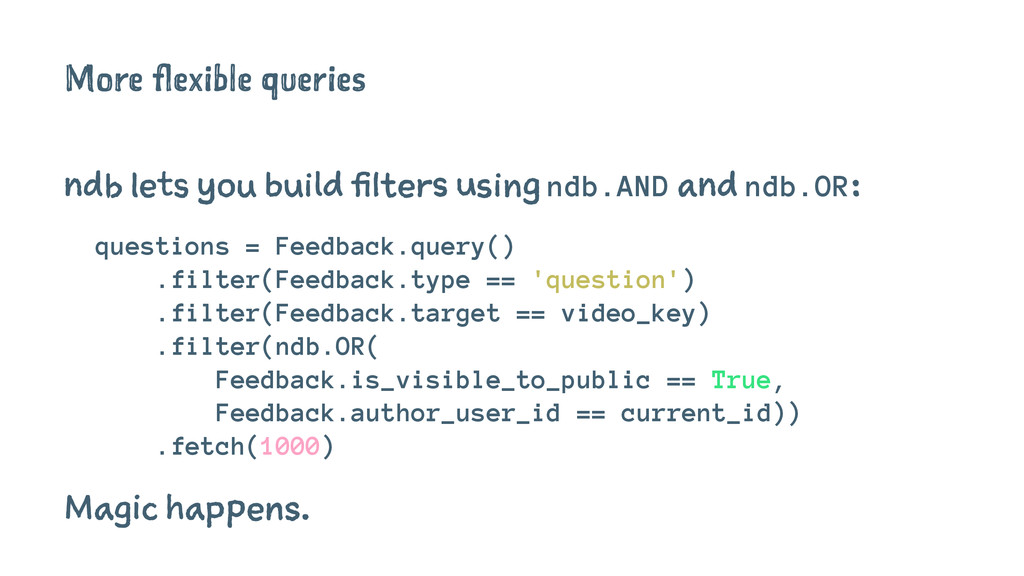
Why ndb? 1. Less stupid by default 2. More flexible
queries 3. Tasklets with autobatching
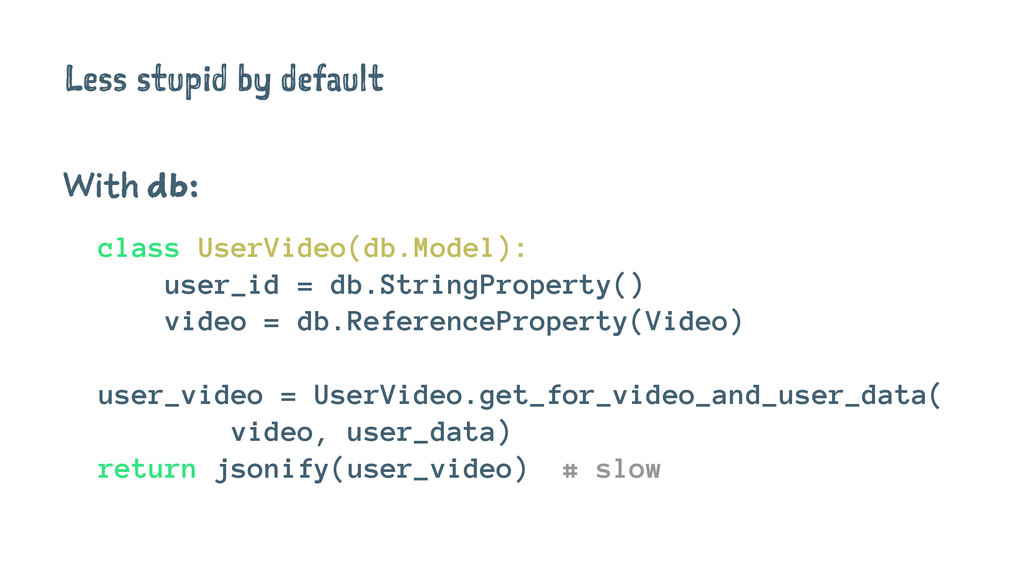
Less stupid by default With db: class UserVideo(db.Model): user_id =
db.StringProperty() video = db.ReferenceProperty(Video) user_video = UserVideo.get_for_video_and_user_data( video, user_data) return jsonify(user_video) # slow
Less stupid by default With ndb: class UserVideo(ndb.Model): user_id =
ndb.StringProperty() video = ndb.KeyProperty(kind=Video) user_video = UserVideo.get_for_video_and_user_data( video, user_data) return jsonify(user_video) # not slow!
More flexible queries ndb lets you build filters using ndb.AND
and ndb.OR: questions = Feedback.query() .filter(Feedback.type == 'question') .filter(Feedback.target == video_key) .filter(ndb.OR( Feedback.is_visible_to_public == True, Feedback.author_user_id == current_id)) .fetch(1000) Magic happens.
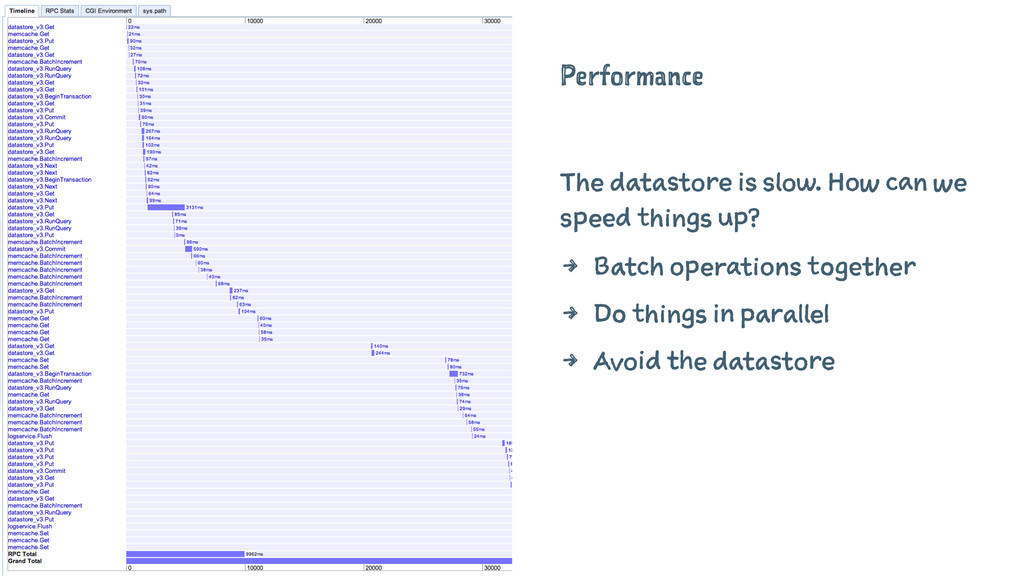
Performance The datastore is slow. How can we speed things
up? 4 Batch operations together 4 Do things in parallel 4 Avoid the datastore
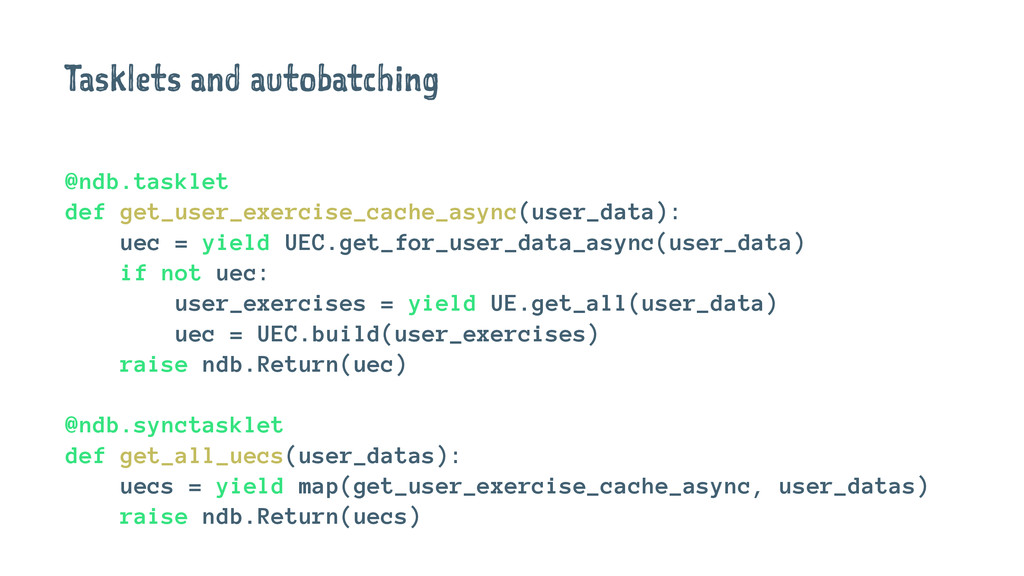
Tasklets and autobatching def get_user_exercise_cache(user_data): uec = UEC.get_for_user_data(user_data) if not
uec: user_exercises = UE.get_all(user_data) uec = UEC.build(user_exercises) return uec def get_all_uecs(user_datas): return map(get_user_exercise_cache, user_datas)
Tasklets and autobatching @ndb.tasklet def get_user_exercise_cache_async(user_data): uec = yield UEC.get_for_user_data_async(user_data)
if not uec: user_exercises = yield UE.get_all(user_data) uec = UEC.build(user_exercises) raise ndb.Return(uec) @ndb.synctasklet def get_all_uecs(user_datas): uecs = yield map(get_user_exercise_cache_async, user_datas) raise ndb.Return(uecs)
Moral ndb is awesome. Use it.
Part 2 of 2
The sad truth ndb isn't perfect.
Mysterious errors You heard from Marcia about this gem back
in March: TypeError: '_BaseValue' object is not subscriptable
Q: What's worse than code that doesn't work at all?
A: Code that mostly works but breaks in subtle ways.
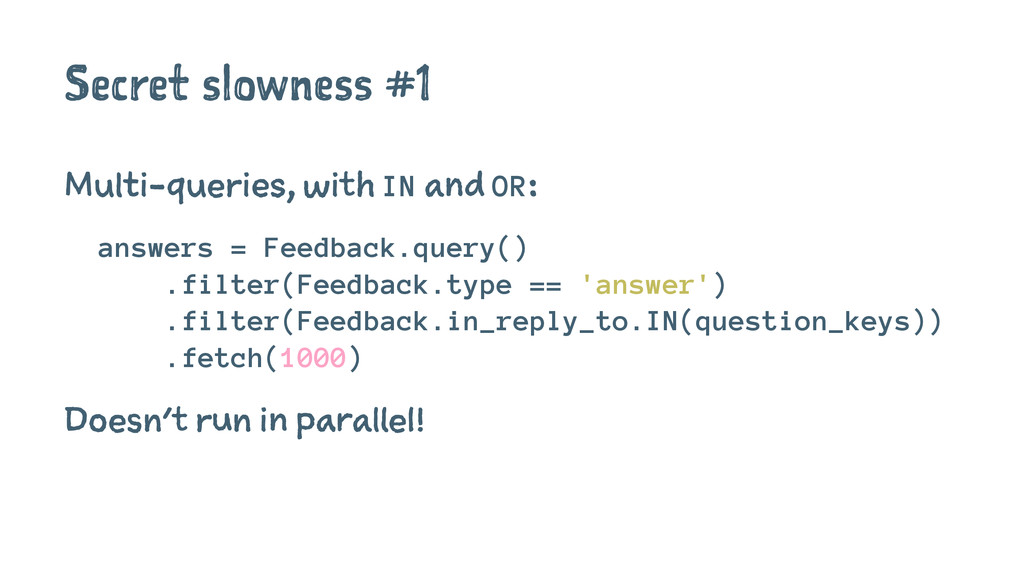
Secret slowness #1 Multi-queries, with IN and OR: answers =
Feedback.query() .filter(Feedback.type == 'answer') .filter(Feedback.in_reply_to.IN(question_keys)) .fetch(1000) Doesn't run in parallel!
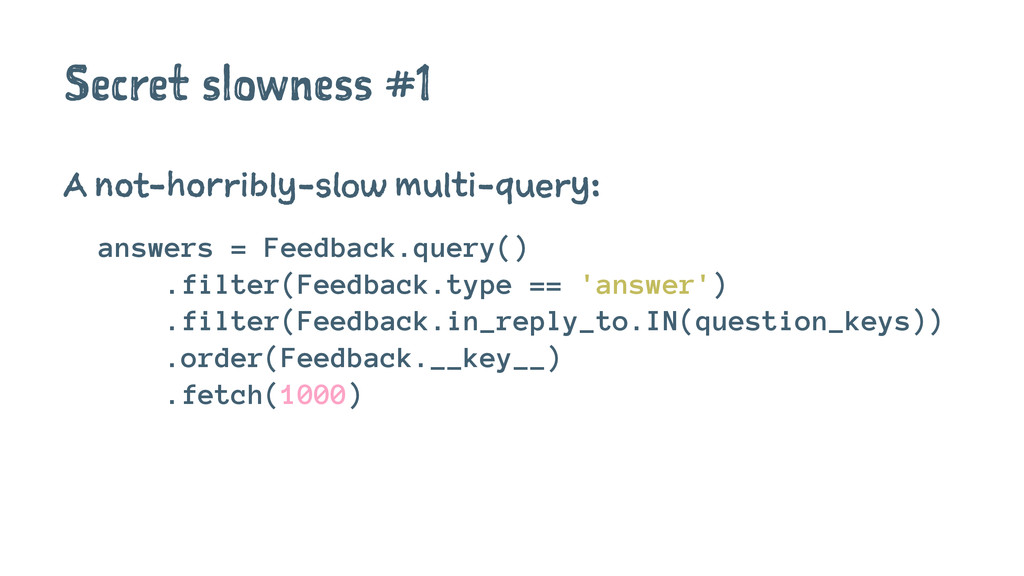
Secret slowness #1 A not-horribly-slow multi-query: answers = Feedback.query() .filter(Feedback.type
== 'answer') .filter(Feedback.in_reply_to.IN(question_keys)) .order(Feedback.__key__) .fetch(1000)
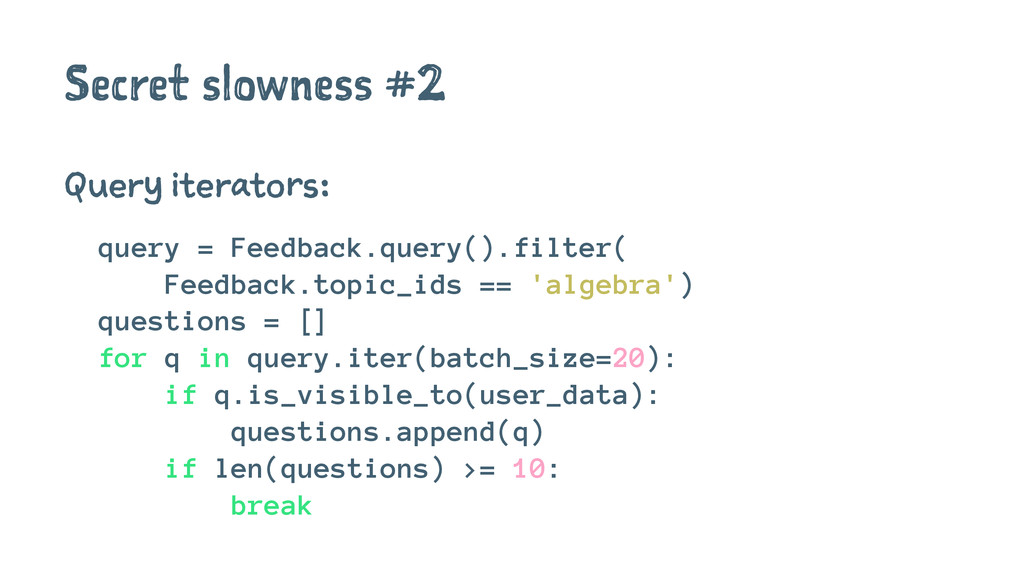
Secret slowness #2 Query iterators: query = Feedback.query().filter( Feedback.topic_ids ==
'algebra') questions = [] for q in query.iter(batch_size=20): if q.is_visible_to(user_data): questions.append(q) if len(questions) >= 10: break
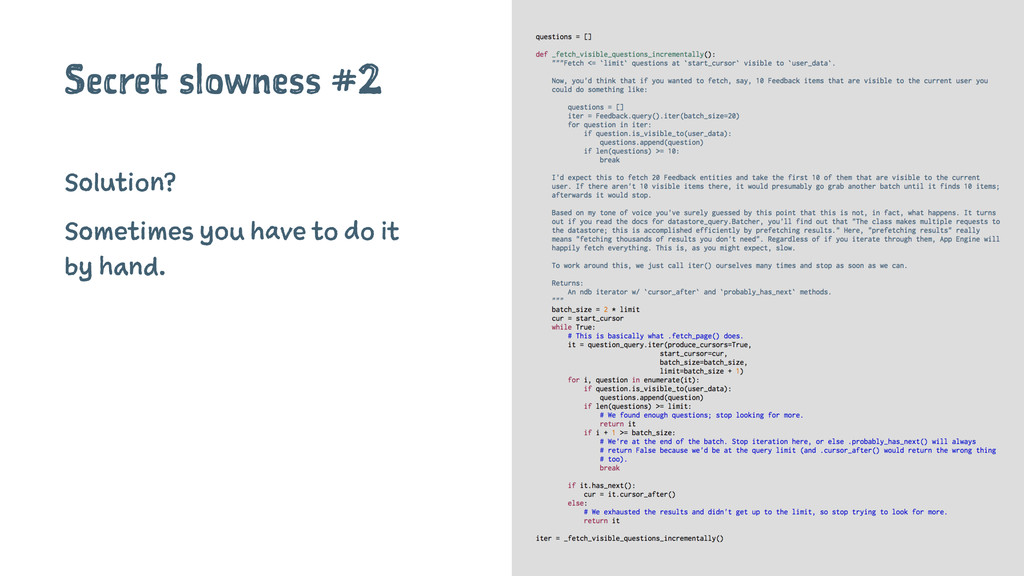
Secret slowness #2 Solution? Sometimes you have to do it
by hand.
Moral ndb isn't perfect. Pay attention. Profile your code.
The End


 spicyj
 nasuvitz
 katzueno
 philipz
 masasuzu
 x5gtrn
 masahirokawahara
 shisyu_gaku
 matsunobu
 yutanonaka
 kurazuuuuuu
 shuheioka123
 ryotarai
 codingconduct
 ianozsvald
 inesmontani
 jct
 pwiseman
 sergeychernyshev
 cassininazir
 lara
 leimatthew05
 baasie
 stuffmc
 akashhashmi