Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
研究室紹介用スライド: Unified Memoryを活⽤した効率的な計算⽅法を考えよう
Search
SuperHotDog
January 09, 2025
140
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
研究室紹介用スライド: Unified Memoryを活⽤した効率的な計算⽅法を考えよう
SuperHotDog
January 09, 2025
More Decks by SuperHotDog
See All by SuperHotDog
LLM高速化勉強会資料
superhotdogcat
9
3.3k
Dockerの裏側を攻める
superhotdogcat
0
47
SigLIP
superhotdogcat
1
150
post-training
superhotdogcat
3
680
大規模モデル計算の裏に潜む 並列分散処理について
superhotdogcat
1
92
オンプレソロプレイ
superhotdogcat
0
110
CUDAを触ろう
superhotdogcat
0
160
GemmaでRAG を作ろう
superhotdogcat
1
810
Featured
See All Featured
Chrome DevTools: State of the Union 2024 - Debugging React & Beyond
addyosmani
10
1.4k
Mobile First: as difficult as doing things right
swwweet
225
10k
Lightning Talk: Beautiful Slides for Beginners
inesmontani
PRO
2
770
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.7k
Practical Tips for Bootstrapping Information Extraction Pipelines
honnibal
25
2.2k
Between Models and Reality
mayunak
4
570
Unlocking the hidden potential of vector embeddings in international SEO
frankvandijk
0
1k
The Cult of Friendly URLs
andyhume
79
7.1k
Why You Should Never Use an ORM
jnunemaker
PRO
61
10k
Being A Developer After 40
akosma
PRO
92
590k
Context Engineering - Making Every Token Count
addyosmani
9
1.3k
Distributed Sagas: A Protocol for Coordinating Microservices
caitiem20
333
23k
Transcript
Unified Memoryを活⽤した効 率的な計算⽅法を考えよう SuperHotDogCat
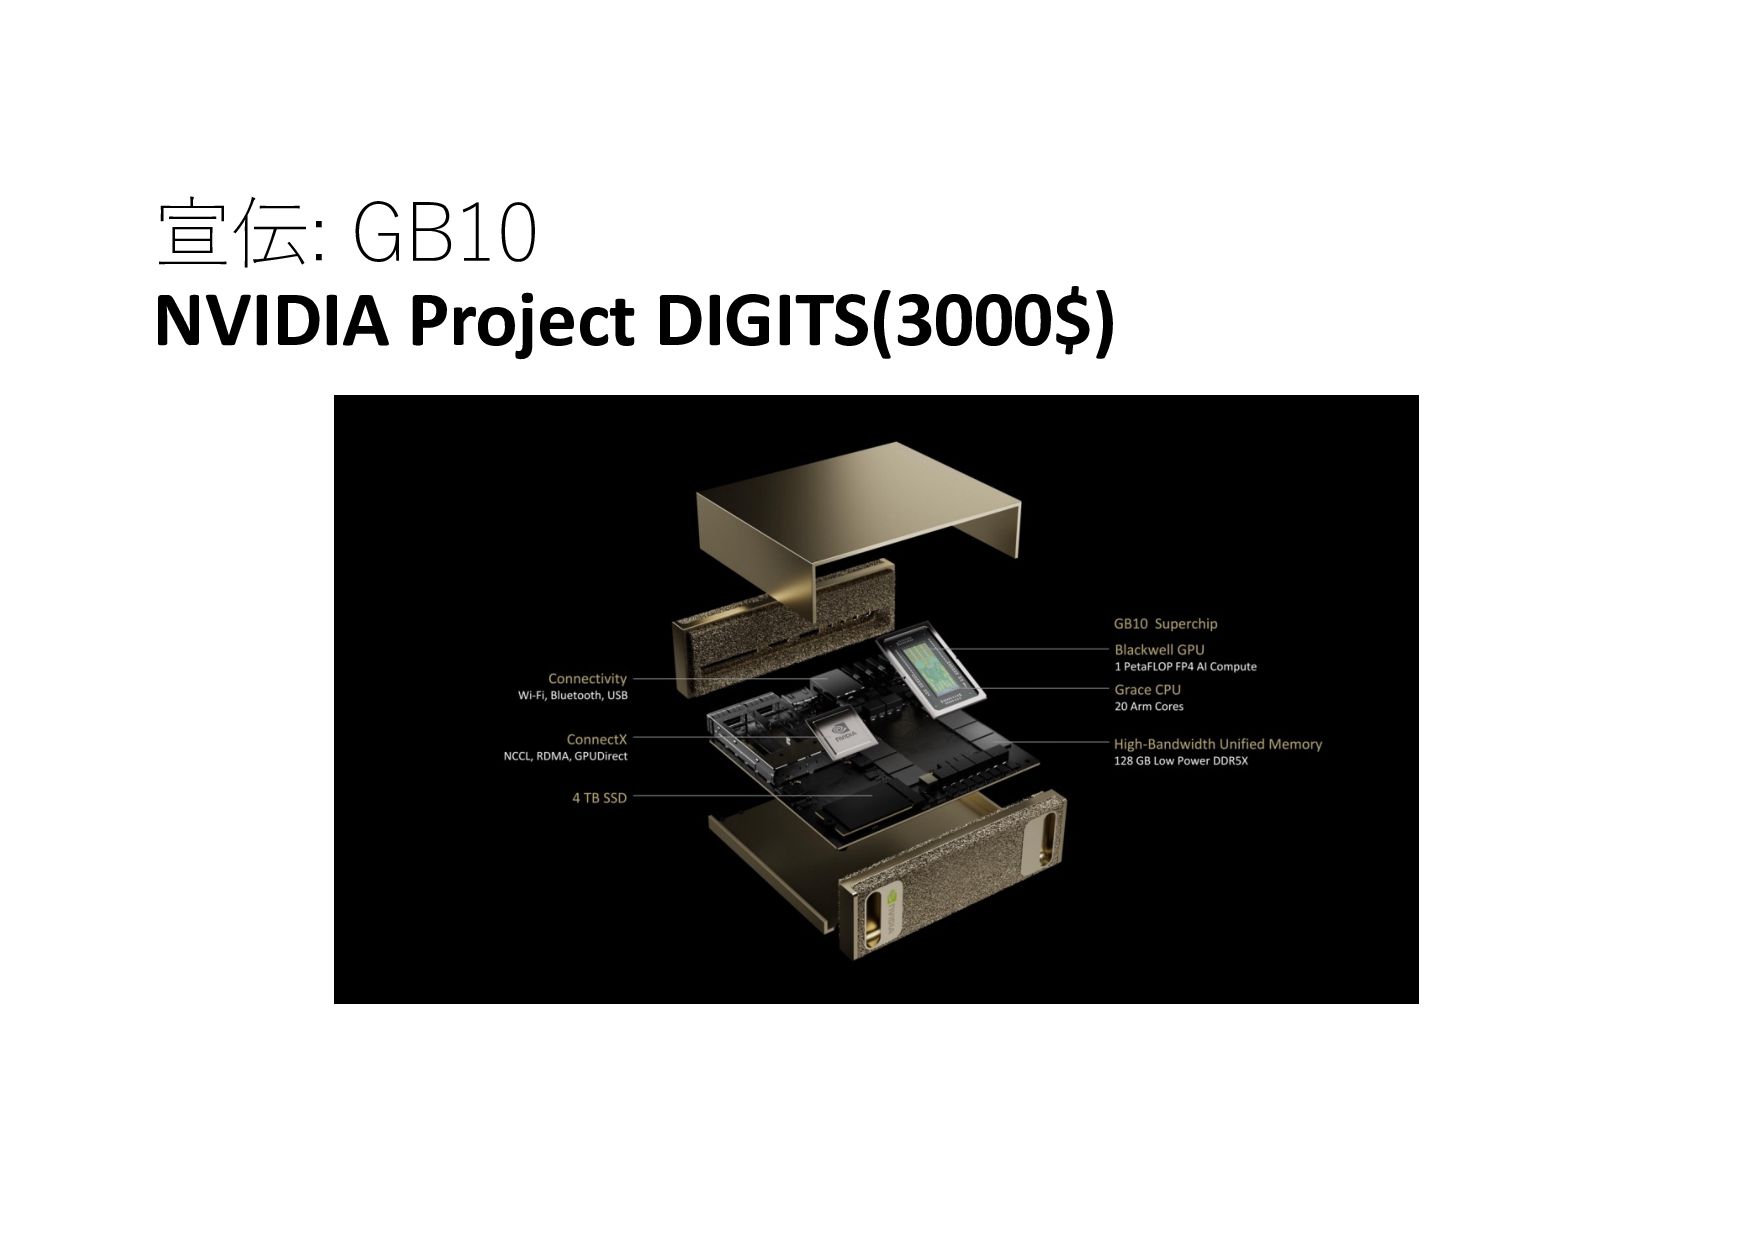
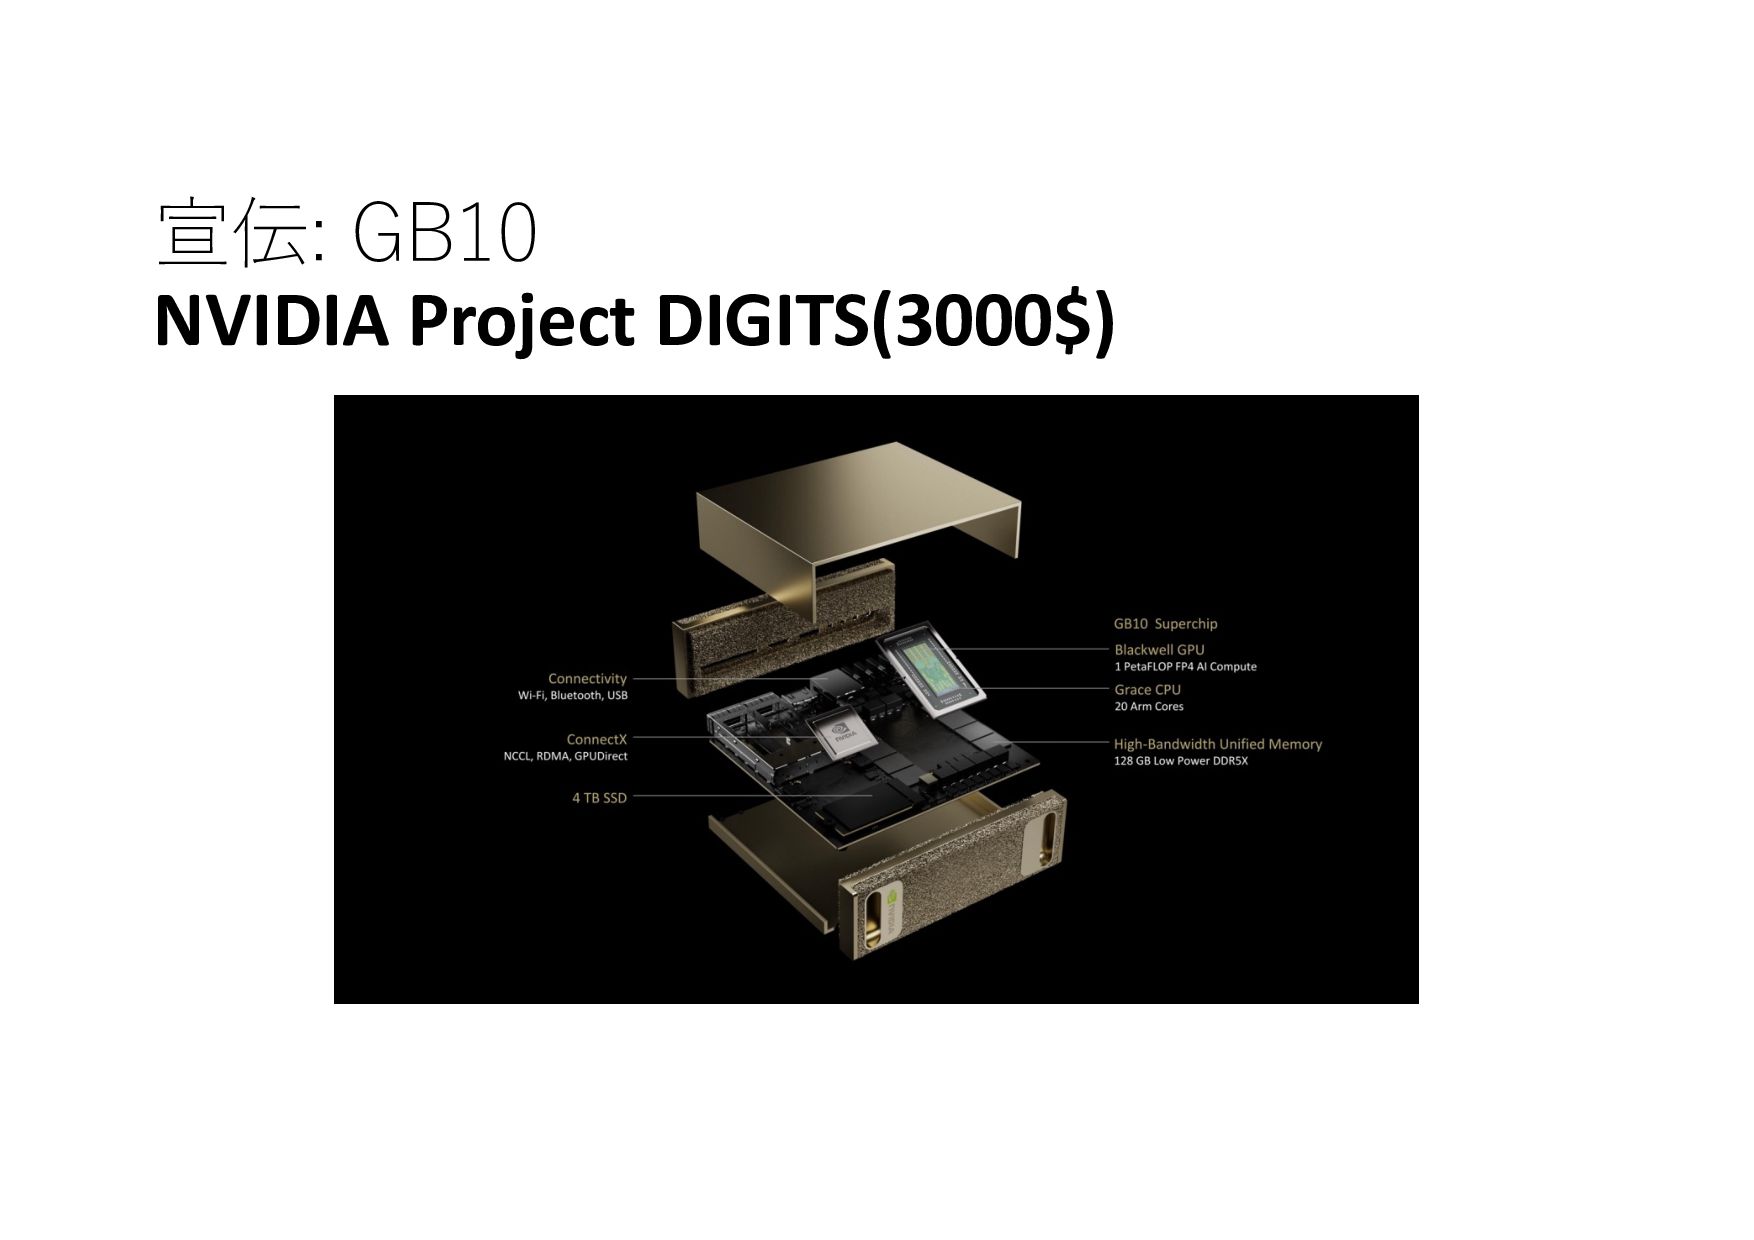
宣伝: GB10 NVIDIA Project DIGITS(3000$)
親の顔より⾒たエラー
何故起きるのか ・GPUメモリが⾜り ない →複数枚積めばいい のか?
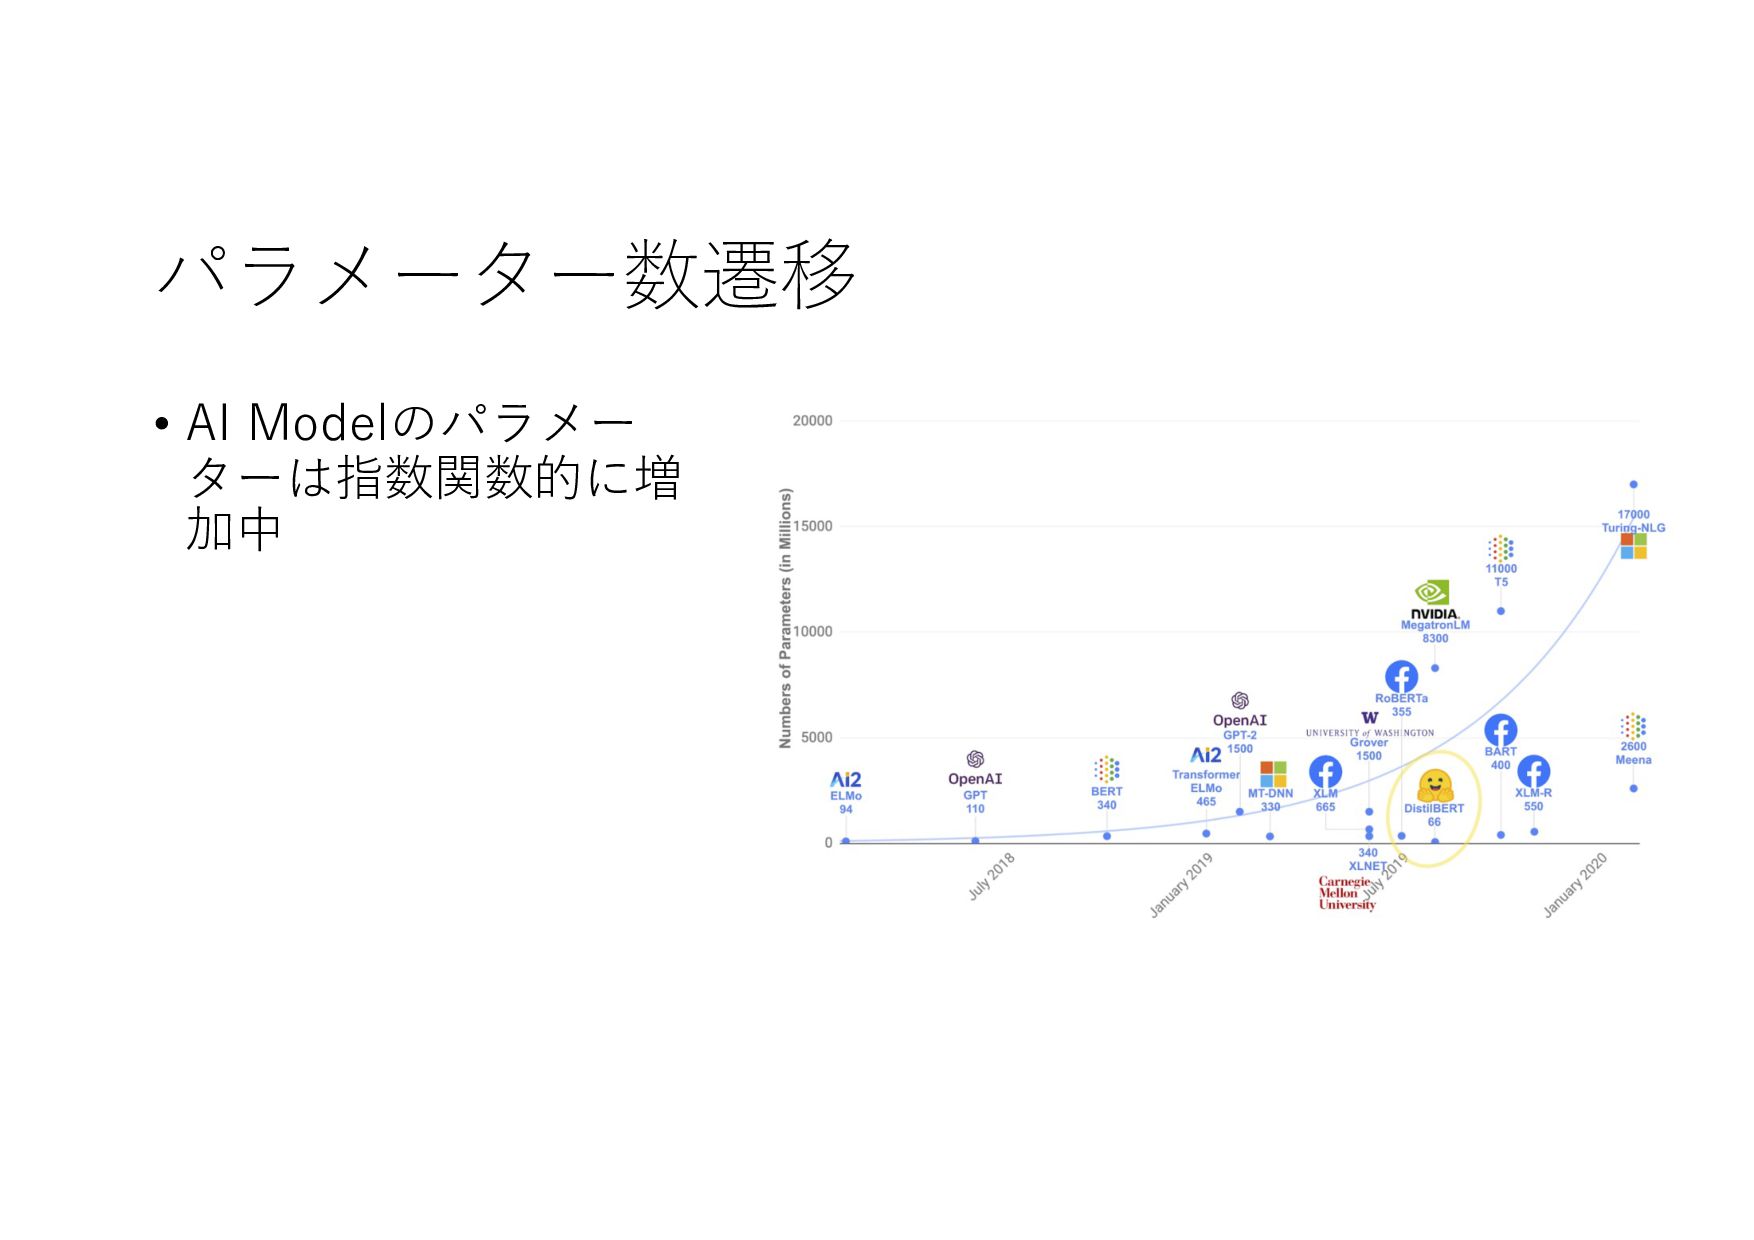
パラメーター数遷移 • AI Modelのパラメー ターは指数関数的に増 加中
VRAMは? ・V100 32GB(2017) ・A100 80GB(2020) ・H100 80GB(2022) ・H200 141GB(2024) ・B200
180GB/192GB(2024) ・1B Model → float32で4GB, fullでの訓練はAdam Optimizerで 16倍ぐらいになるので64GB必要 ・100B Modelで6.4TBのGPU必要 ・1T Modelだと640TB, 苦しい
省メモリへのアプローチ ・量⼦化(1/2~1/4倍削減), 枝刈り(1/2倍削減程度)←精度劣化が 避けられない, 枝刈りは推論のみでしか使えない(Edgeデバイス では依然として重要) ・アルゴリズム的な削減 ・再計算(Gradient Checkpointing) ・Flash
attention ↑厳密計算かつメモリ削減でGood ・複数台に分散 ・Megatron-LM, Deepspeedなどが開発ではよく使われる
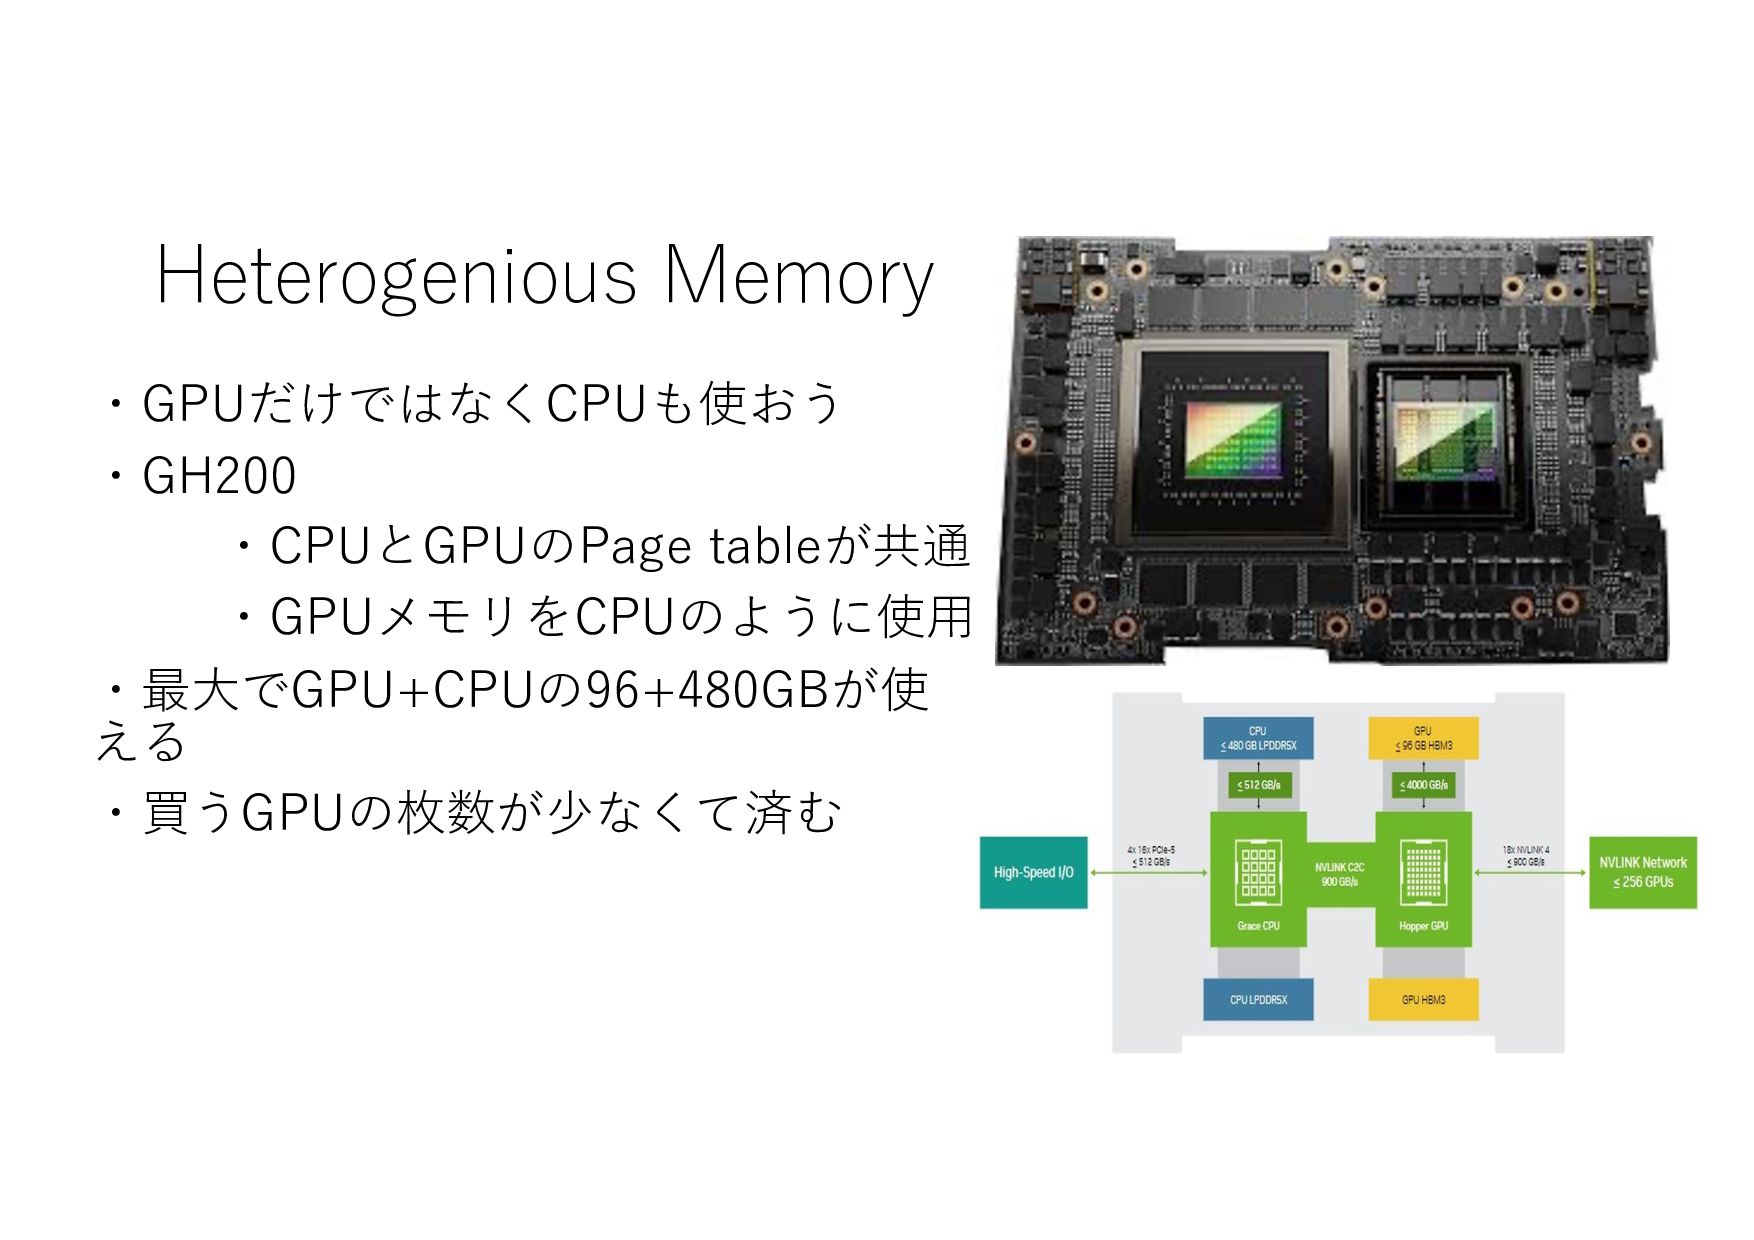
Heterogenious Memory ・GPUだけではなくCPUも使おう ・GH200 ・CPUとGPUのPage tableが共通 ・GPUメモリをCPUのように使⽤ ・最⼤でGPU+CPUの96+480GBが使 える ・買うGPUの枚数が少なくて済む
問題点 ・ソフトウェア上はGPUとCPUのメモリが同じように使える ・物理メモリ的にどこに割り当てられているかで速度低下などが 起きる←速度向上のためにGPUを使うのだから本末転倒 ・頑張って両⽴する
宣伝: GB10 NVIDIA Project DIGITS(3000$)


 superhotdogcat
 addyosmani
 swwweet
 inesmontani
 irinanazarova
 honnibal
 mayunak
 frankvandijk
 andyhume
 jnunemaker
 akosma
 caitiem20