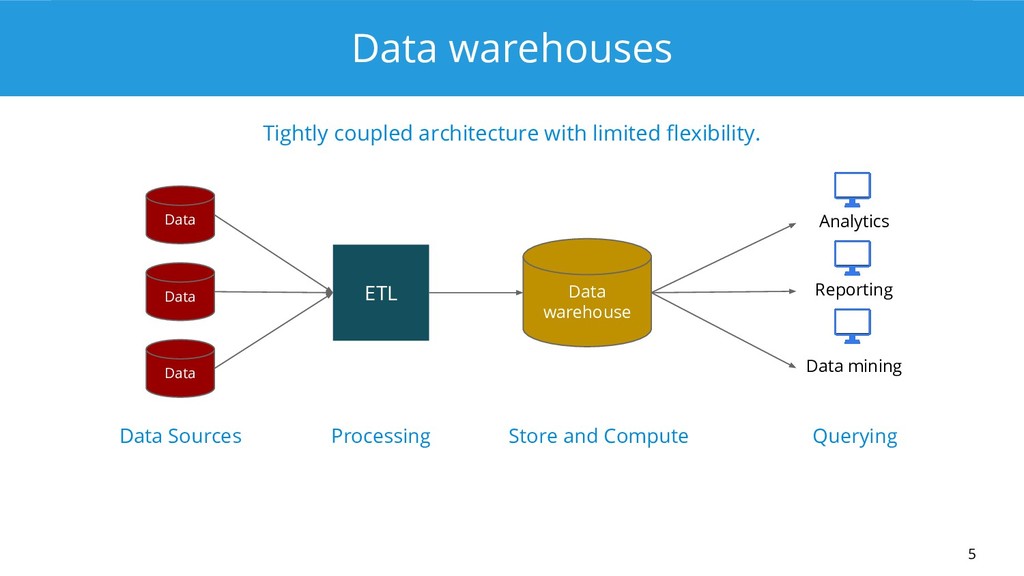
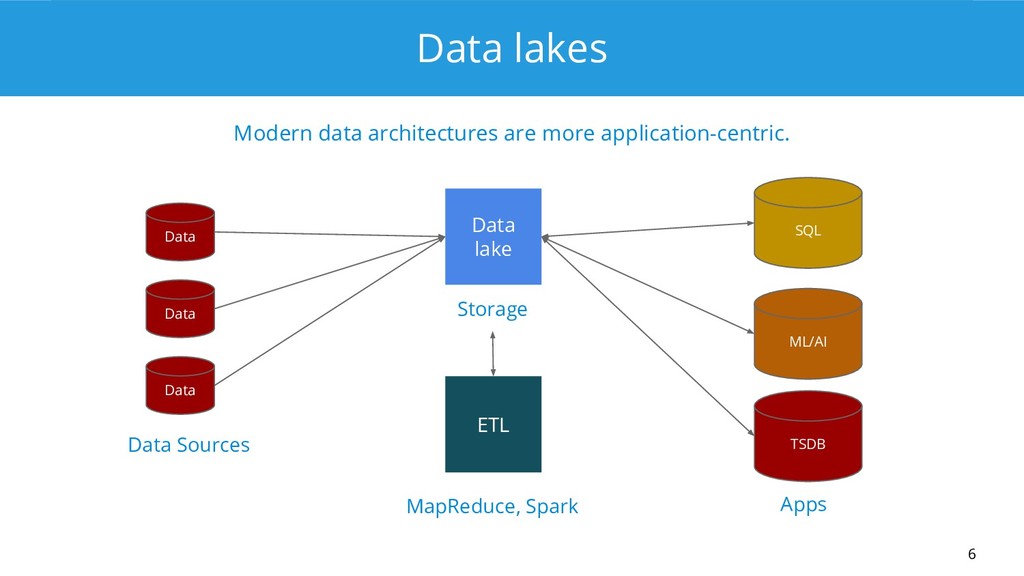
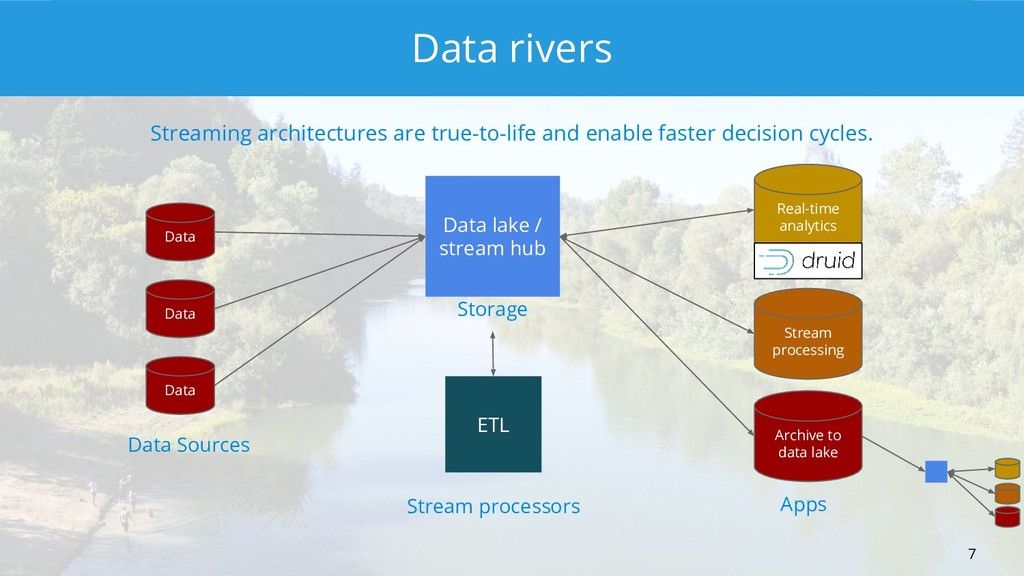
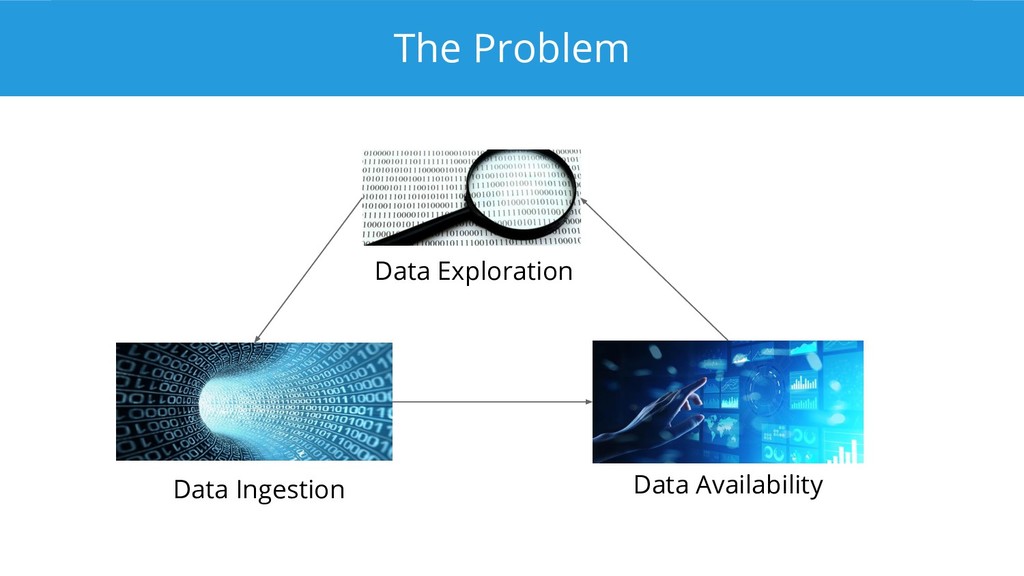
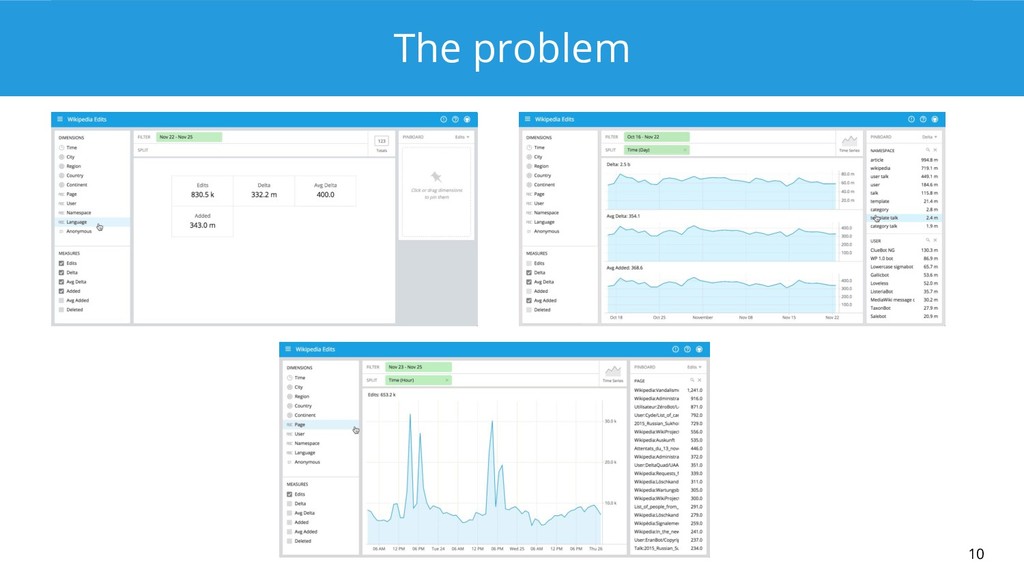
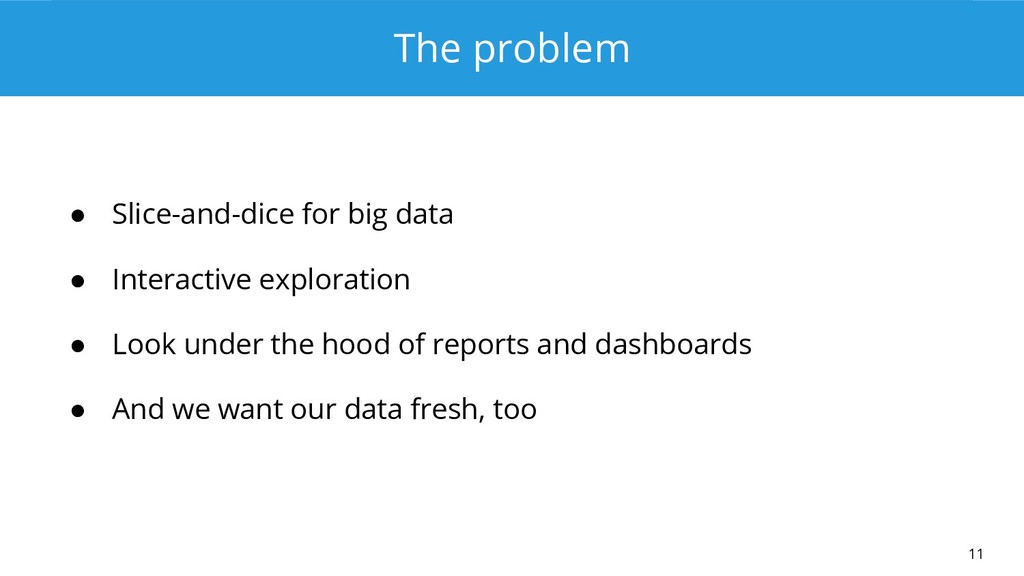
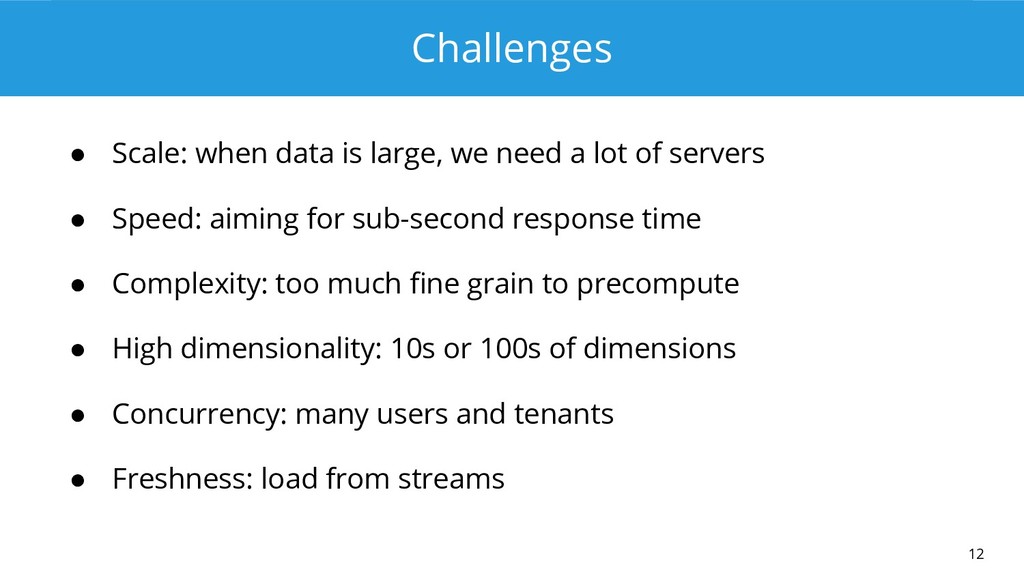
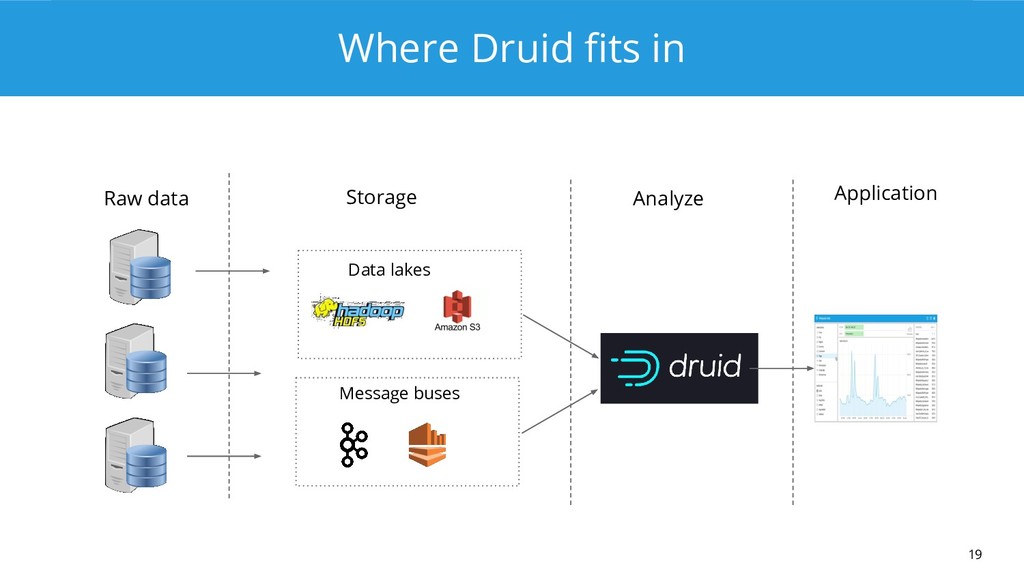
Data lake / stream hub Real-time analytics Stream processing ETL Storage Apps Archive to data lake Streaming architectures are true-to-life and enable faster decision cycles.
lot of servers • Speed: aiming for sub-second response time • Complexity: too much fine grain to precompute • High dimensionality: 10s or 100s of dimensions • Concurrency: many users and tenants • Freshness: load from streams 12
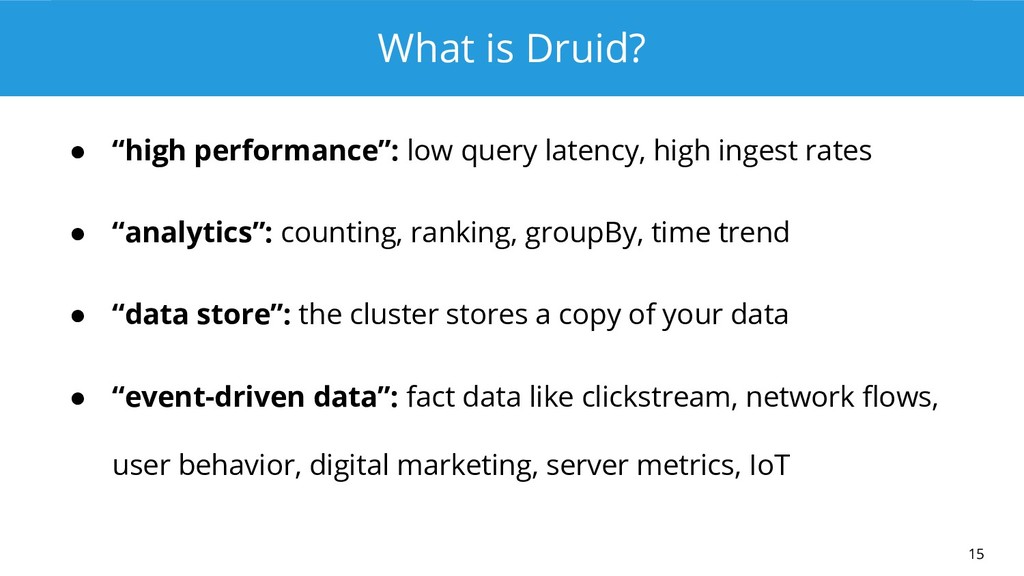
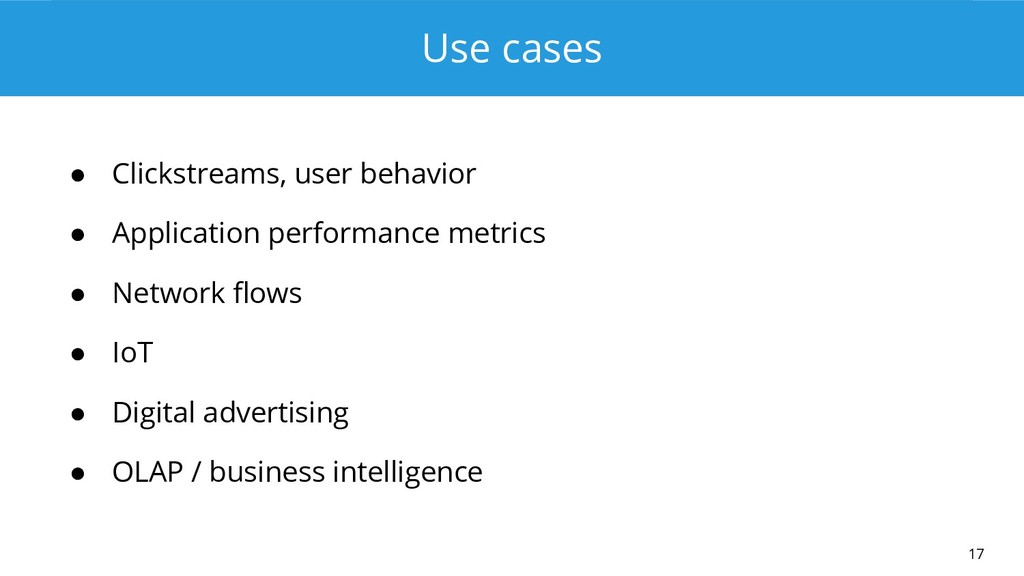
ingest rates • “analytics”: counting, ranking, groupBy, time trend • “data store”: the cluster stores a copy of your data • “event-driven data”: fact data like clickstream, network flows, user behavior, digital marketing, server metrics, IoT 15
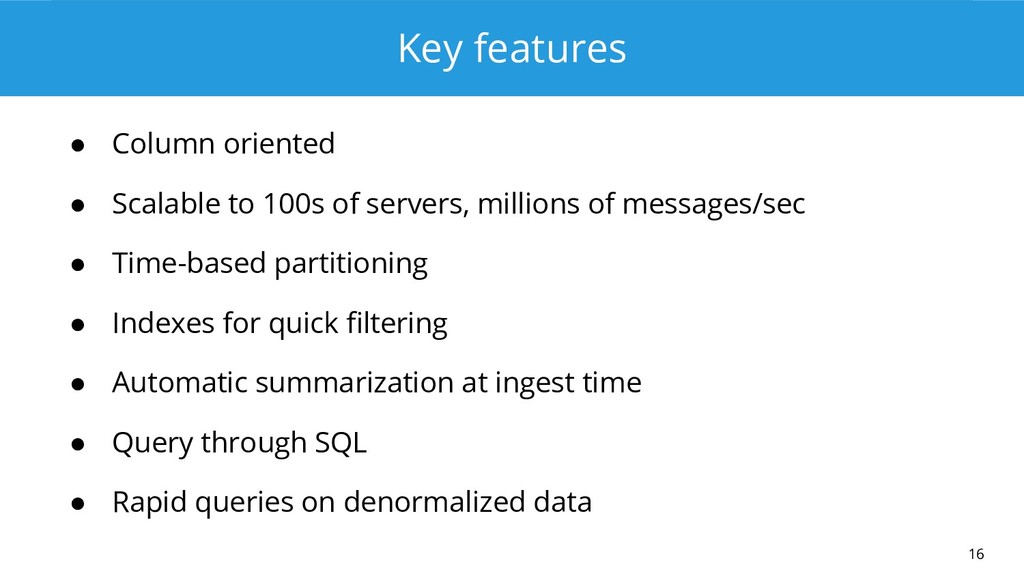
servers, millions of messages/sec • Time-based partitioning • Indexes for quick filtering • Automatic summarization at ingest time • Query through SQL • Rapid queries on denormalized data 16
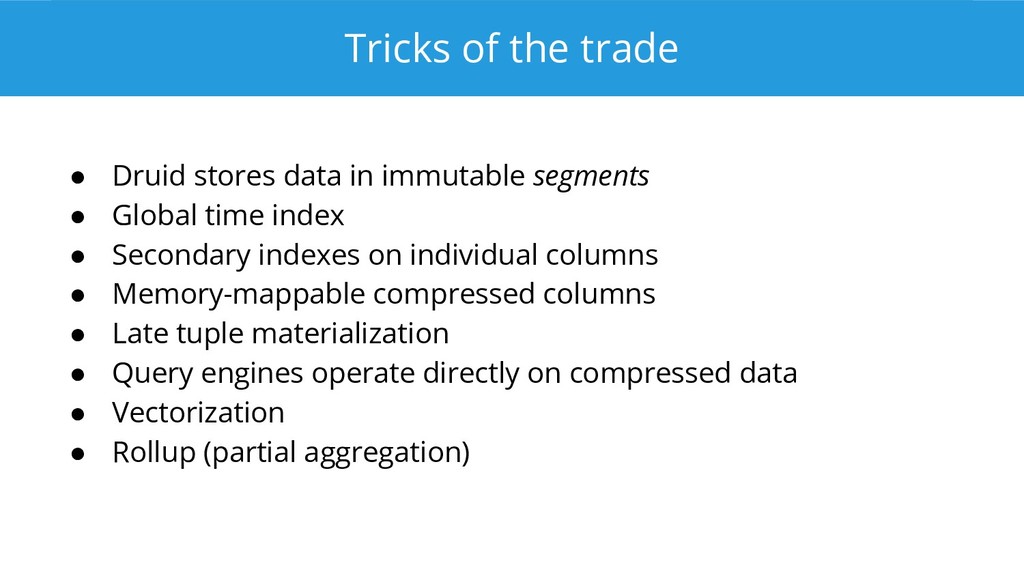
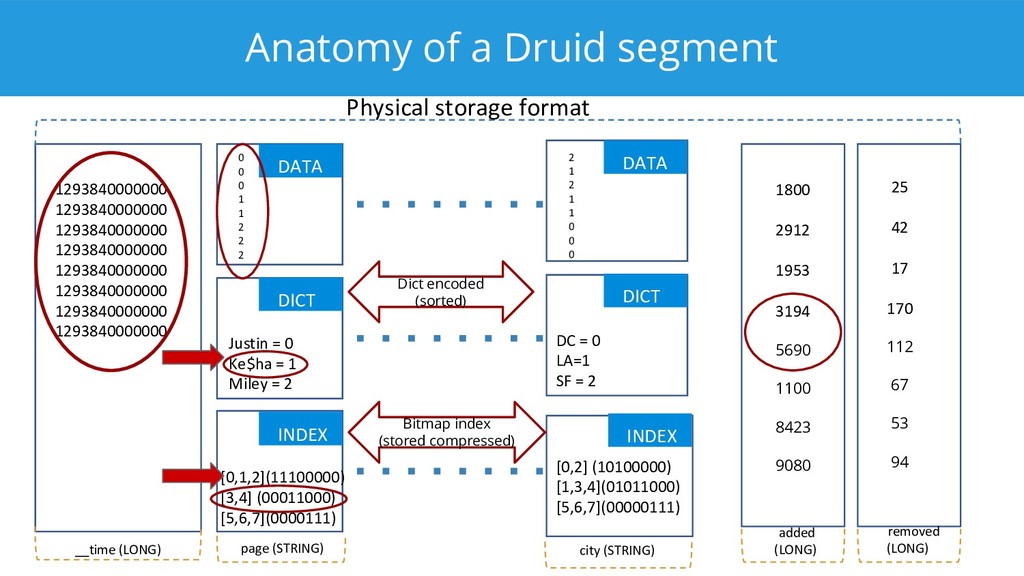
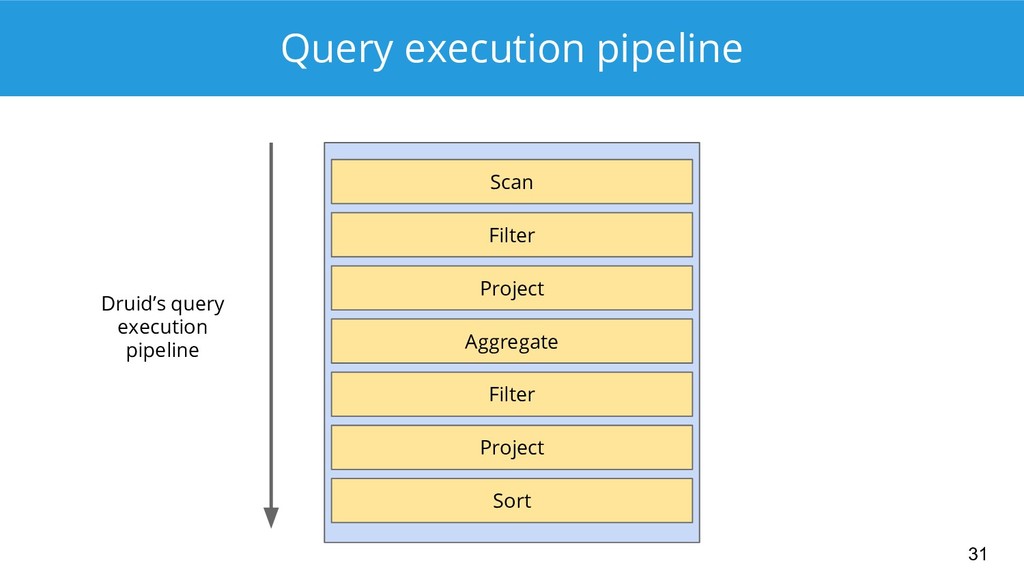
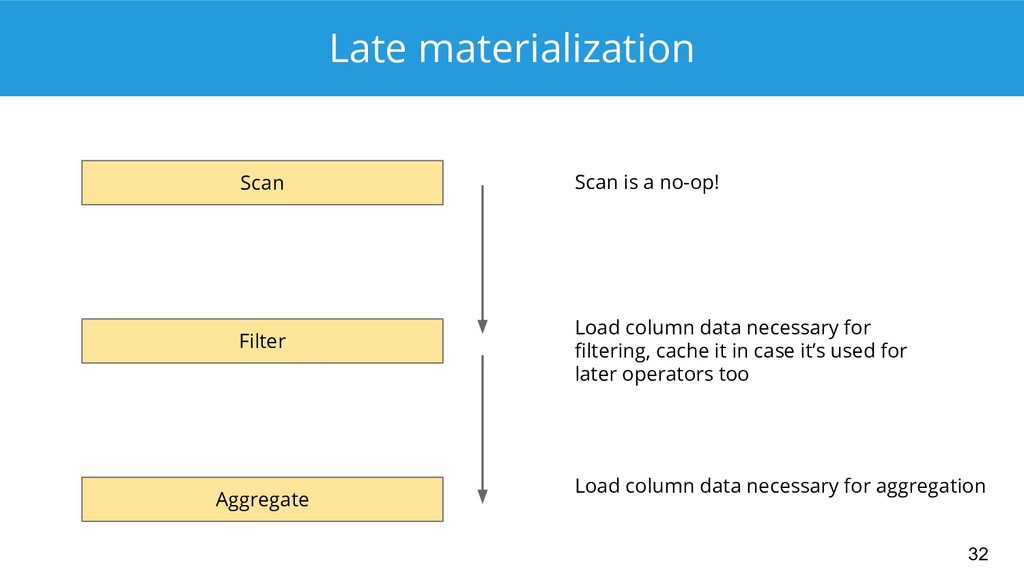
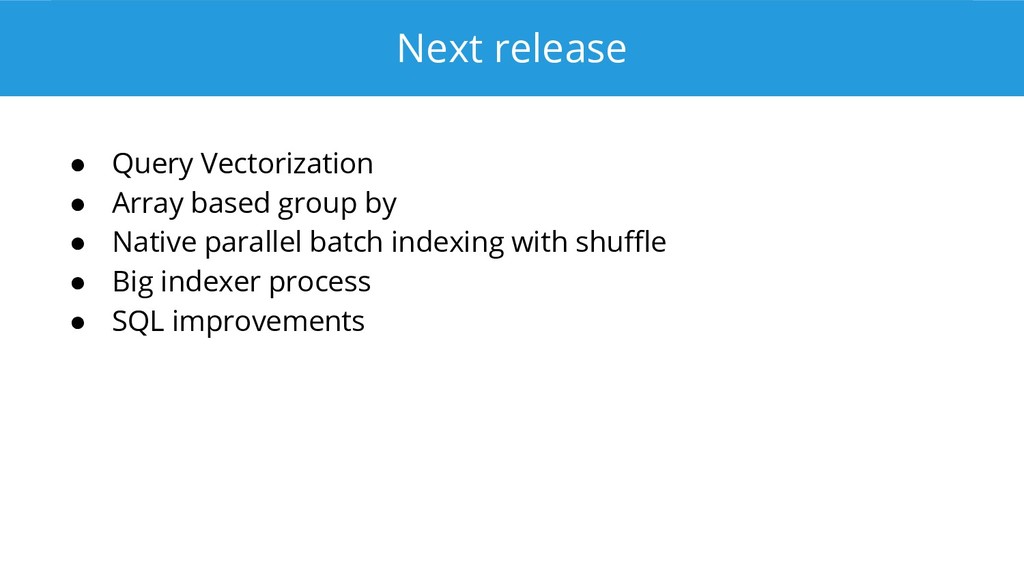
segments • Global time index • Secondary indexes on individual columns • Memory-mappable compressed columns • Late tuple materialization • Query engines operate directly on compressed data • Vectorization • Rollup (partial aggregation)
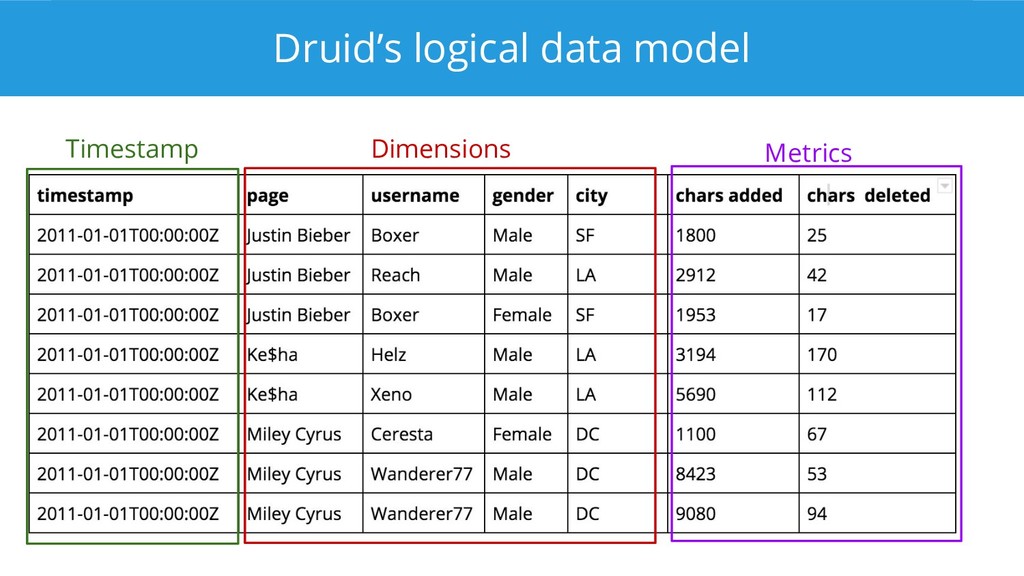
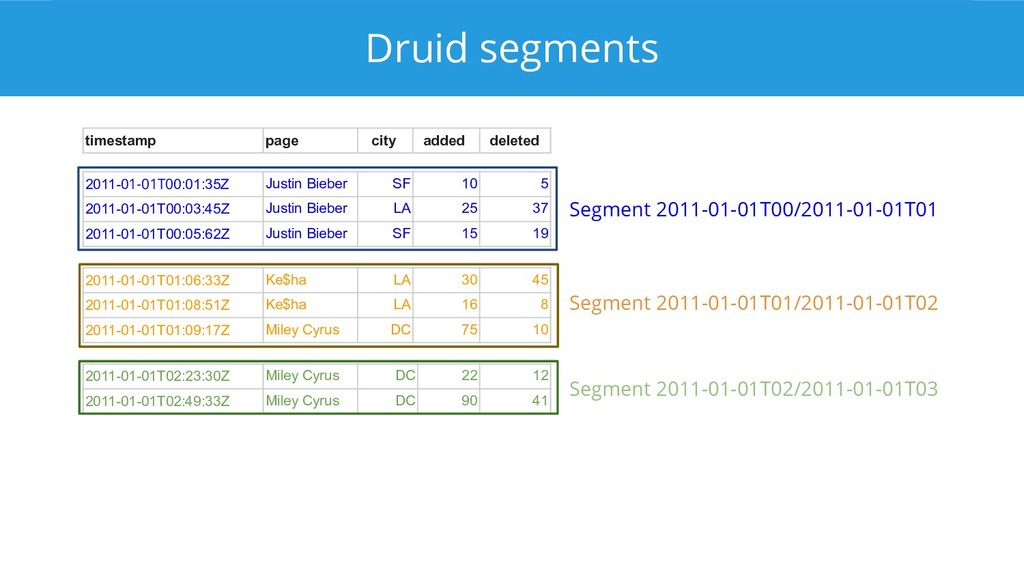
Bieber LA 25 37 2011-01-01T00:05:62Z Justin Bieber SF 15 19 2011-01-01T01:06:33Z Ke$ha LA 30 45 2011-01-01T01:08:51Z Ke$ha LA 16 8 2011-01-01T01:09:17Z Miley Cyrus DC 75 10 2011-01-01T02:23:30Z Miley Cyrus DC 22 12 2011-01-01T02:49:33Z Miley Cyrus DC 90 41 Segment 2011-01-01T00/2011-01-01T01 Segment 2011-01-01T01/2011-01-01T02 Segment 2011-01-01T02/2011-01-01T03 timestamp page city added deleted
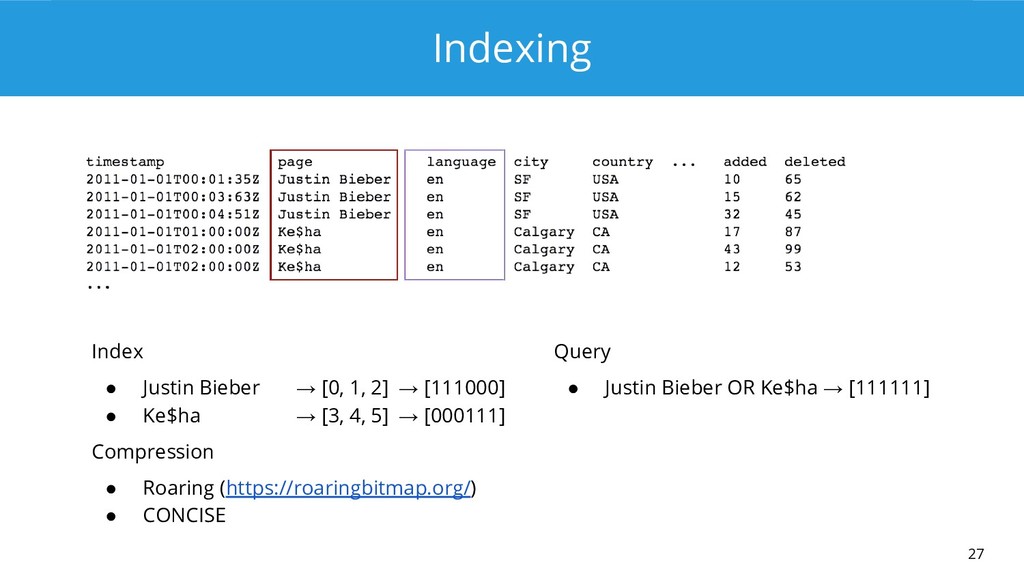
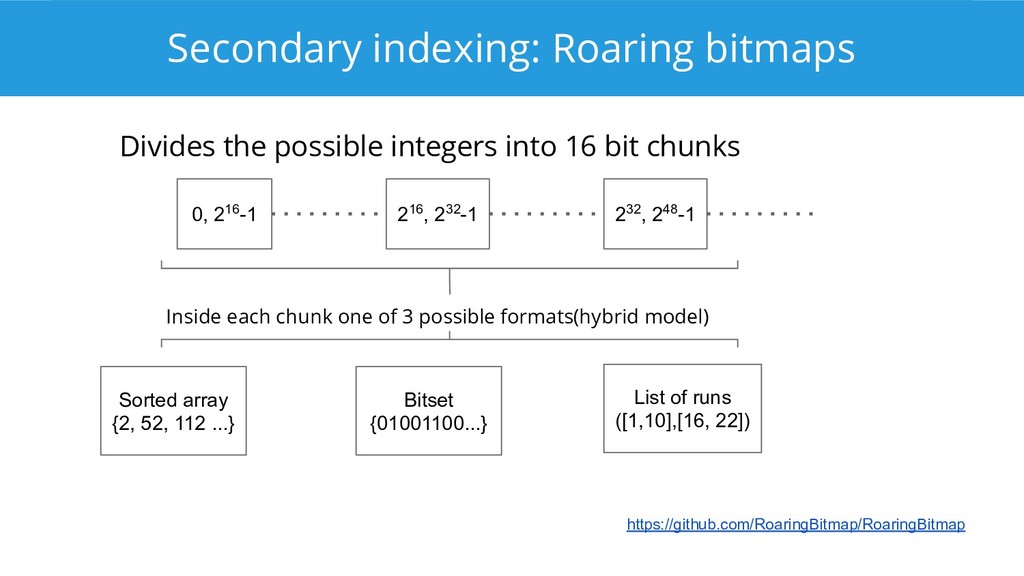
bit chunks 0, 216-1 216, 232-1 232, 248-1 Inside each chunk one of 3 possible formats(hybrid model) Sorted array {2, 52, 112 ...} Bitset {01001100...} List of runs ([1,10],[16, 22]) https://github.com/RoaringBitmap/RoaringBitmap
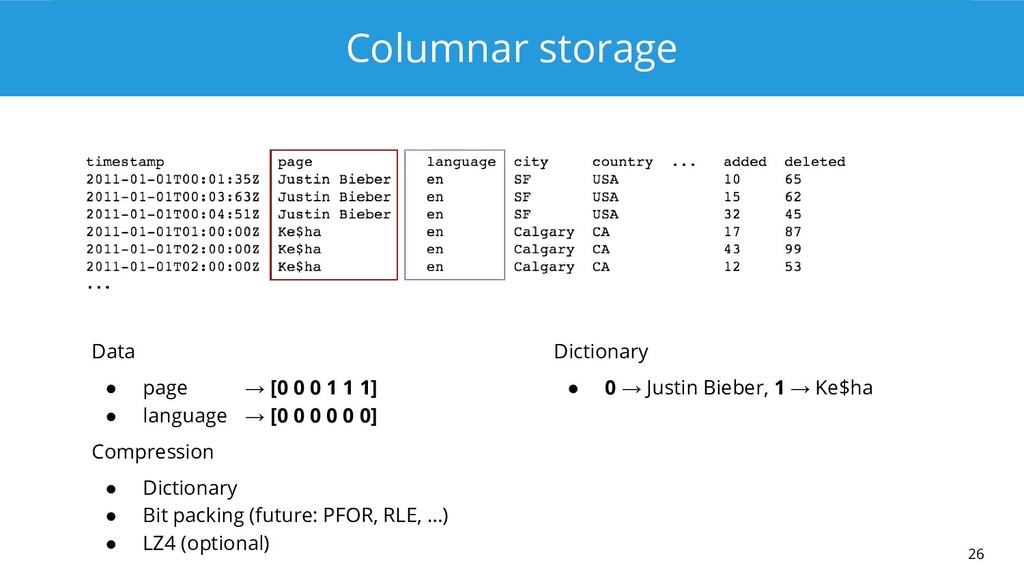
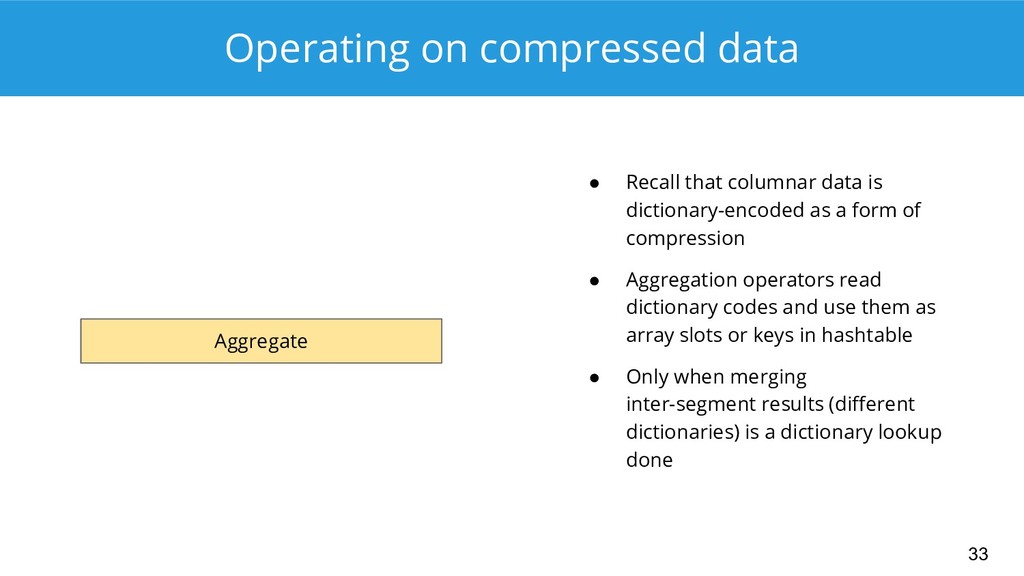
is dictionary-encoded as a form of compression • Aggregation operators read dictionary codes and use them as array slots or keys in hashtable • Only when merging inter-segment results (different dictionaries) is a dictionary lookup done Aggregate
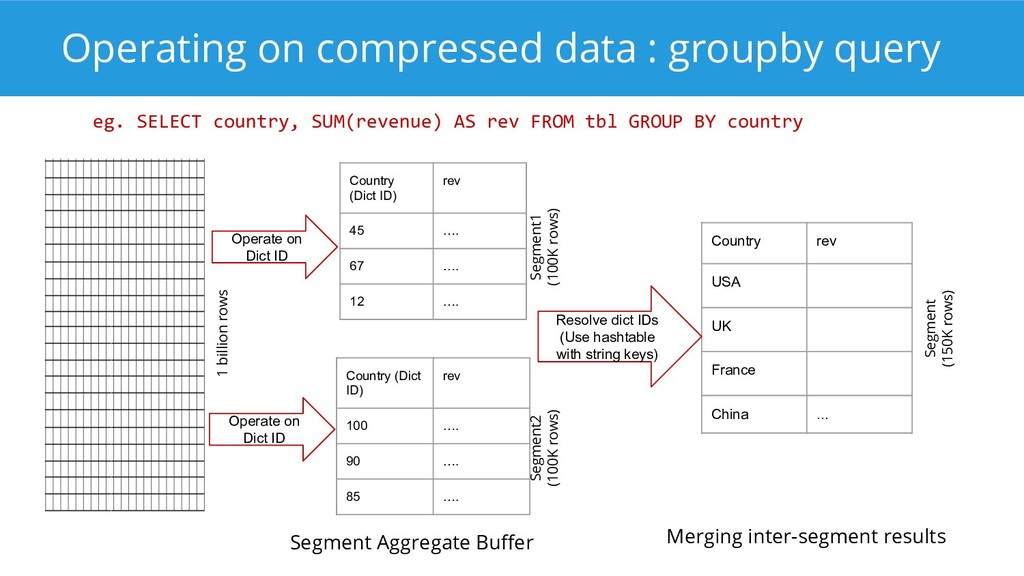
rev 100 …. 90 …. 85 …. Country rev USA UK France China ... Segment Aggregate Buffer Segment1 (100K rows) Segment2 (100K rows) Merging inter-segment results eg. SELECT country, SUM(revenue) AS rev FROM tbl GROUP BY country Country (Dict ID) rev 45 …. 67 …. 12 …. 1 billion rows Operate on Dict ID Operate on Dict ID Resolve dict IDs (Use hashtable with string keys) Segment (150K rows)
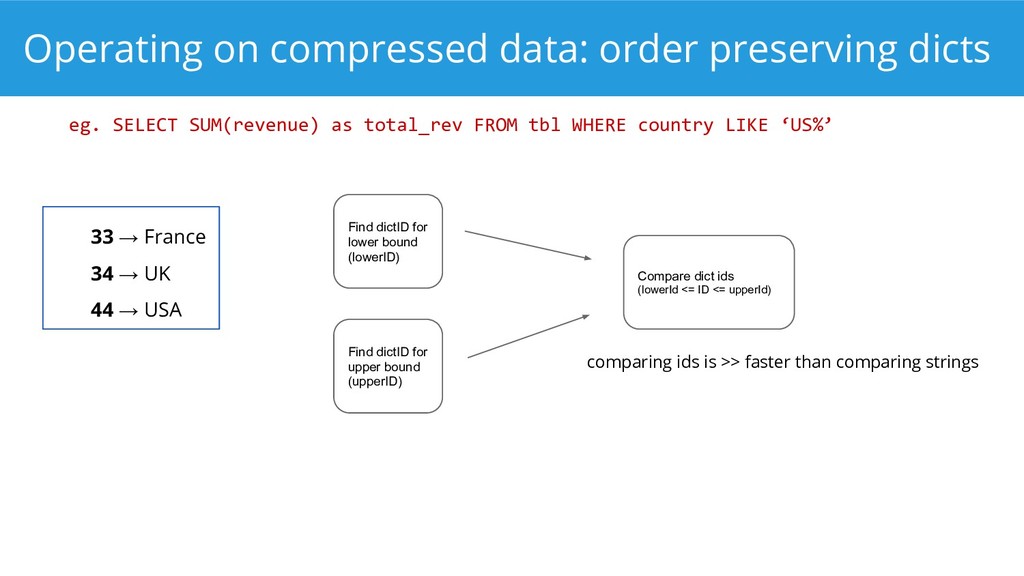
as total_rev FROM tbl WHERE country LIKE ‘US%’ Find dictID for lower bound (lowerID) Find dictID for upper bound (upperID) Compare dict ids (lowerId <= ID <= upperId) 33 → France 34 → UK 44 → USA comparing ids is >> faster than comparing strings
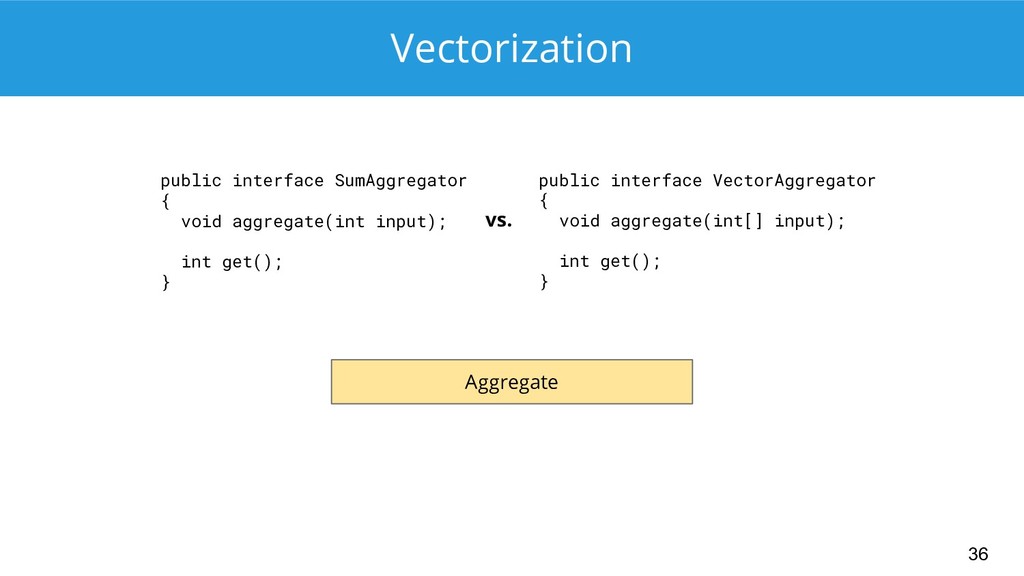
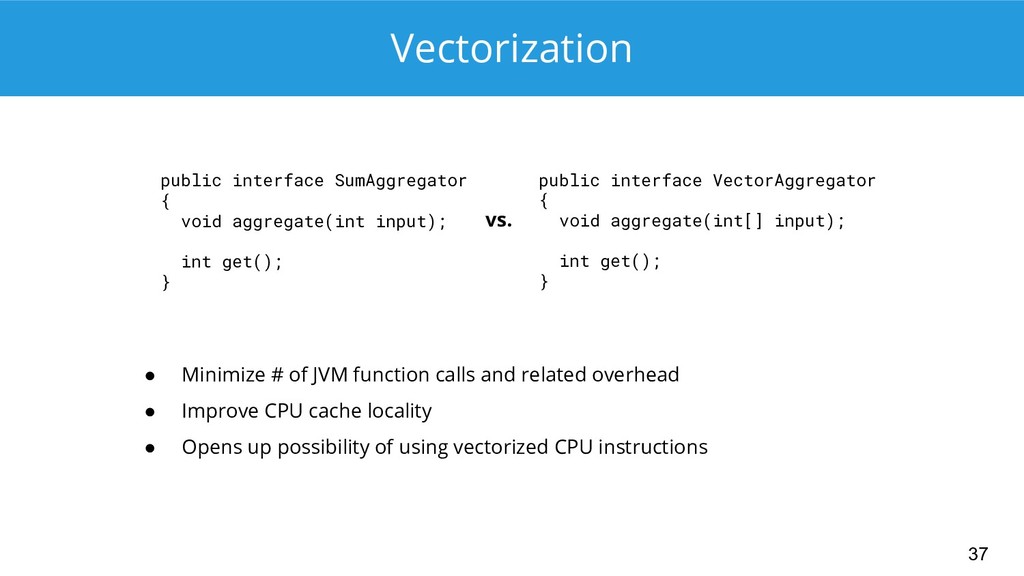
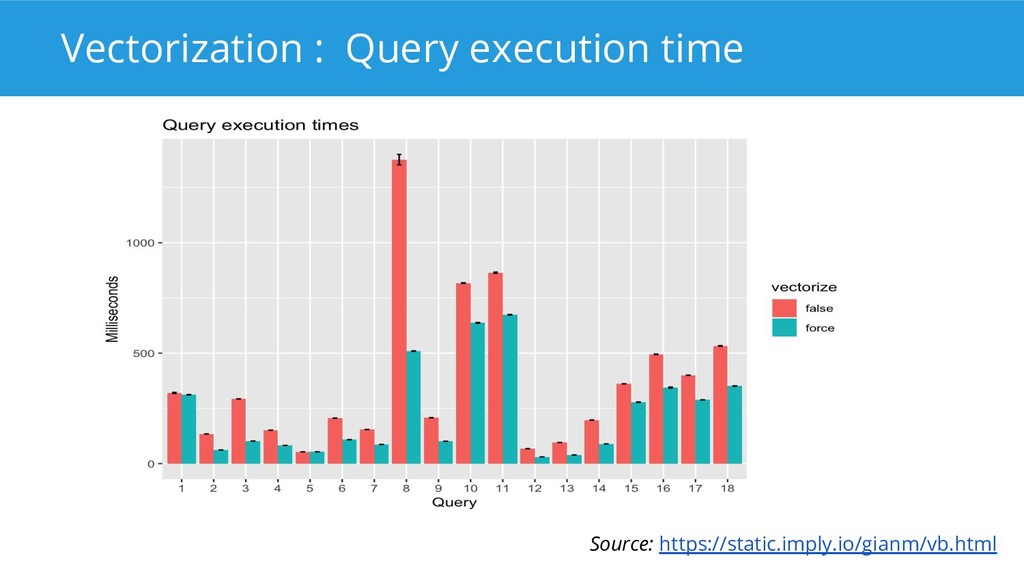
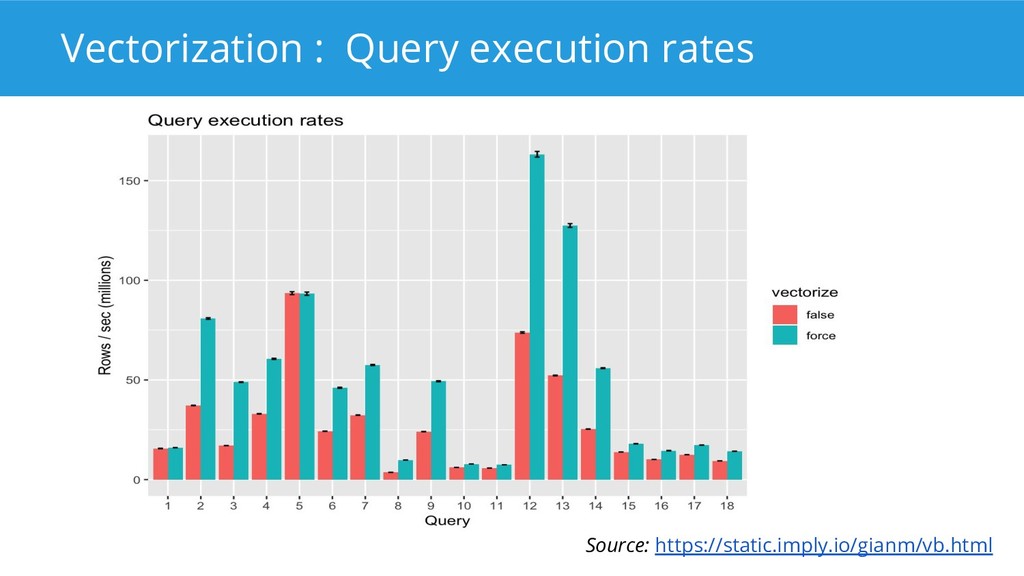
get(); } public interface VectorAggregator { void aggregate(int[] input); int get(); } vs. • Minimize # of JVM function calls and related overhead • Improve CPU cache locality • Opens up possibility of using vectorized CPU instructions
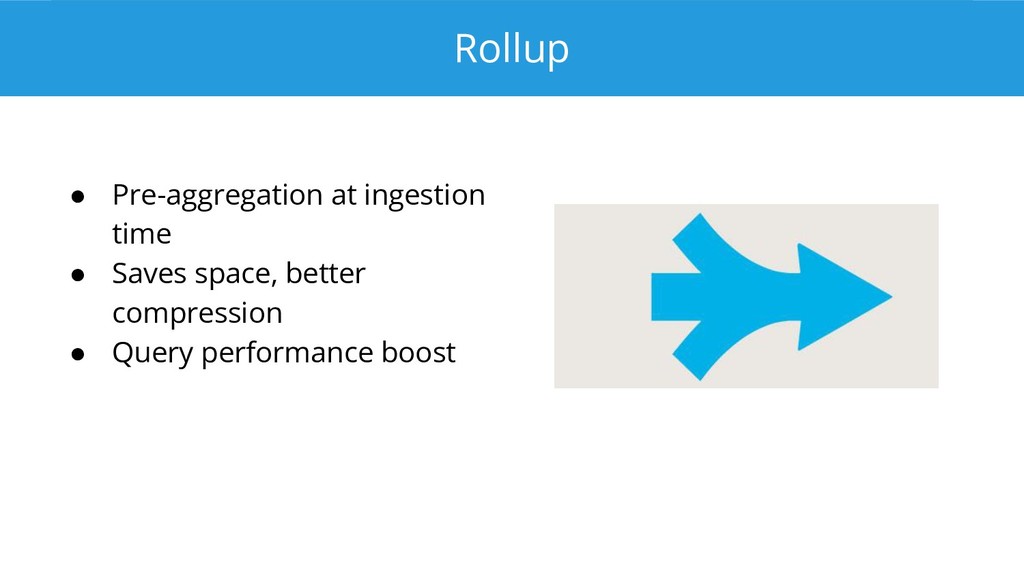
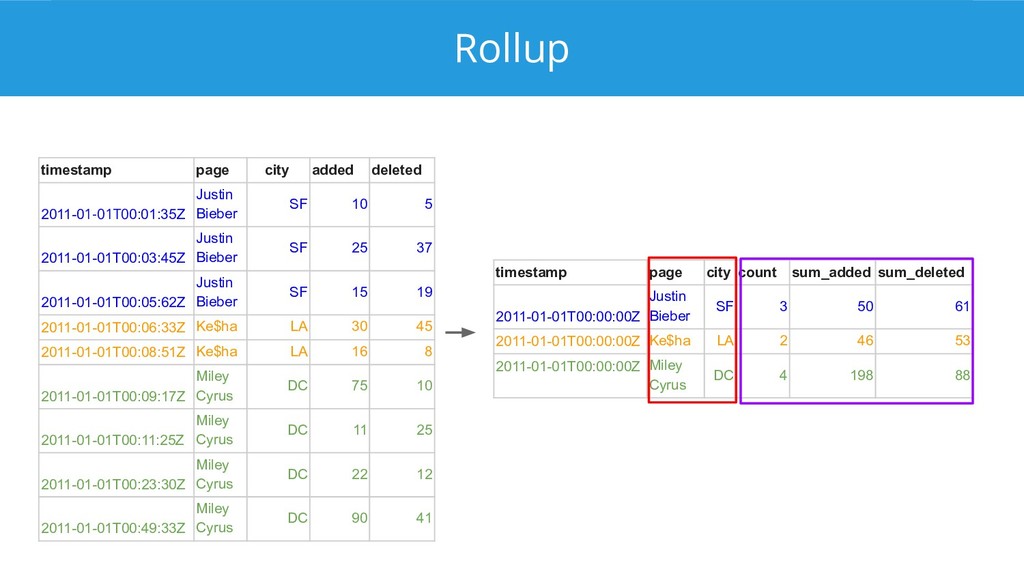
SF 3 50 61 2011-01-01T00:00:00Z Ke$ha LA 2 46 53 2011-01-01T00:00:00Z Miley Cyrus DC 4 198 88 timestamp page city added deleted 2011-01-01T00:01:35Z Justin Bieber SF 10 5 2011-01-01T00:03:45Z Justin Bieber SF 25 37 2011-01-01T00:05:62Z Justin Bieber SF 15 19 2011-01-01T00:06:33Z Ke$ha LA 30 45 2011-01-01T00:08:51Z Ke$ha LA 16 8 2011-01-01T00:09:17Z Miley Cyrus DC 75 10 2011-01-01T00:11:25Z Miley Cyrus DC 11 25 2011-01-01T00:23:30Z Miley Cyrus DC 22 12 2011-01-01T00:49:33Z Miley Cyrus DC 90 41
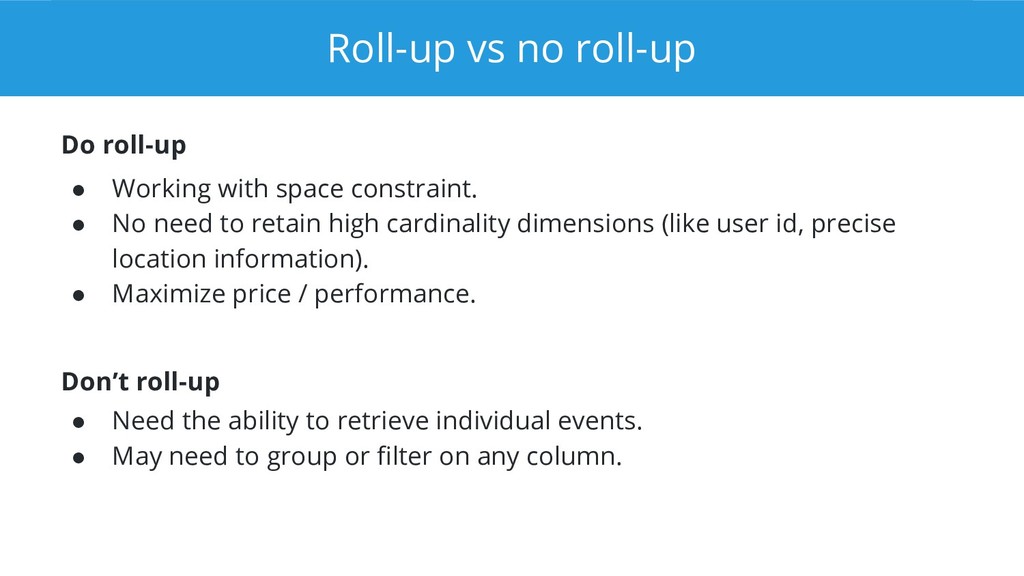
constraint. • No need to retain high cardinality dimensions (like user id, precise location information). • Maximize price / performance. Don’t roll-up • Need the ability to retrieve individual events. • May need to group or filter on any column.
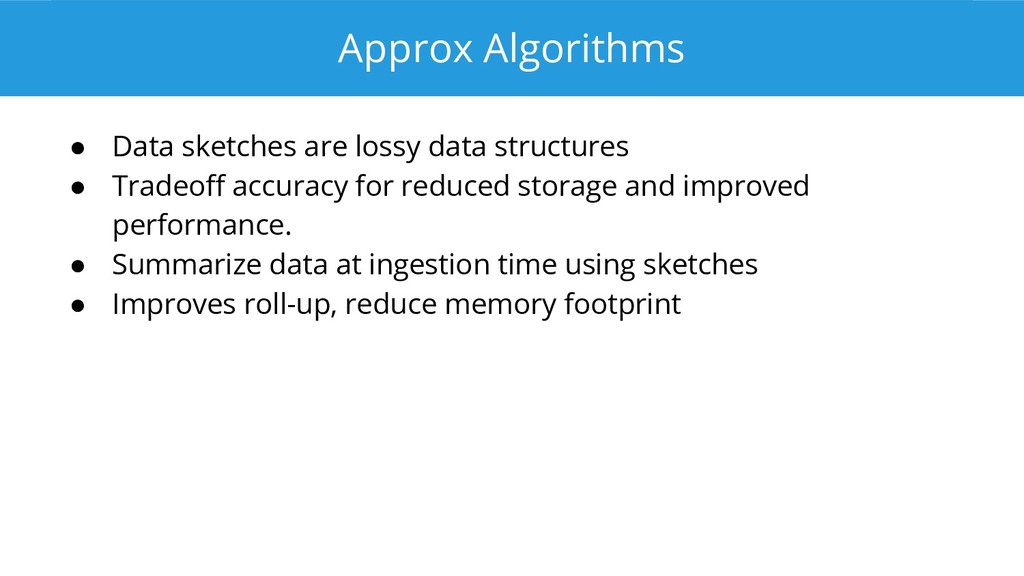
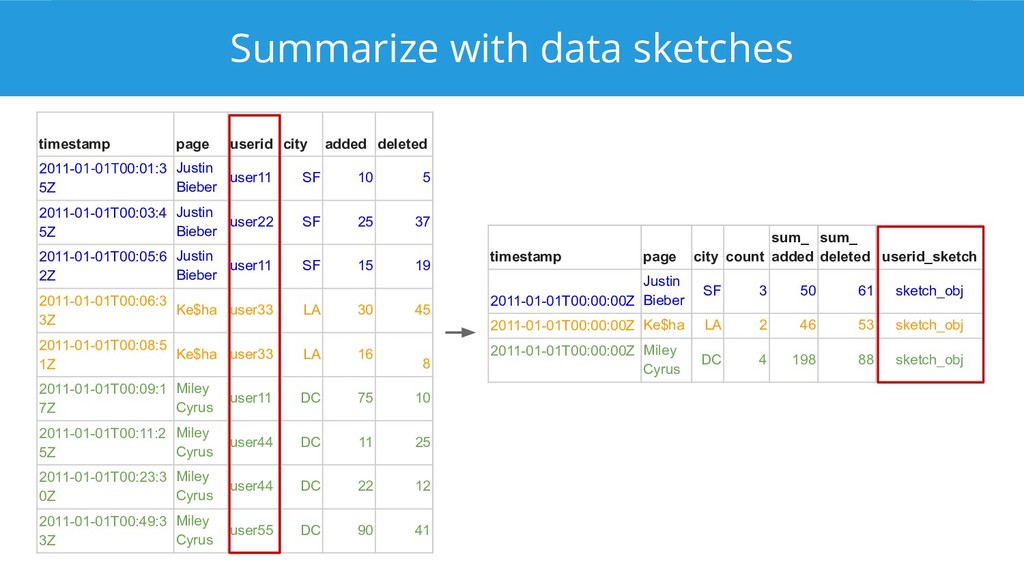
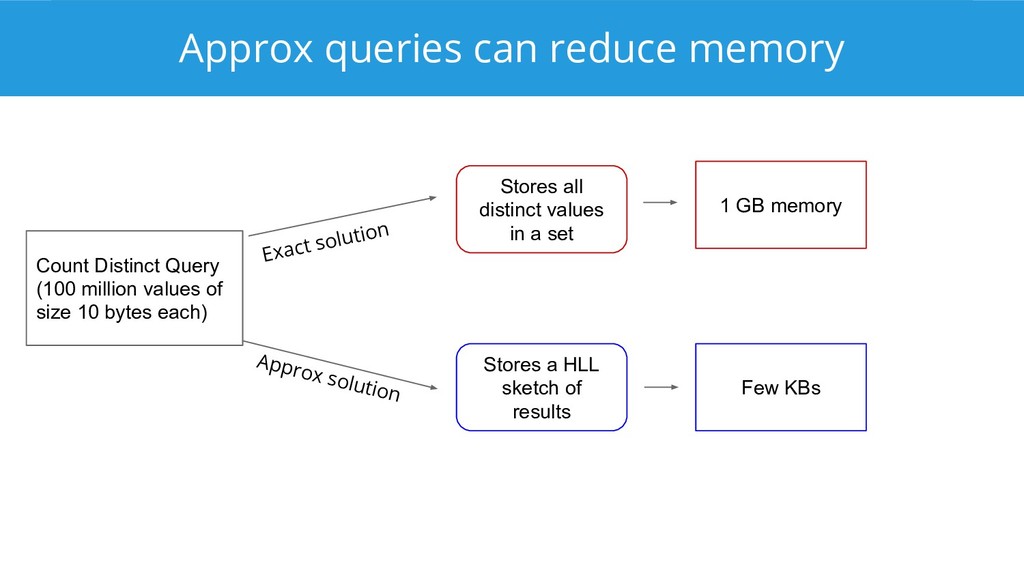
Tradeoff accuracy for reduced storage and improved performance. • Summarize data at ingestion time using sketches • Improves roll-up, reduce memory footprint
sum_ deleted userid_sketch 2011-01-01T00:00:00Z Justin Bieber SF 3 50 61 sketch_obj 2011-01-01T00:00:00Z Ke$ha LA 2 46 53 sketch_obj 2011-01-01T00:00:00Z Miley Cyrus DC 4 198 88 sketch_obj timestamp page userid city added deleted 2011-01-01T00:01:3 5Z Justin Bieber user11 SF 10 5 2011-01-01T00:03:4 5Z Justin Bieber user22 SF 25 37 2011-01-01T00:05:6 2Z Justin Bieber user11 SF 15 19 2011-01-01T00:06:3 3Z Ke$ha user33 LA 30 45 2011-01-01T00:08:5 1Z Ke$ha user33 LA 16 8 2011-01-01T00:09:1 7Z Miley Cyrus user11 DC 75 10 2011-01-01T00:11:2 5Z Miley Cyrus user44 DC 11 25 2011-01-01T00:23:3 0Z Miley Cyrus user44 DC 22 12 2011-01-01T00:49:3 3Z Miley Cyrus user55 DC 90 41

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 codatum
 mohab1
 kzkhykw1991
 kaminashi
 kentarofujii
 kworkdev
 gogutan
 sh_fk2
 techtekt
 kentapapa
 gionn
 carta_engineering
 lynnandtonic
 lauravandoore
 seathinner
 tammielis
 danielanewman
 pwiseman
 madoxten
 stephaniewalter
 bkeepers
 kimpetersen
 lara
 marcelosomers