Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Regularizations of Inverse Problems
Search
Samuel Vaiter
September 06, 2013
Science
53
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Regularizations of Inverse Problems
GRETSI'13, Quartz, Brest, September 2013.
Samuel Vaiter
September 06, 2013
More Decks by Samuel Vaiter
See All by Samuel Vaiter
Low Complexity Regularizations: A ''Localization'' Result
svaiter
0
80
A First Look at Proximal Methods
svaiter
0
250
Fast Distributed Total Variation
svaiter
0
130
Low Complexity Regularizations: A Localization Result
svaiter
0
80
Low Complexity Regularizations: a Localization Result
svaiter
0
130
Model Selection with Partly Smooth Functions
svaiter
0
57
Low Complexity Models: Robustness
svaiter
0
82
Low Complexity Models: Robustness and Sensivity
svaiter
0
49
Recovery Guarantees for Low Complexity Models
svaiter
1
84
Other Decks in Science
See All in Science
AI(人工知能)の過去・現在・未来 ~AIは人類を越えるのか~
tagtag
PRO
0
170
データベース04: SQL (1/3) 単純質問 & 集約演算
trycycle
PRO
0
1.8k
(CVPR2026) Back to Basics: Let Denoising Generative Models Denoise
shumpei777
0
410
「念のためのログ保存」を組織全体でやめるためのポリシーと仕組み作り
i2tsuki
4
410
機械学習 - 決定木からはじめる機械学習
trycycle
PRO
0
1.7k
Cross-Media Technologies, Information Science and Human-Information Interaction
signer
PRO
3
33k
「AIエージェントを作る」とは、何を設計することか
salt2
0
230
O(log n)-Approximation Algorithms for Bipartiteness Ratio
tasusu
0
260
自社のレビュー履歴からAIコードレビュアーをつくる方法
estie
5
1.7k
明治薬科大学講義_ビッグデータ解析を支えるデータベース技術とクラウドコンピューティング
ktatsuya
1
200
From Prediction to Understanding: Causal Discovery for Data Science and AI Applications
sshimizu2006
0
320
社内で活躍できるデータサイエンティストになるために
aikinohara
1
180
Featured
See All Featured
Faster Mobile Websites
deanohume
310
32k
Applied NLP in the Age of Generative AI
inesmontani
PRO
4
2.5k
Breaking role norms: Why Content Design is so much more than writing copy - Taylor Woolridge
uxyall
1
450
AI Search: Where Are We & What Can We Do About It?
aleyda
0
8.1k
The SEO Collaboration Effect
kristinabergwall1
1
590
"I'm Feeling Lucky" - Building Great Search Experiences for Today's Users (#IAC19)
danielanewman
230
23k
Stop Working from a Prison Cell
hatefulcrawdad
274
21k
Game over? The fight for quality and originality in the time of robots
wayneb77
1
300
SERP Conf. Vienna - Web Accessibility: Optimizing for Inclusivity and SEO
sarafernandez
2
1.6k
Getting science done with accelerated Python computing platforms
jacobtomlinson
2
530
Testing 201, or: Great Expectations
jmmastey
46
8.3k
Avoiding the “Bad Training, Faster” Trap in the Age of AI
tmiket
0
270
Transcript
Régularisation de problèmes inverses Analyse unifiée de la robustesse Samuel
VAITER CNRS, CEREMADE, Université Paris-Dauphine, France Travaux en collaboration avec M. GOLBABAEE, G. PEYRÉ et J. FADILI
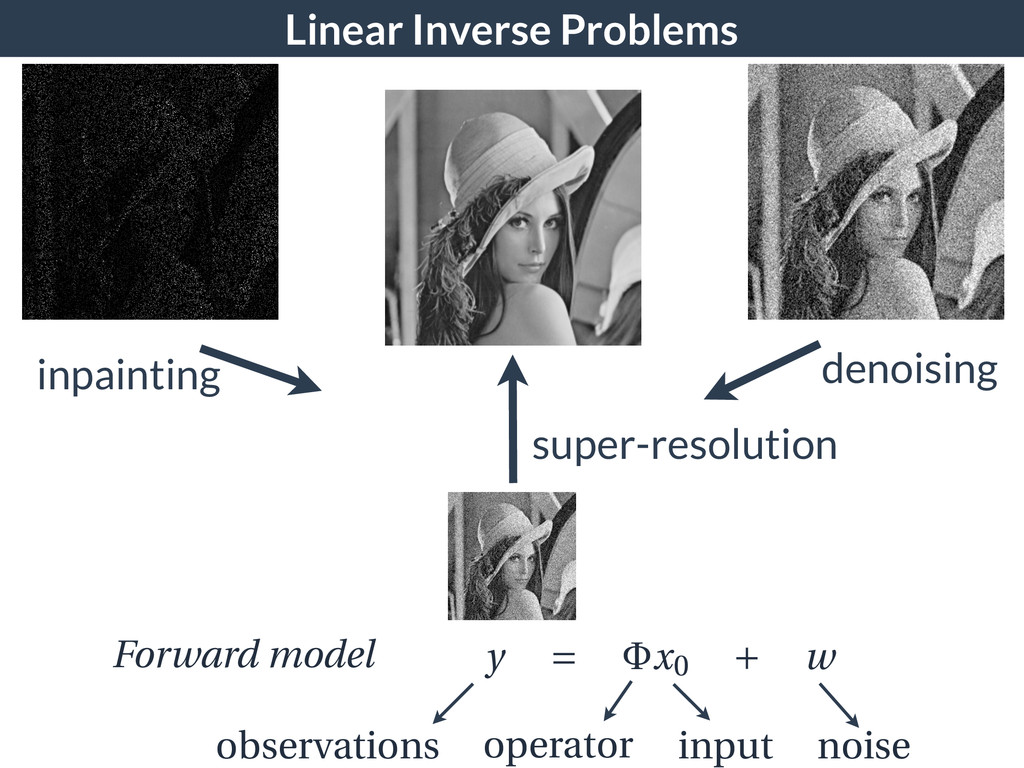
Linear Inverse Problems inpainting denoising super-resolution Forward model y =
x0 + w observations noise input operator
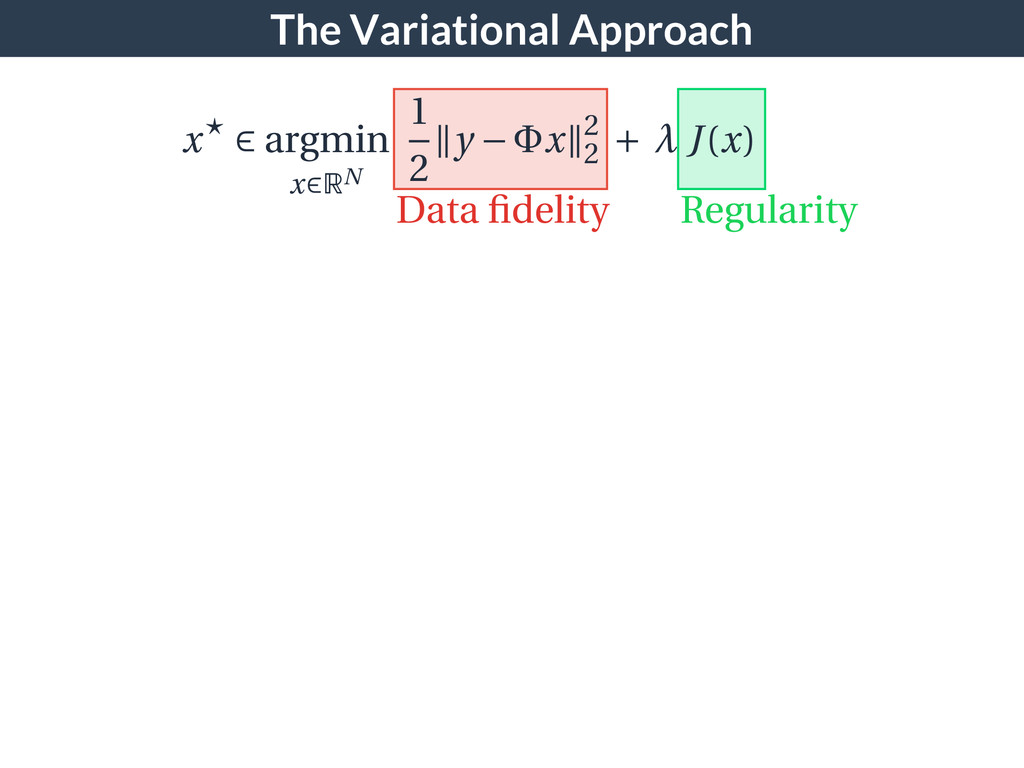
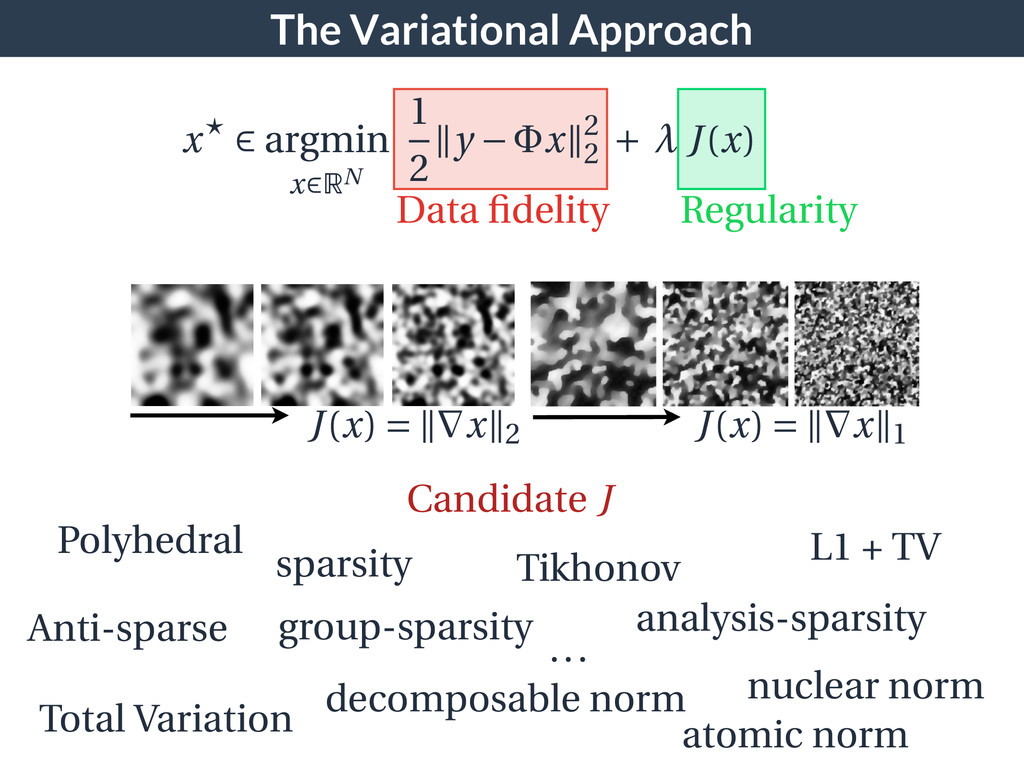
The Variational Approach x argmin x RN 1 2 ||y
x||2 2 + J(x) Data fidelity Regularity
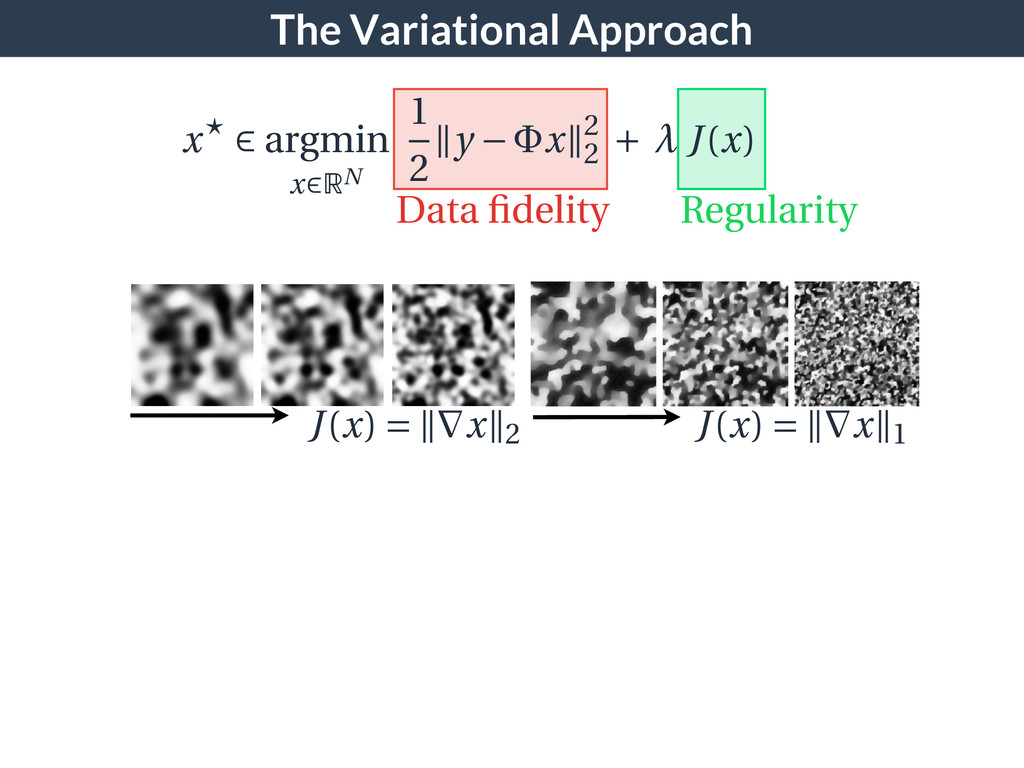
The Variational Approach x argmin x RN 1 2 ||y
x||2 2 + J(x) Data fidelity Regularity J(x) = || x||2 J(x) = || x||1
The Variational Approach x argmin x RN 1 2 ||y
x||2 2 + J(x) Data fidelity Regularity J(x) = || x||2 J(x) = || x||1 sparsity analysis-sparsity group-sparsity nuclear norm Tikhonov Total Variation Anti-sparse Polyhedral L1 + TV ... atomic norm decomposable norm Candidate J
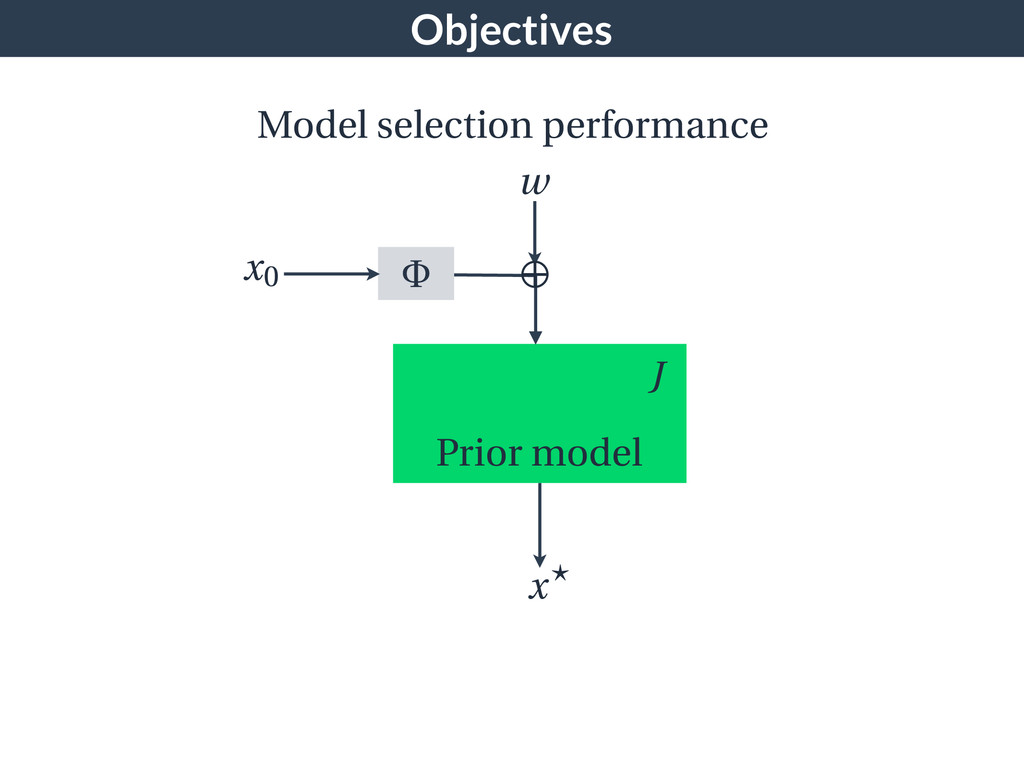
Objectives Model selection performance x0 x w Prior model J
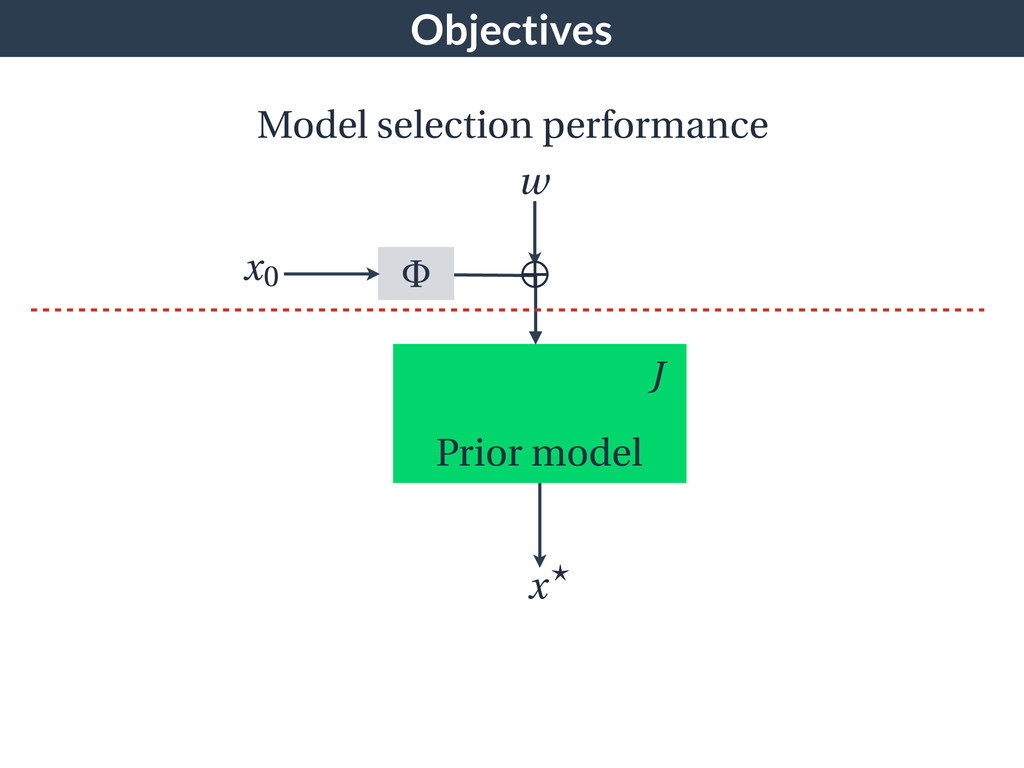
Objectives Model selection performance x0 x w Prior model J
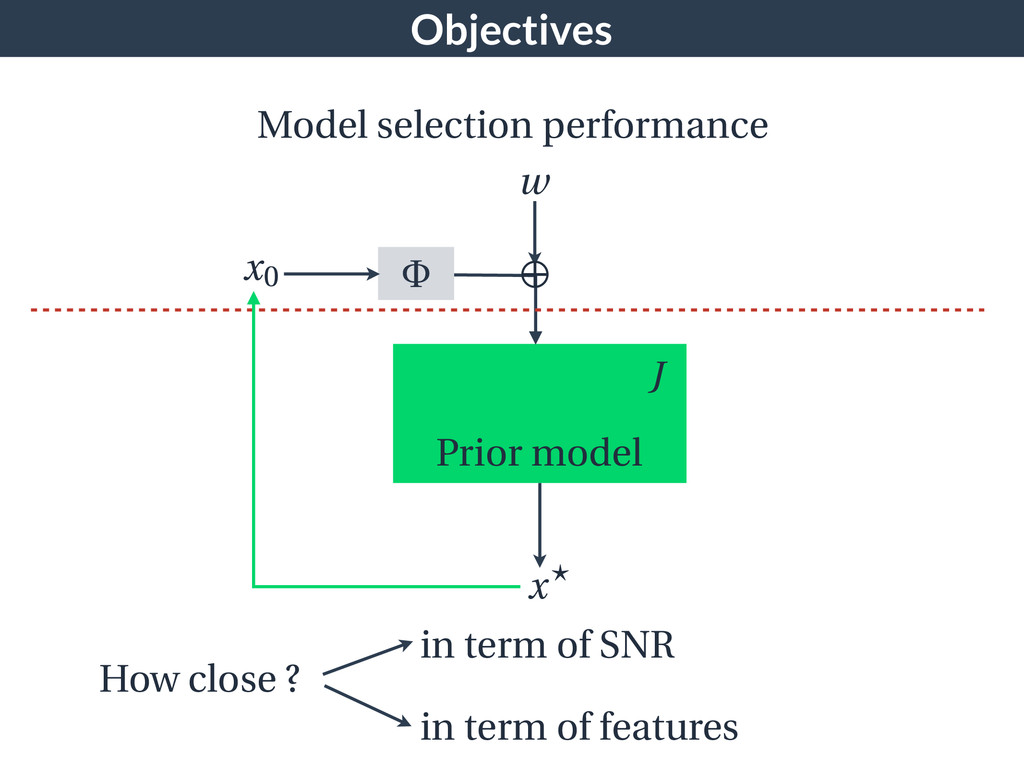
Objectives Model selection performance x0 x w Prior model J
How close ? in term of SNR in term of features
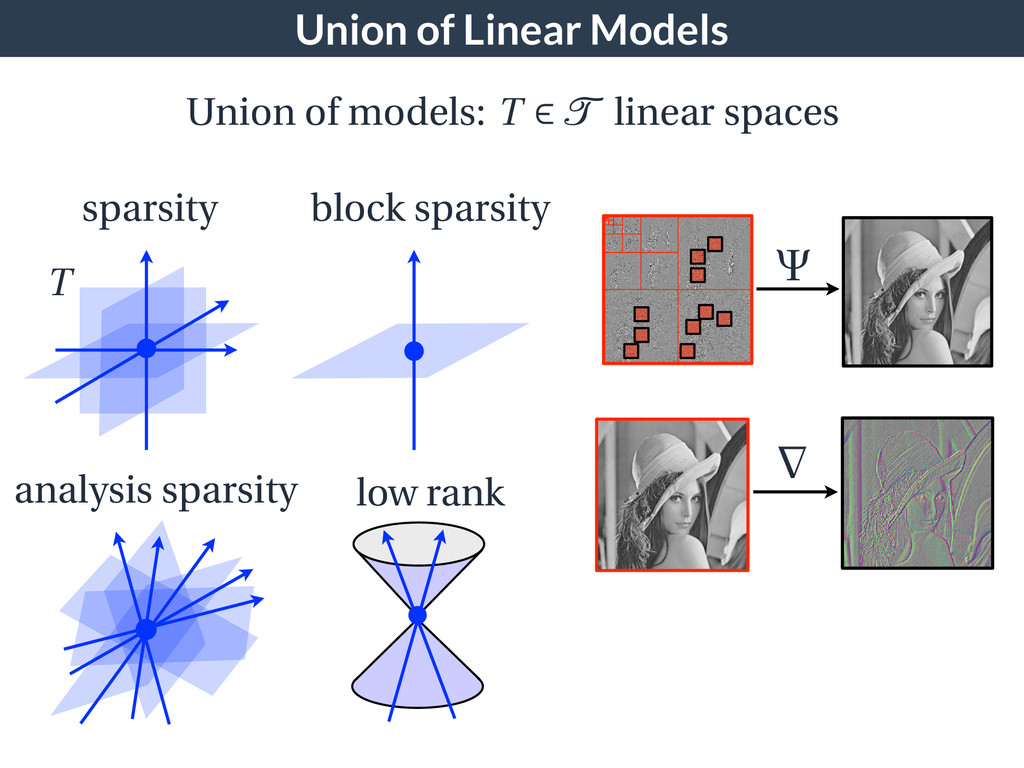
Union of Linear Models Union of models: T T linear
spaces
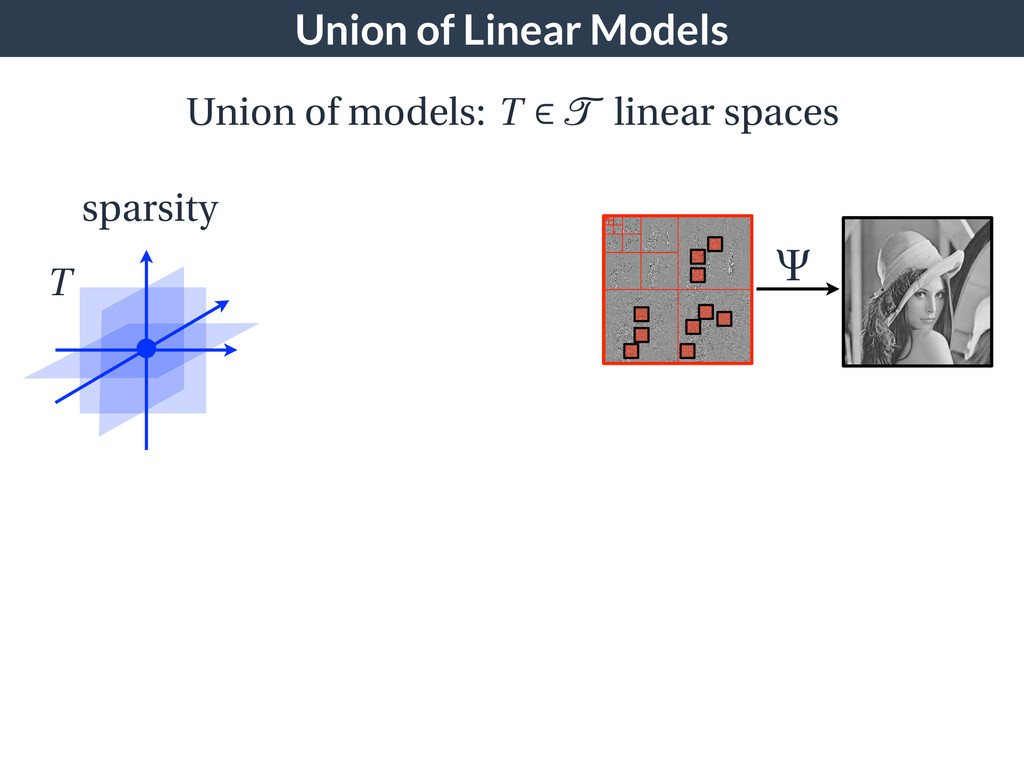
Union of Linear Models Union of models: T T linear
spaces T sparsity
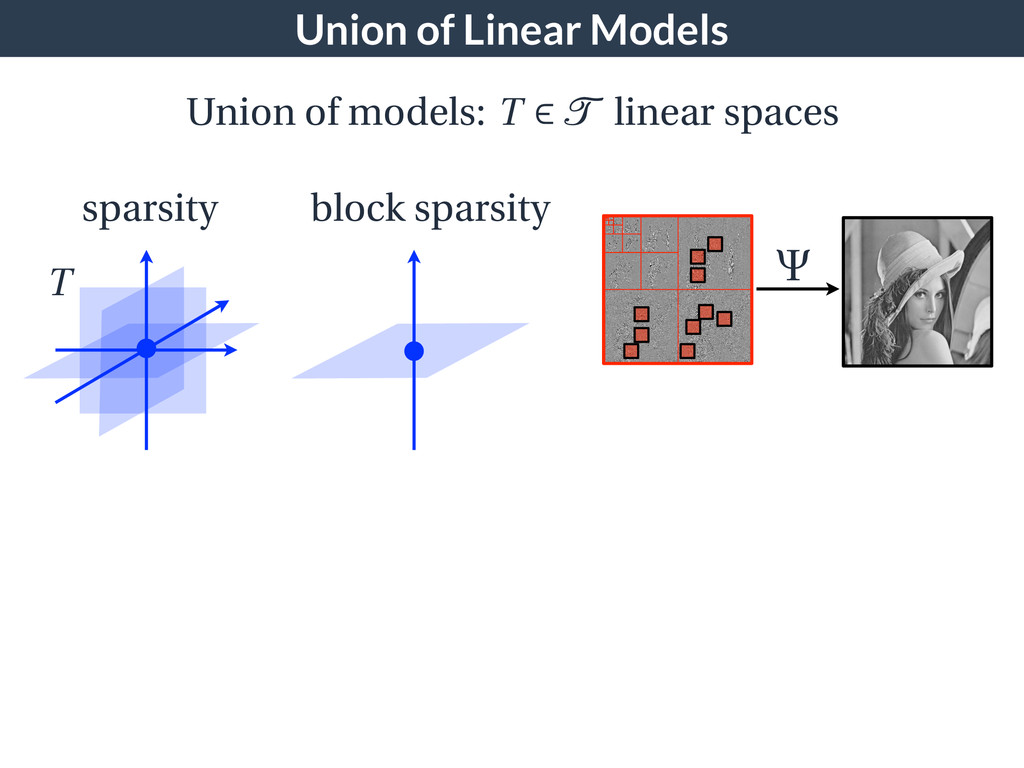
Union of Linear Models Union of models: T T linear
spaces block sparsity T sparsity
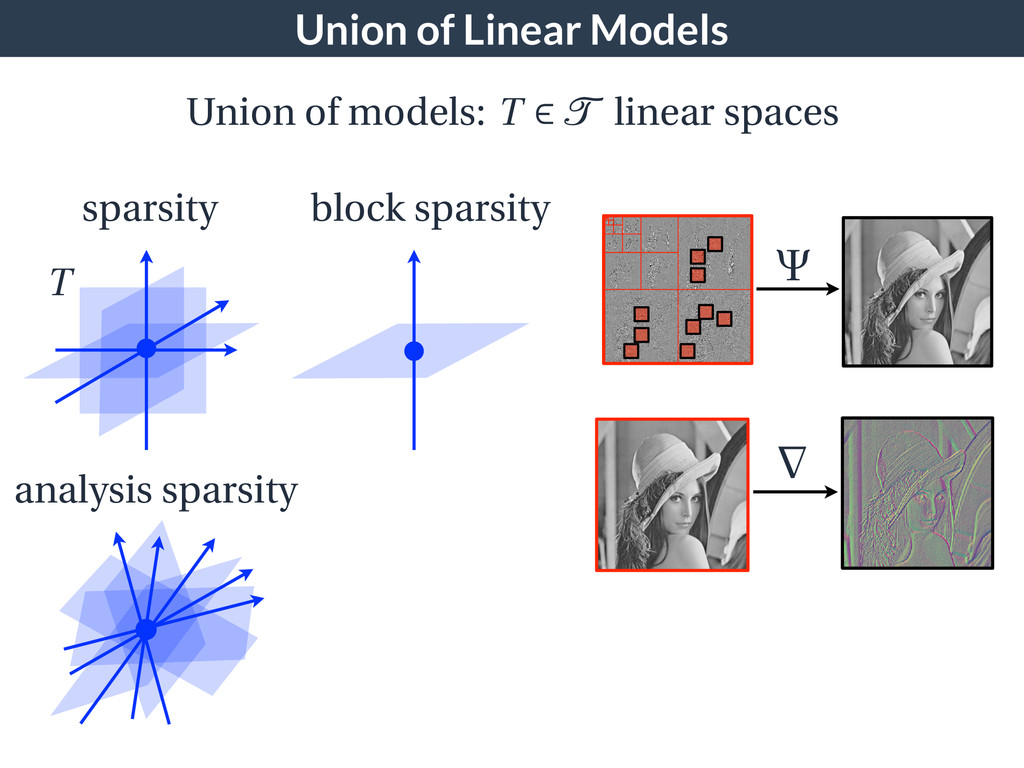
Union of Linear Models Union of models: T T linear
spaces block sparsity T sparsity analysis sparsity
Union of Linear Models Union of models: T T linear
spaces block sparsity low rank T sparsity analysis sparsity
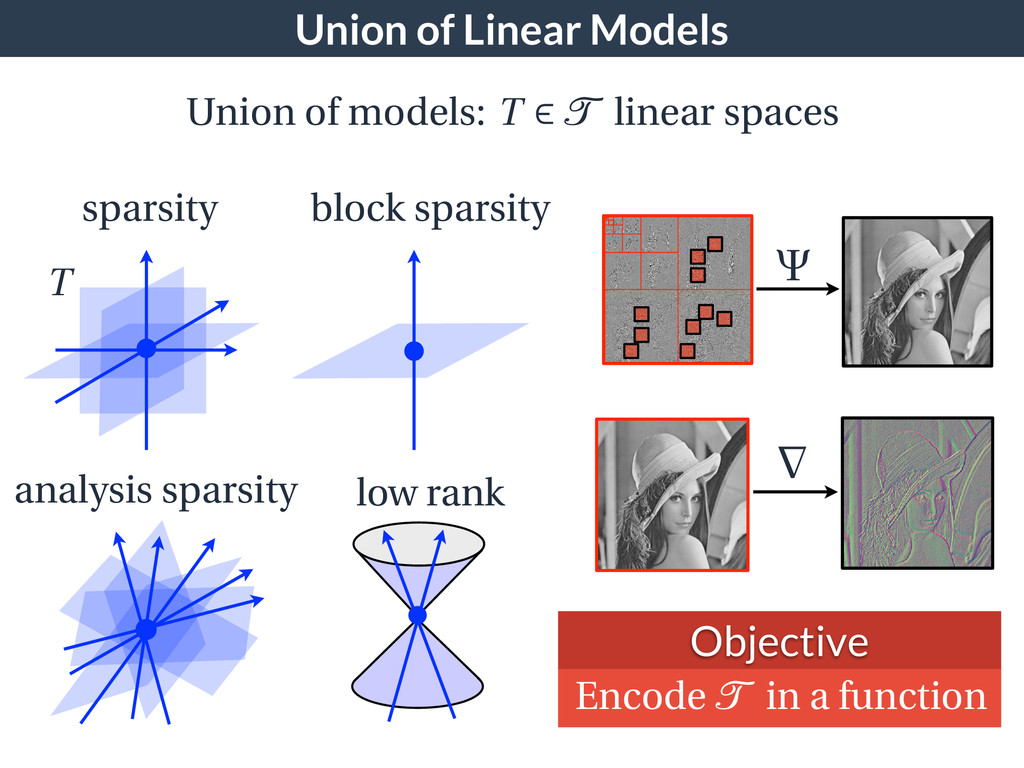
Union of Linear Models Union of models: T T linear
spaces block sparsity low rank Objective Encode T in a function T sparsity analysis sparsity
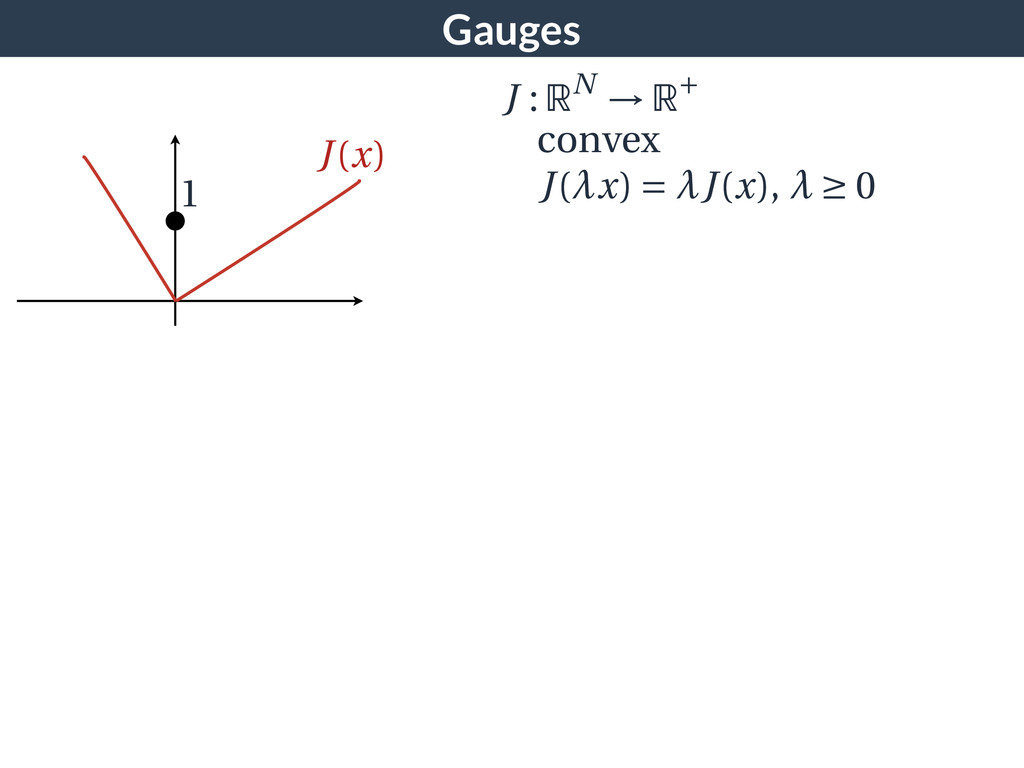
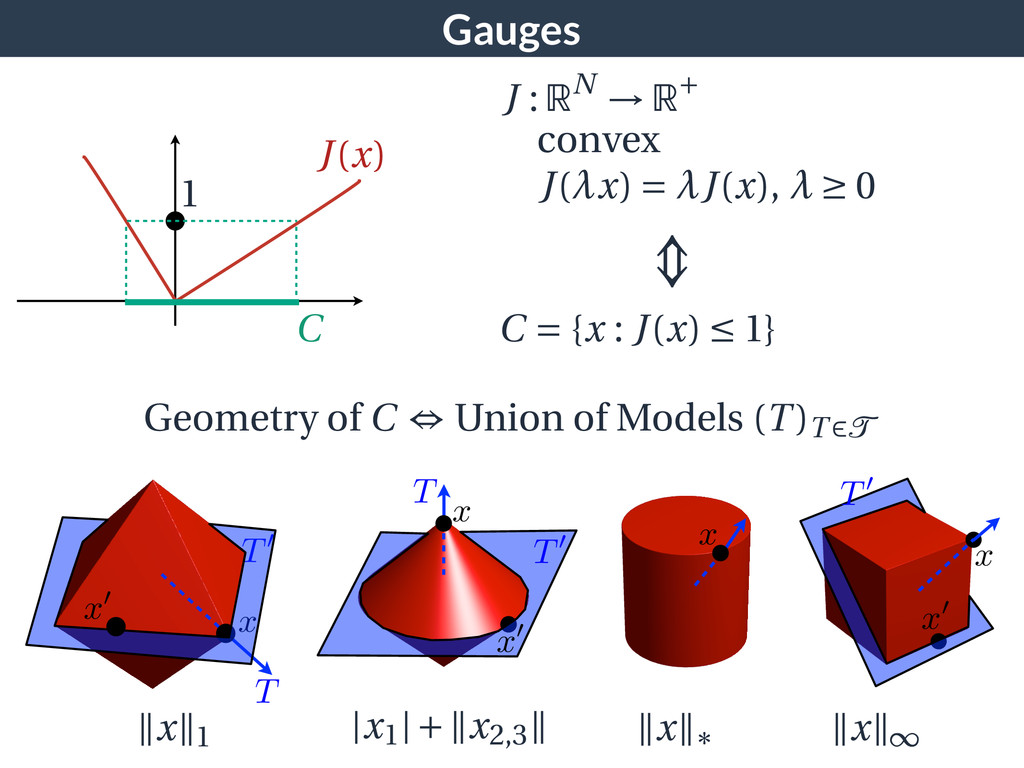
Gauges 1 J(x) J : RN R+ convex J( x)
= J(x), 0
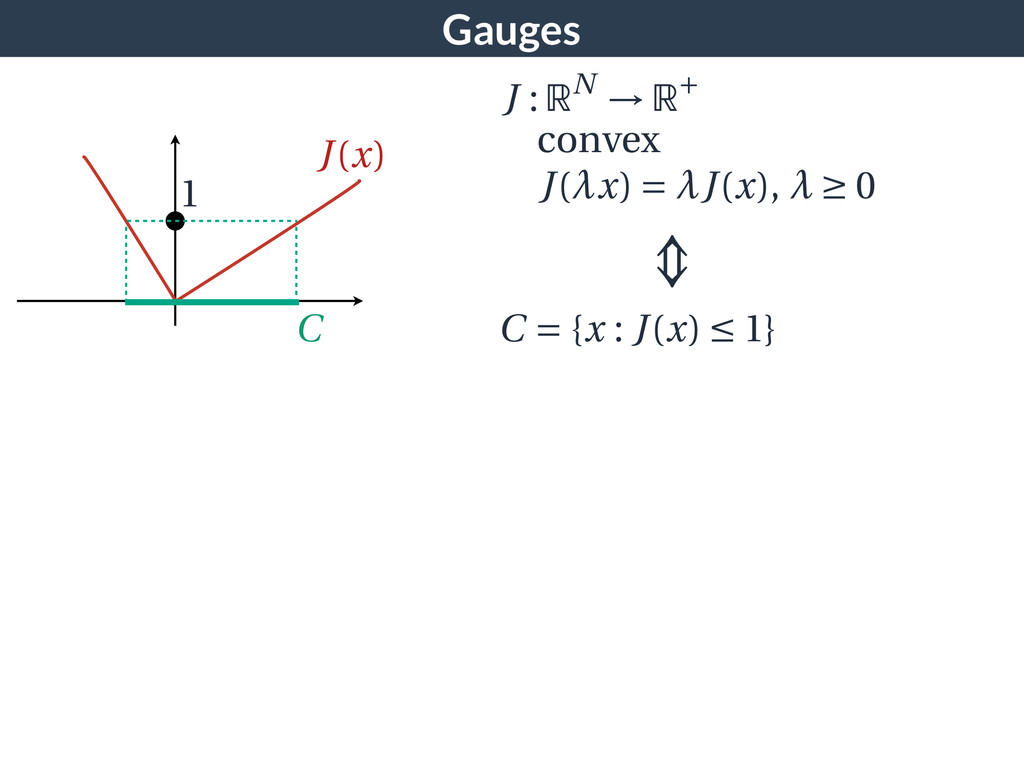
Gauges 1 J(x) J : RN R+ convex C C
= {x : J(x) 1} J( x) = J(x), 0
Gauges 1 J(x) J : RN R+ convex C C
= {x : J(x) 1} Geometry of C Union of Models (T )T T x T x x 0 T0 x x 0 T0 x 0 x T T0 ||x||1 |x1|+||x2,3|| ||x|| ||x|| J( x) = J(x), 0
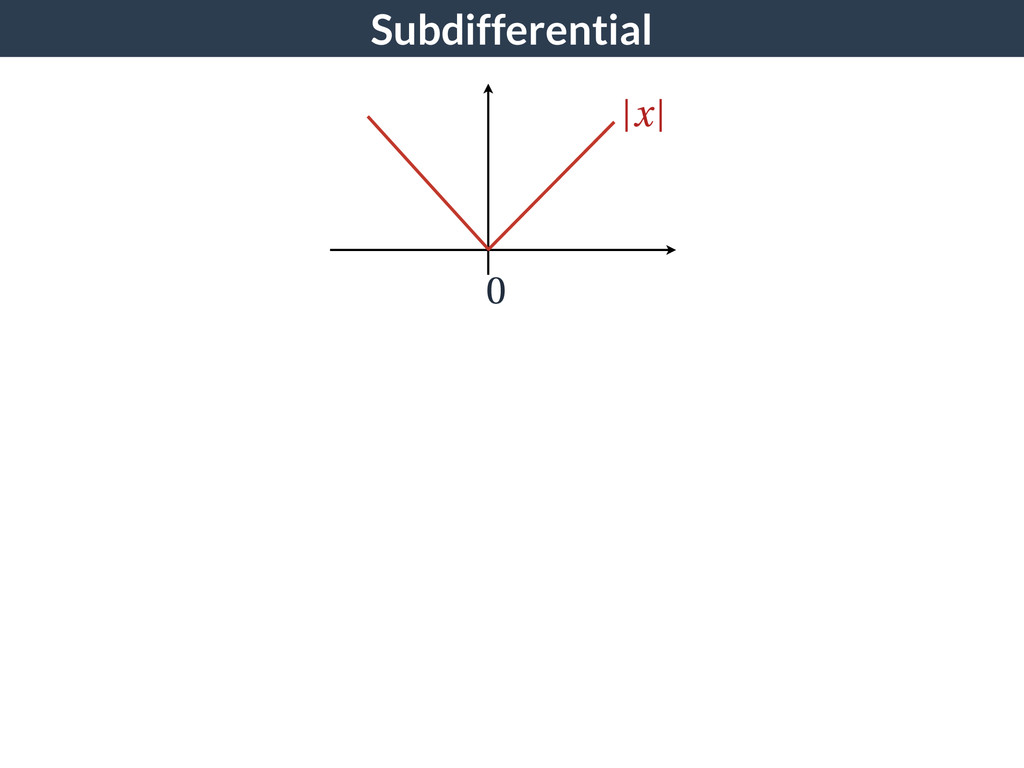
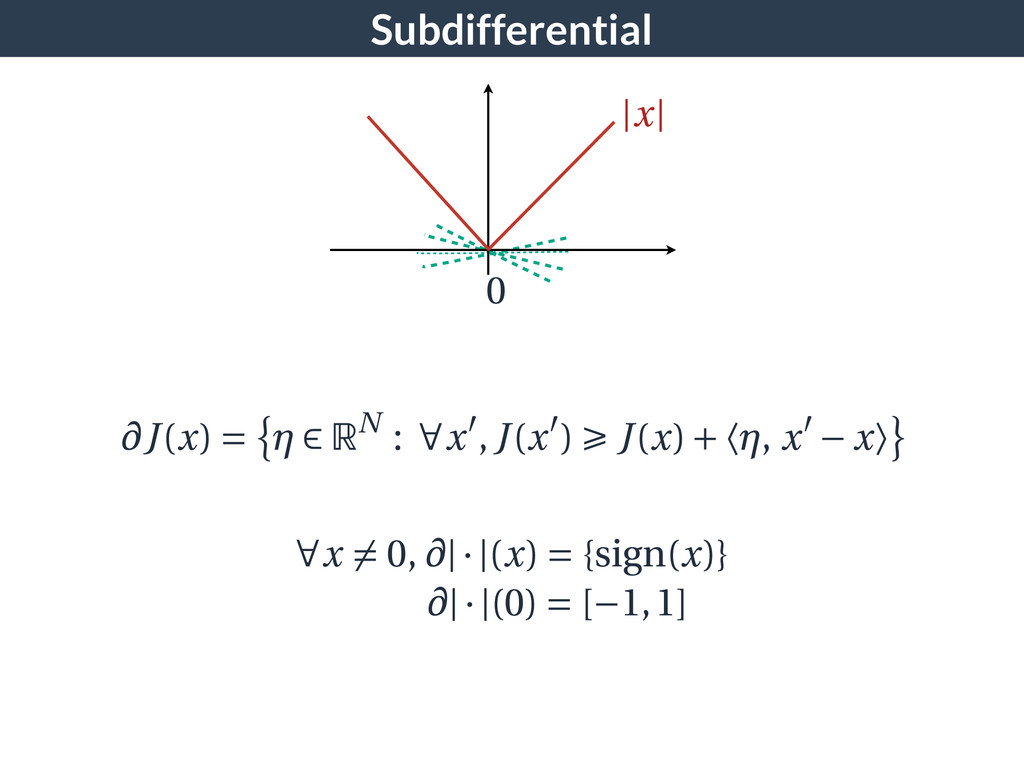
Subdifferential |x| 0
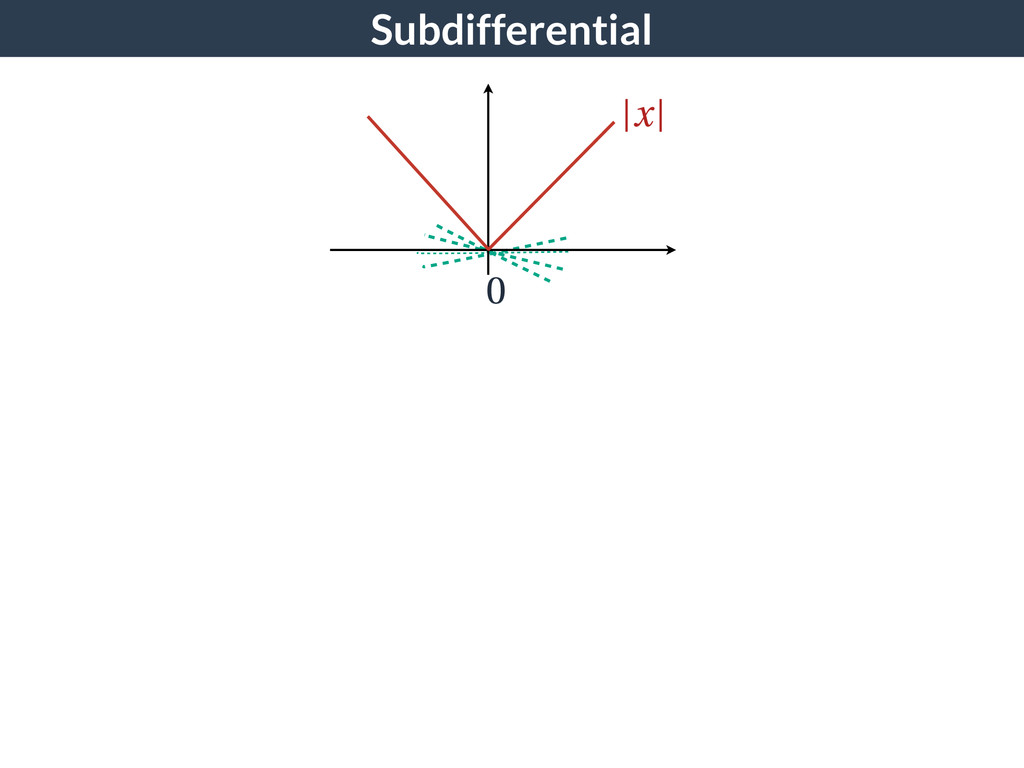
Subdifferential |x| 0
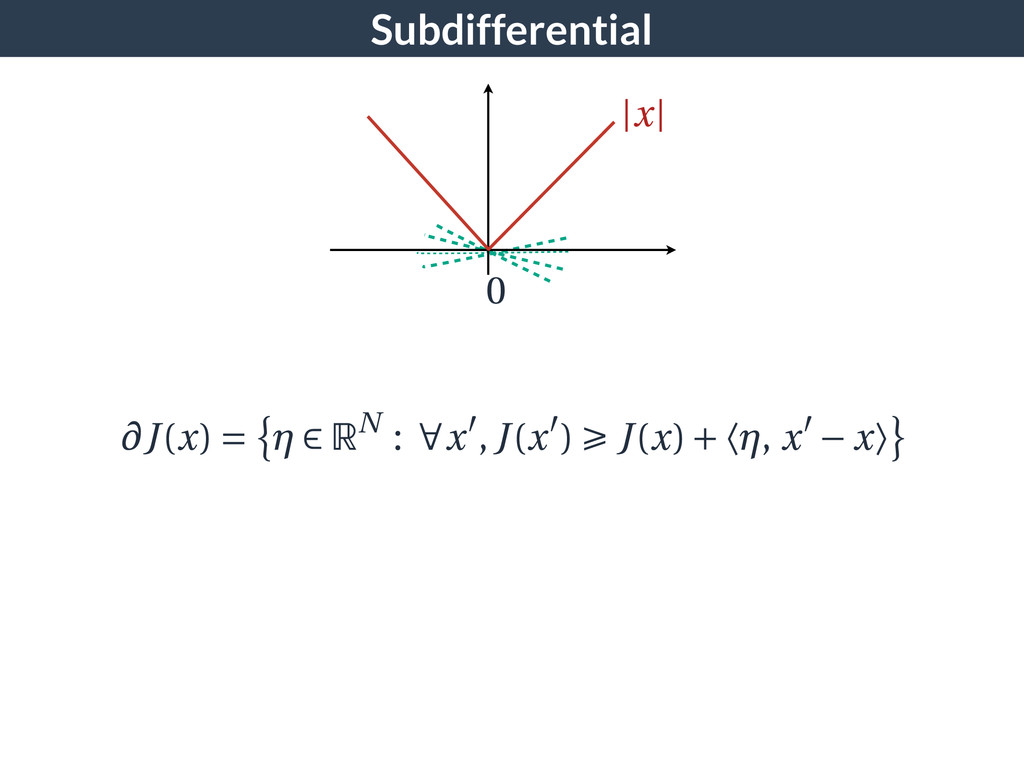
J(x) = RN : x , J(x ) J(x)+ ,
x x Subdifferential |x| 0
J(x) = RN : x , J(x ) J(x)+ ,
x x Subdifferential |x| 0 |·|(0) = [ 1,1] x = 0, |·|(x) = {sign(x)}
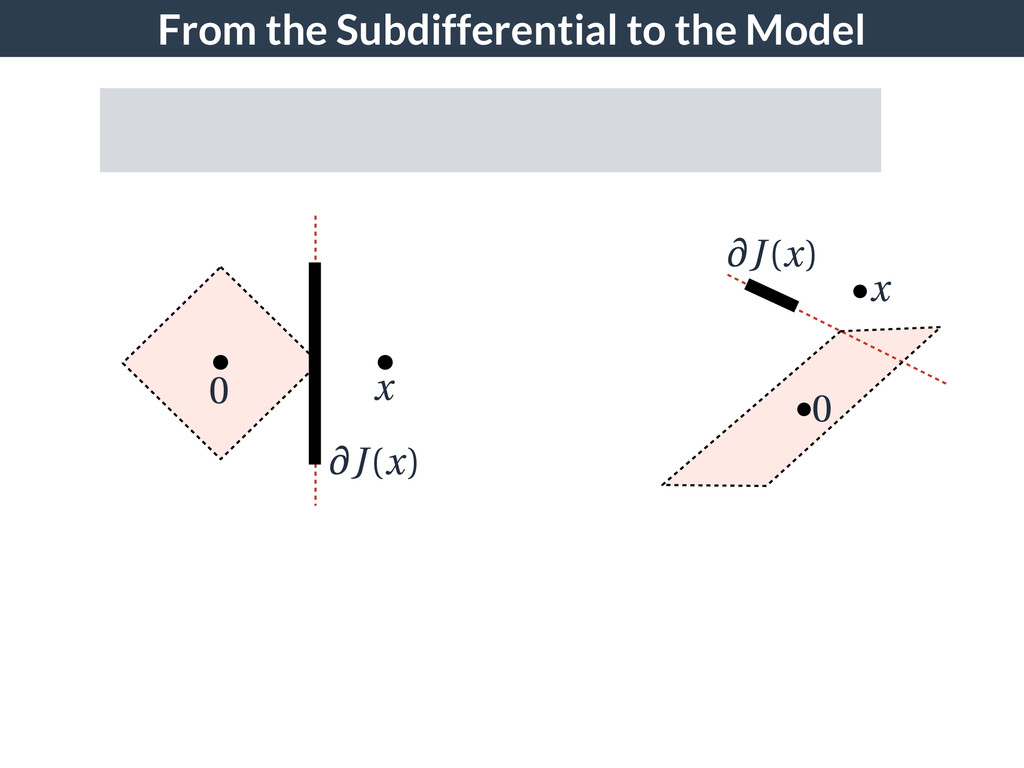
From the Subdifferential to the Model J(x) x 0 J(x)
x 0
From the Subdifferential to the Model J(x) x 0 J(x)
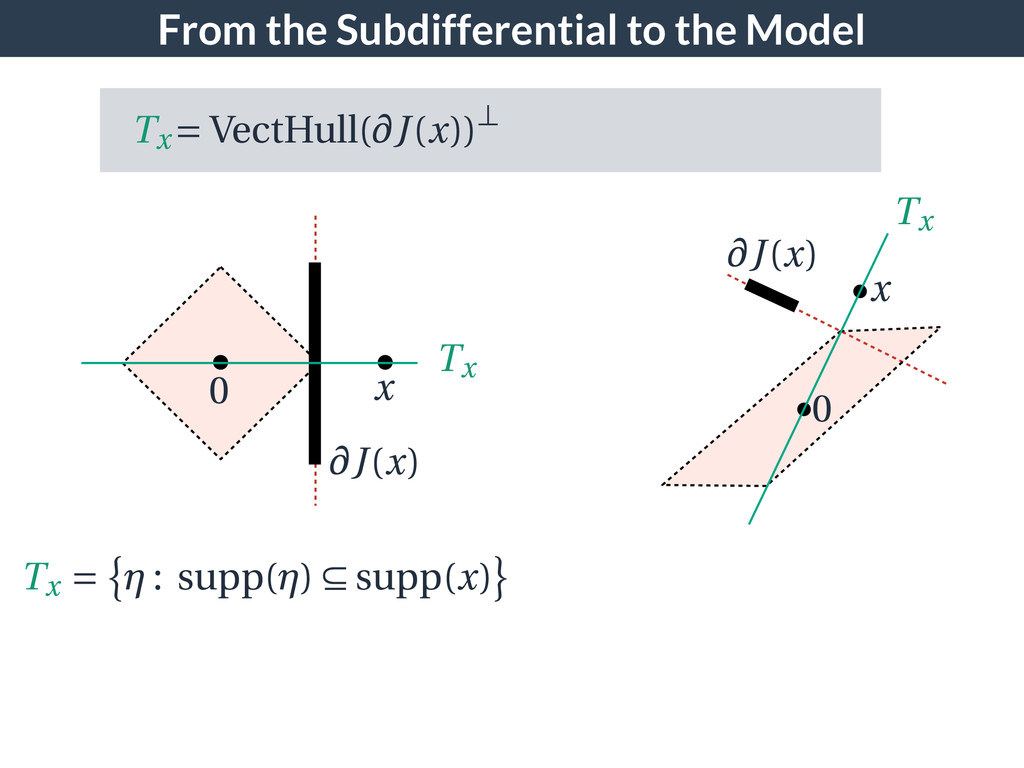
x 0 Tx= VectHull( J(x)) Tx Tx Tx = : supp( ) supp(x)
From the Subdifferential to the Model J(x) x 0 J(x)
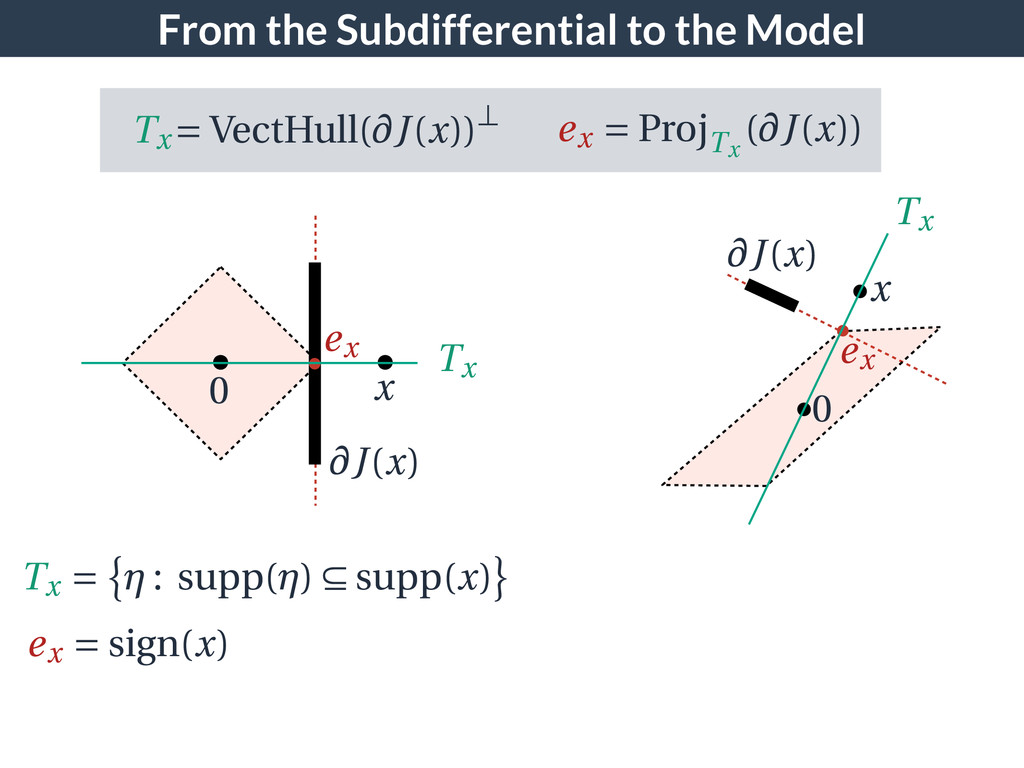
x 0 ex = ProjTx ( J(x)) ex ex ex = sign(x) Tx= VectHull( J(x)) Tx Tx Tx = : supp( ) supp(x)
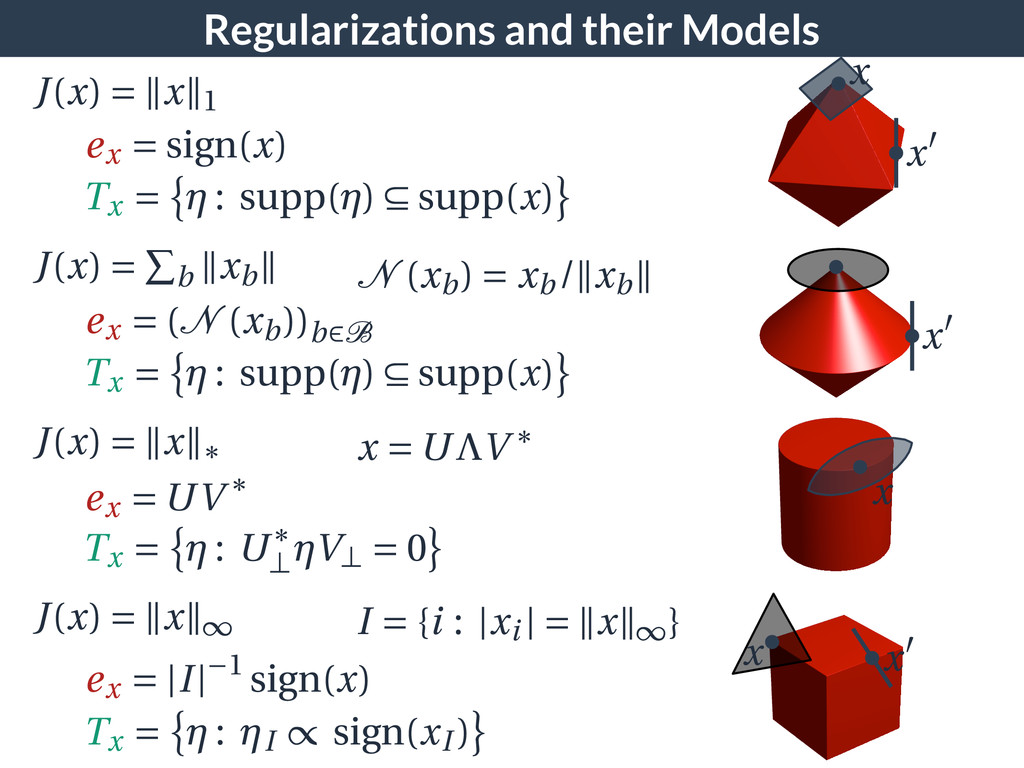
Regularizations and their Models J(x) = ||x||1 ex = sign(x)
Tx = : supp( ) supp(x) x x J(x) = b ||xb|| ex = (N (xb))b B Tx = : supp( ) supp(x) x N (xb) = xb/||xb|| J(x) = ||x||∗ ex =UV Tx = : U V = 0 x x =UΛV ∗ J(x) = ||x||∞ ex = |I| 1 sign(x) Tx = : I sign(xI ) x x I = {i : |xi | = ||x||∞}
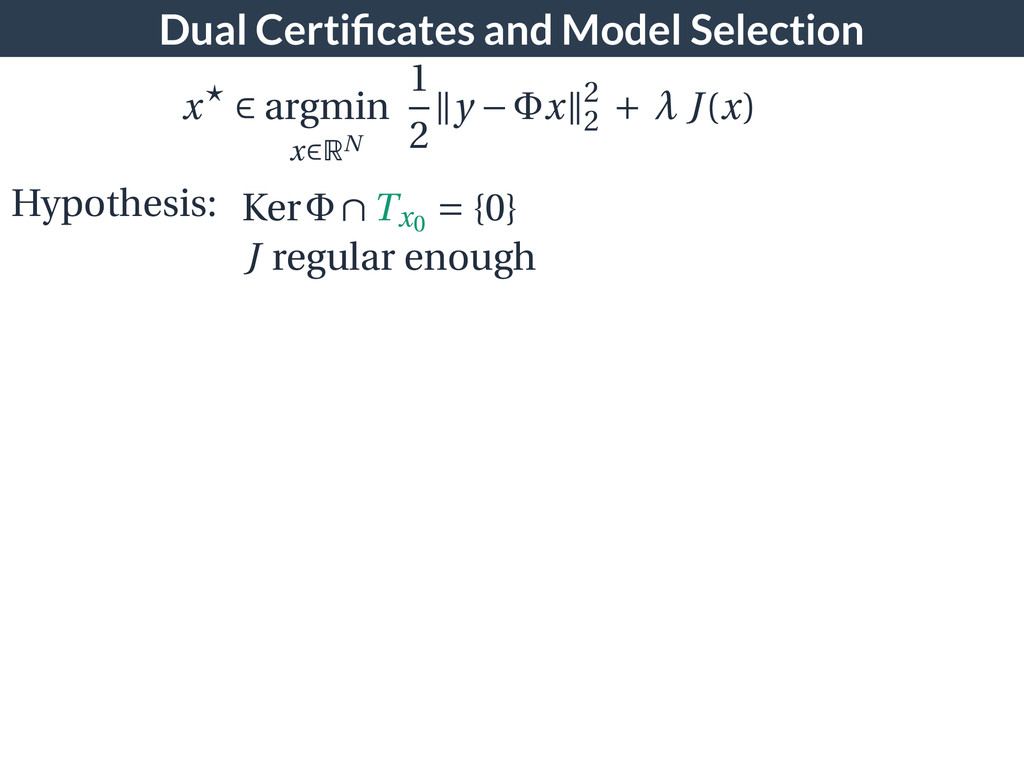
Dual Certificates and Model Selection x argmin x RN 1
2 ||y x||2 2 + J(x) Hypothesis: Ker Tx0 = {0} J regular enough
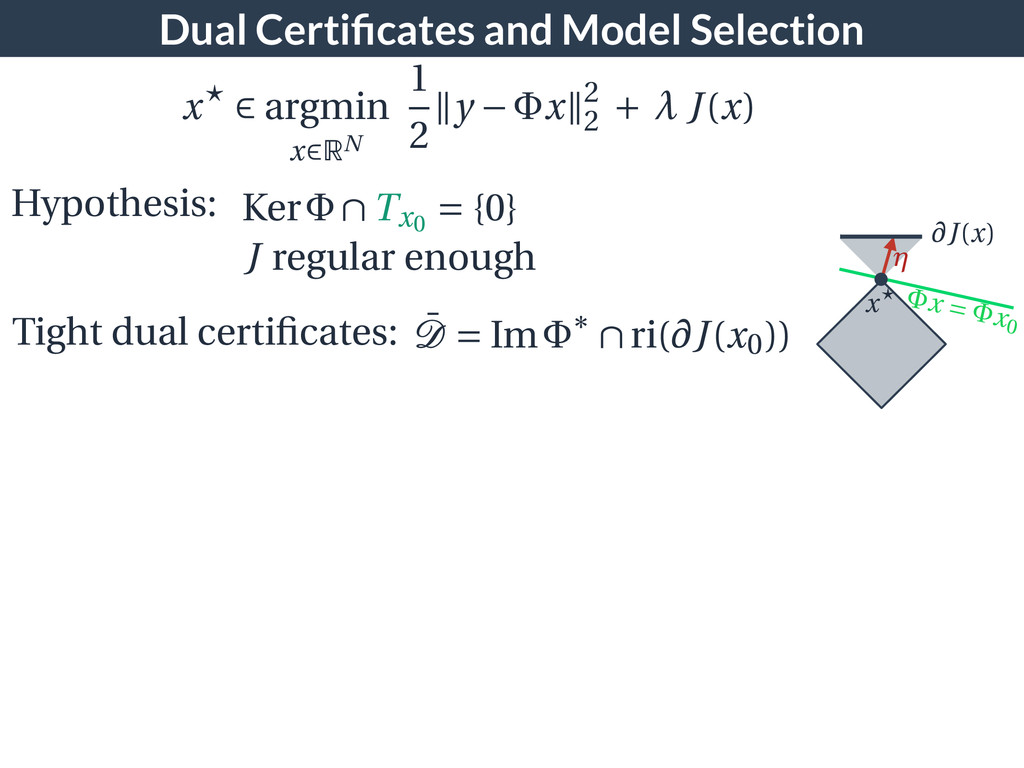
Dual Certificates and Model Selection x argmin x RN 1
2 ||y x||2 2 + J(x) Hypothesis: Ker Tx0 = {0} J regular enough ¯ D = Im ri( J(x0)) Tight dual certificates: x = x0 J(x) x
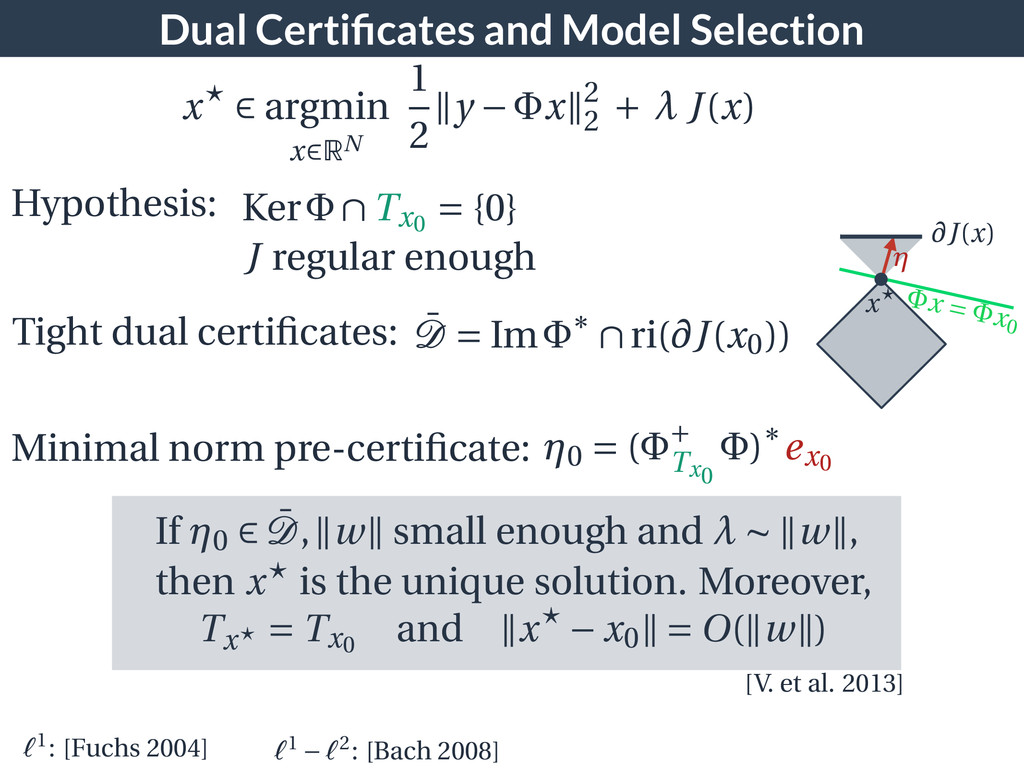
Dual Certificates and Model Selection x argmin x RN 1
2 ||y x||2 2 + J(x) Hypothesis: 0 = ( + Tx0 ) ex0 Minimal norm pre-certificate: Tx = Tx0 and ||x x0|| = O(||w||) If 0 ¯ D,||w|| small enough and ||w||, then x is the unique solution. Moreover, [V. et al. 2013] 1: [Fuchs 2004] 1 2: [Bach 2008] Ker Tx0 = {0} J regular enough ¯ D = Im ri( J(x0)) Tight dual certificates: x = x0 J(x) x
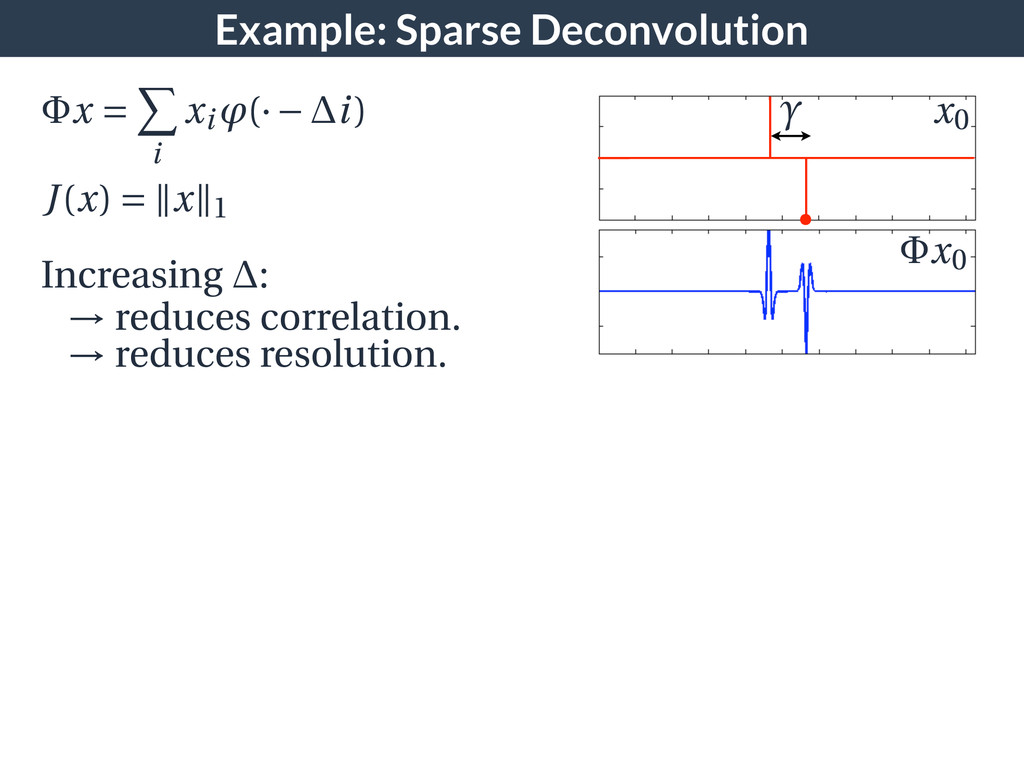
Example: Sparse Deconvolution x = i xi (· i) J(x)
= ||x||1 Increasing : reduces correlation. reduces resolution. x0 x0
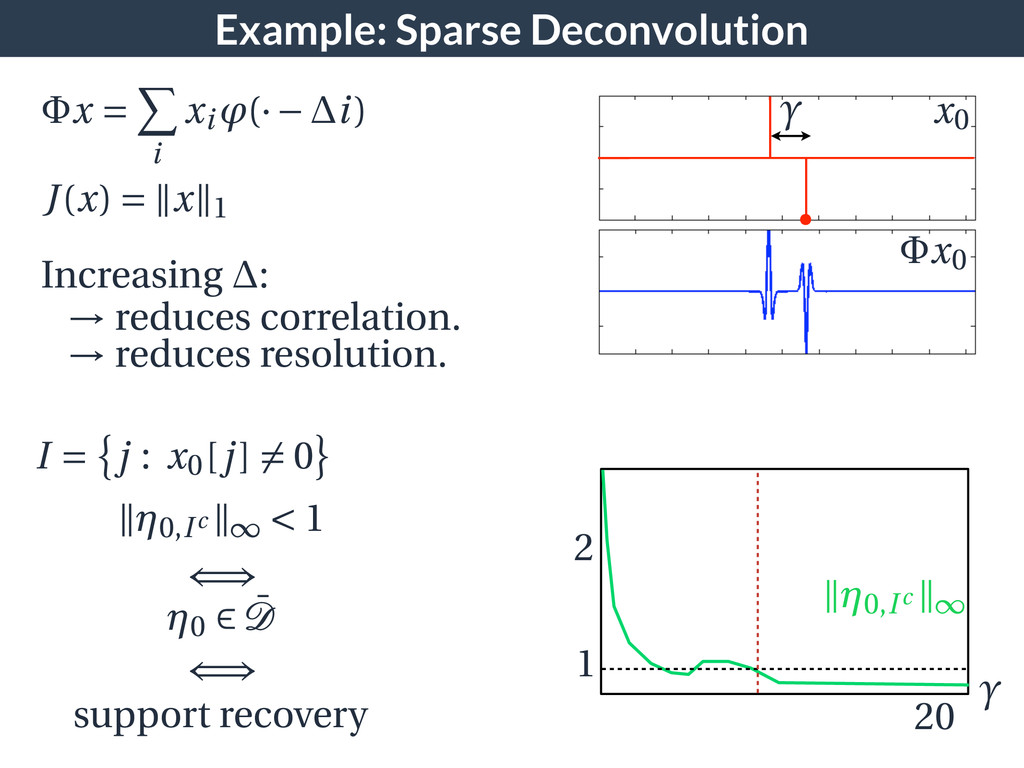
Example: Sparse Deconvolution x = i xi (· i) J(x)
= ||x||1 Increasing : reduces correlation. reduces resolution. x0 x0 I = j : x0[j] = 0 || 0,Ic || < 1 0 ¯ D support recovery || 0,Ic || 1 2 20
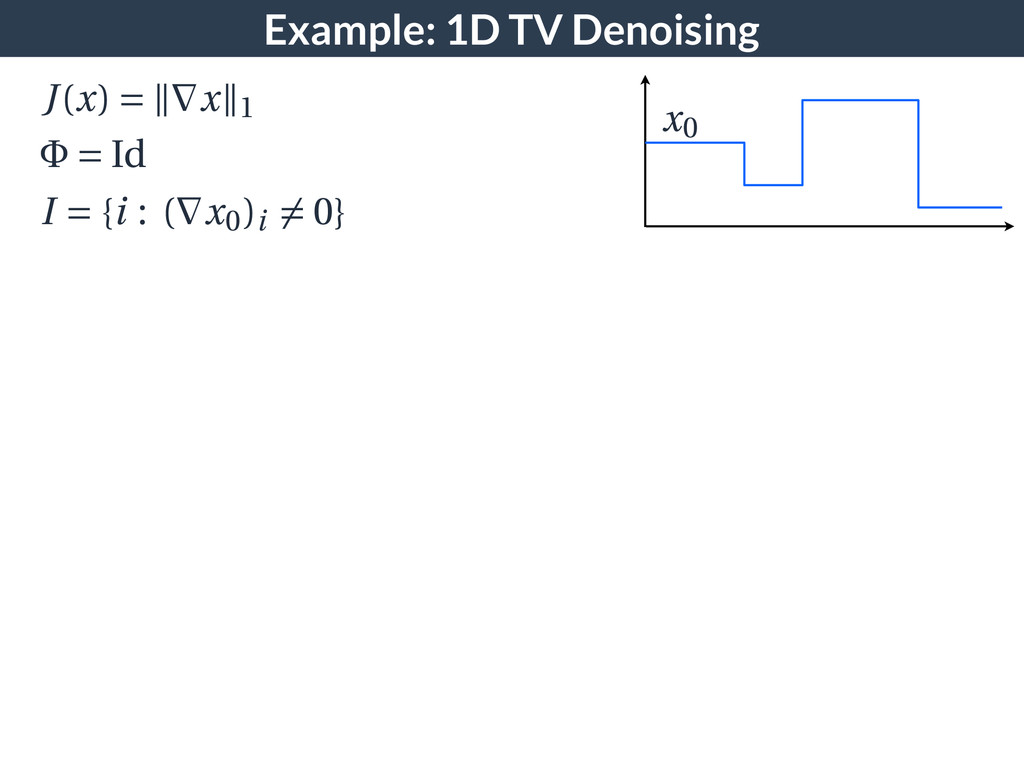
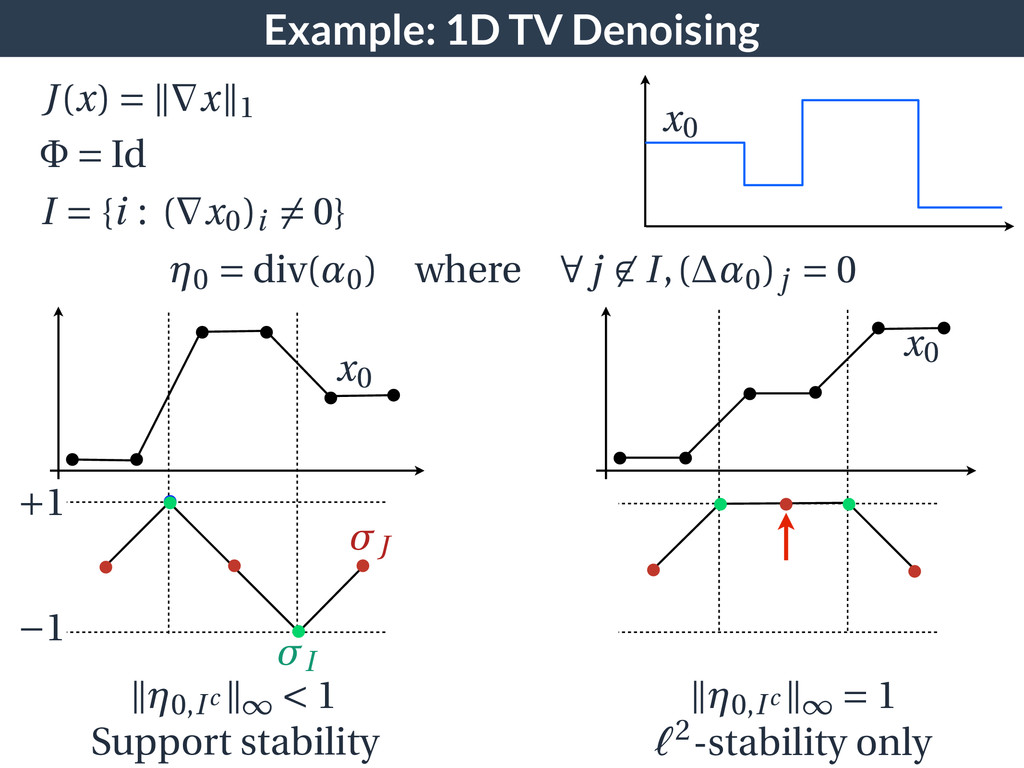
Example: 1D TV Denoising J(x) = || x||1 = Id
I = {i : ( x0)i = 0} x0
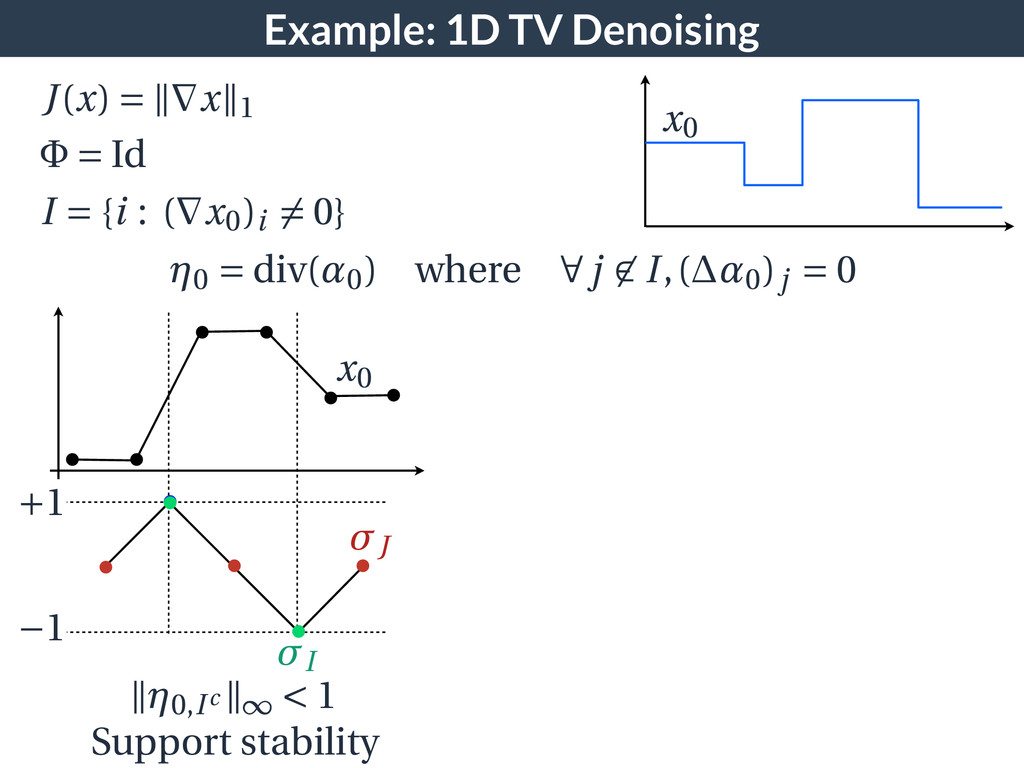
Example: 1D TV Denoising J(x) = || x||1 = Id
I = {i : ( x0)i = 0} x0 +1 1 0 = div( 0) where j I,( 0)j = 0 x0 I J || 0,Ic || < 1 Support stability
Example: 1D TV Denoising J(x) = || x||1 = Id
I = {i : ( x0)i = 0} x0 +1 1 0 = div( 0) where j I,( 0)j = 0 x0 I J || 0,Ic || < 1 Support stability x0 || 0,Ic || = 1 2-stability only
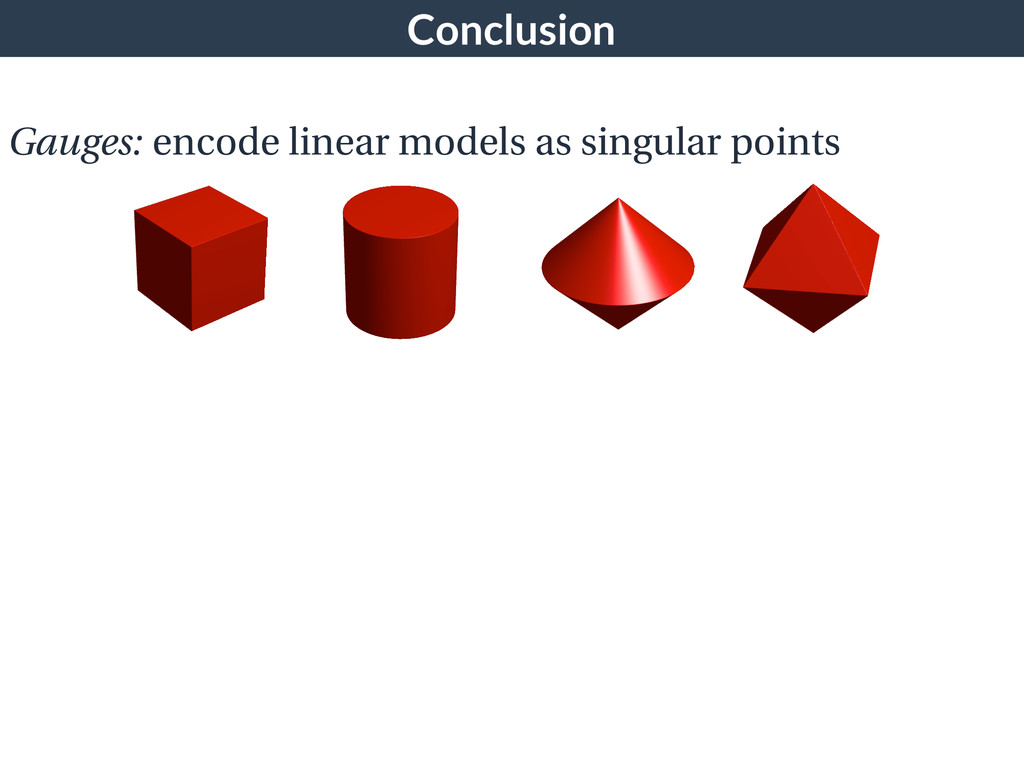
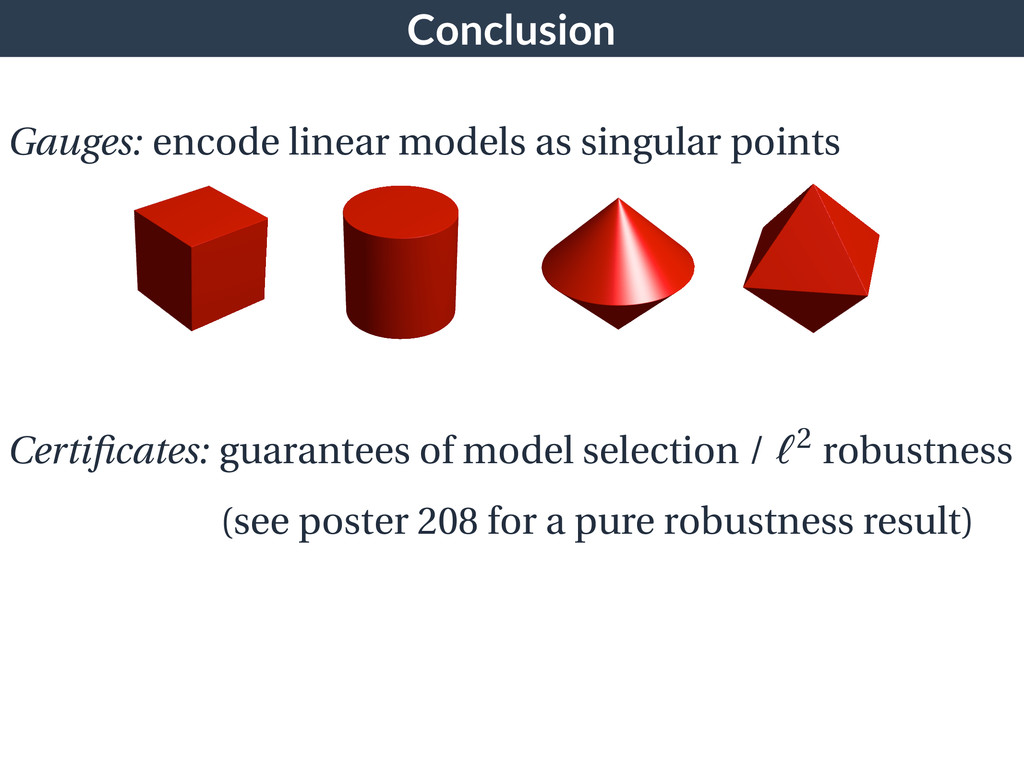
Conclusion Gauges: encode linear models as singular points
Conclusion Gauges: encode linear models as singular points Certificates: guarantees
of model selection / 2 robustness (see poster 208 for a pure robustness result)
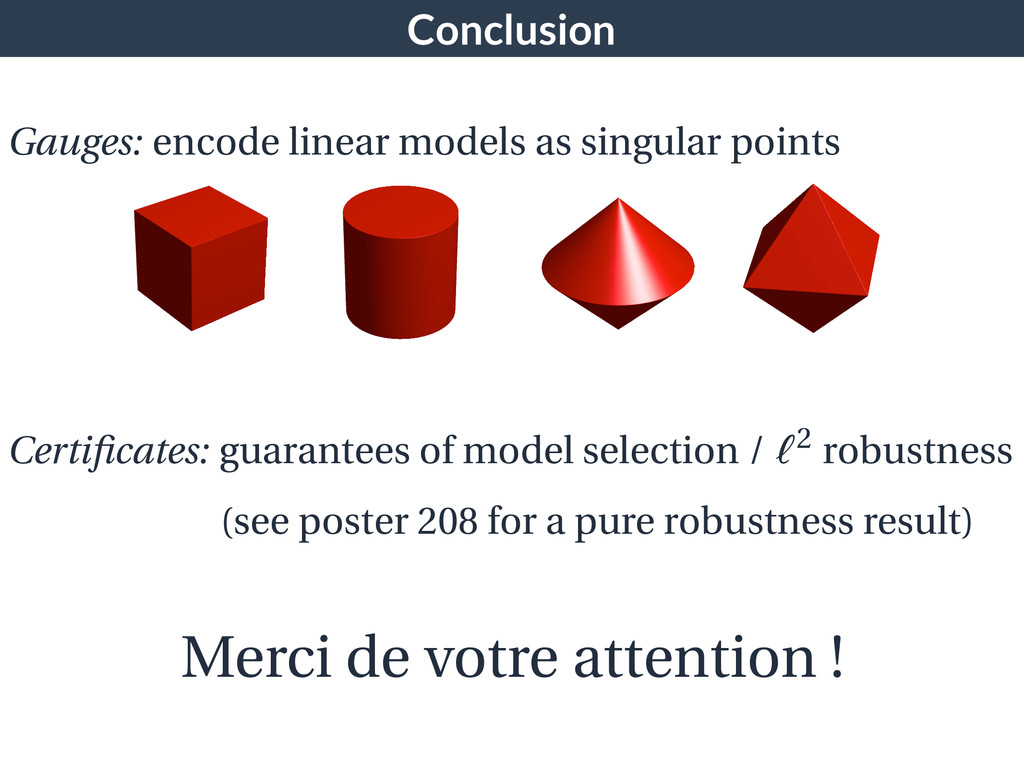
Conclusion Merci de votre attention ! Gauges: encode linear models
as singular points Certificates: guarantees of model selection / 2 robustness (see poster 208 for a pure robustness result)


 svaiter
 tagtag
 trycycle
 shumpei777
 i2tsuki
 signer
 salt2
 tasusu
 estie
 ktatsuya
 sshimizu2006
 aikinohara
 deanohume
 inesmontani
 uxyall
 aleyda
 kristinabergwall1
 danielanewman
 hatefulcrawdad
 wayneb77
 sarafernandez
 jacobtomlinson
 jmmastey
 tmiket