Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Machine Learning in Production with R or Python...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
szilard
June 08, 2017
200
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Machine Learning in Production with R or Python - Budapest Data Forum - June 2017
szilard
June 08, 2017
More Decks by szilard
See All by szilard
Gradient Boosting Machines (GBM): From Zero to Hero (with R and Python Code) - Data Con LA - Oct 2020
szilard
0
250
Make Machine Learning Boring Again: Best Practices for Using Machine Learning in Businesses - Albuquerque Machine Learning Meetup (Online) - Aug 2020
szilard
0
180
Better than Deep Learning: Gradient Boosting Machines (GBM) - eRum conference - invited talk - June 2020
szilard
0
160
Gradient Boosting Machines (GBM): From Zero to Hero (with R and Python Code) - LA Data Science Meetup - February 2020
szilard
0
150
A Random Walk in Data Science and Machine Learning in Practice - CEU, Business Analytics Masters - Budapest, Febr 2020
szilard
0
350
Better than My Meetup/Conference Talks: Going Deeper in Various GBM Topics - GBM Advanced Workshop - Budapest, Nov 2019
szilard
0
120
Gradient Boosting Machines (GBM): From Zero to Hero (with R and Python Code) - Budapest BI Forum, Budapest, Nov 2019
szilard
0
180
Make Machine Learning Boring Again: Best Practices for Using Machine Learning in Businesses - LA Data Science Meetup - Playa Vista, August 2019
szilard
0
160
Better than Deep Learning: Gradient Boosting Machines (GBM) / 2019 edition - Budapest R and Data Science Meetups - Budapest, June 2019
szilard
0
140
Featured
See All Featured
Navigating Team Friction
lara
192
16k
My Coaching Mixtape
mlcsv
0
320
How to Talk to Developers About Accessibility
jct
2
550
Exploring anti-patterns in Rails
aemeredith
4
510
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
BBQ
matthewcrist
89
10k
The Invisible Side of Design
smashingmag
301
52k
世界の人気アプリ100個を分析して見えたペイウォール設計の心得
akihiro_kokubo
PRO
74
42k
jQuery: Nuts, Bolts and Bling
dougneiner
66
8.6k
SEOcharity - Dark patterns in SEO and UX: How to avoid them and build a more ethical web
sarafernandez
0
280
Jamie Indigo - Trashchat’s Guide to Black Boxes: Technical SEO Tactics for LLMs
techseoconnect
PRO
0
670
Leadership Guide Workshop - DevTernity 2021
reverentgeek
1
370
Transcript
Machine Learning in Production Szilárd Pafka, PhD Chief Scientist, Epoch
Budapest Data Forum June 2017
Machine Learning in Production with R Szilárd Pafka, PhD Chief
Scientist, Epoch Budapest Data Forum June 2017
Machine Learning in Production with R or Python Szilárd Pafka,
PhD Chief Scientist, Epoch Budapest Data Forum June 2017
Machine Learning in Production with R or maybe Python Szilárd
Pafka, PhD Chief Scientist, Epoch Budapest Data Forum June 2017
None
Disclaimer: I am not representing my employer (Epoch) in this
talk I cannot confirm nor deny if Epoch is using any of the methods, tools, results etc. mentioned in this talk
None
http://datascience.la/meetup-machine-learning-in-production-with-szilard-pafka/
None
None
None
None
None
None
None
None
None
None
None
None
None
Aggregation 100M rows 1M groups Join 100M rows x 1M
rows time [s] time [s]
Aggregation 100M rows 1M groups Join 100M rows x 1M
rows time [s] time [s]
None
None
None
None
binary classification, 10M records numeric & categorical features, non-sparse
http://www.cs.cornell.edu/~alexn/papers/empirical.icml06.pdf http://lowrank.net/nikos/pubs/empirical.pdf
http://www.cs.cornell.edu/~alexn/papers/empirical.icml06.pdf http://lowrank.net/nikos/pubs/empirical.pdf
None
None
None
None
None
EC2
n = 10K, 100K, 1M, 10M, 100M Training time RAM
usage AUC CPU % by core read data, pre-process, score test data
n = 10K, 100K, 1M, 10M, 100M Training time RAM
usage AUC CPU % by core read data, pre-process, score test data
None
None
None
None
None
None
None
10x
None
None
None
None
None
http://datascience.la/benchmarking-random-forest-implementations/#comment-53599
None
None
None
None
None
None
None
Best linear: 71.1
None
None
learn_rate = 0.1, max_depth = 6, n_trees = 300 learn_rate
= 0.01, max_depth = 16, n_trees = 1000
None
None
None
None
None
None
None
None
None
None
None
None
None
None
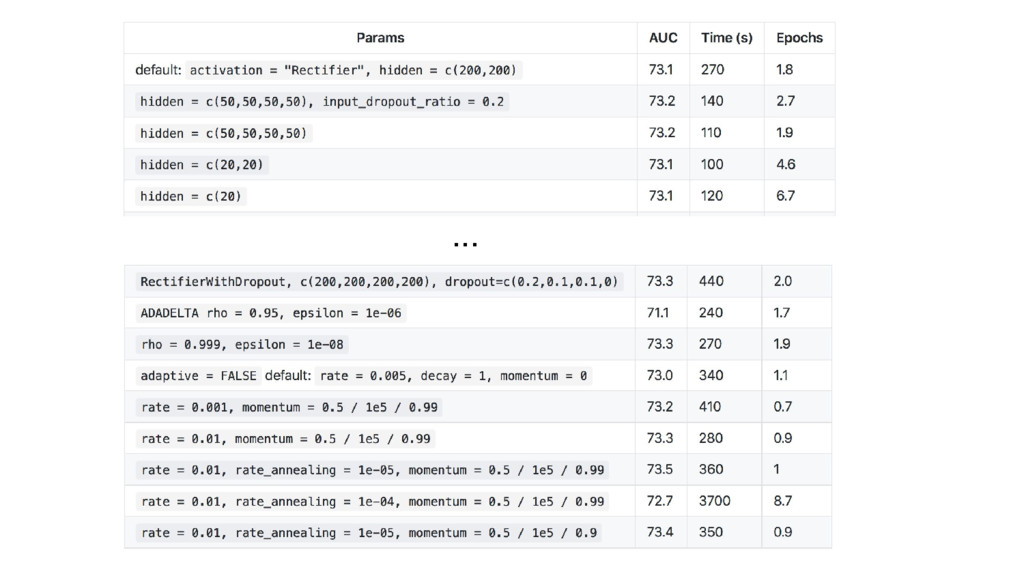
...
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None
None

 Your Podcast. Everywhere. Effortlessly.


 szilard
 lara
 mlcsv
 jct
 aemeredith
 chriscoyier
 matthewcrist
 smashingmag
 akihiro_kokubo
 dougneiner
 sarafernandez
 techseoconnect
 reverentgeek