Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Experimenting with continuous deployment for fe...

Sponsored · SiteGround - Reliable hosting with speed, security, and support you can count on. →

Experimenting with continuous deployment for feature branches

My lightning talk was given at Sydney DevOps on the 16 May, 2013. It was based on an earlier blog post (http://tatey.com/2013/05/06/experimenting-with-continuous-deployment-for-feature-branches/)

Avatar for Tate Johnson

Tate Johnson

May 16, 2013

More Decks by Tate Johnson

Other Decks in Programming

Transcript

  1. • Ask non-technical person to come to my computer •

    Manually deploy to staging server. Merge branches. Run migrations. Update sample data. • Distraction. Take away from meaningful work.
  2. • Developer pushes code • Application is immediately deployed on

    disposable instance with sample data • Accessible to anyone • Zero impact on developer’s workflow • Cheap ($)
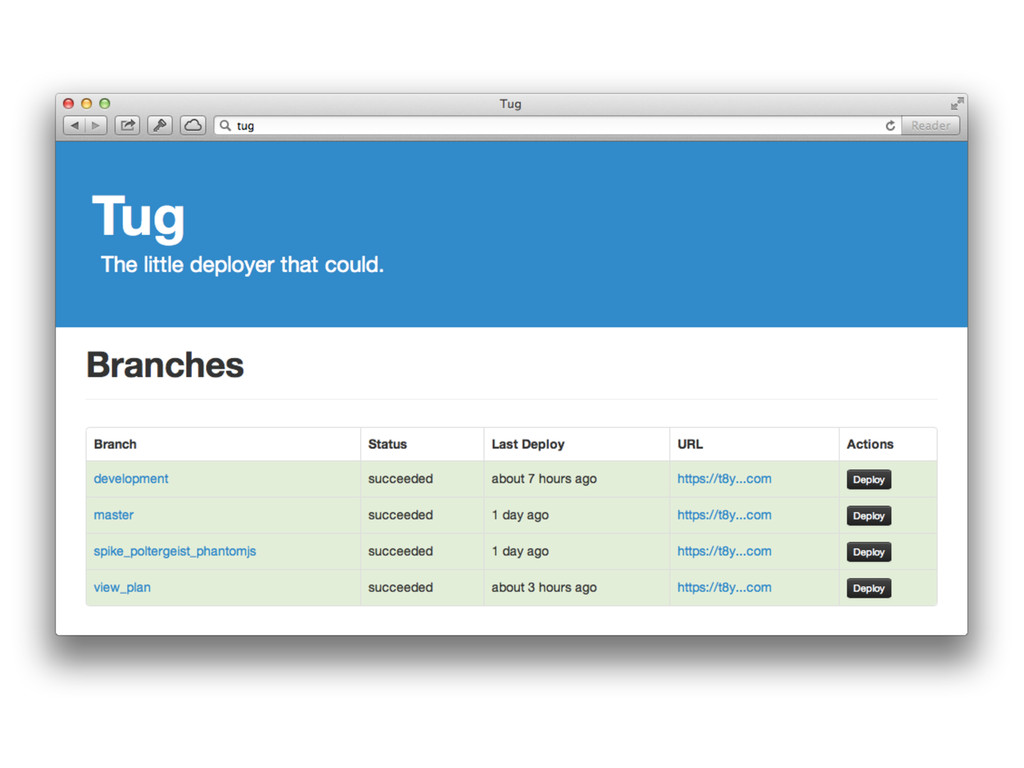
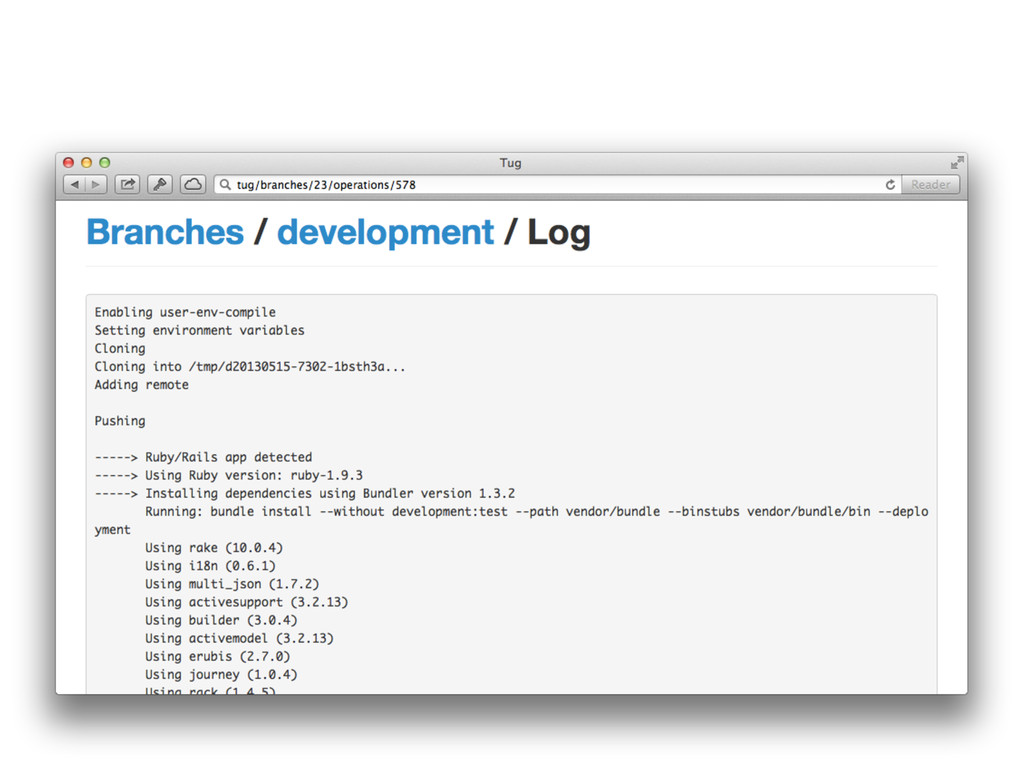
  3. • Listens for web hooks from GitHub • Queues deploy

    for new and existing branches • Queues teardown for deleted branches • Announces result on Campfire
  4. • Right amount of abstraction on top of AWS EC2

    • We see Heroku as a tool for provisioning instances • Could easily be some combination of Puppet, Chef or Vagrant
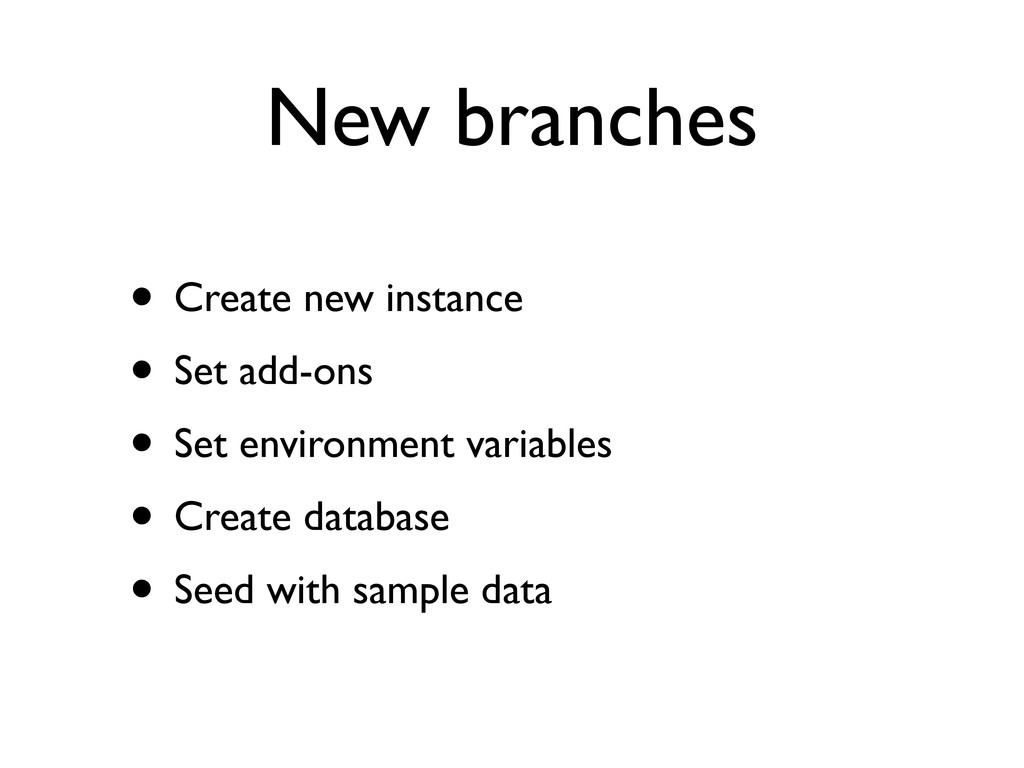
  5. New branches • Create new instance • Set add-ons •

    Set environment variables • Create database • Seed with sample data
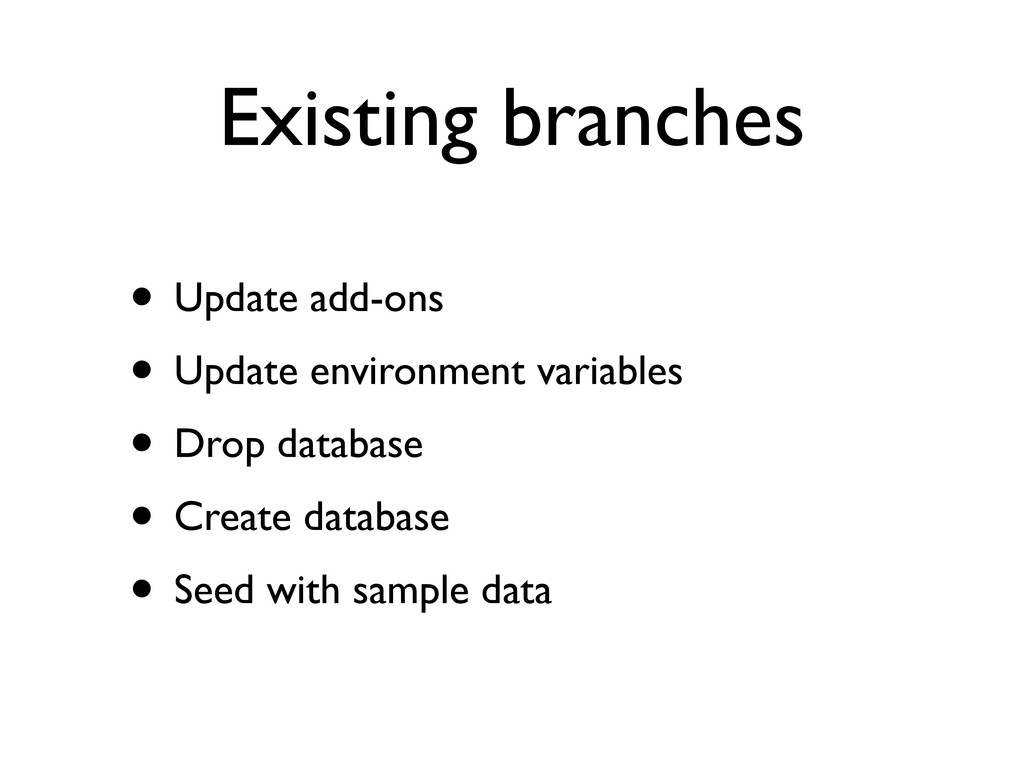
  6. Existing branches • Update add-ons • Update environment variables •

    Drop database • Create database • Seed with sample data
  7. Environment Variables • Sourced from application.yml or configuration variables (Heroku

    for ENV) • Tug injects configuration variables at deploy time • Mostly used for configuring external services (Eg: SMTP and AWS S3)
  8. External services • All external services have distinct credentials •

    Nothing is shared with production instances • For simplicity, staging instances share credentials
  9. • 1x web dyno running unicorn with three children processes

    • 1x worker dyno running delayed job for working off queue in background • PostgreSQL (Dev tier) • Difference between staging instances and production instances is number of dynos, database tier and monitoring add-ons Dynos and Add-ons
  10. Cheap ($) • 750 free dyno hours per month •

    Shuts down after 1 hour of inactivity • Unless someone is consuming all the time, pretty much free • Add-ons use free tier
  11. • No more waiting to try changes • We can

    turn around from discussion, to implementation and into the hands of a tester in less than a day
  12. • Caught out failed deploys before they hit production (Eg:

    Asset pipeline failed to compile) • Experiment with new configuration under controller conditions (Eg: Switch from Thin to Unicorn)
  13. • “End of iteration” demo’s are pain free. Nothing to

    setup, just go. • Better code reviews on pull requests. Try out code without stashing changes locally
  14. • Deploy after build is green • Continuous deployment for

    production • Make Tug available to other organisations if people think it’s valuable