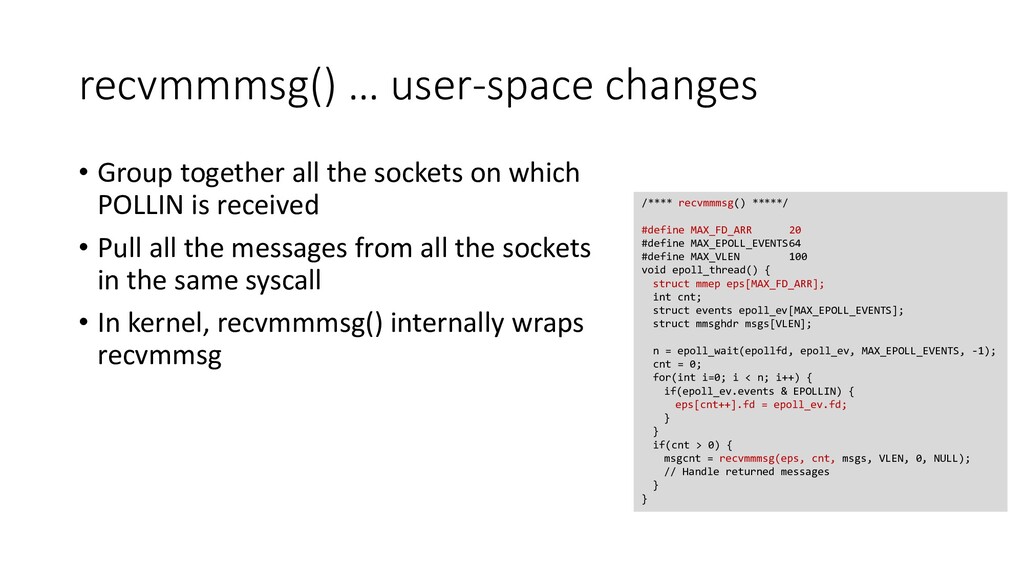
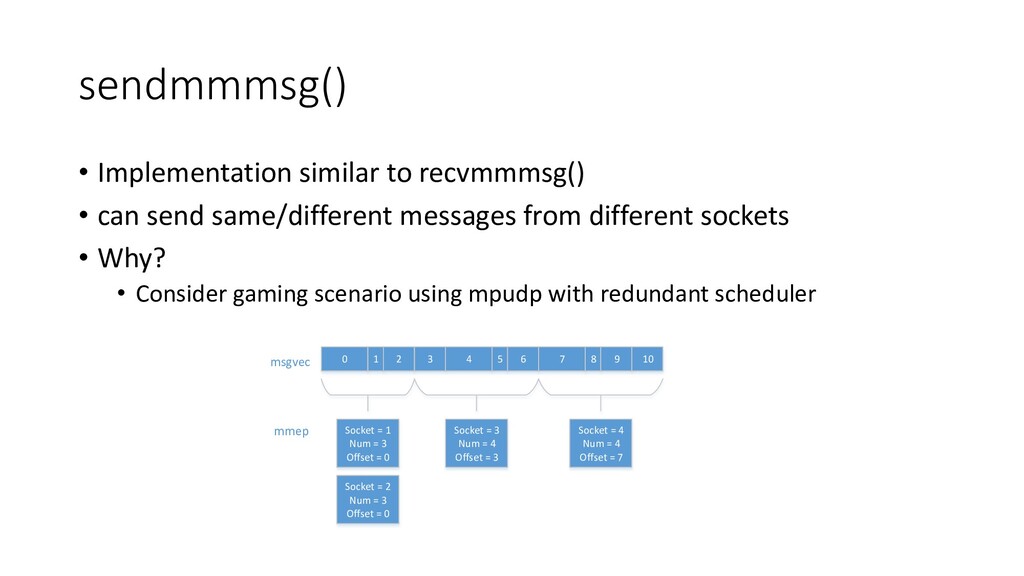
sockets • Both TCP and UDP sockets • Packet Rate characteristics • Less throughput (and packet-rate) per connection • But thousands of such connection • Reverse proxies • Handling thousands of connections in parallel (NGINX) • Multipath Transports • Send different/same packets on multiple sockets
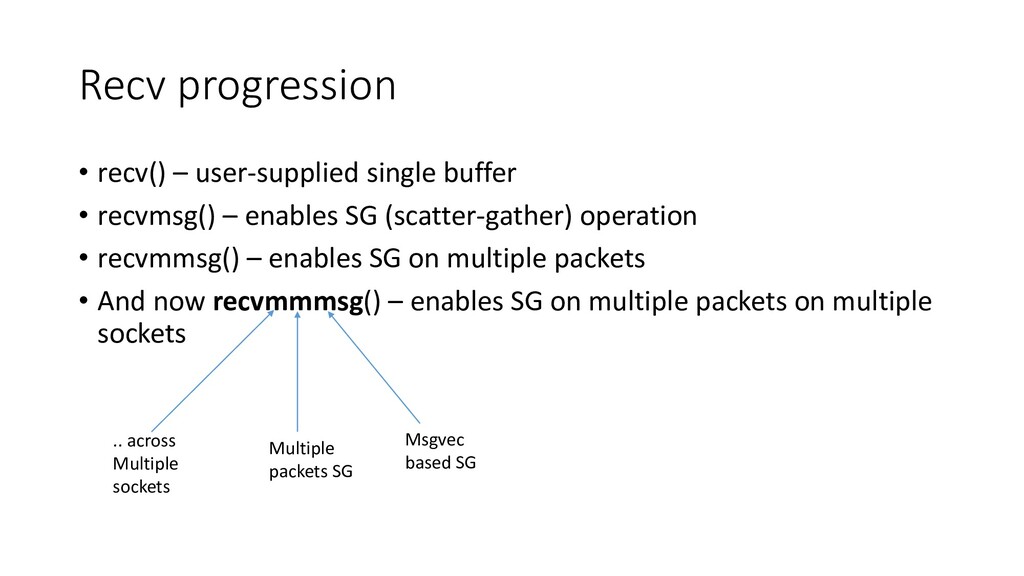
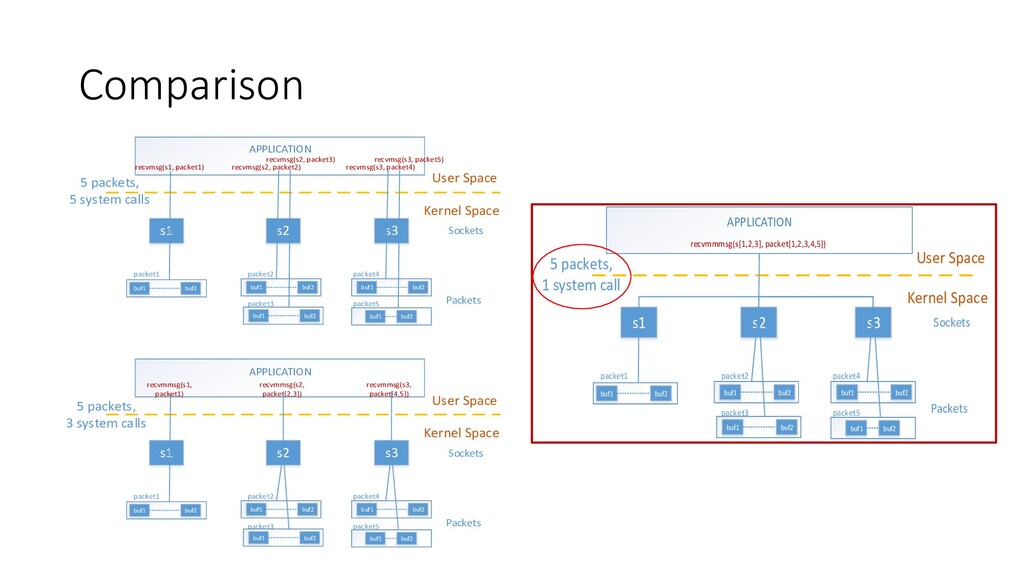
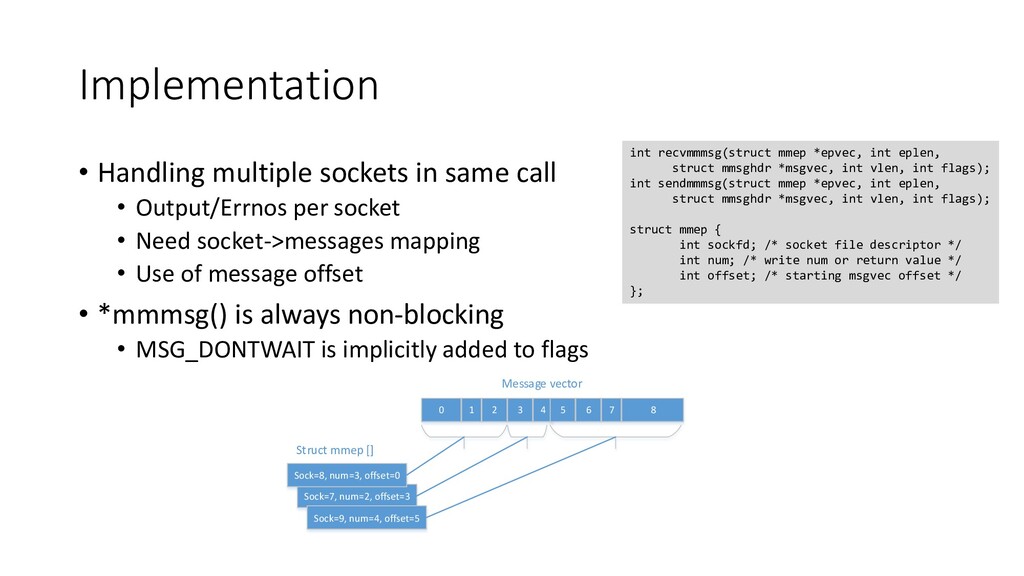
per socket • Need socket->messages mapping • Use of message offset • *mmmsg() is always non-blocking • MSG_DONTWAIT is implicitly added to flags int recvmmmsg(struct mmep *epvec, int eplen, struct mmsghdr *msgvec, int vlen, int flags); int sendmmmsg(struct mmep *epvec, int eplen, struct mmsghdr *msgvec, int vlen, int flags); struct mmep { int sockfd; /* socket file descriptor */ int num; /* write num or return value */ int offset; /* starting msgvec offset */ }; 0 1 2 3 4 Sock=7, num=2, offset=3 Sock=8, num=3, offset=0 Sock=9, num=4, offset=5 5 6 7 8 Struct mmep [] Message vector
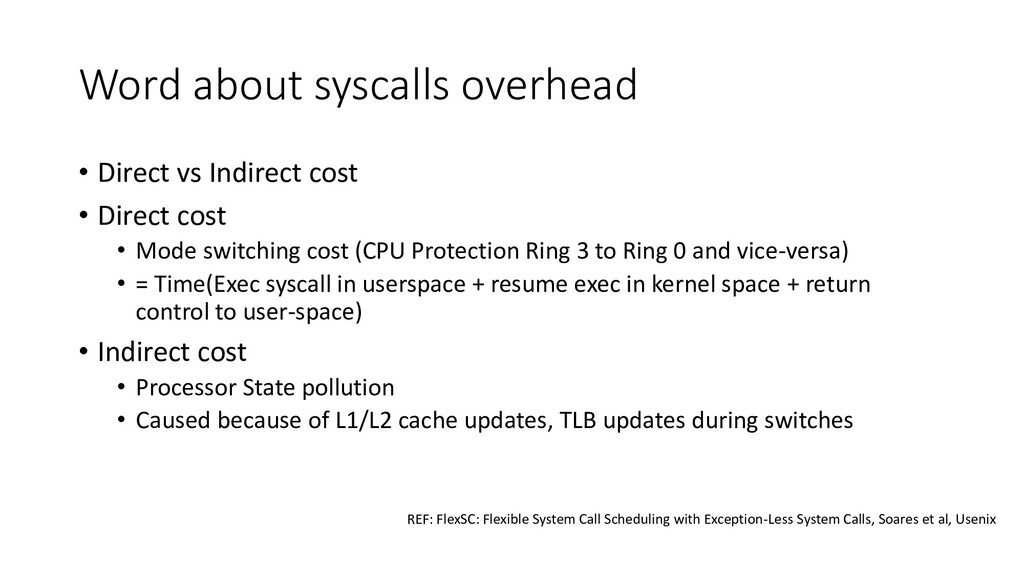
Direct cost • Mode switching cost (CPU Protection Ring 3 to Ring 0 and vice-versa) • = Time(Exec syscall in userspace + resume exec in kernel space + return control to user-space) • Indirect cost • Processor State pollution • Caused because of L1/L2 cache updates, TLB updates during switches REF: FlexSC: Flexible System Call Scheduling with Exception-Less System Calls, Soares et al, Usenix
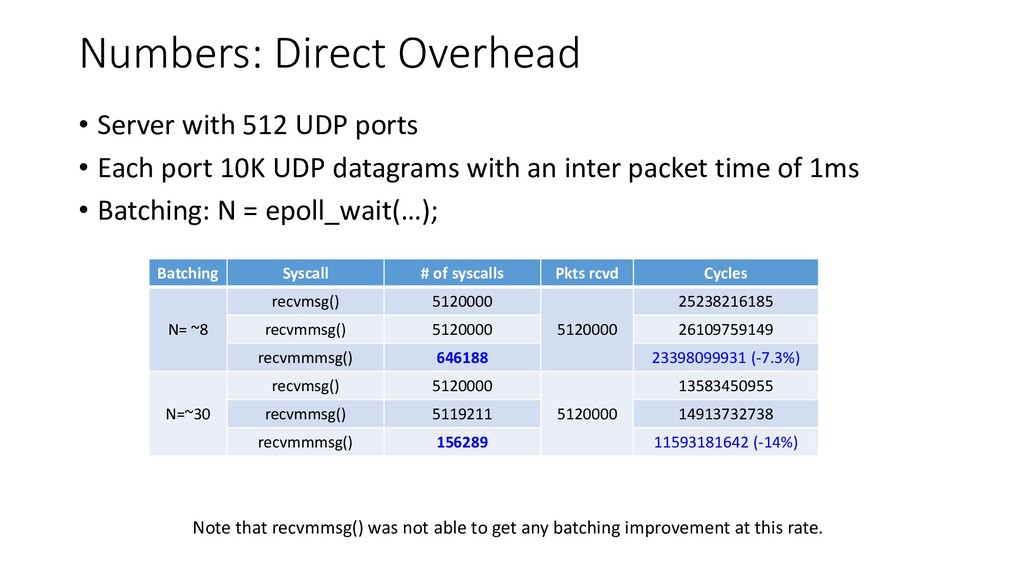
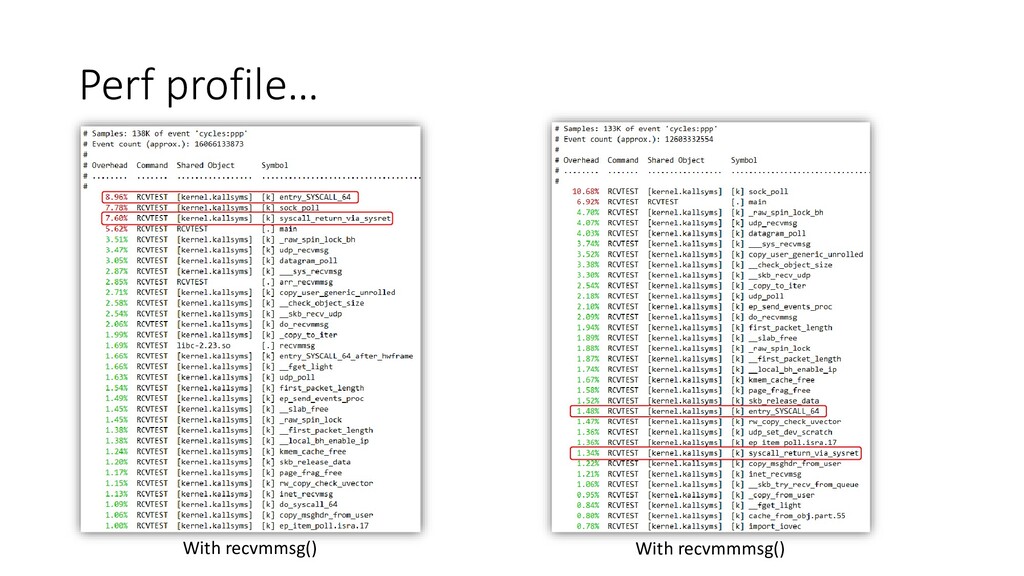
Each port 10K UDP datagrams with an inter packet time of 1ms • Batching: N = epoll_wait(…); Batching Syscall # of syscalls Pkts rcvd Cycles N= ~8 recvmsg() 5120000 5120000 25238216185 recvmmsg() 5120000 26109759149 recvmmmsg() 646188 23398099931 (-7.3%) N=~30 recvmsg() 5120000 5120000 13583450955 recvmmsg() 5119211 14913732738 recvmmmsg() 156289 11593181642 (-14%) Note that recvmmsg() was not able to get any batching improvement at this rate.
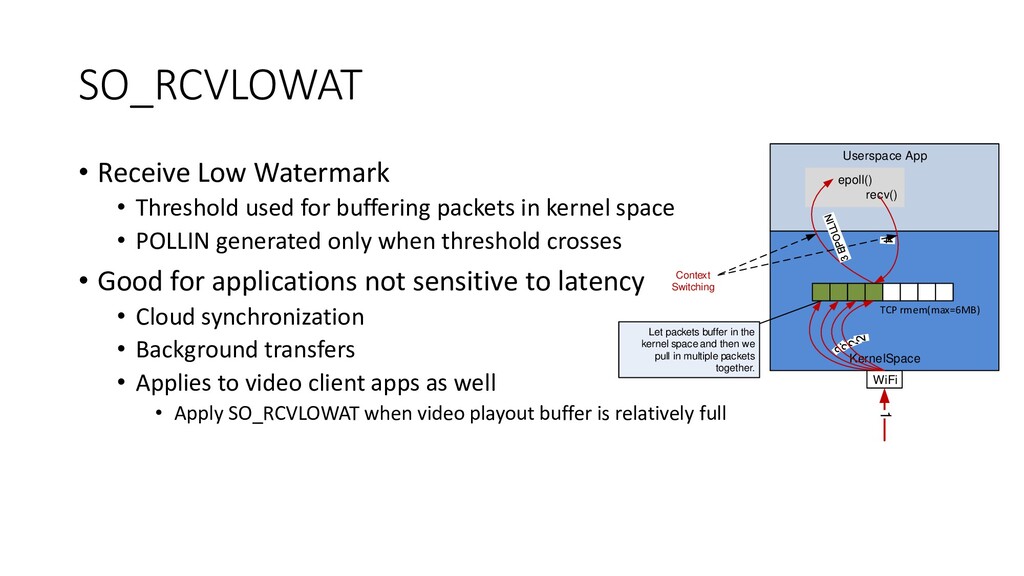
packets in kernel space • POLLIN generated only when threshold crosses • Good for applications not sensitive to latency • Cloud synchronization • Background transfers • Applies to video client apps as well • Apply SO_RCVLOWAT when video playout buffer is relatively full WiFi KernelSpace Userspace App 1 epoll() recv() TCP rmem(max=6MB) Context Switching Let packets buffer in the kernel space and then we pull in multiple packets together.
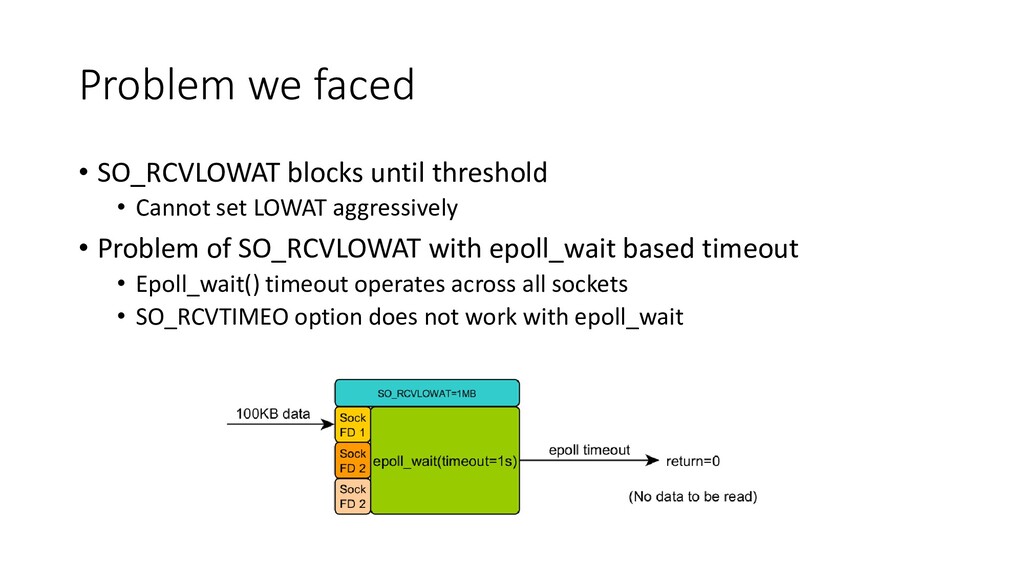
set LOWAT aggressively • Problem of SO_RCVLOWAT with epoll_wait based timeout • Epoll_wait() timeout operates across all sockets • SO_RCVTIMEO option does not work with epoll_wait
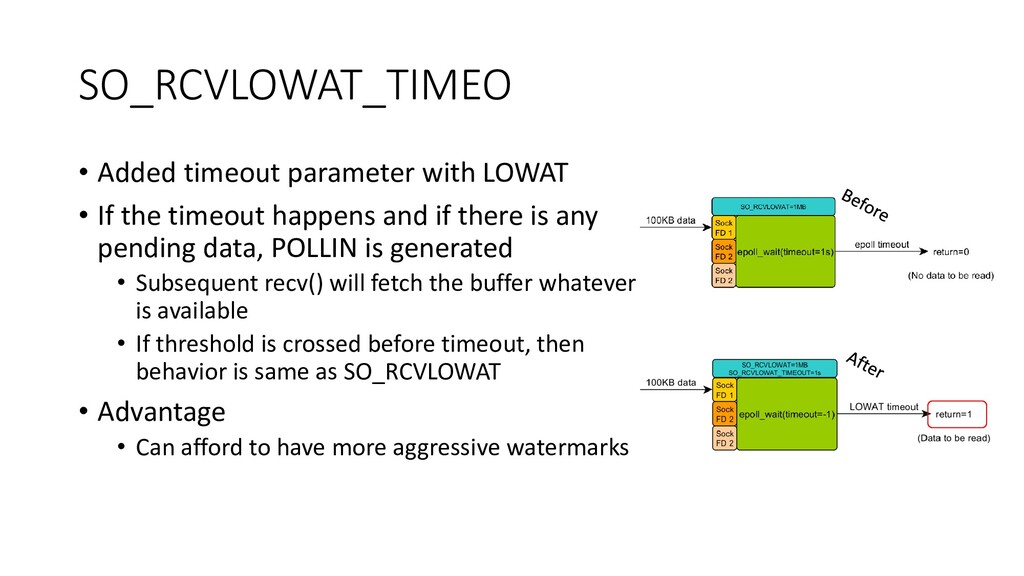
timeout happens and if there is any pending data, POLLIN is generated • Subsequent recv() will fetch the buffer whatever is available • If threshold is crossed before timeout, then behavior is same as SO_RCVLOWAT • Advantage • Can afford to have more aggressive watermarks
• *mmmsg(): Easy to use interfaces which gels with existing syscalls • Reduces system overhead for userspace multipath transports • SO_RCVLOWAT_TIMEO • Allows more aggressive watermark settings


 unmole
 jugyo
 yuukiw00w
 rkaga
 tsutsui
 camiha
 ktcryomm
 curekoshimizu
 atsuki_seo
 ivargrimstad
 s_shimotori
 riofujimon
 hideg
 stephenakadiri
 seathinner
 palkan
 kristinabergwall1
 aleyda
 nikkihalliwell
 rocio
 iamctodd
 kneath
 michaelherold
 axbom
 helmedeiros