From Resilience to Ultra-resilience of Data for...
Sponsored
·
 Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→

Share
Embed
From Resilience to Ultra-resilience of Data for Modern Applications
YugabyteDB Japan Meetup #5 - Karthik, YugabyteDB co-founder & co-CEO

YugabyteDB Japan
August 05, 2024
Transcript
73 slides
-
FROM RESILIENCE TO ULTRA-RESILIENCE OF DATA FOR MODERN APPLICATIONS Karthik
Ranganathan Co-Founder & Co-CEO, Yugabyte -
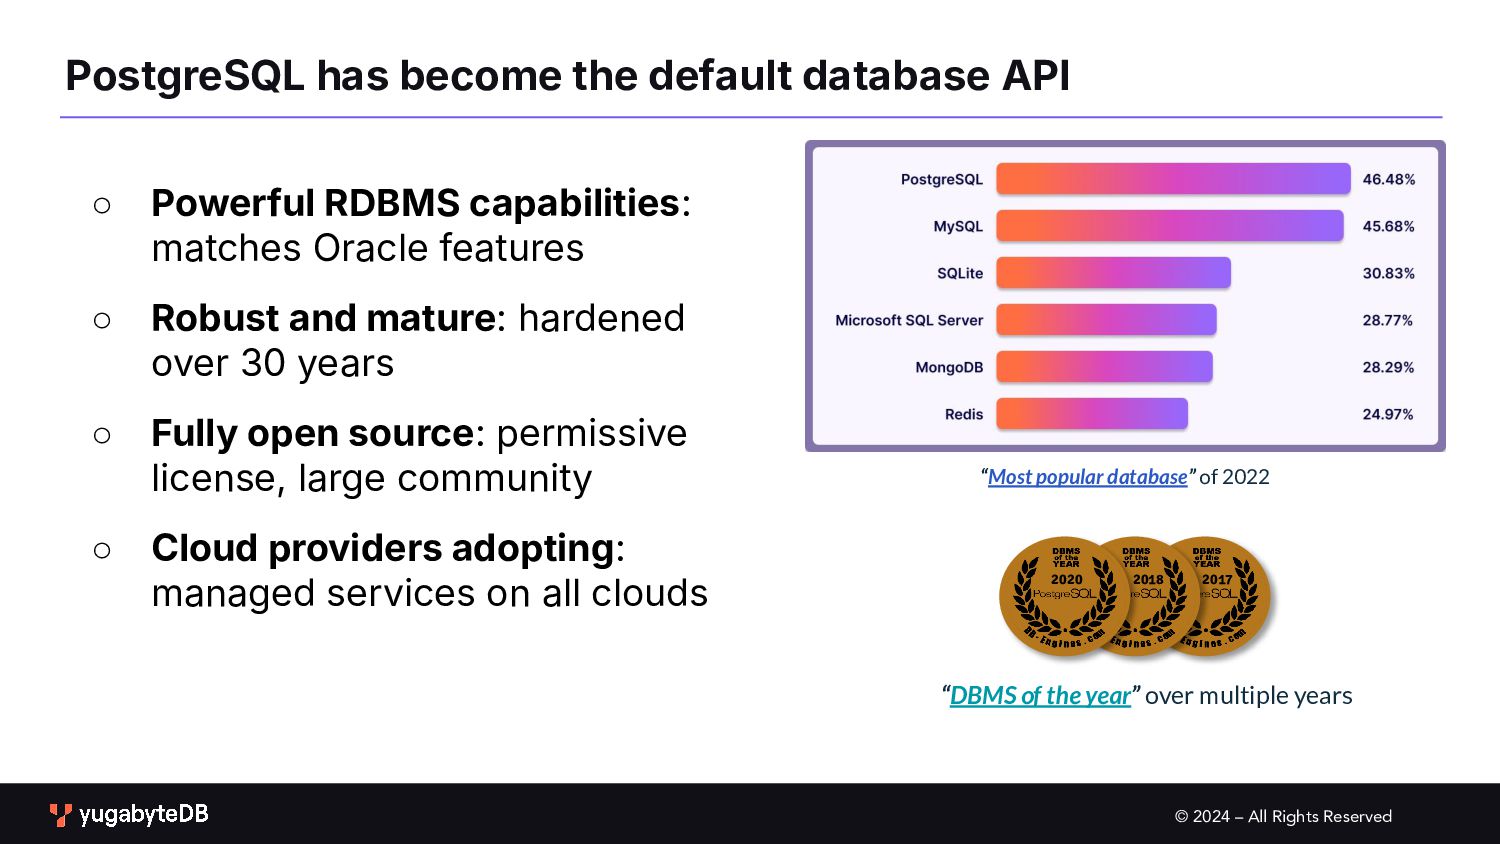
© 2024 – All Rights Reserved PostgreSQL has become the
default database API ◦ Powerful RDBMS capabilities: matches Oracle features ◦ Robust and mature: hardened over 30 years ◦ Fully open source: permissive license, large community ◦ Cloud providers adopting: managed services on all clouds “Most popular database” of 2022 “DBMS of the year” over multiple years 2017 2018 2020 -
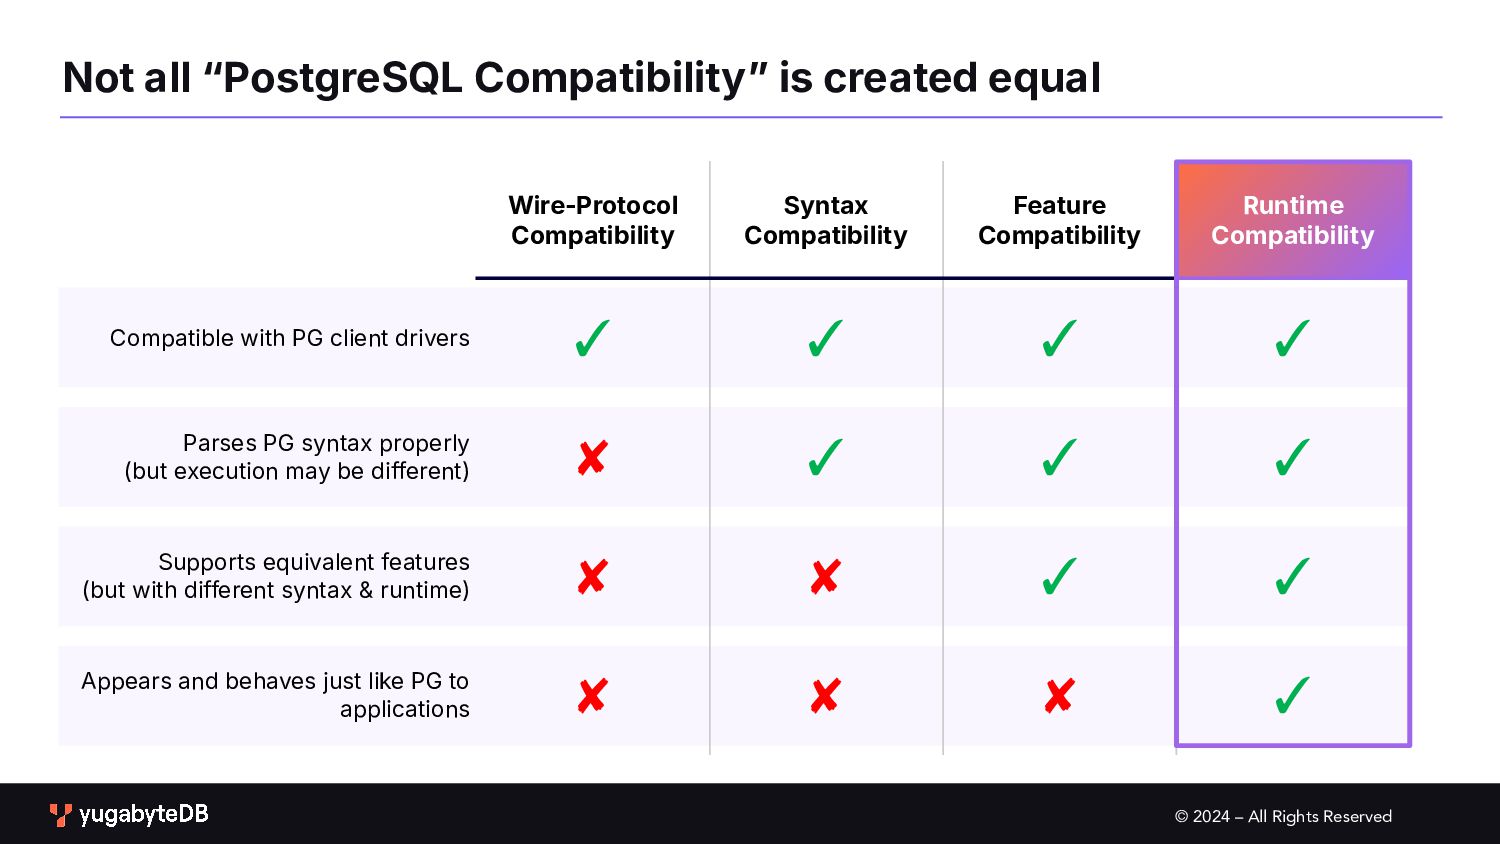
© 2024 – All Rights Reserved Wire-Protocol Compatibility Syntax Compatibility
Feature Compatibility Runtime Compatibility Compatible with PG client drivers ✓ ✓ ✓ ✓ Parses PG syntax properly (but execution may be different) ✘ ✓ ✓ ✓ Supports equivalent features (but with different syntax & runtime) ✘ ✘ ✓ ✓ Appears and behaves just like PG to applications ✘ ✘ ✘ ✓ Not all “PostgreSQL Compatibilityˮ is created equal -
© 2024 – All Rights Reserved 6 The ability of
a system to readily respond to or recover from change, disruption, or a crisis Resilience -
© 2024 – All Rights Reserved Just resilience is no
longer enough… -
© 2024 – All Rights Reserved Modern applications demand ultra-resilience
Customers expect always-on apps Nations run on digital infrastructure Brand reputation requires uptime -
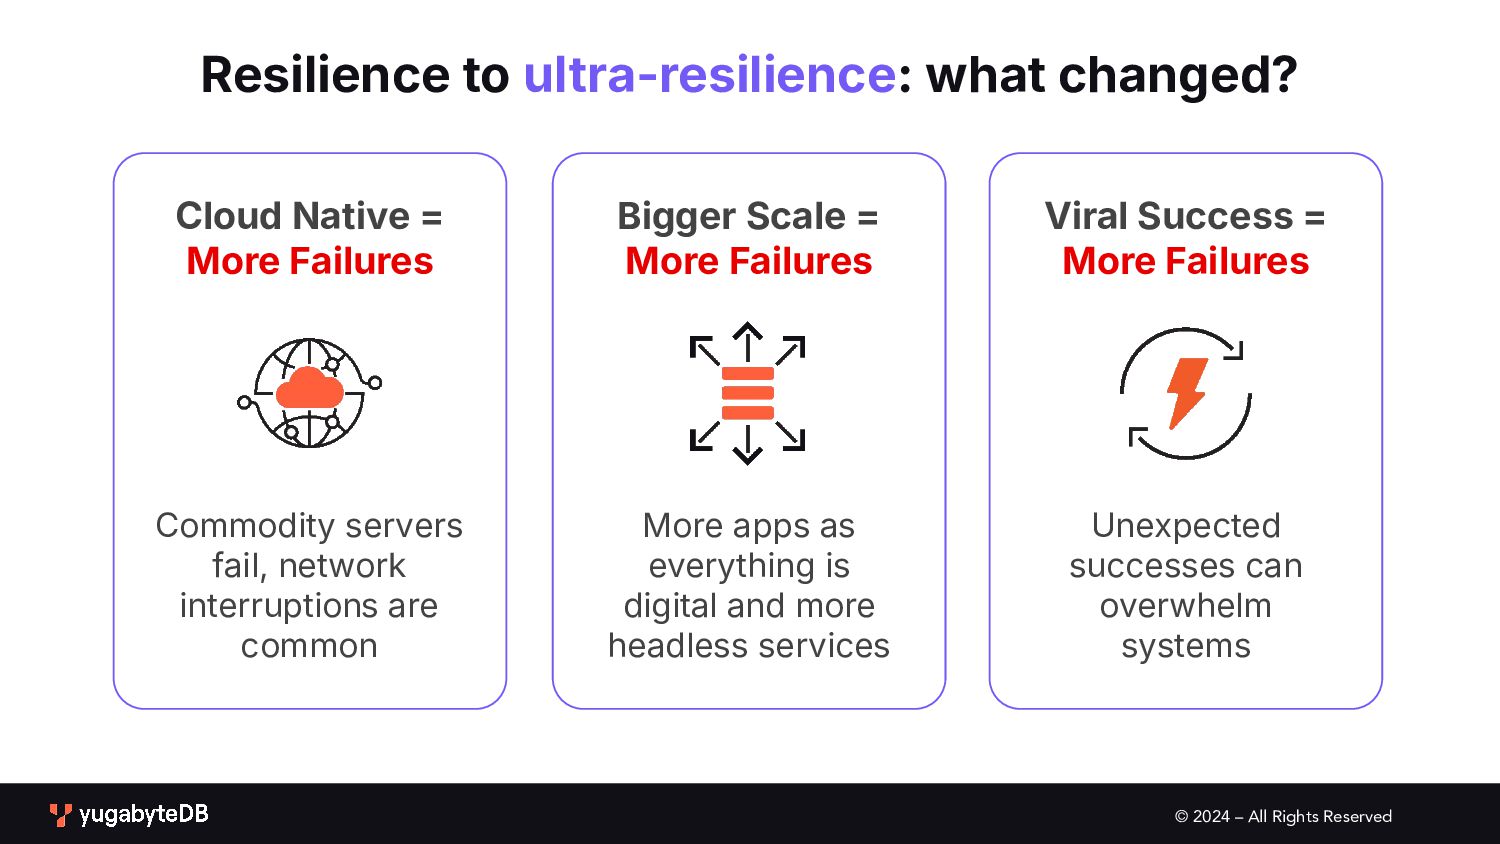
© 2024 – All Rights Reserved Commodity servers fail, network
interruptions are common More apps as everything is digital and more headless services Unexpected successes can overwhelm systems Resilience to ultra-resilience: what changed? Cloud Native = More Failures Bigger Scale = More Failures Viral Success = More Failures -
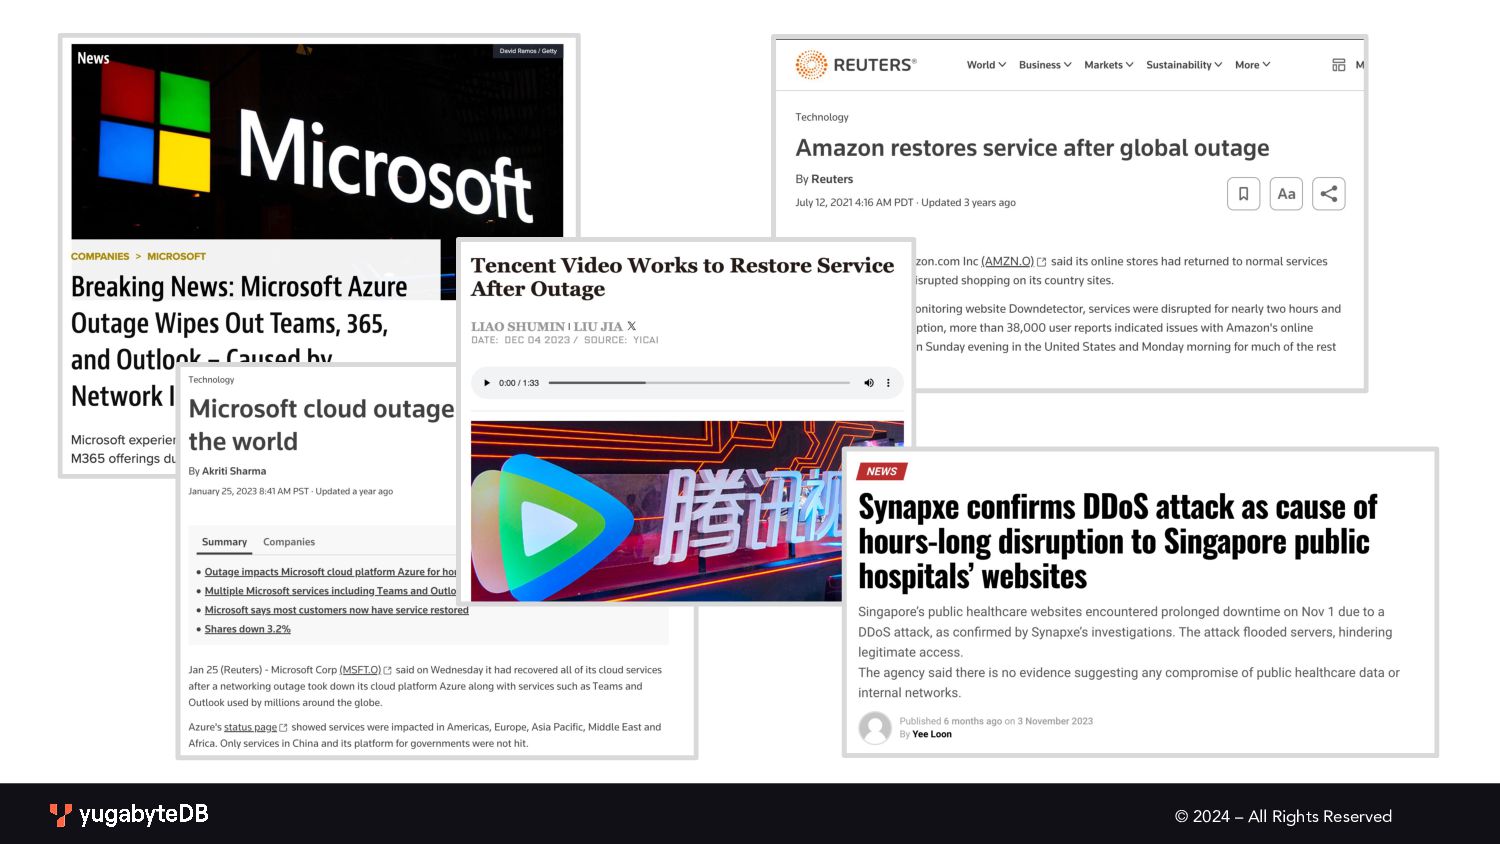
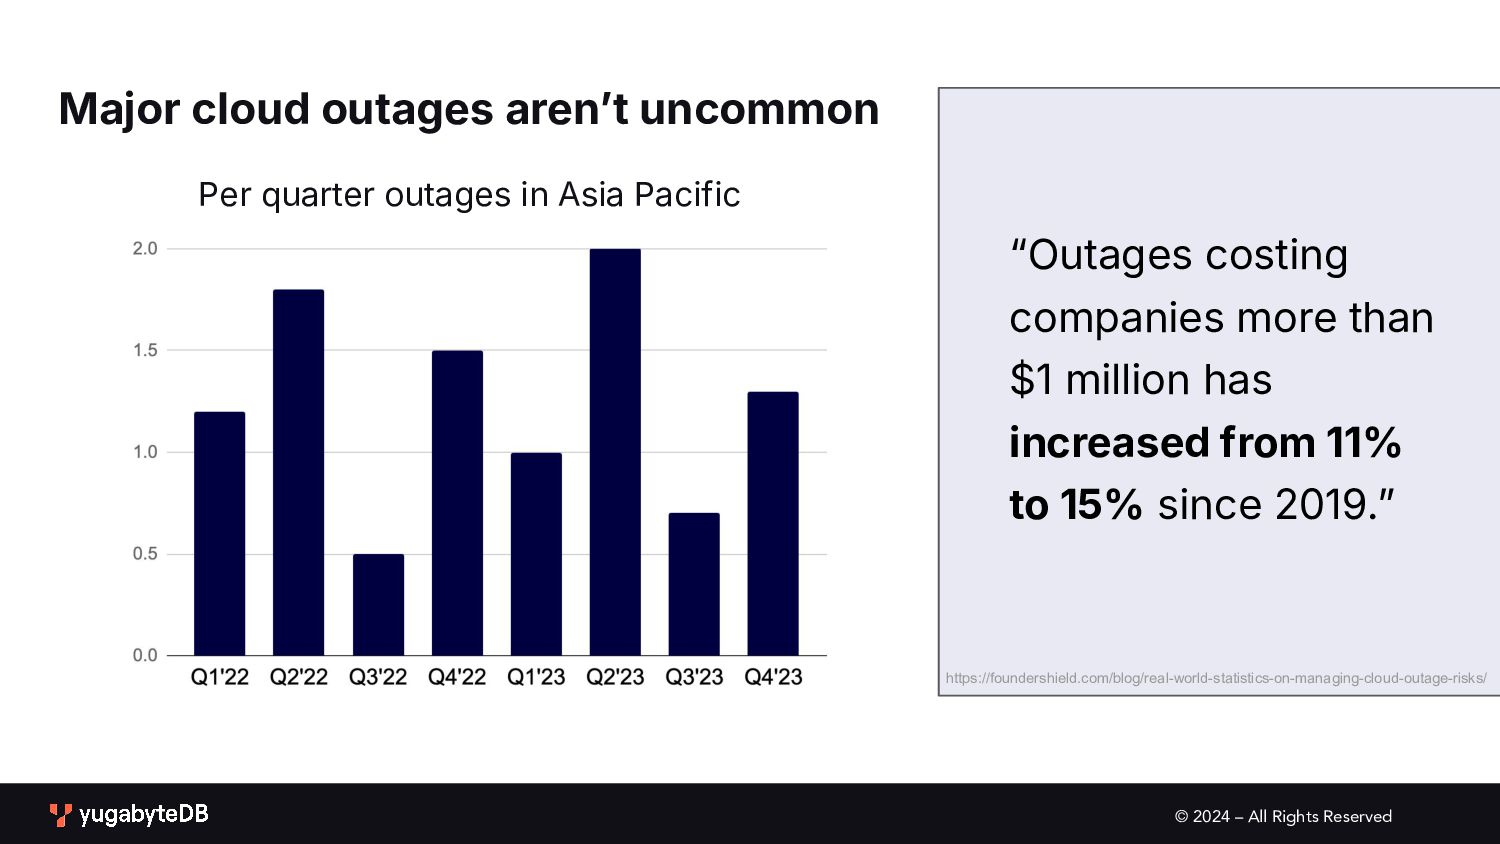
© 2024 – All Rights Reserved Major cloud outages arenʼt
uncommon Per quarter outages in Asia Pacific “Outages costing companies more than $1 million has increased from 11% to 15% since 2019.ˮ https://foundershield.com/blog/real-world-statistics-on-managing-cloud-outage-risks/ -
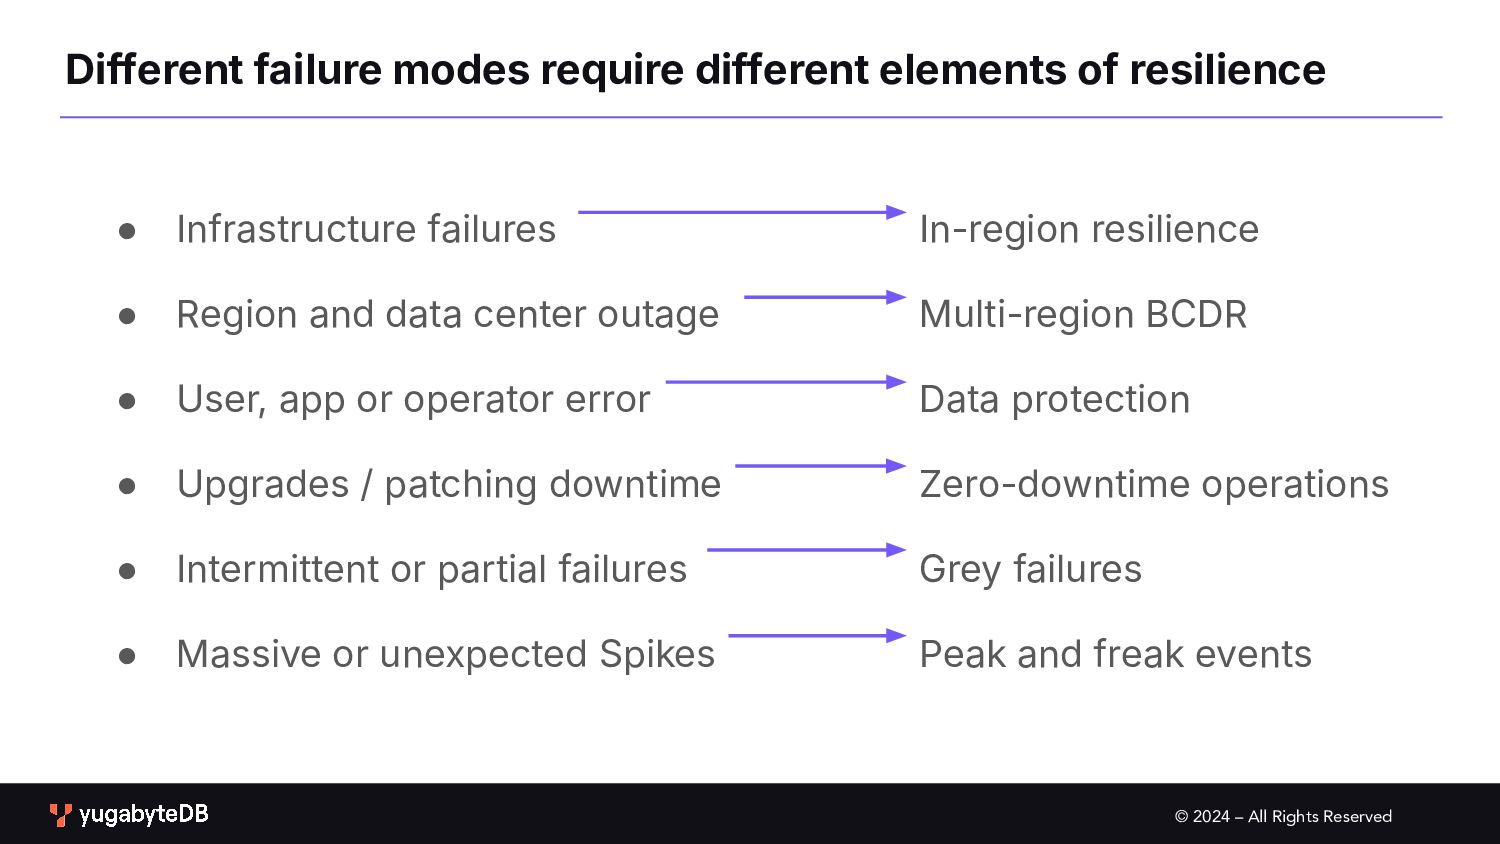
© 2024 – All Rights Reserved • Infrastructure failures •
Region and data center outage • User, app or operator error • Upgrades / patching downtime • Intermittent or partial failures • Massive or unexpected Spikes Different failure modes require different elements of resilience In-region resilience Multi-region BCDR Data protection Zero-downtime operations Grey failures Peak and freak events -
© 2024 – All Rights Reserved From resilience to ultra-resilience…
… for no downtime, no limits In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
© 2024 – All Rights Reserved Letʼs dive into the
six elements of ultra-resilience -
© 2024 – All Rights Reserved Six Elements of Ultra-Resilience
In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
© 2024 – All Rights Reserved ✓ Disk, node, and
zone failures ✓ Network partitions ✓ Back-end process failures What is in-region resilience? -
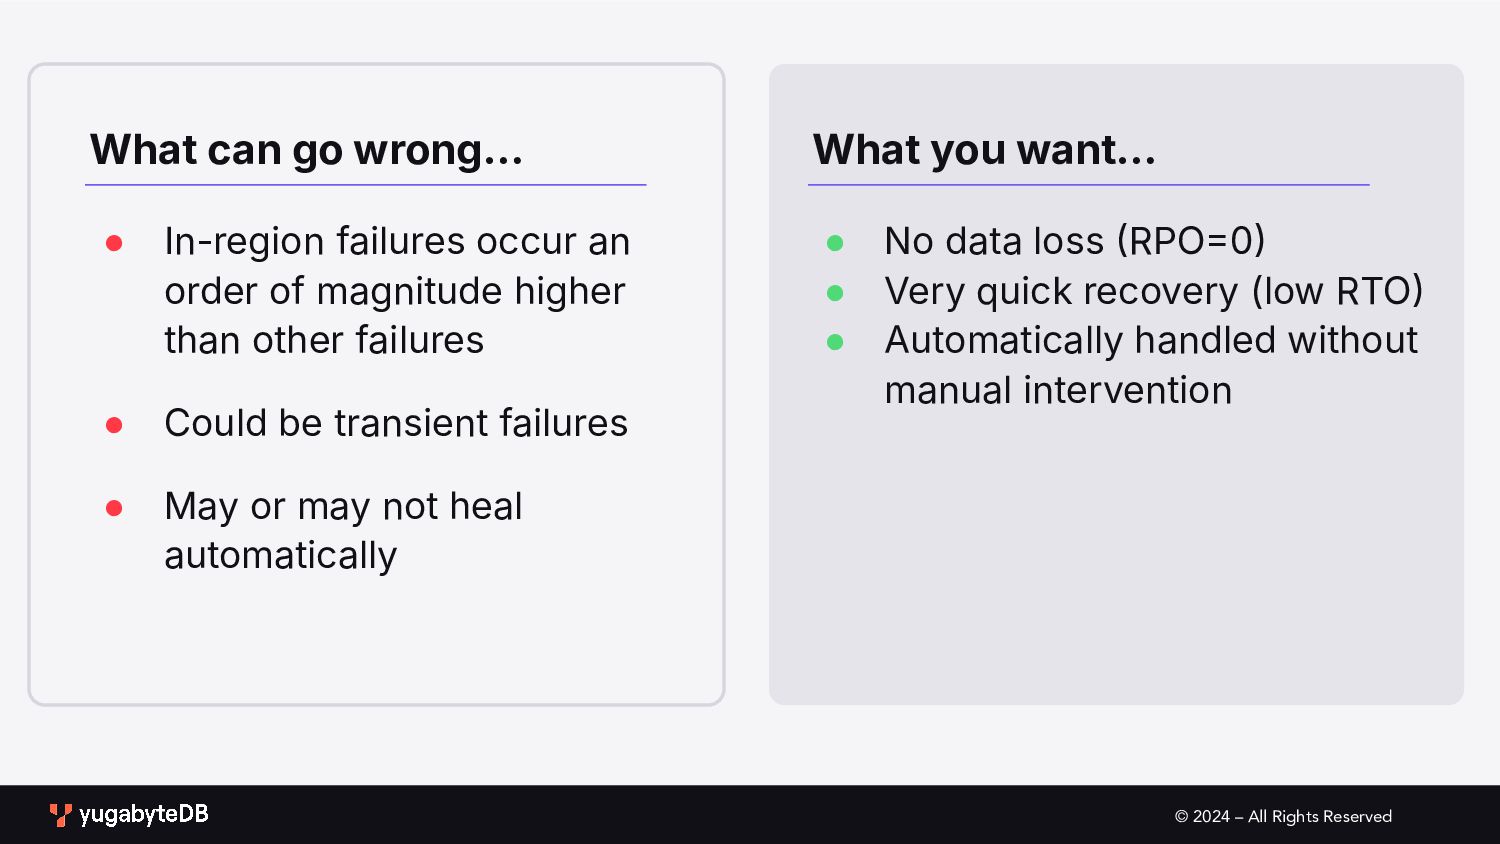
© 2024 – All Rights Reserved • In-region failures occur
an order of magnitude higher than other failures • Could be transient failures • May or may not heal automatically • No data loss RPO0 • Very quick recovery (low RTO • Automatically handled without manual intervention What can go wrong… What you want… -
© 2024 – All Rights Reserved Letʼs explore four common
in-region challenges 1. Node failure 2. Zone failure 3. Network partition 4. Application architecture -
© 2024 – All Rights Reserved Zone A Zone B
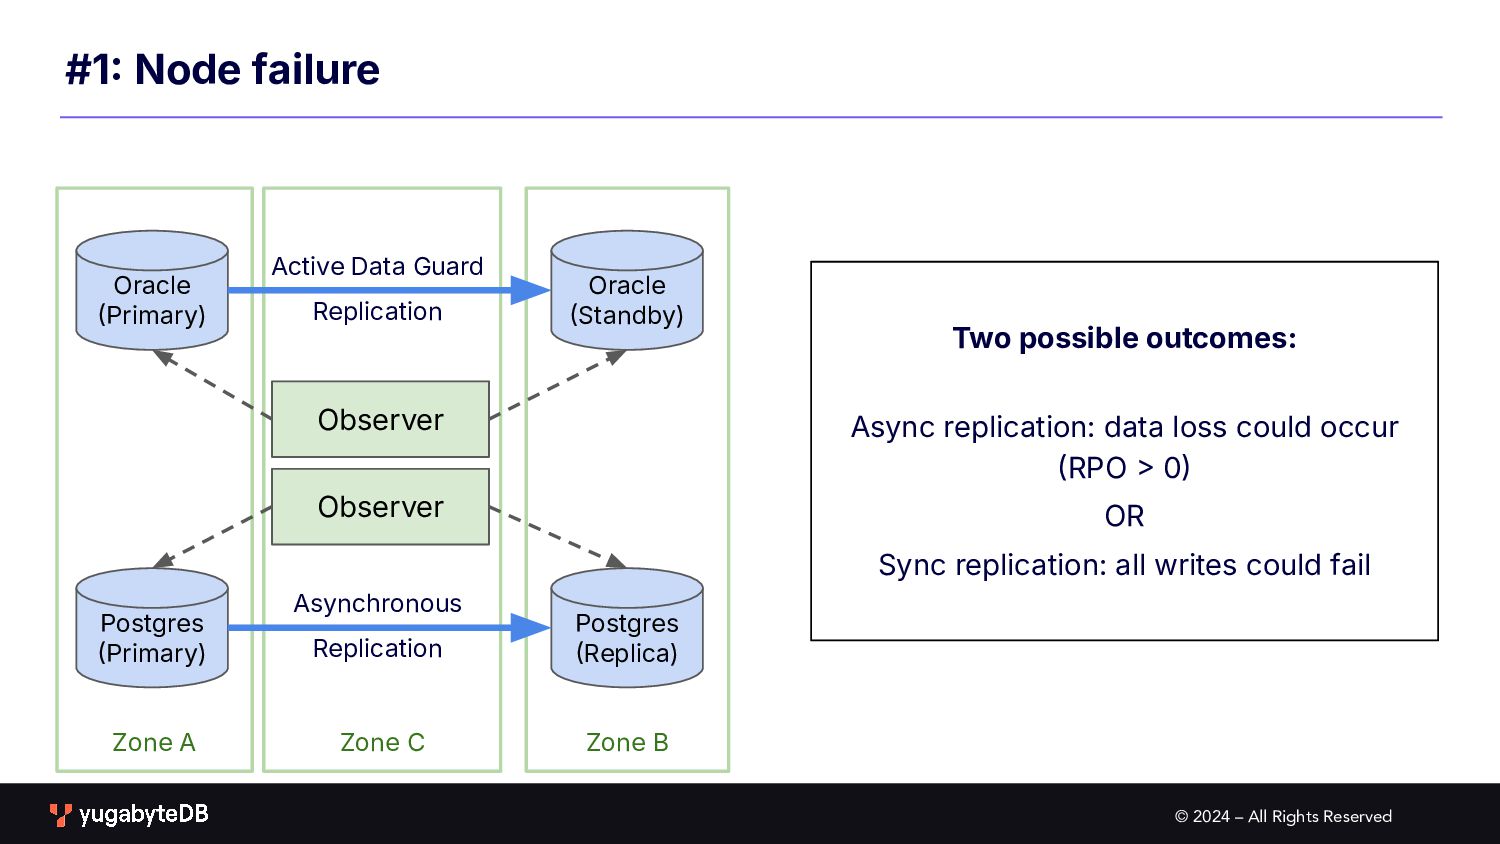
Zone C #1 Node failure Oracle Primary) Oracle Standby) Active Data Guard Replication Postgres Primary) Postgres Replica) Asynchronous Replication Observer Observer Two possible outcomes: Async replication: data loss could occur RPO 0 OR Sync replication: all writes could fail -
© 2024 – All Rights Reserved Zone A Zone B
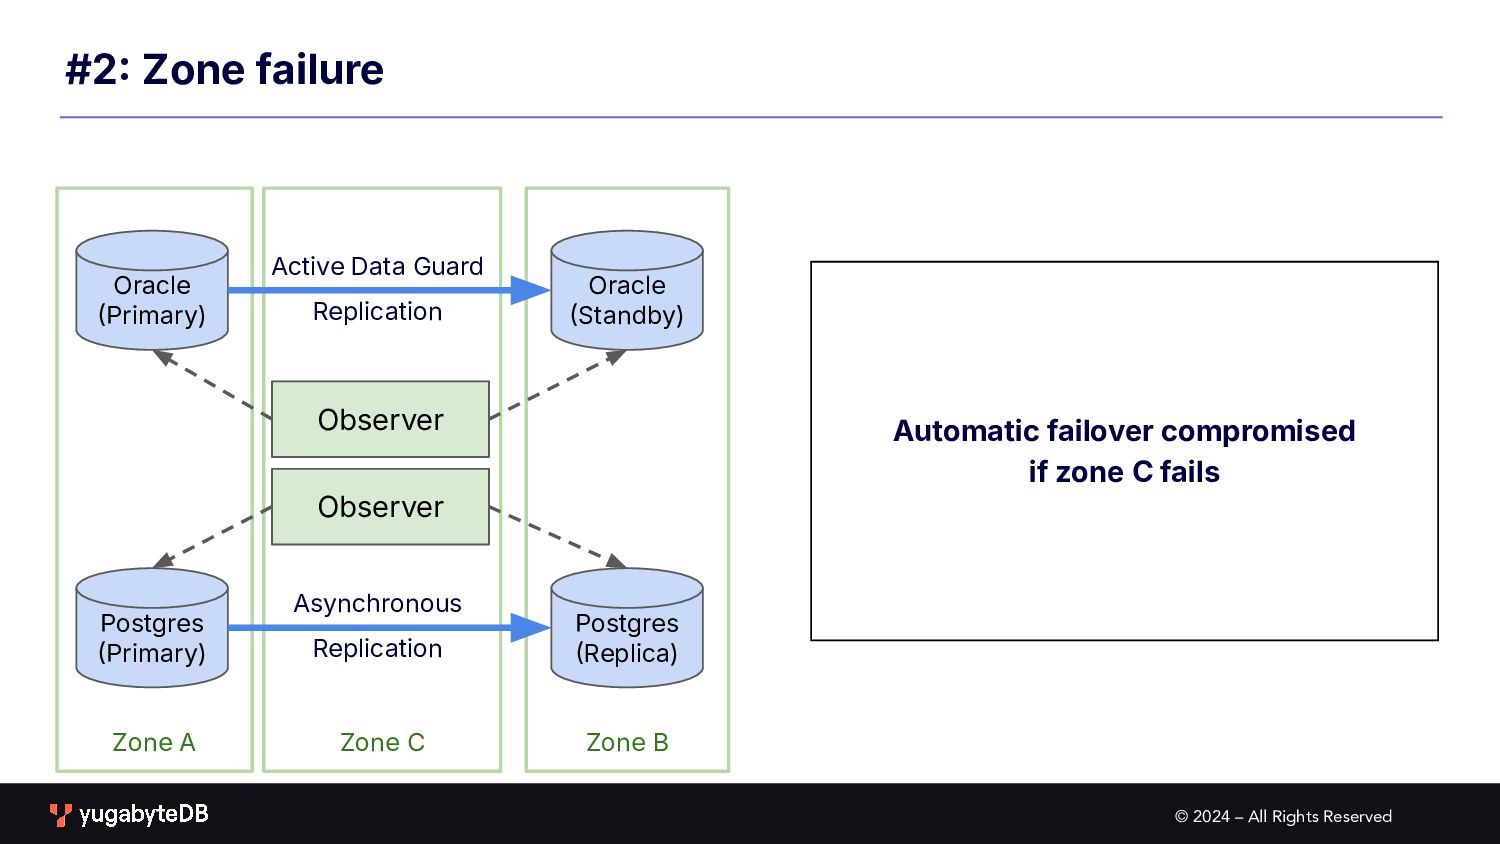
Zone C #2 Zone failure Oracle Primary) Oracle Standby) Active Data Guard Replication Postgres Primary) Postgres Replica) Asynchronous Replication Observer Observer Automatic failover compromised if zone C fails -
© 2024 – All Rights Reserved Zone A Zone B
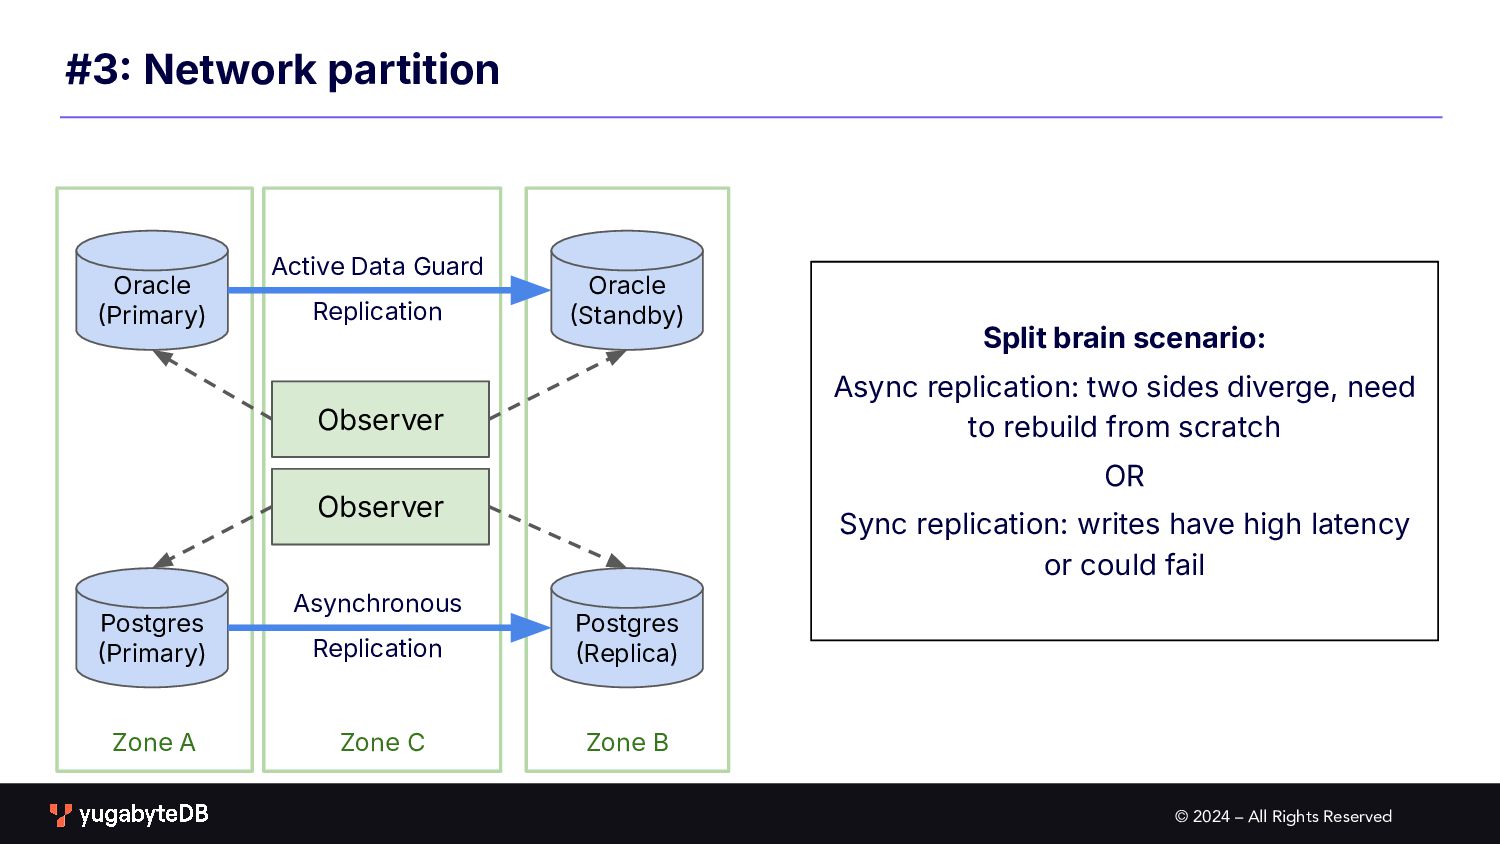
Zone C #3 Network partition Oracle Primary) Oracle Standby) Active Data Guard Replication Postgres Primary) Postgres Replica) Asynchronous Replication Observer Observer Split brain scenario: Async replication: two sides diverge, need to rebuild from scratch OR Sync replication: writes have high latency or could fail -
© 2024 – All Rights Reserved Zone A Zone B
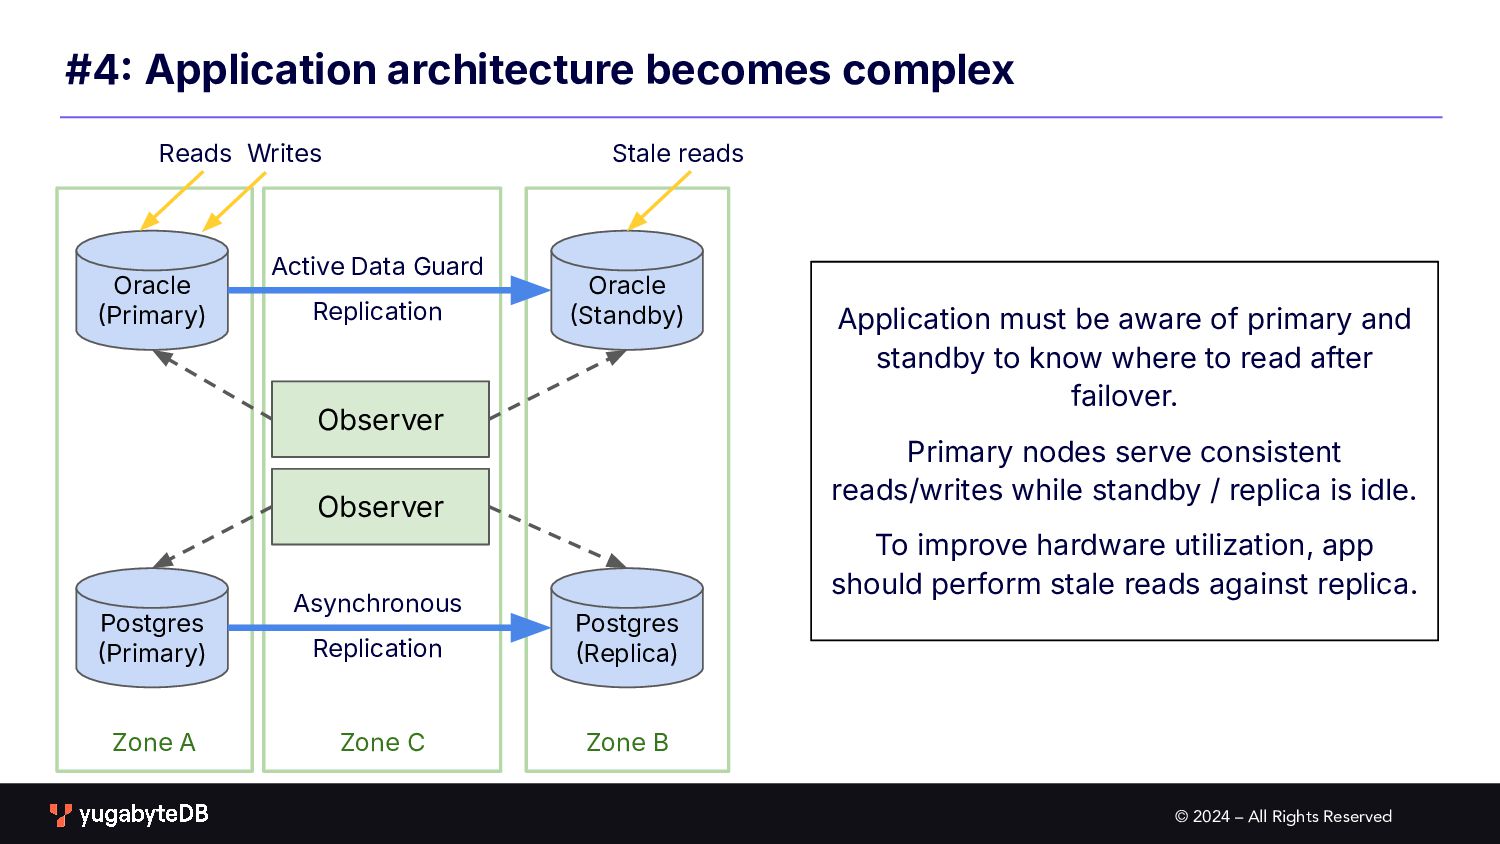
Zone C #4 Application architecture becomes complex Oracle Primary) Oracle Standby) Active Data Guard Replication Postgres Primary) Postgres Replica) Asynchronous Replication Observer Observer Reads Writes Stale reads Application must be aware of primary and standby to know where to read after failover. Primary nodes serve consistent reads/writes while standby / replica is idle. To improve hardware utilization, app should perform stale reads against replica. -
© 2024 – All Rights Reserved Distributed SQL solves these
challenges natively -
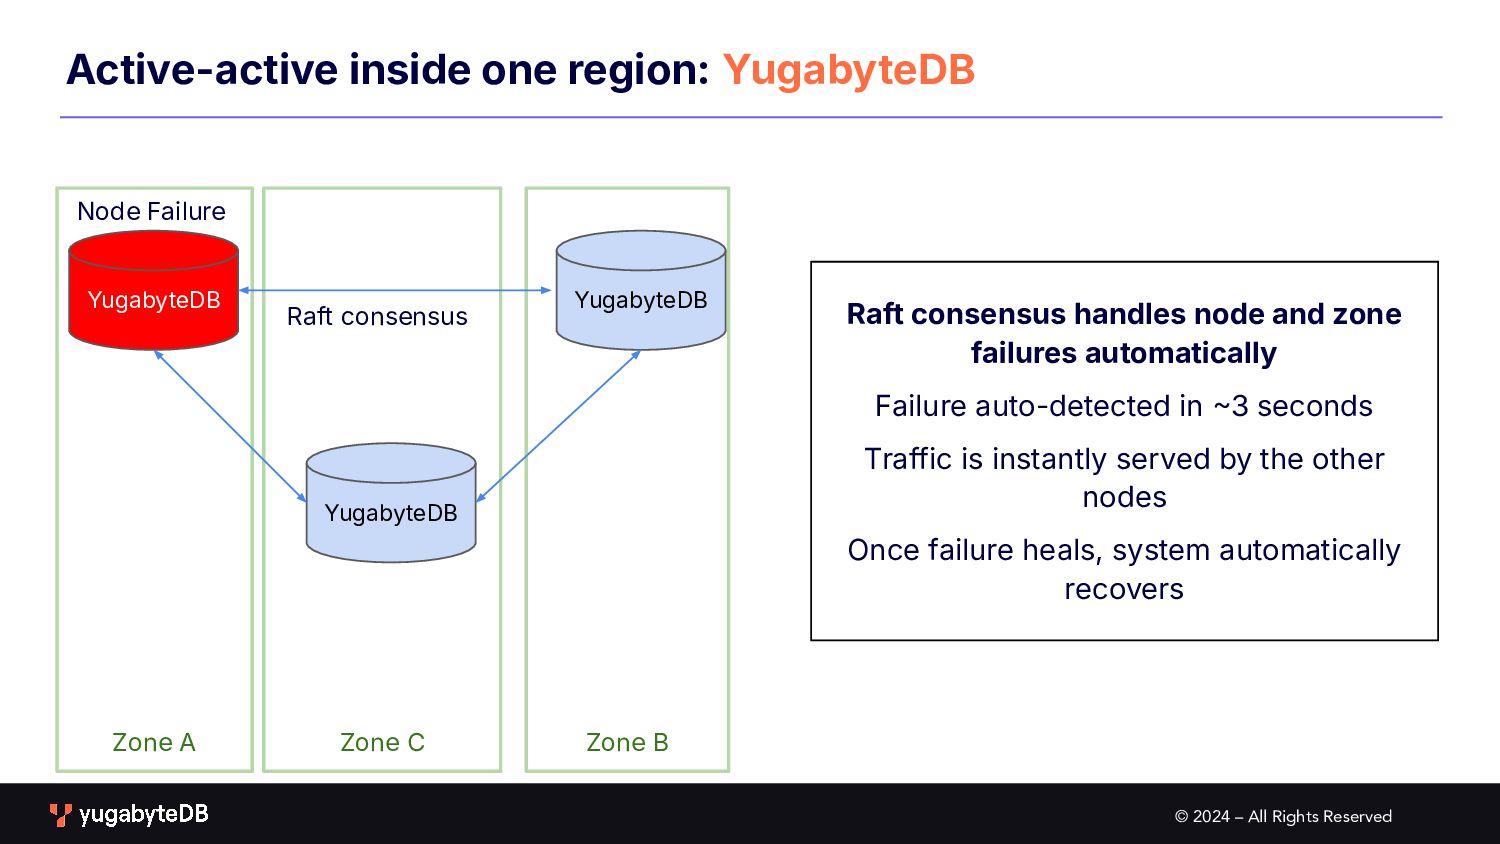
© 2024 – All Rights Reserved Zone C Zone B
Zone A Active-active inside one region: YugabyteDB YugabyteDB Raft consensus YugabyteDB YugabyteDB Raft consensus handles node and zone failures automatically Failure auto-detected in 3 seconds Traffic is instantly served by the other nodes Once failure heals, system automatically recovers Node Failure -
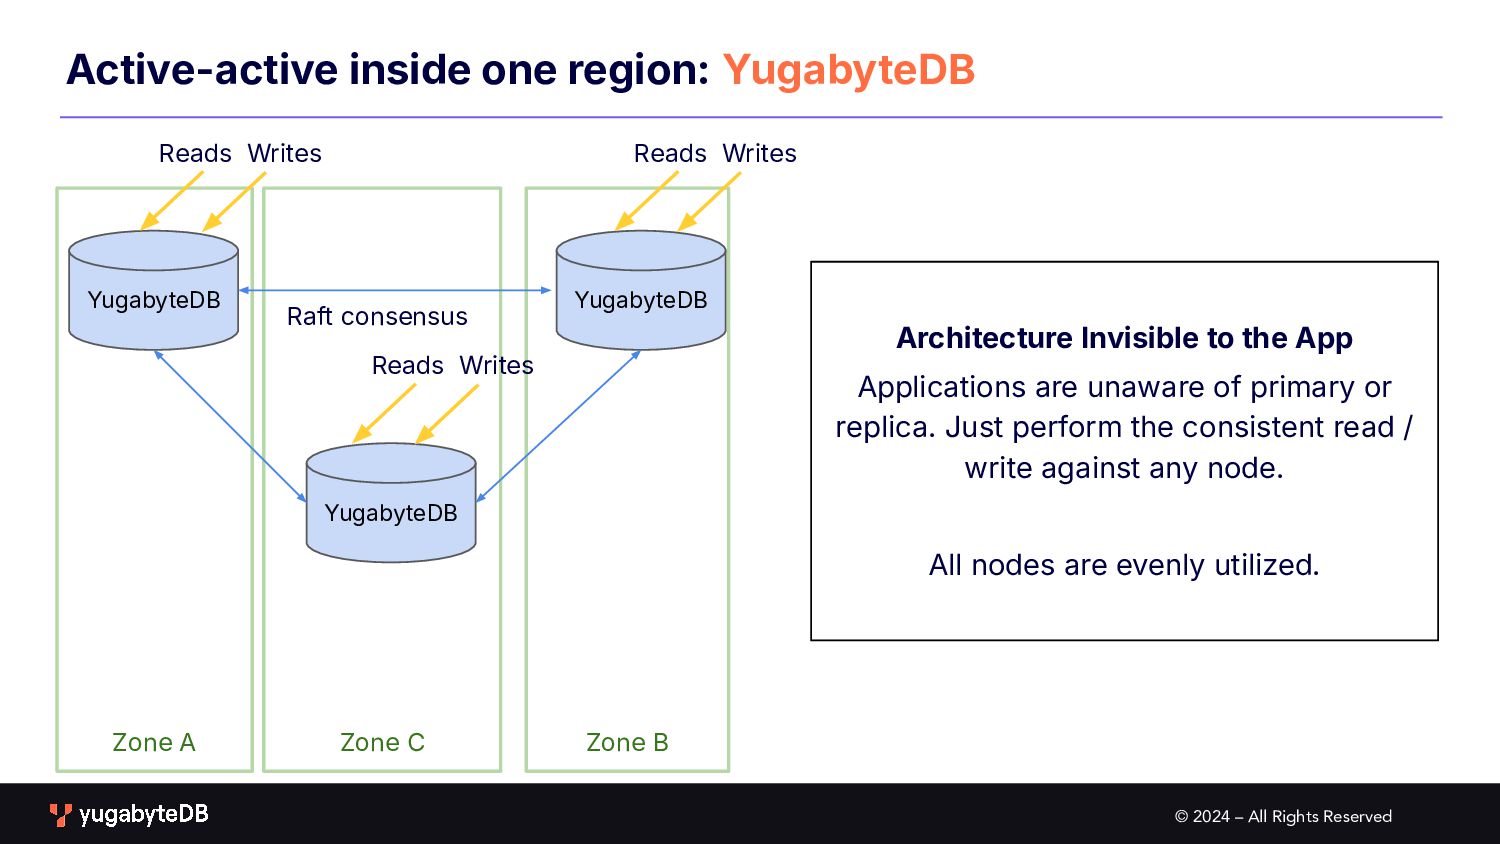
© 2024 – All Rights Reserved Zone C Zone B
Zone A Active-active inside one region: YugabyteDB YugabyteDB Raft consensus YugabyteDB YugabyteDB Reads Writes Reads Writes Reads Writes Architecture Invisible to the App Applications are unaware of primary or replica. Just perform the consistent read / write against any node. All nodes are evenly utilized. -
© 2024 – All Rights Reserved Six Elements of Ultra-Resilience
In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
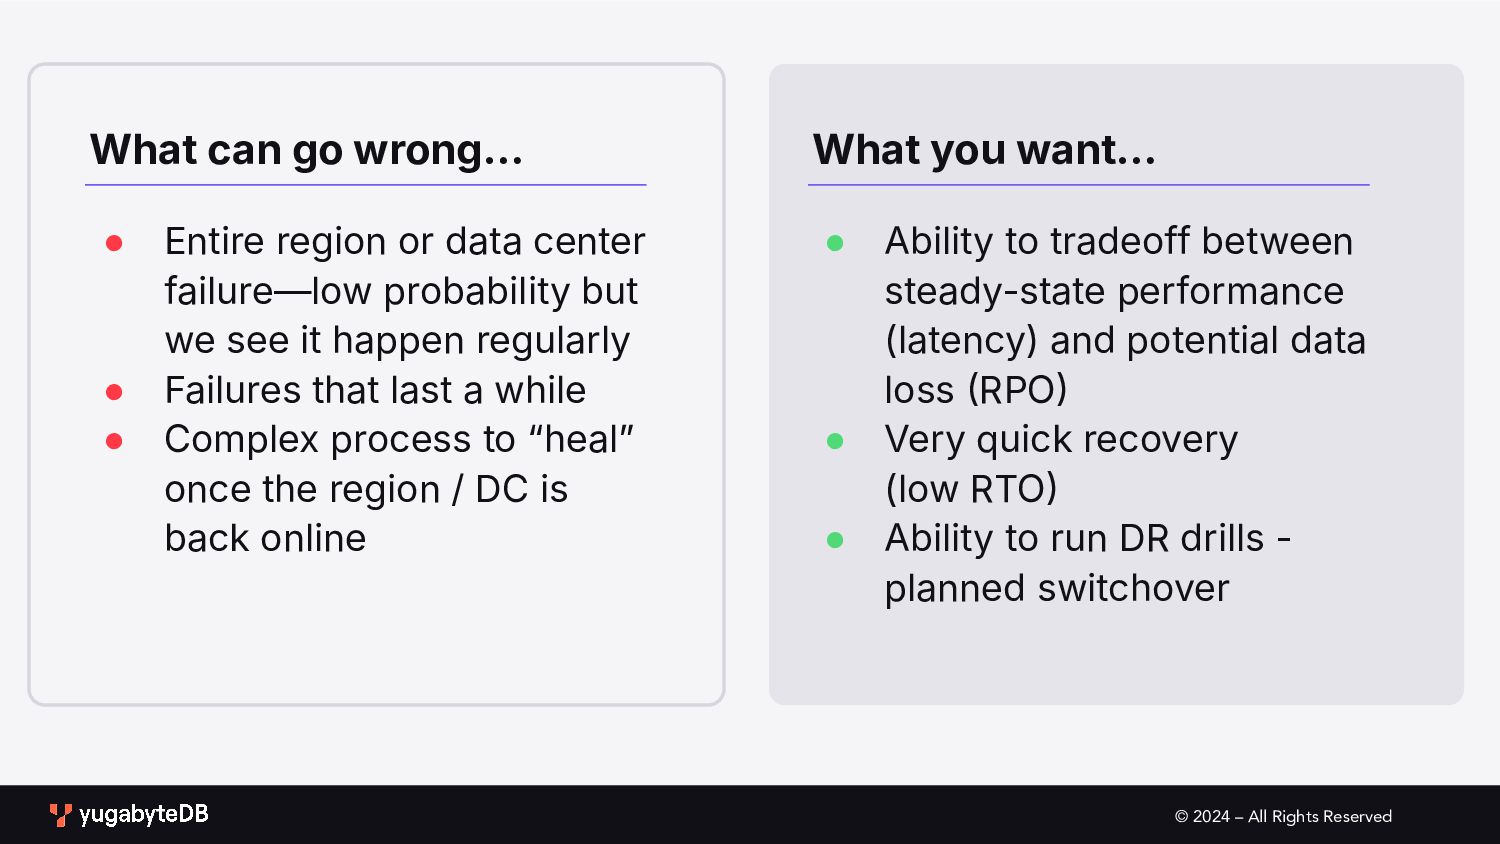
© 2024 – All Rights Reserved • Entire region or
data center failure—low probability but we see it happen regularly • Failures that last a while • Complex process to “healˮ once the region / DC is back online • Ability to tradeoff between steady-state performance (latency) and potential data loss RPO • Very quick recovery (low RTO • Ability to run DR drills - planned switchover What can go wrong… What you want… -
© 2024 – All Rights Reserved Application Architecture: High-level structure
of an application, defining how data flows to deliver functionality Availability Architecture: Design principles and features that ensure continuous operation and minimize downtime Two dimensions to consider -
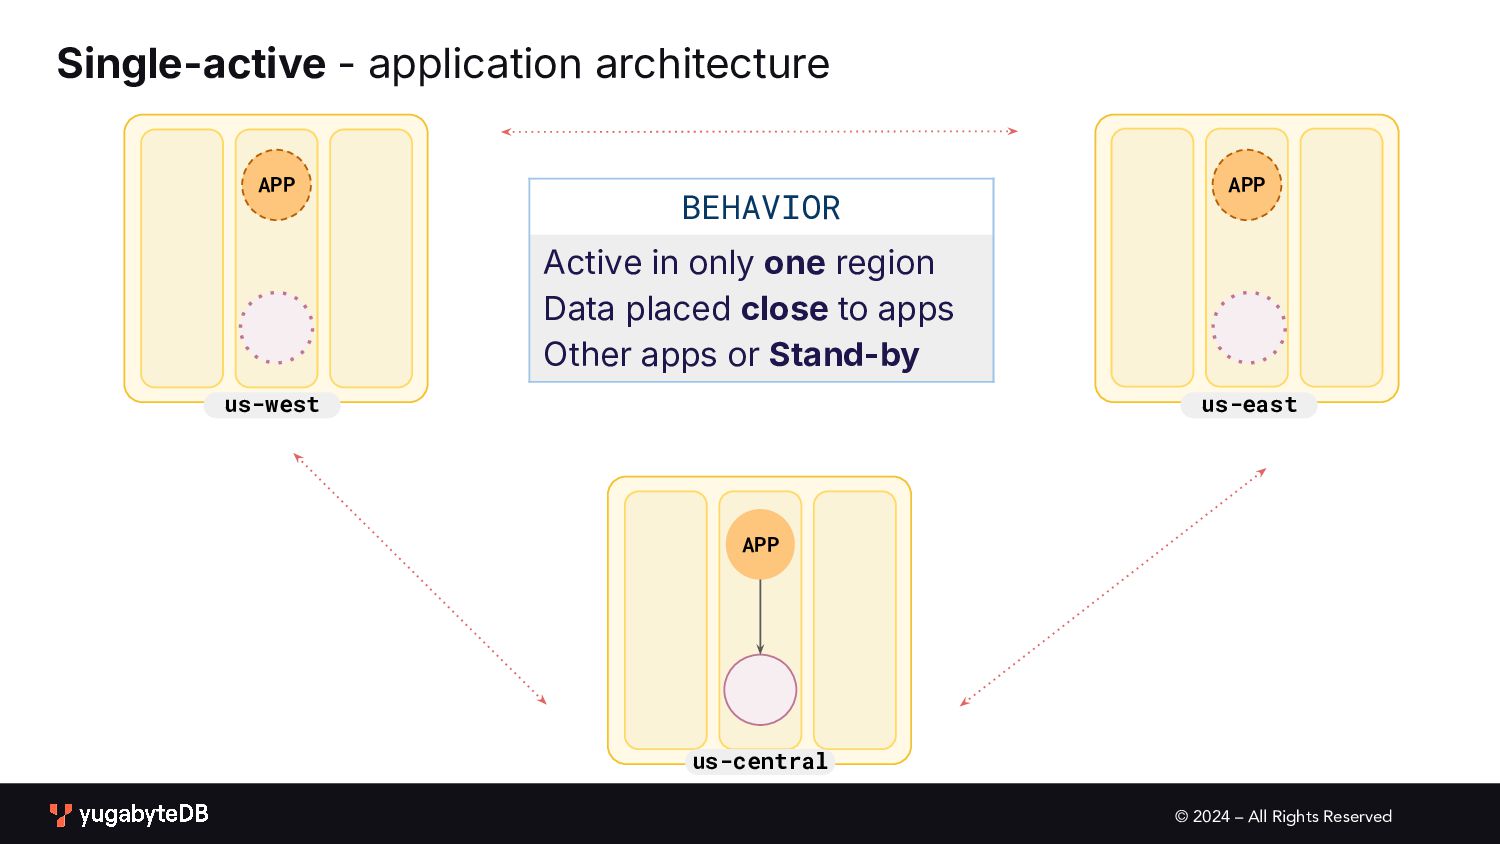
© 2024 – All Rights Reserved us-west us-east us-central Single-active
- application architecture BEHAVIOR Active in only one region Data placed close to apps Other apps or Stand-by APP APP APP -
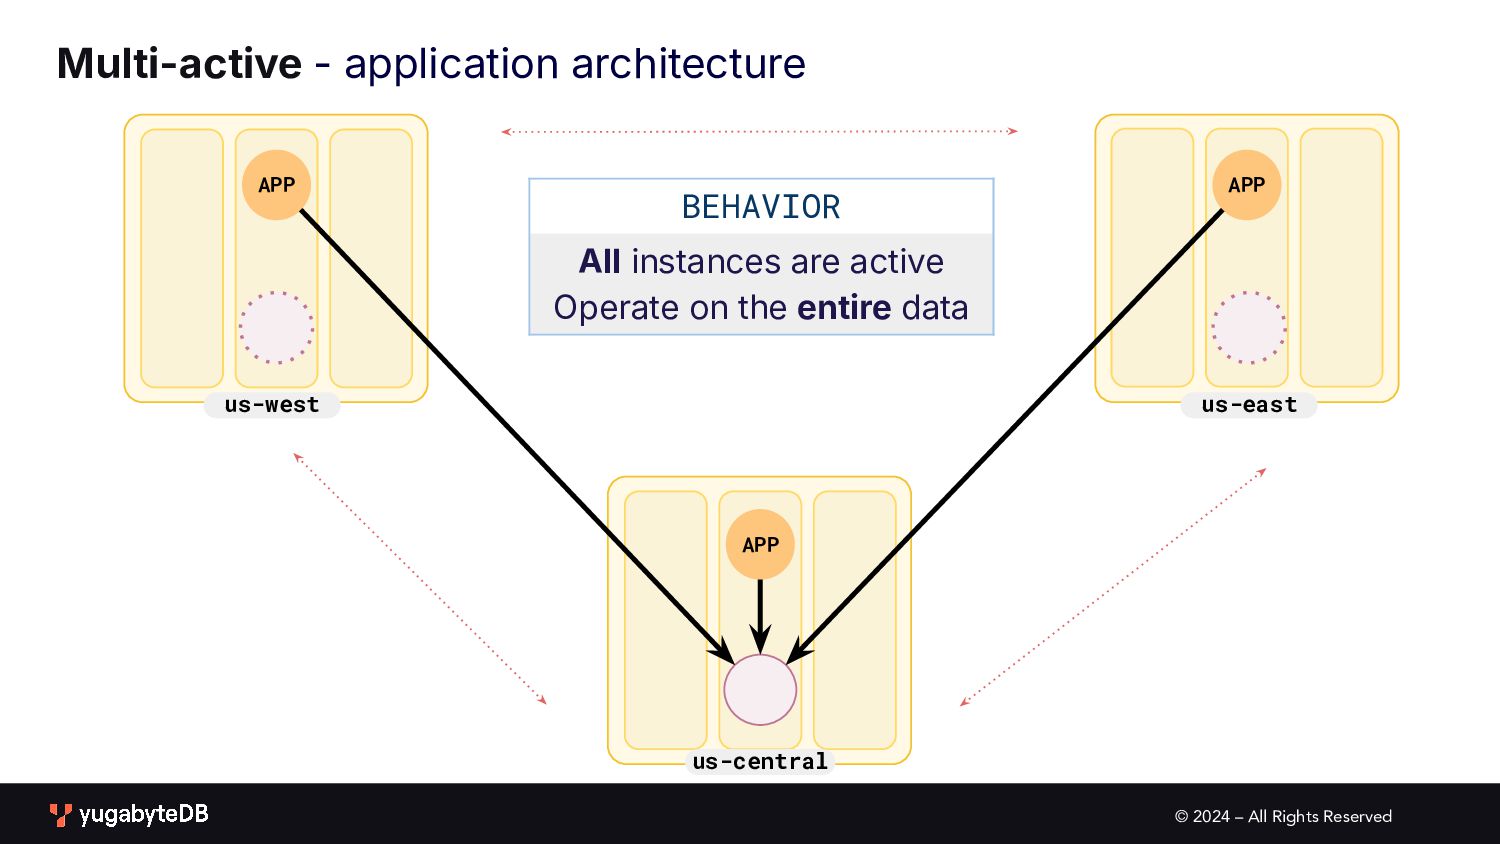
© 2024 – All Rights Reserved us-west us-east us-central Multi-active
- application architecture BEHAVIOR All instances are active Operate on the entire data APP APP APP -
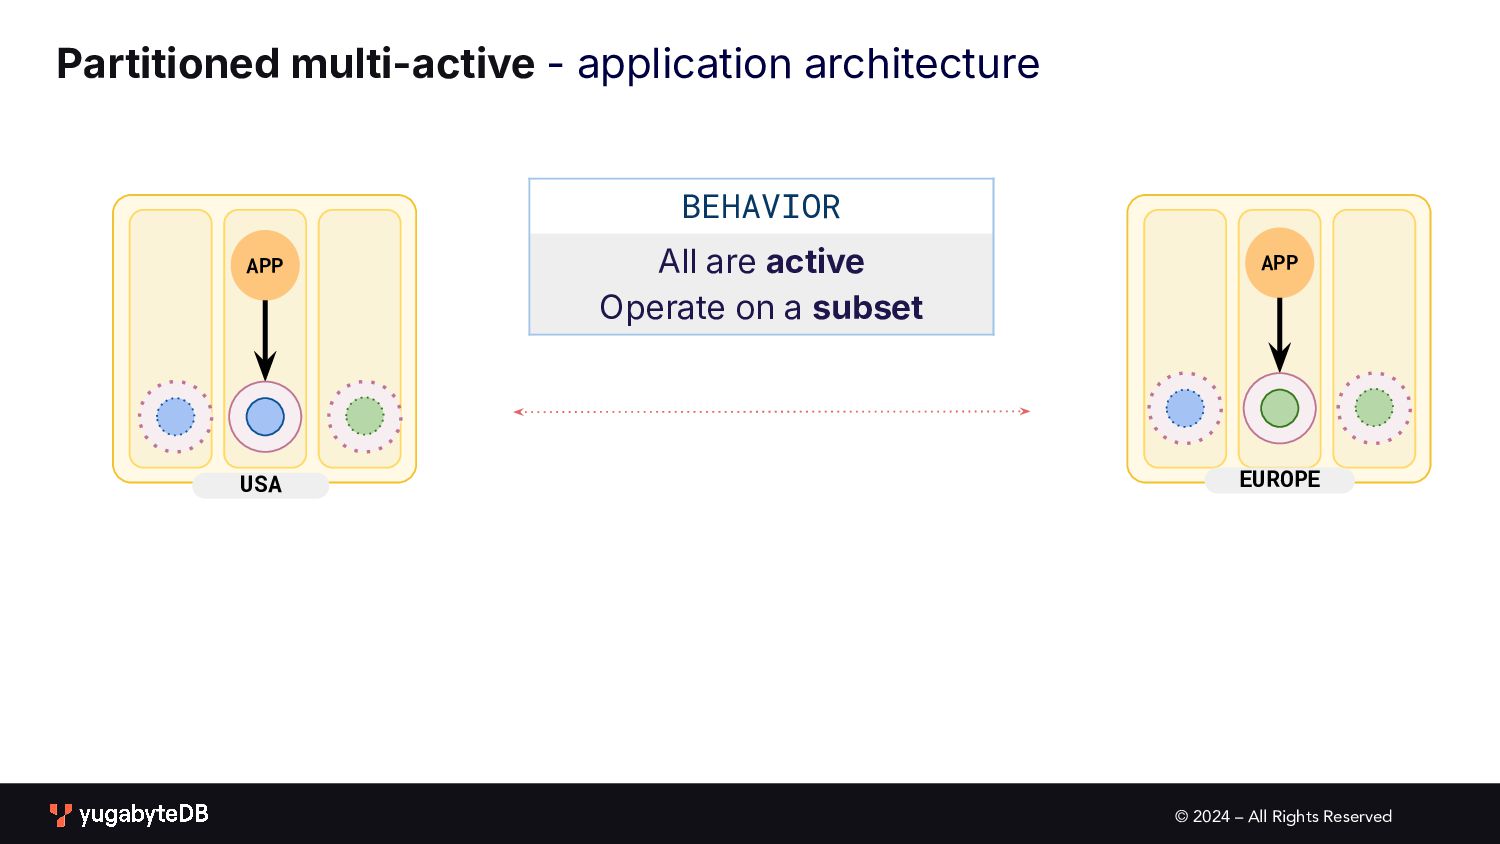
© 2024 – All Rights Reserved USA EUROPE Partitioned multi-active
- application architecture BEHAVIOR All are active Operate on a subset APP APP -
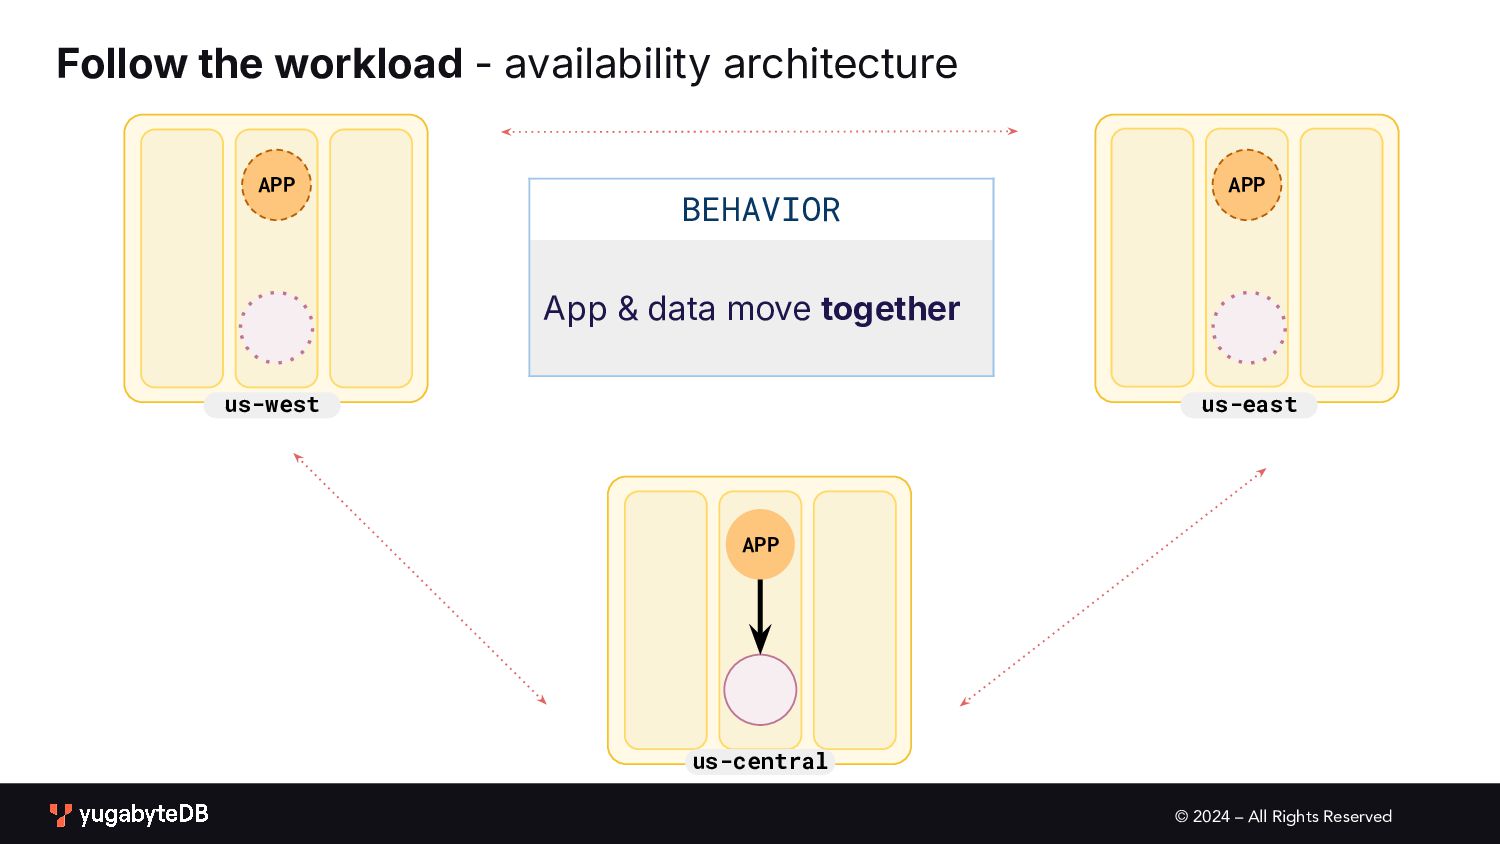
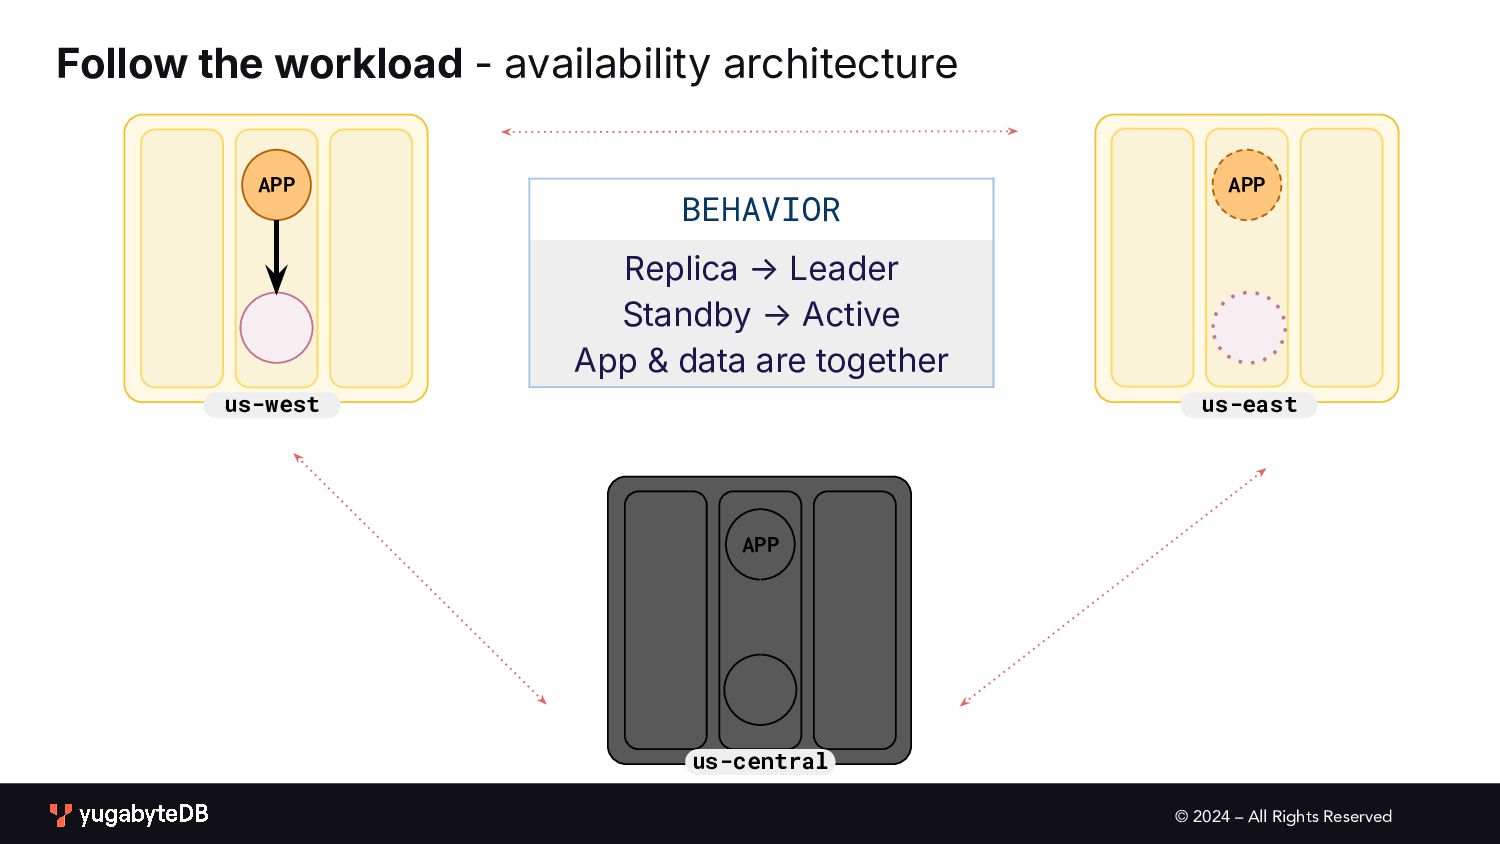
© 2024 – All Rights Reserved us-west us-east us-central Follow
the workload - availability architecture BEHAVIOR App & data move together APP APP APP -
© 2024 – All Rights Reserved us-west us-east us-central Follow
the workload - availability architecture BEHAVIOR Replica → Leader Standby → Active App & data are together APP APP APP -
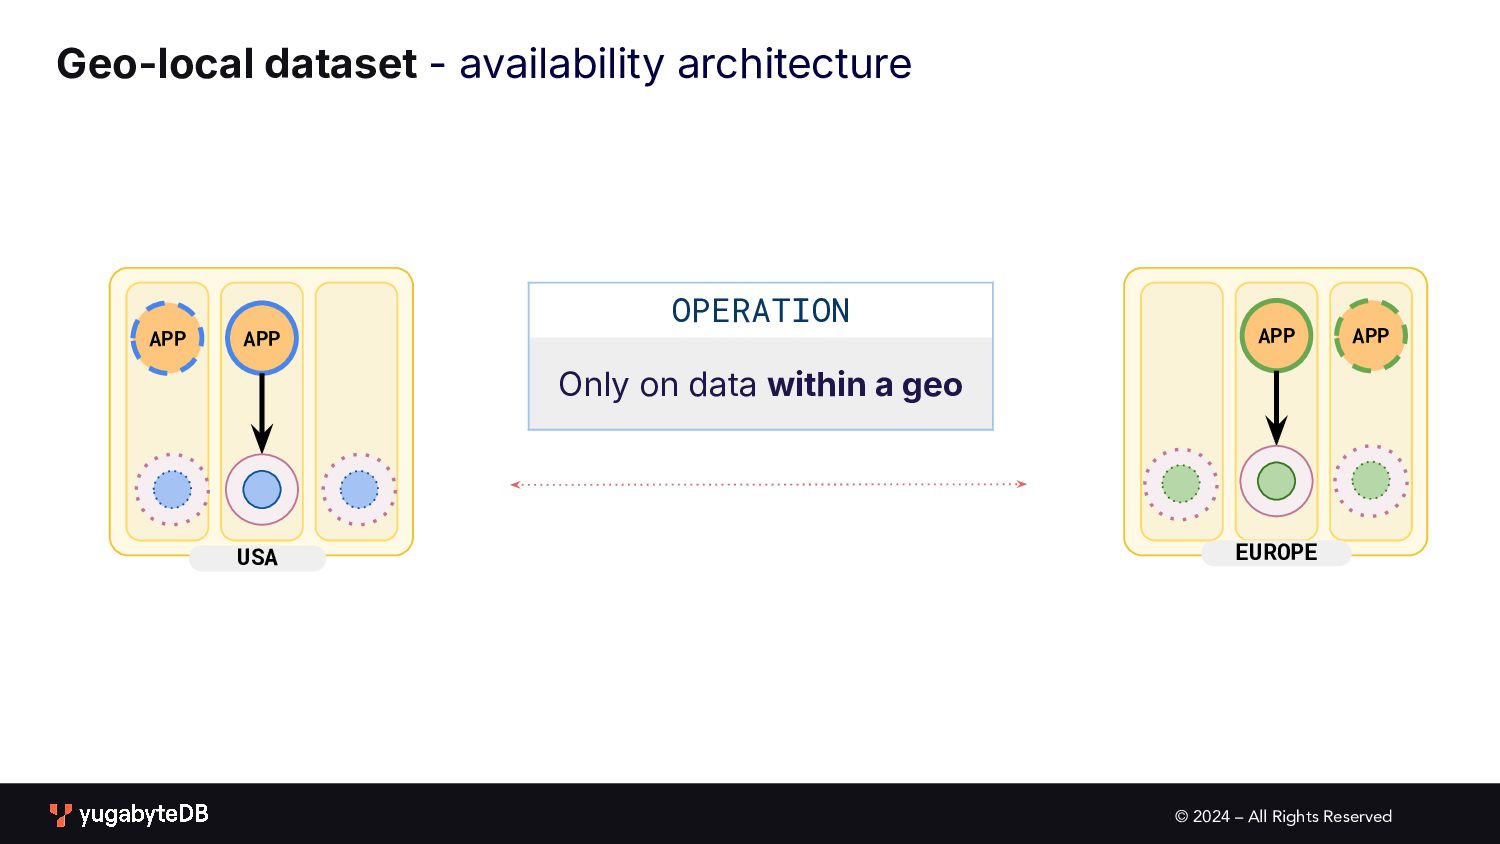
© 2024 – All Rights Reserved USA EUROPE Geo-local dataset
- availability architecture OPERATION Only on data within a geo APP APP APP APP -
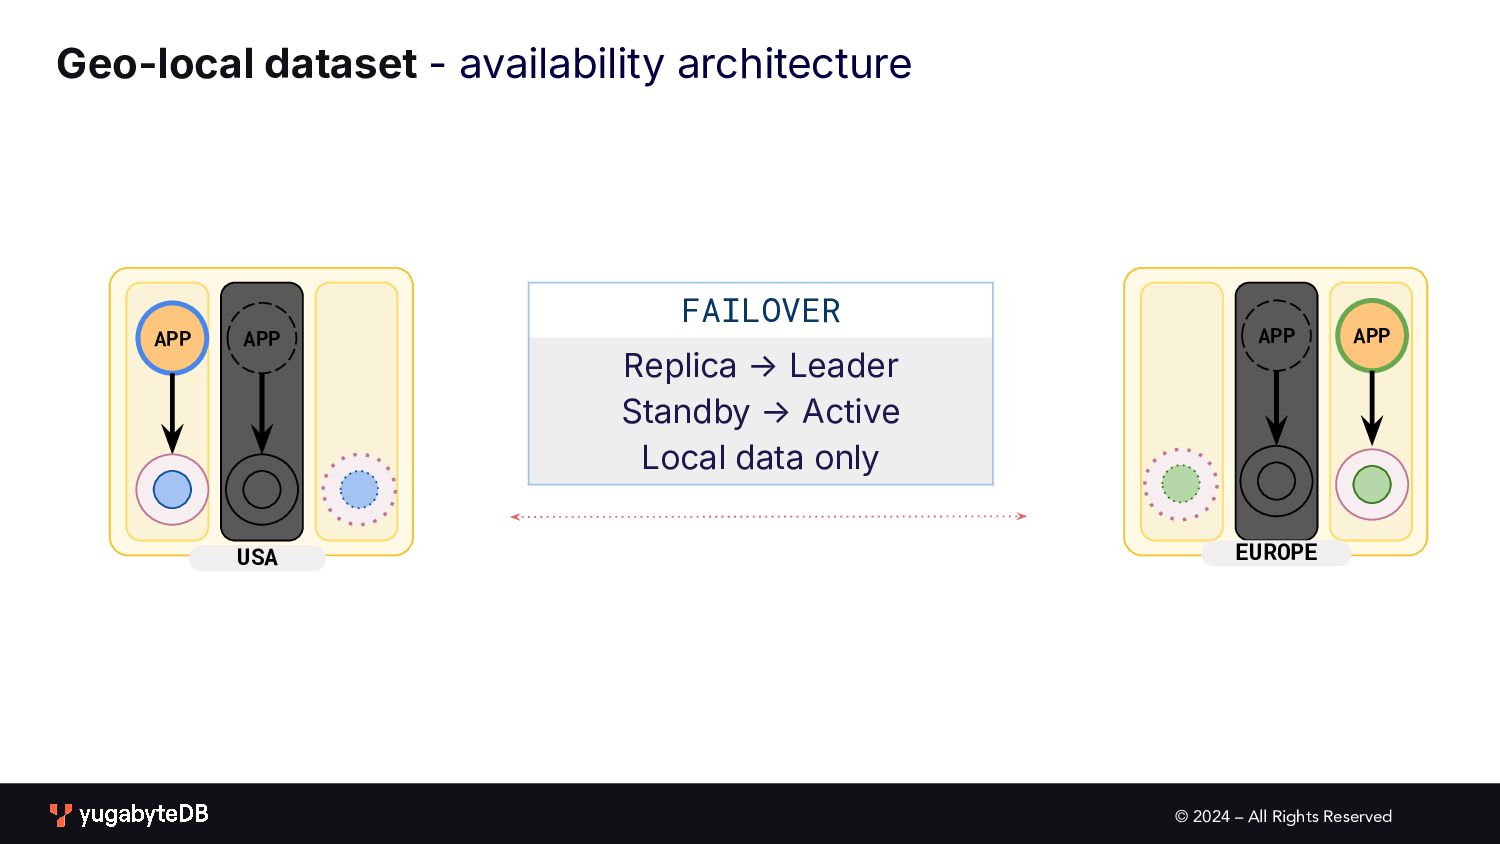
© 2024 – All Rights Reserved USA EUROPE Geo-local dataset
- availability architecture FAILOVER Replica → Leader Standby → Active Local data only APP APP APP APP -
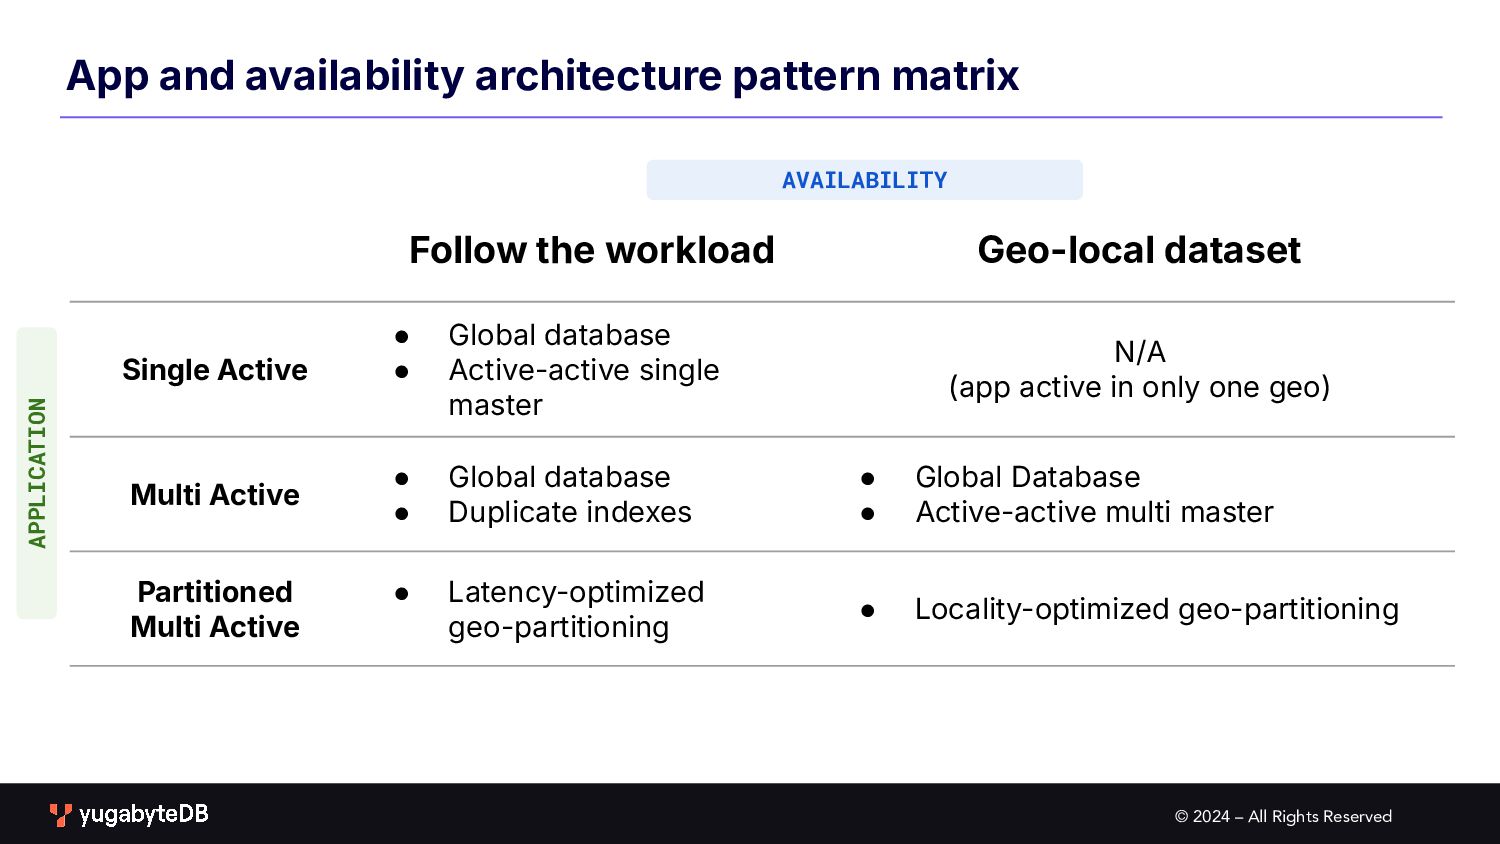
© 2024 – All Rights Reserved App and availability architecture
pattern matrix Follow the workload Geo-local dataset Single Active • Global database • Active-active single master N/A (app active in only one geo) Multi Active • Global database • Duplicate indexes • Global Database • Active-active multi master Partitioned Multi Active • Latency-optimized geo-partitioning • Locality-optimized geo-partitioning AVAILABILITY APPLICATION -
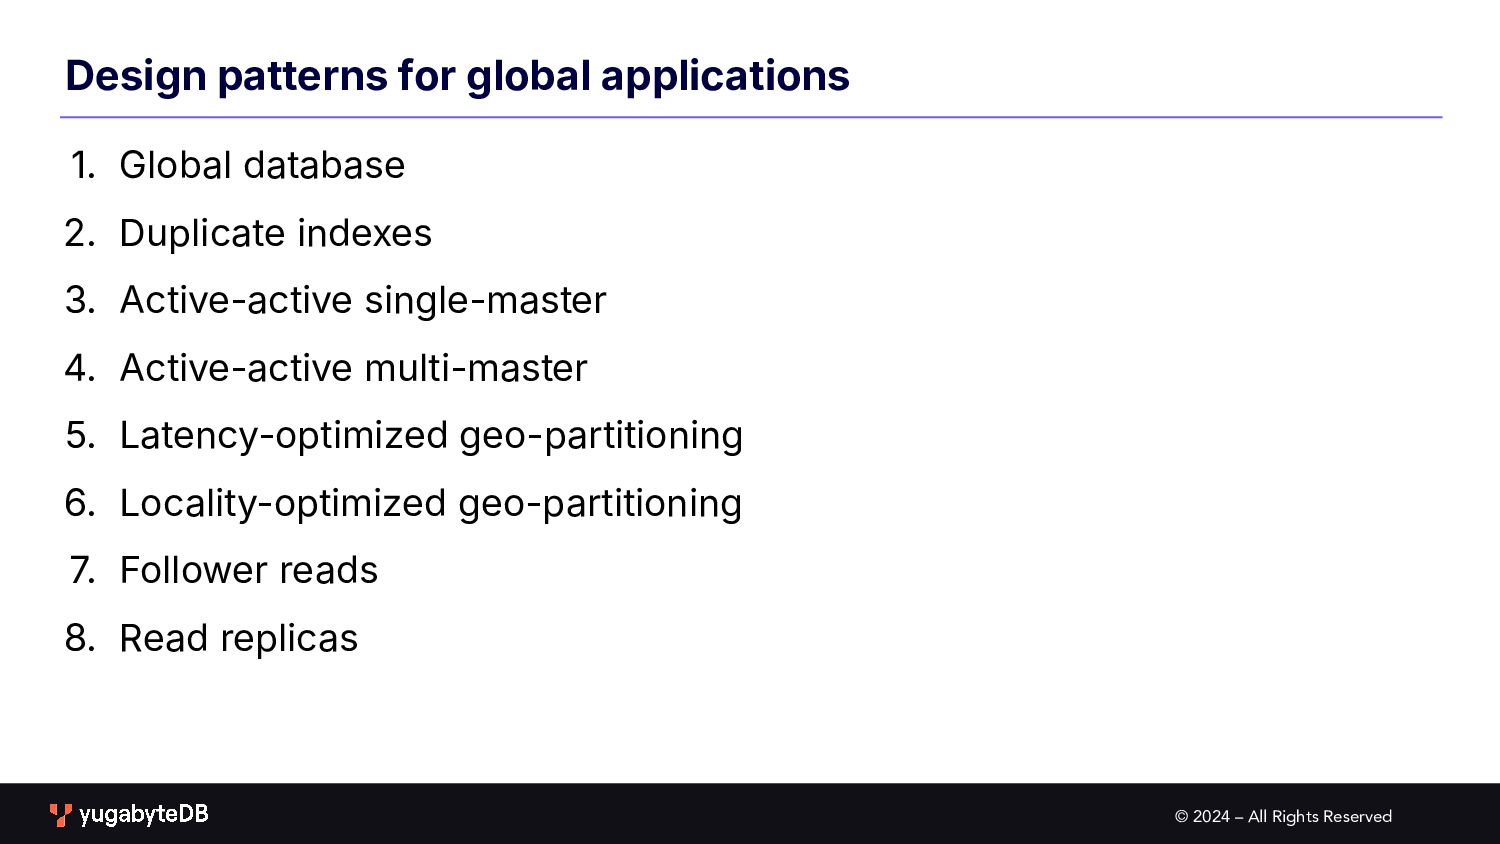
© 2024 – All Rights Reserved Design patterns for global
applications 1. Global database 2. Duplicate indexes 3. Active-active single-master 4. Active-active multi-master 5. Latency-optimized geo-partitioning 6. Locality-optimized geo-partitioning 7. Follower reads 8. Read replicas -
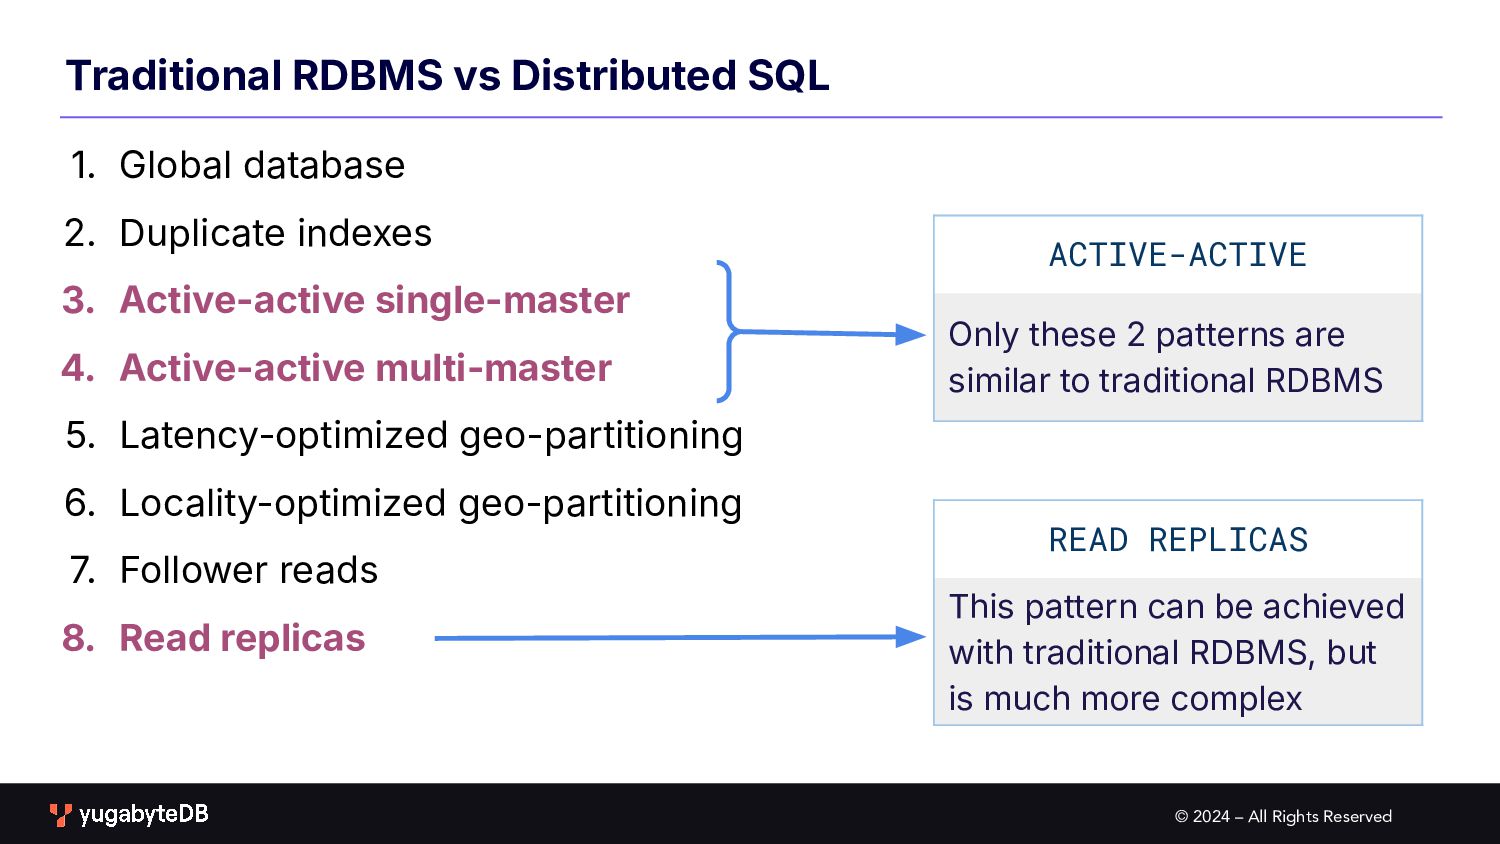
© 2024 – All Rights Reserved Traditional RDBMS vs Distributed
SQL 1. Global database 2. Duplicate indexes 3. Active-active single-master 4. Active-active multi-master 5. Latency-optimized geo-partitioning 6. Locality-optimized geo-partitioning 7. Follower reads 8. Read replicas ACTIVE-ACTIVE Only these 2 patterns are similar to traditional RDBMS READ REPLICAS This pattern can be achieved with traditional RDBMS, but is much more complex -
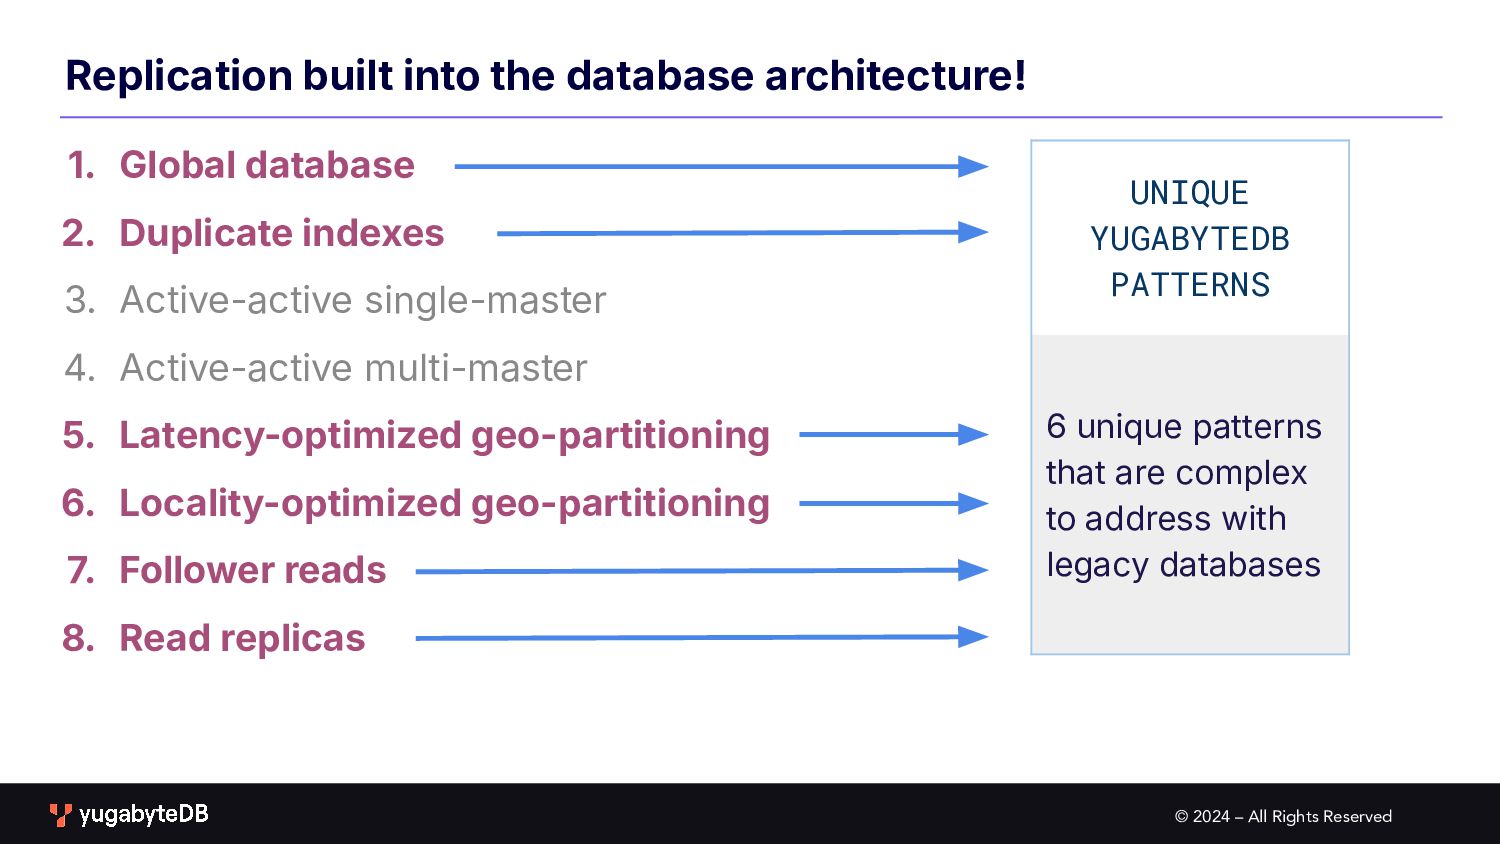
© 2024 – All Rights Reserved Replication built into the
database architecture! 1. Global database 2. Duplicate indexes 3. Active-active single-master 4. Active-active multi-master 5. Latency-optimized geo-partitioning 6. Locality-optimized geo-partitioning 7. Follower reads 8. Read replicas UNIQUE YUGABYTEDB PATTERNS 6 unique patterns that are complex to address with legacy databases -
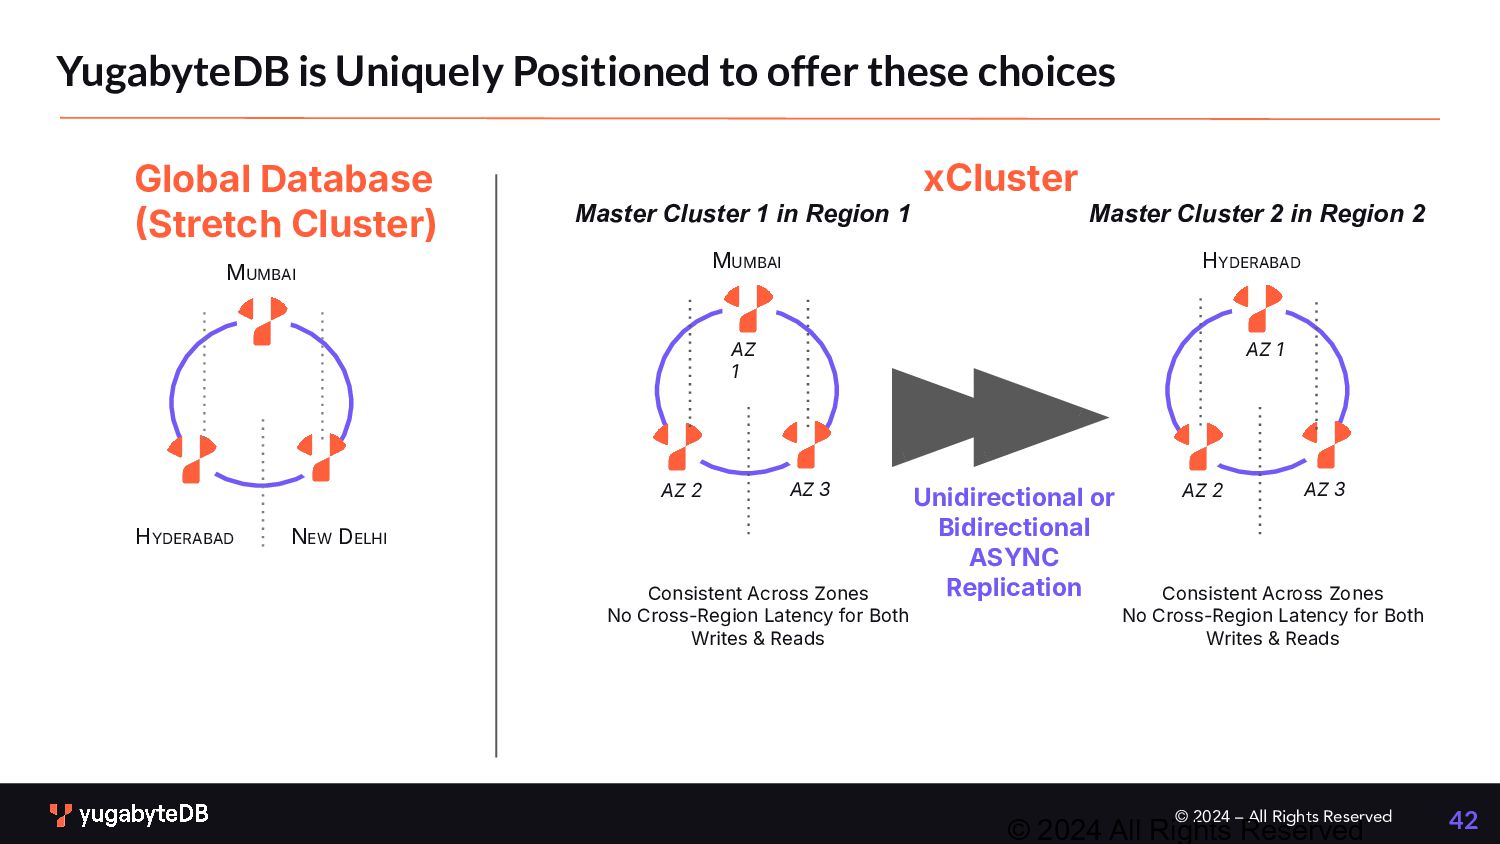
© 2024 – All Rights Reserved xCluster AZ 1 AZ
2 AZ 3 MUMBAI Master Cluster 1 in Region 1 Consistent Across Zones No Cross-Region Latency for Both Writes & Reads HYDERABAD AZ 1 AZ 2 AZ 3 Master Cluster 2 in Region 2 Consistent Across Zones No Cross-Region Latency for Both Writes & Reads Unidirectional or Bidirectional ASYNC Replication Global Database Stretch Cluster) MUMBAI HYDERABAD NEW DELHI YugabyteDB is Uniquely Positioned to offer these choices 42 © 2024 All Rights Reserved -
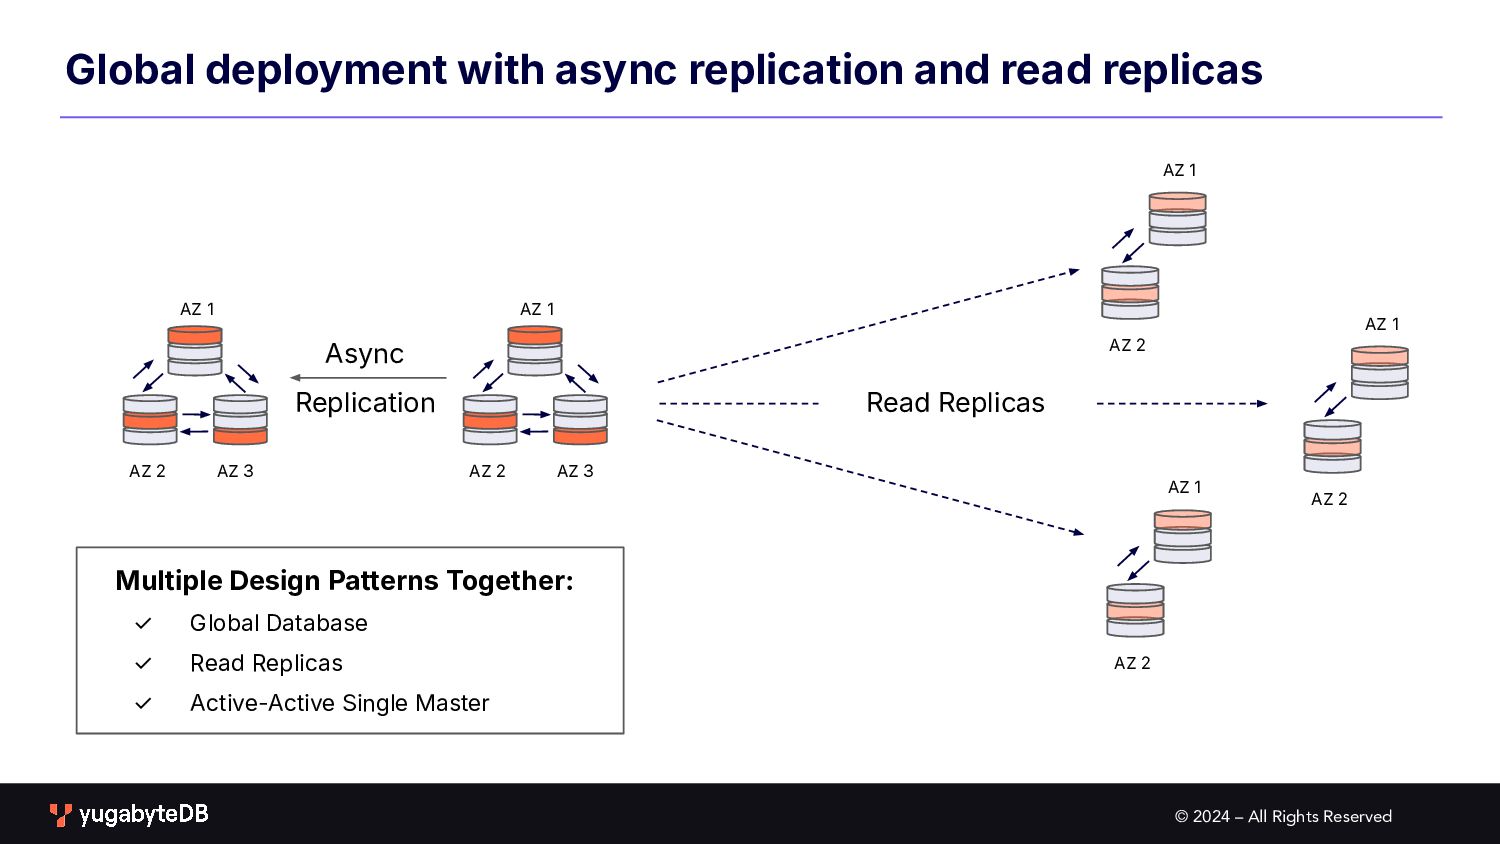
© 2024 – All Rights Reserved AZ 1 AZ 2
AZ 3 AZ 1 AZ 2 Global deployment with async replication and read replicas AZ 1 AZ 2 AZ 3 AZ 1 AZ 2 AZ 1 AZ 2 Async Replication Read Replicas Multiple Design Patterns Together: ✓ Global Database ✓ Read Replicas ✓ Active-Active Single Master -
© 2024 – All Rights Reserved Airwallex spans multiple regions
using YugabyteDB ◦ Global payments and financial operations platform ◦ Multi-region resilience goals ◦ Continuous global operations ◦ Consistent, distributed data ◦ Low latency ◦ Deployment: ◦ Multi-region 1 primary, 3 read replicas) ◦ xCluster asynchronous replication ◦ Smart Drivers JDBC, R2DBC -
© 2024 – All Rights Reserved Six Elements of Ultra-Resilience
In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
© 2024 – All Rights Reserved ✓ Backups ✓ Point-in-time-Recovery
PITR ✓ Software rollbacks ✓ Blue green upgrades What Matters… -
© 2024 – All Rights Reserved ◦ Cluster size: 9
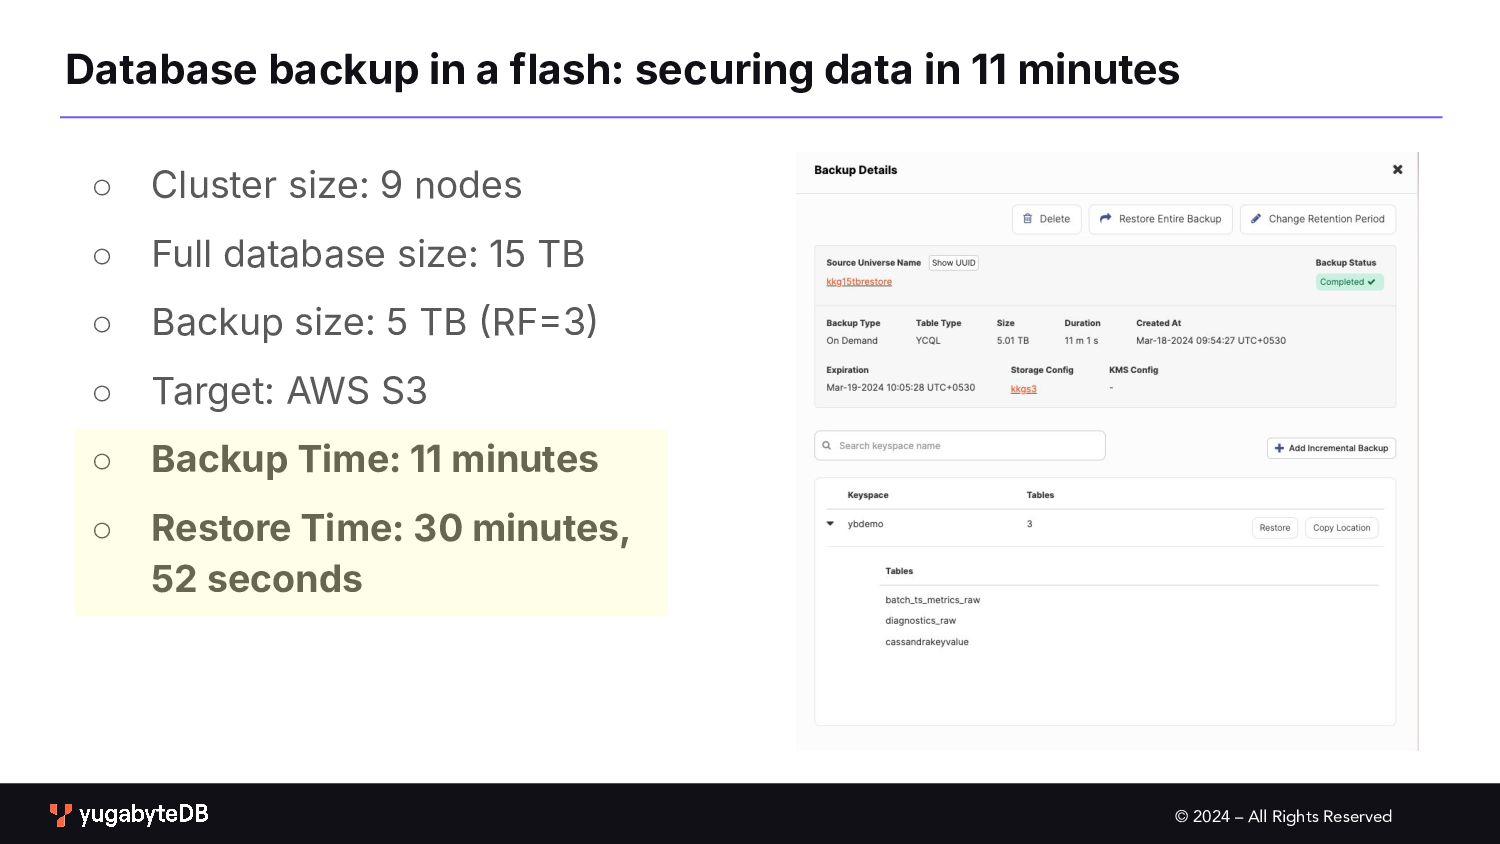
nodes ◦ Full database size: 15 TB ◦ Backup size: 5 TB RF3 ◦ Target: AWS S3 ◦ Backup Time: 11 minutes ◦ Restore Time: 30 minutes, 52 seconds Database backup in a flash: securing data in 11 minutes -
© 2024 – All Rights Reserved Xignite requires enterprise-grade data
protection ◦ Use Case: ◦ Deliver real-time and reference financial market data to more than 700 customers ◦ Deployment: ◦ Multi-zone, single region ◦ AWS VPC ◦ Key Challenges ◦ Flexible upgrades with no downtime ◦ Data consistency ◦ Easy scalability -
© 2024 – All Rights Reserved Six Elements of Ultra-Resilience
In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
© 2024 – All Rights Reserved ✓ Software upgrades ✓
OS patching ✓ Machine, SKU, AMI refresh ✓ Changing instance types ✓ Security key rotations What Matters… -
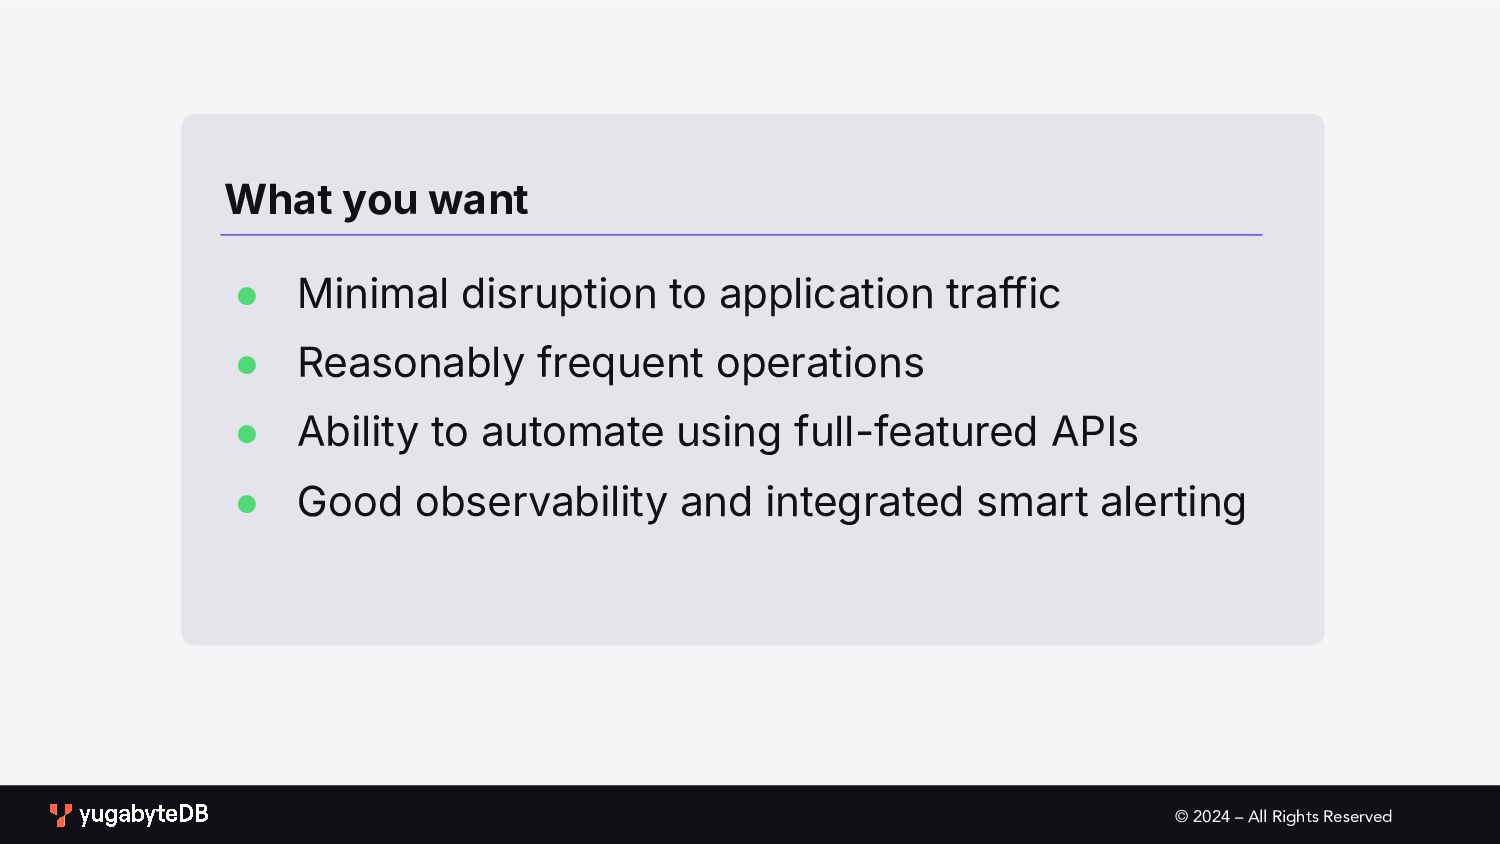
© 2024 – All Rights Reserved • Minimal disruption to
application traffic • Reasonably frequent operations • Ability to automate using full-featured APIs • Good observability and integrated smart alerting What you want -
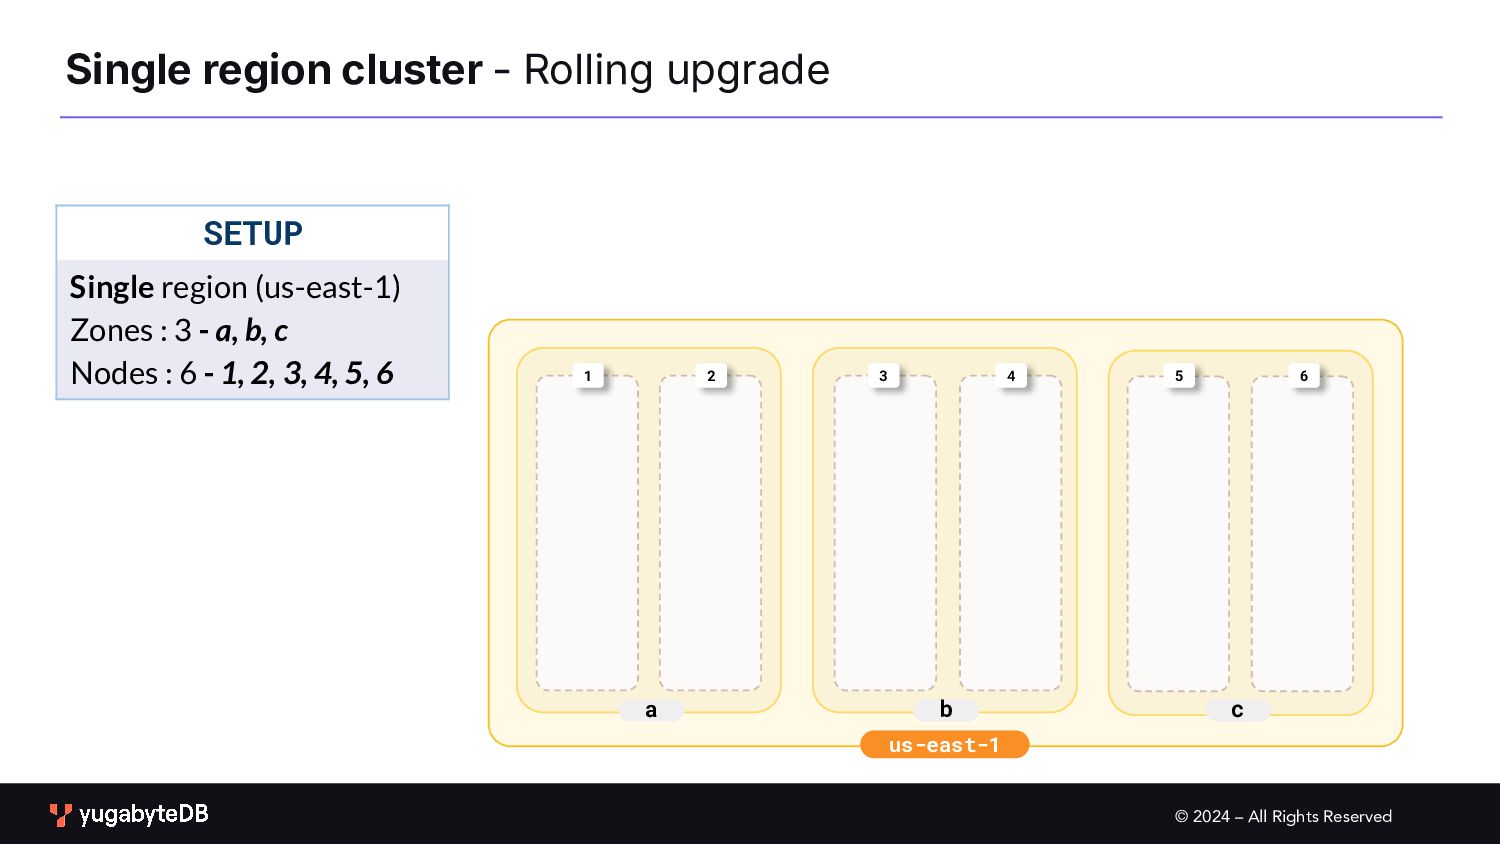
© 2024 – All Rights Reserved us-east-1 Single region cluster
- Rolling upgrade b c a 1 2 3 4 5 6 SETUP Single region (us-east-1) Zones : 3 - a, b, c Nodes : 6 - 1, 2, 3, 4, 5, 6 -
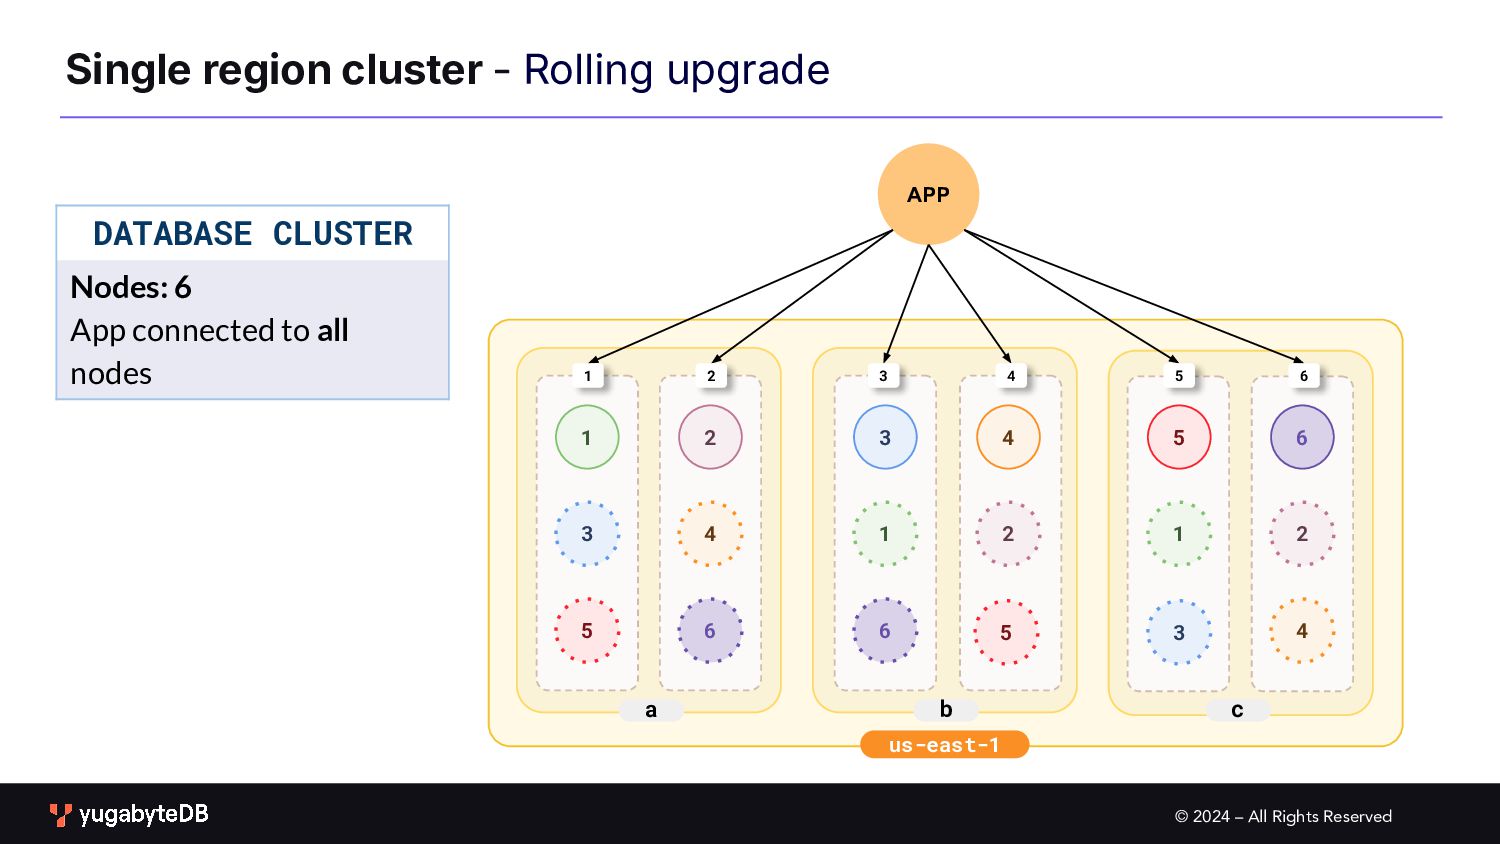
© 2024 – All Rights Reserved APP us-east-1 Single region
cluster - Rolling upgrade b c a 1 2 3 1 2 3 5 4 4 5 6 6 1 2 3 4 5 6 1 2 3 4 5 6 DATABASE CLUSTER Nodes: 6 App connected to all nodes -
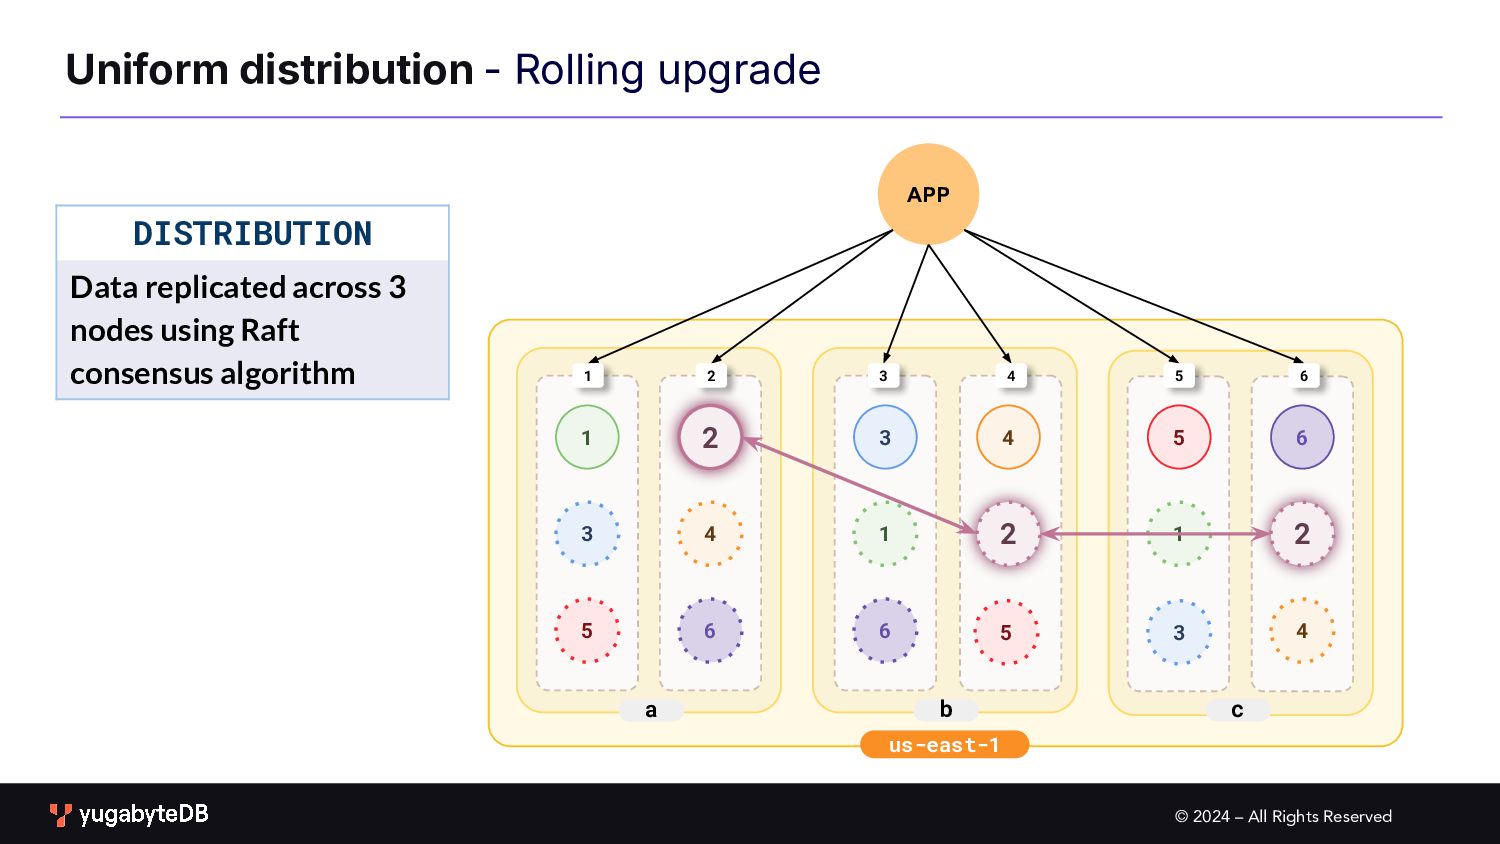
© 2024 – All Rights Reserved APP us-east-1 Uniform distribution
- Rolling upgrade b c a 1 2 3 1 2 3 5 4 4 5 6 6 1 2 3 4 5 6 DISTRIBUTION Data replicated across 3 nodes using Raft consensus algorithm 1 2 3 4 5 6 -
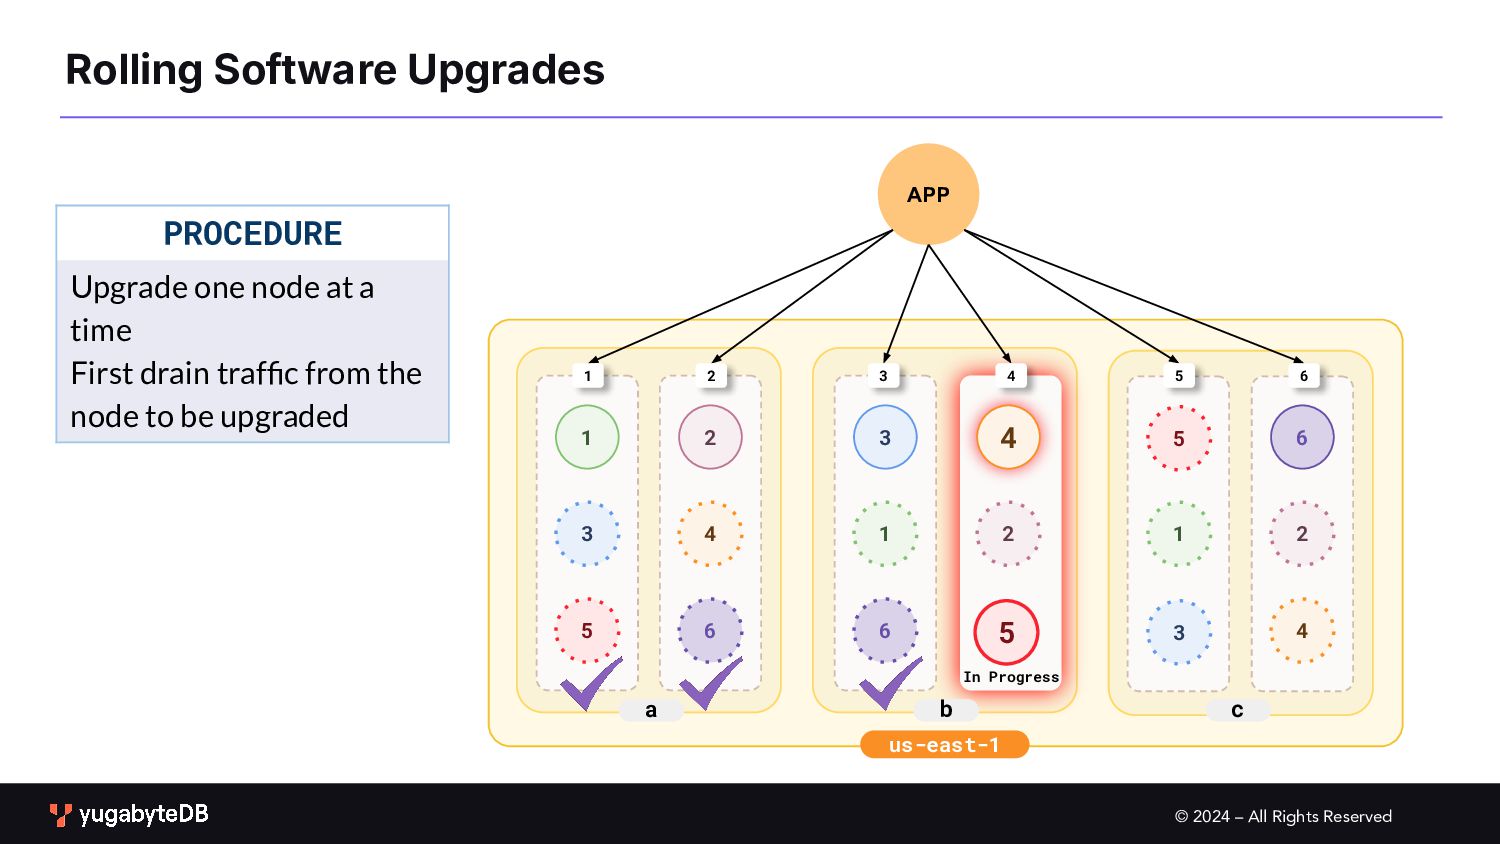
© 2024 – All Rights Reserved APP us-east-1 Rolling Software
Upgrades b c a 1 2 3 1 2 3 4 4 5 6 6 1 2 3 4 5 6 1 2 3 4 5 6 PROCEDURE Upgrade one node at a time First drain traffic from the node to be upgraded 5 In Progress -
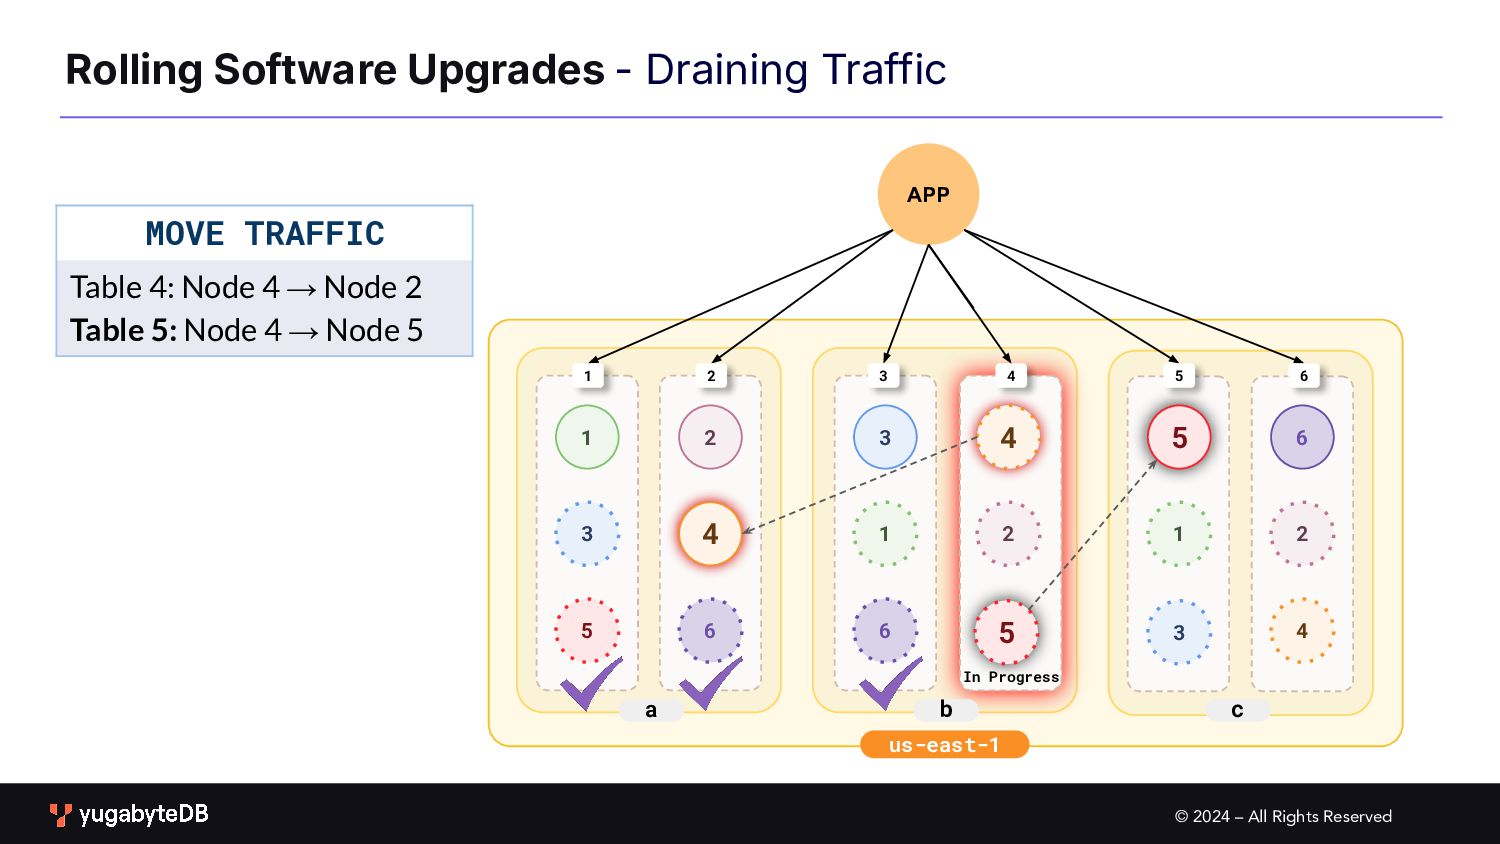
© 2024 – All Rights Reserved APP us-east-1 Rolling Software
Upgrades - Draining Traffic b c a 1 2 3 1 2 3 5 4 4 5 6 6 1 2 3 4 5 6 1 2 3 4 5 6 MOVE TRAFFIC Table 4: Node 4 → Node 2 Table 5: Node 4 → Node 5 In Progress -
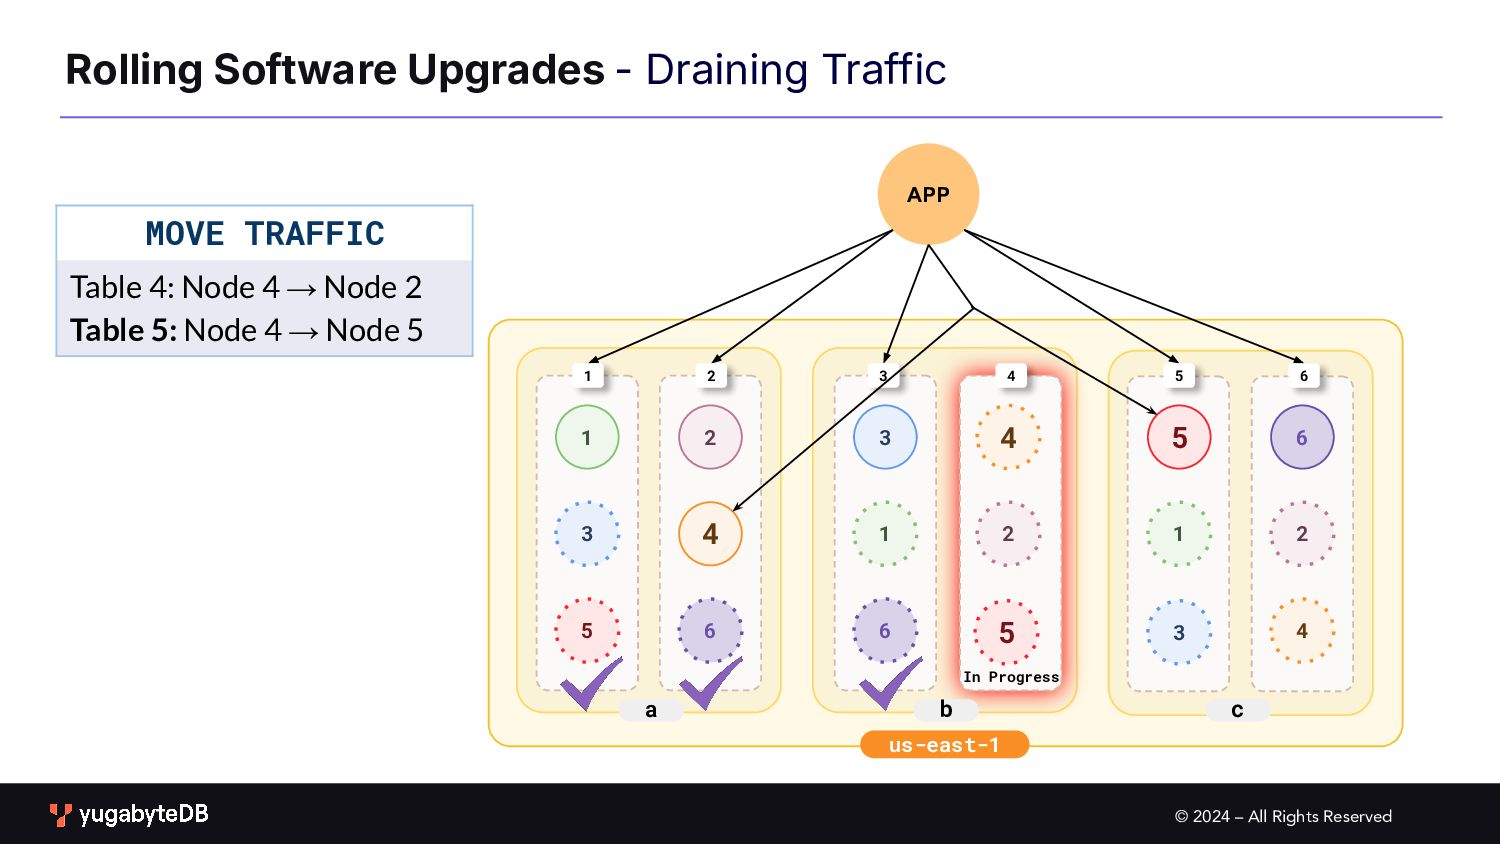
© 2024 – All Rights Reserved APP us-east-1 Rolling Software
Upgrades - Draining Traffic b c a 1 2 3 1 2 3 5 4 4 5 6 6 1 2 3 4 5 6 1 2 3 4 5 6 MOVE TRAFFIC Table 4: Node 4 → Node 2 Table 5: Node 4 → Node 5 In Progress -
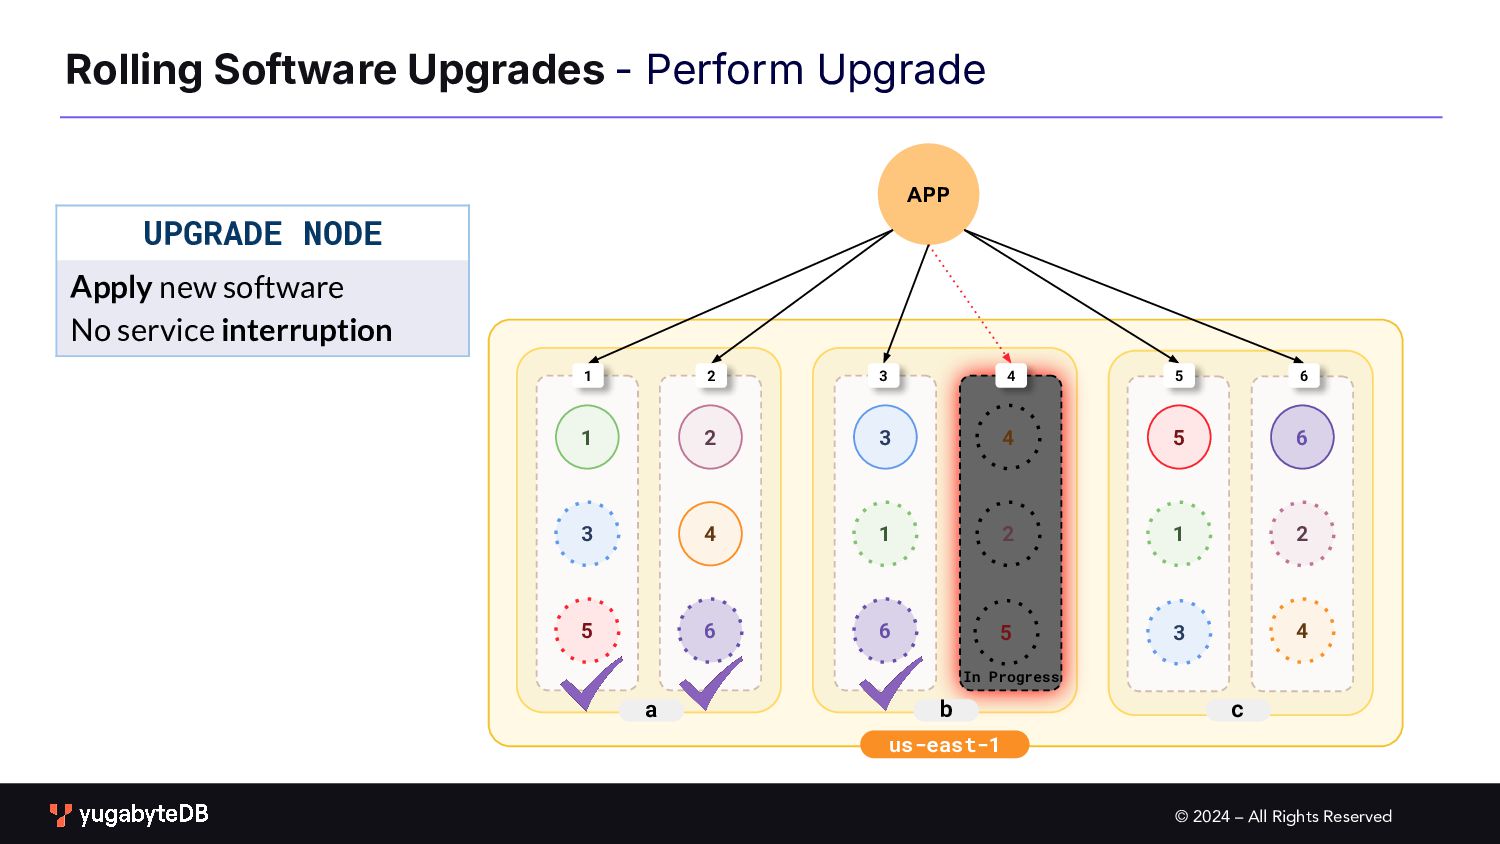
© 2024 – All Rights Reserved APP us-east-1 Rolling Software
Upgrades - Perform Upgrade b c a 1 2 3 1 2 3 5 4 4 5 6 6 1 2 3 4 5 6 1 2 3 4 5 6 UPGRADE NODE Apply new software No service interruption In Progress -
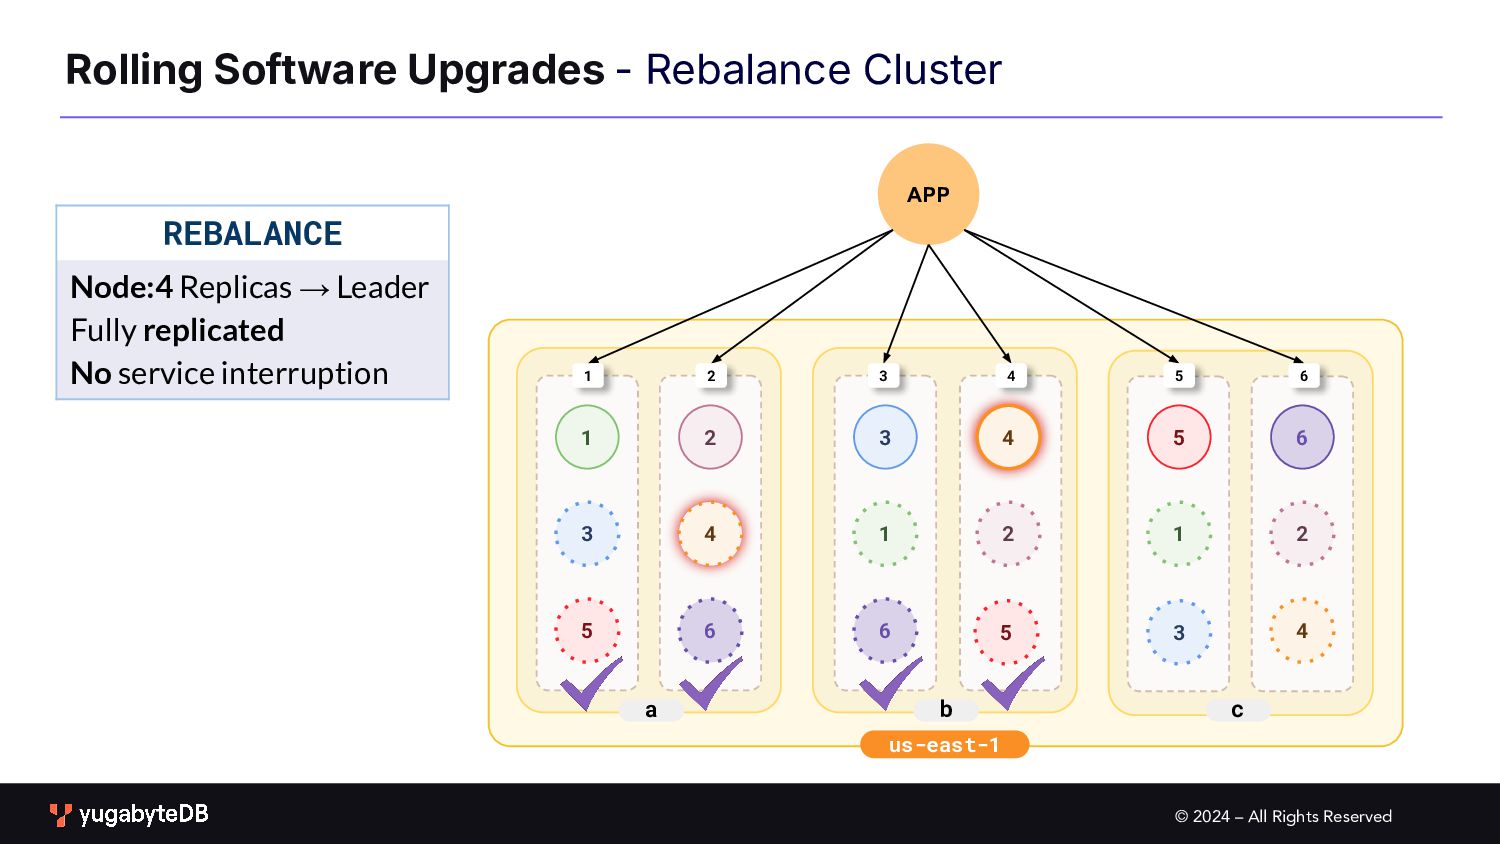
© 2024 – All Rights Reserved APP us-east-1 Rolling Software
Upgrades - Rebalance Cluster b c a 1 2 3 1 2 3 5 4 4 5 6 6 1 2 3 4 5 6 1 2 3 4 5 6 REBALANCE Node:4 Replicas → Leader Fully replicated No service interruption -
© 2024 – All Rights Reserved Jakarta delivers intelligent, IoT
system in single region ◦ IoT-based service to monitor Jakartaʼs water networks and flood system ◦ Online operations with full automation while retaining PostgreSQL features ◦ Deployment: ◦ Multi-zone, single region ◦ On-premises data center -
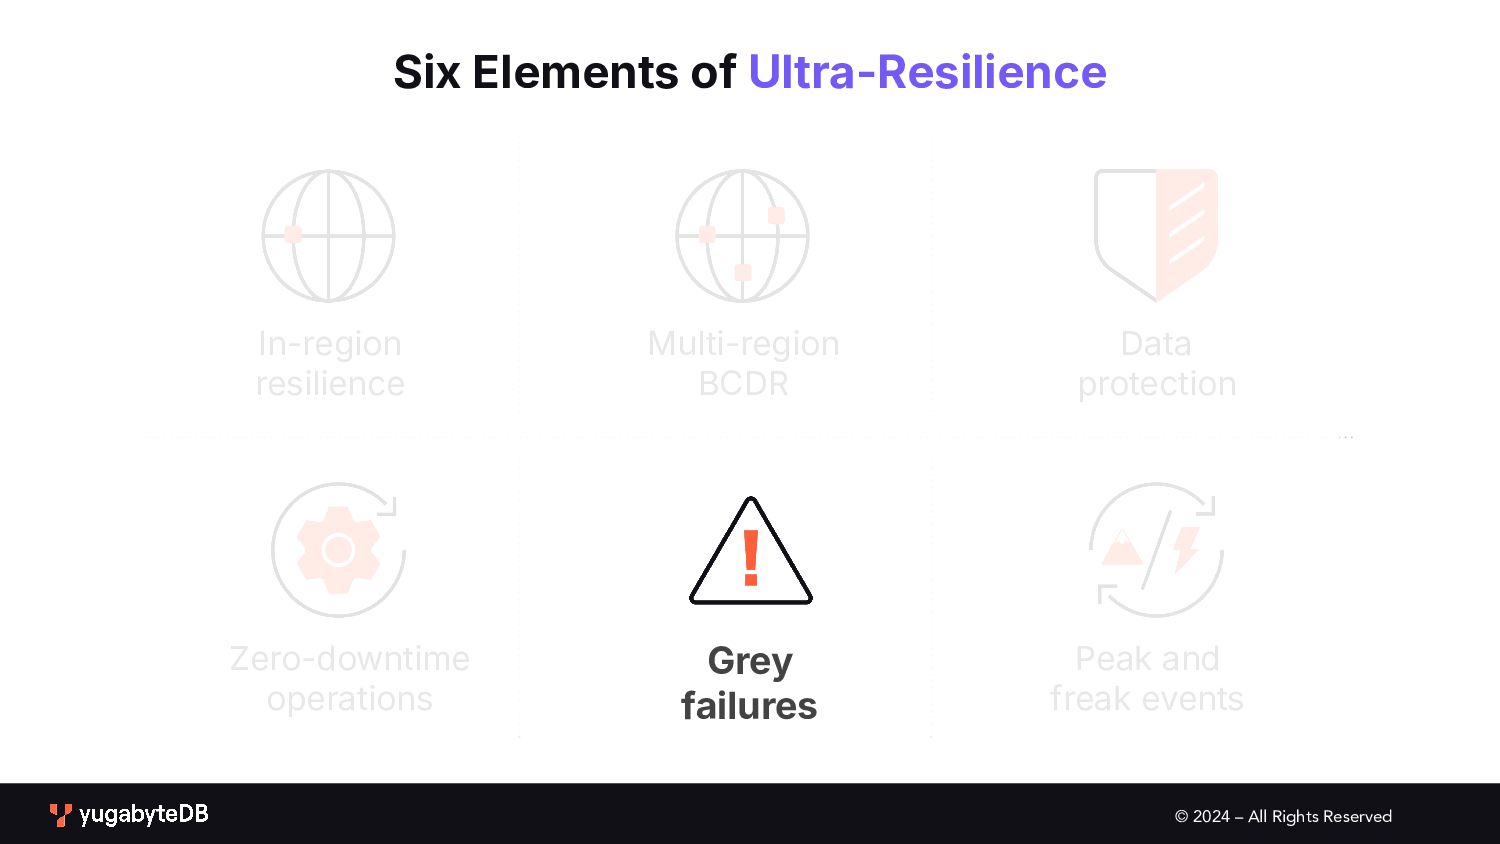
© 2024 – All Rights Reserved Six Elements of Ultra-Resilience
In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
© 2024 – All Rights Reserved ✓ Performance degradation ✓
Random data delays or loss ✓ Flaky I/O ✓ Memory thrashing ✓ Capacity pressure ✓ Non-fatal exceptions Examples of grey failures -
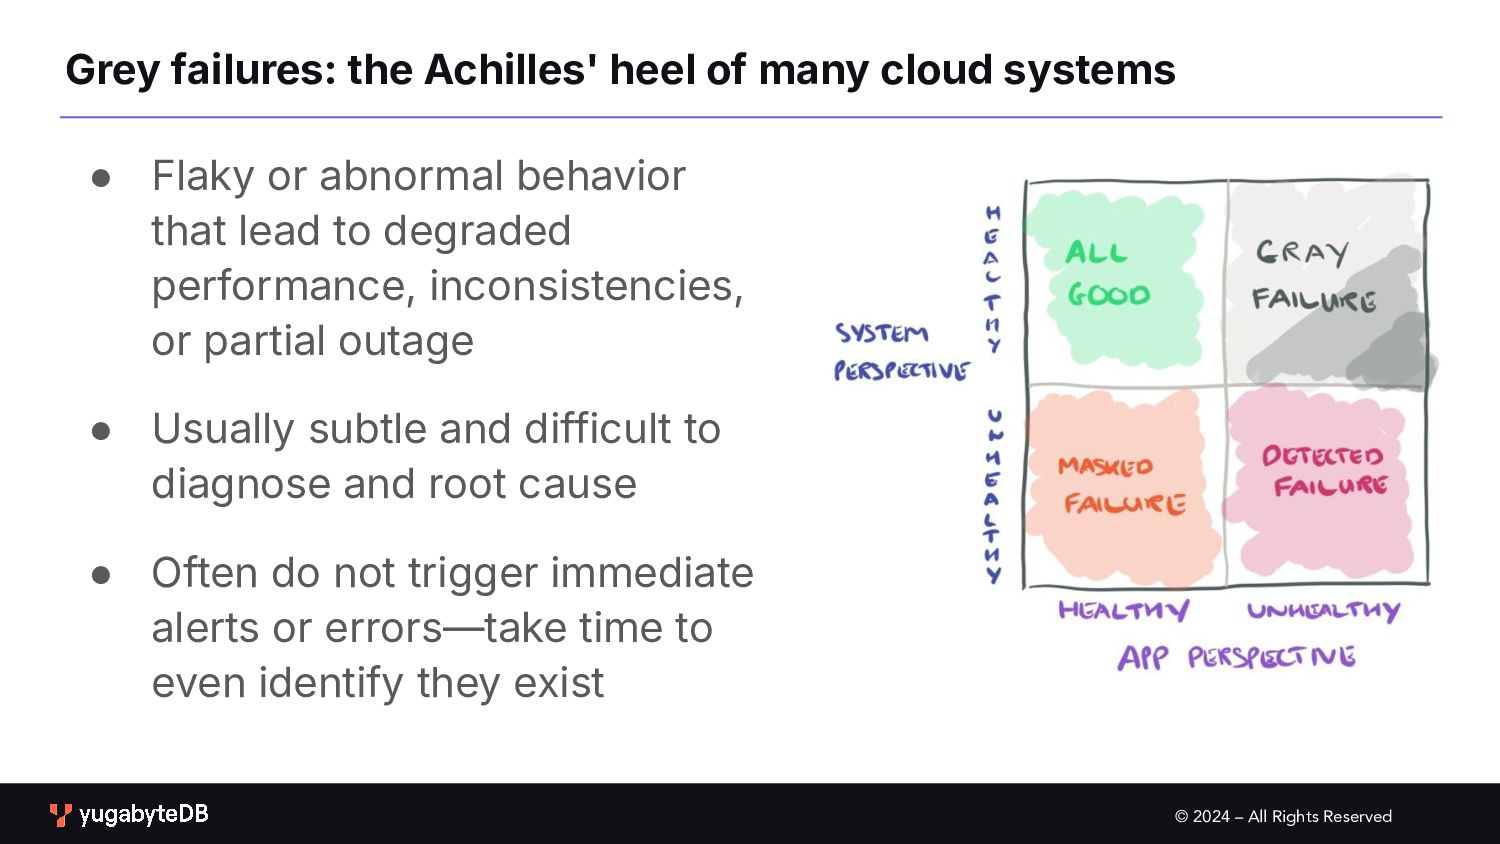
© 2024 – All Rights Reserved • Flaky or abnormal
behavior that lead to degraded performance, inconsistencies, or partial outage • Usually subtle and difficult to diagnose and root cause • Often do not trigger immediate alerts or errors—take time to even identify they exist Grey failures: the Achilles' heel of many cloud systems -
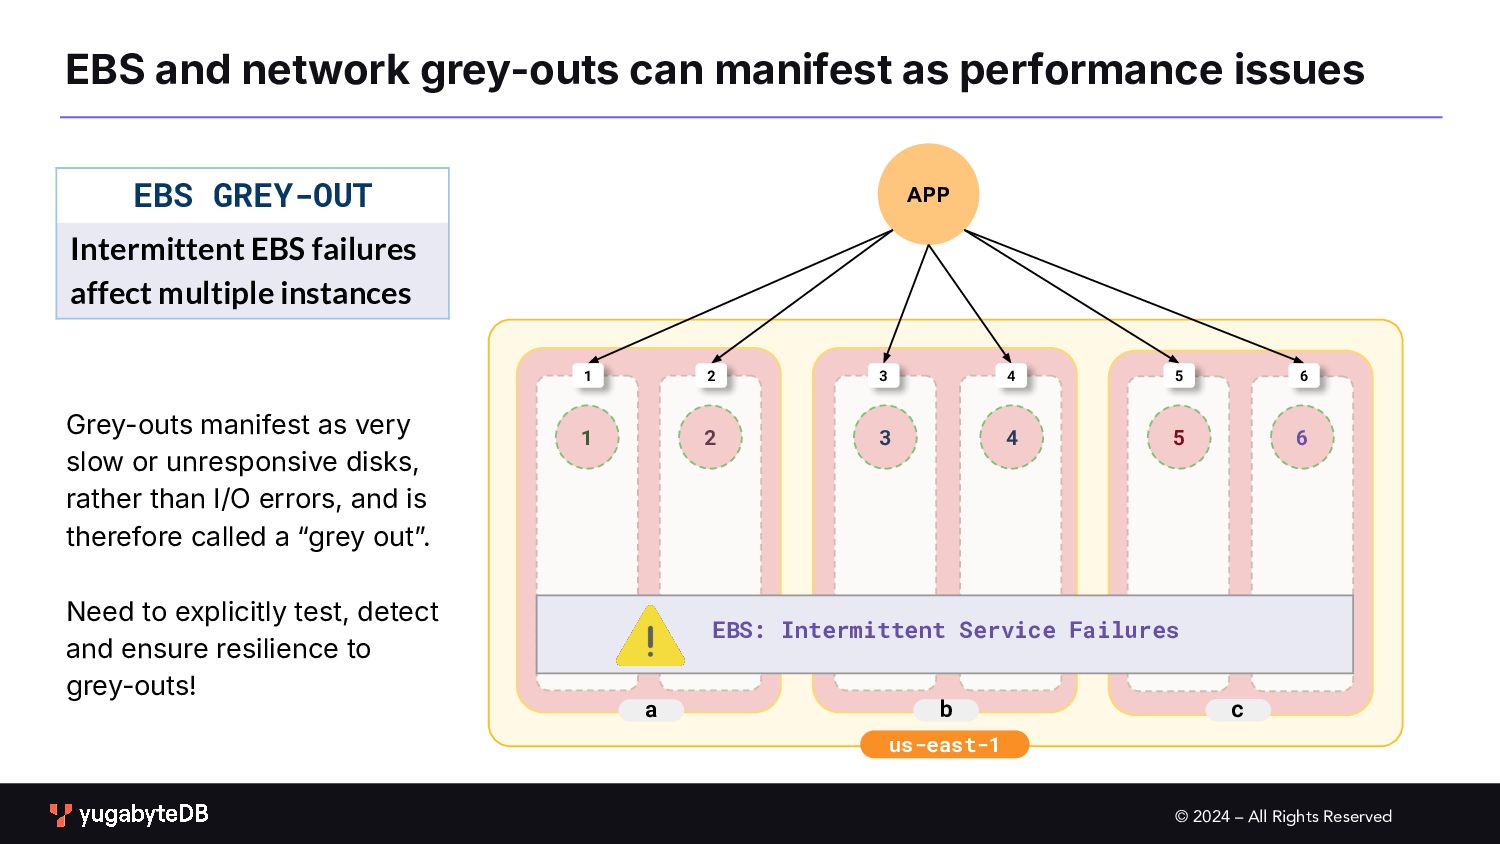
© 2024 – All Rights Reserved APP us-east-1 EBS and
network grey-outs can manifest as performance issues b c a 1 2 3 5 6 1 2 3 4 5 6 EBS GREY-OUT Intermittent EBS failures affect multiple instances EBS: Intermittent Service Failures 4 Grey-outs manifest as very slow or unresponsive disks, rather than I/O errors, and is therefore called a “grey outˮ. Need to explicitly test, detect and ensure resilience to grey-outs! -
© 2024 – All Rights Reserved Six Elements of Ultra-Resilience
In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures -
© 2024 – All Rights Reserved ✓ Prepared for unexpected
bursts ✓ Built for expected peaks ✓ Surviving DDoS attacks ✓ Flexible expansion, anywhere ✓ Multitenancy ✓ No performance compromise What matters -
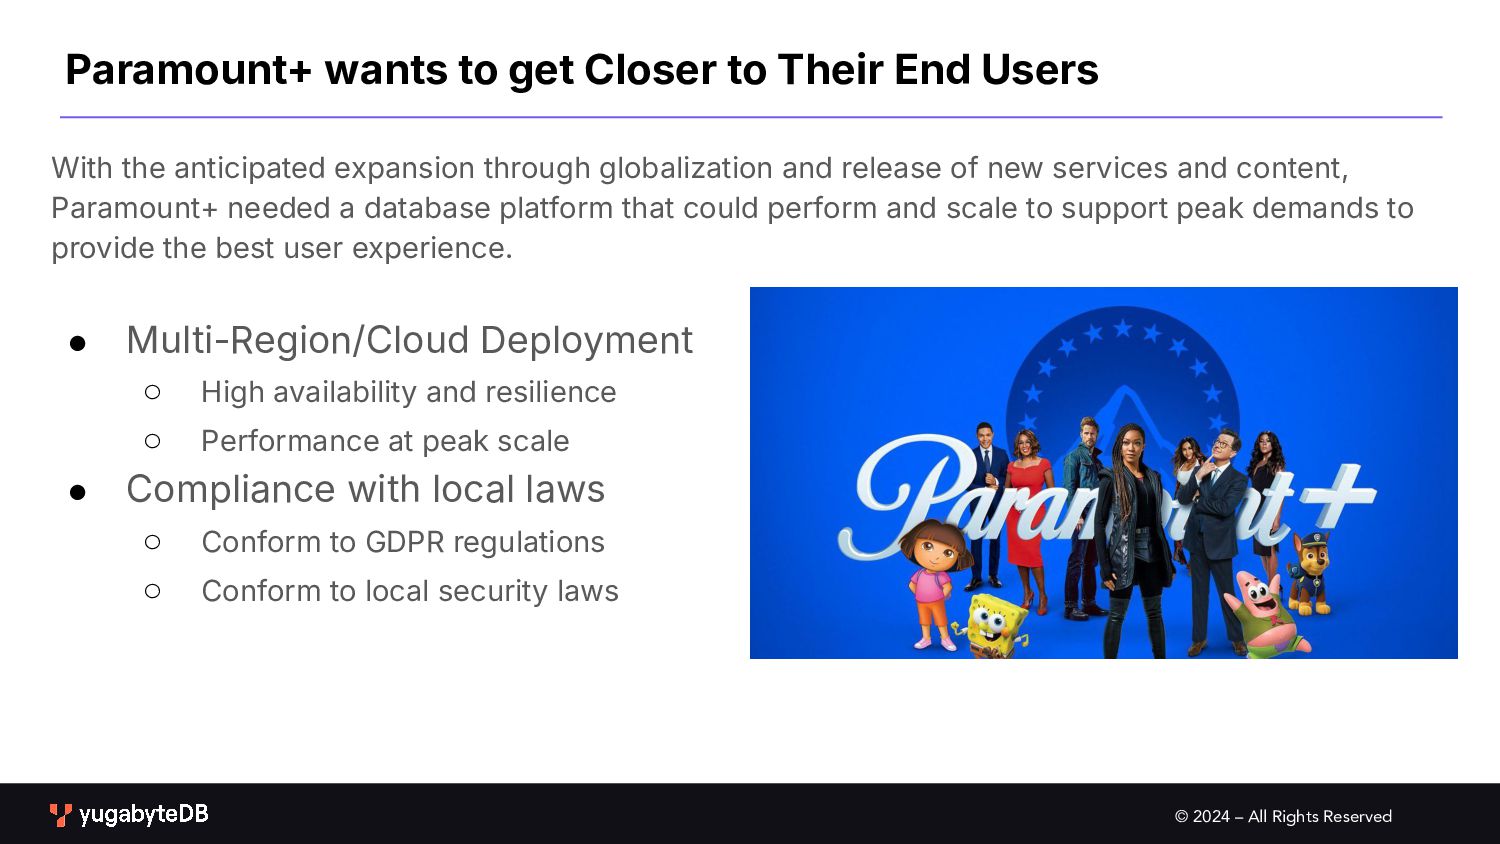
© 2024 – All Rights Reserved Paramount+ wants to get
Closer to Their End Users With the anticipated expansion through globalization and release of new services and content, Paramount+ needed a database platform that could perform and scale to support peak demands to provide the best user experience. • Multi-Region/Cloud Deployment ◦ High availability and resilience ◦ Performance at peak scale • Compliance with local laws ◦ Conform to GDPR regulations ◦ Conform to local security laws -
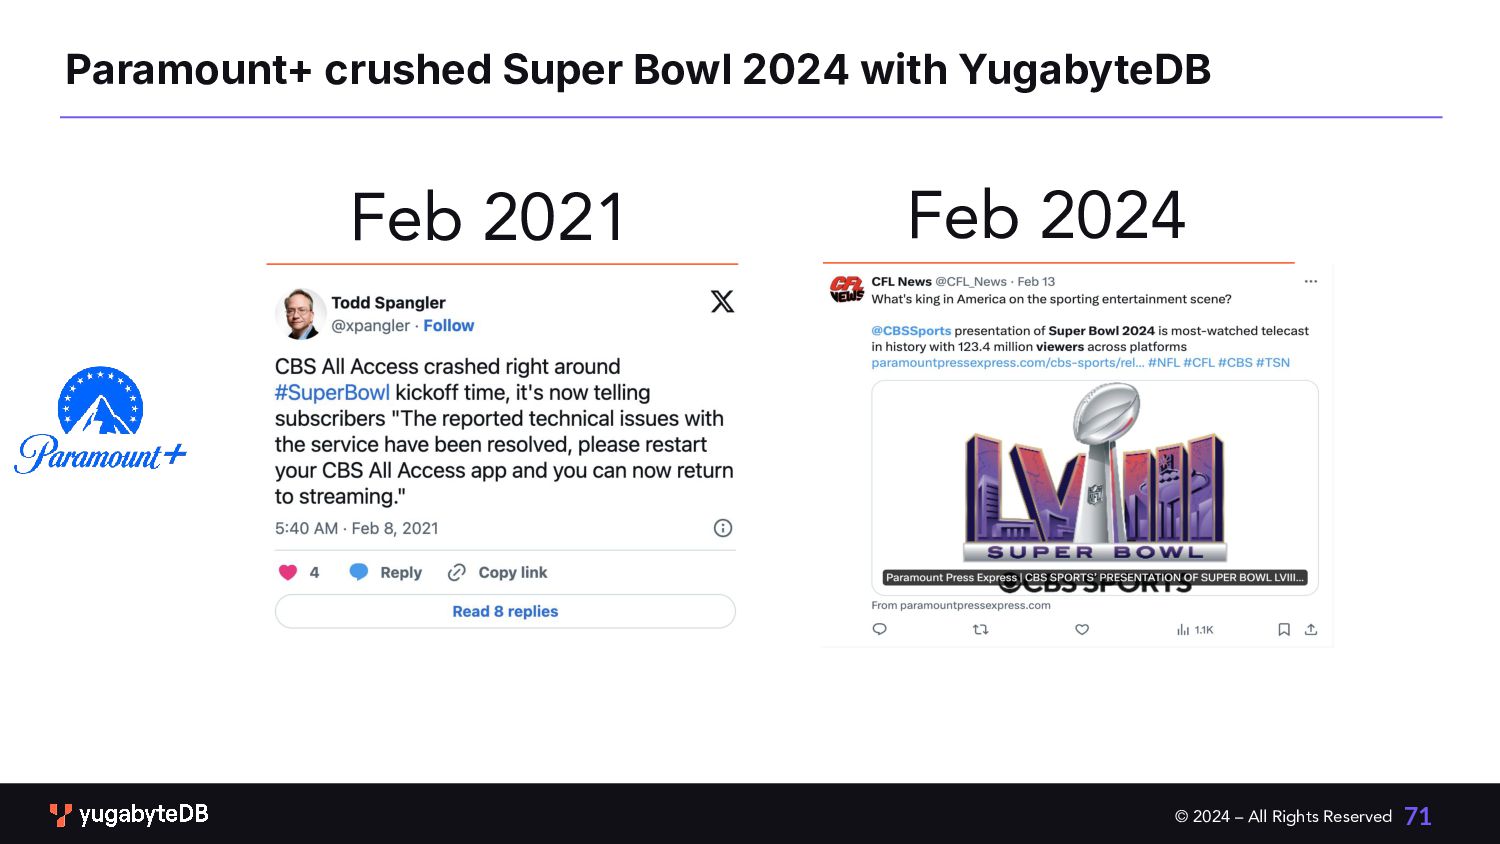
© 2024 – All Rights Reserved 71 Paramount+ crushed Super
Bowl 2024 with YugabyteDB Feb 2021 Feb 2024 -
© 2024 – All Rights Reserved “How much scale do
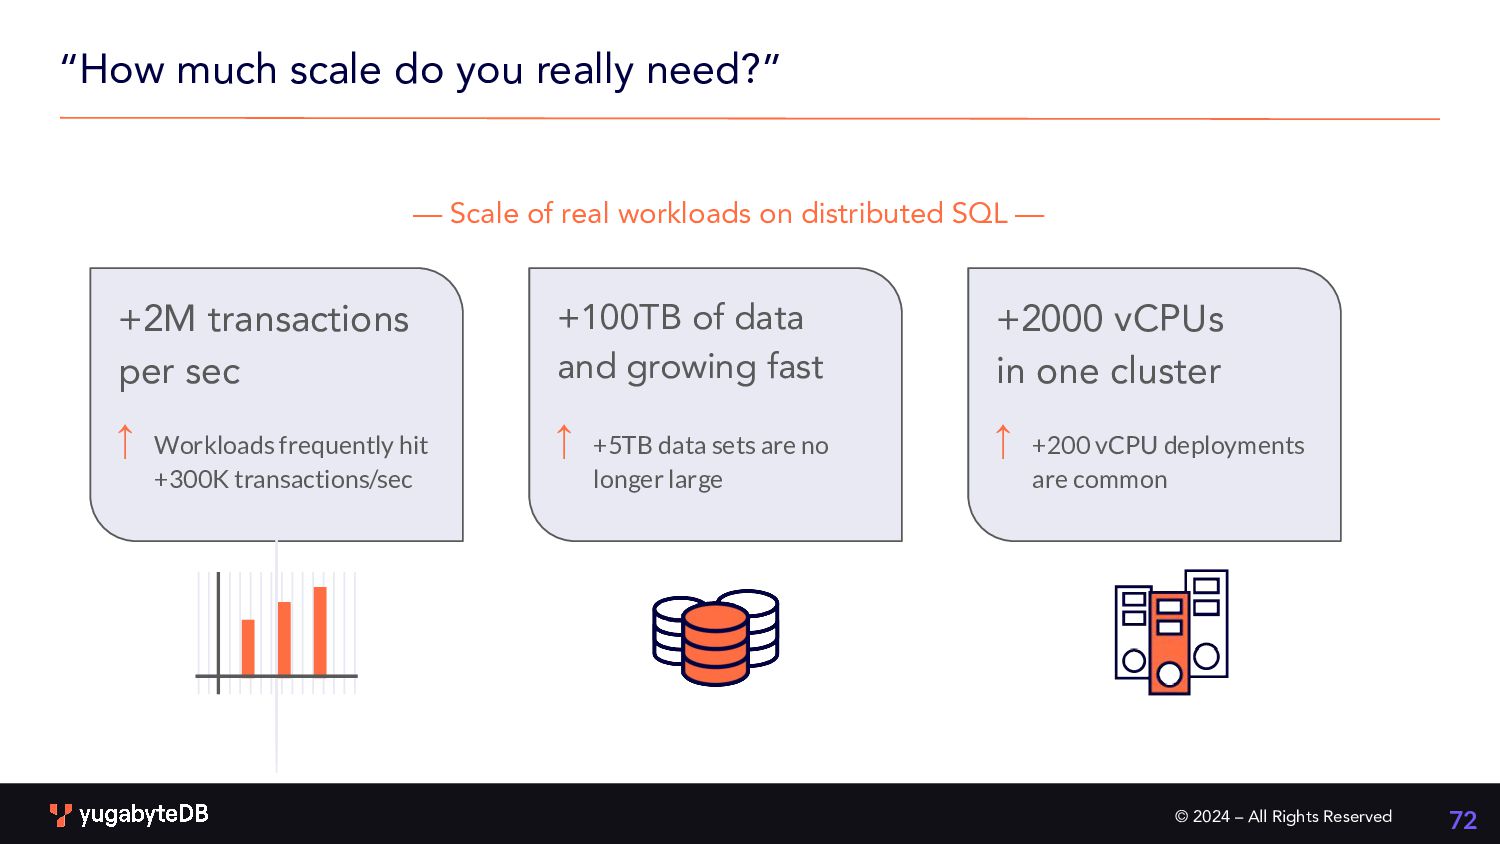
you really need?” 72 +2M transactions per sec Workloads frequently hit +300K transactions/sec ← — Scale of real workloads on distributed SQL — +100TB of data and growing fast +5TB data sets are no longer large ← +2000 vCPUs in one cluster +200 vCPU deployments are common ← -
© 2024 – All Rights Reserved IOPS • Scale on
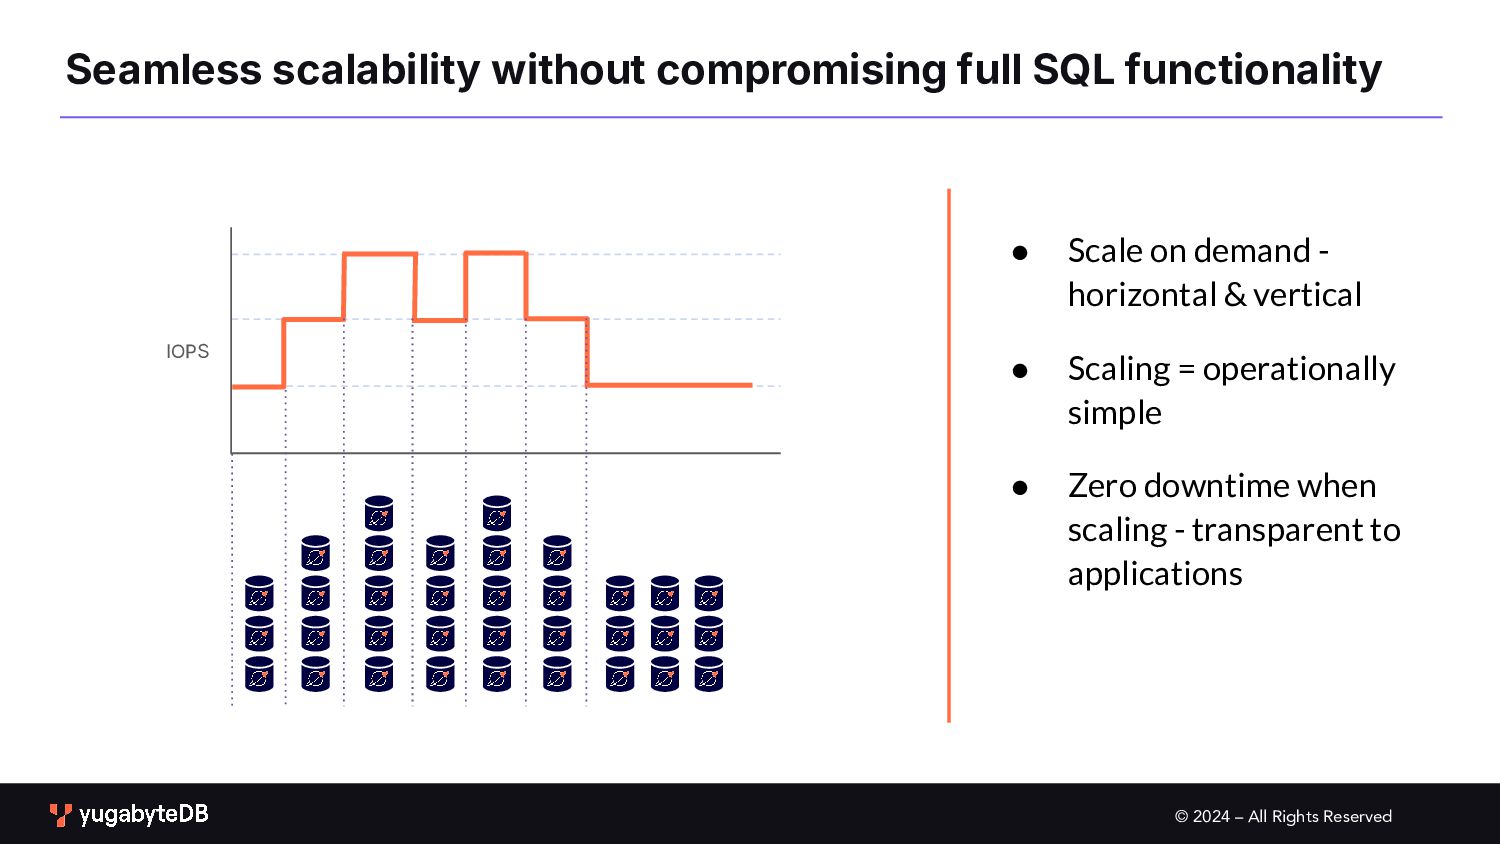
demand - horizontal & vertical • Scaling = operationally simple • Zero downtime when scaling - transparent to applications Seamless scalability without compromising full SQL functionality -
© 2024 – All Rights Reserved Remember these Six Elements
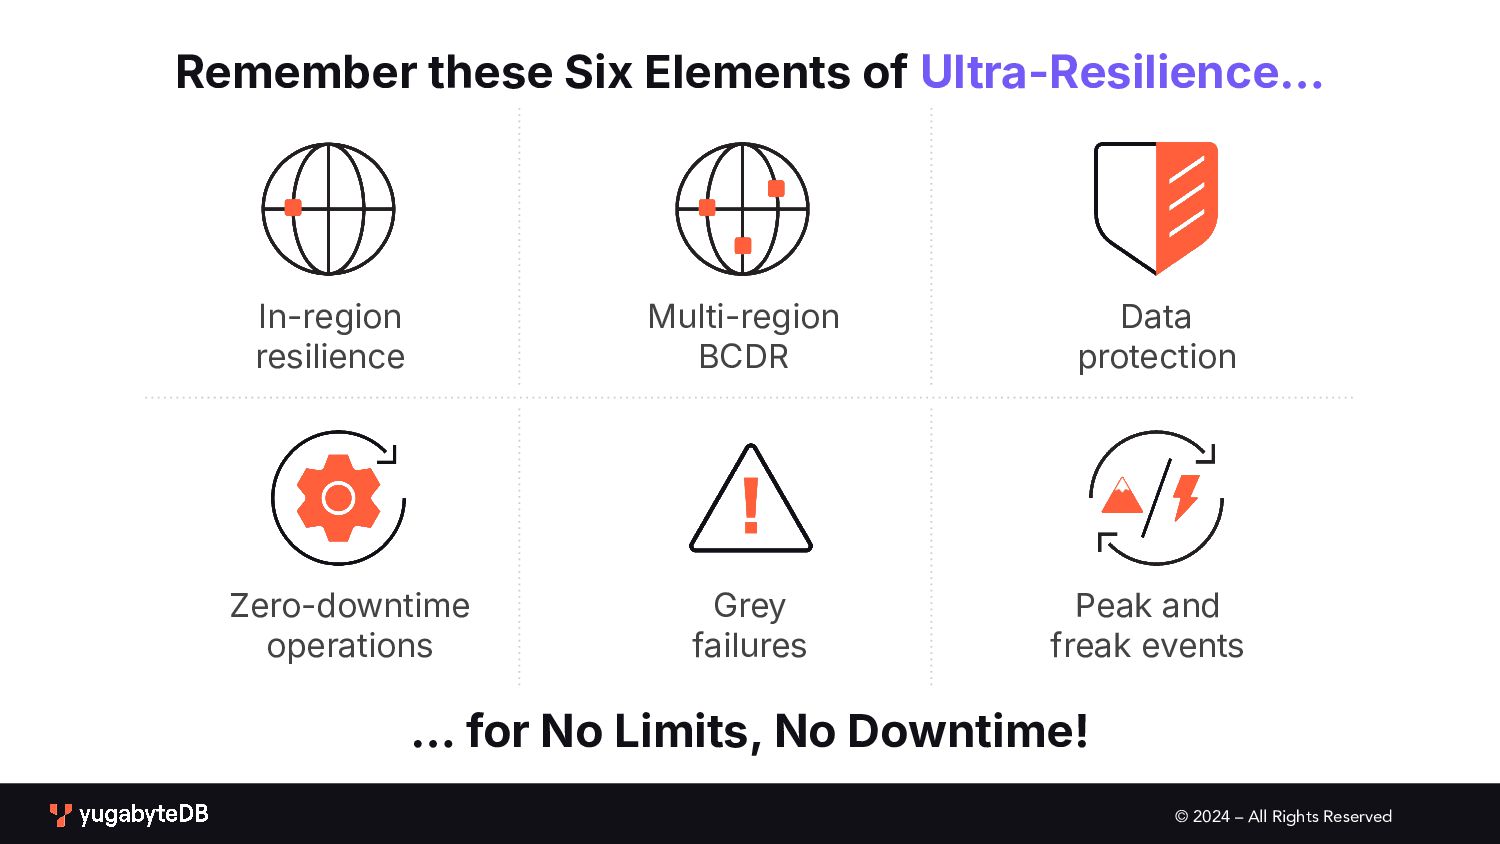
of Ultra-Resilience… In-region resilience Multi-region BCDR Zero-downtime operations Data protection Peak and freak events Grey failures … for No Limits, No Downtime! -
© 2024 – All Rights Reserved Scale High-Availability Zero-downtime Cost
Low Latency Throughput Performance Cloud Agnostic Open Source Lower Risk 99.99% Business Continuity 75 © 2024 All Rights Reserved Security -
© 2024 – All Rights Reserved Thank You Join us
on Slack: yugabyte.com/slack Star us on Github: github.com/yugabyte/yugabyte-db
 yugabytejapan
 irinanazarova
 rabernat
 chriscoyier
 malarkey
 davidcarrasco
 lara
 inesmontani
 oripsolob
 cassininazir
 emna__ayadi
 lemiorhan
 ryanjones