Share
Embed
Kingdom of the Machine
RubyKaigi 2026
https://rubykaigi.org/2026/presentations/spikeolaf.html

yui-knk
April 22, 2026
Transcript
132 slides
-
Kingdom of the Machine April 22, 2026 in RubyKaigi 2026
@yui-knk Yuichiro Kaneko -
˒ Chomsky Hierarchy ˒ Equivalence Checking for (Regular) Languages ˒
Attribute Grammars and Their Subclasses ˒ Automatic Parser Generation from Grammars ˒ etc. The Golden Age of Formal Languages -
˒ Ruby ˒ PHP ˒ Perl ˒ C ˒ Go
˒ PostgreSQL ˒ etc. The Golden Age of Formal Parser Generators -
˒ Were people fed up with dif fi cult theory?
˒ Had GNU Bison stopped evolving? ˒ Go ahead - put your favorite complaint about parsing theory here!!! ˒ 2006: GCC migrates it’s parser from Bison to hand-written recursive- descent parsers (C++ was 2004) ˒ 2015: Go migrates it’s parser from Bison to hand-written recursive- descent parsers They are like a dream on a spring night… -
˒ A Combination of Recursive Descent and Pratt Parsing ˒
Largely absent from major textbooks, such as the Dragon Book ˒ Vaughan R. Pratt, “Top Down Operator Precedence.” (1973) Implementing a Hand-Written Parser Today -
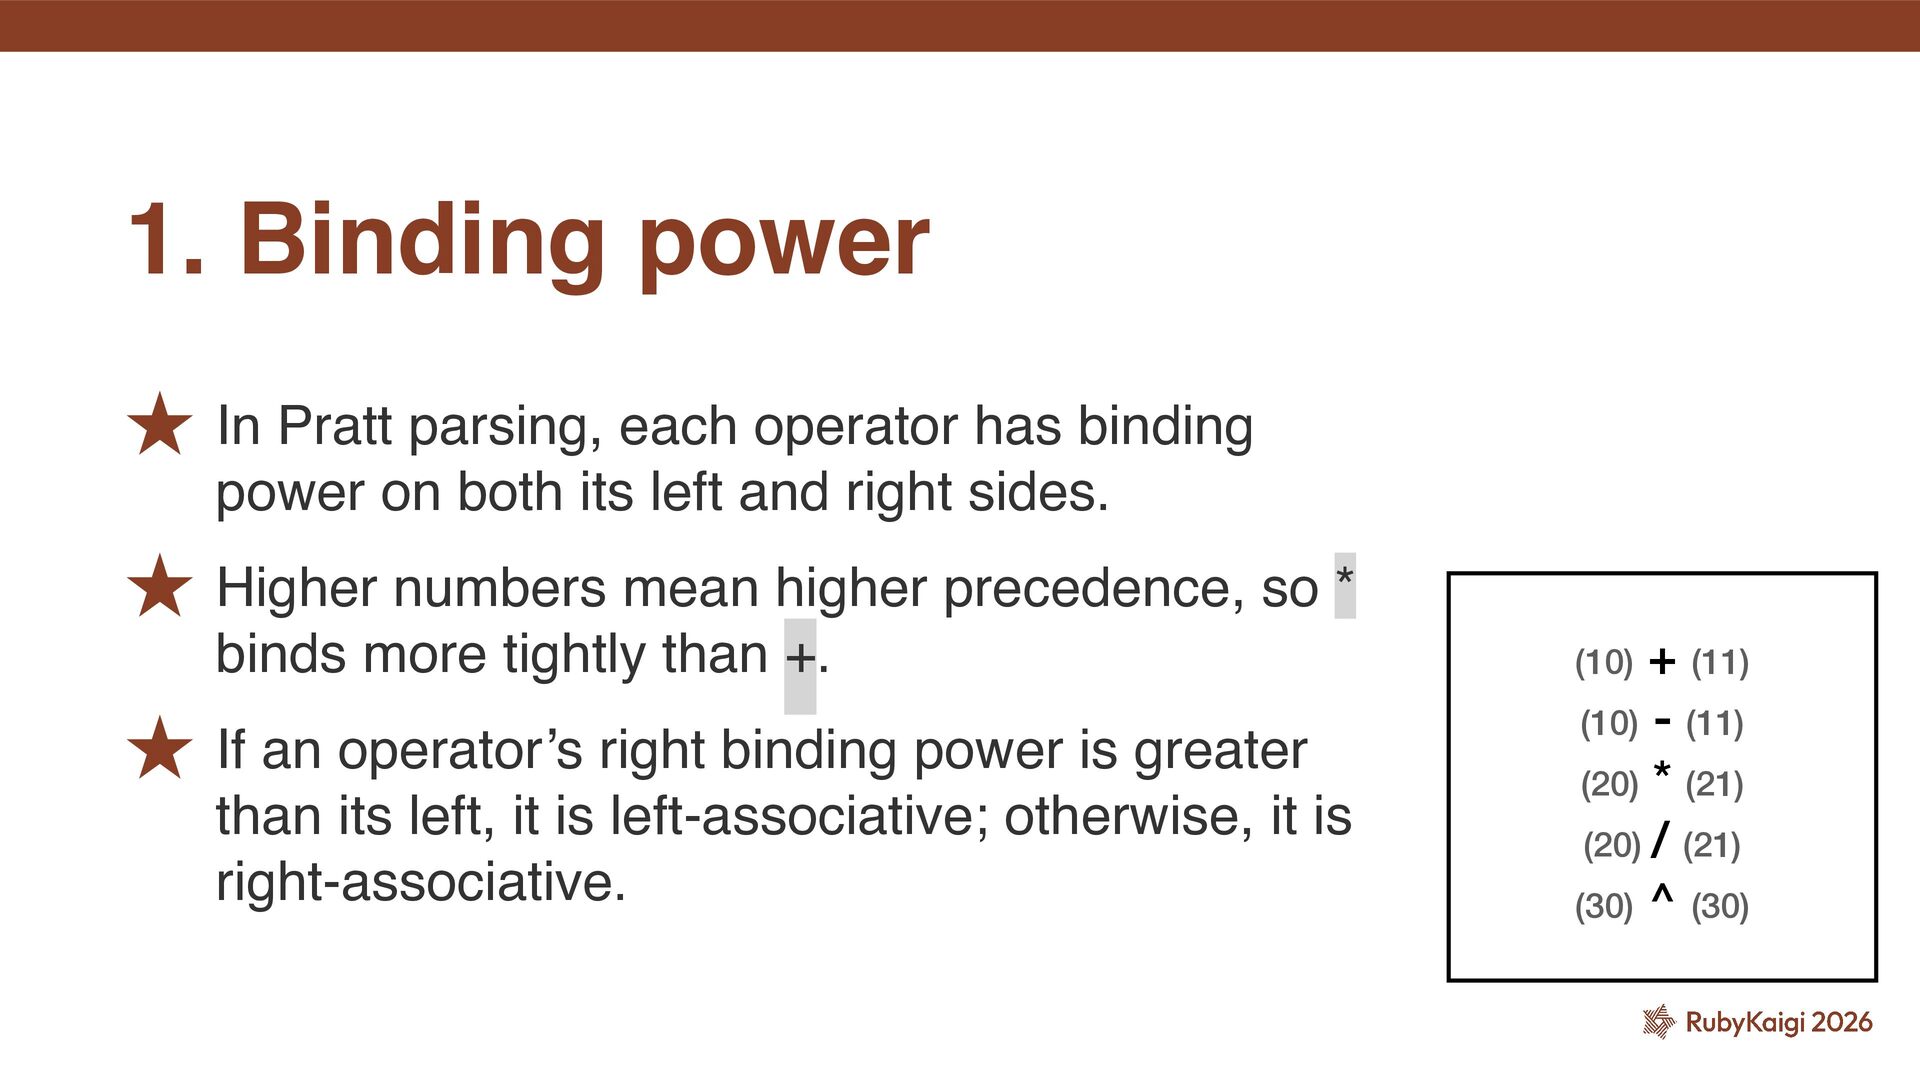
˒ In Pratt parsing, each operator has binding power on
both its left and right sides. ˒ Higher numbers mean higher precedence, so * binds more tightly than +. ˒ If an operator’s right binding power is greater than its left, it is left-associative; otherwise, it is right-associative. 1. Binding power (10) + (11) (10) - (11) (20) * (21) (20) / (21) (30) ^ (30) -
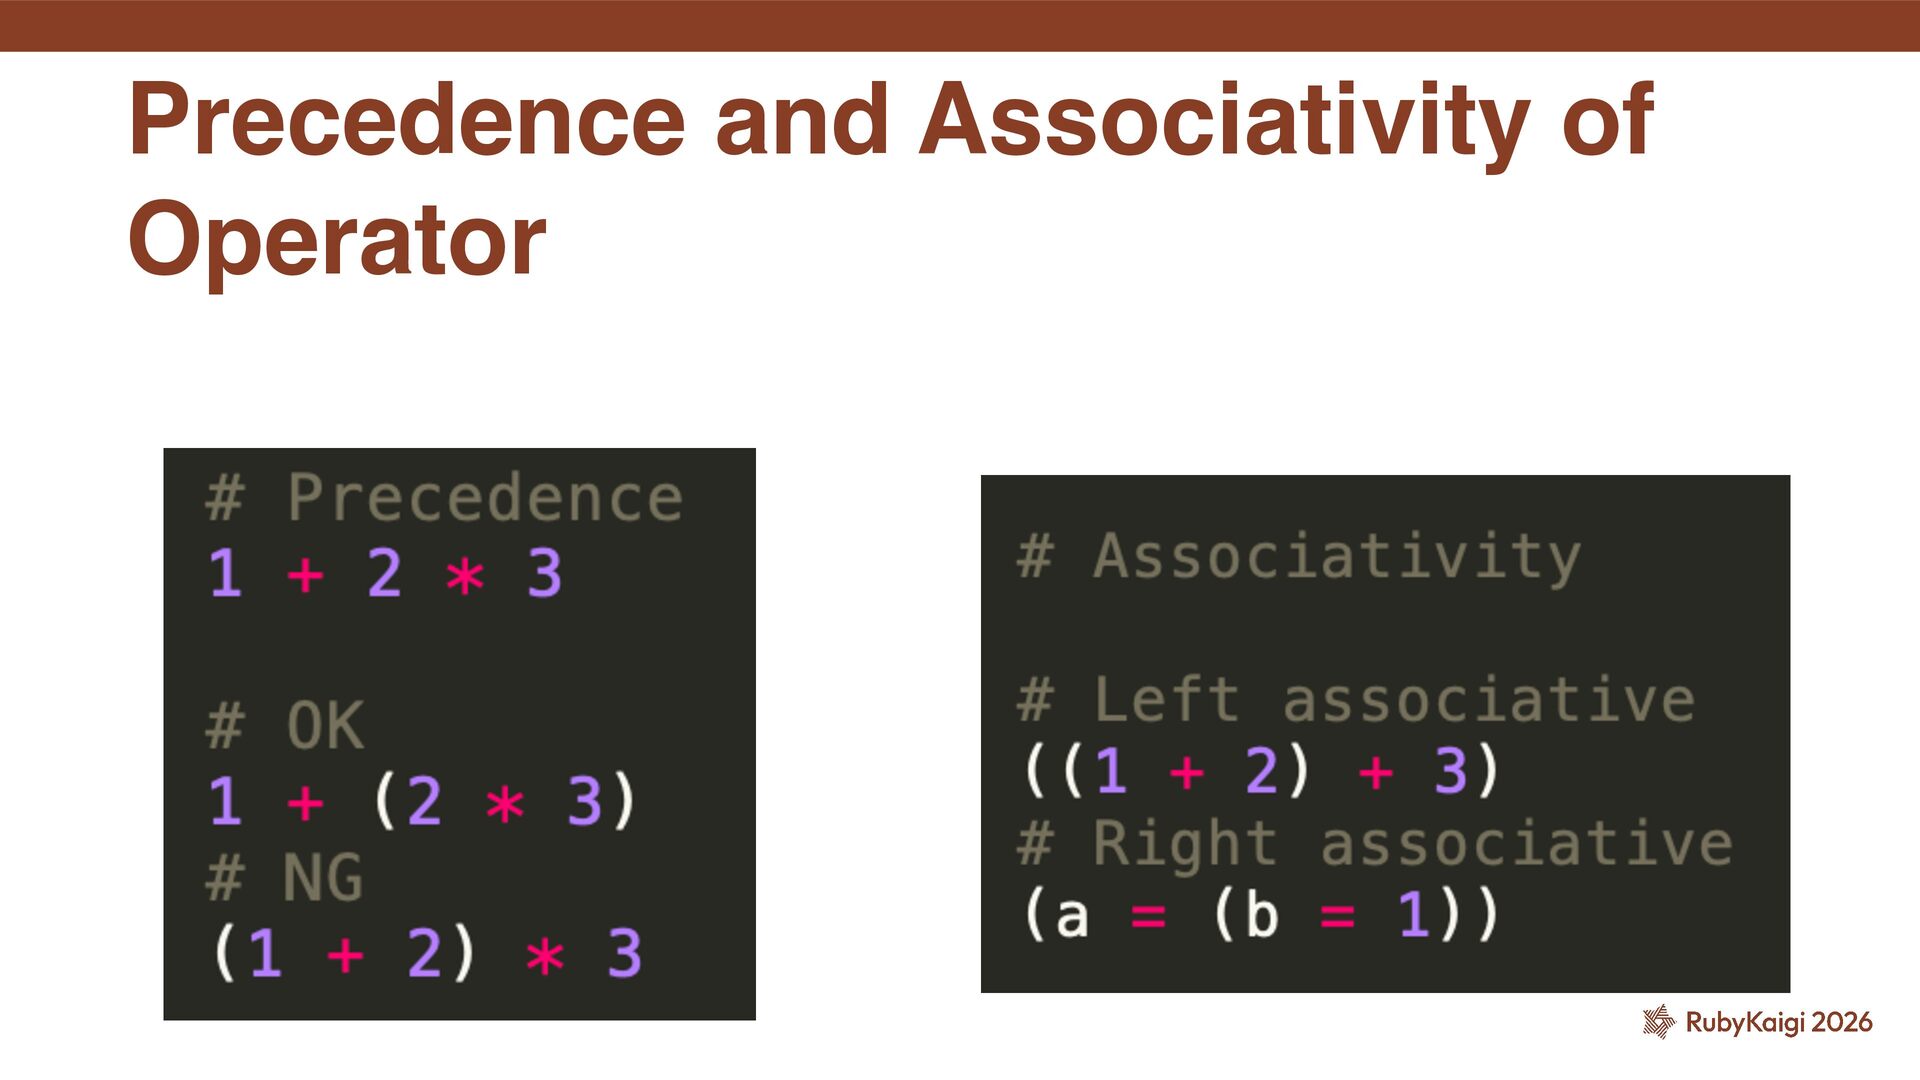
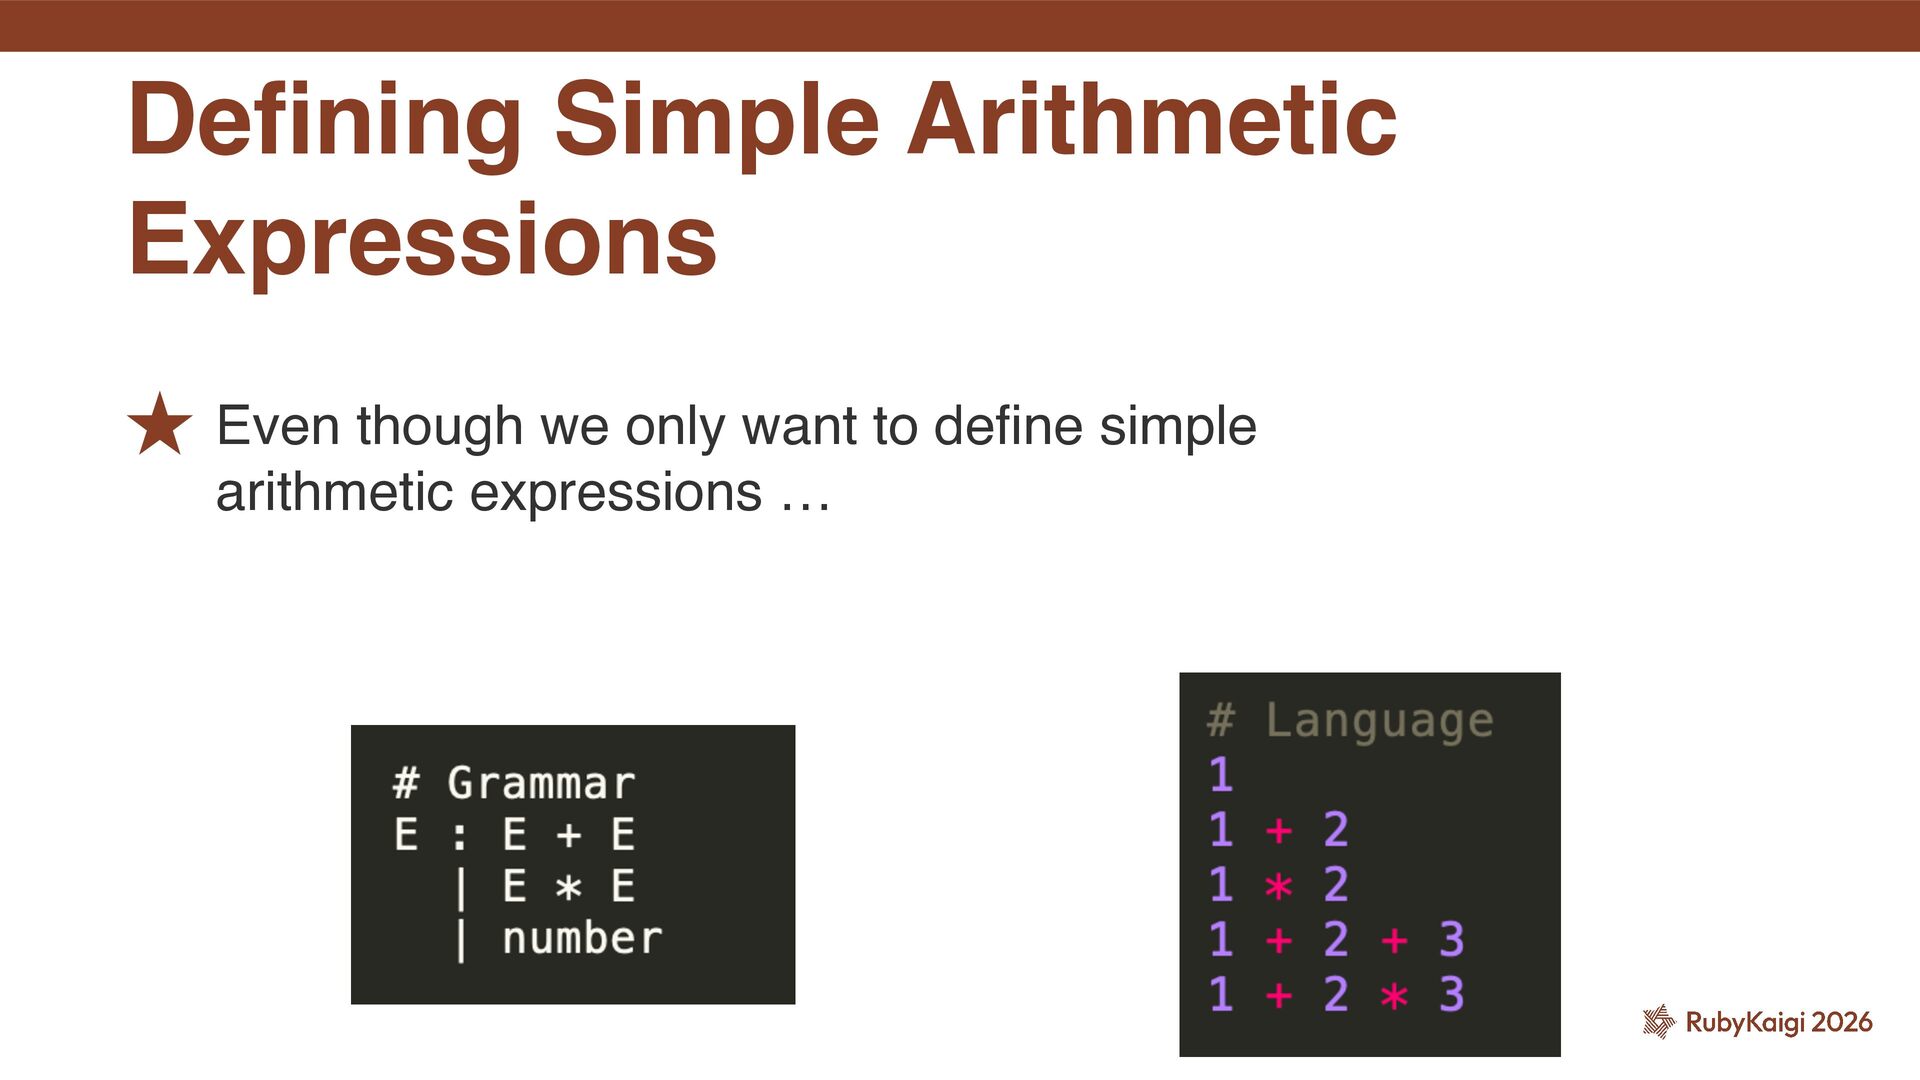
De fi ning Simple Arithmetic Expressions ˒ Even though we
only want to de fi ne simple arithmetic expressions … -
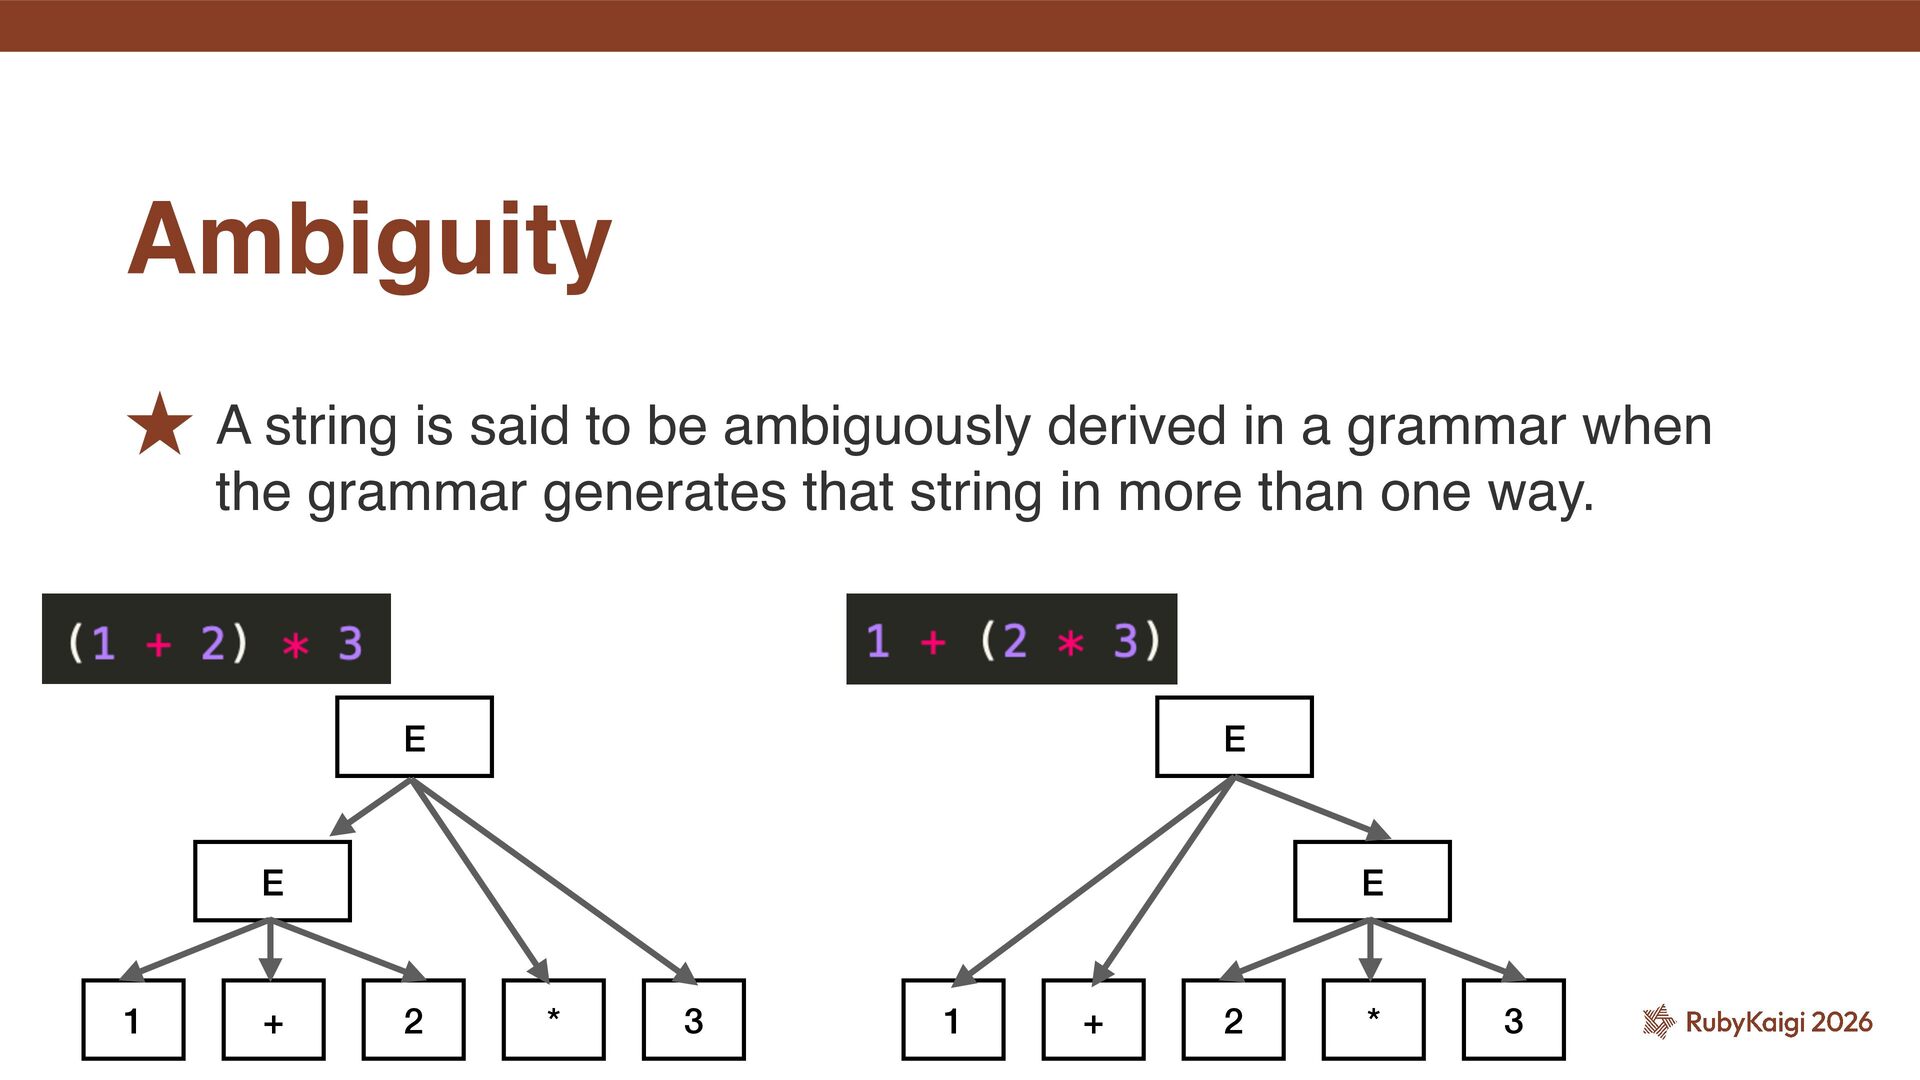
˒ A string is said to be ambiguously derived in
a grammar when the grammar generates that string in more than one way. Ambiguity E 1 2 3 E + * E 1 2 3 E + * -
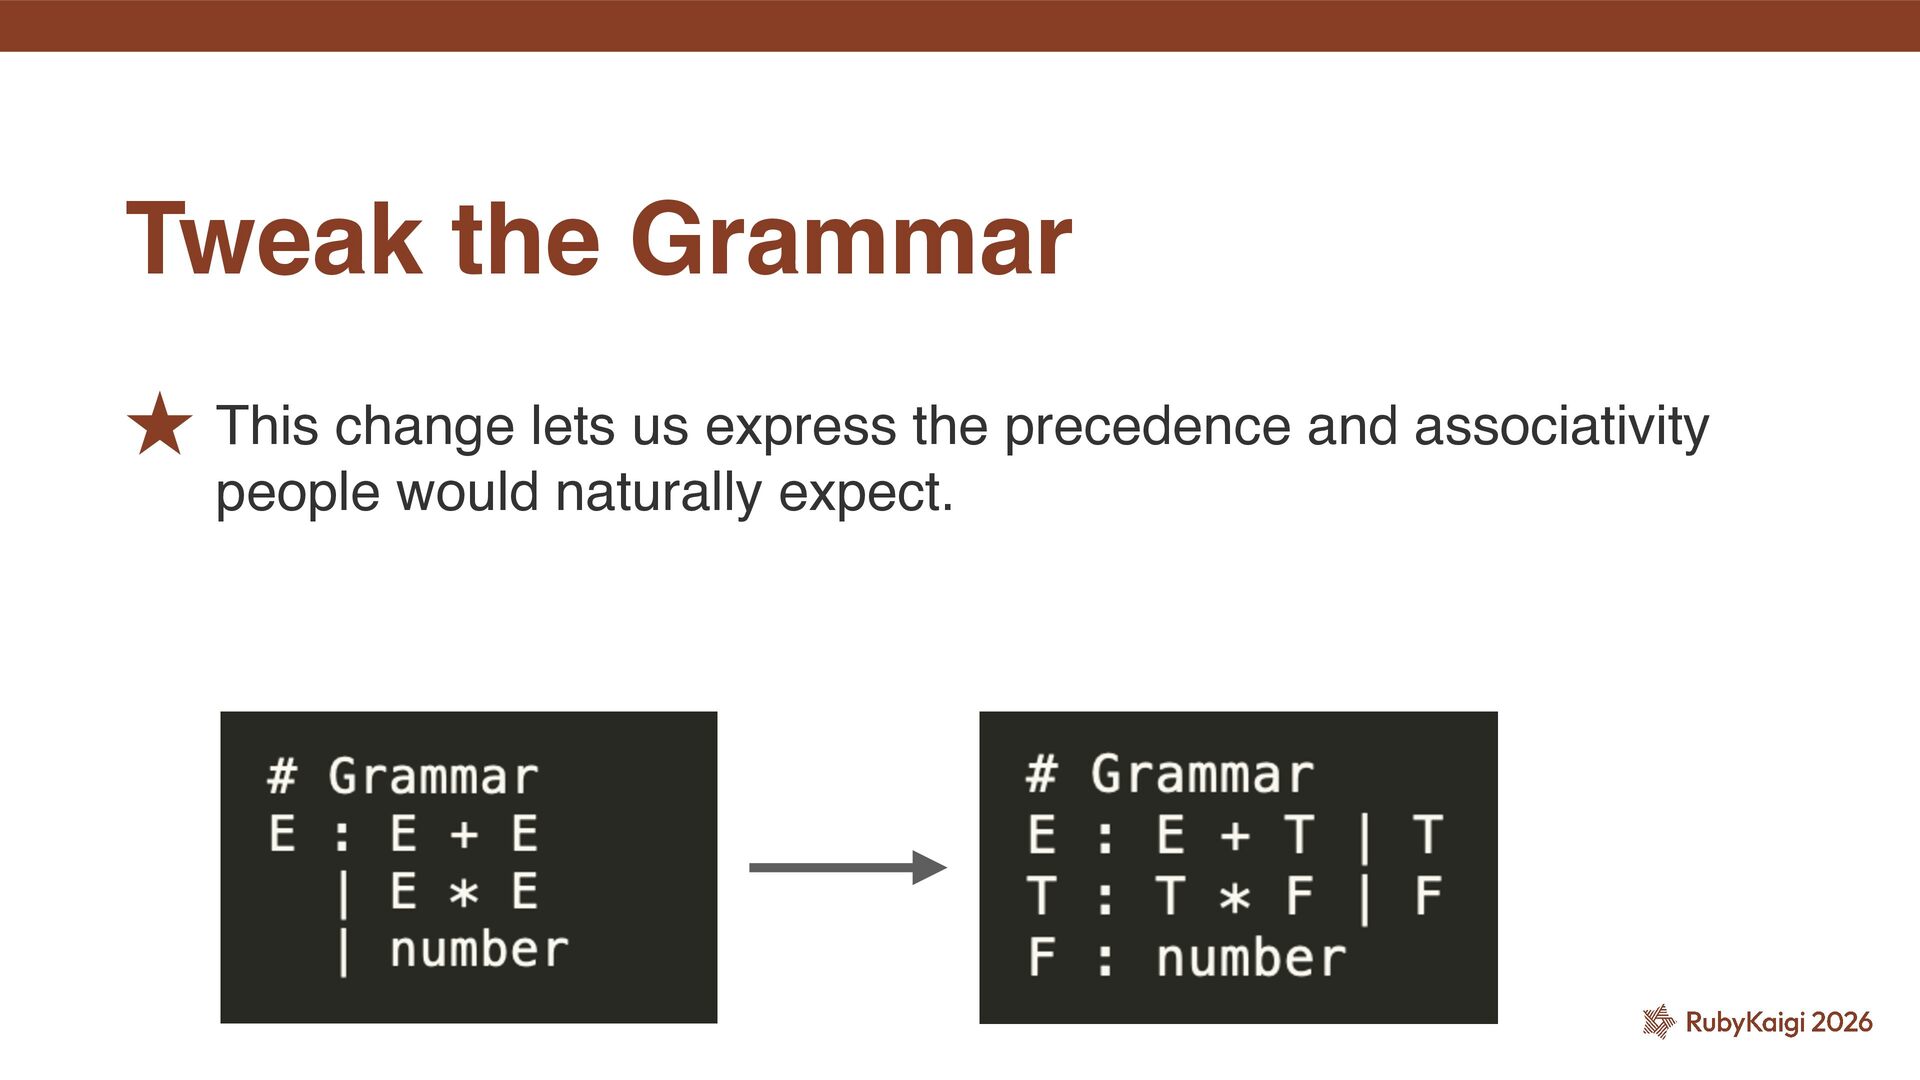
Tweak the Grammar ˒ This change lets us express the
precedence and associativity people would naturally expect. -
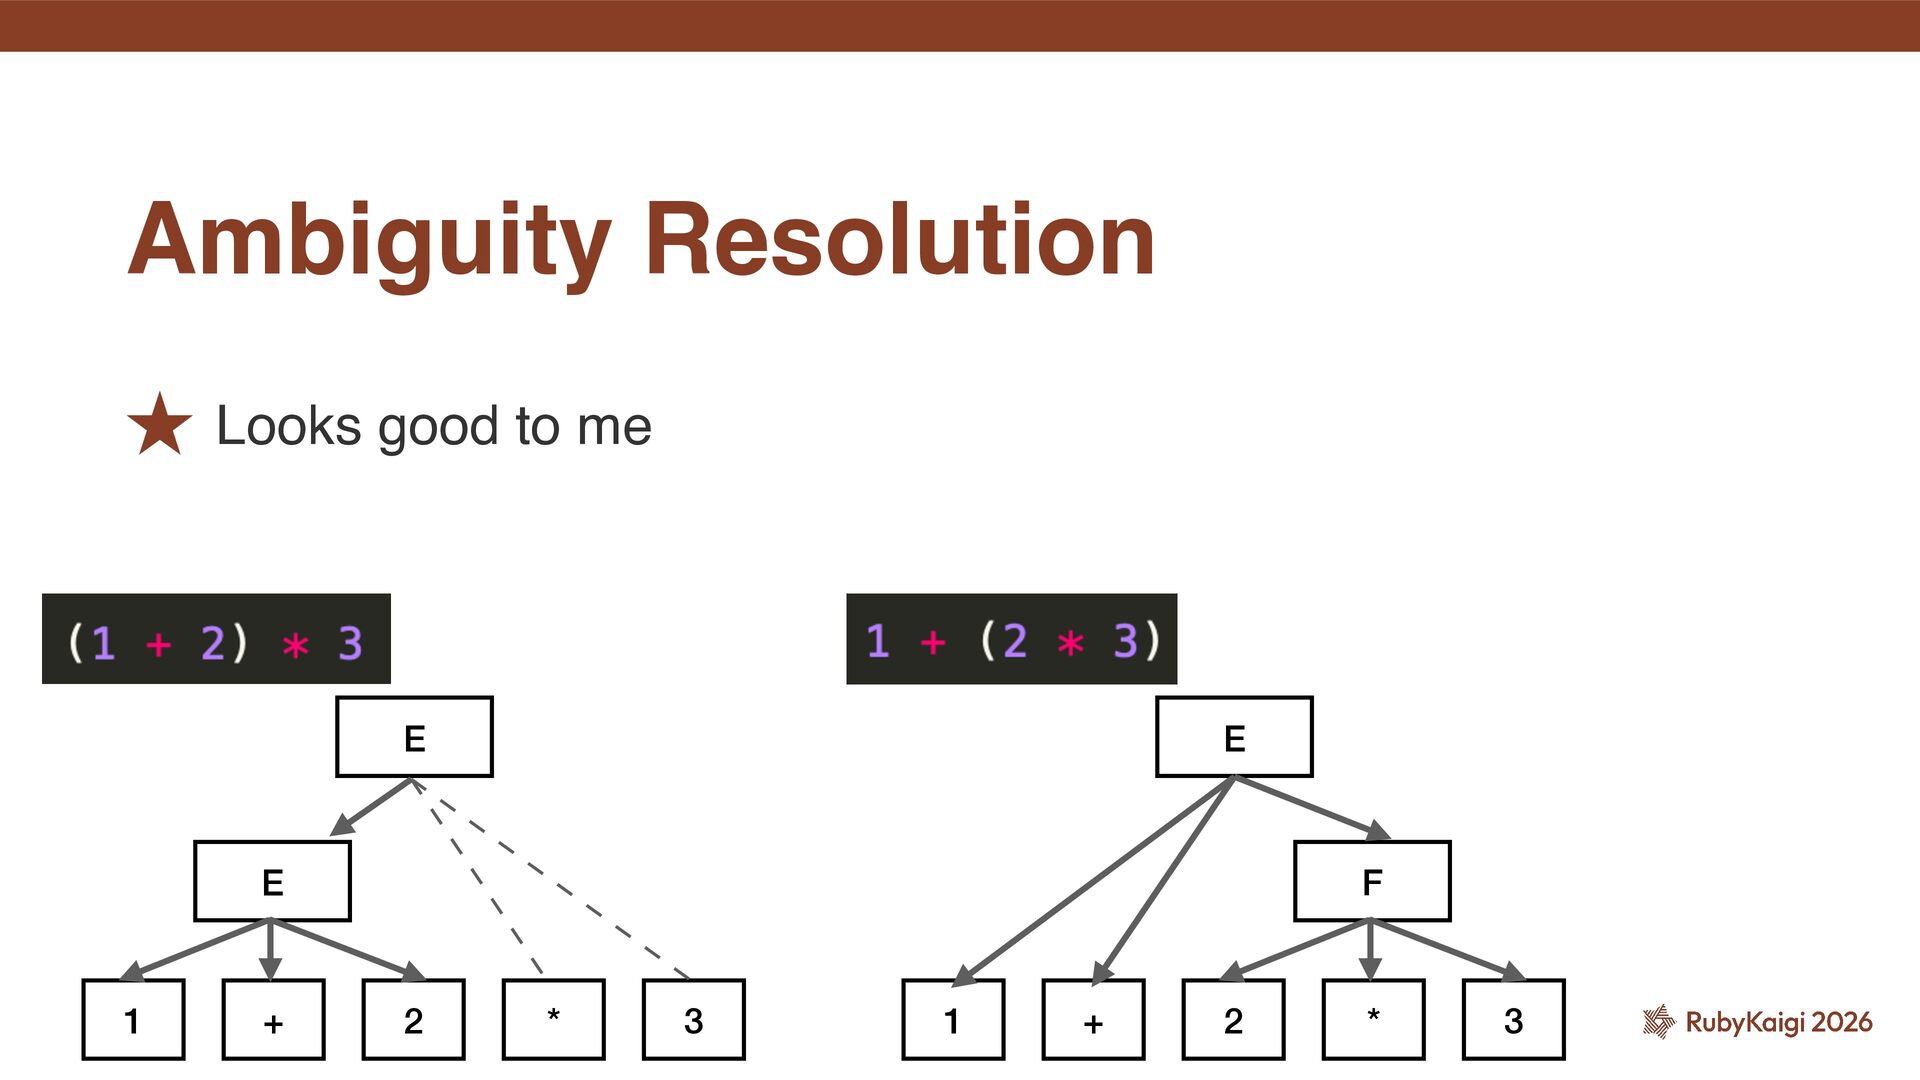
˒ Looks good to me Ambiguity Resolution E 1 2
3 E + * E 1 2 3 F + * -
˒ Determine which rule to apply by always looking ahead
a token. ˒ LL(k) allows us to look ahead k tokens, but here we assume the usual case: k = 1. ˒ In other words, this forbids multiple rules from beginning with the same token. ˒ In an actual implementation, left-recursive rules cause an in fi nite loop. Recursive Descent Parser (LL parser) -
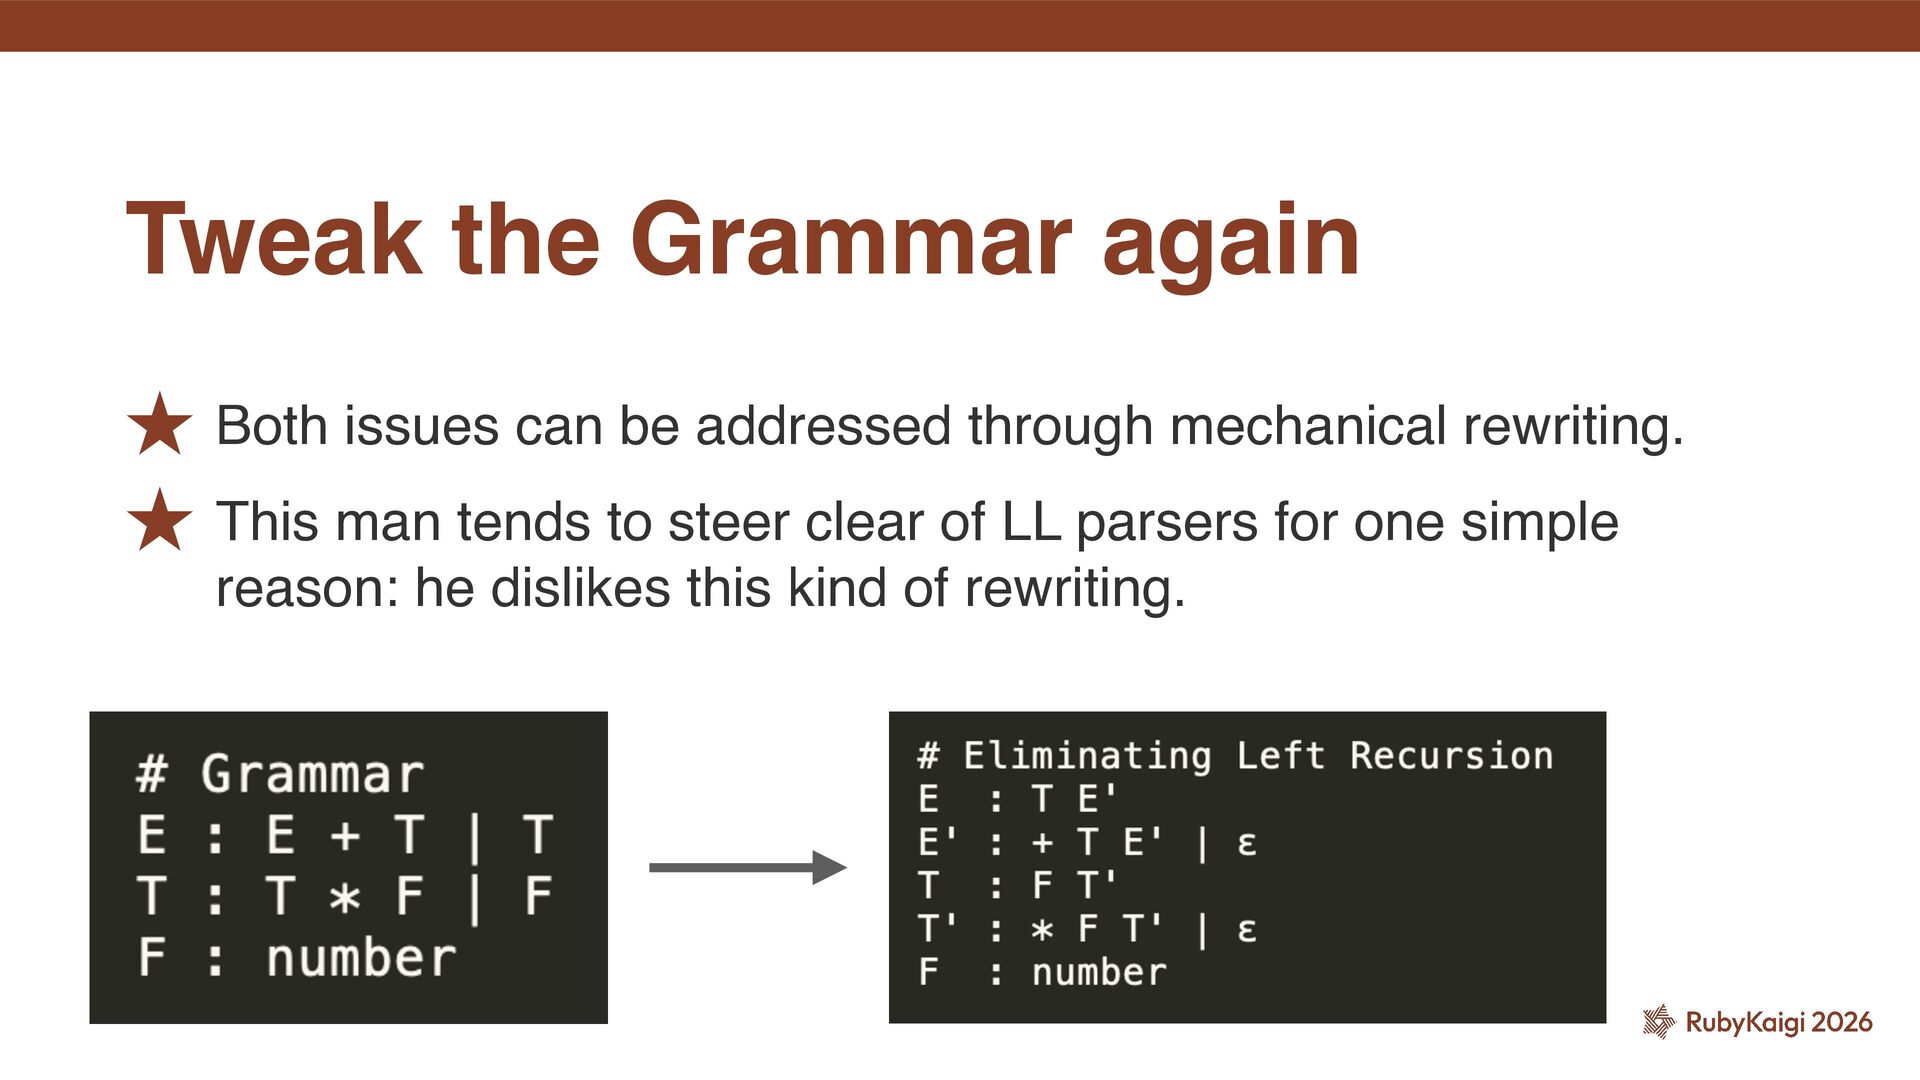
˒ Both issues can be addressed through mechanical rewriting. ˒
This man tends to steer clear of LL parsers for one simple reason: he dislikes this kind of rewriting. Tweak the Grammar again -
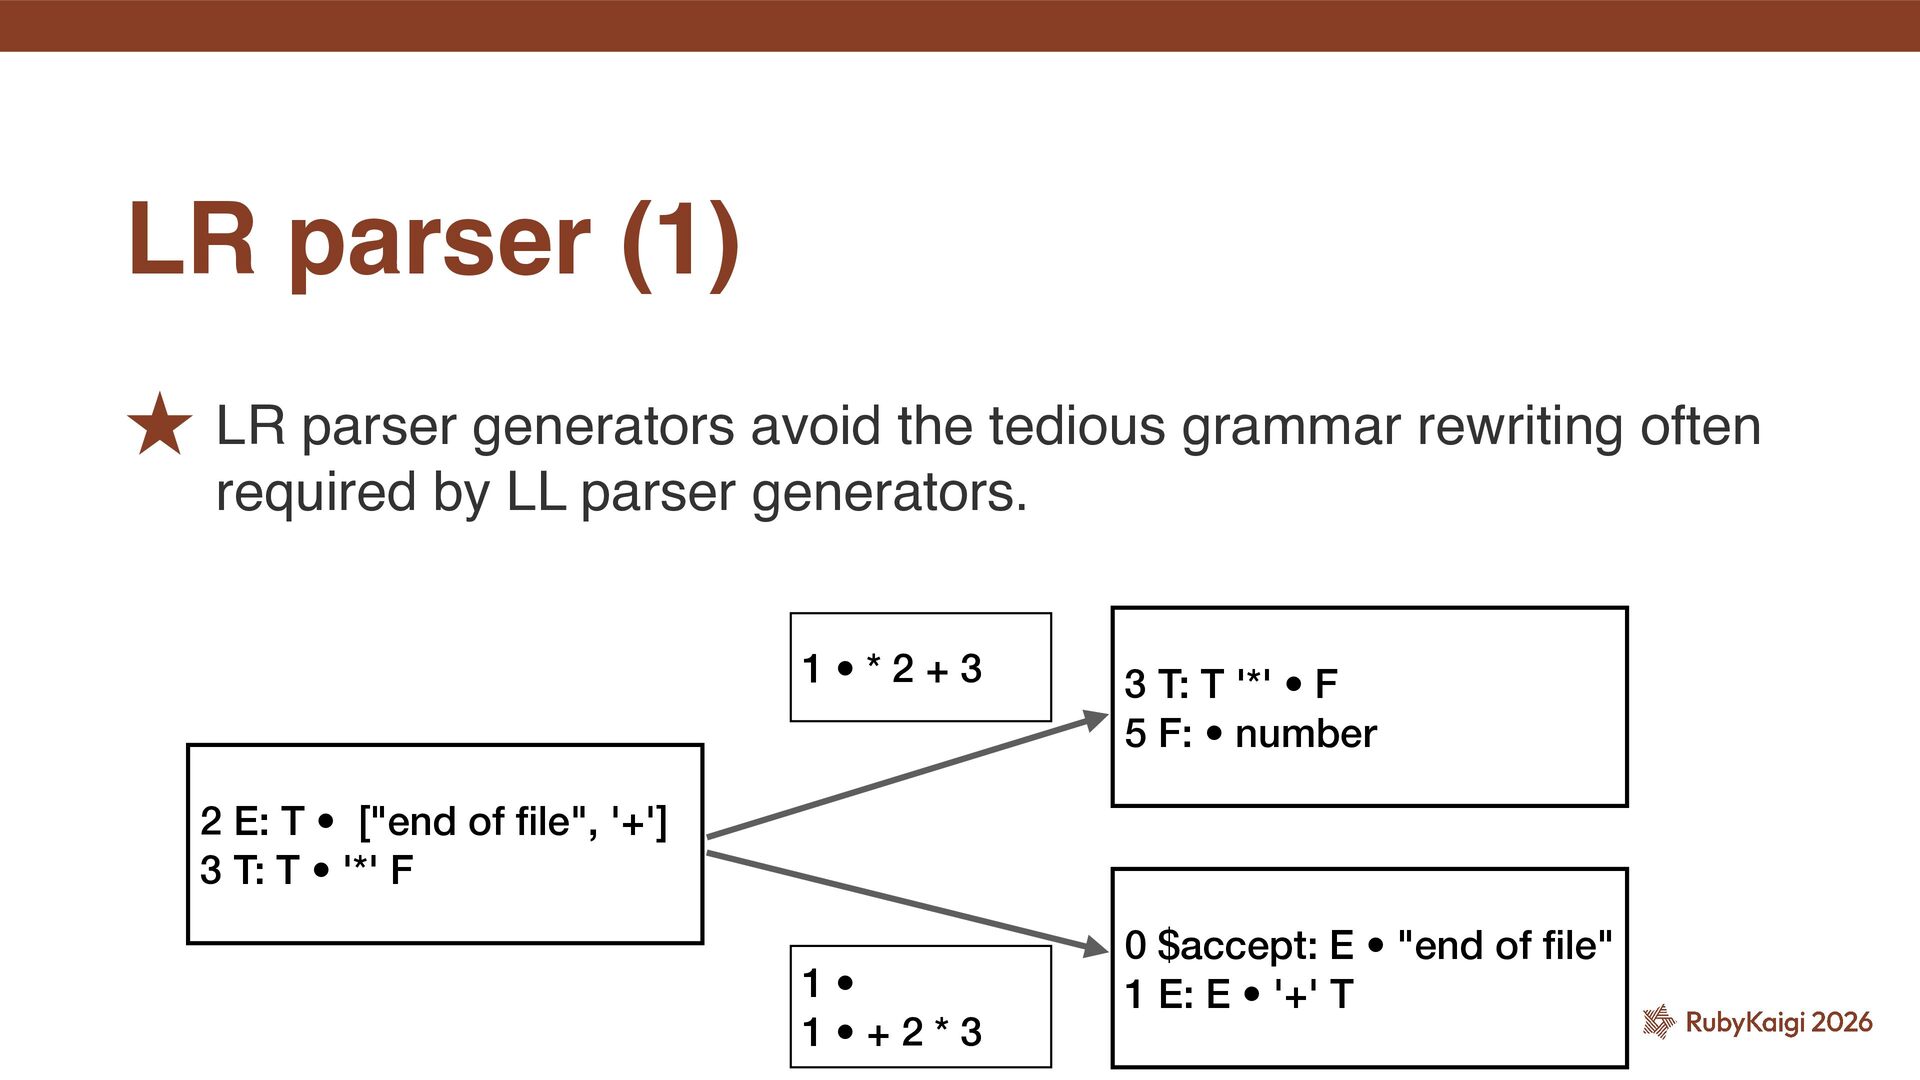
˒ LR parser generators avoid the tedious grammar rewriting often
required by LL parser generators. LR parser (1) 2 E: T • ["end of fi le", '+'] 3 T: T • '*' F 3 T: T '*' • F 5 F: • number 0 $accept: E • "end of fi le" 1 E: E • '+' T 1 • * 2 + 3 1 • 1 • + 2 * 3 -
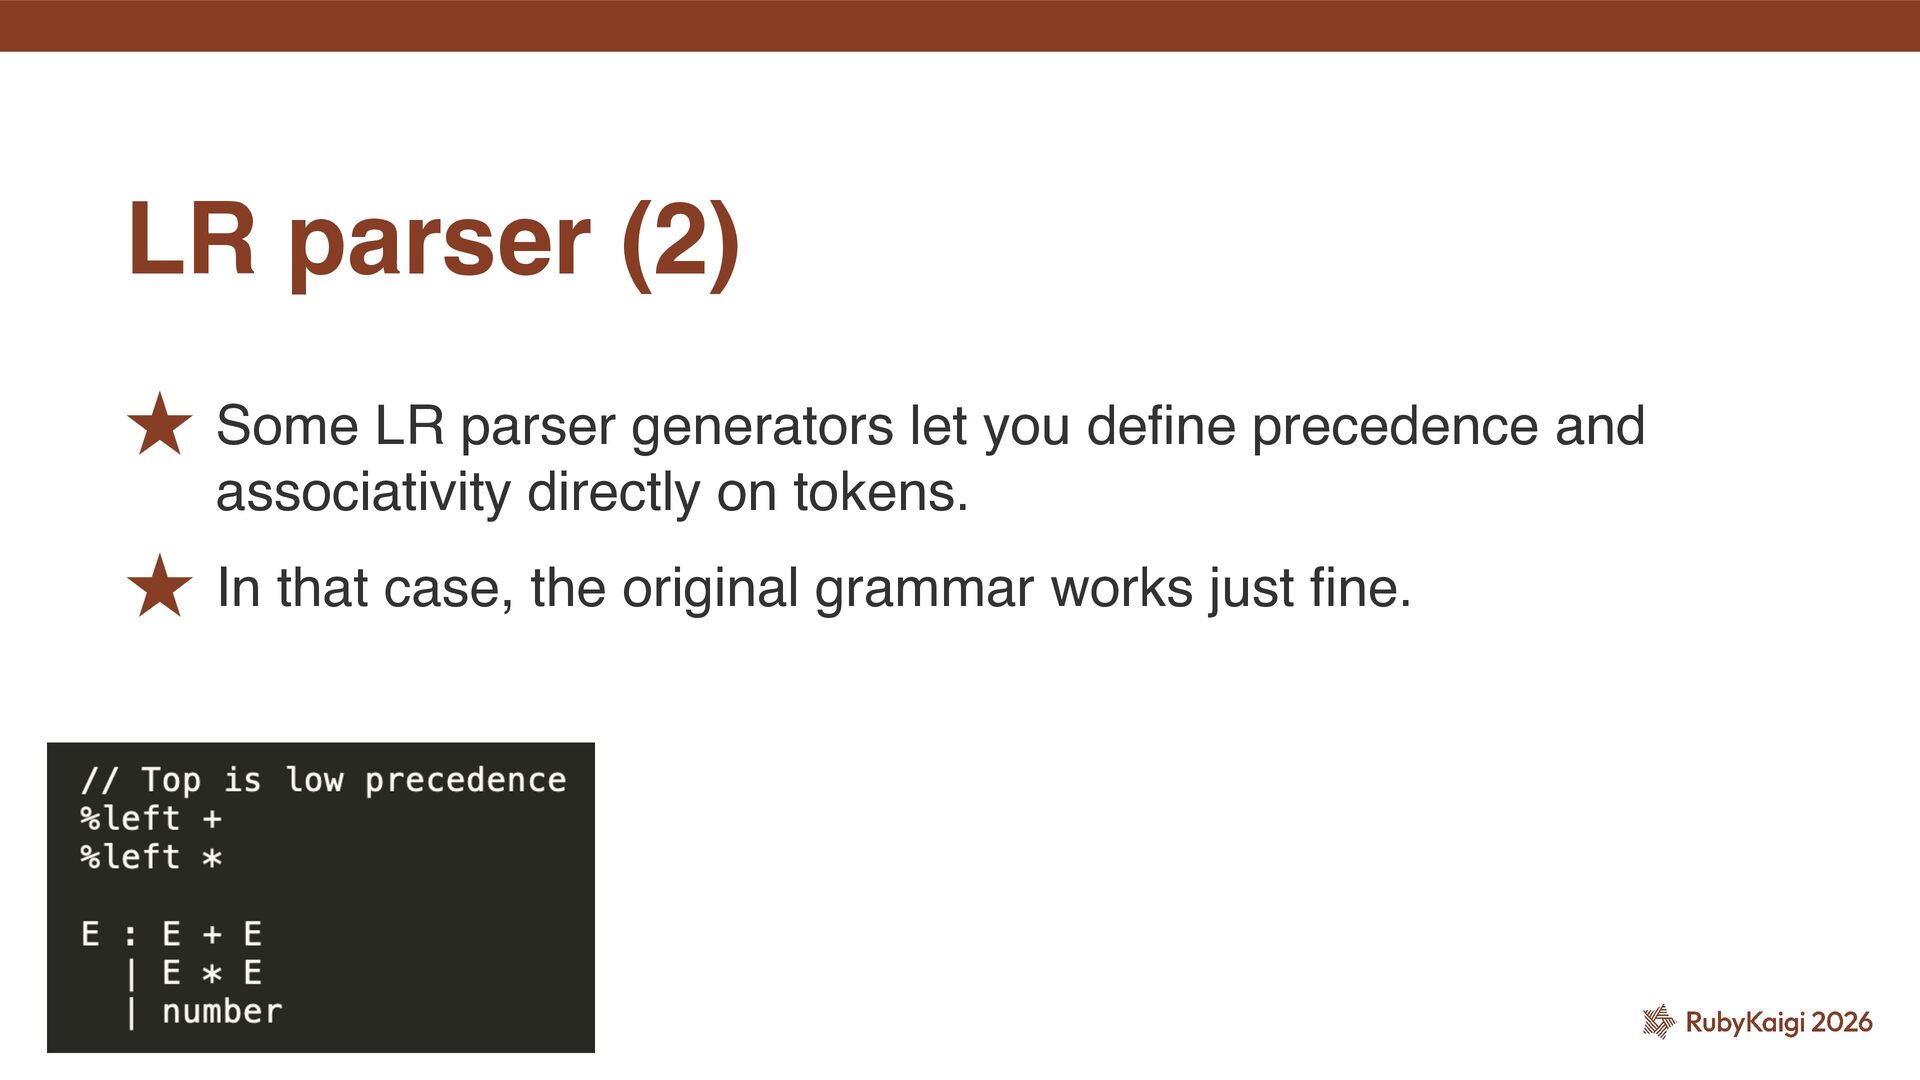
˒ Some LR parser generators let you de fi ne
precedence and associativity directly on tokens. ˒ In that case, the original grammar works just fi ne. LR parser (2) -
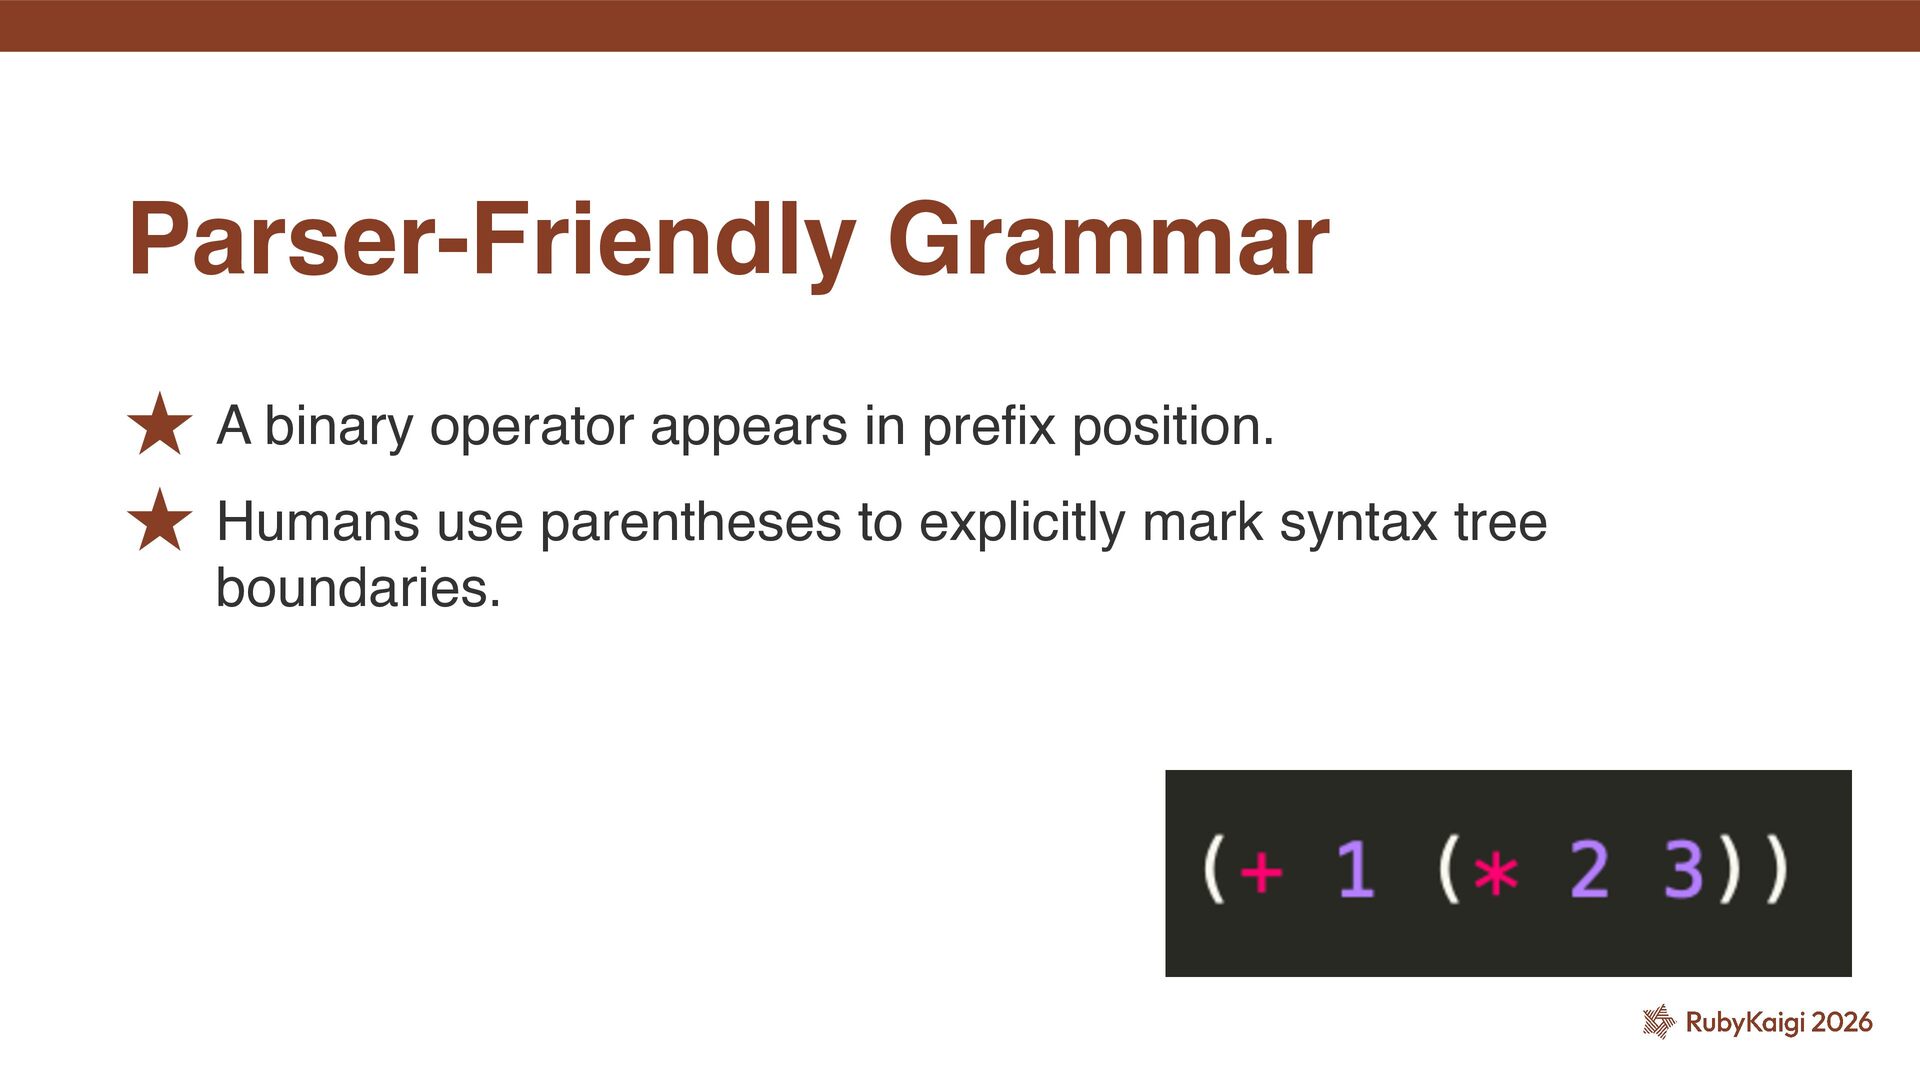
˒ A binary operator appears in pre fi x position.
˒ Humans use parentheses to explicitly mark syntax tree boundaries. Parser-Friendly Grammar -
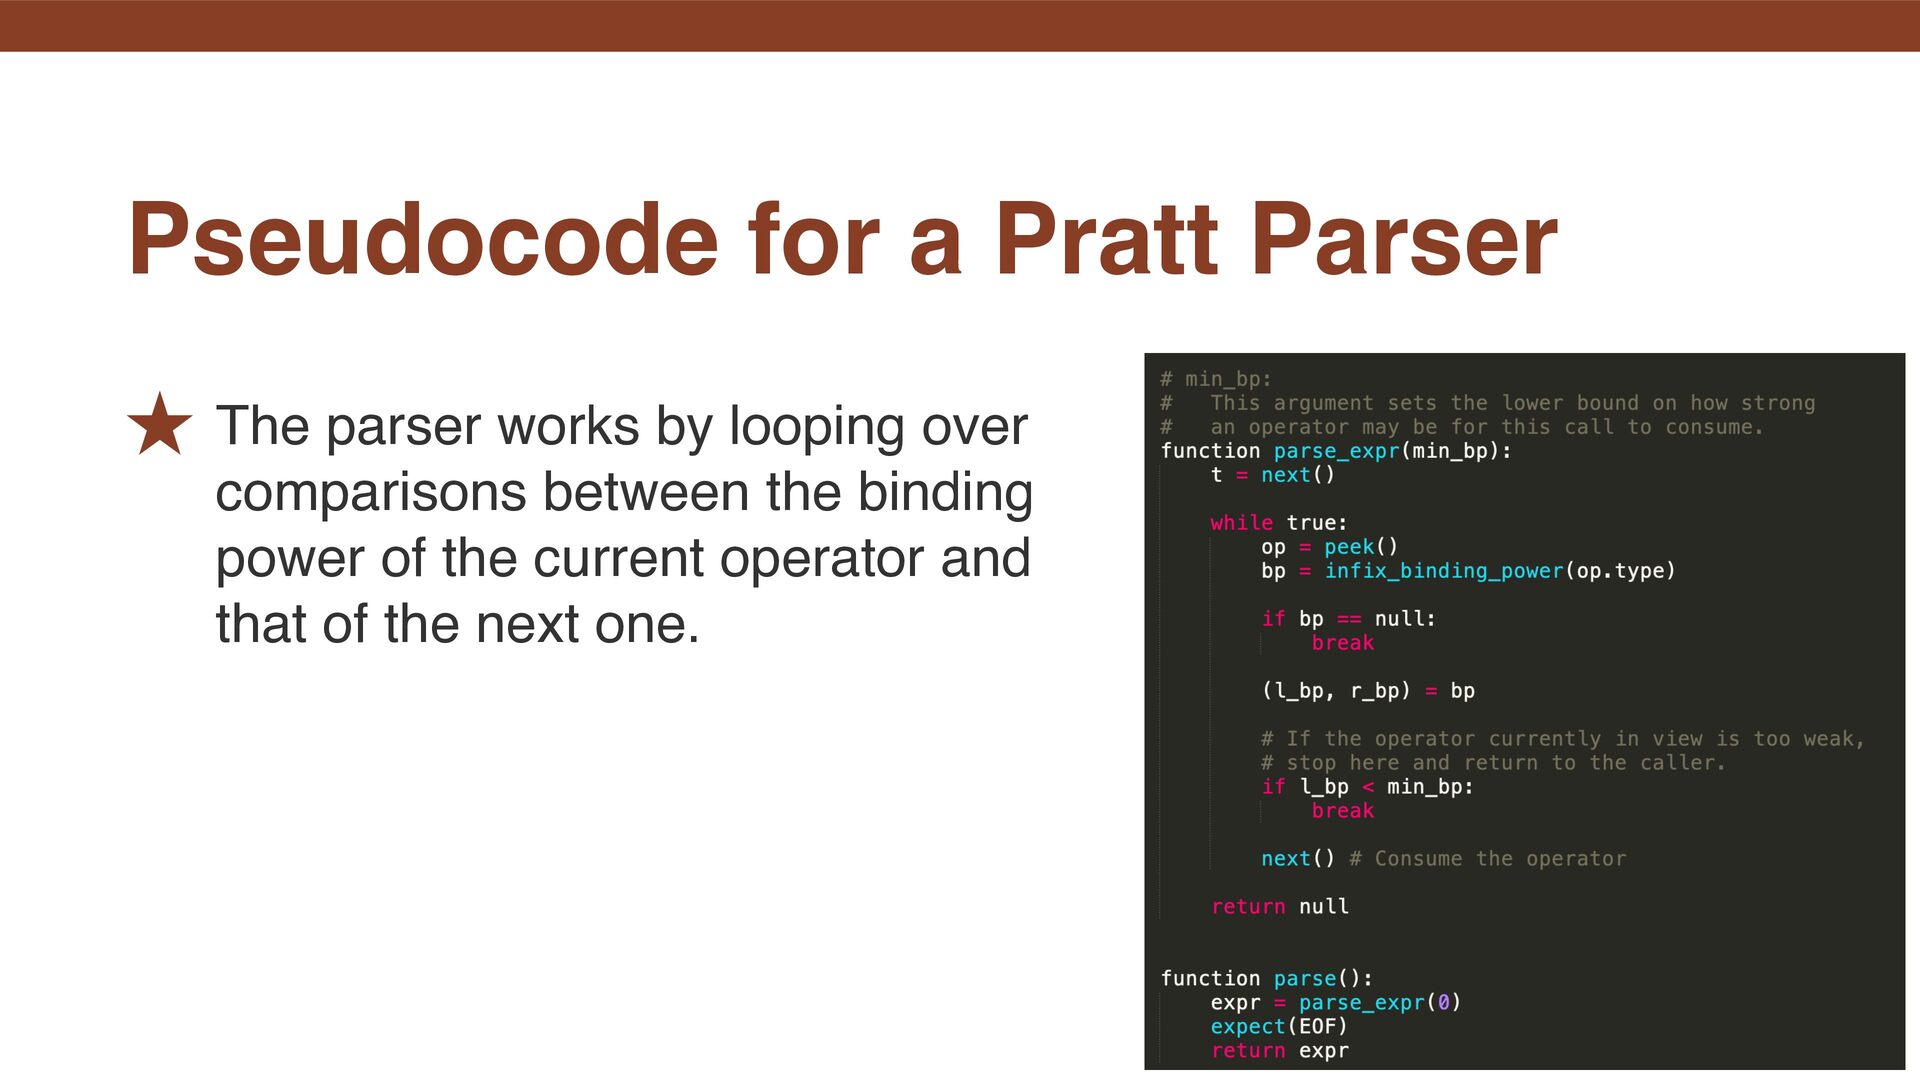
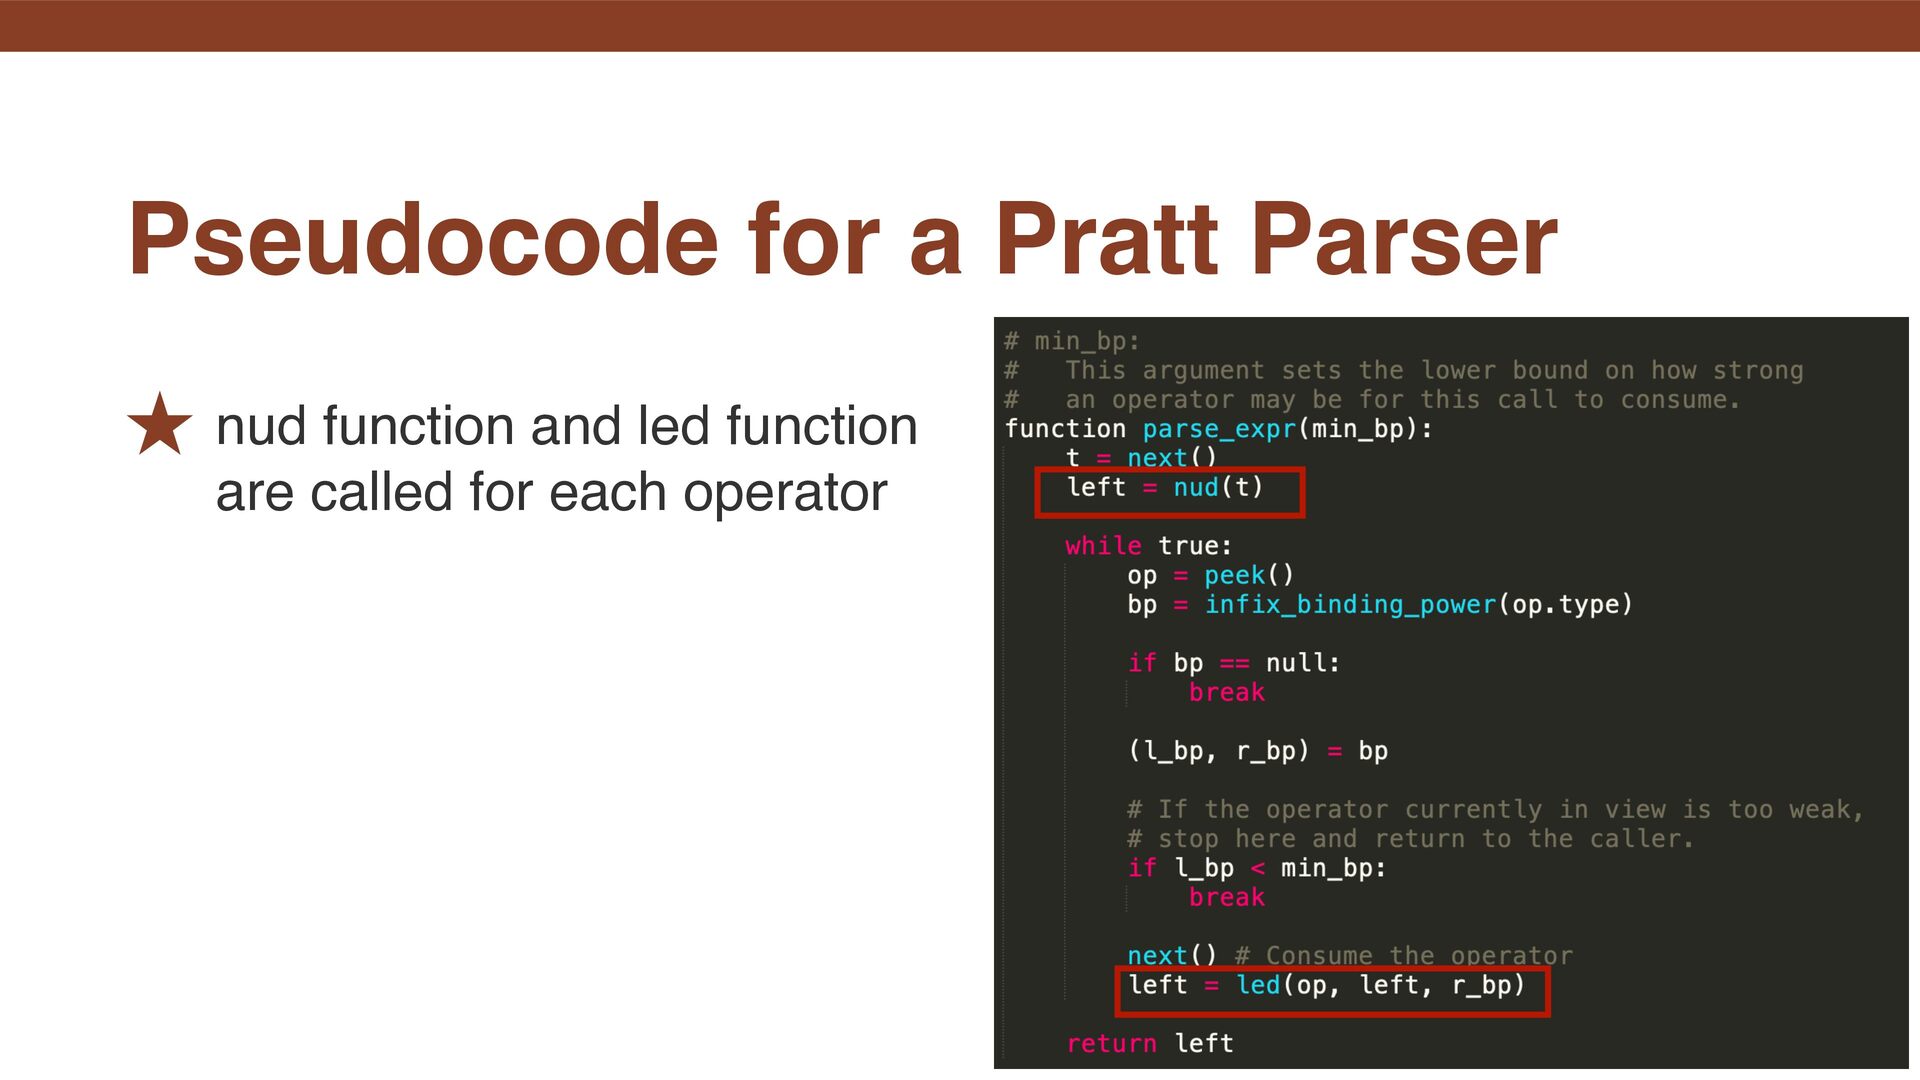
˒ The parser works by looping over comparisons between the
binding power of the current operator and that of the next one. Pseudocode for a Pratt Parser -
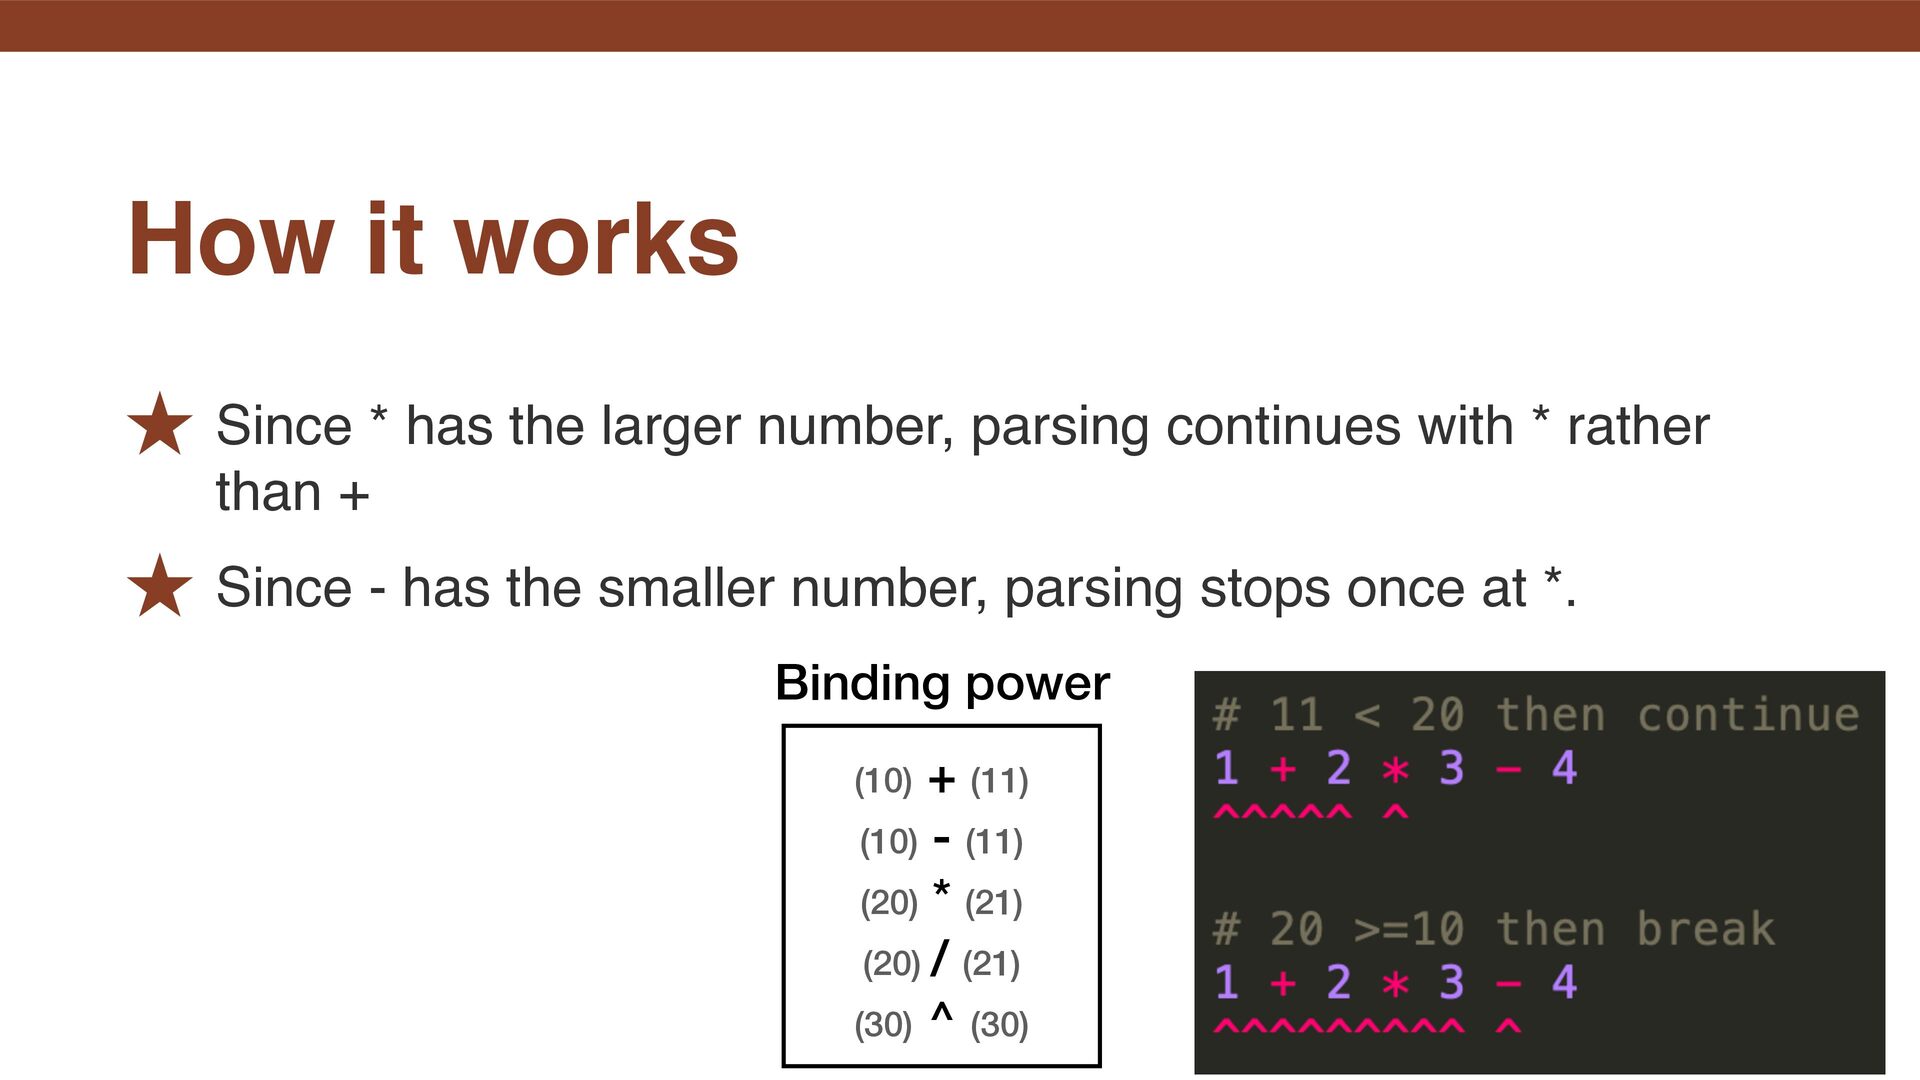
˒ Since * has the larger number, parsing continues with
* rather than + ˒ Since - has the smaller number, parsing stops once at *. How it works (10) + (11) (10) - (11) (20) * (21) (20) / (21) (30) ^ (30) Binding power -
˒ The code denoted by a token ˒ nud: Null
denotation ˒ led: Left denotation ˒ It is something like a semantic action in an LR parser. 2. nud & led -
˒ nud function and led function are called for each
operator Pseudocode for a Pratt Parser -
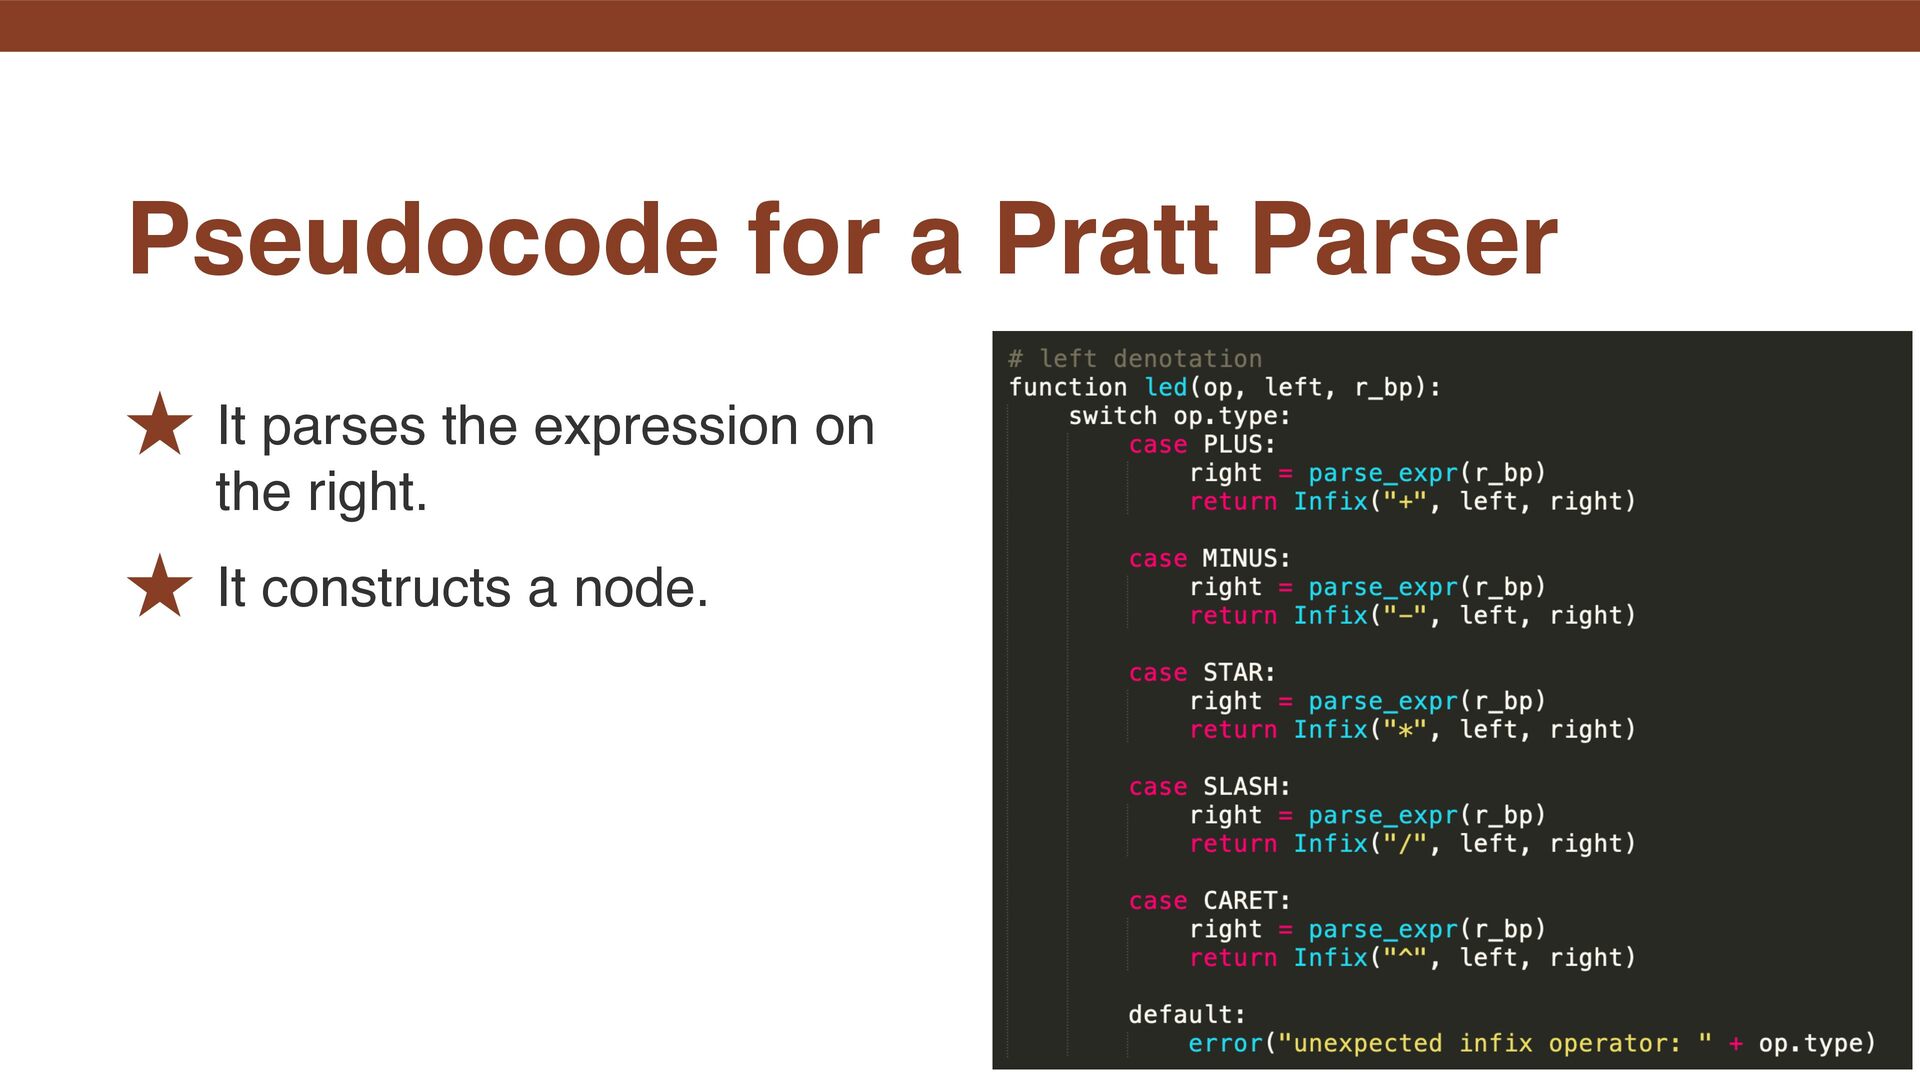
˒ It parses the expression on the right. ˒ It
constructs a node. Pseudocode for a Pratt Parser -
˒ > BNF grammars alone do not deal adequately with
either of these issues … ˒ > writing an LL(k) grammar, and keeping it LL(k) after extending it, seems to be a black art … ˒ > However, this is really a draw-back of BNF; the non-terminals tempt one to try to say everything with just context-free rules … ˒ One thing I can say is that, in the pseudocode, what nud and led receive is a token. 3. Anti-BNF -
˒ The thrill of seeing operators handled so simply ˒
LL parsers require grammar rewriting. ˒ LR parsers are not as simple as Pratt parsers, either. ˒ There was the confusion—or perhaps unease—of not using BNF at all. Excitement and Unease -
˒ token_begins_expression_p function ˒ parse_expression_terminator function ˒ Something that looks
like a nonterminal Three Points to Clarify -
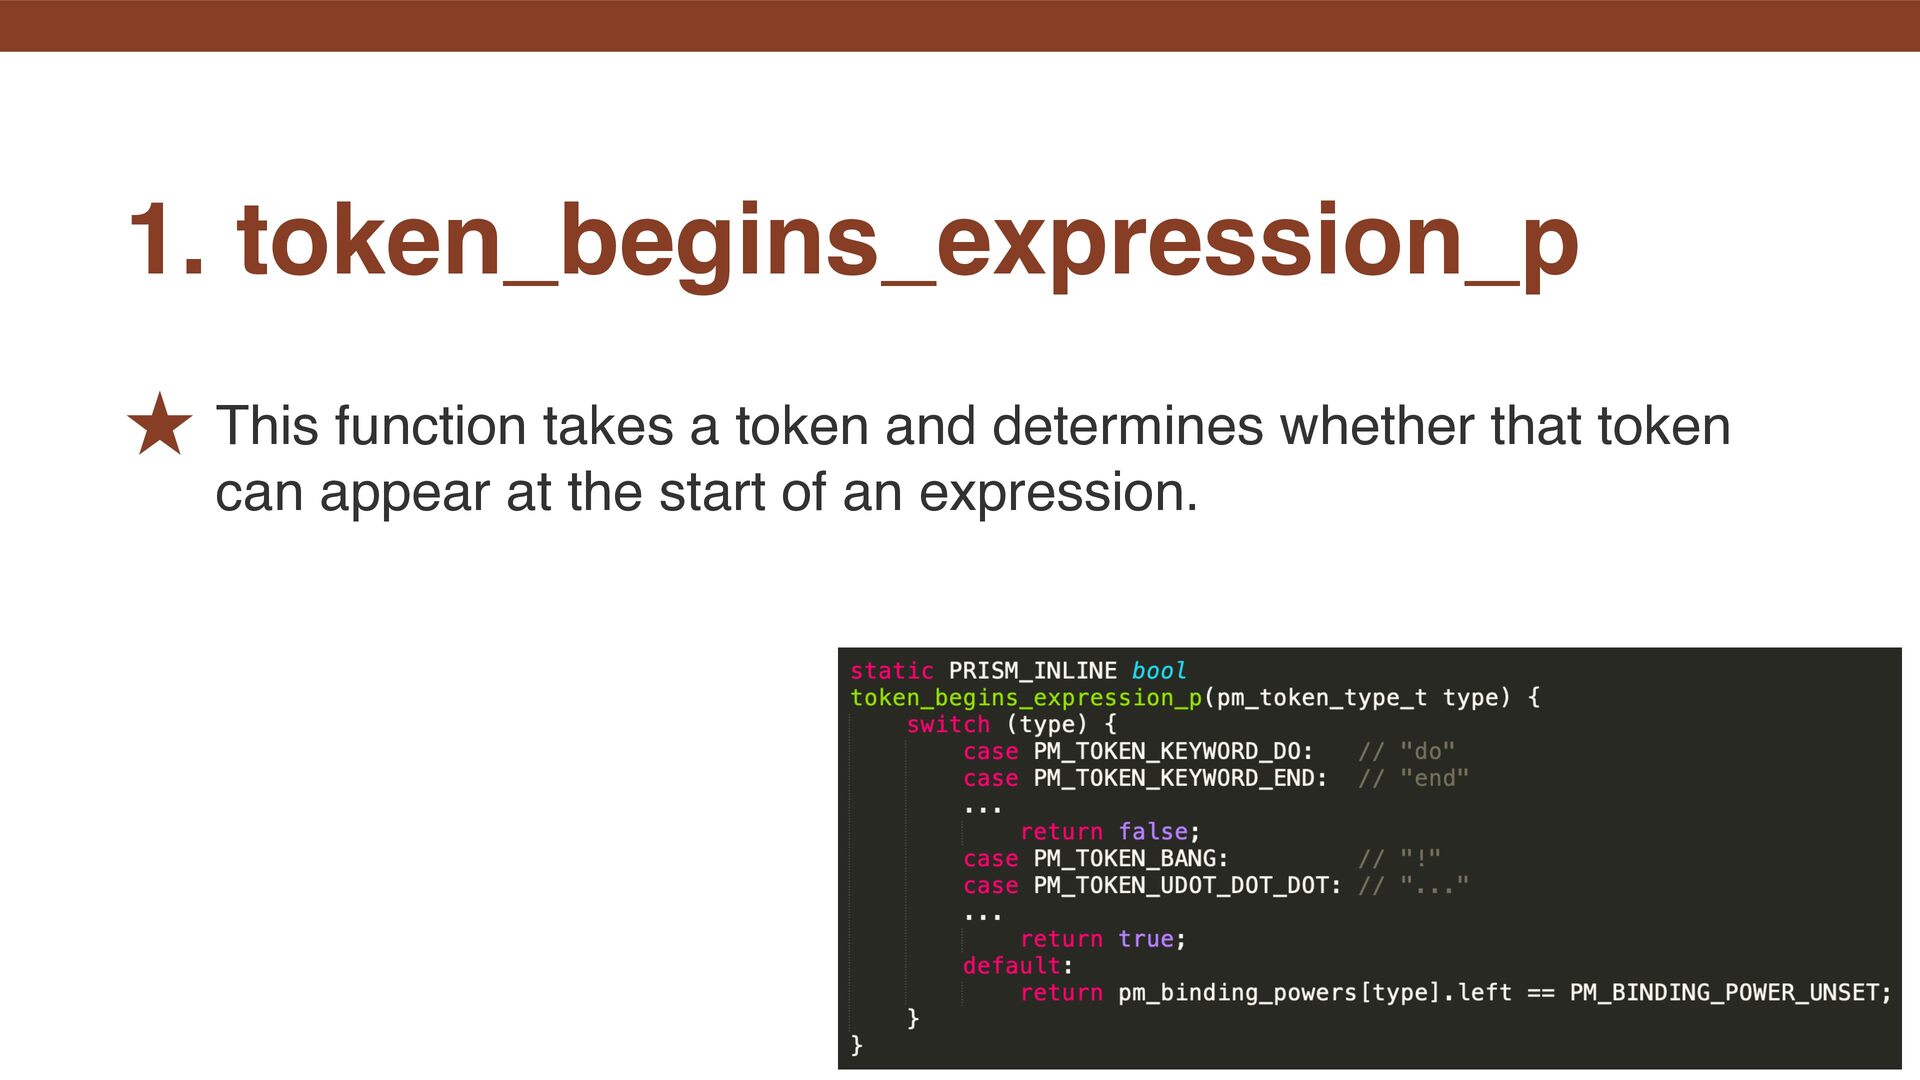
˒ This function takes a token and determines whether that
token can appear at the start of an expression. 1. token_begins_expression_p -
˒ We will not discuss here what “expression” means in
Ruby. ˒ Normally, statements represent actions, while expressions yield values—but in Ruby, even actions have values. ˒ In parse.y terms, an expr is not an arg, so it cannot be used as an argument, but it is still a smaller unit than a stmt—though that is probably not worth getting into here. Note: What is the “expression”? -
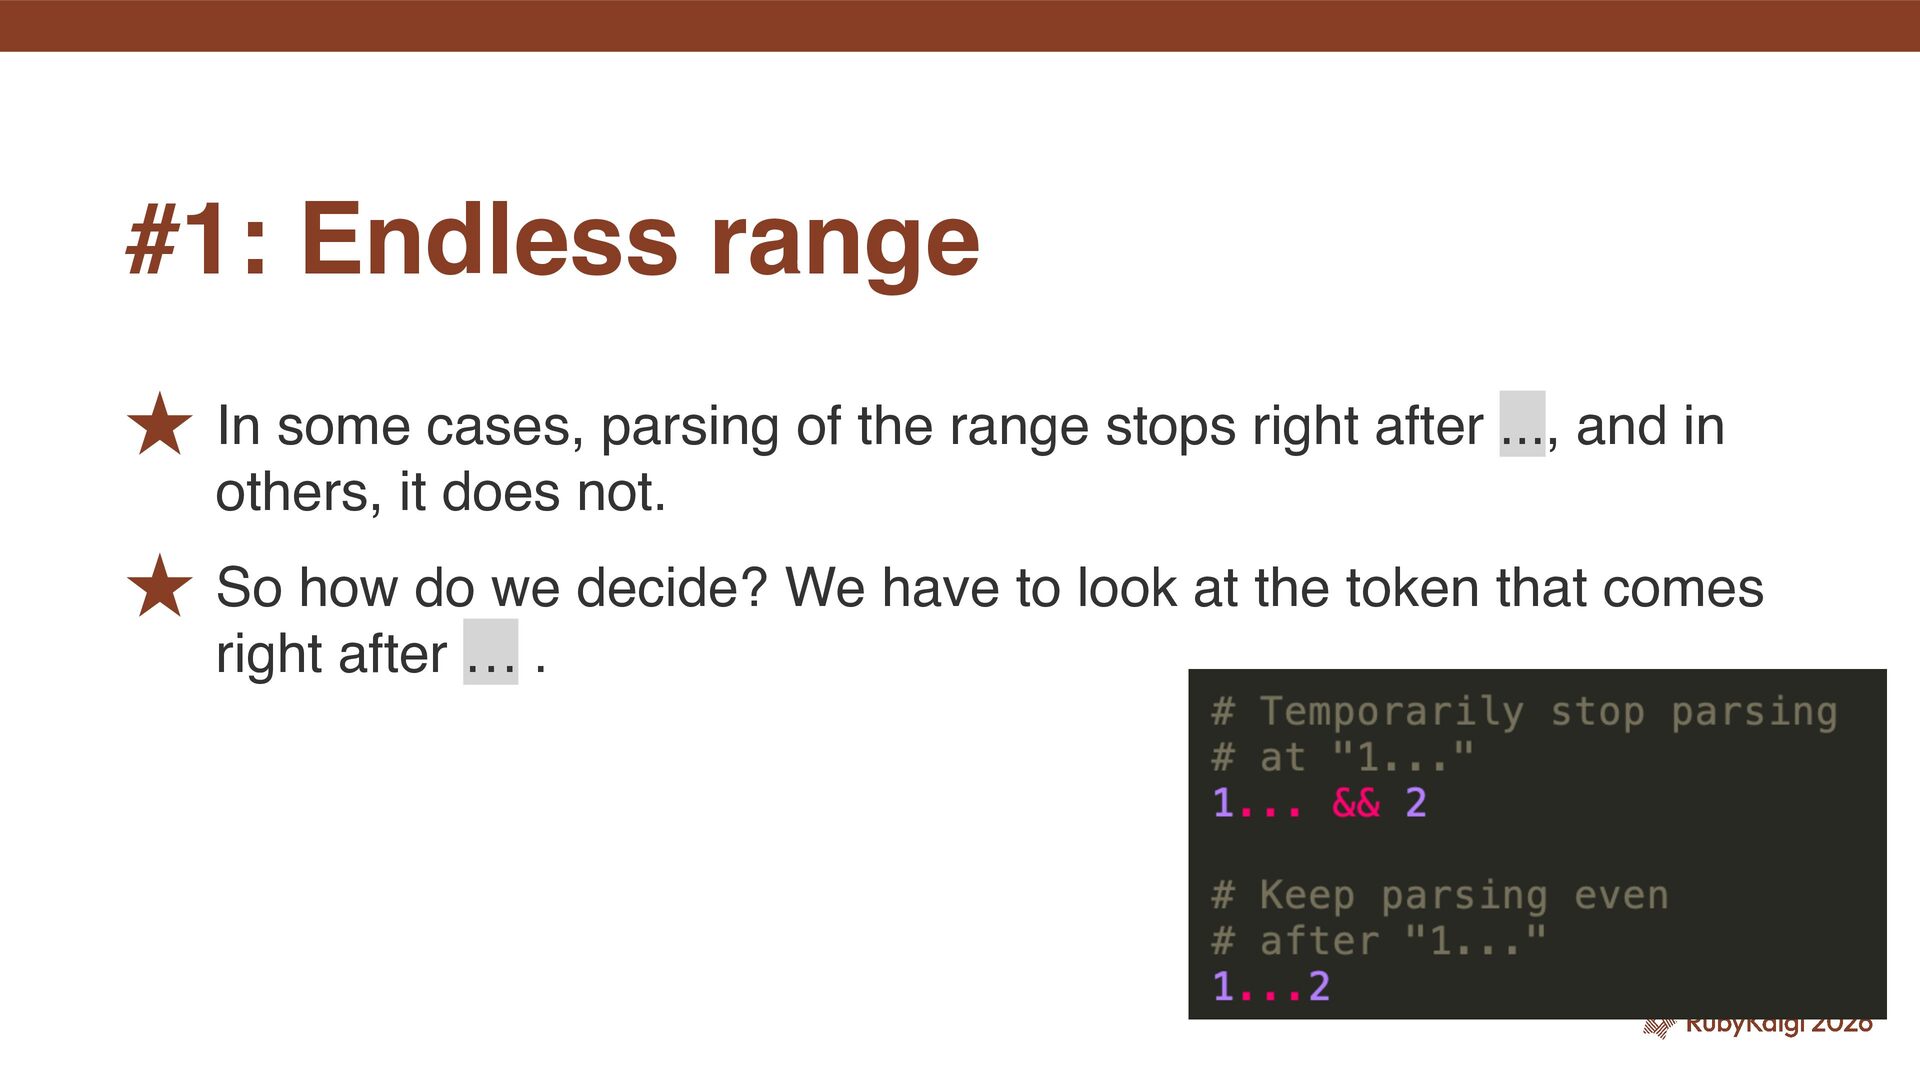
˒ In some cases, parsing of the range stops right
after ..., and in others, it does not. ˒ So how do we decide? We have to look at the token that comes right after … . #1: Endless range -
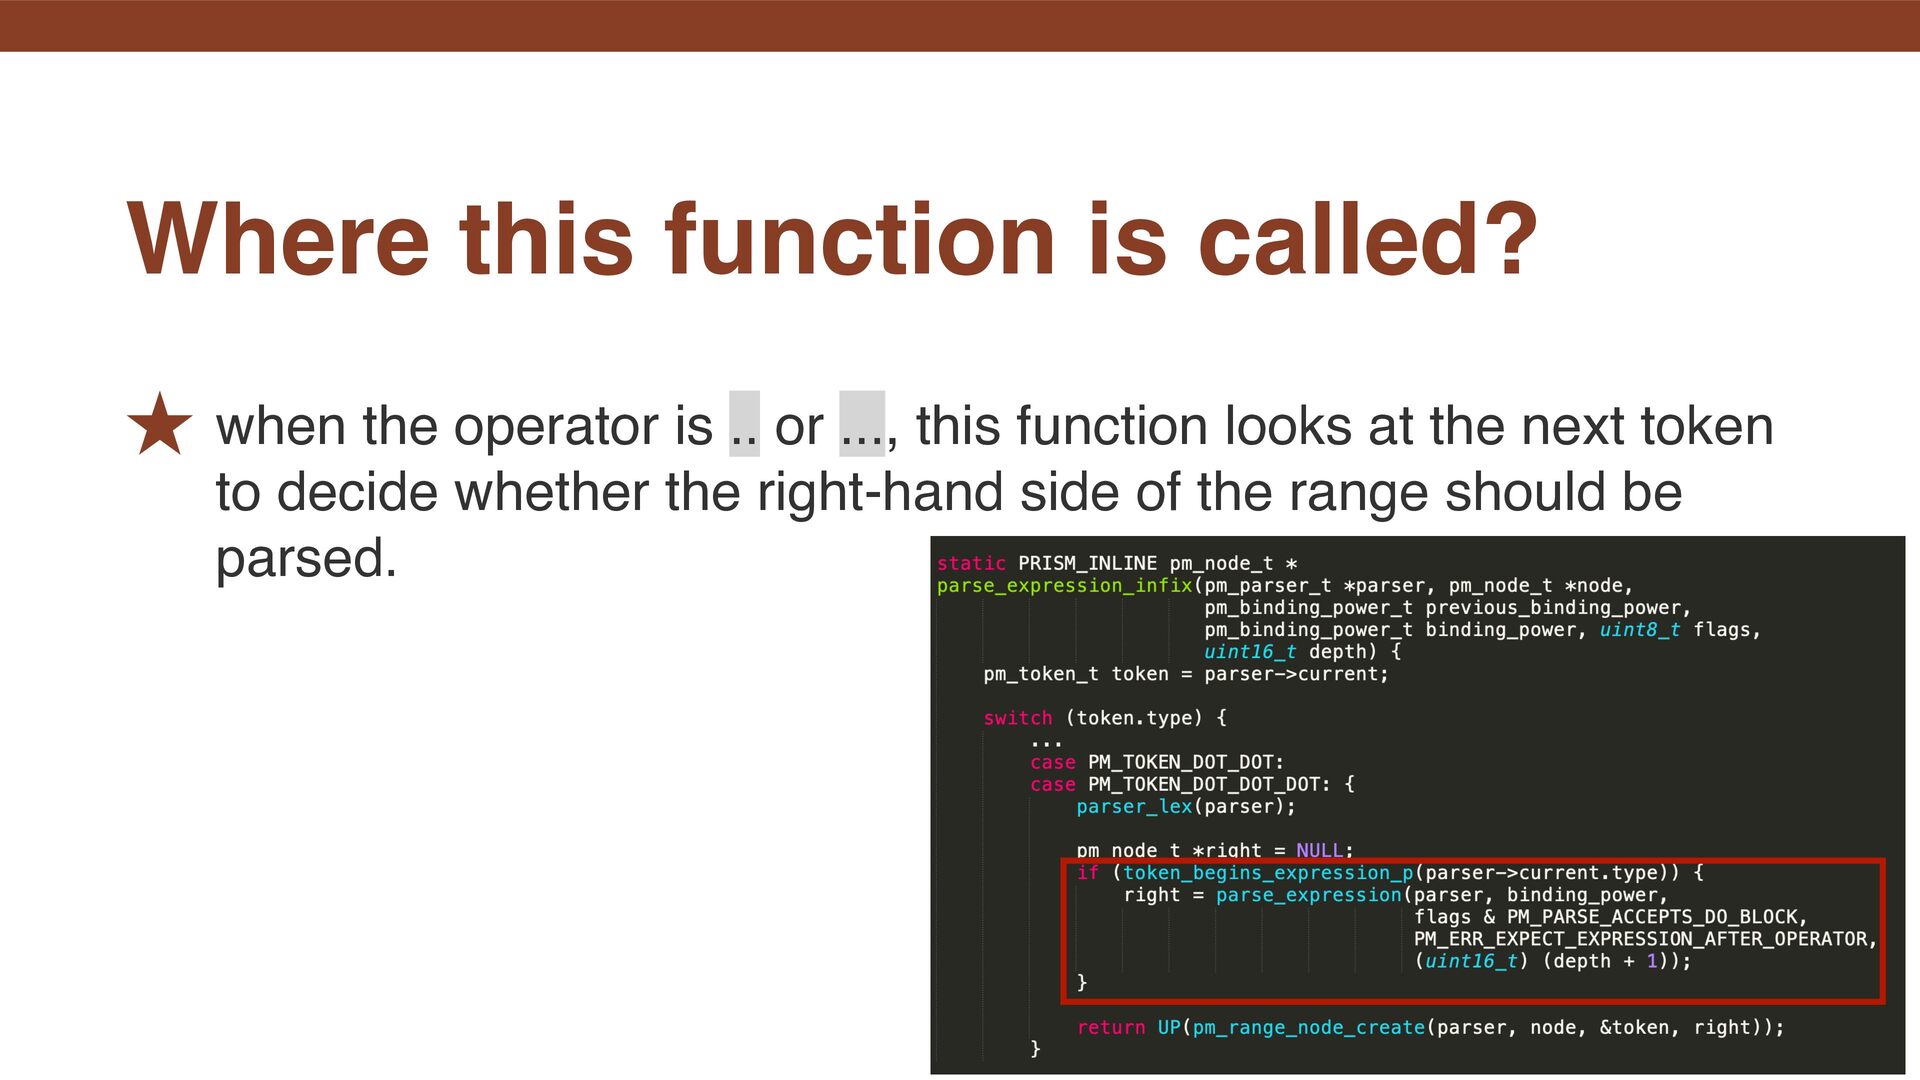
˒ when the operator is .. or ..., this function
looks at the next token to decide whether the right-hand side of the range should be parsed. Where this function is called? -
˒ How is token_begins_expression_p function itself implemented? ˒ Fortunately, the
number of token types is fi nite, so each one can be checked individually. By the way -
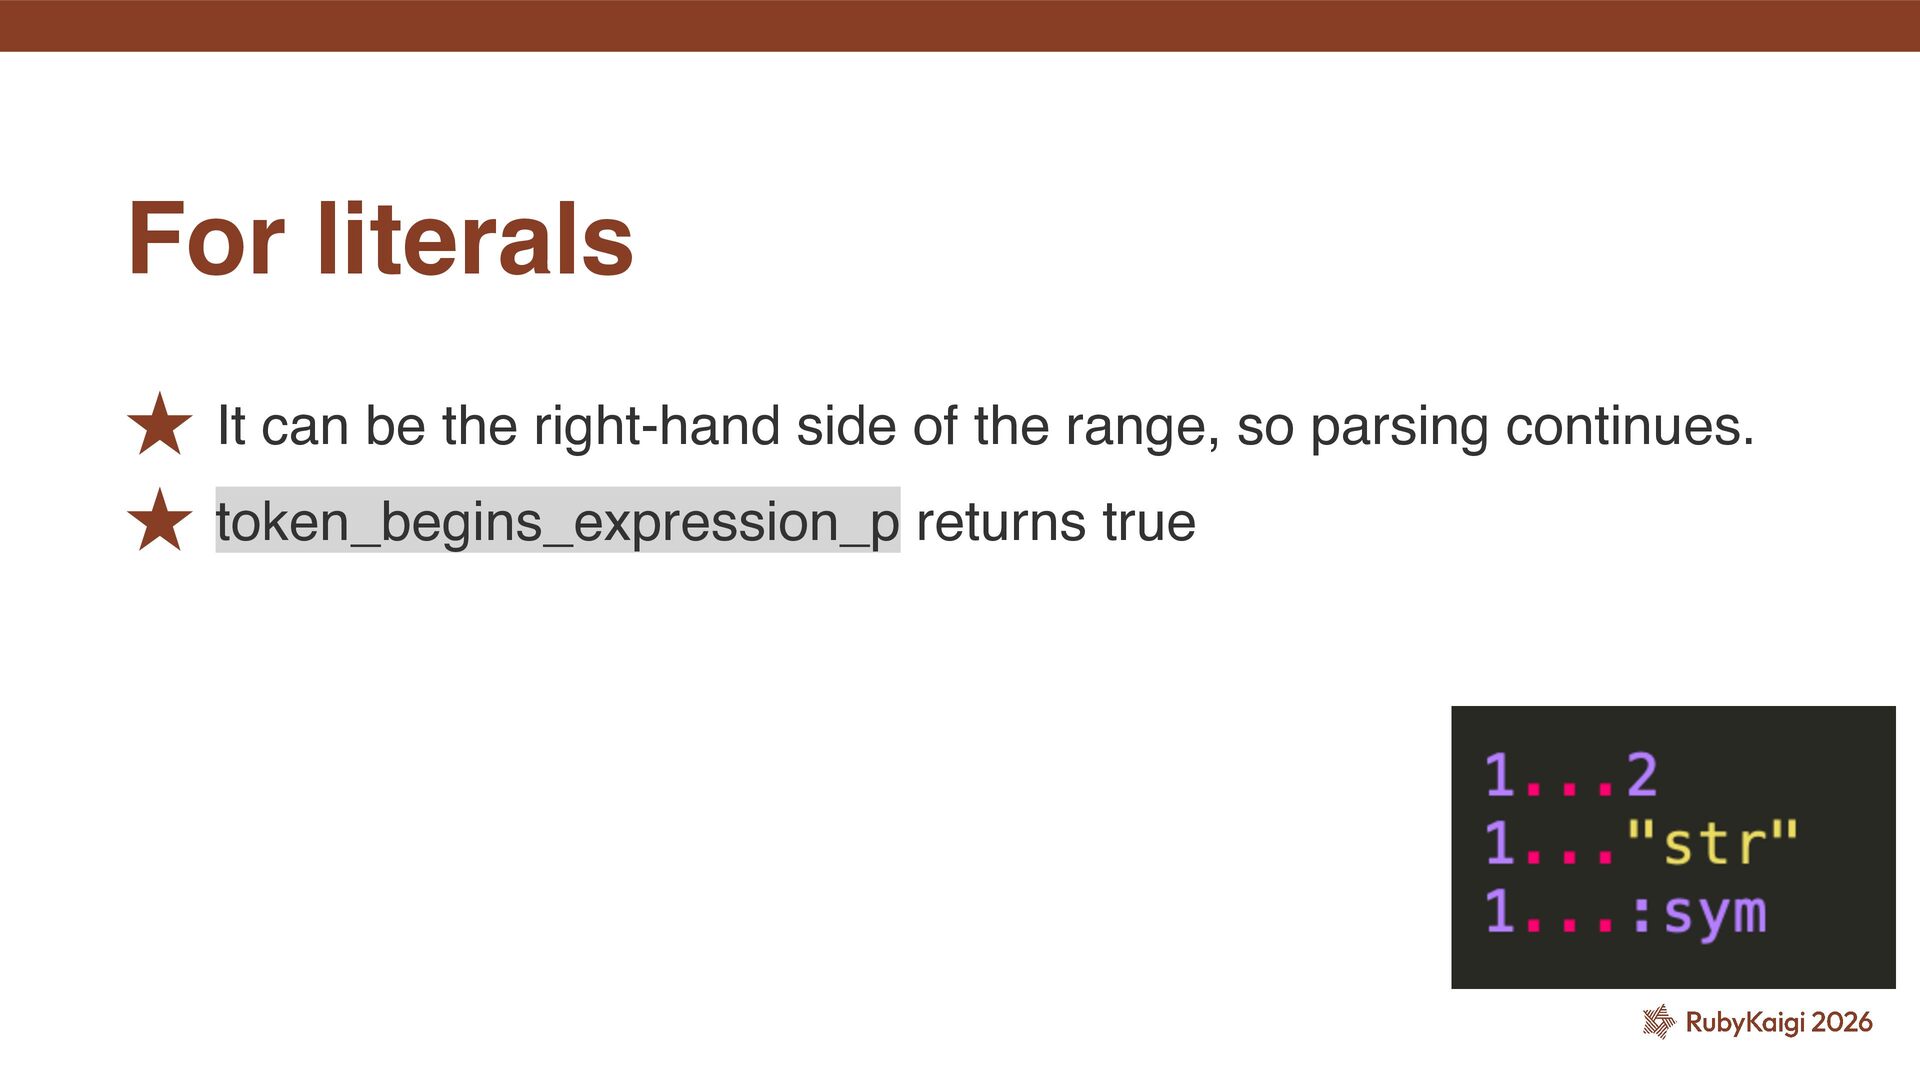
˒ It can be the right-hand side of the range,
so parsing continues. ˒ token_begins_expression_p returns true For literals -
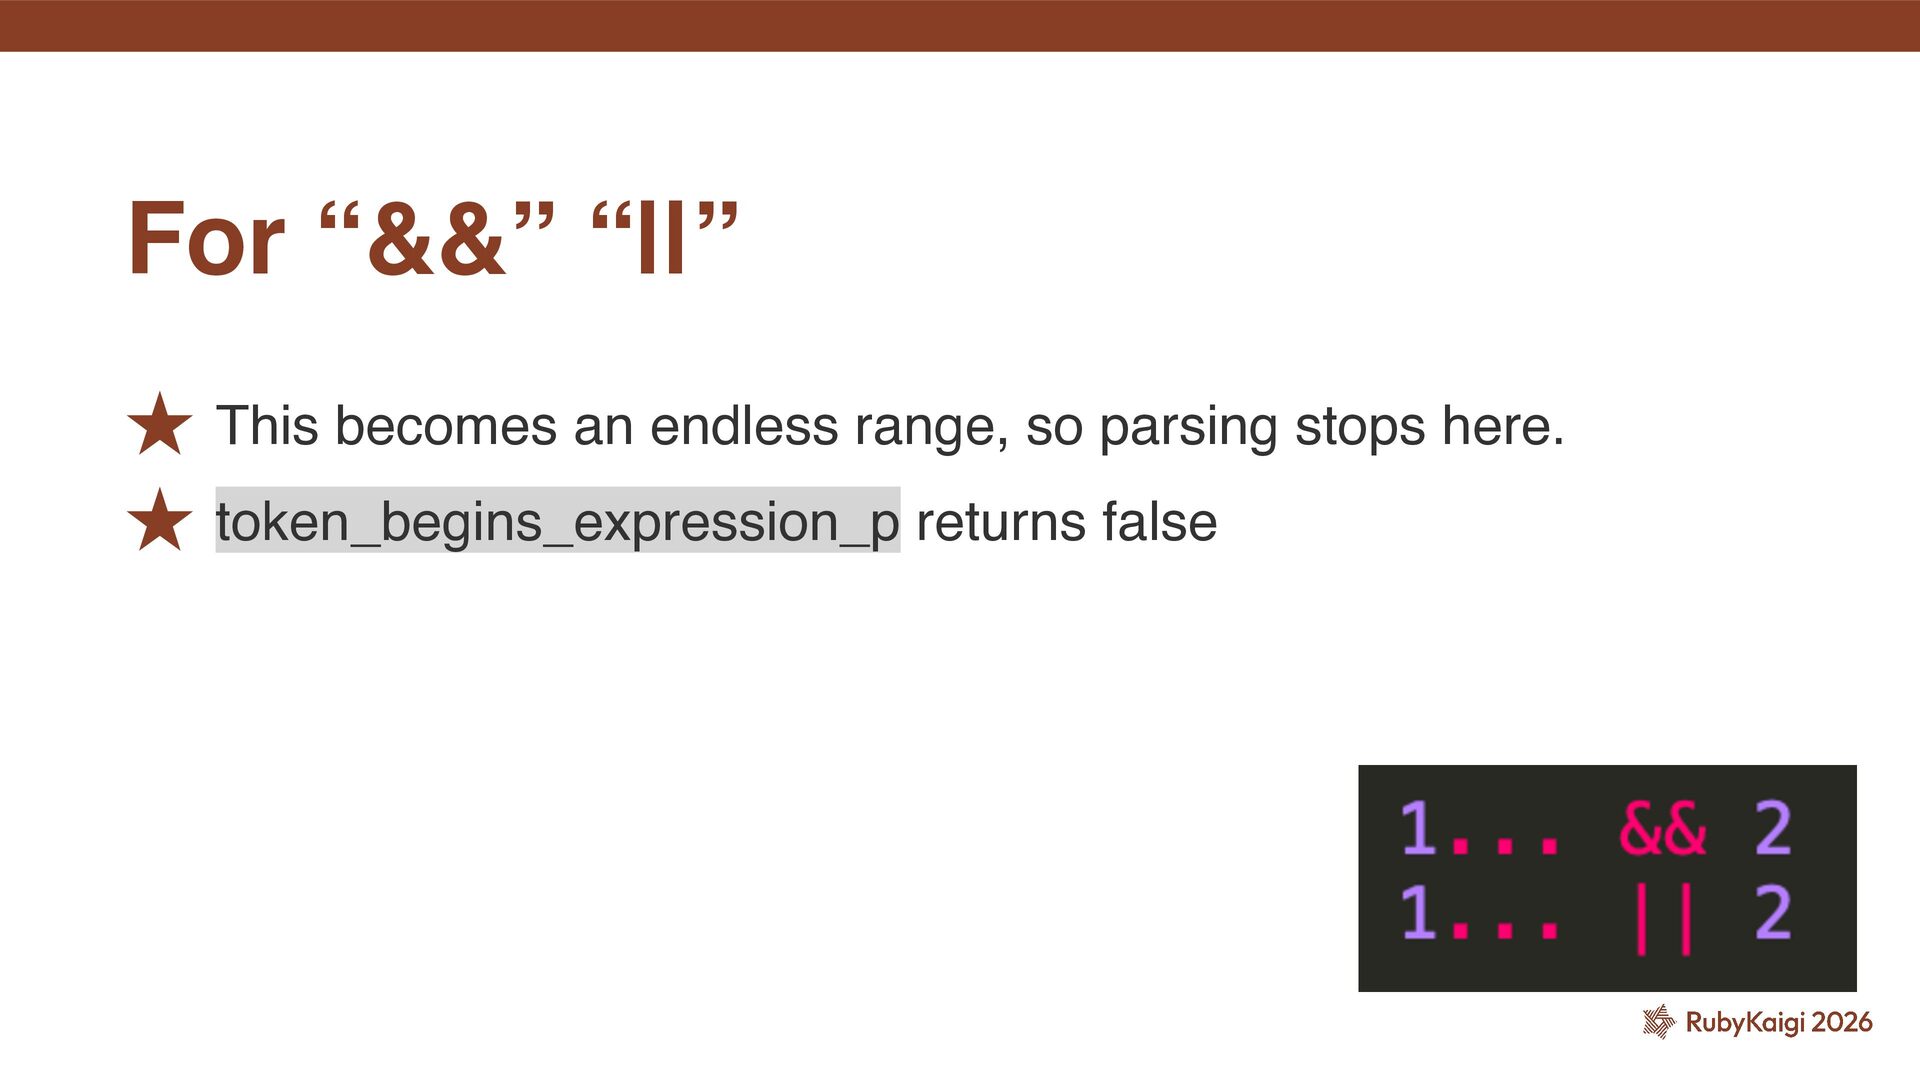
˒ This becomes an endless range, so parsing stops here.
˒ token_begins_expression_p returns false For “&&” “||” -
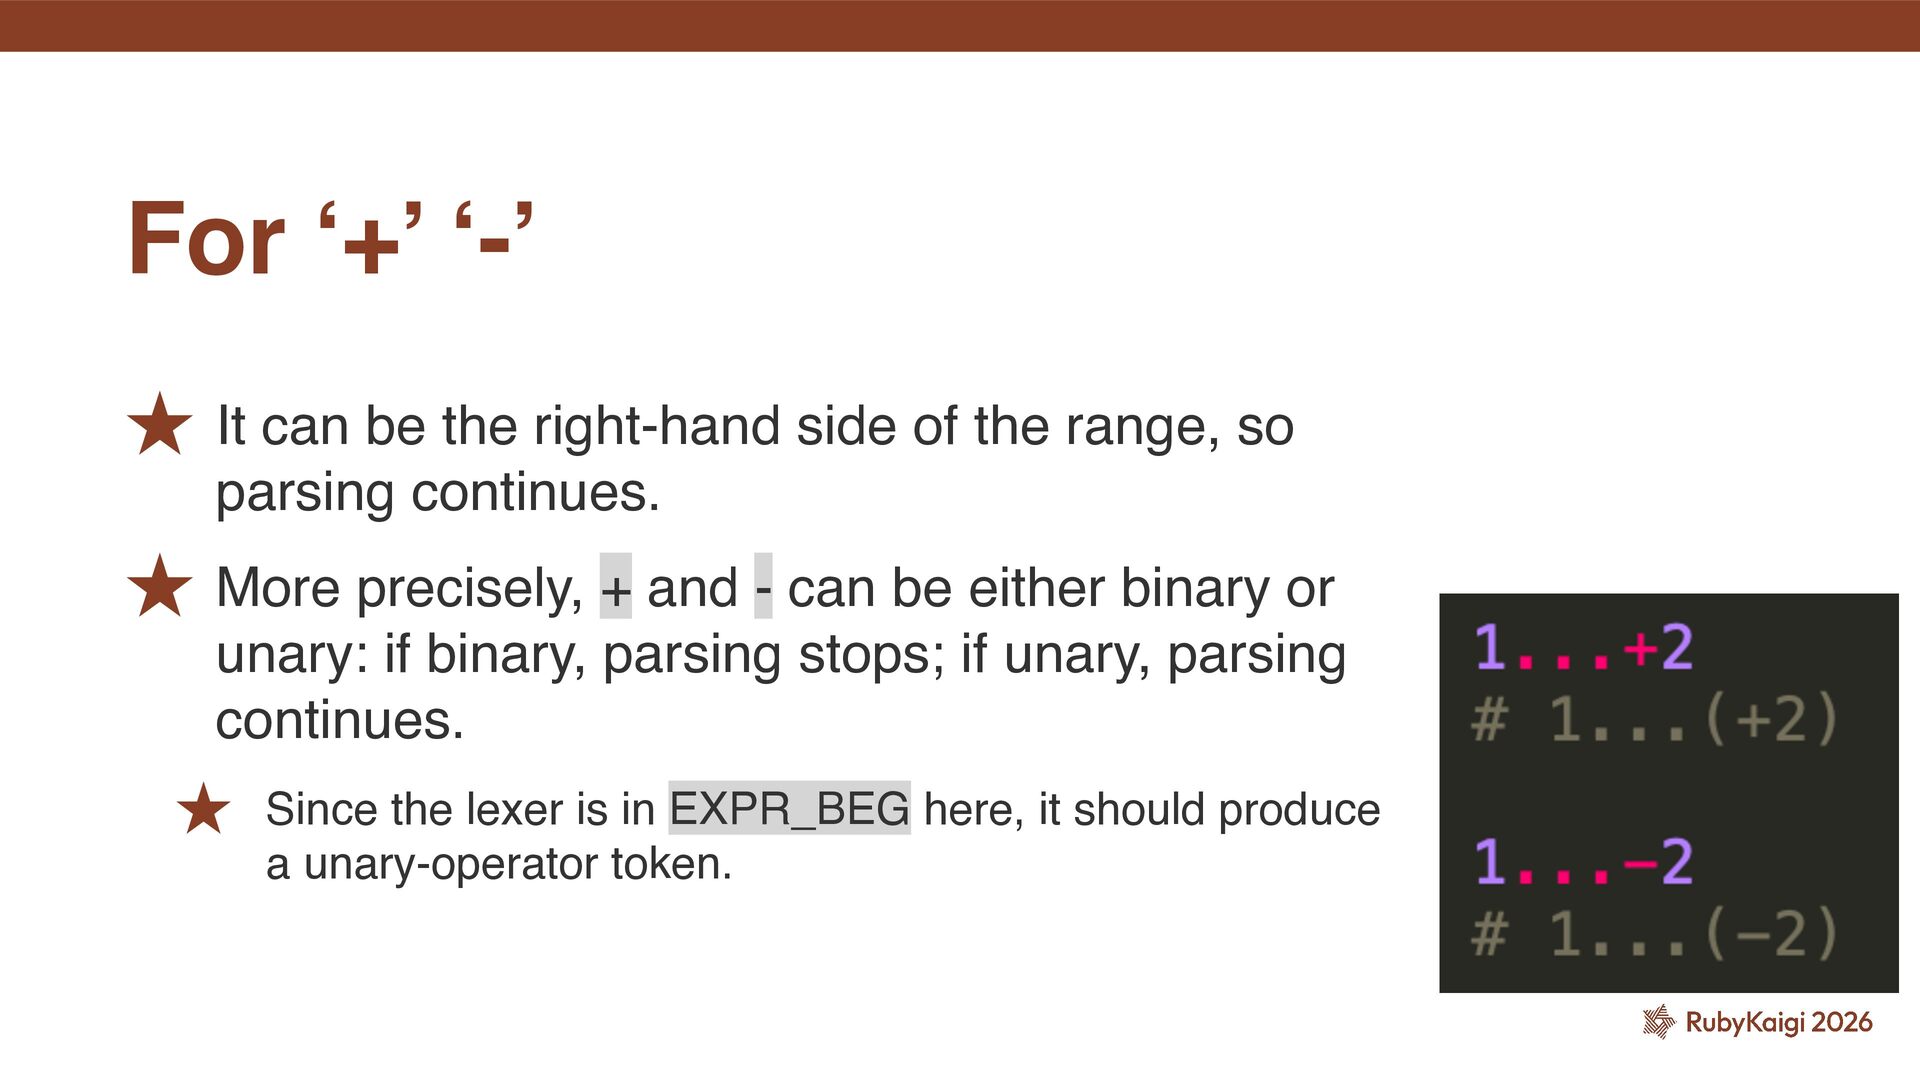
˒ It can be the right-hand side of the range,
so parsing continues. ˒ More precisely, + and - can be either binary or unary: if binary, parsing stops; if unary, parsing continues. ˒ Since the lexer is in EXPR_BEG here, it should produce a unary-operator token. For ‘+’ ‘-’ -
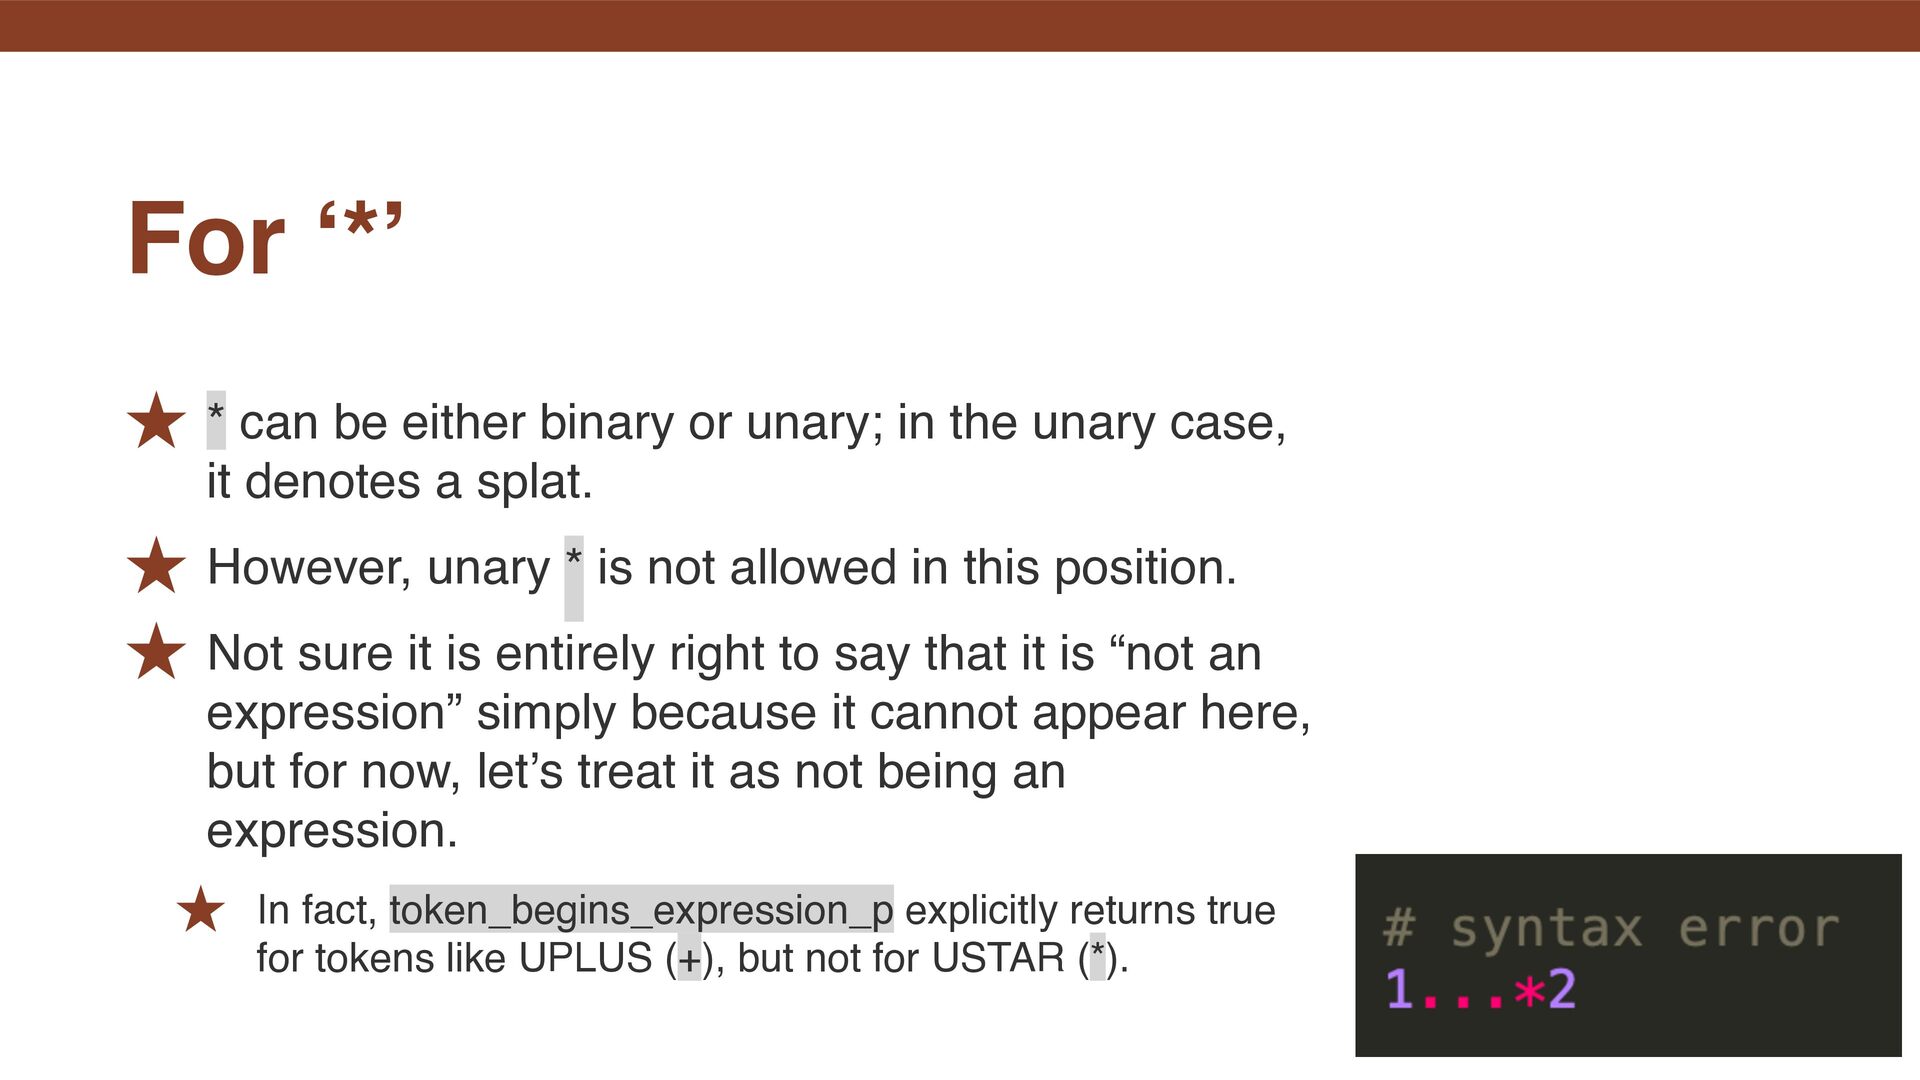
˒ * can be either binary or unary; in the
unary case, it denotes a splat. ˒ However, unary * is not allowed in this position. ˒ Not sure it is entirely right to say that it is “not an expression” simply because it cannot appear here, but for now, let’s treat it as not being an expression. ˒ In fact, token_begins_expression_p explicitly returns true for tokens like UPLUS (+), but not for USTAR (*). For ‘*’ -
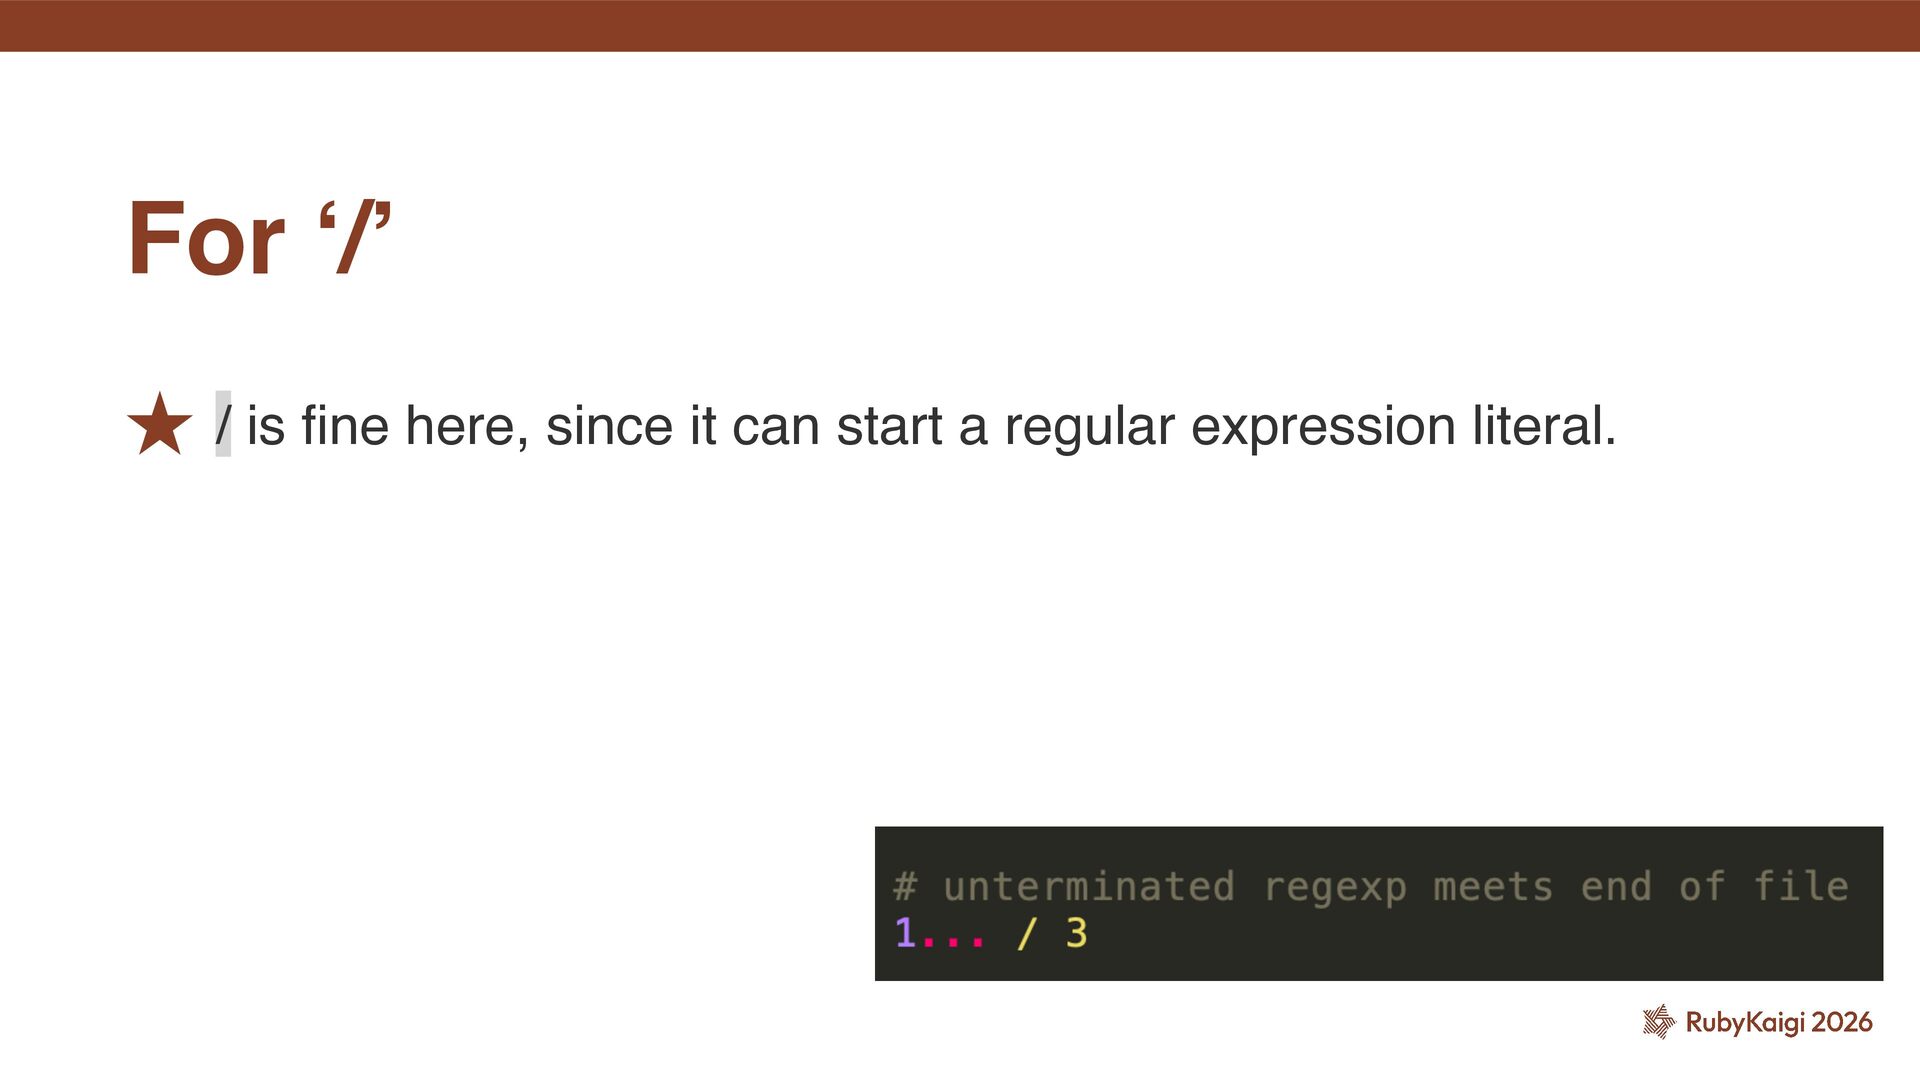
˒ / is fi ne here, since it can start
a regular expression literal. For ‘/’ -
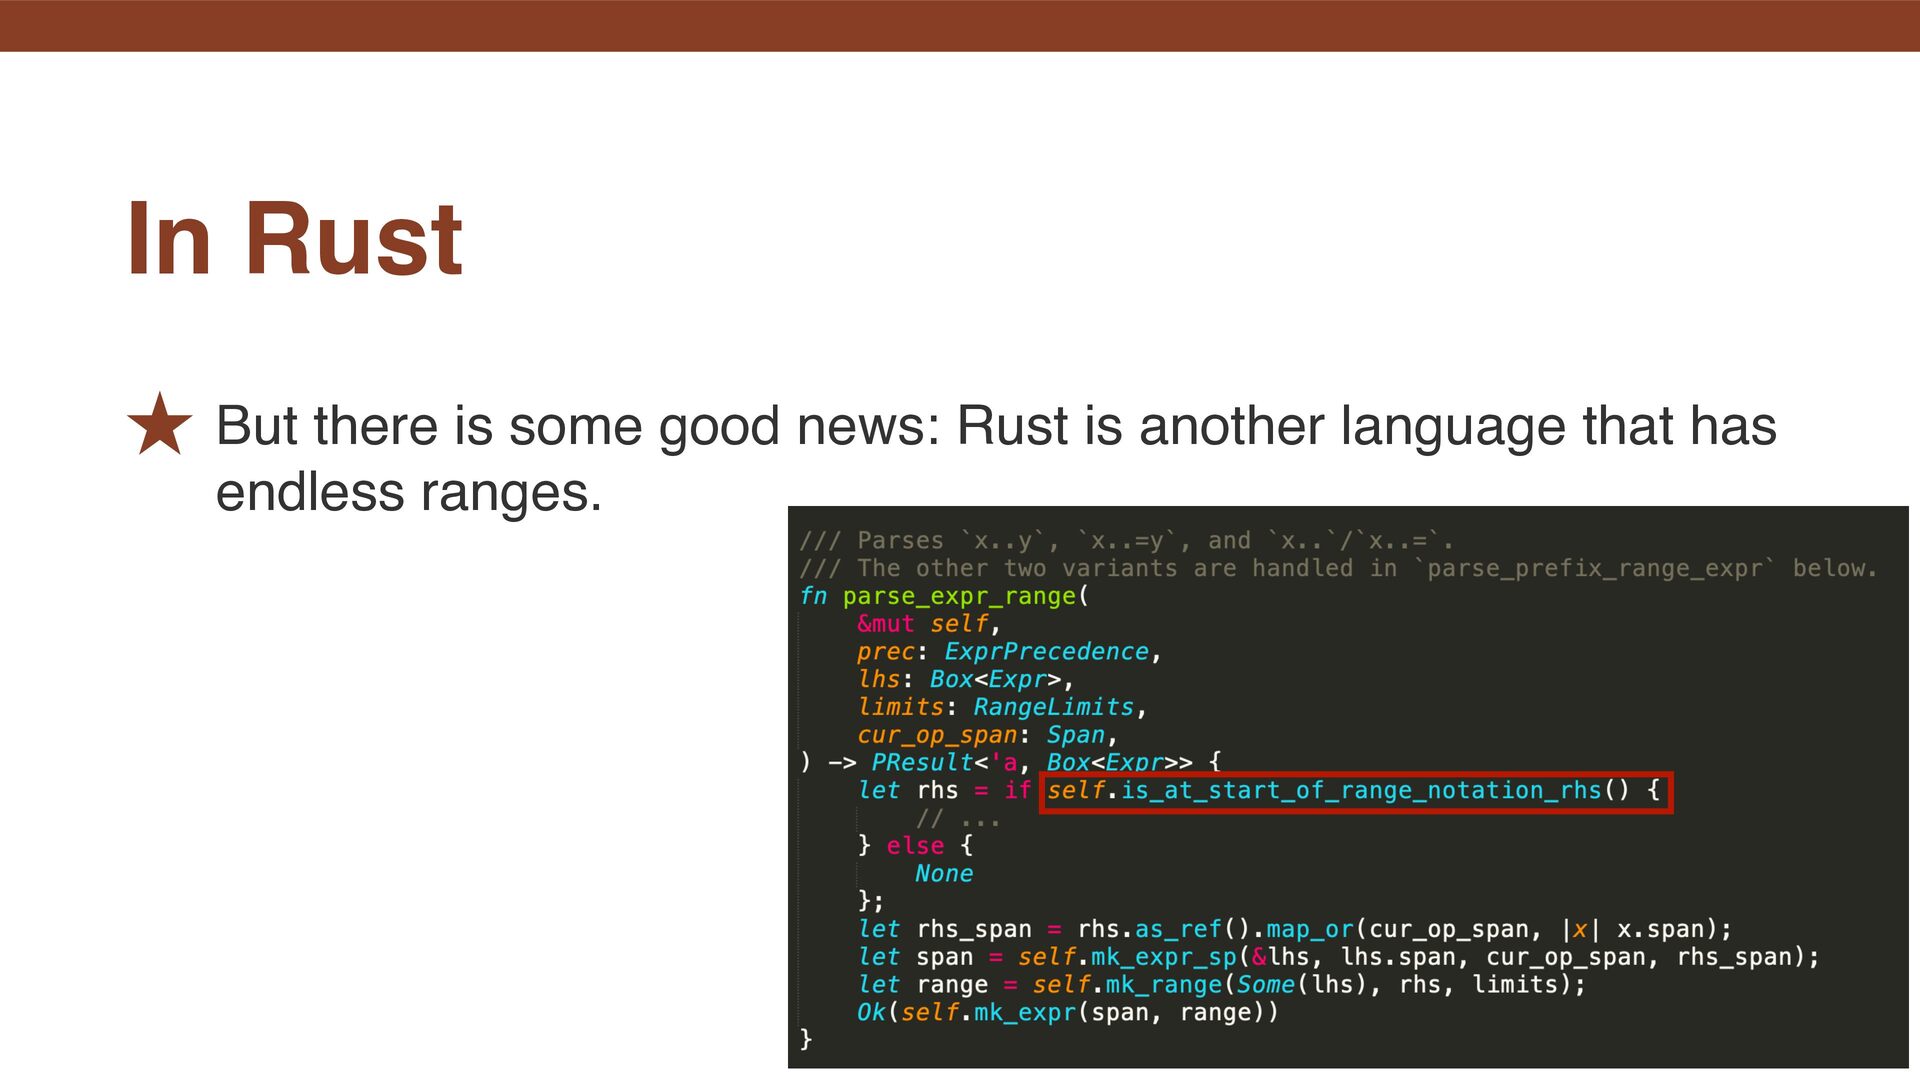
˒ But there is some good news: Rust is another
language that has endless ranges. In Rust -
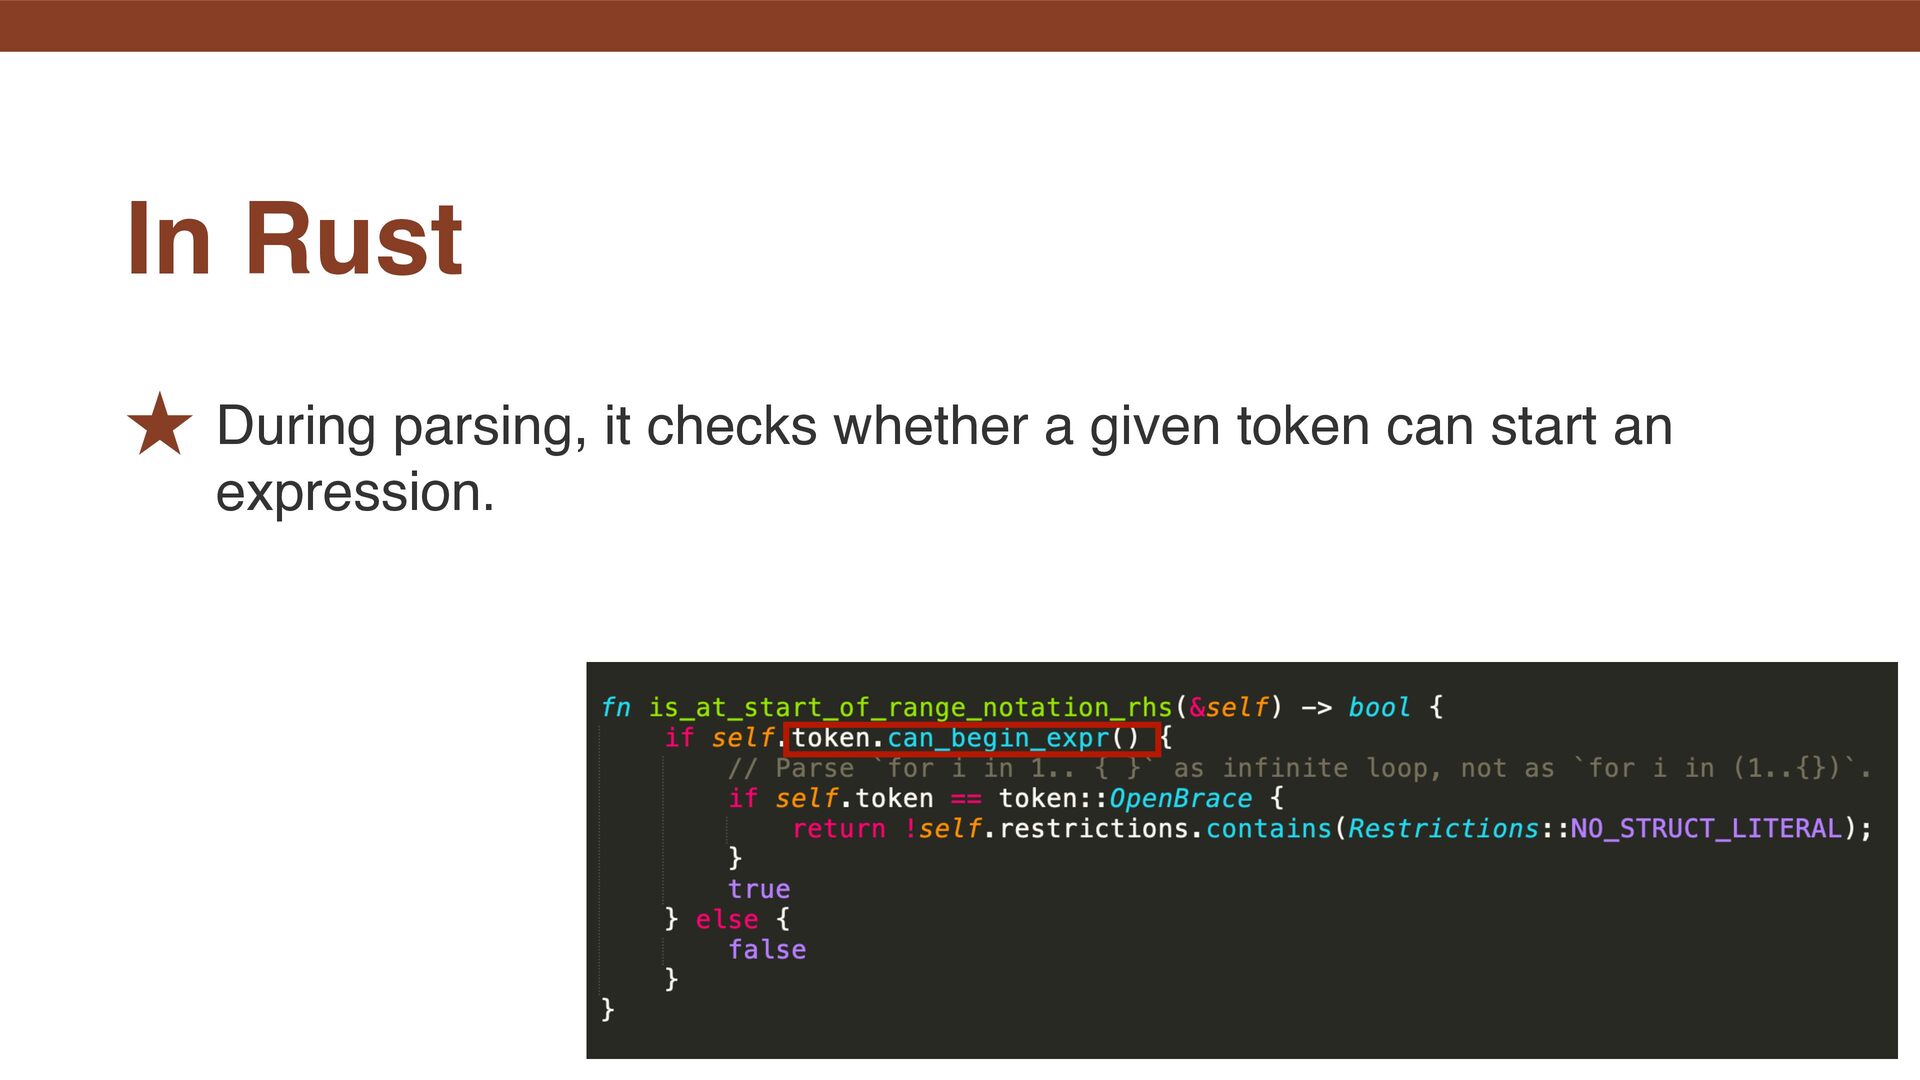
˒ During parsing, it checks whether a given token can
start an expression. In Rust -
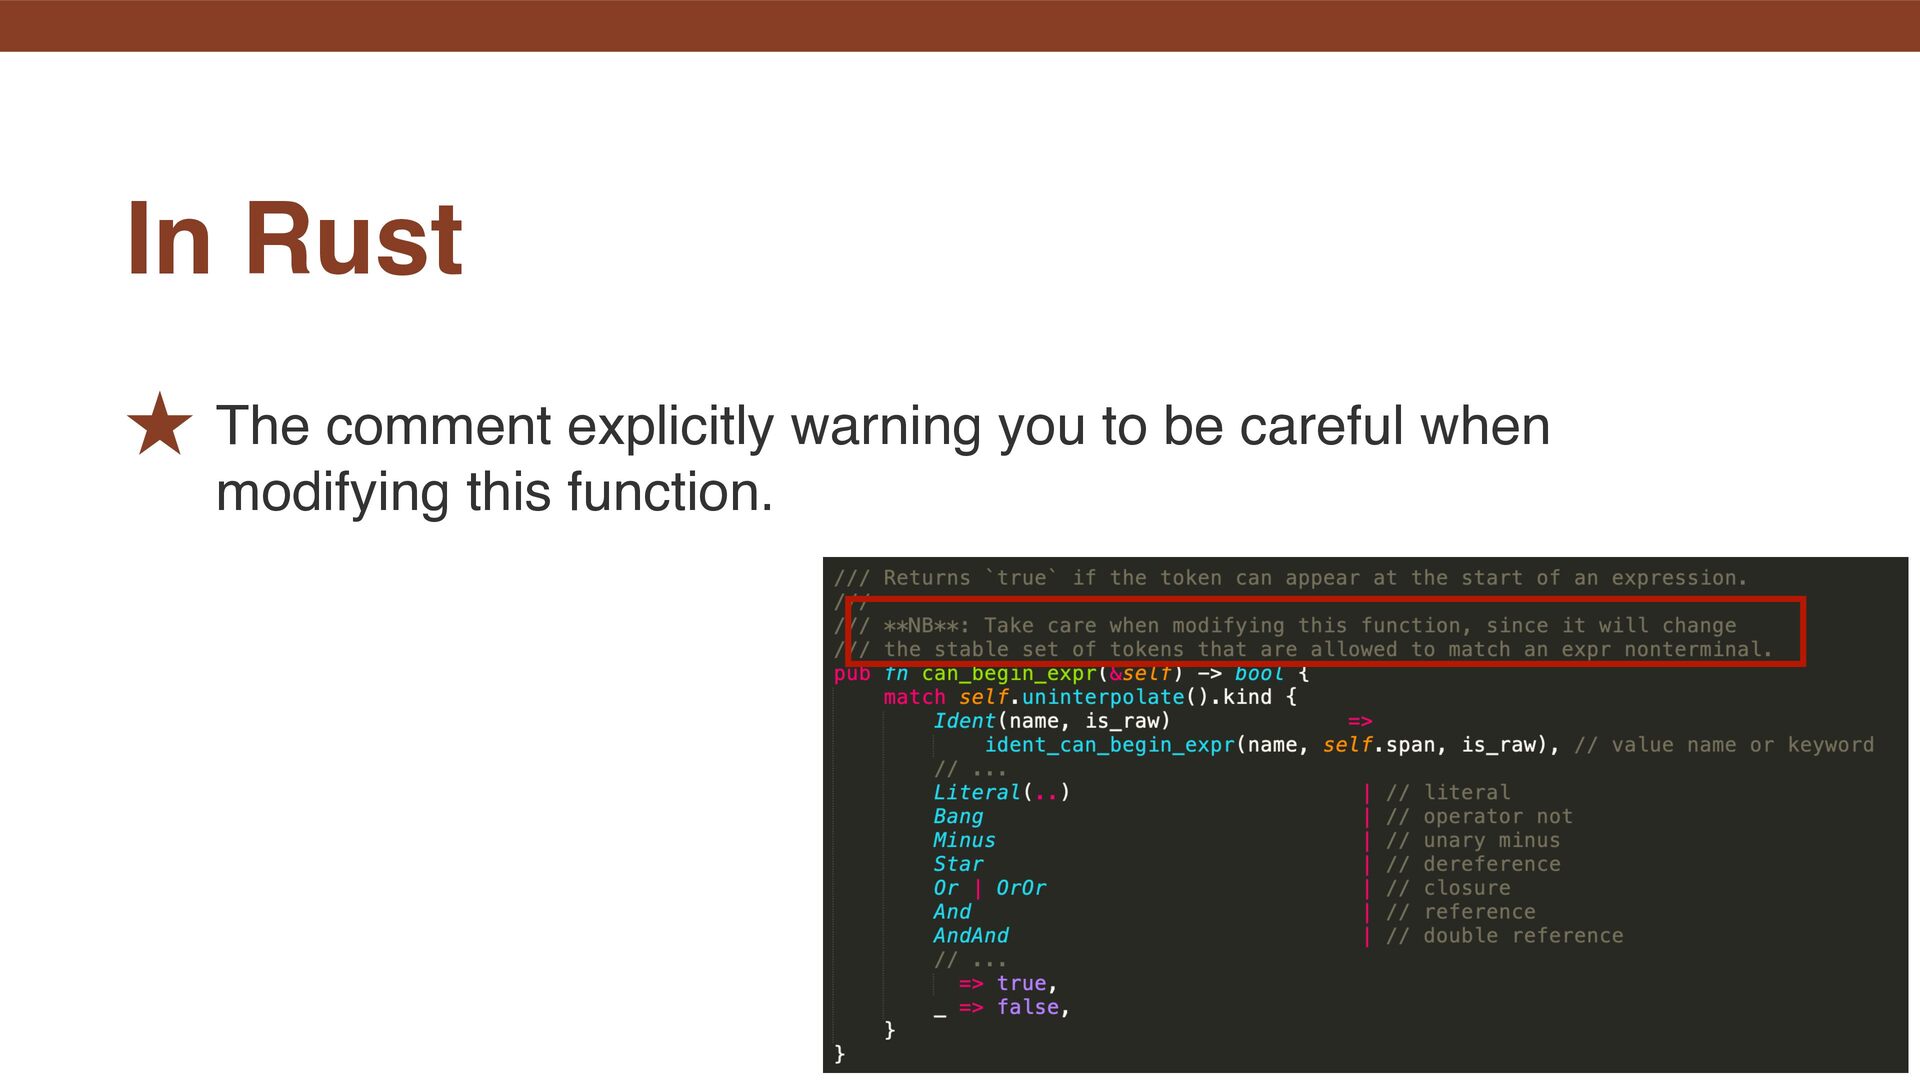
˒ The comment explicitly warning you to be careful when
modifying this function. In Rust -
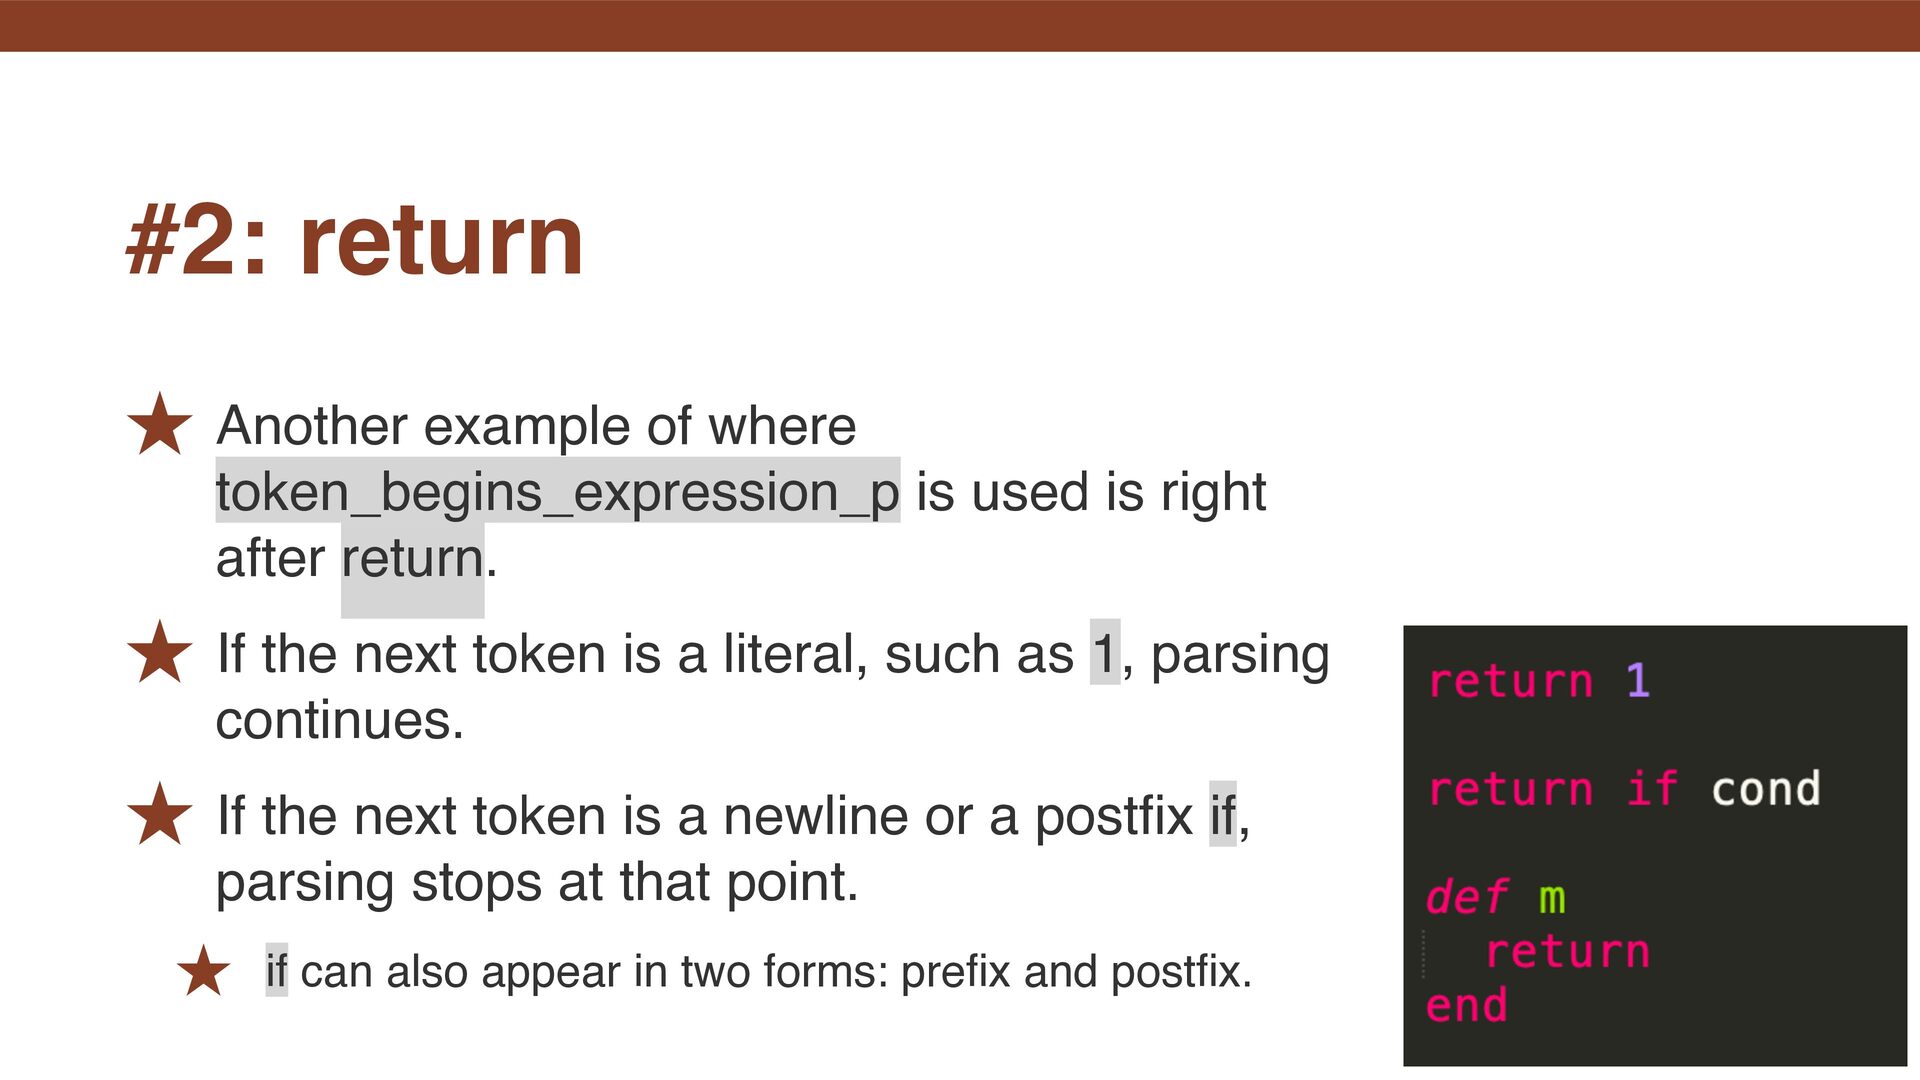
˒ Another example of where token_begins_expression_p is used is right
after return. ˒ If the next token is a literal, such as 1, parsing continues. ˒ If the next token is a newline or a post fi x if, parsing stops at that point. ˒ if can also appear in two forms: pre fi x and post fi x. #2: return -
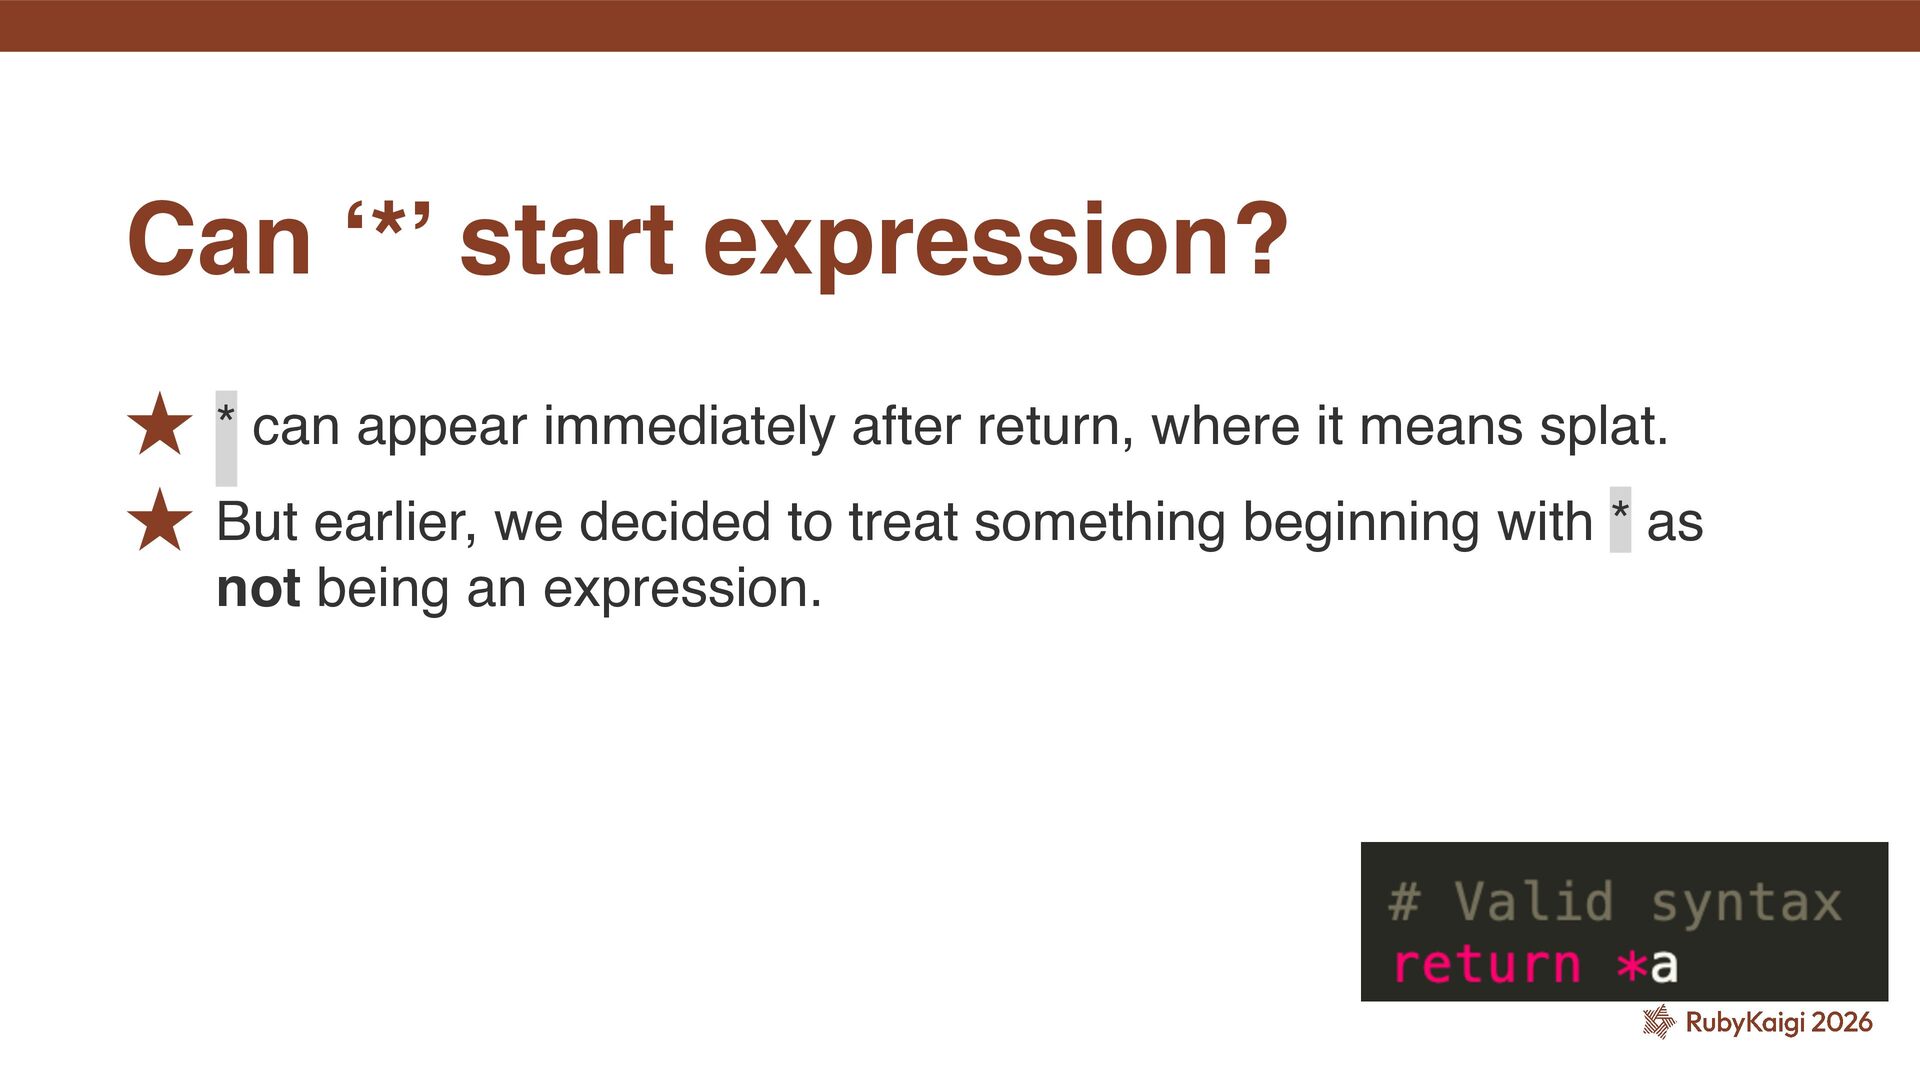
˒ * can appear immediately after return, where it means
splat. ˒ But earlier, we decided to treat something beginning with * as not being an expression. Can ‘*’ start expression? -
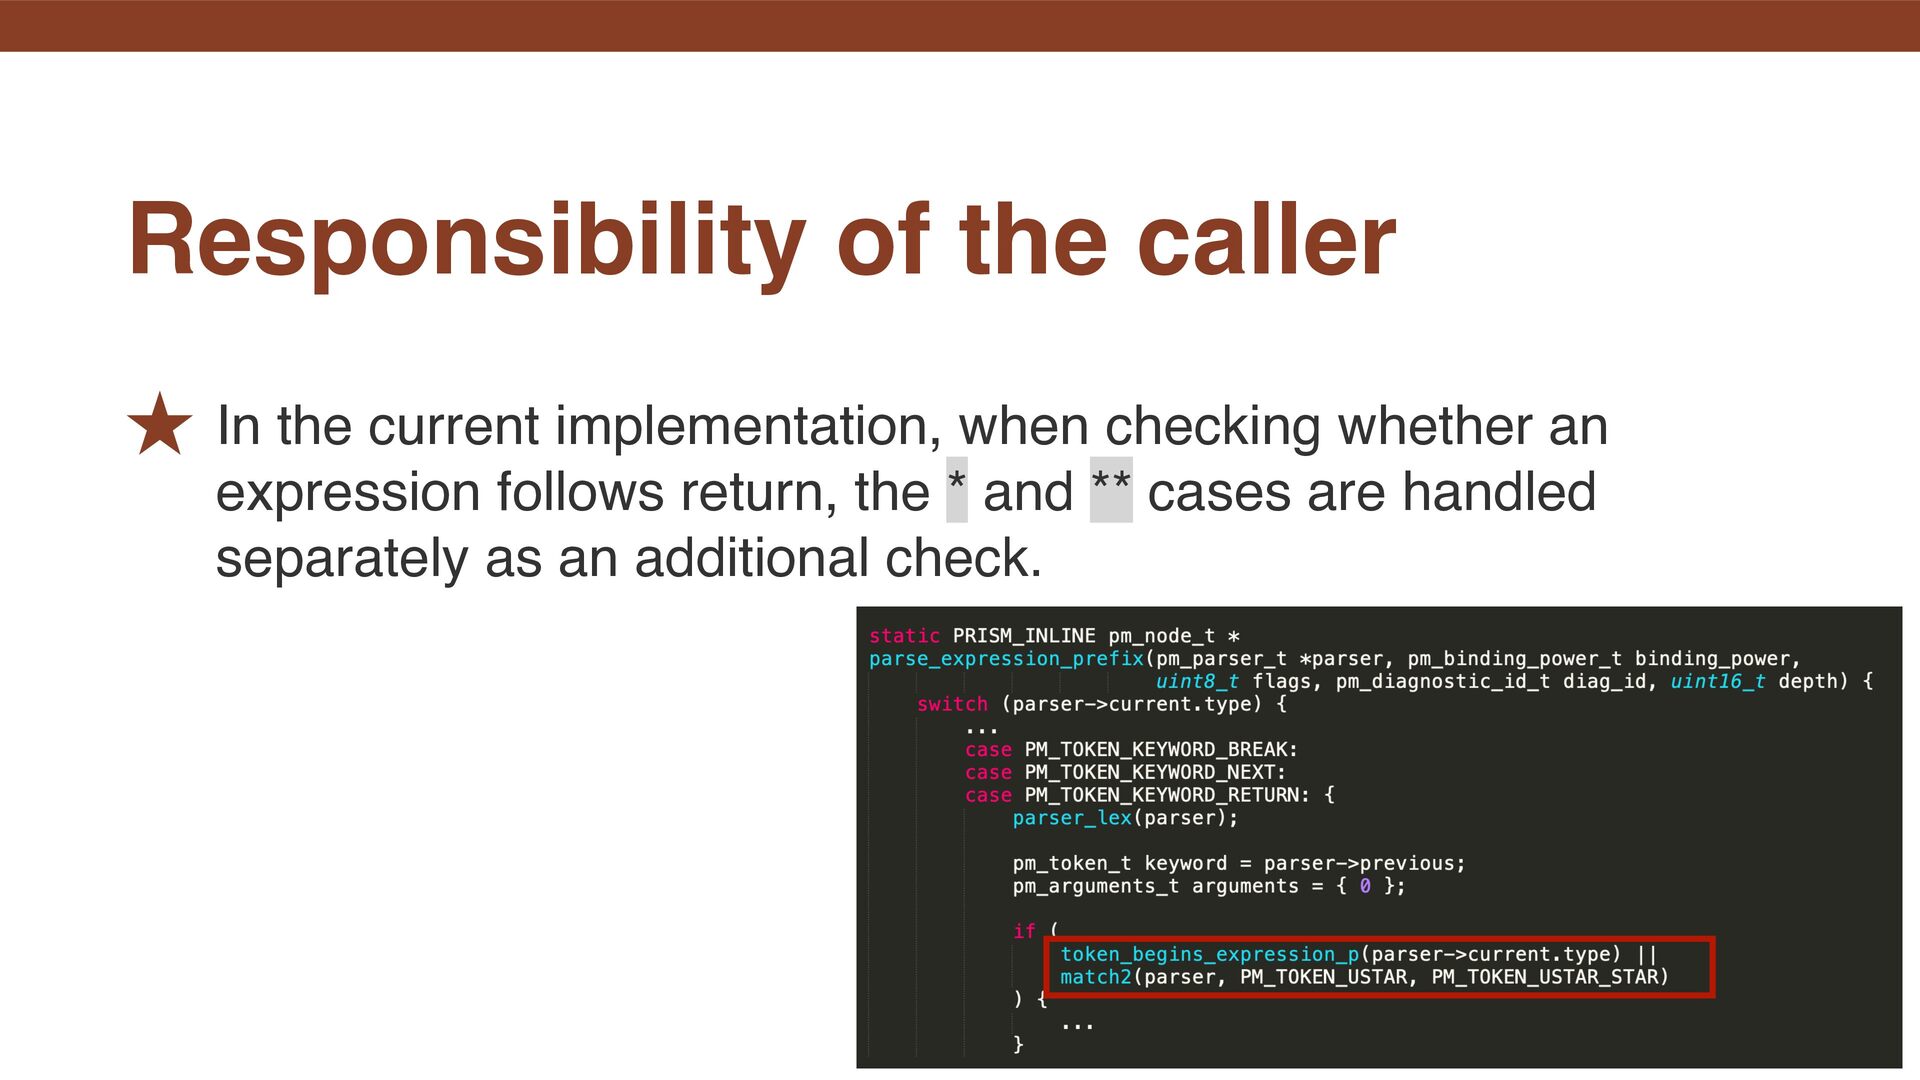
˒ In the current implementation, when checking whether an expression
follows return, the * and ** cases are handled separately as an additional check. Responsibility of the caller -
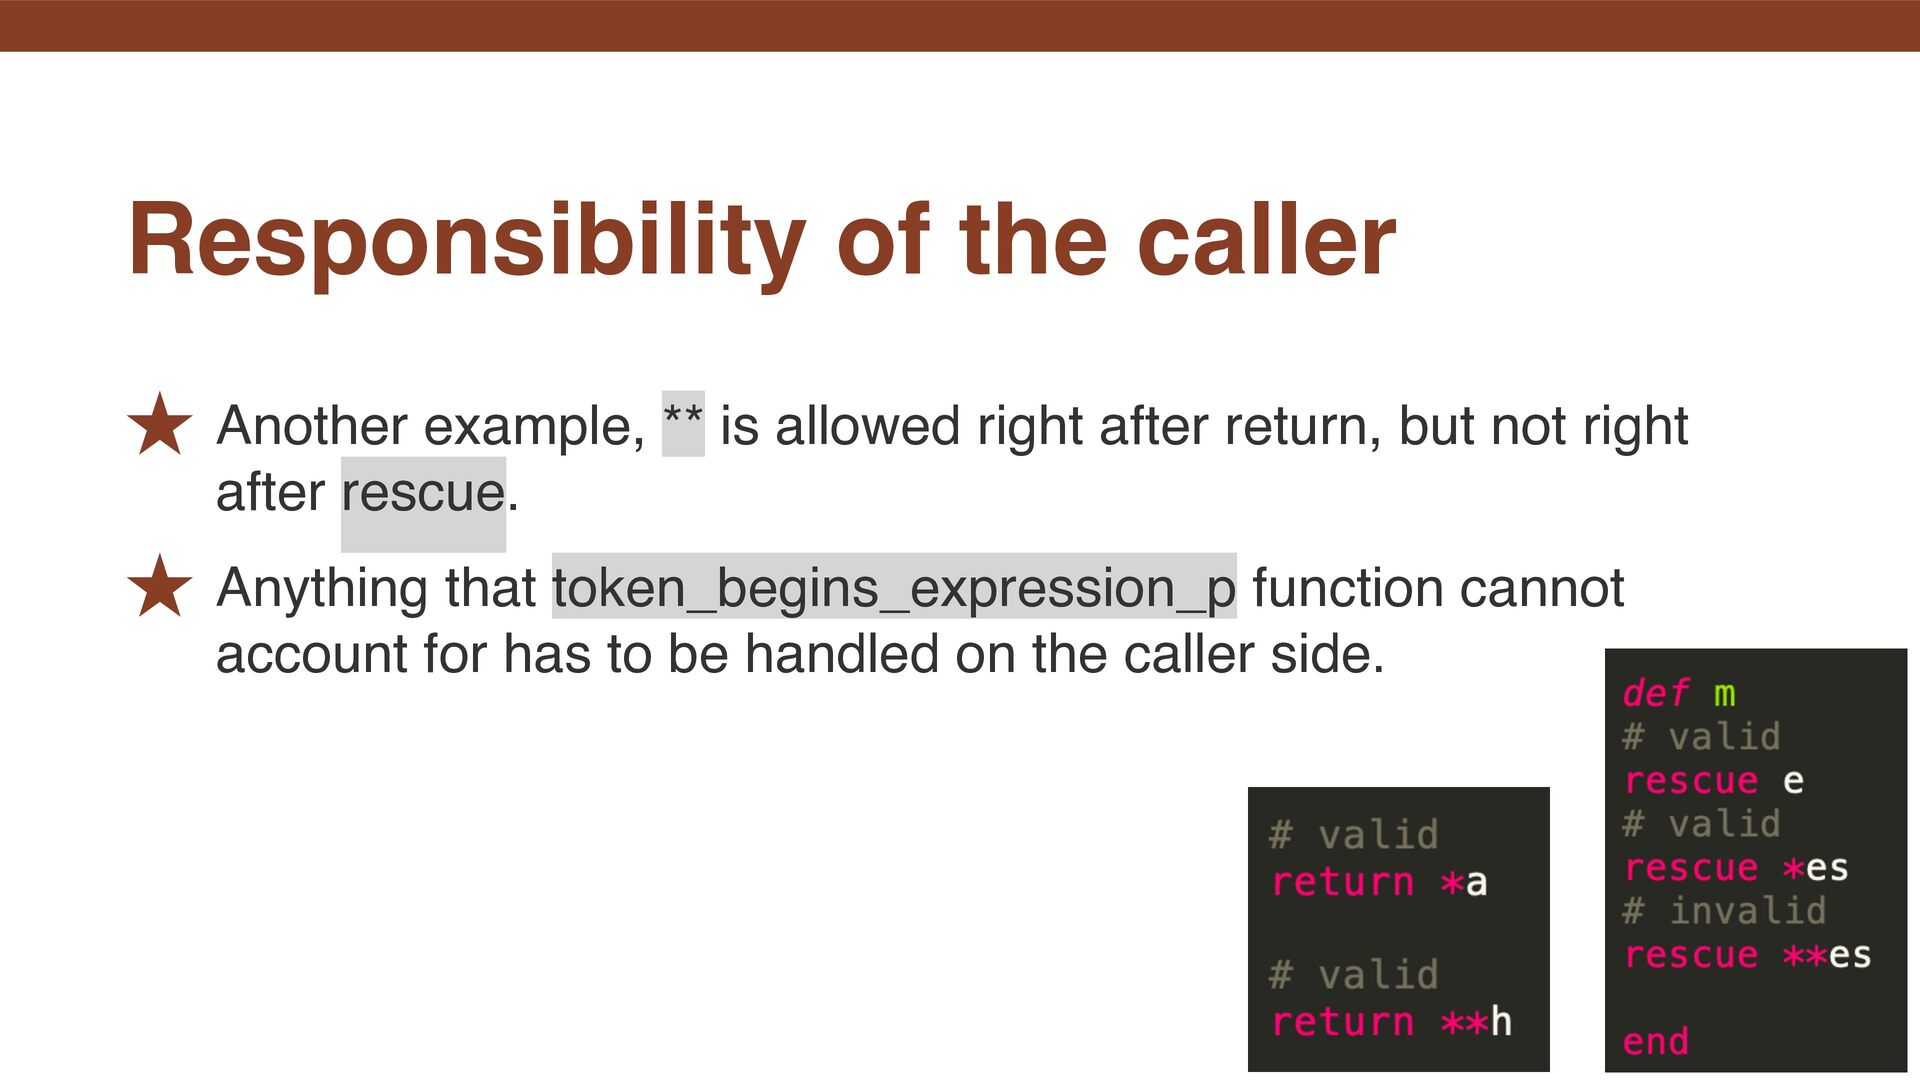
˒ Another example, ** is allowed right after return, but
not right after rescue. ˒ Anything that token_begins_expression_p function cannot account for has to be handled on the caller side. Responsibility of the caller -
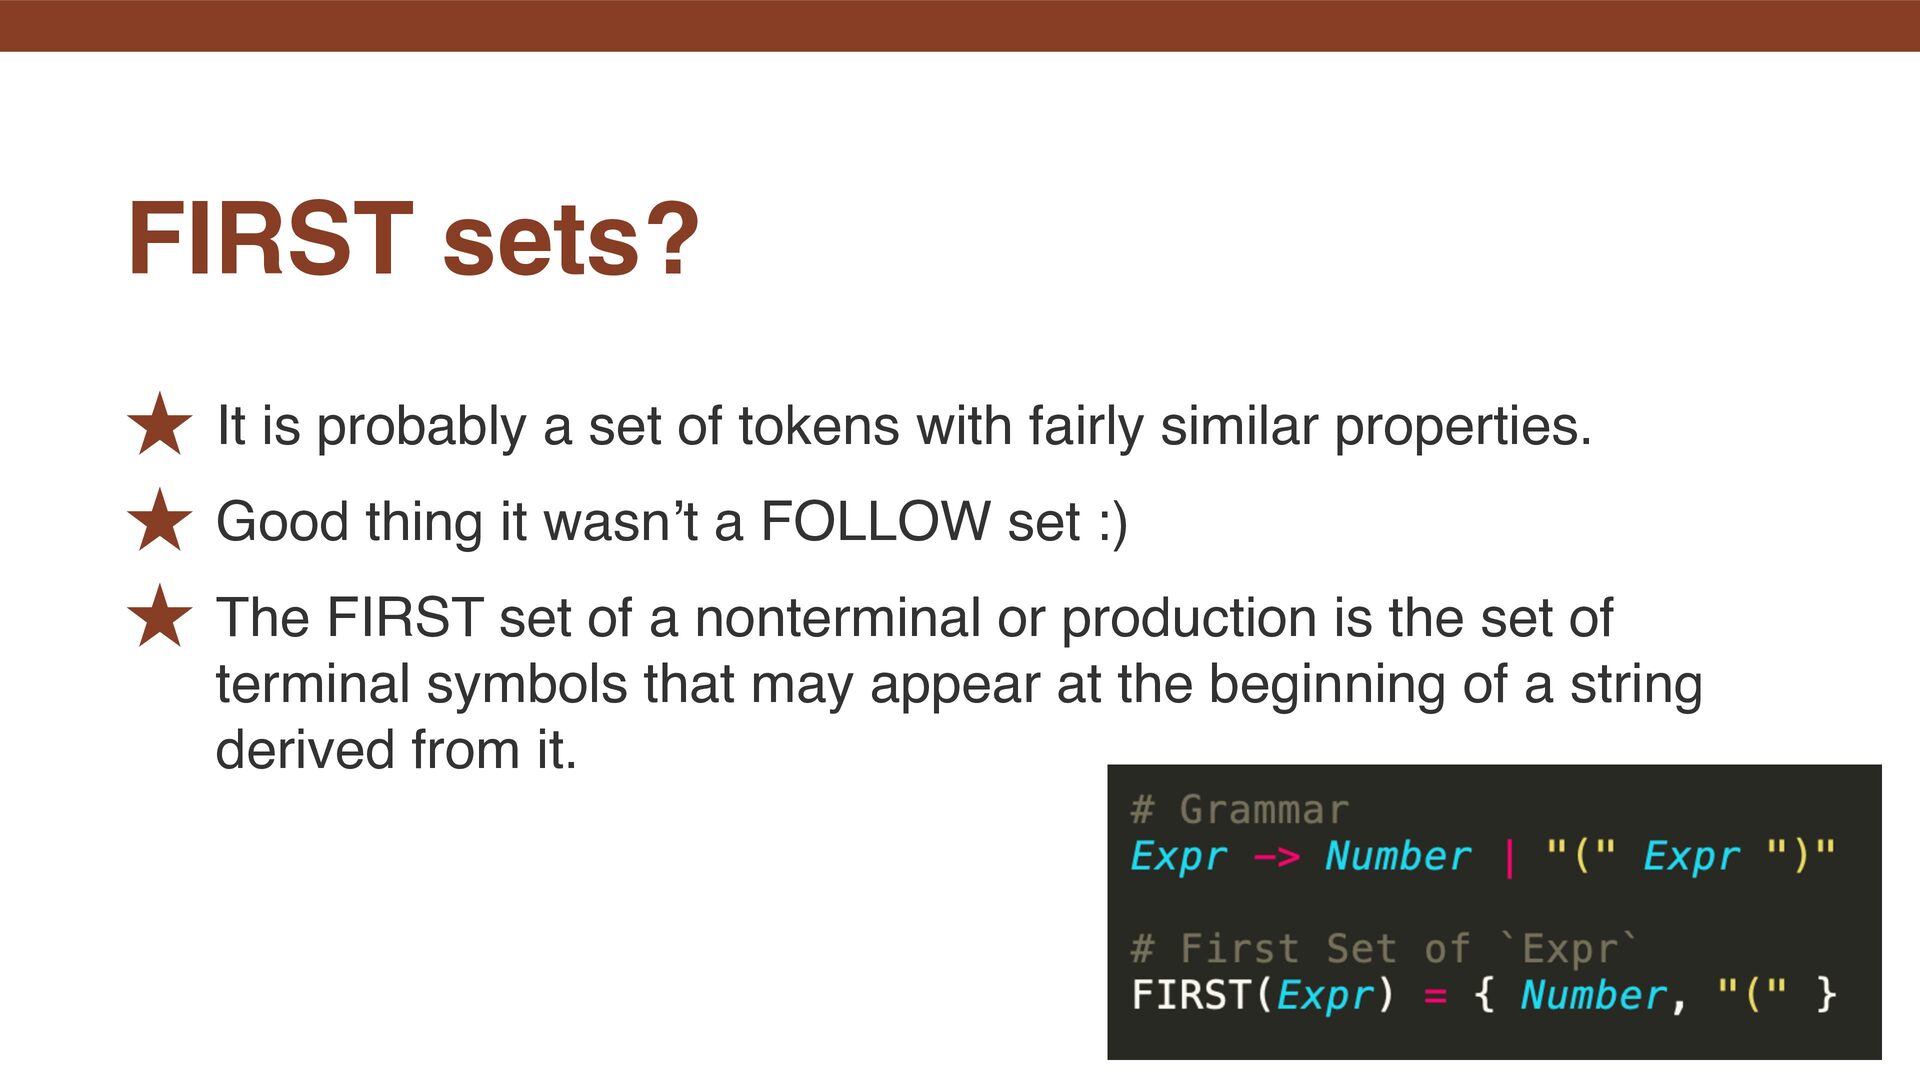
˒ It is probably a set of tokens with fairly
similar properties. ˒ Good thing it wasn’t a FOLLOW set :) ˒ The FIRST set of a nonterminal or production is the set of terminal symbols that may appear at the beginning of a string derived from it. FIRST sets? -
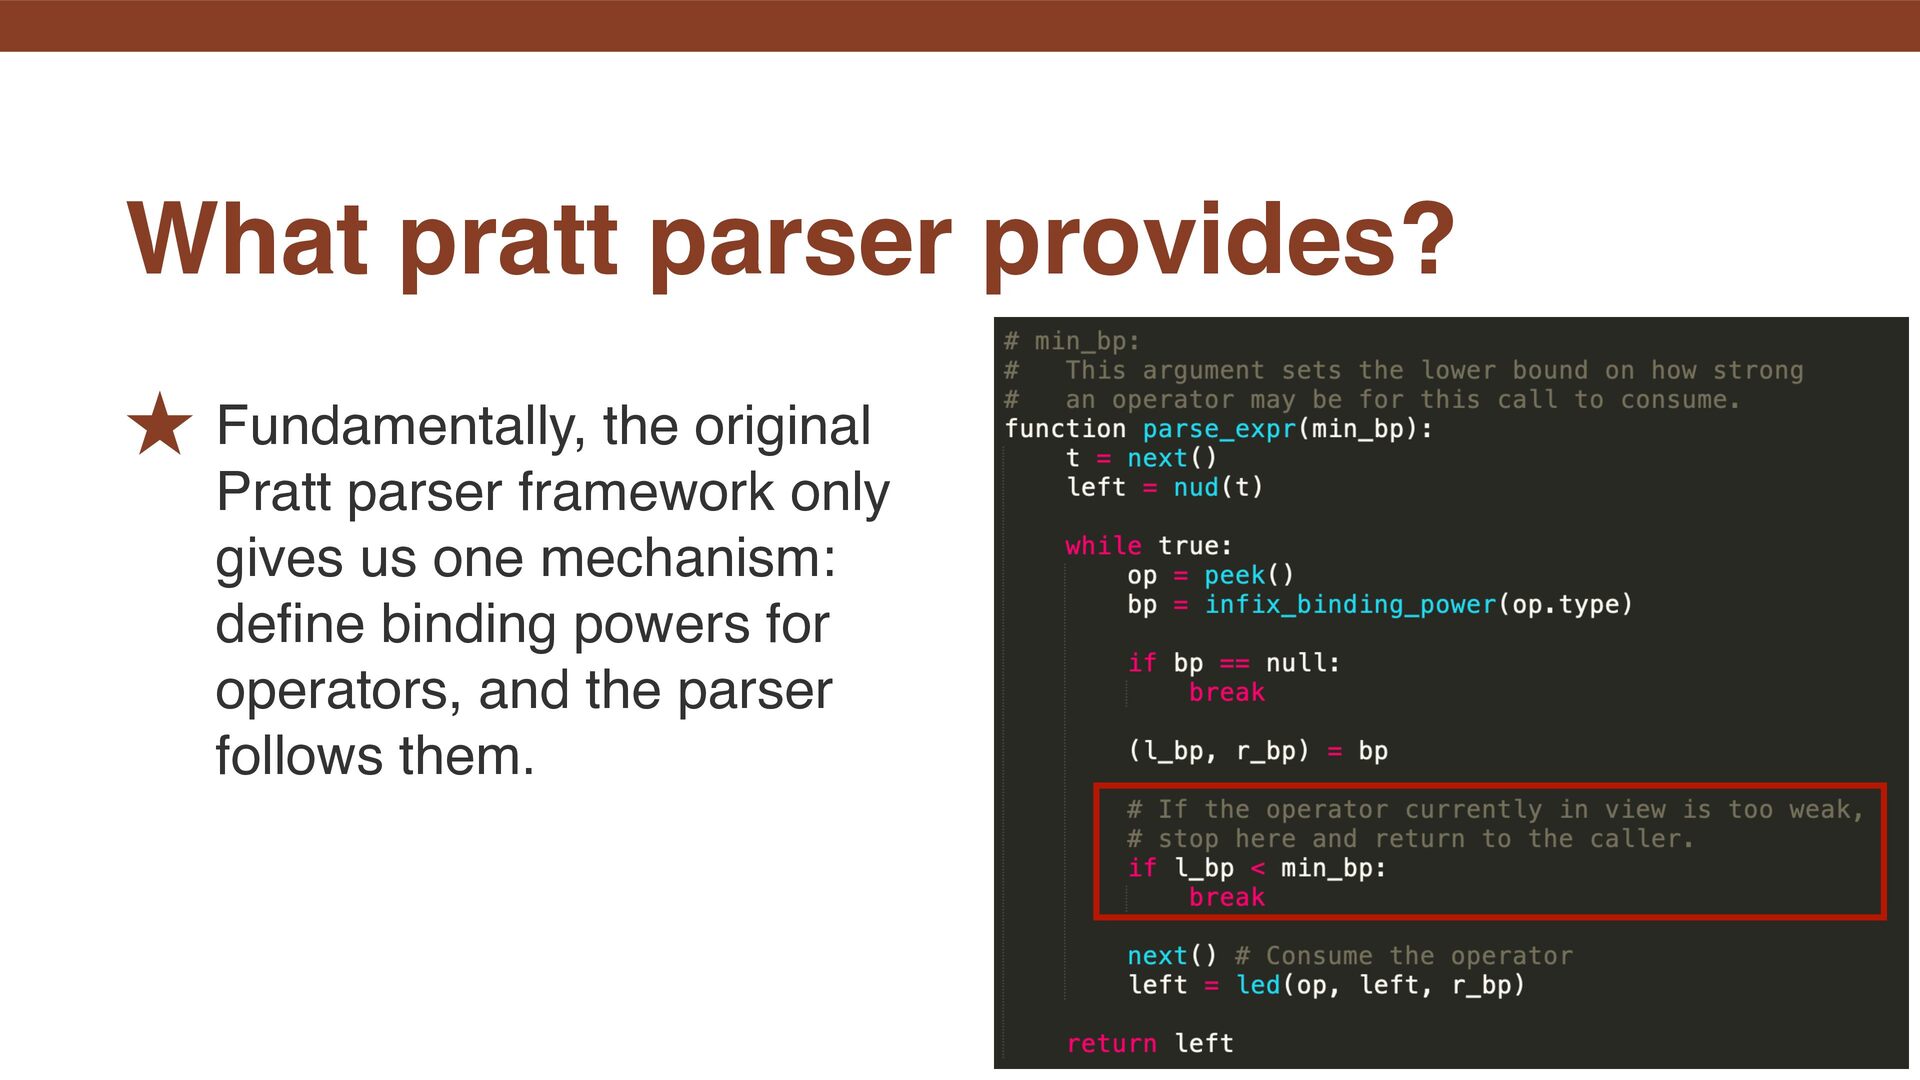
˒ Fundamentally, the original Pratt parser framework only gives us
one mechanism: de fi ne binding powers for operators, and the parser follows them. What pratt parser provides? -
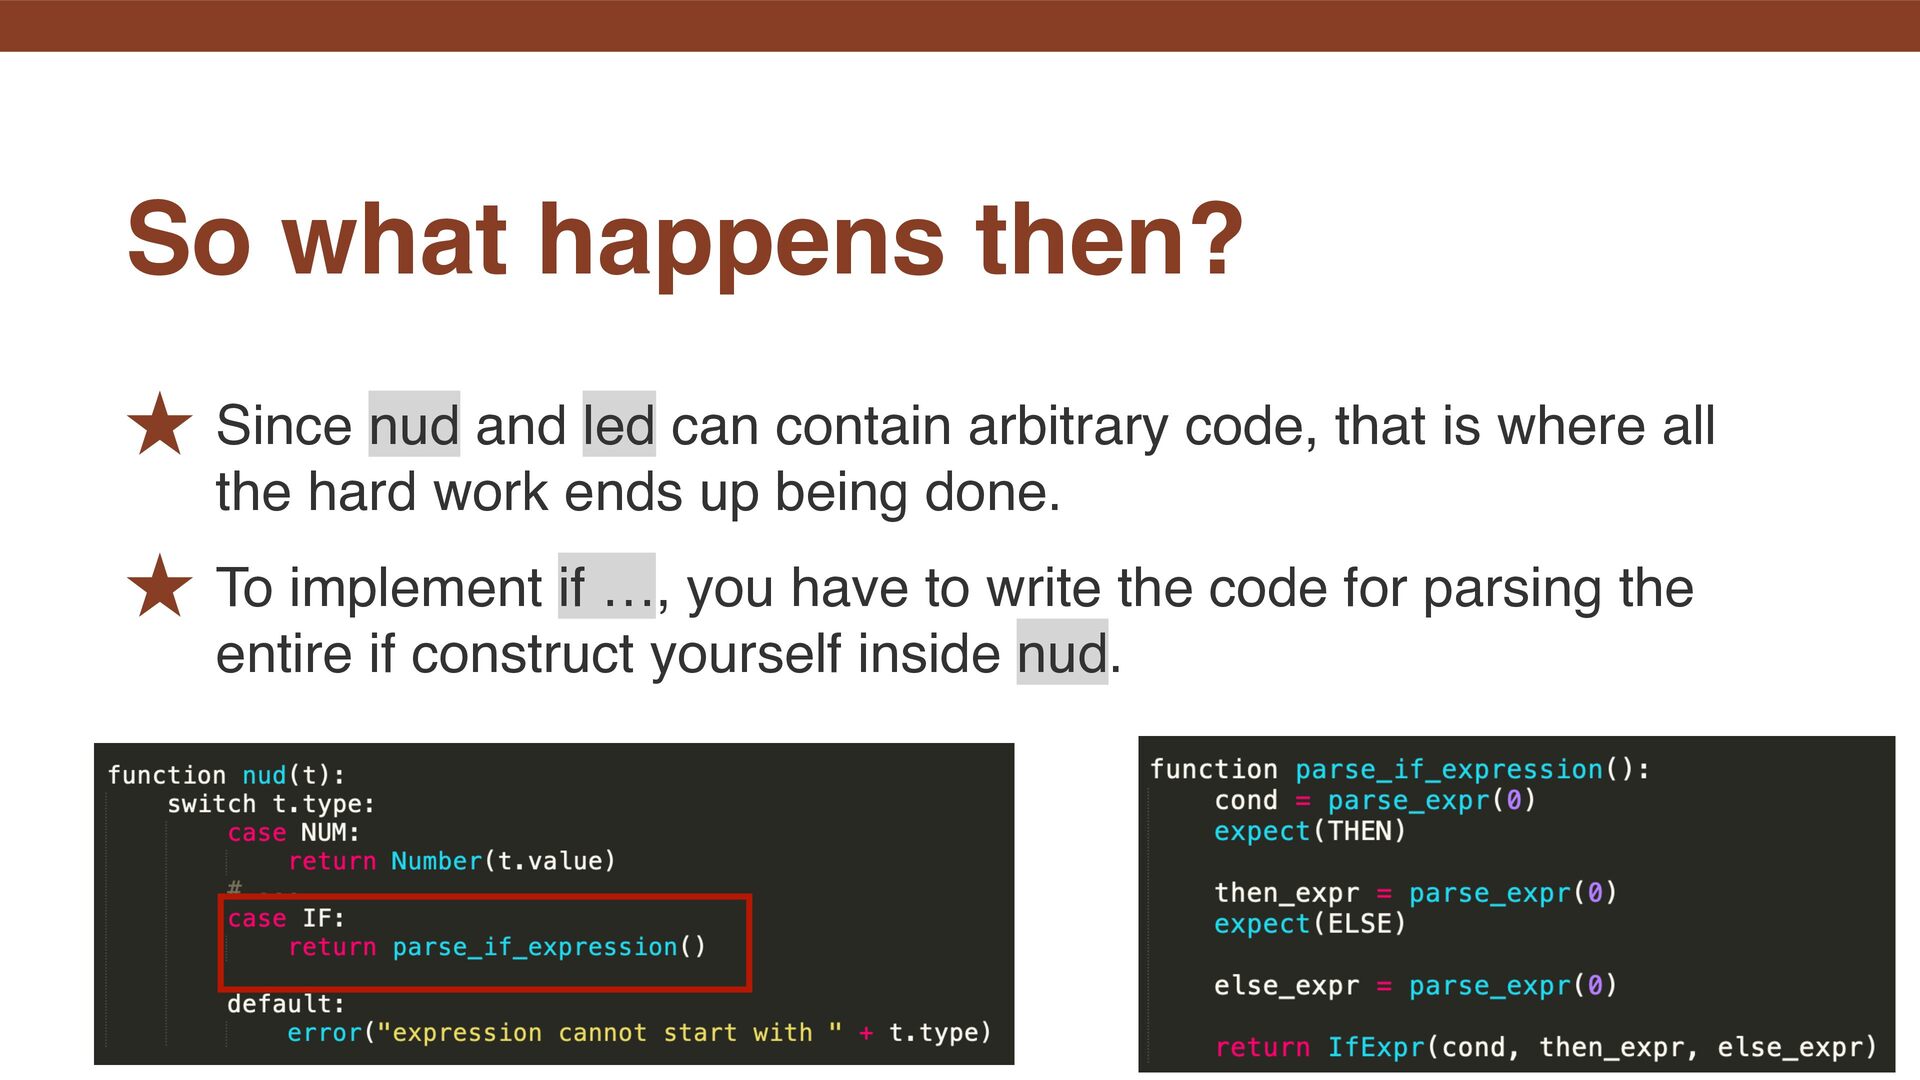
˒ Since nud and led can contain arbitrary code, that
is where all the hard work ends up being done. ˒ To implement if …, you have to write the code for parsing the entire if construct yourself inside nud. So what happens then? -
˒ With an LR parser, the generator just handles it,
so I do not really have to think about it. How is this handled in LR parsing? -
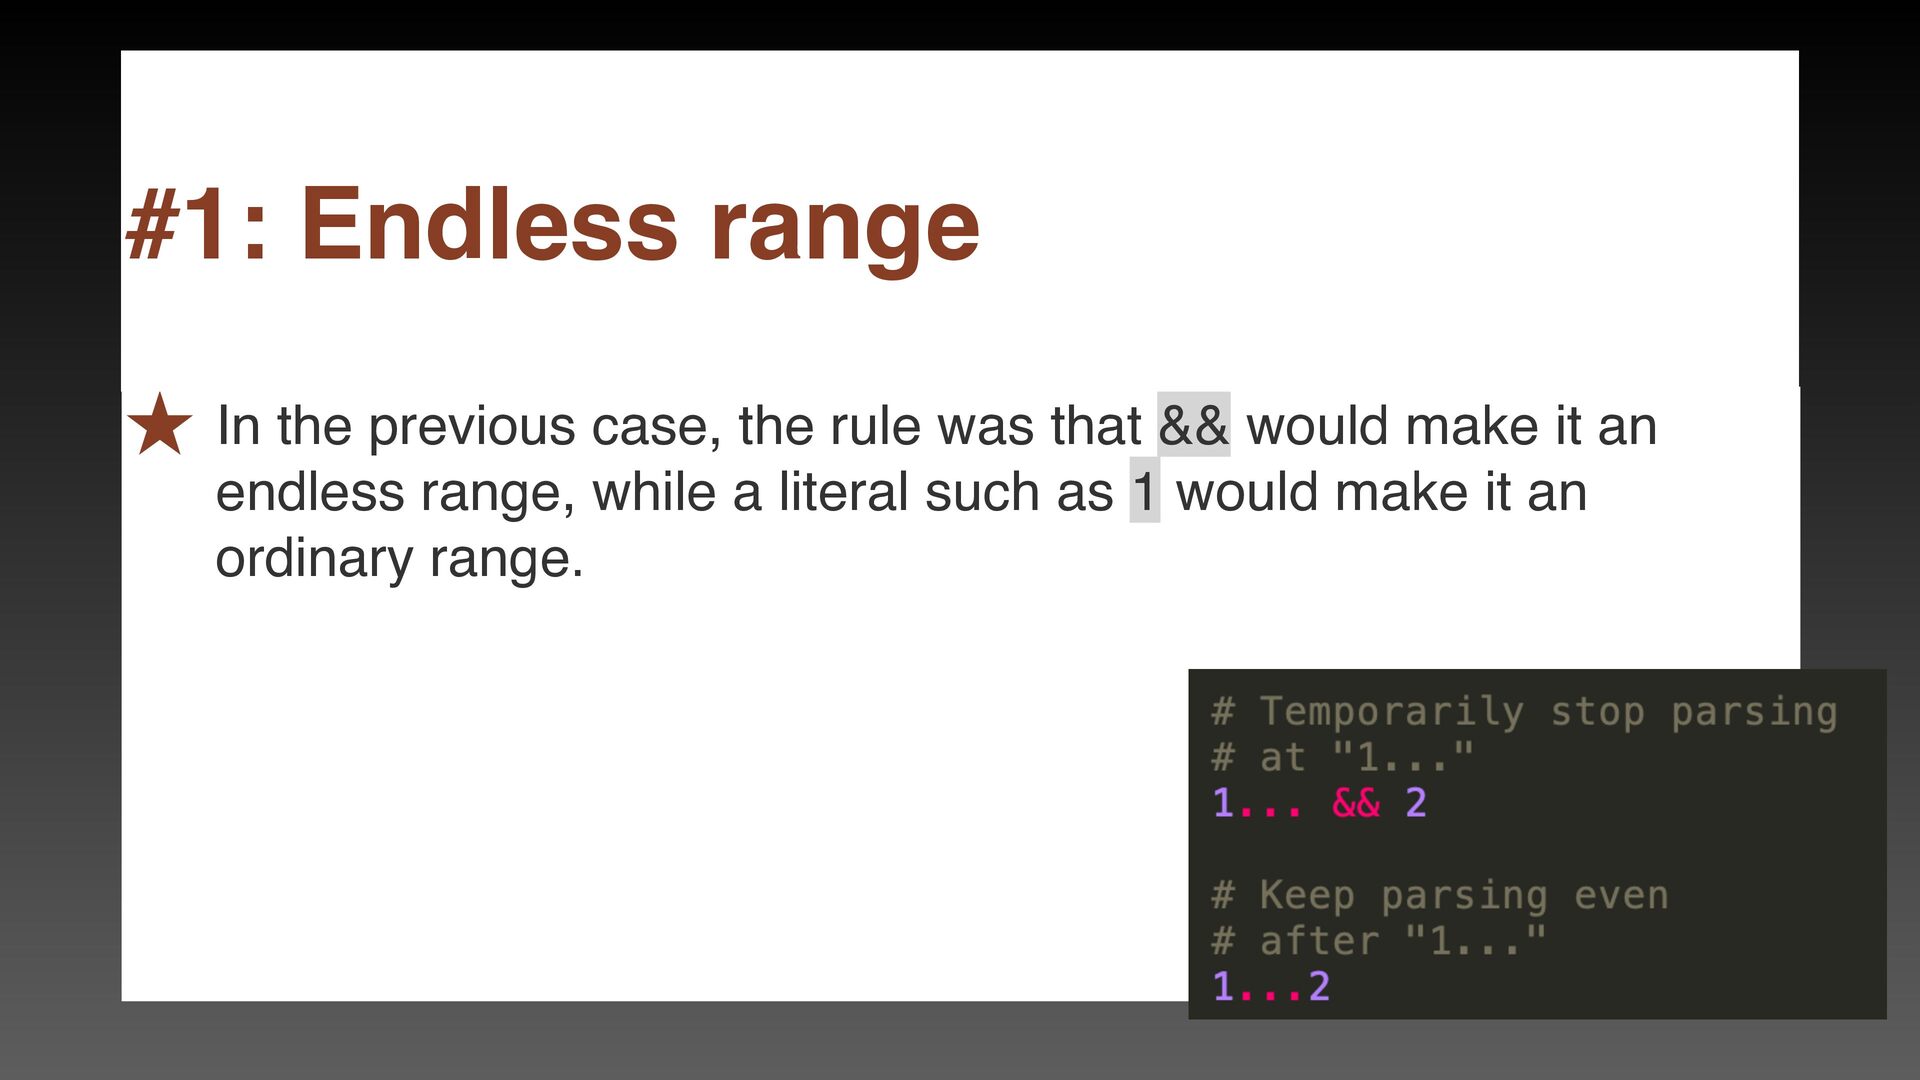
˒ In the previous case, the rule was that &&
would make it an endless range, while a literal such as 1 would make it an ordinary range. #1: Endless range -
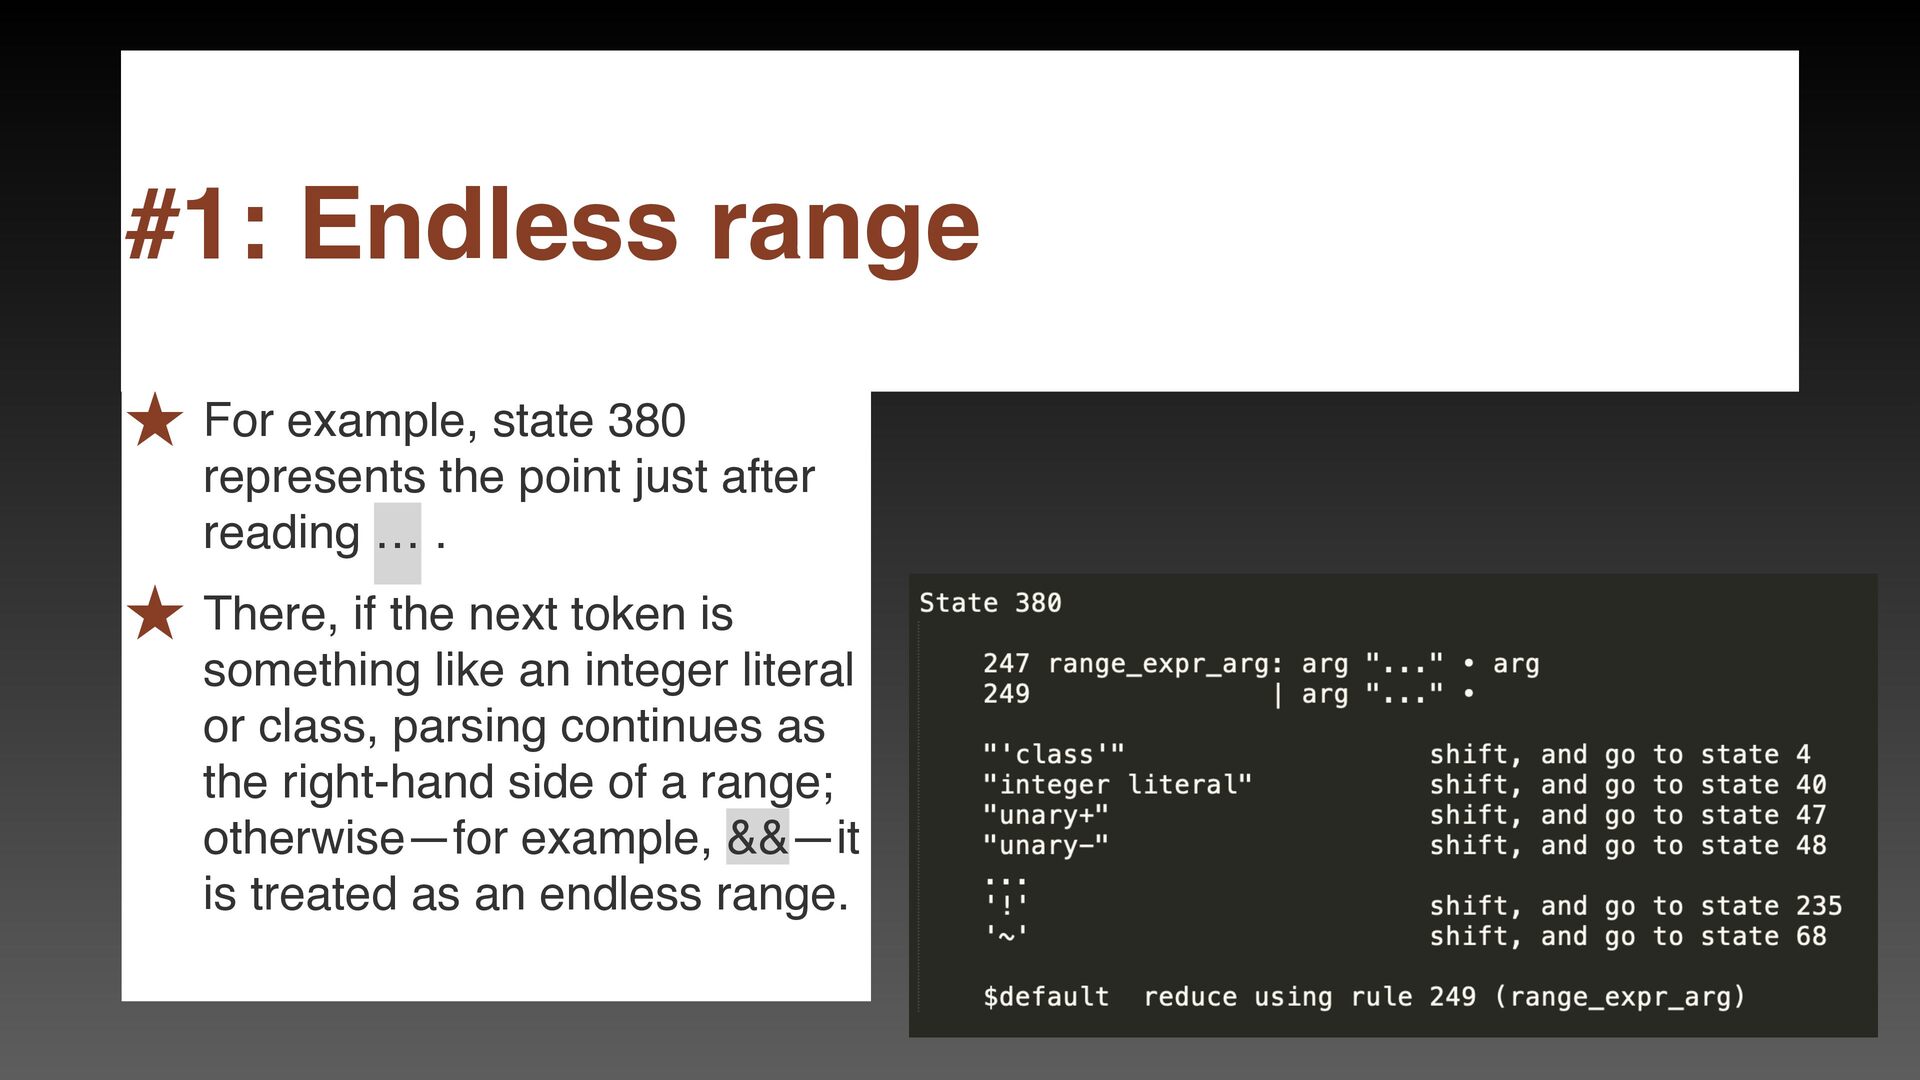
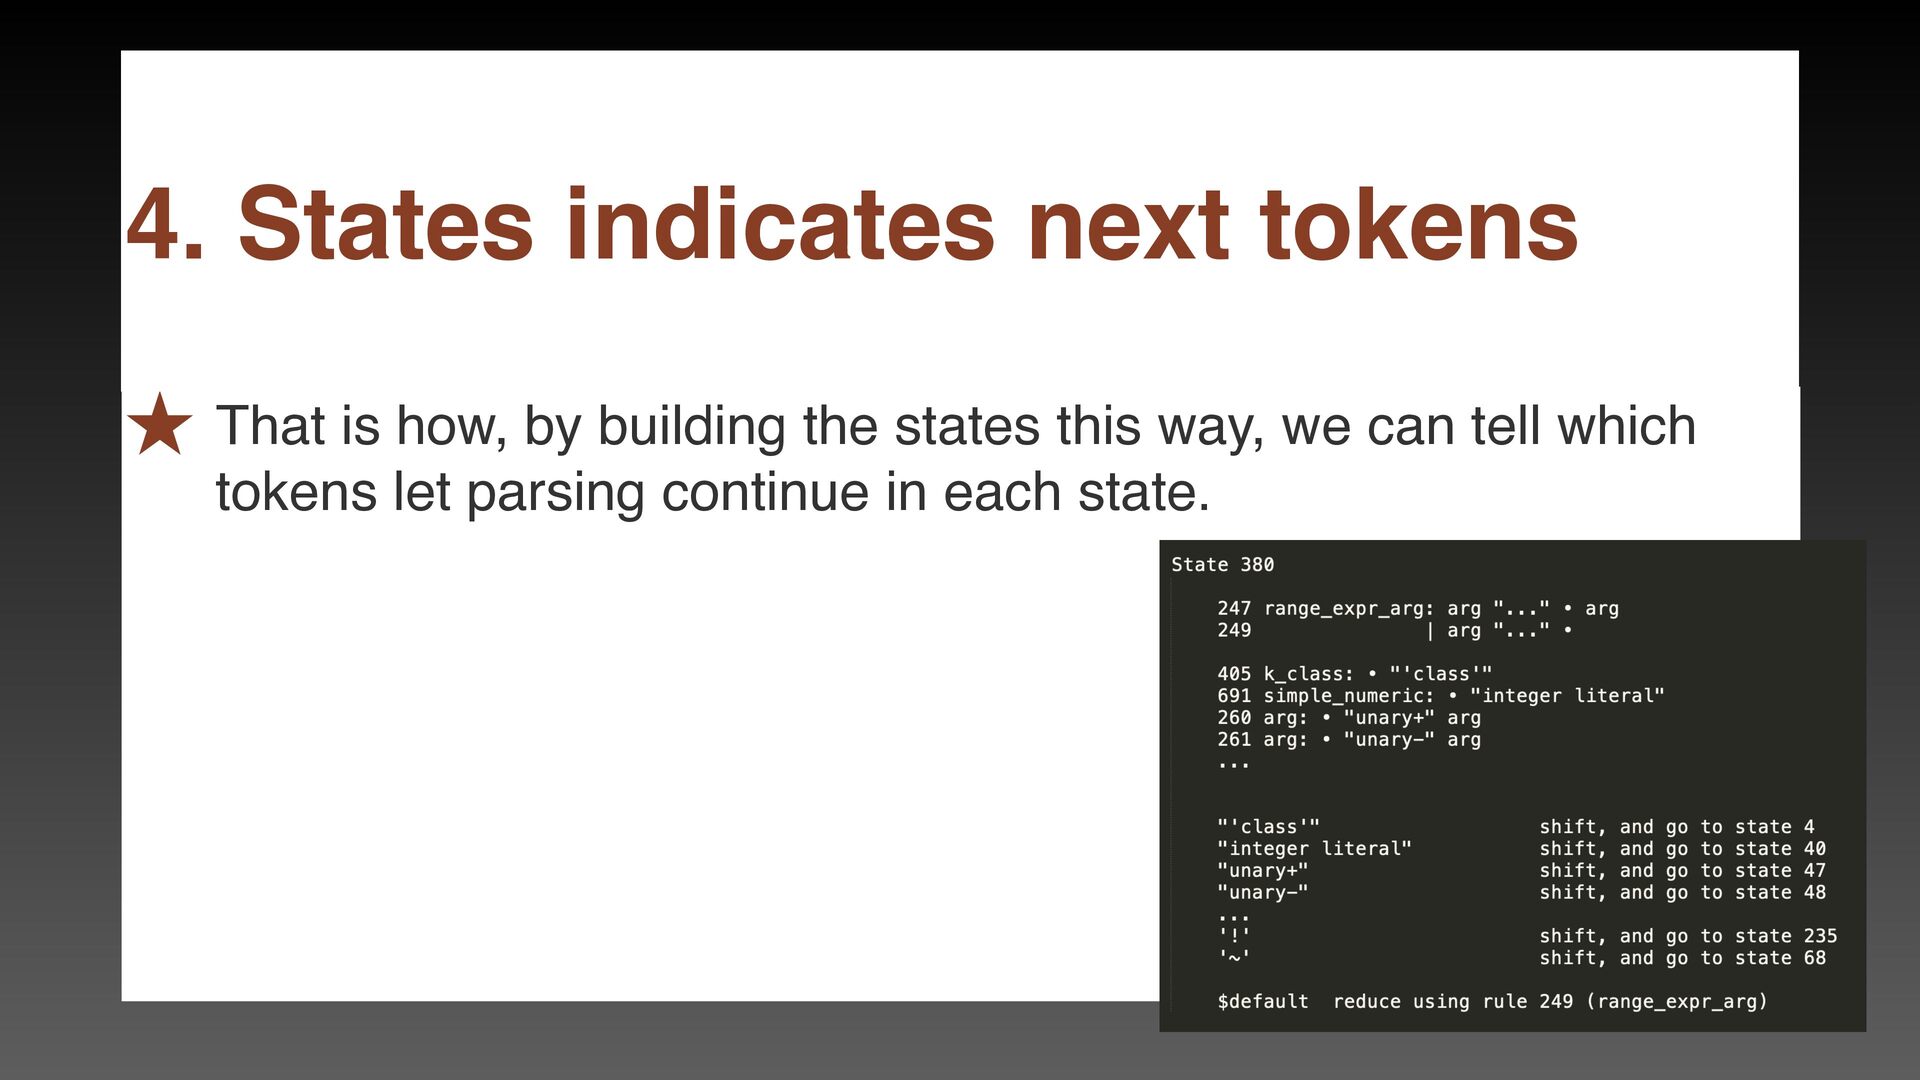
˒ For example, state 380 represents the point just after
reading … . ˒ There, if the next token is something like an integer literal or class, parsing continues as the right-hand side of a range; otherwise—for example, &&—it is treated as an endless range. #1: Endless range -
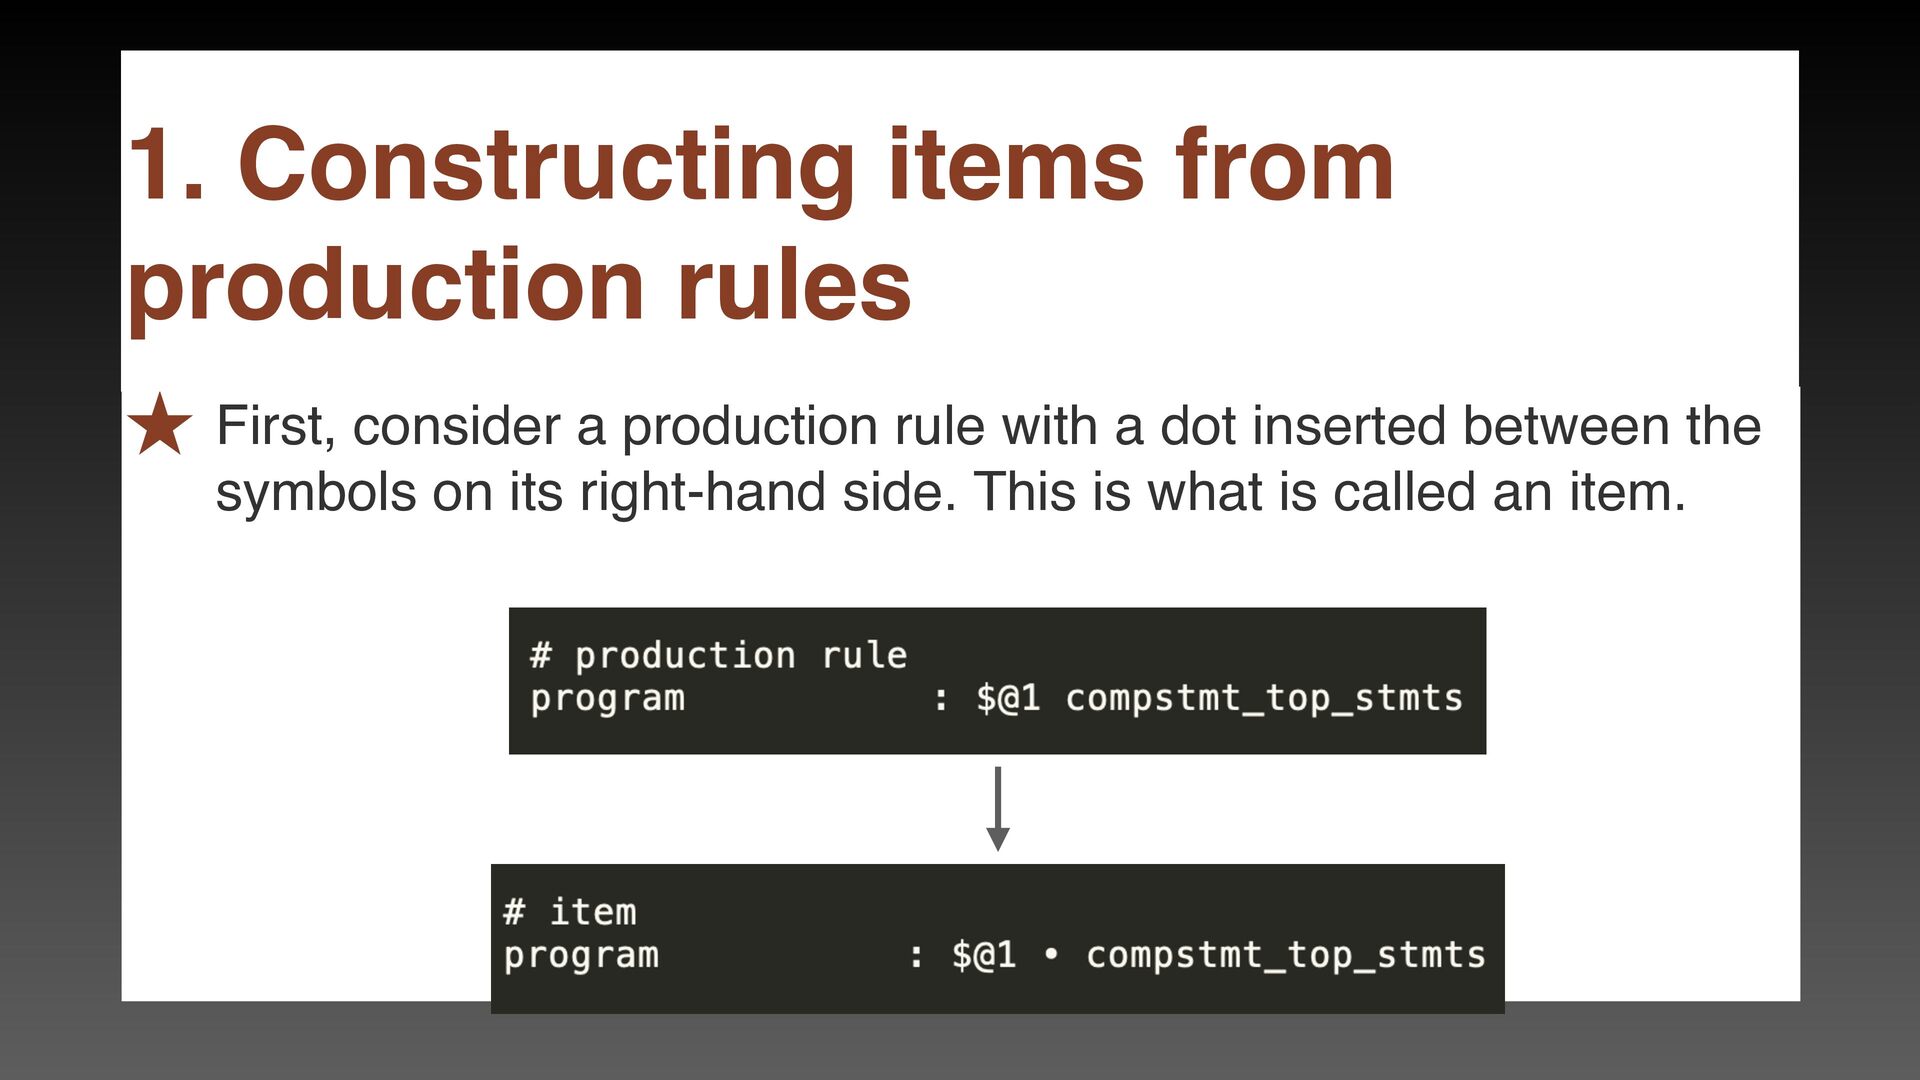
˒ First, consider a production rule with a dot inserted
between the symbols on its right-hand side. This is what is called an item. 1. Constructing items from production rules -
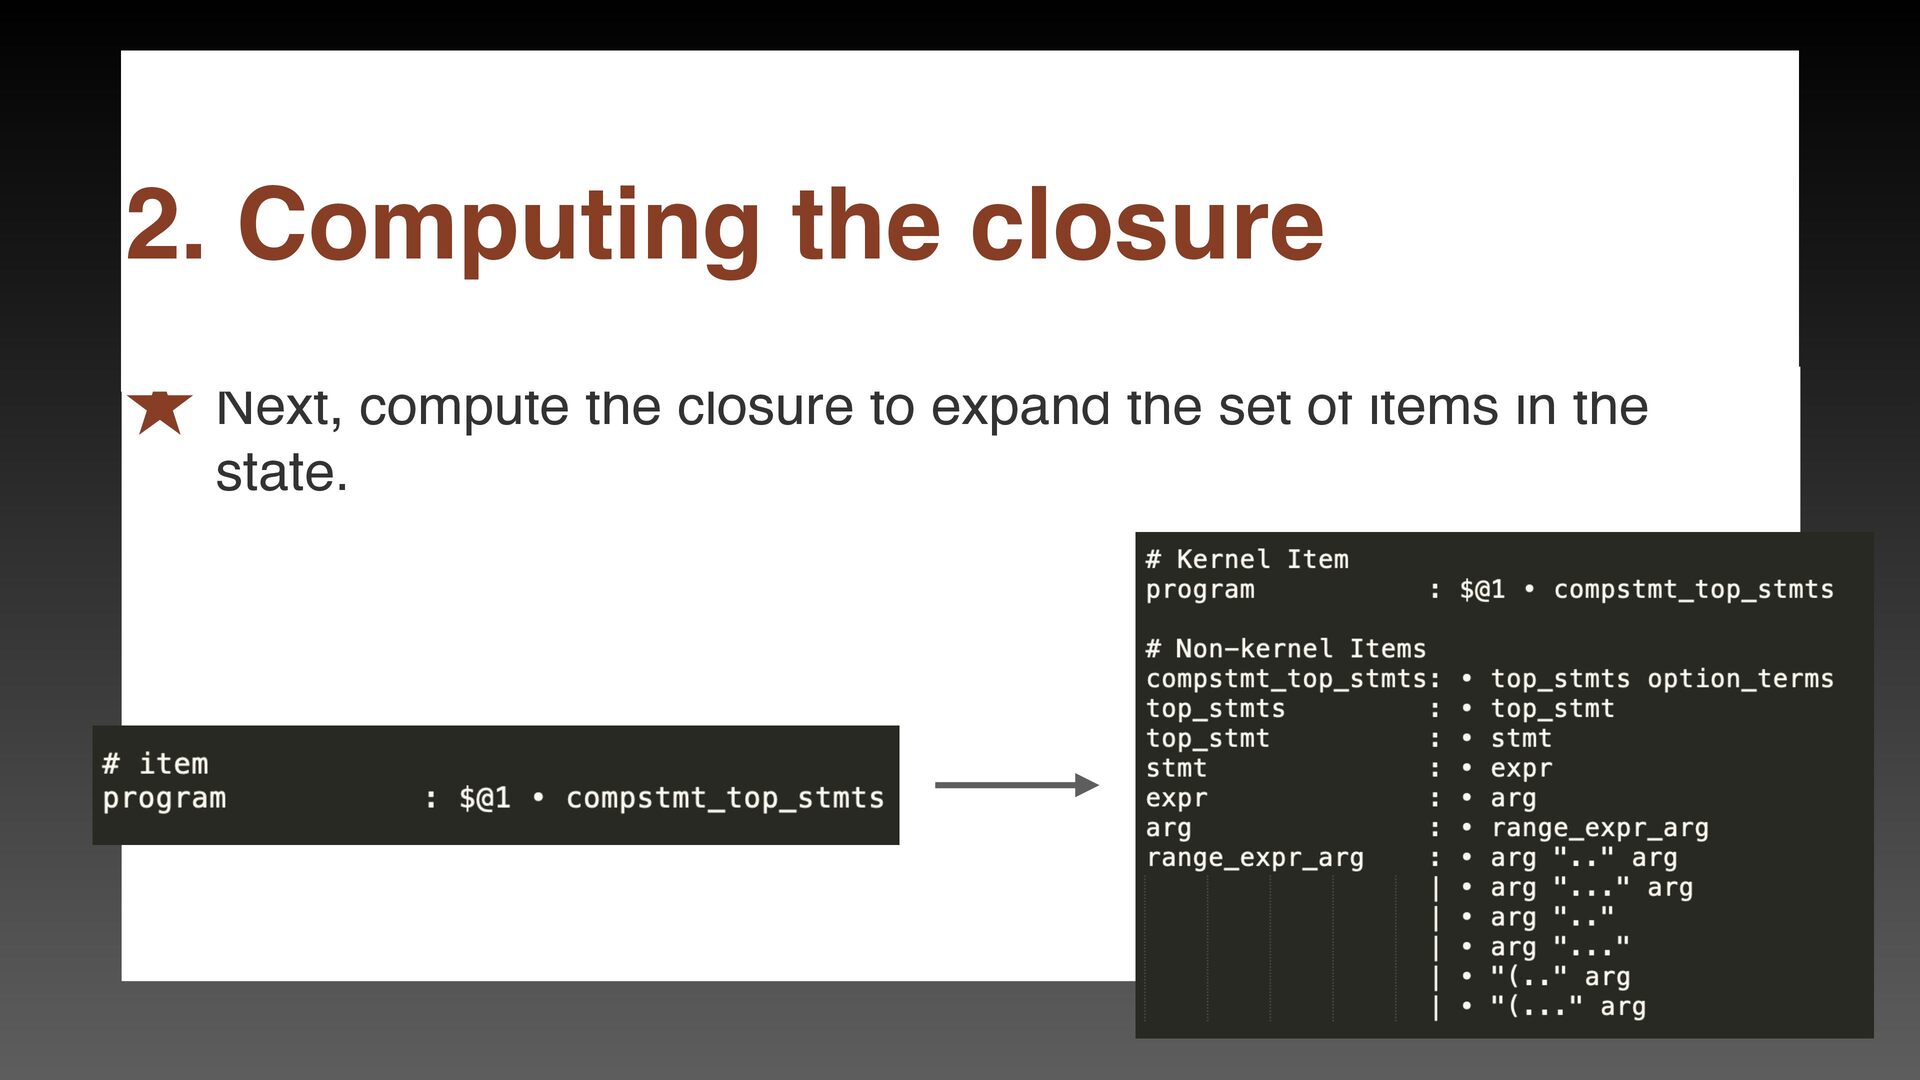
˒ Next, compute the closure to expand the set of
items in the state. 2. Computing the closure -
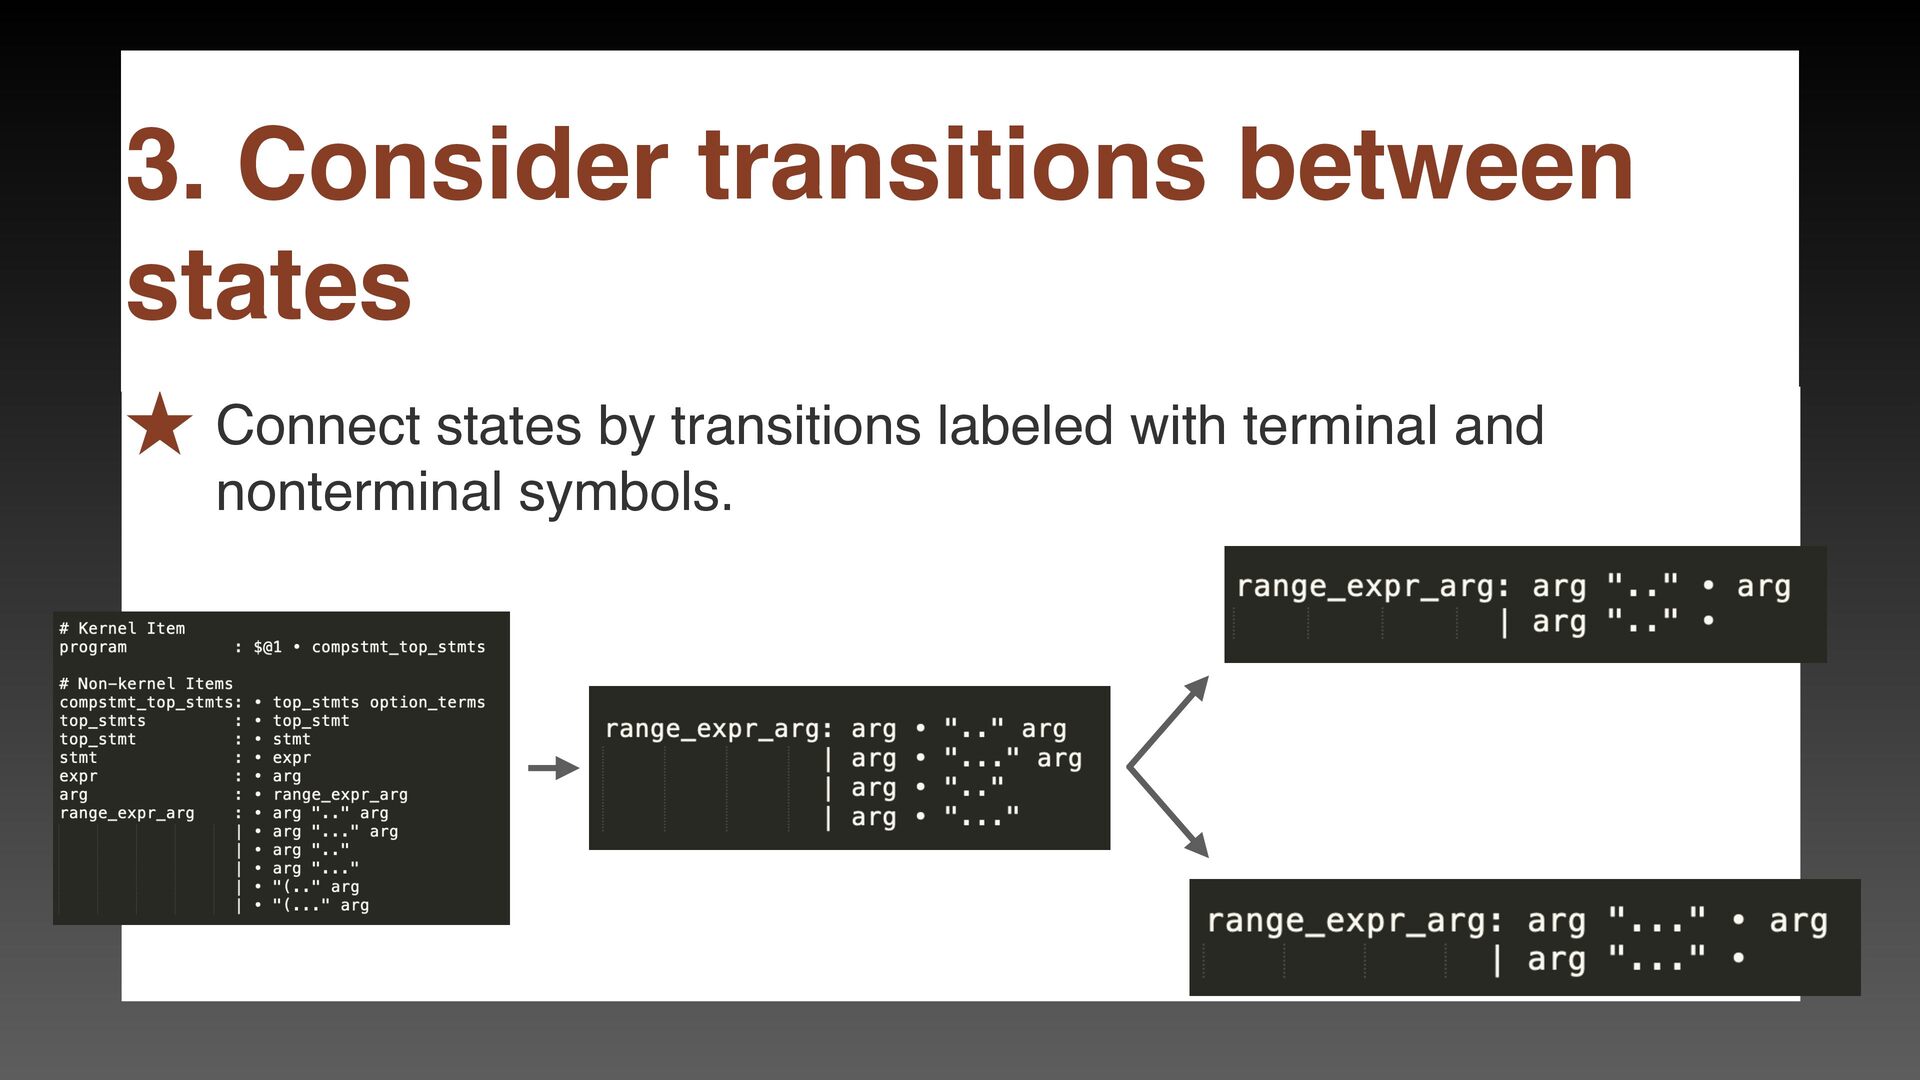
˒ Connect states by transitions labeled with terminal and nonterminal
symbols. 3. Consider transitions between states -
˒ That is how, by building the states this way,
we can tell which tokens let parsing continue in each state. 4. States indicates next tokens -
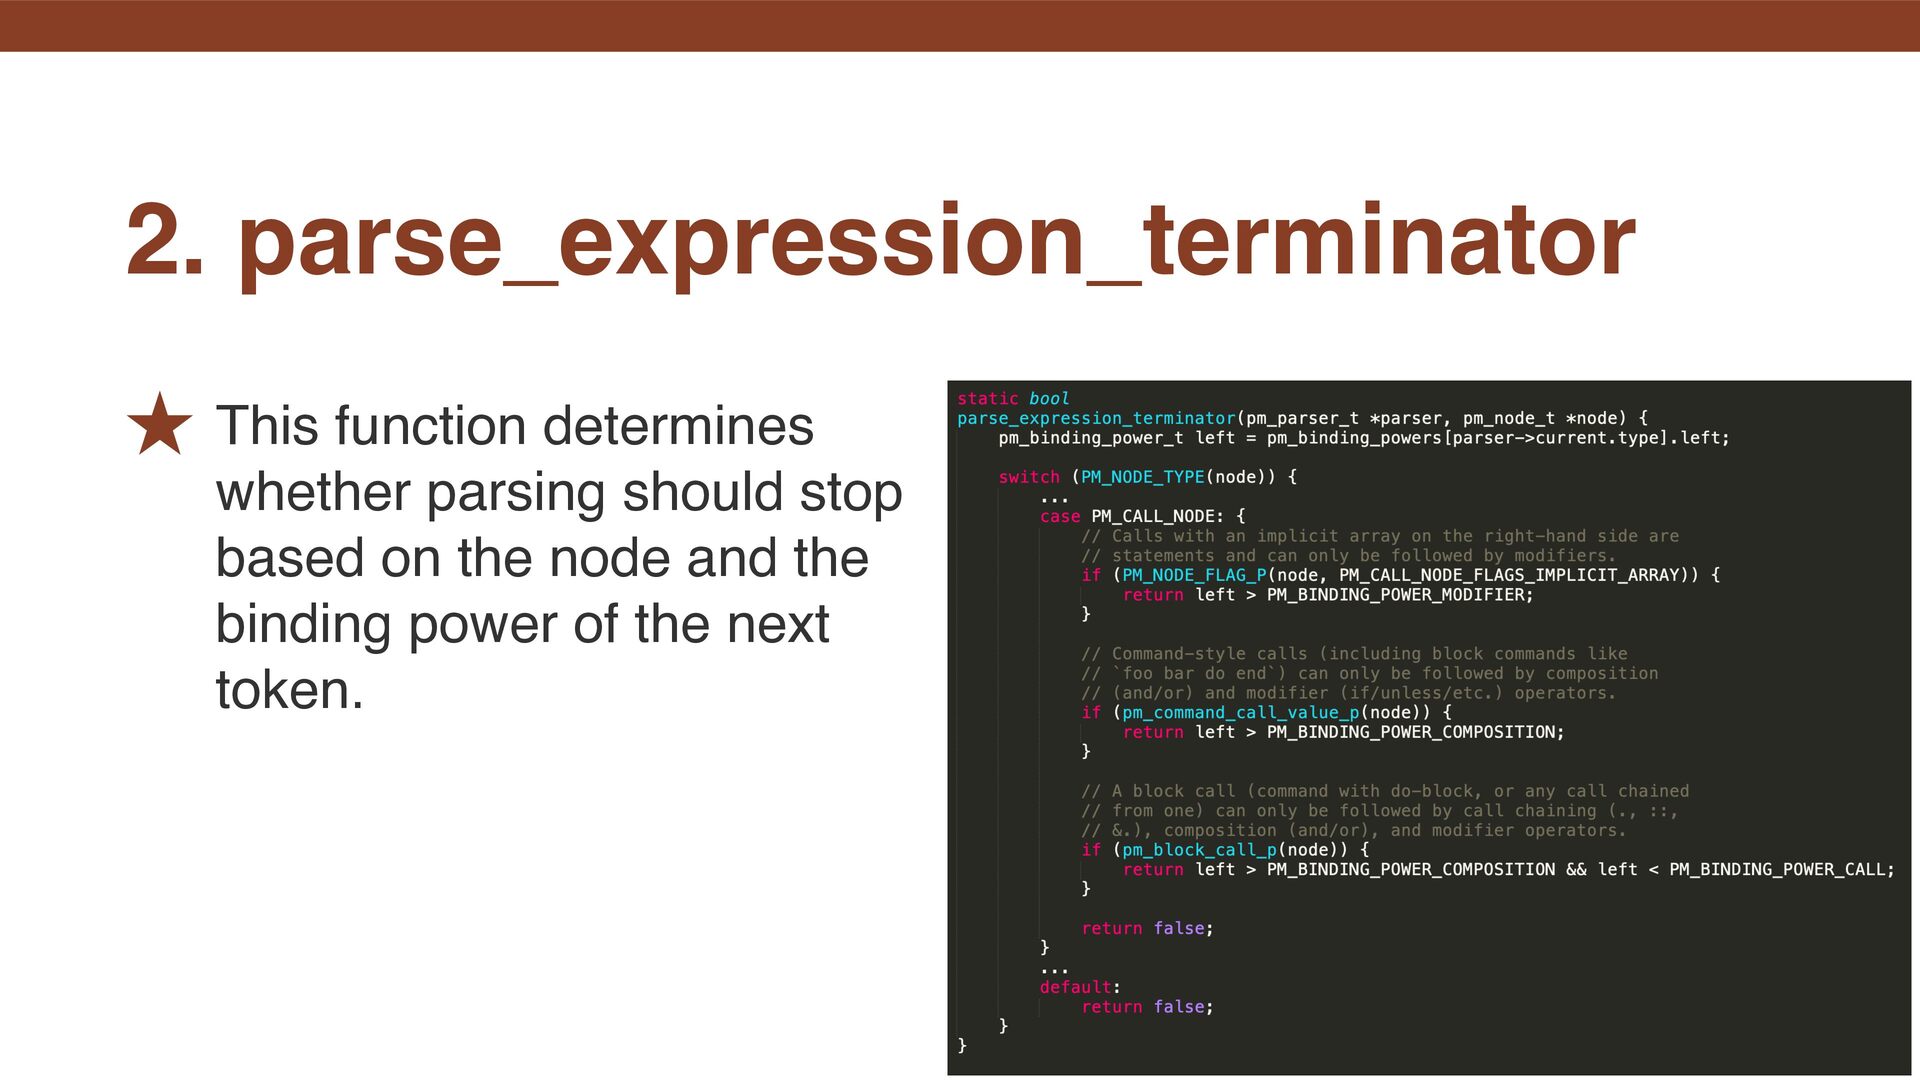
˒ This function determines whether parsing should stop based on
the node and the binding power of the next token. 2. parse_expression_terminator -
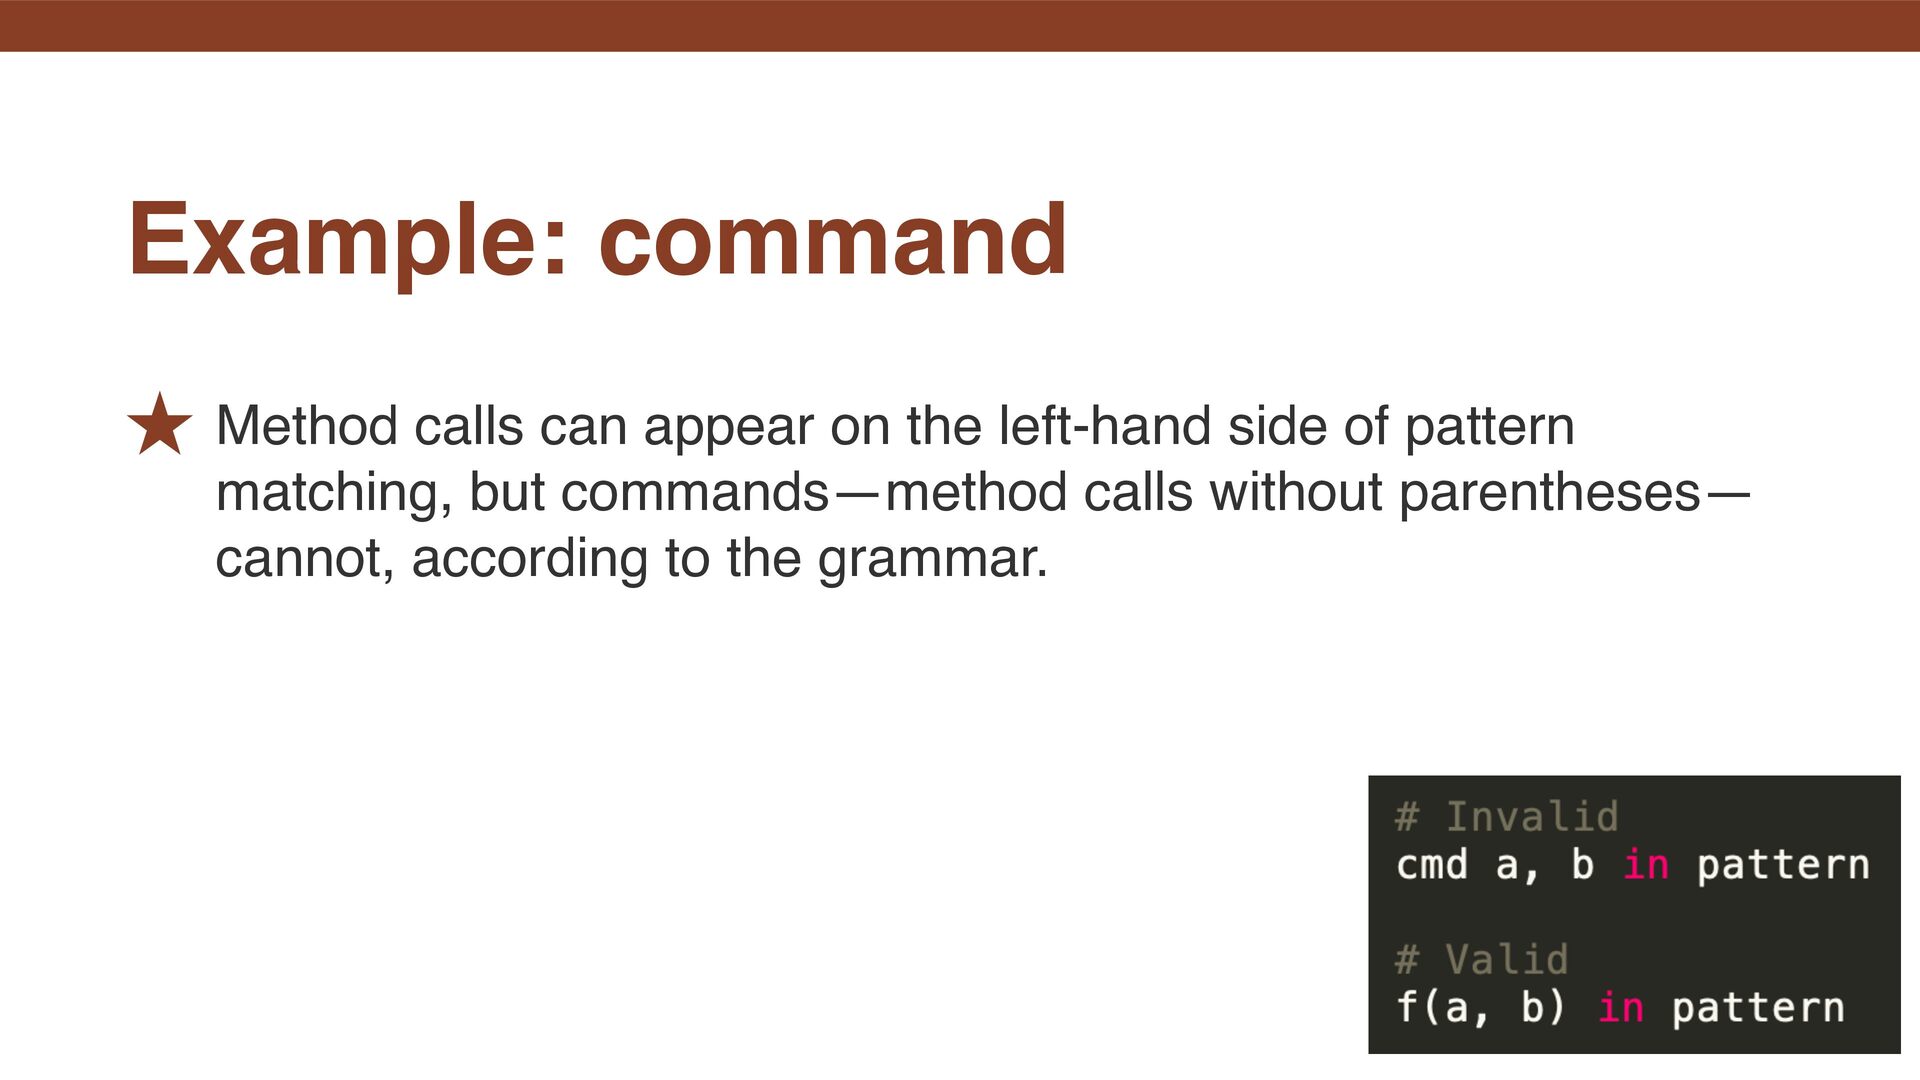
˒ Method calls can appear on the left-hand side of
pattern matching, but commands—method calls without parentheses— cannot, according to the grammar. Example: command -
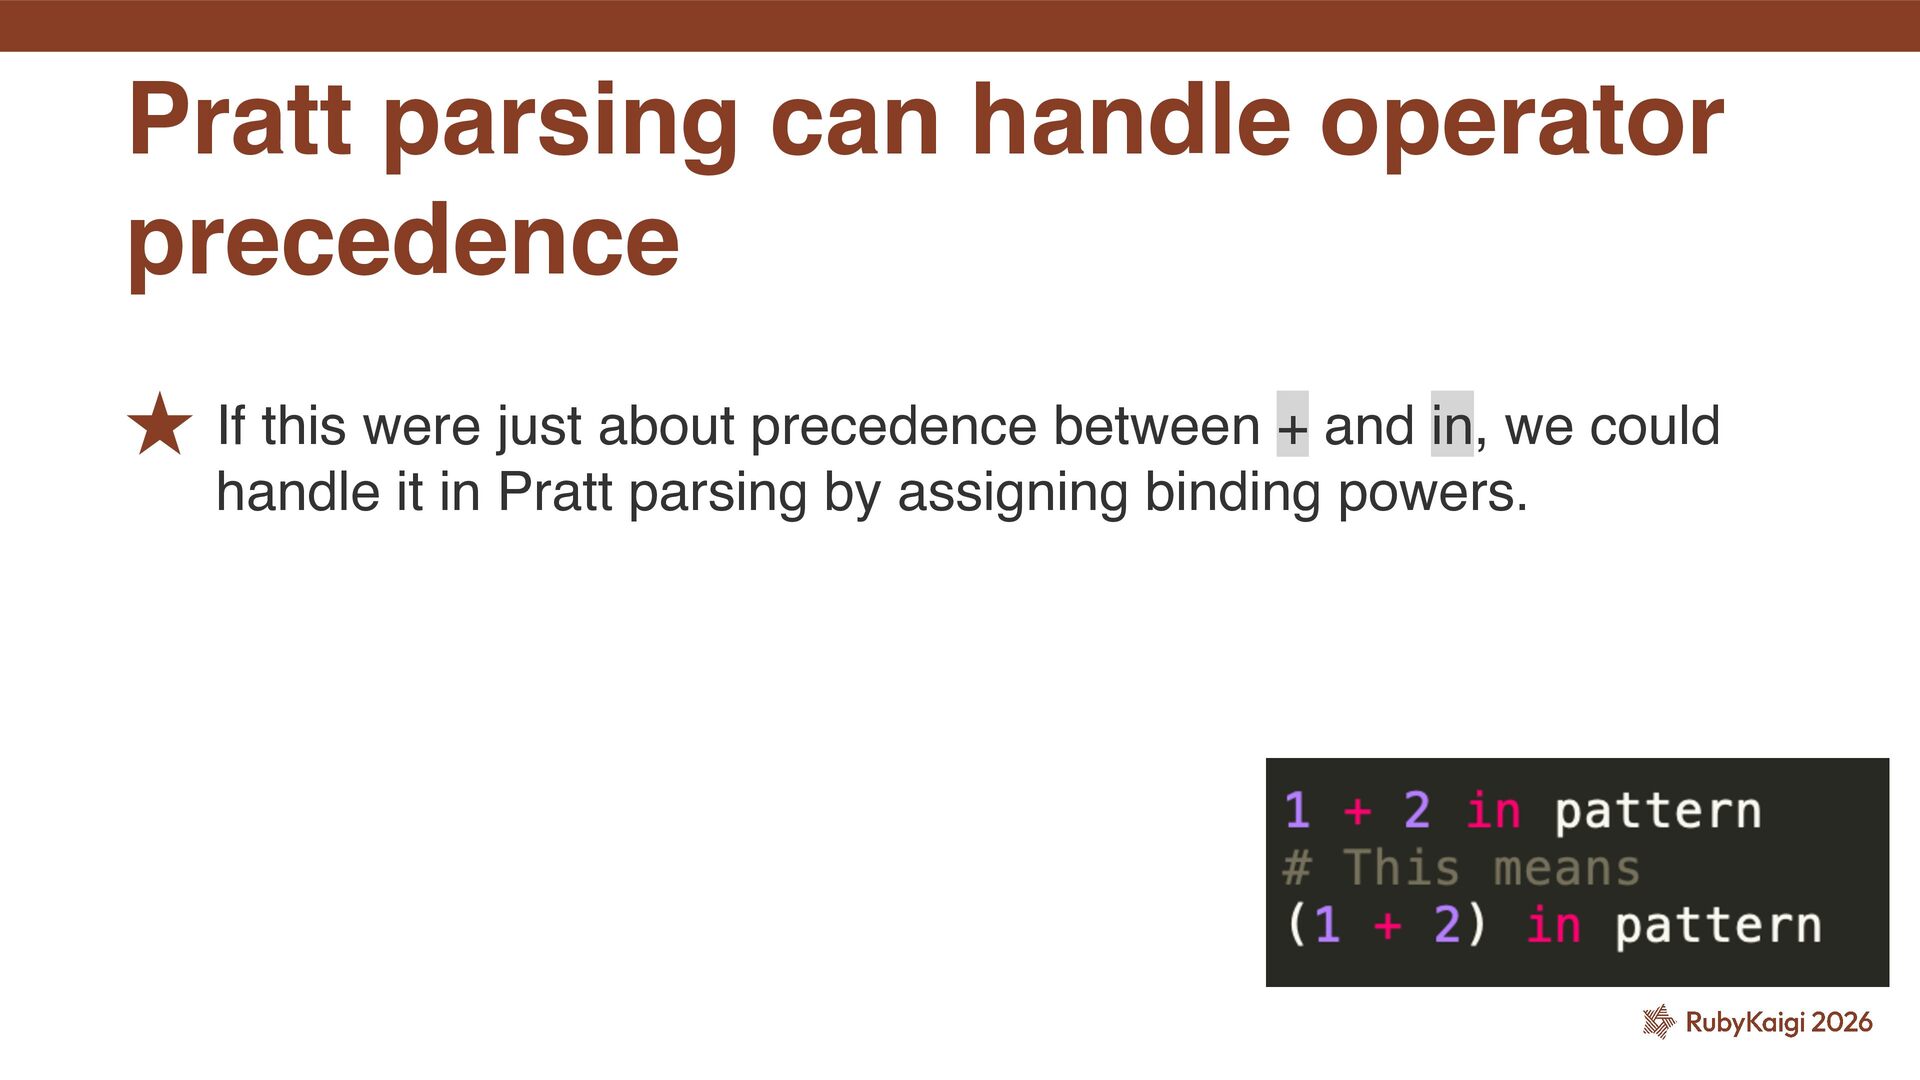
˒ If this were just about precedence between + and
in, we could handle it in Pratt parsing by assigning binding powers. Pratt parsing can handle operator precedence -
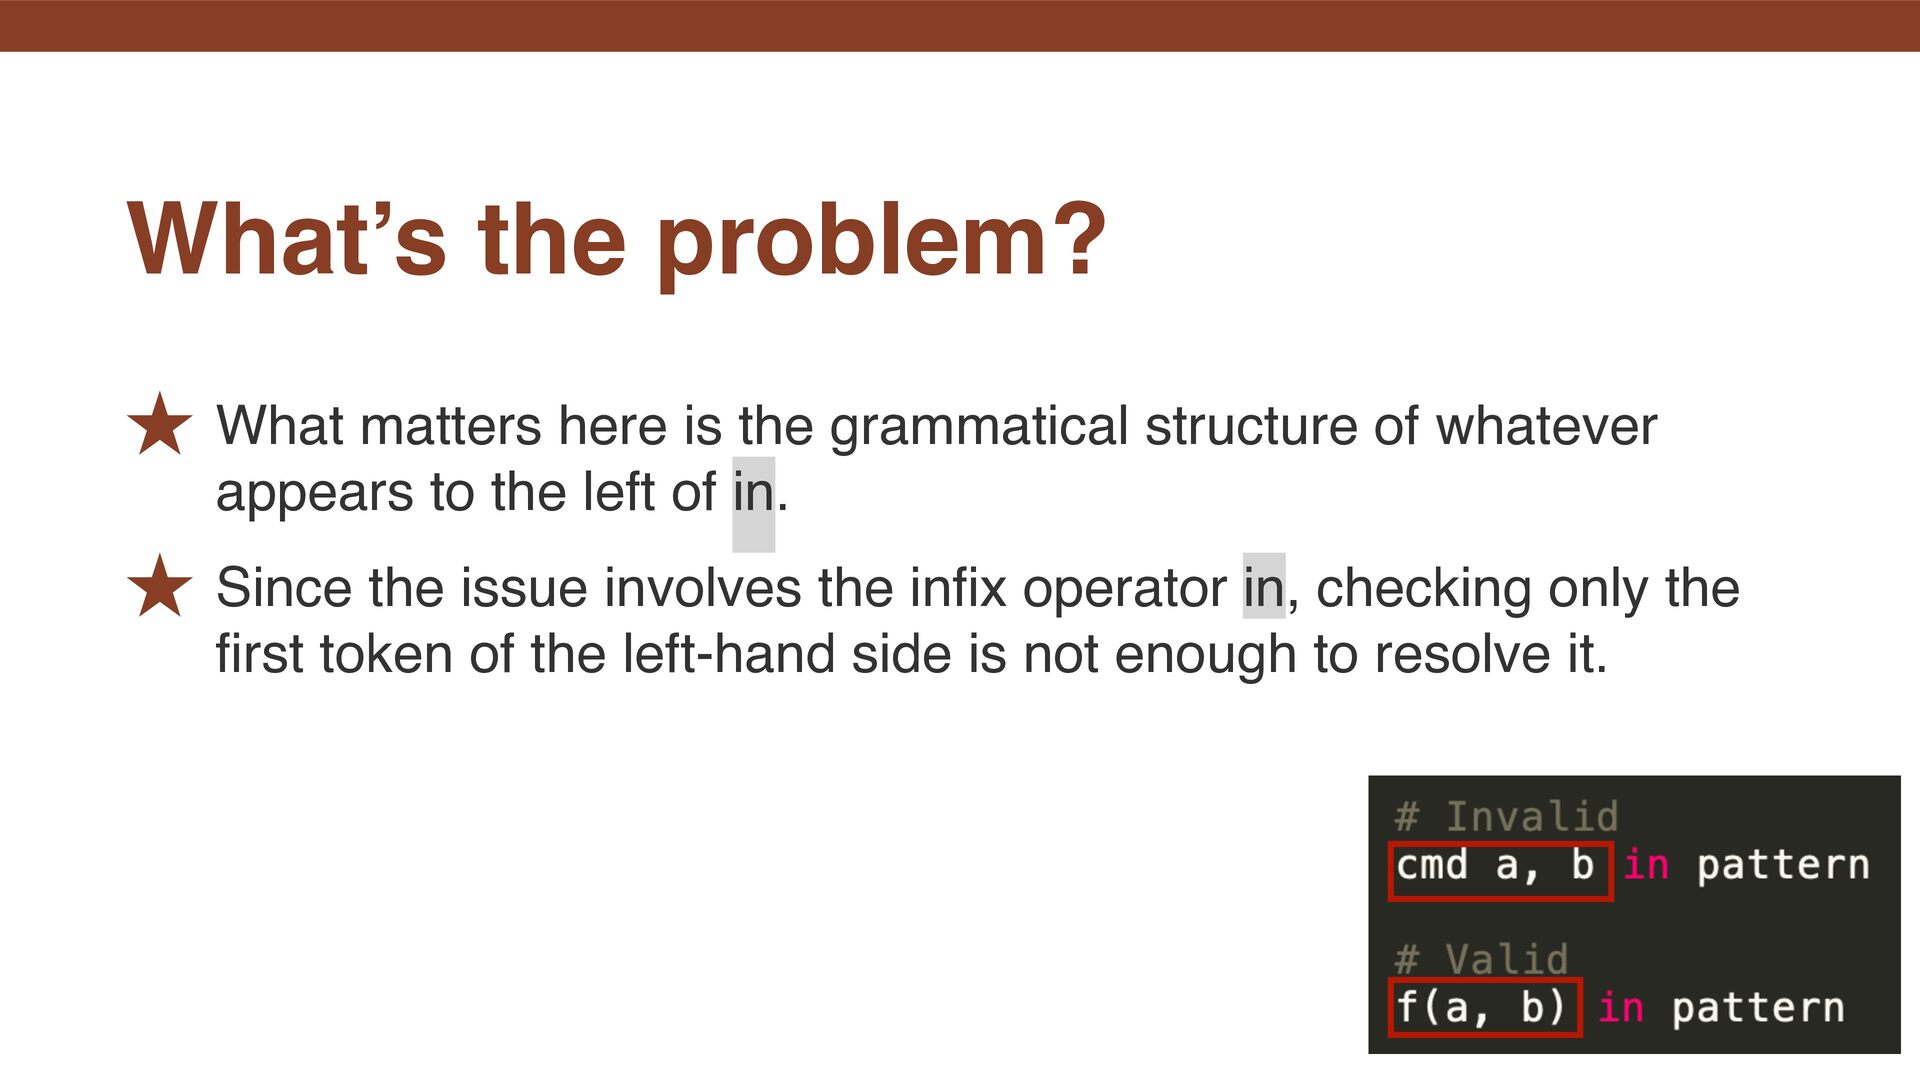
˒ What matters here is the grammatical structure of whatever
appears to the left of in. ˒ Since the issue involves the in fi x operator in, checking only the fi rst token of the left-hand side is not enough to resolve it. What’s the problem? -
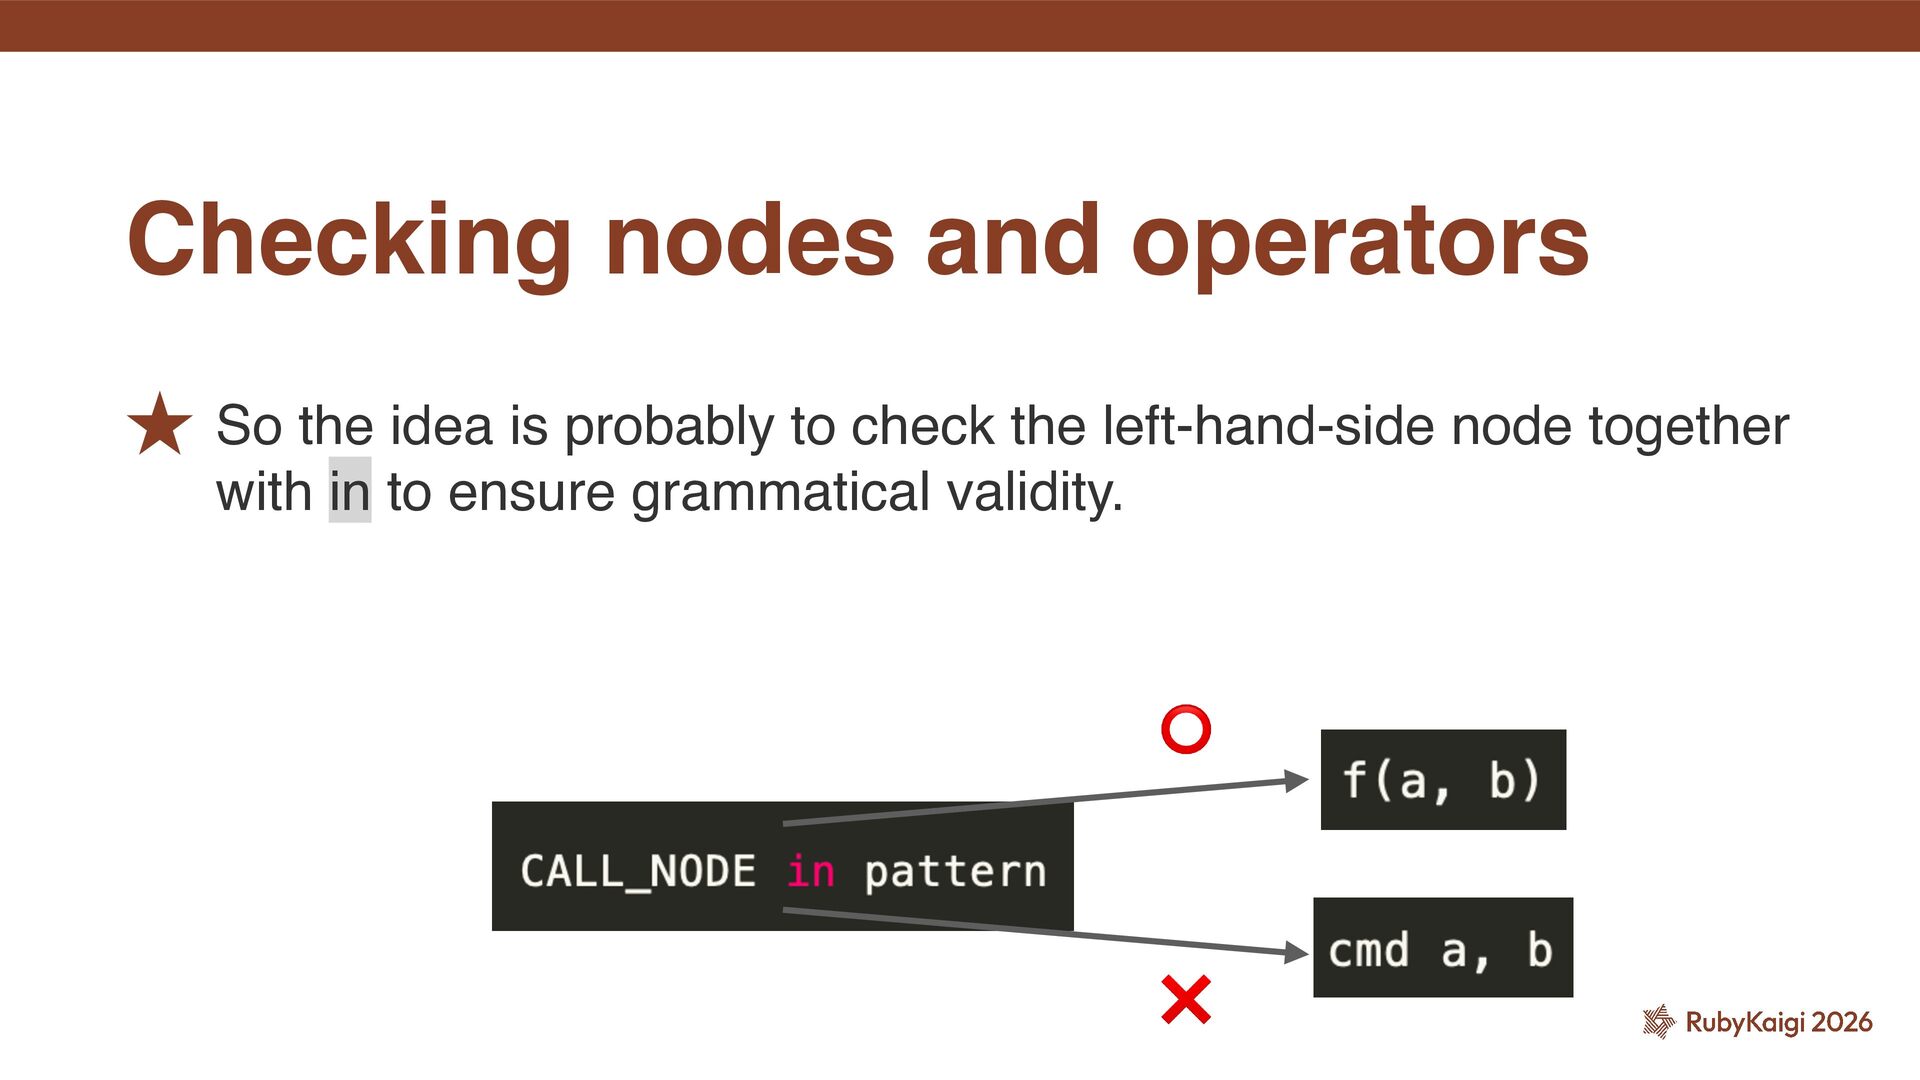
˒ So the idea is probably to check the left-hand-side
node together with in to ensure grammatical validity. Checking nodes and operators ⭕ ❌ -
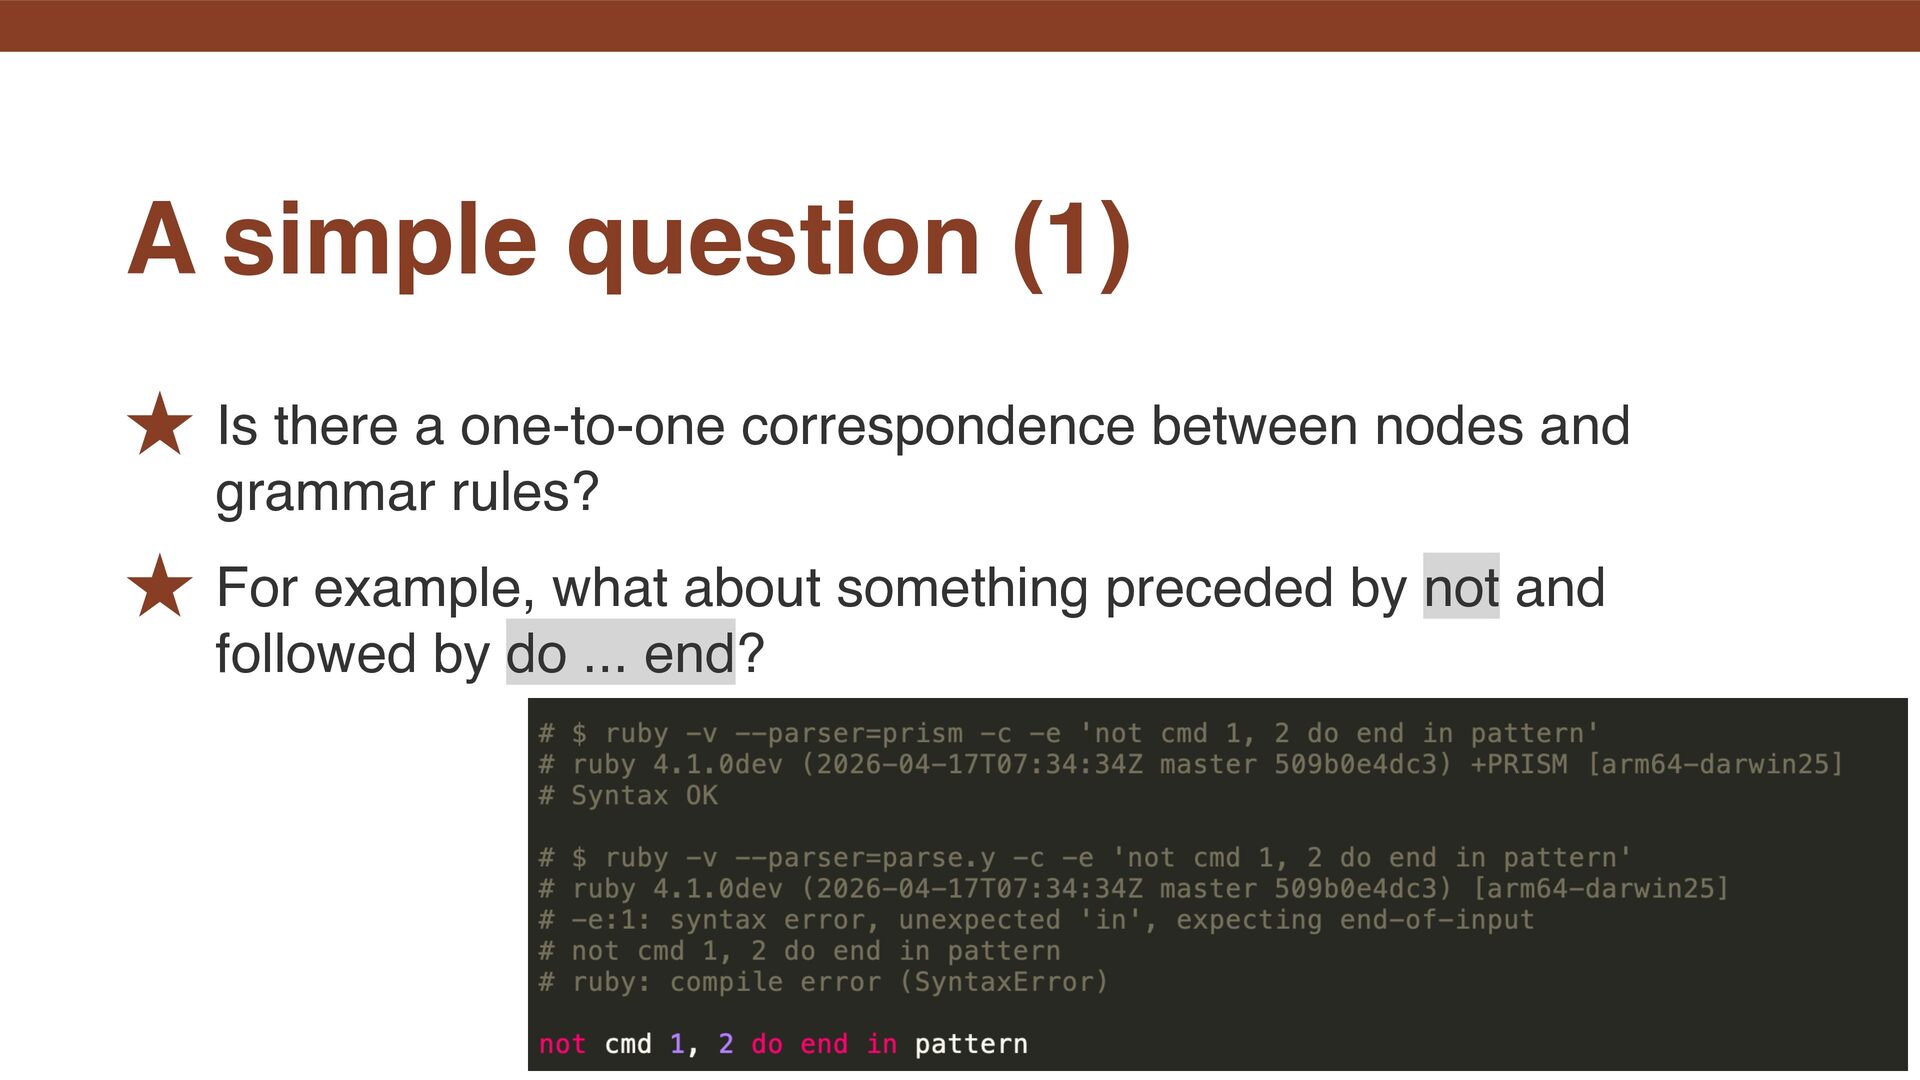
˒ Is there a one-to-one correspondence between nodes and grammar
rules? ˒ For example, what about something preceded by not and followed by do ... end? A simple question (1) -
˒ Given the vast universe of valid strings, some can
appear on the left-hand side of in and some cannot. Doesn’t this ultimately turn into a function that enumerates all the syntax trees that are not allowed there? A simple question (2) -
˒ With an LR parser, the generator just handles it,
so I do not really have to think about it. How is this handled in LR parsing? -
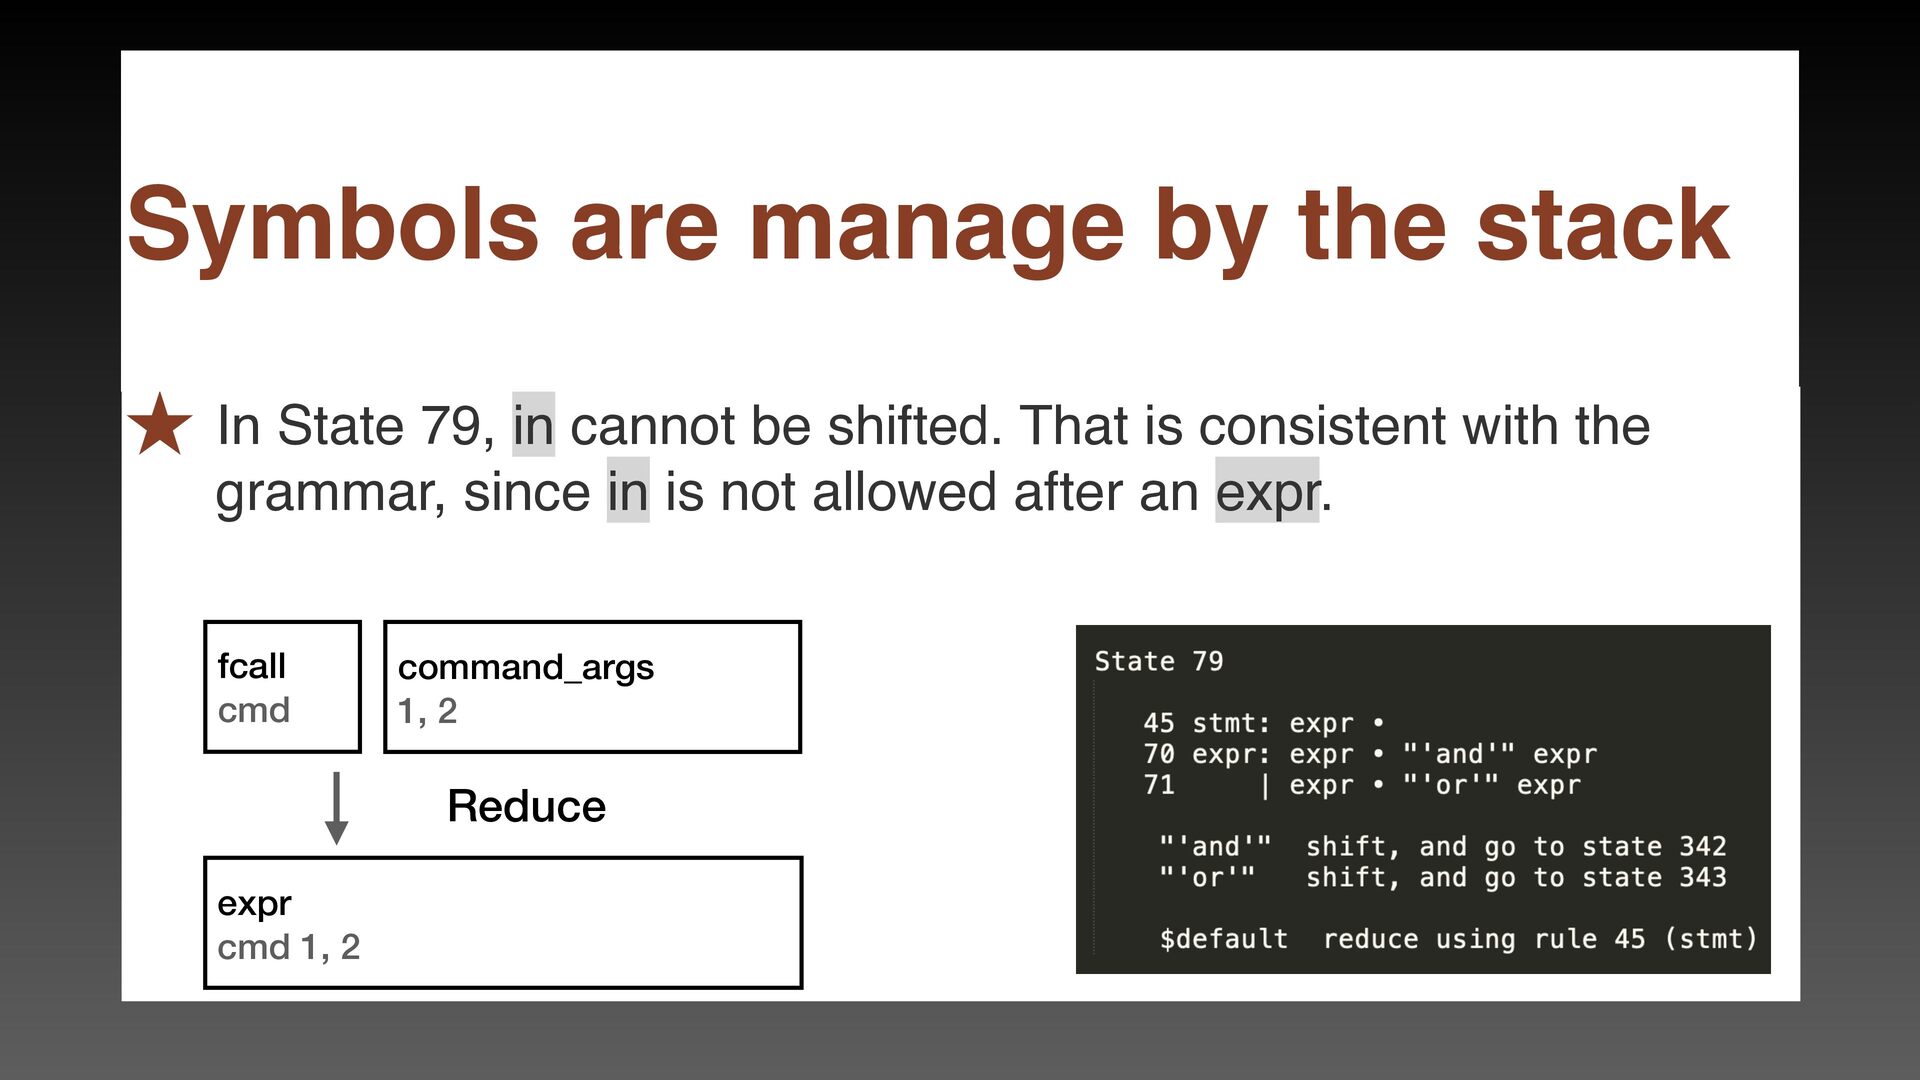
˒ In State 79, in cannot be shifted. That is
consistent with the grammar, since in is not allowed after an expr. Symbols are manage by the stack fcall cmd command_args 1, 2 expr cmd 1, 2 Reduce -
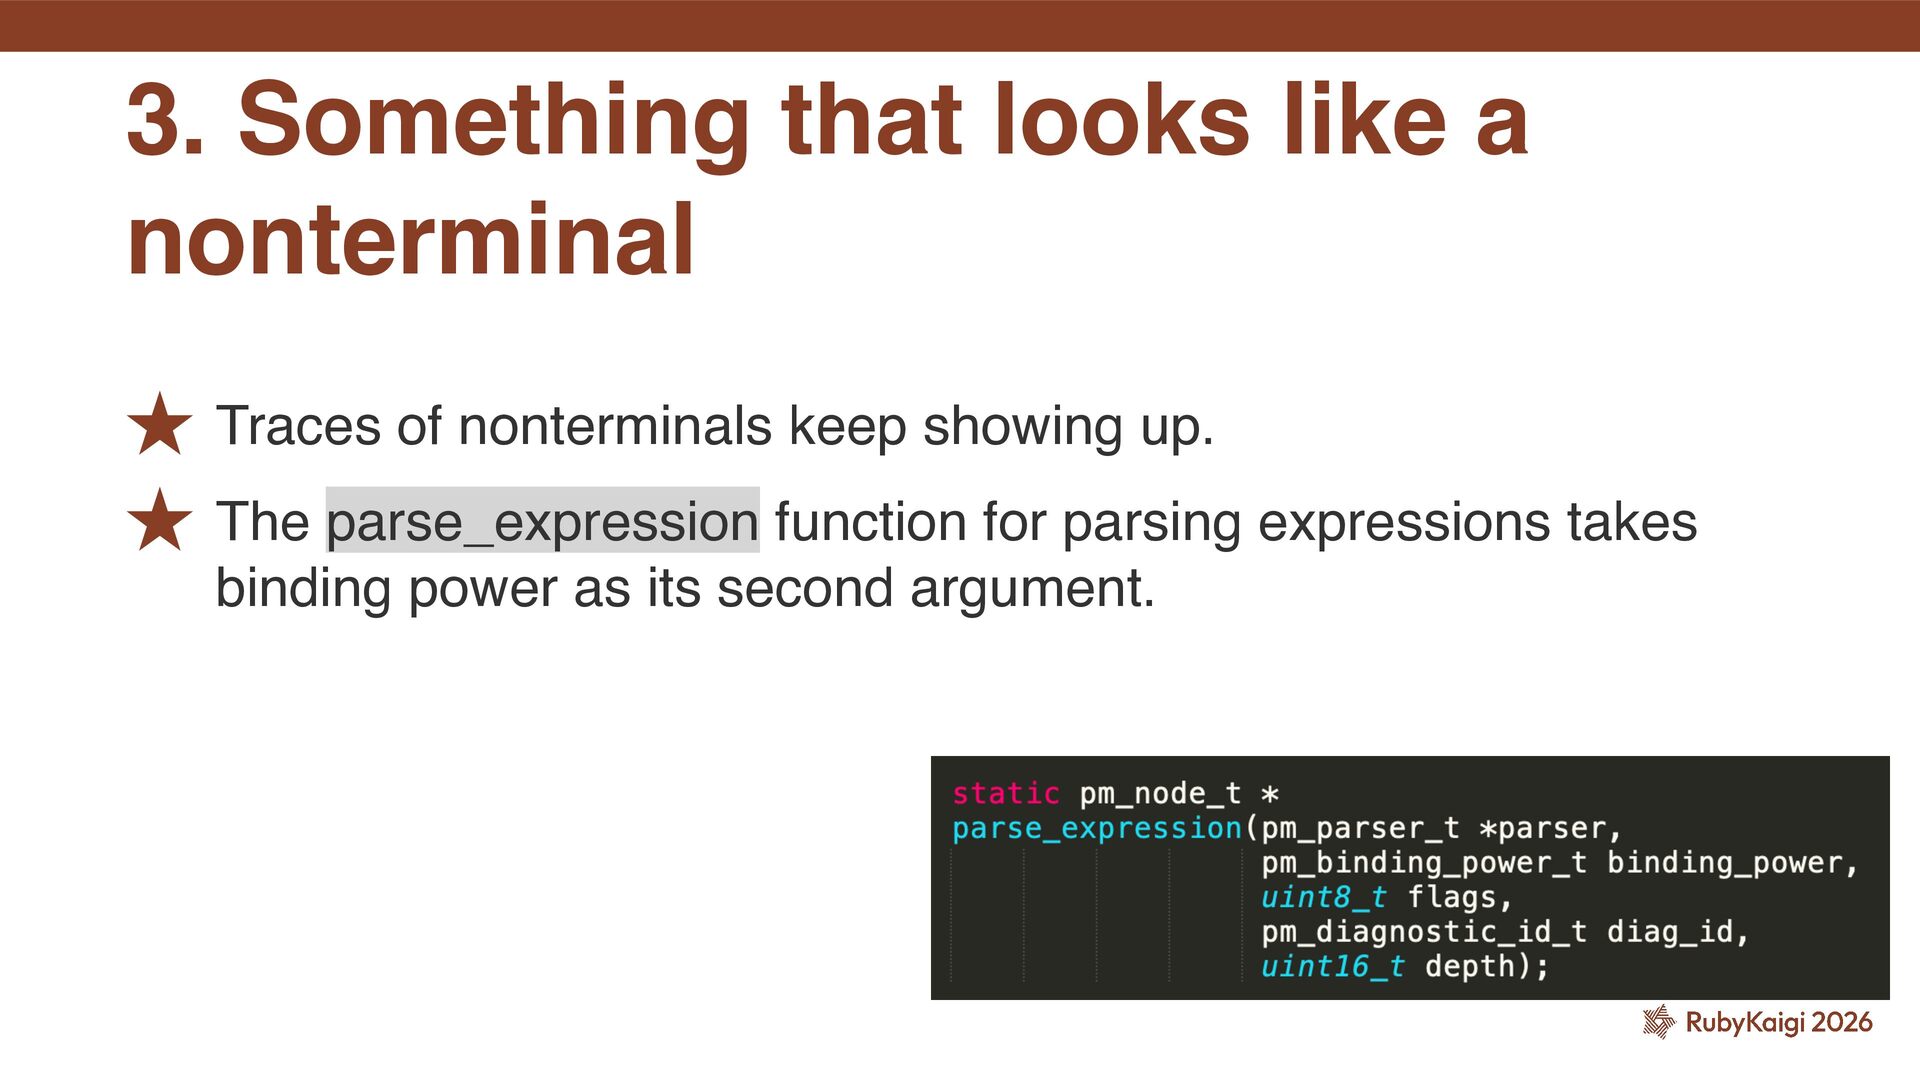
˒ Traces of nonterminals keep showing up. ˒ The parse_expression
function for parsing expressions takes binding power as its second argument. 3. Something that looks like a nonterminal -
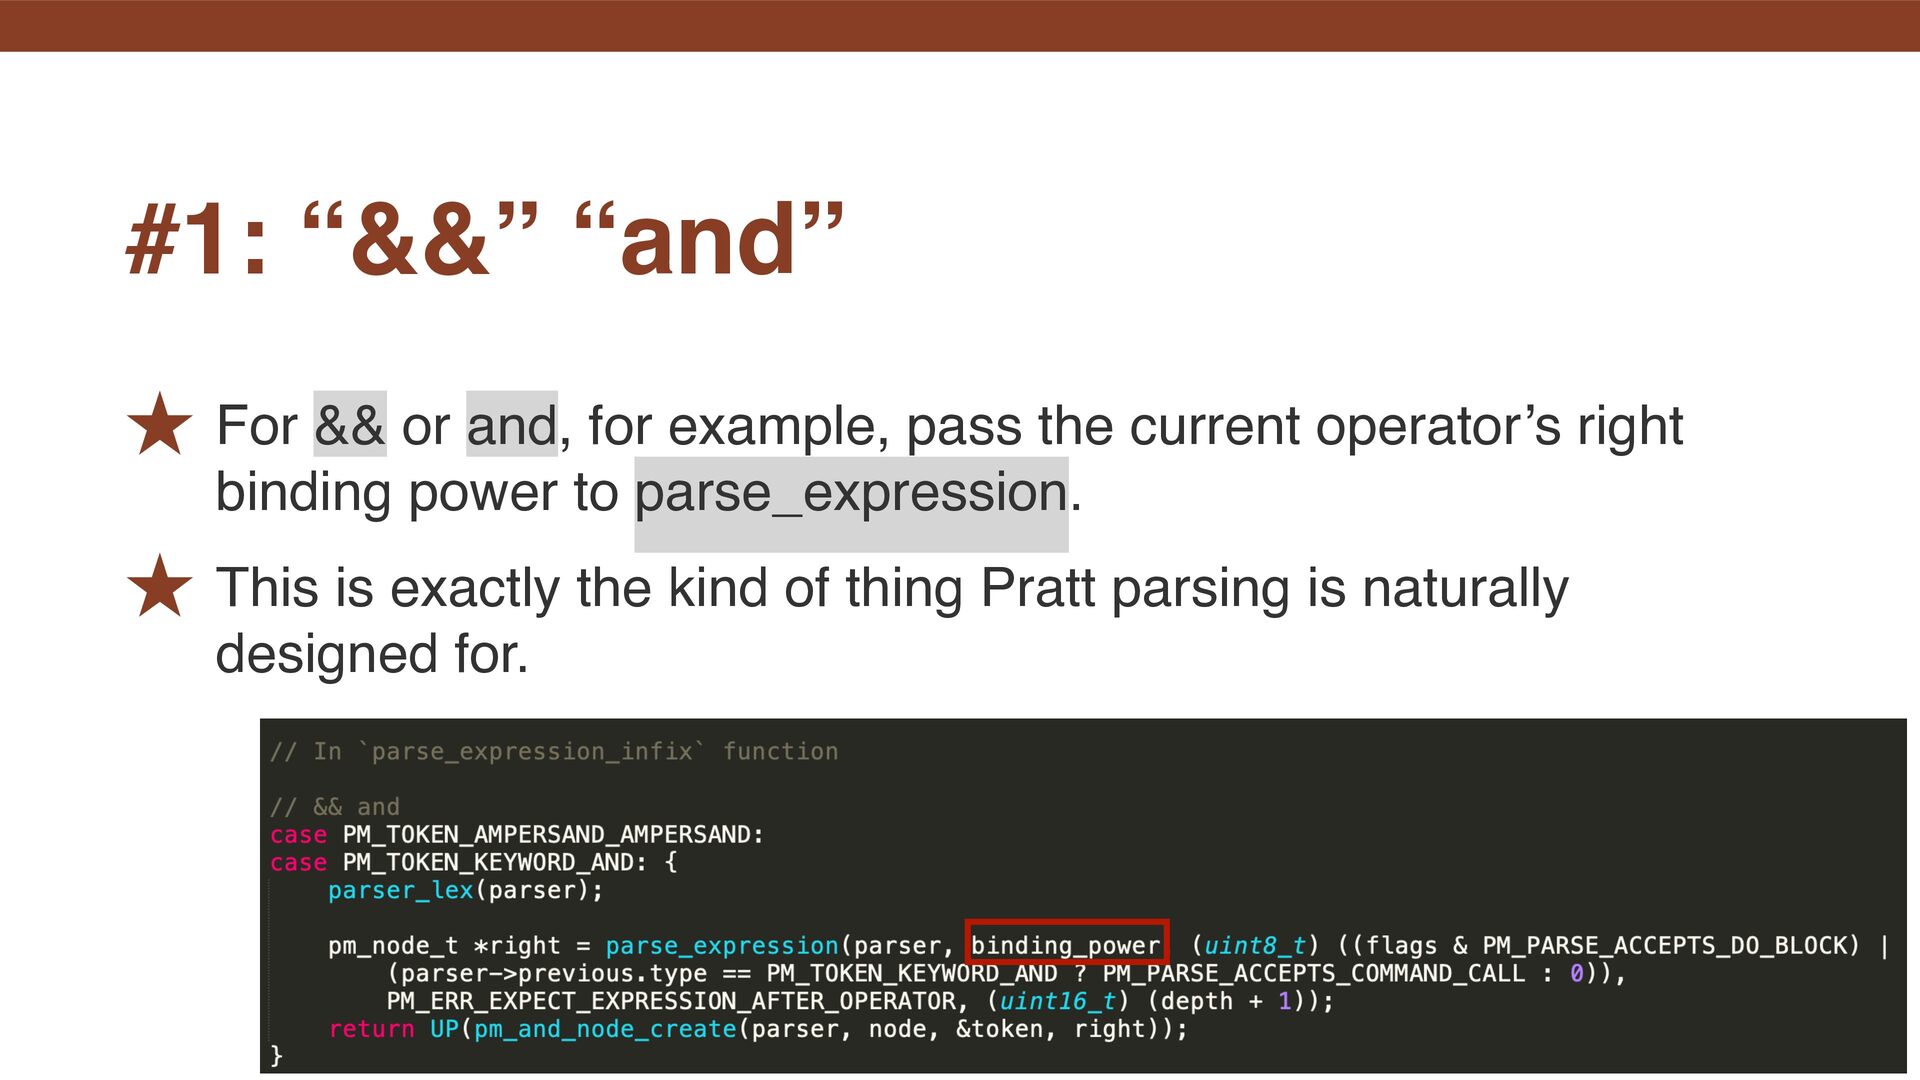
˒ For && or and, for example, pass the current
operator’s right binding power to parse_expression. ˒ This is exactly the kind of thing Pratt parsing is naturally designed for. #1: “&&” “and” -
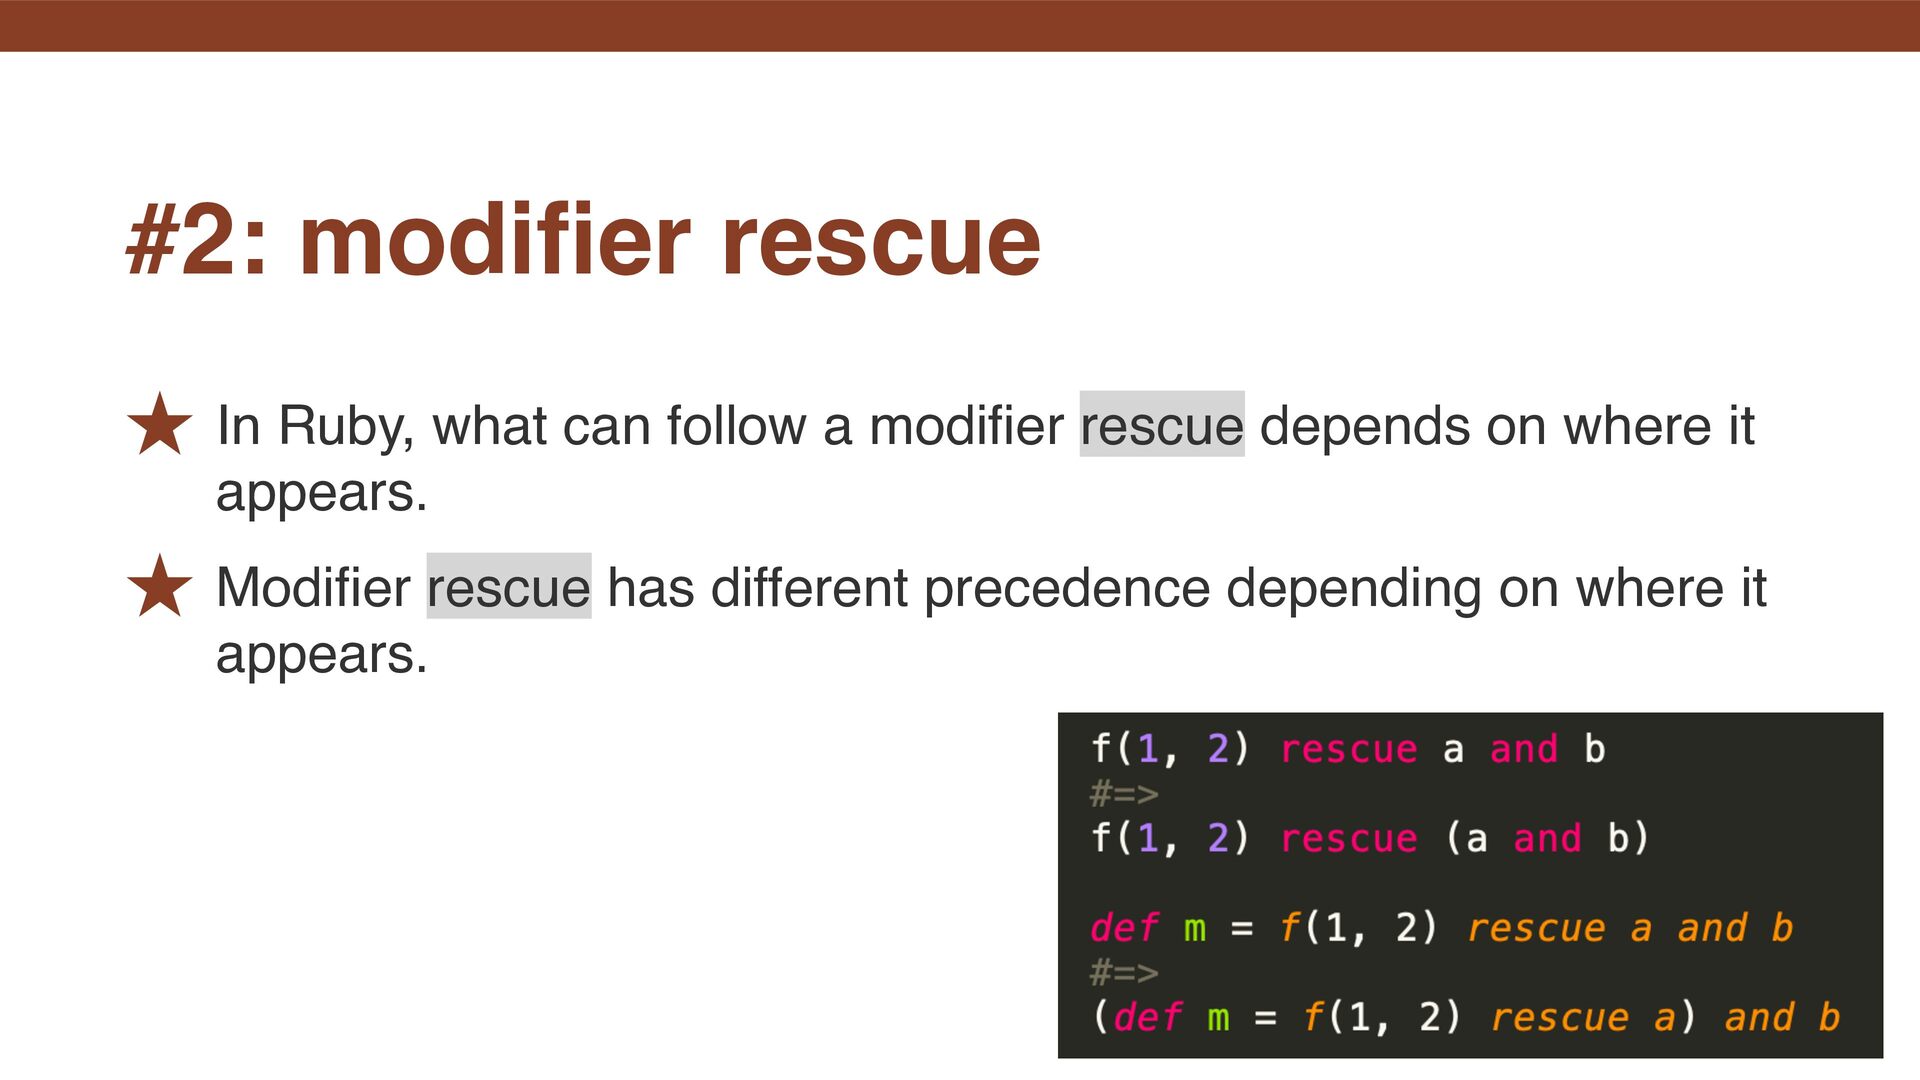
˒ In Ruby, what can follow a modi fi er
rescue depends on where it appears. ˒ Modi fi er rescue has different precedence depending on where it appears. #2: modi fi er rescue -
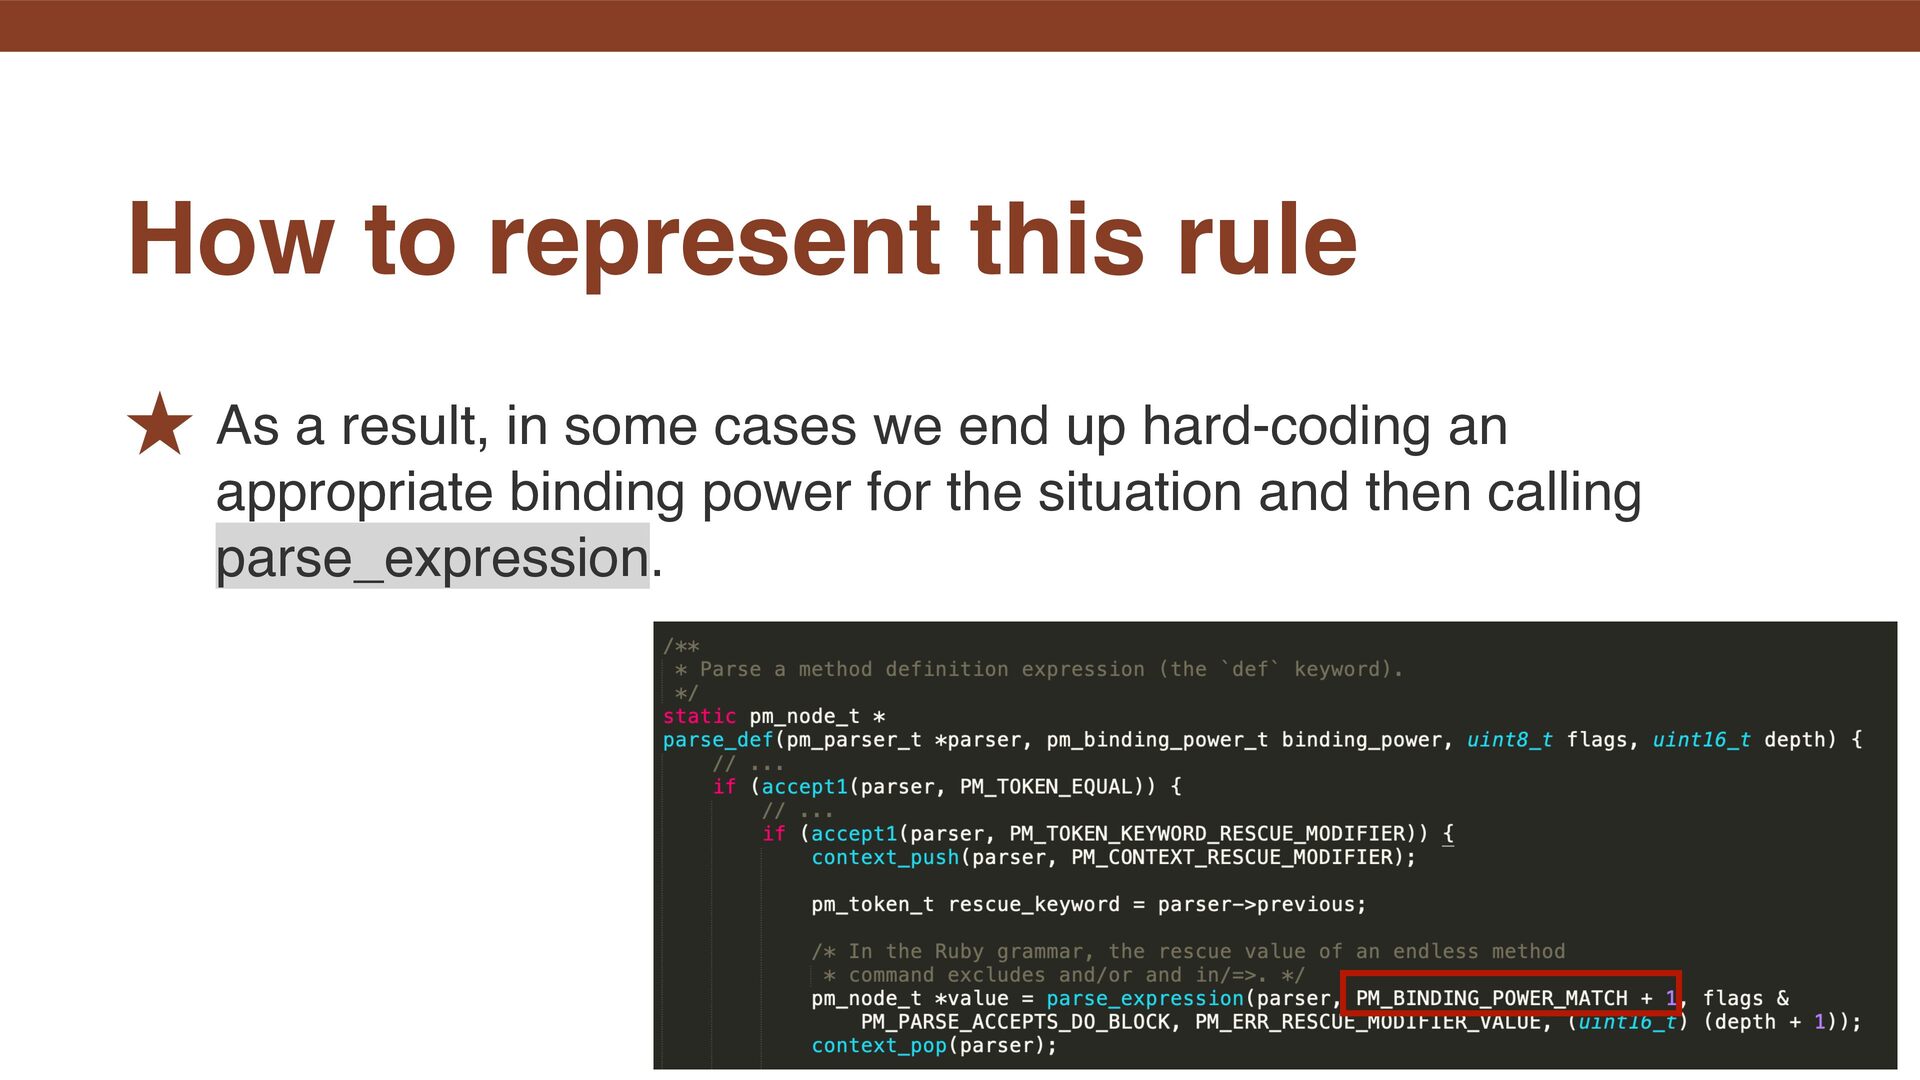
˒ As a result, in some cases we end up
hard-coding an appropriate binding power for the situation and then calling parse_expression. How to represent this rule -
˒ A Pratt parser assumes that each operator has a
single fi xed precedence within the grammar. ˒ To handle operators like modi fi er rescue, whose precedence changes depending on the situation, you need some extra mechanism outside the Pratt parser itself. ˒ From a parser-generator person’s point of view, this really starts to look like a nonterminal. Assumption -
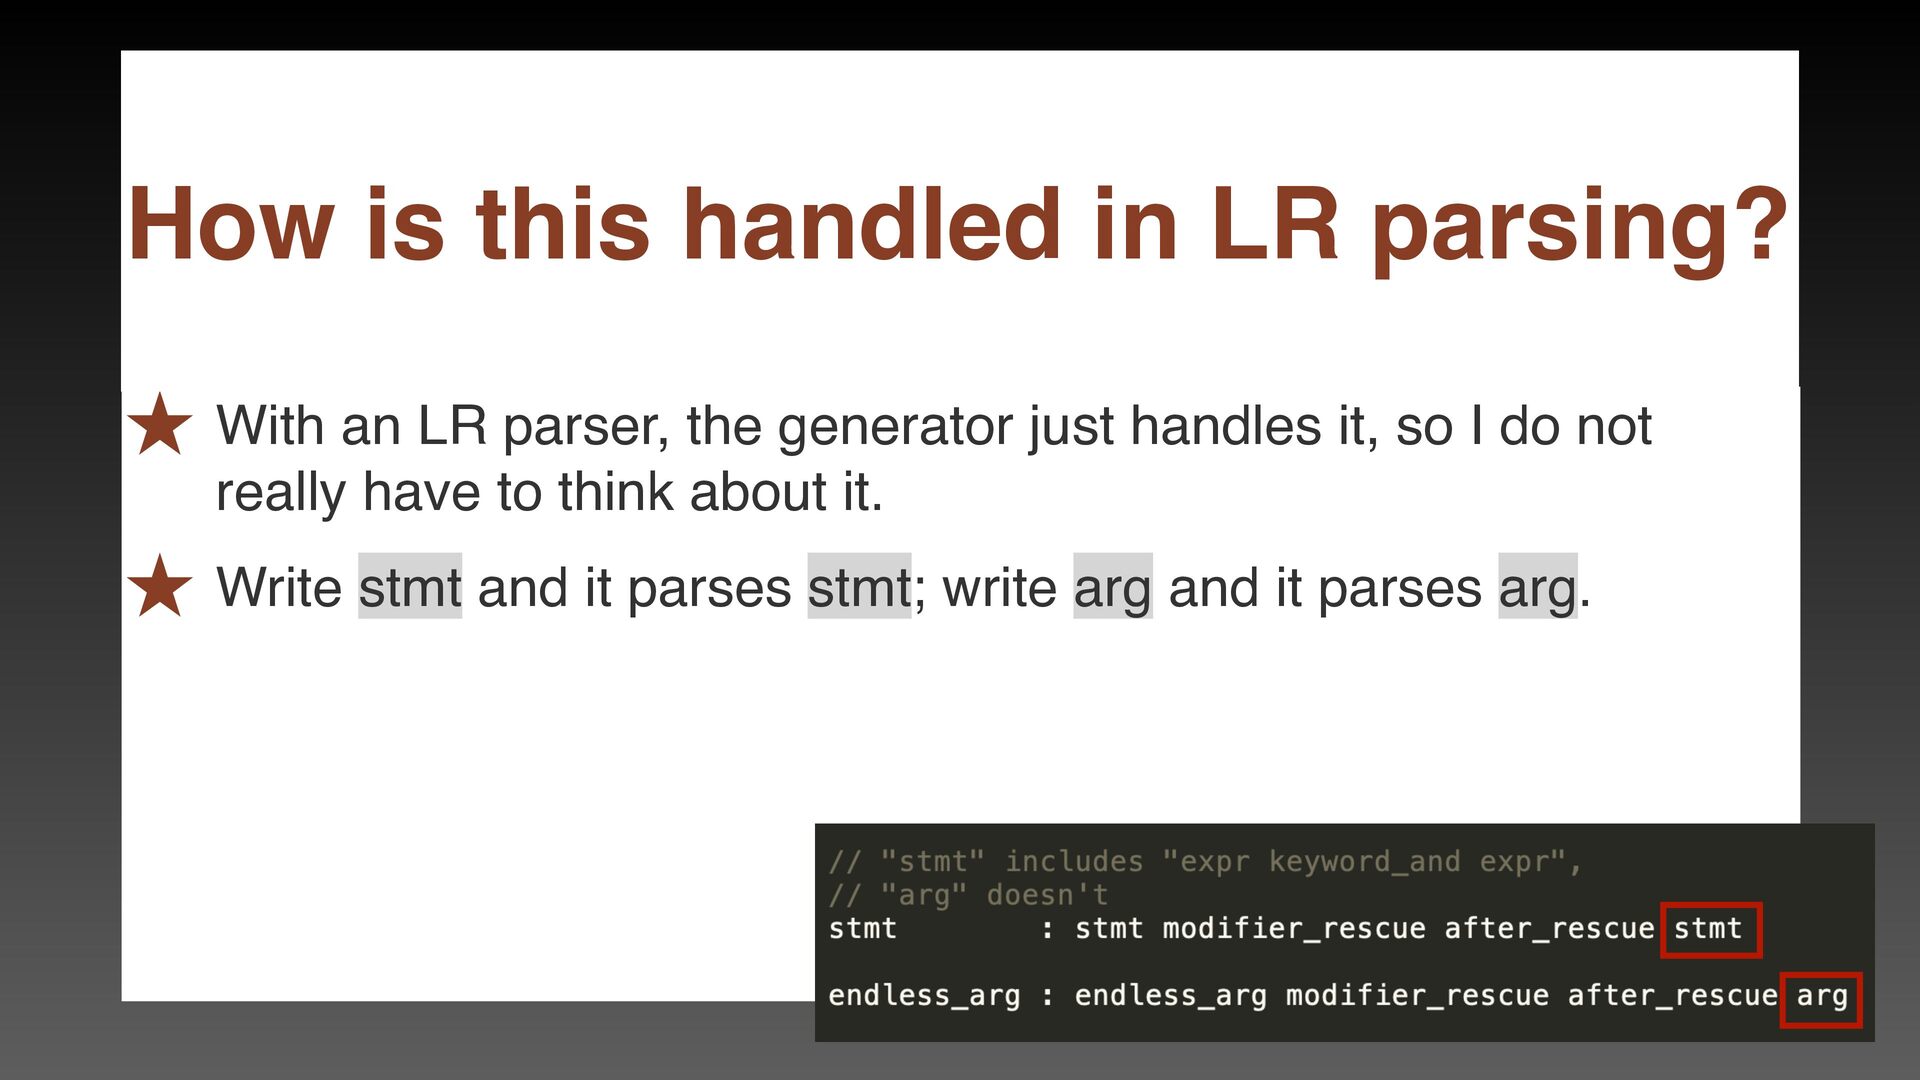
˒ With an LR parser, the generator just handles it,
so I do not really have to think about it. ˒ Write stmt and it parses stmt; write arg and it parses arg. How is this handled in LR parsing? -
˒ Knowledge speci fi c to parser generators ˒ Knowledge
speci fi c to parser ˒ Grammar knowledge of the target language Three Distinct Kinds of Knowledge -
˒ How to declare precedence, how to use %prec, and
how to read con fl ict reports and so on. ˒ This is knowledge you only need when working with parser generators. 1. Knowledge speci fi c to parser generators -
˒ How operators—especially in fi x operators—are handled, including precedence
and associativity. ˒ How to tell whether a token can start an expression ˒ How to determine where an expression ends 2. Knowledge speci fi c to parser -
˒ For operators, you need to understand how Pratt parsing
works. ˒ You may also need to understand functions like token_begins_expression_p and parse_expression_terminator. ˒ My personal impression is that Pratt parsing has a fairly narrow scope: it really only handles operators. As a result, you have to face the problem of how to design everything outside that scope, and what makes it dif fi cult is that those parts tend to become highly language-speci fi c. With a hand-written parser. -
˒ You normally do not have to think about this
when things are going well, but you may still need this kind of knowledge when investigating the cause of a con fl ict. ˒ Of course, anyone implementing a parser generator is expected to have a solid understanding of parsing. ˒ But that’s part of the fun, isn’t it? With parser generators -
˒ What can and cannot appear in each grammatical position.
˒ For an ambiguous grammar, what choices were made to resolve the ambiguity. ˒ This is necessary whether the parser is hand-written or built with a parser generator. 3. Grammar knowledge of the target language -
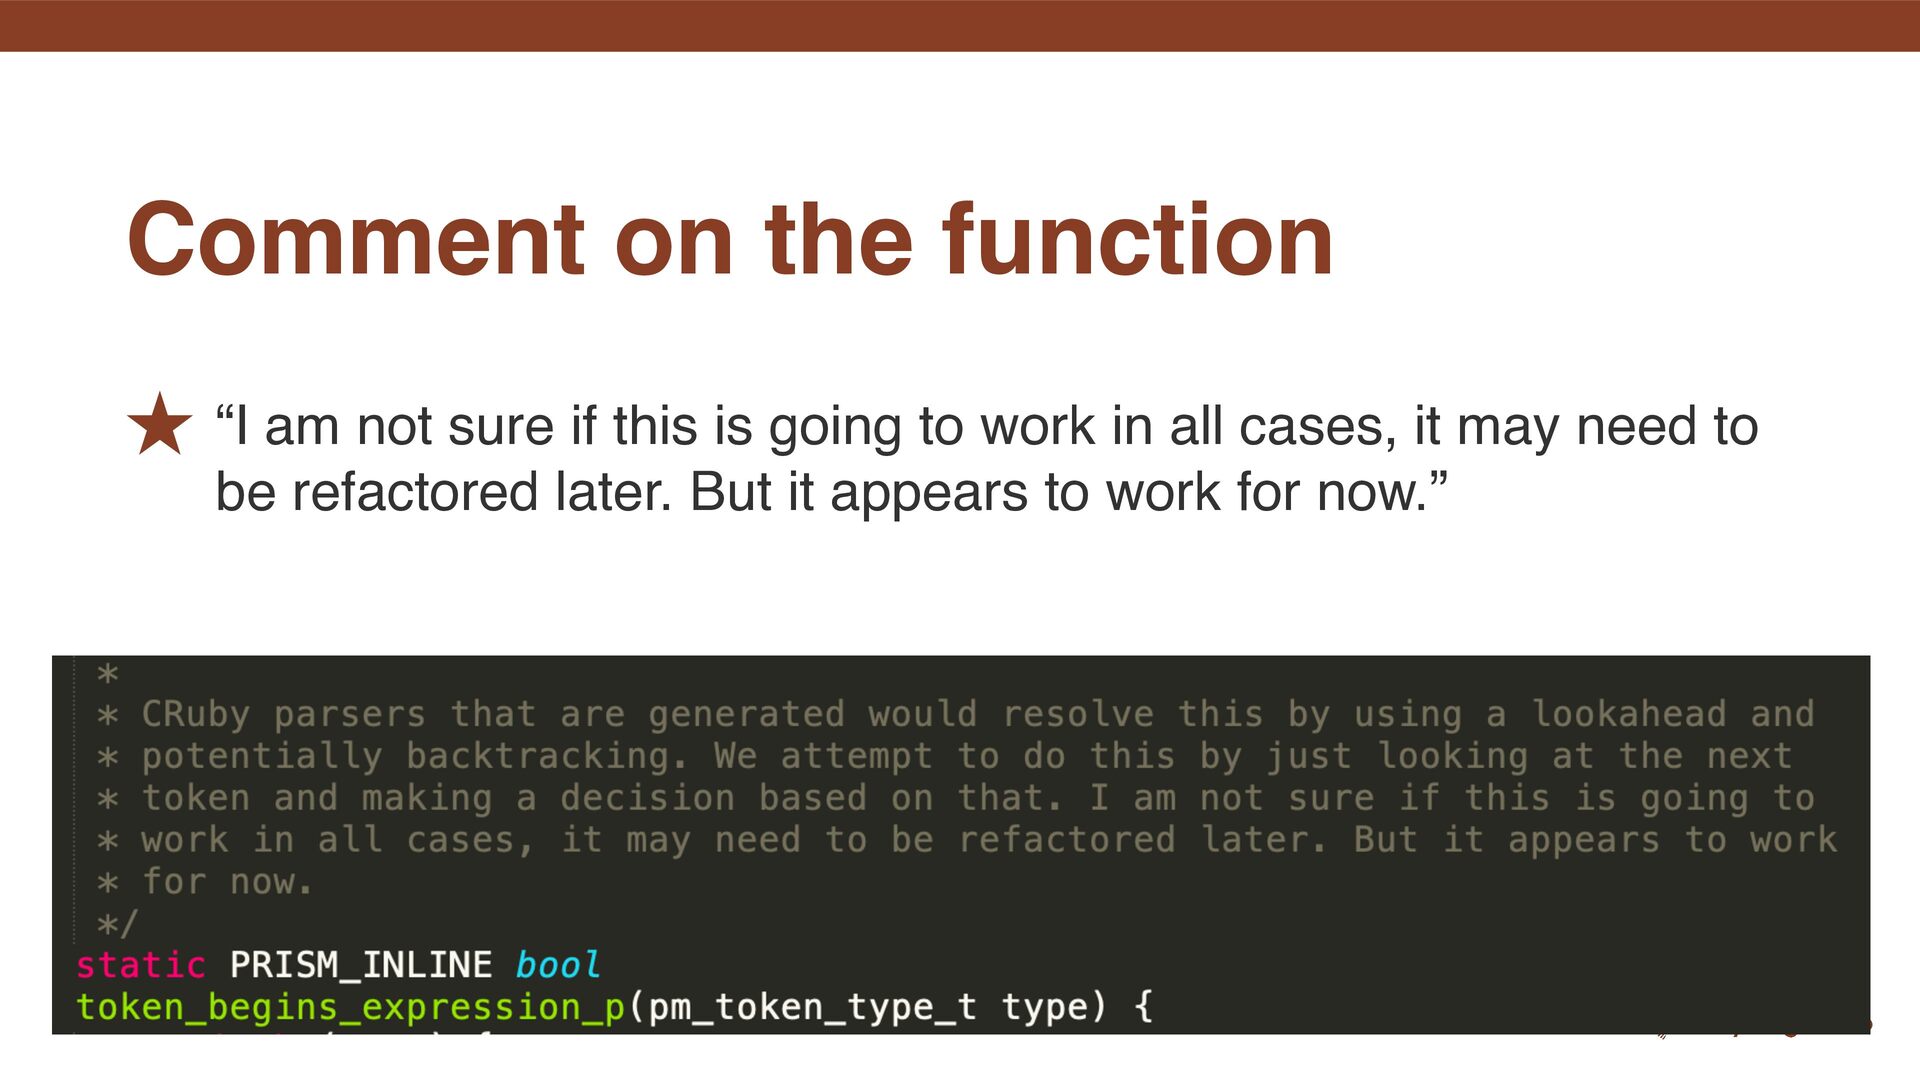
˒ “I am not sure if this is going to
work in all cases, it may need to be refactored later. But it appears to work for now.” Comment on the function -
˒ There are always some people who want to add
new grammar. ˒ One of the points that comes up in such discussions is whether adding that grammar is syntactically sound. ˒ In other words, whether it introduces ambiguity. ˒ At the same time, this also leads to discussions about how far such additions can go. Grammar is a living thing -
˒ That naturally raises the question: how do languages with
hand- written parsers verify ambiguity? ˒ You think it’s a stretch to make the parser responsible for feedback on new grammar? ˒ Perhaps. But surely it remains the case that someone, somewhere, must do it, does it not? Grammar is a living thing -
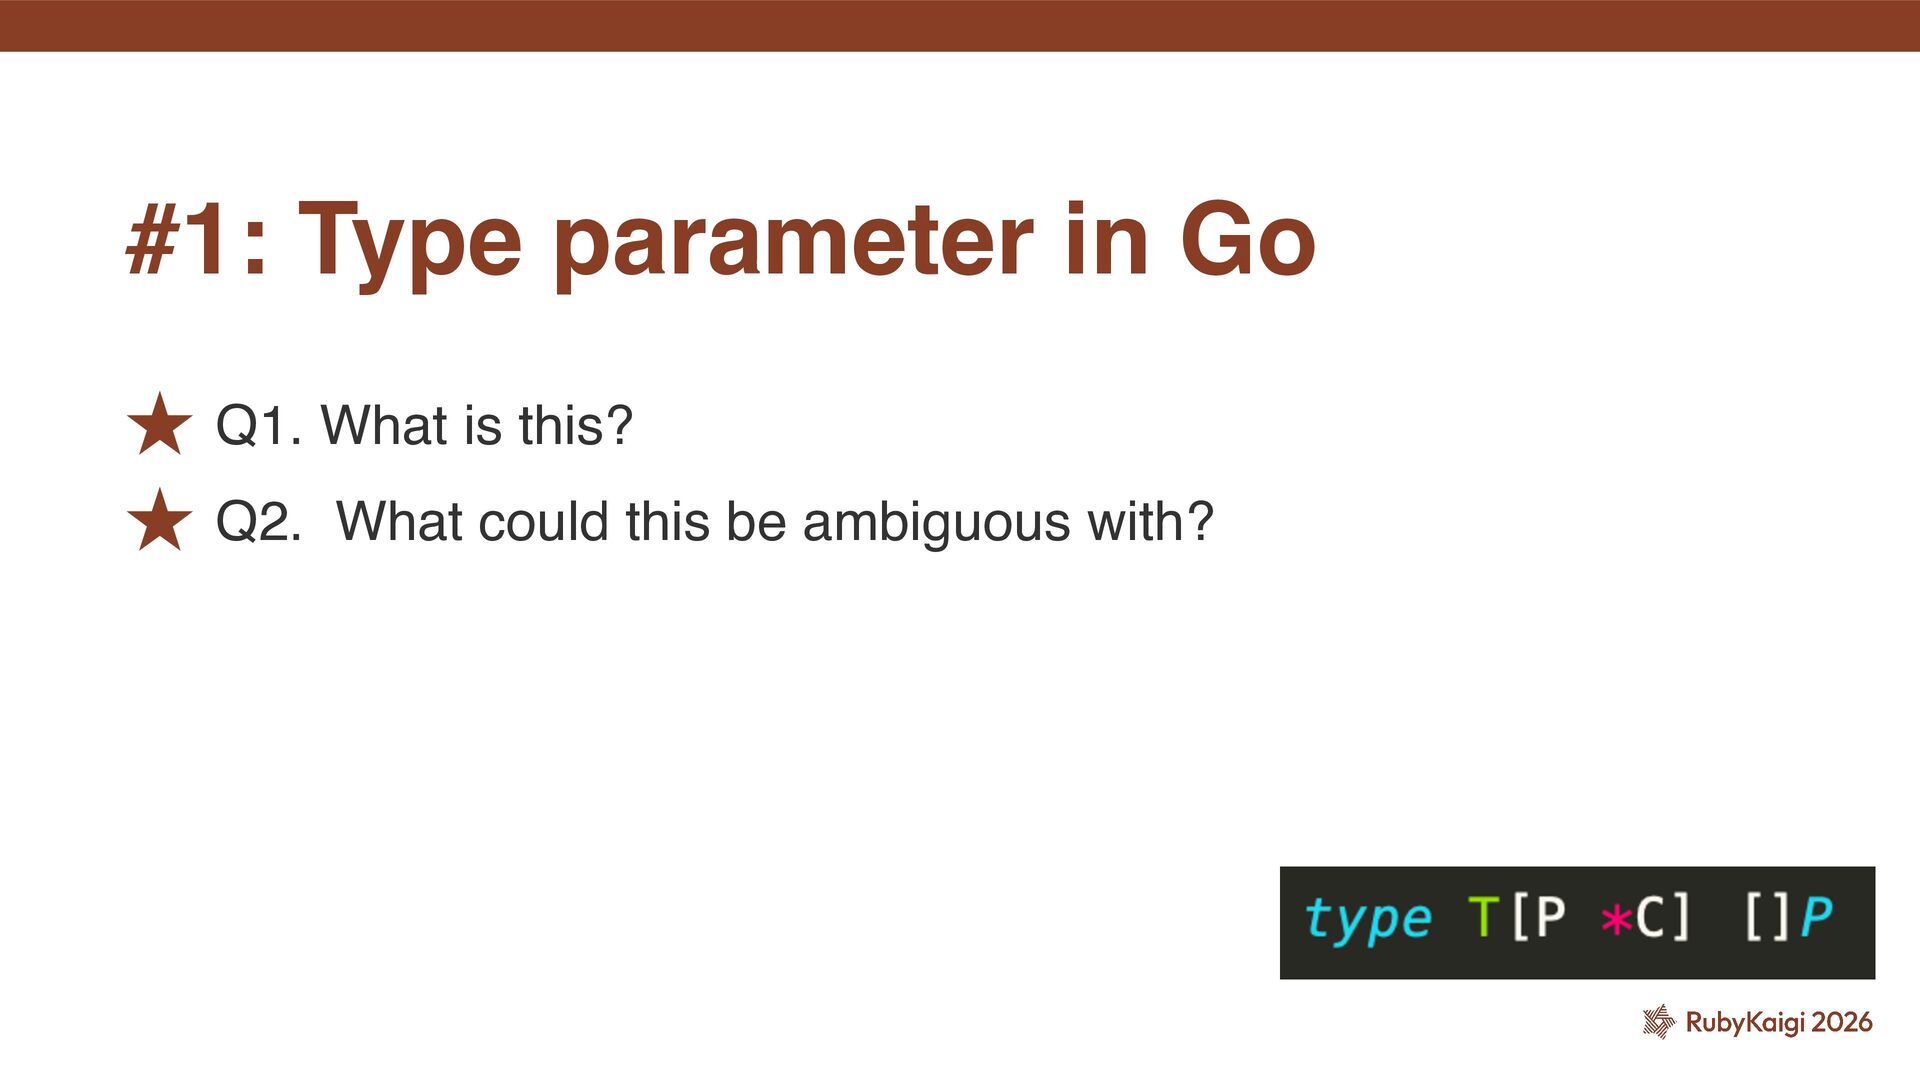
˒ Q1. What is this? ˒ Q2. What could this
be ambiguous with? #1: Type parameter in Go -
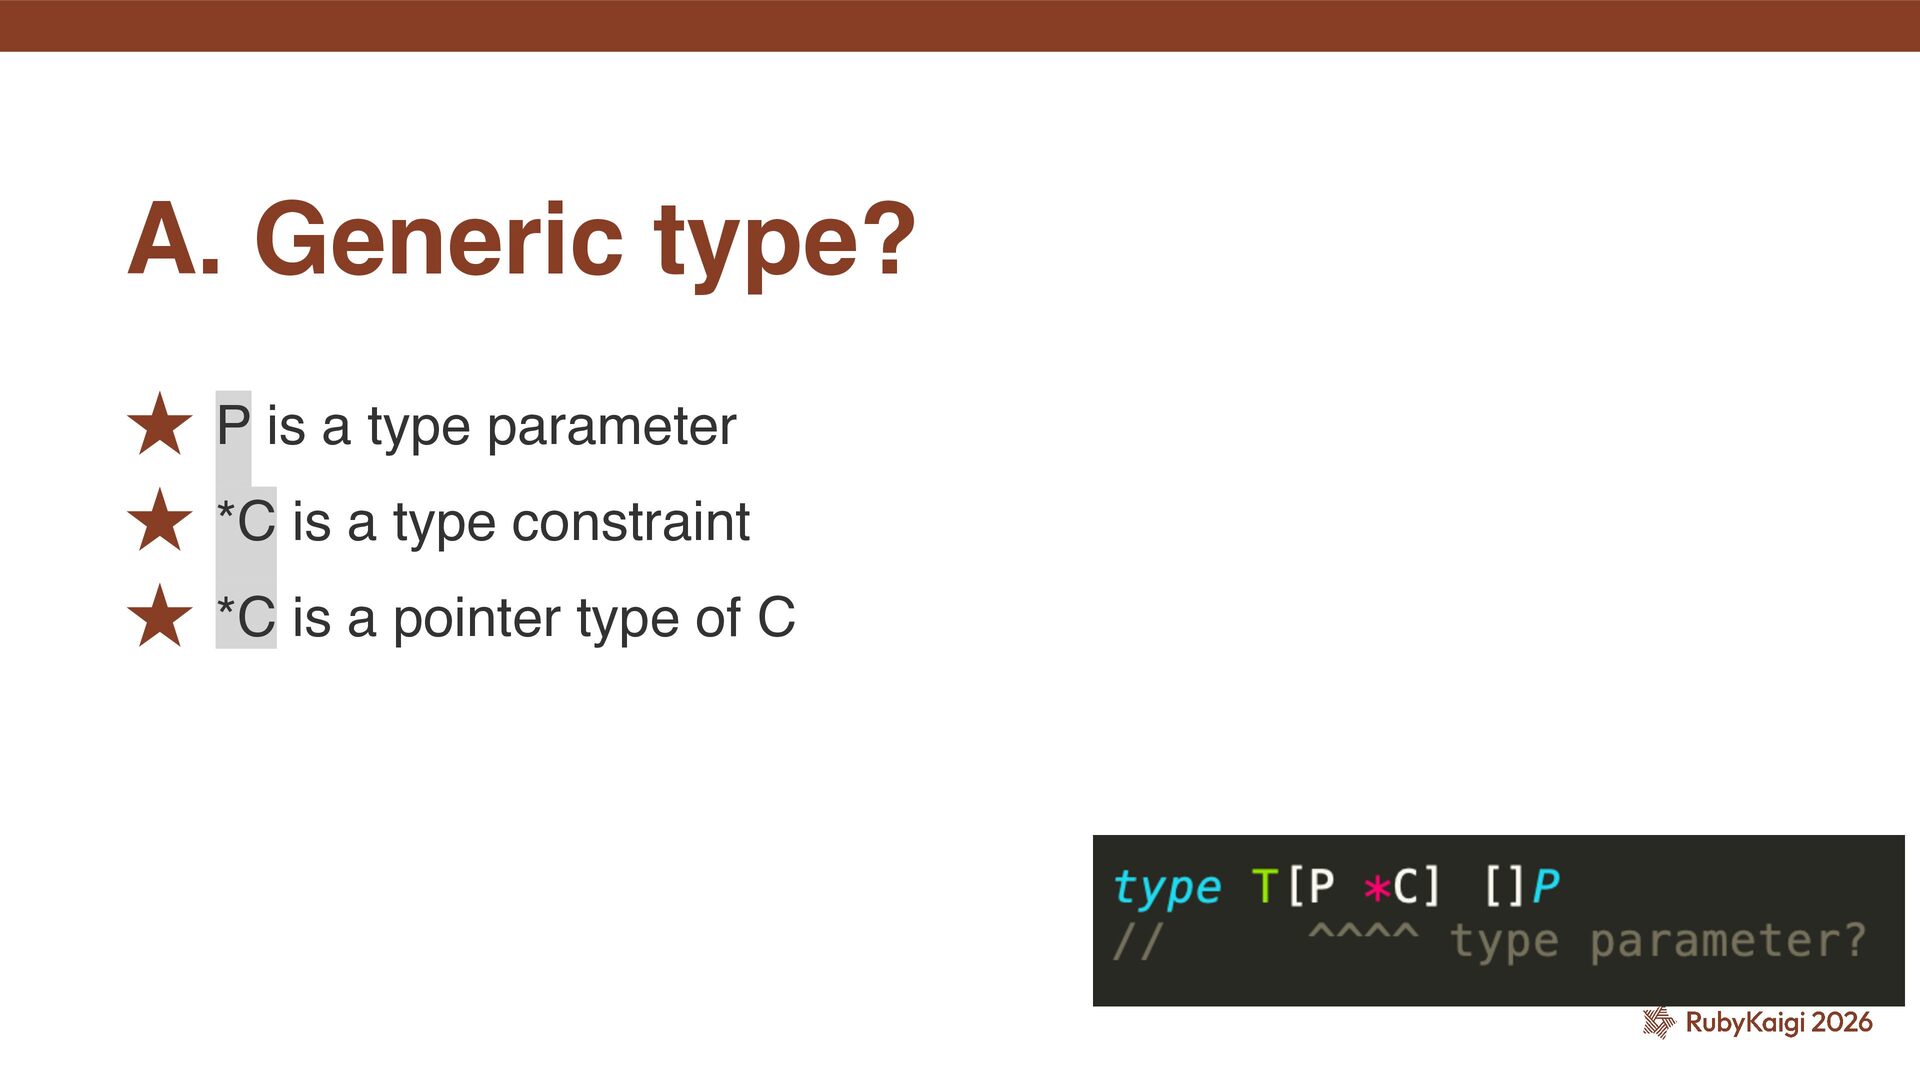
˒ P is a type parameter ˒ *C is a
type constraint ˒ *C is a pointer type of C A. Generic type? -
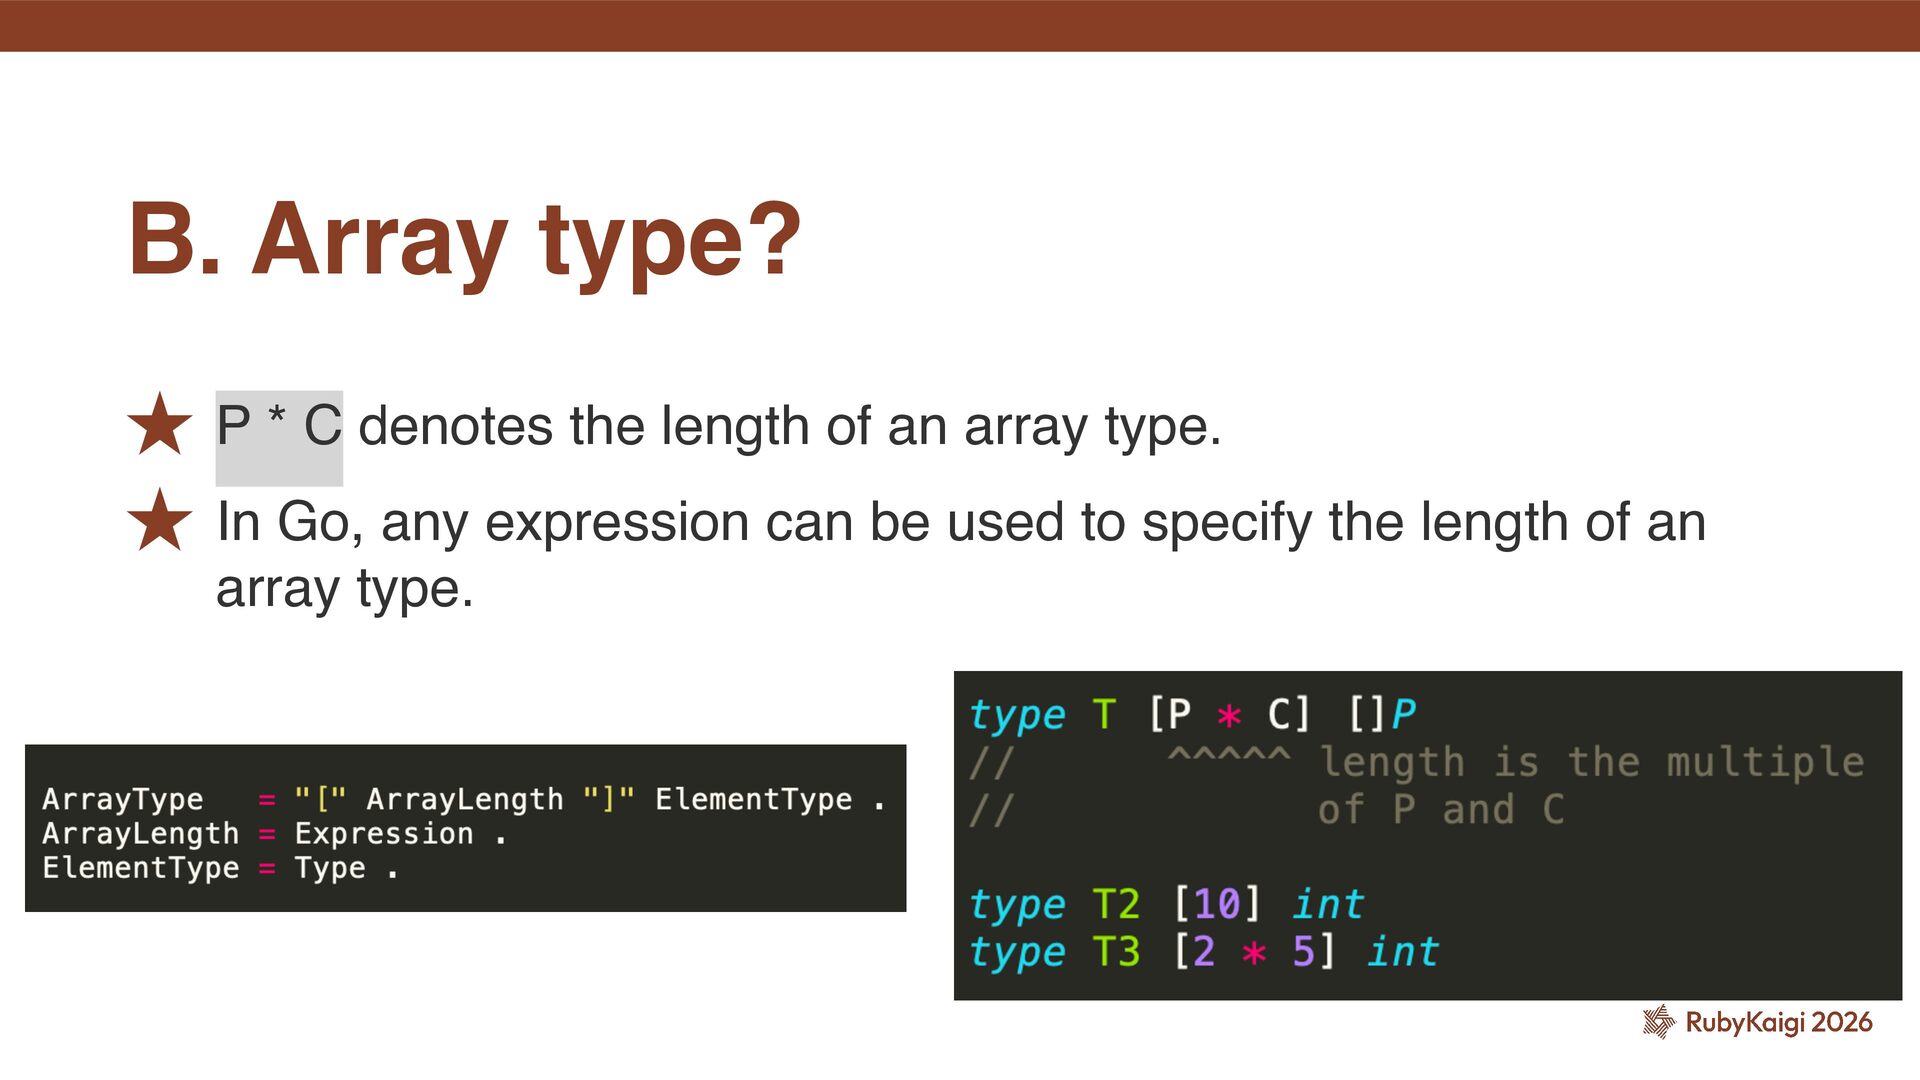
˒ P * C denotes the length of an array
type. ˒ In Go, any expression can be used to specify the length of an array type. B. Array type? -
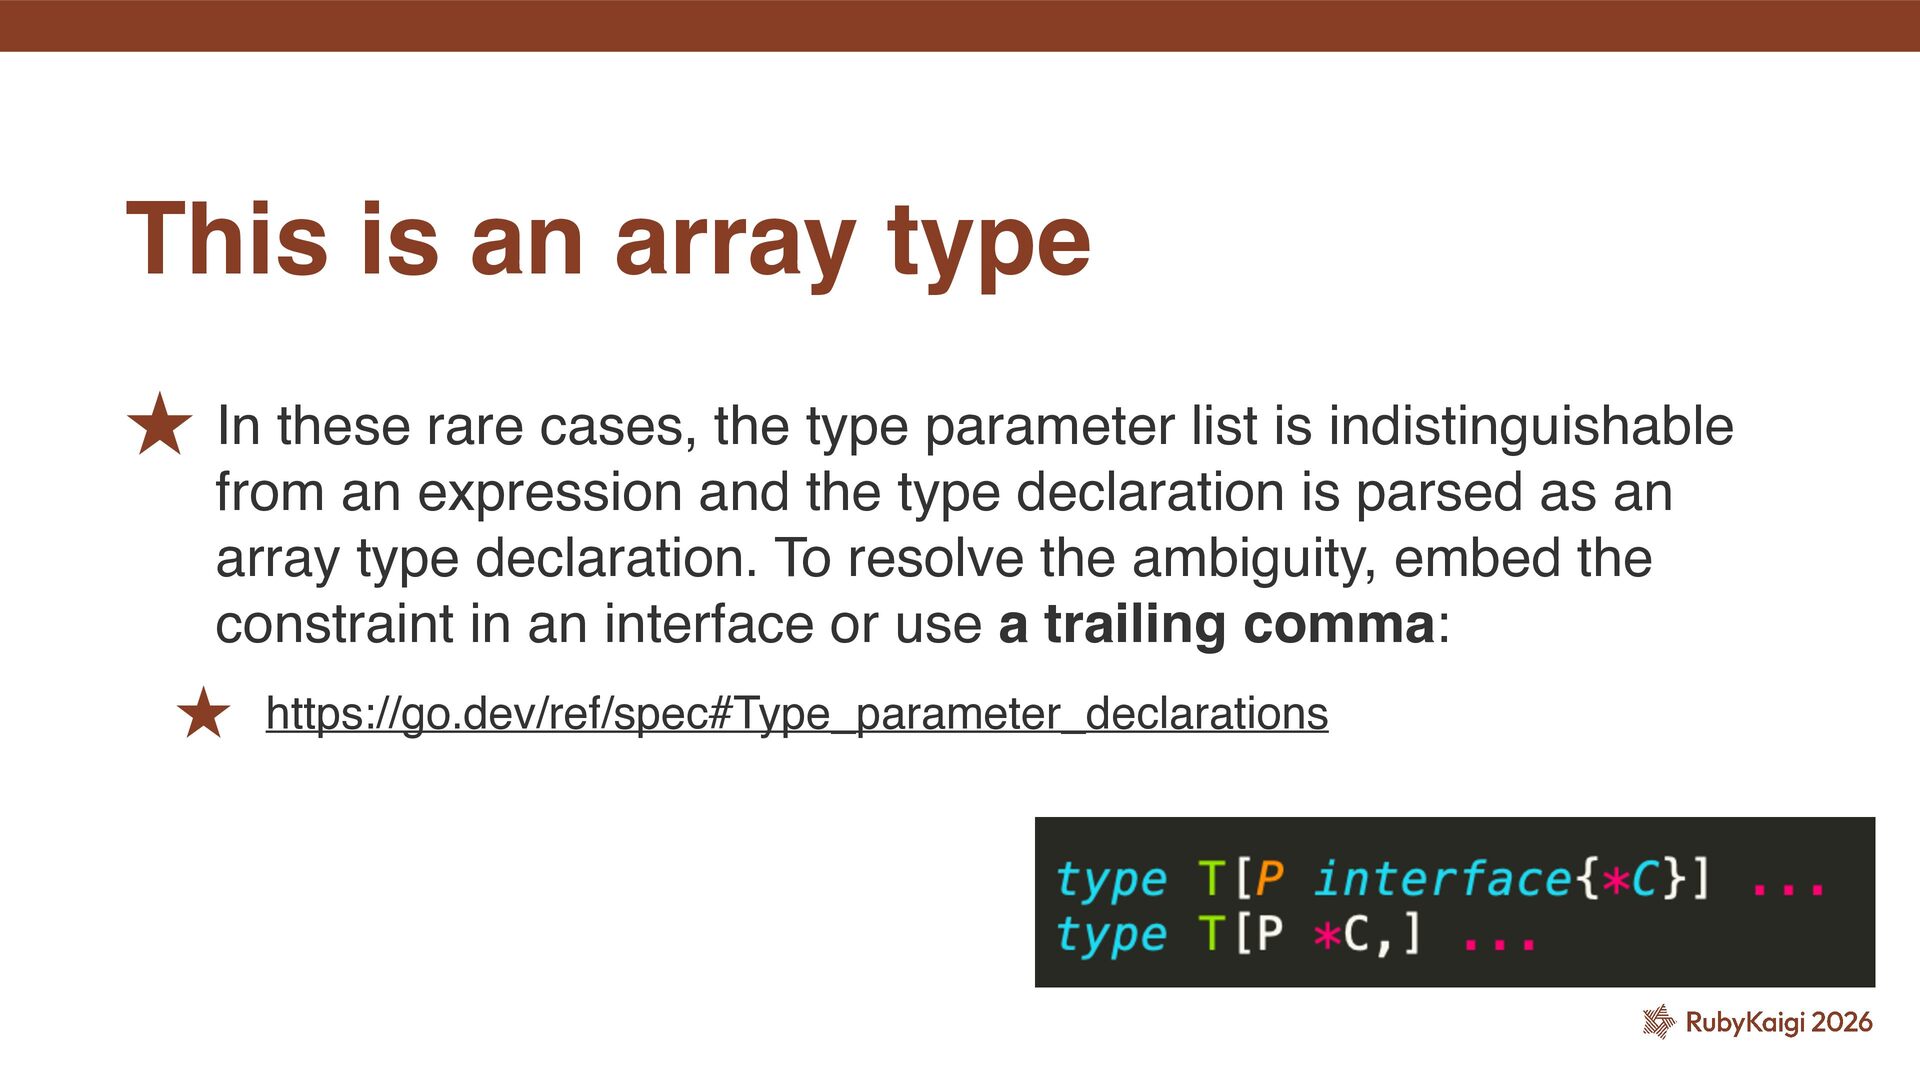
˒ In these rare cases, the type parameter list is
indistinguishable from an expression and the type declaration is parsed as an array type declaration. To resolve the ambiguity, embed the constraint in an interface or use a trailing comma: ˒ https://go.dev/ref/spec#Type_parameter_declarations This is an array type -
˒ We will not go into the pros and cons
of this grammar here. ˒ My personal view is that operators often end up being contested between types and the core grammar, which makes it dif fi cult to integrate types cleanly into the grammar. ˒ What interests me here is whether this was actually designed that way. What to Focus On -
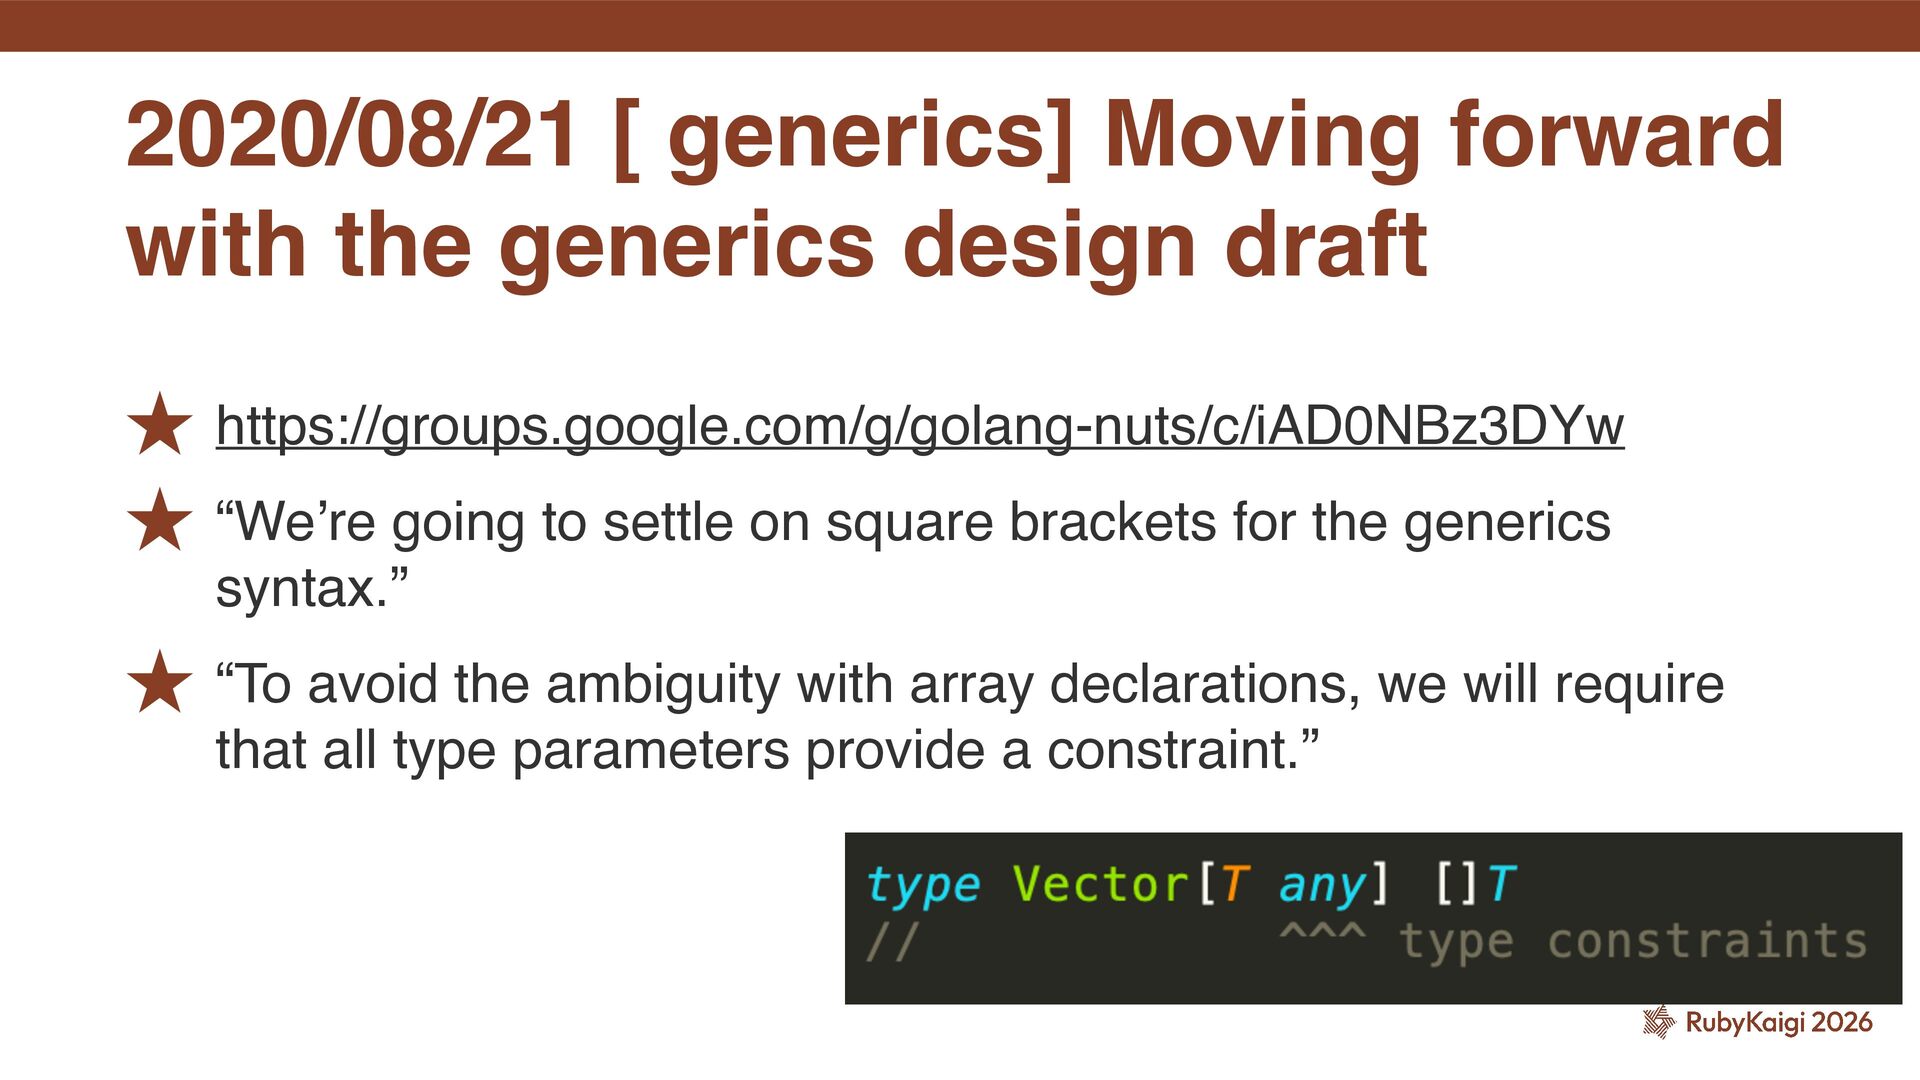
˒ https://groups.google.com/g/golang-nuts/c/iAD0NBz3DYw ˒ “We’re going to settle on square brackets
for the generics syntax.” ˒ “To avoid the ambiguity with array declarations, we will require that all type parameters provide a constraint.” 2020/08/21 [ generics] Moving forward with the generics design draft -
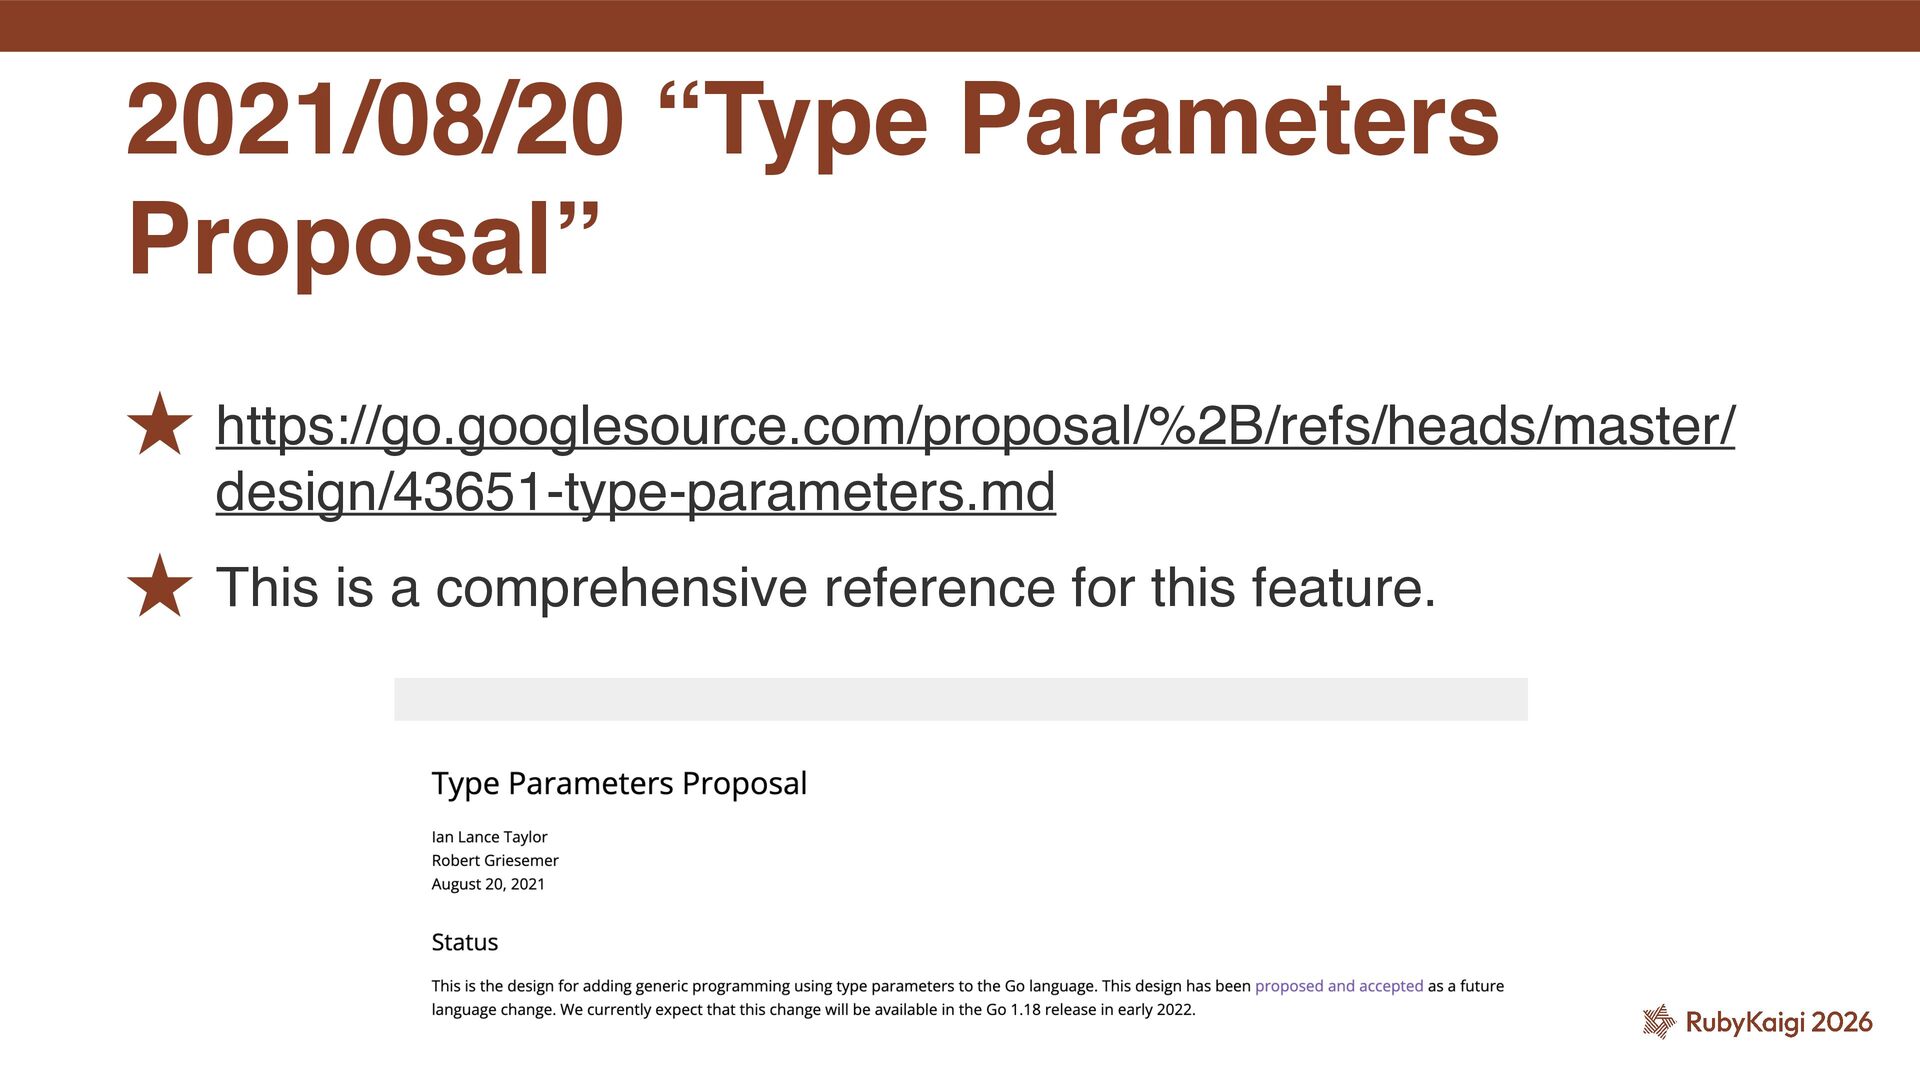
˒ https://go.googlesource.com/proposal/%2B/refs/heads/master/ design/43651-type-parameters.md ˒ This is a comprehensive reference for
this feature. 2021/08/20 “Type Parameters Proposal” -
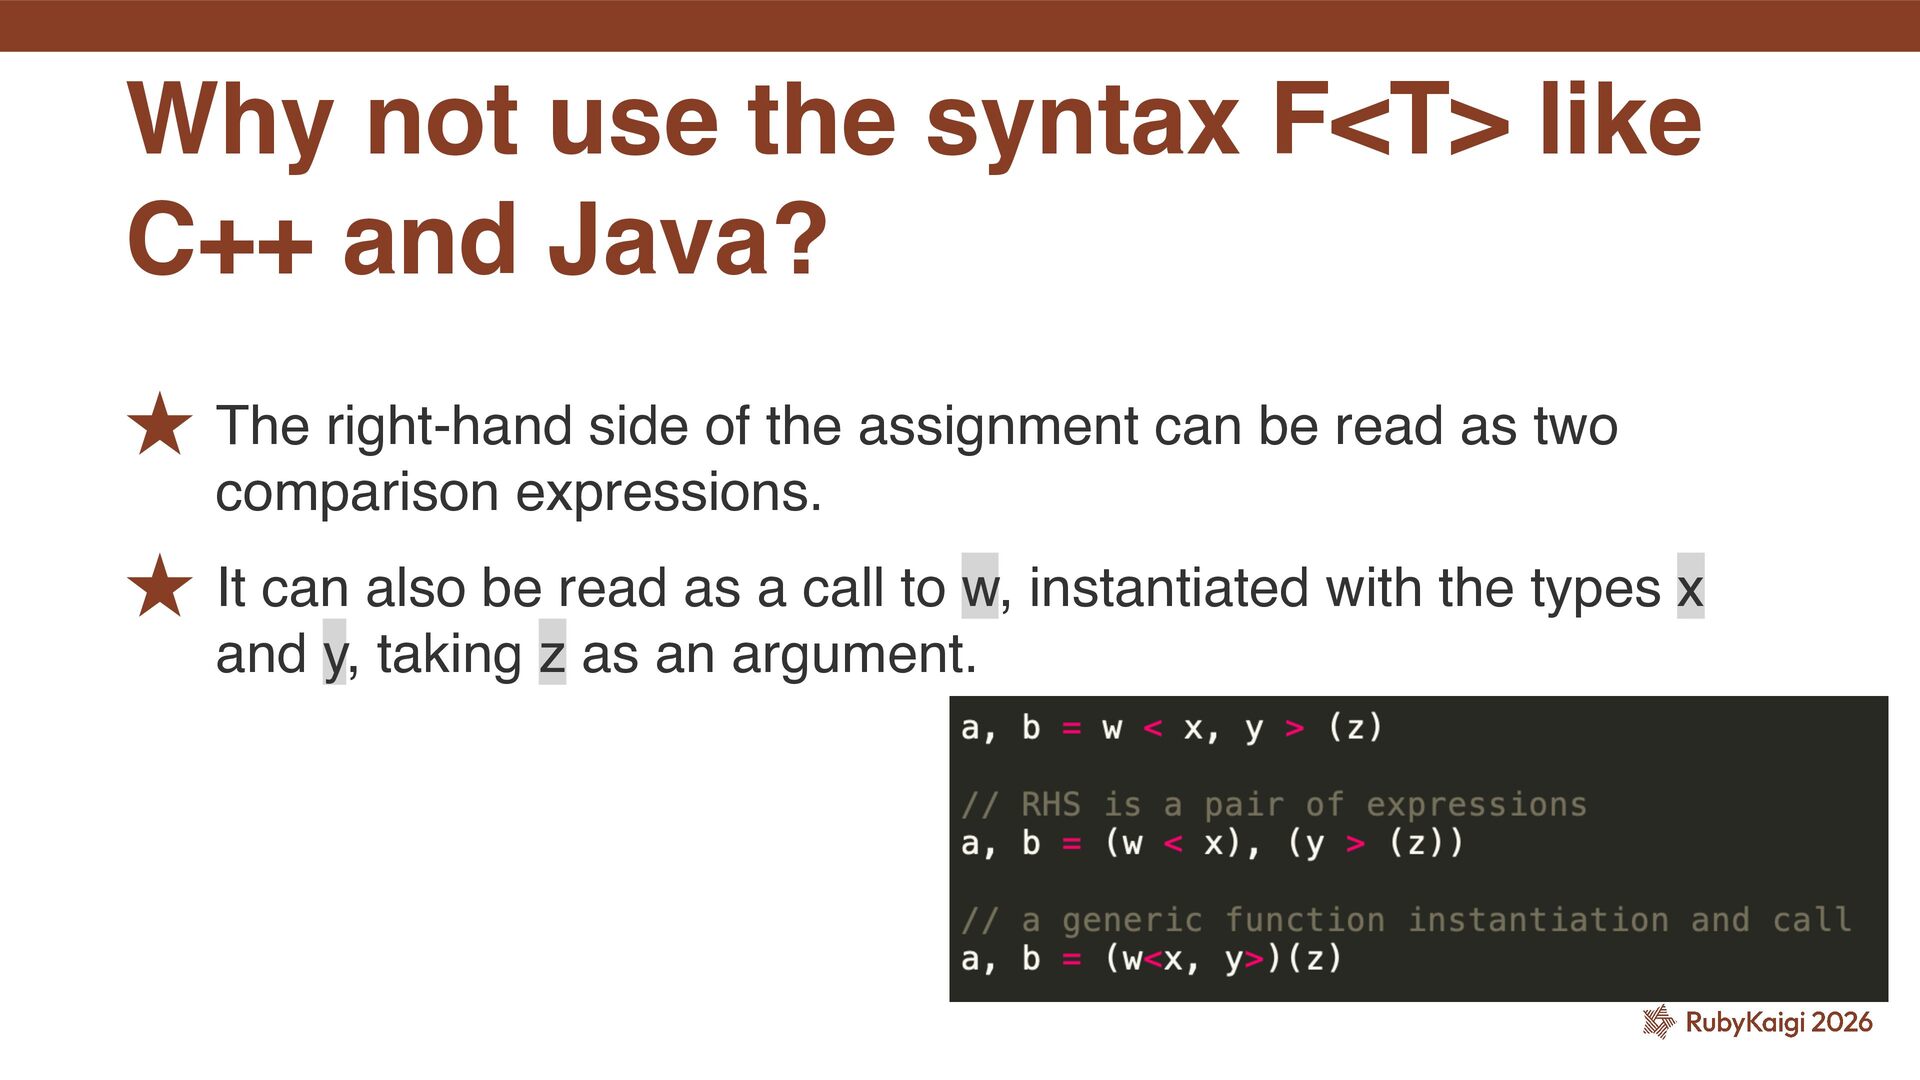
˒ The right-hand side of the assignment can be read
as two comparison expressions. ˒ It can also be read as a call to w, instantiated with the types x and y, taking z as an argument. Why not use the syntax F<T> like C++ and Java? -
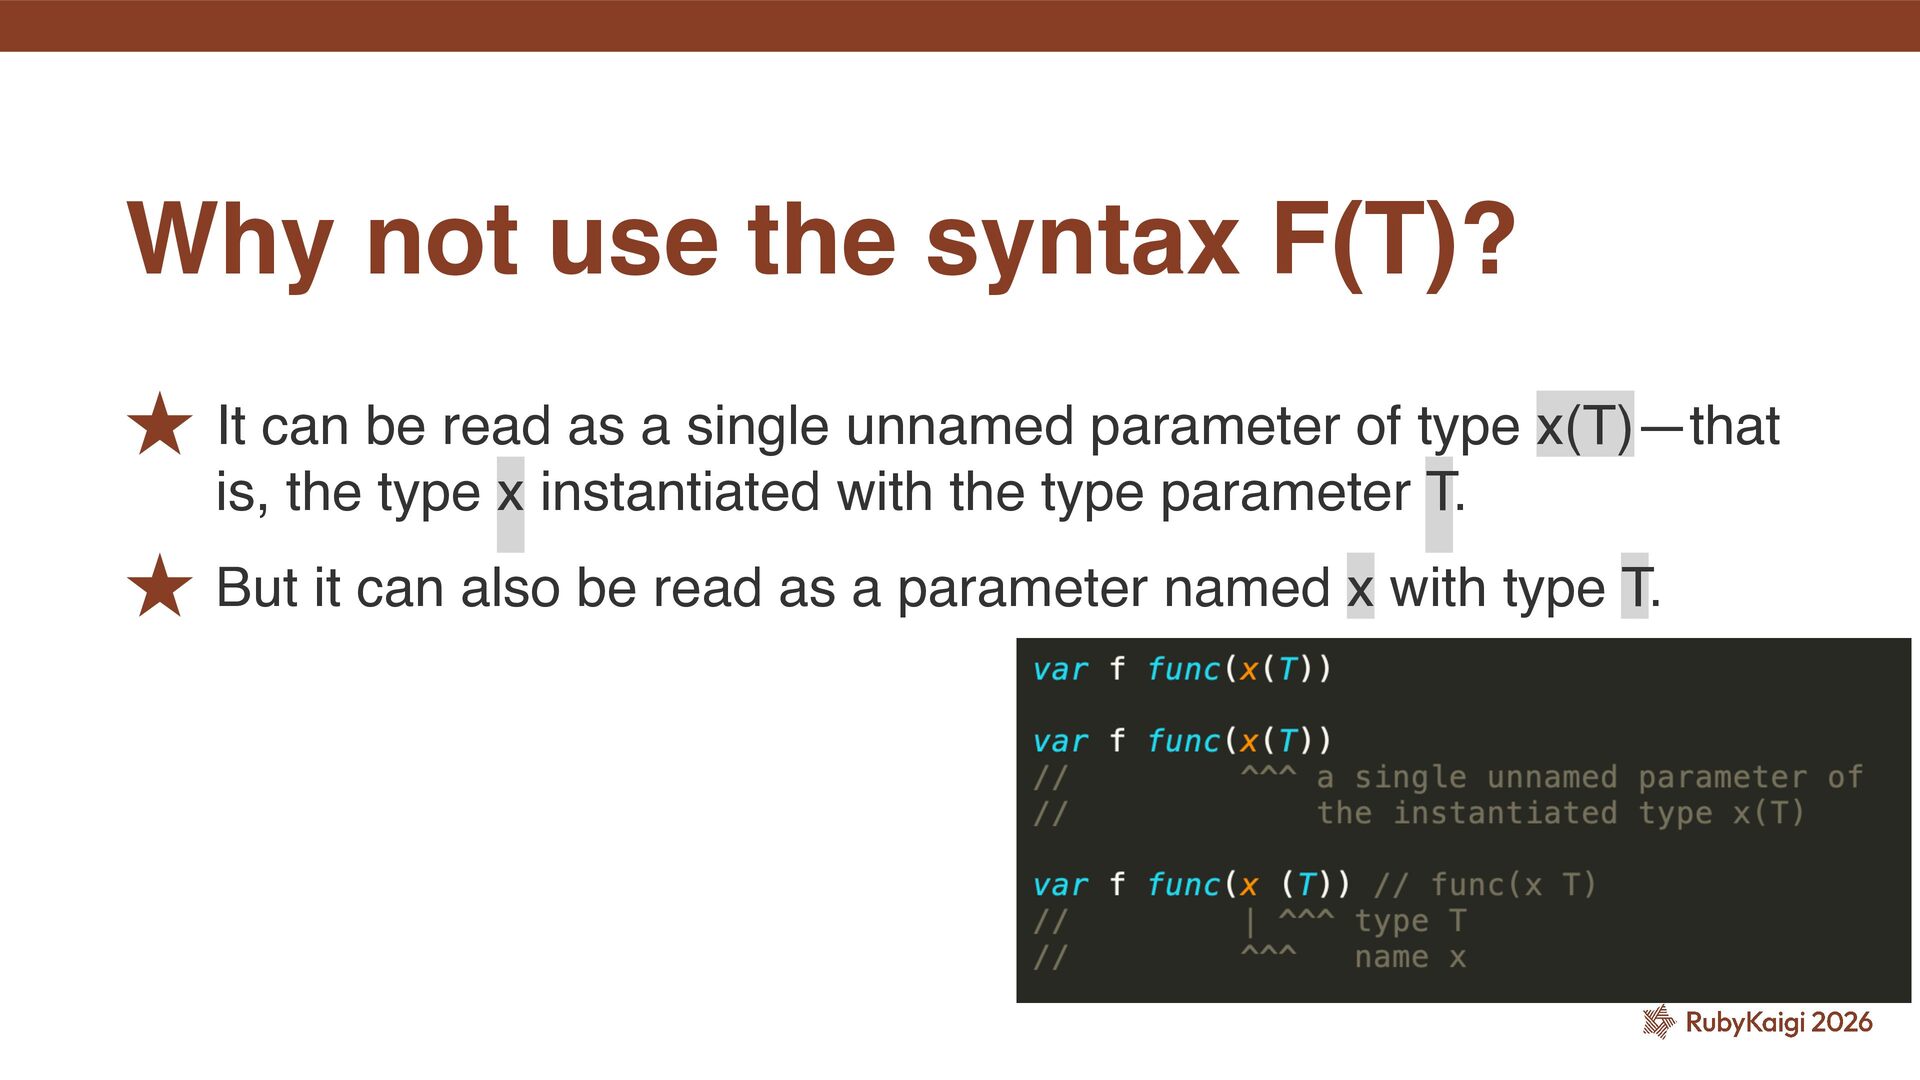
˒ It can be read as a single unnamed parameter
of type x(T)—that is, the type x instantiated with the type parameter T. ˒ But it can also be read as a parameter named x with type T. Why not use the syntax F(T)? -
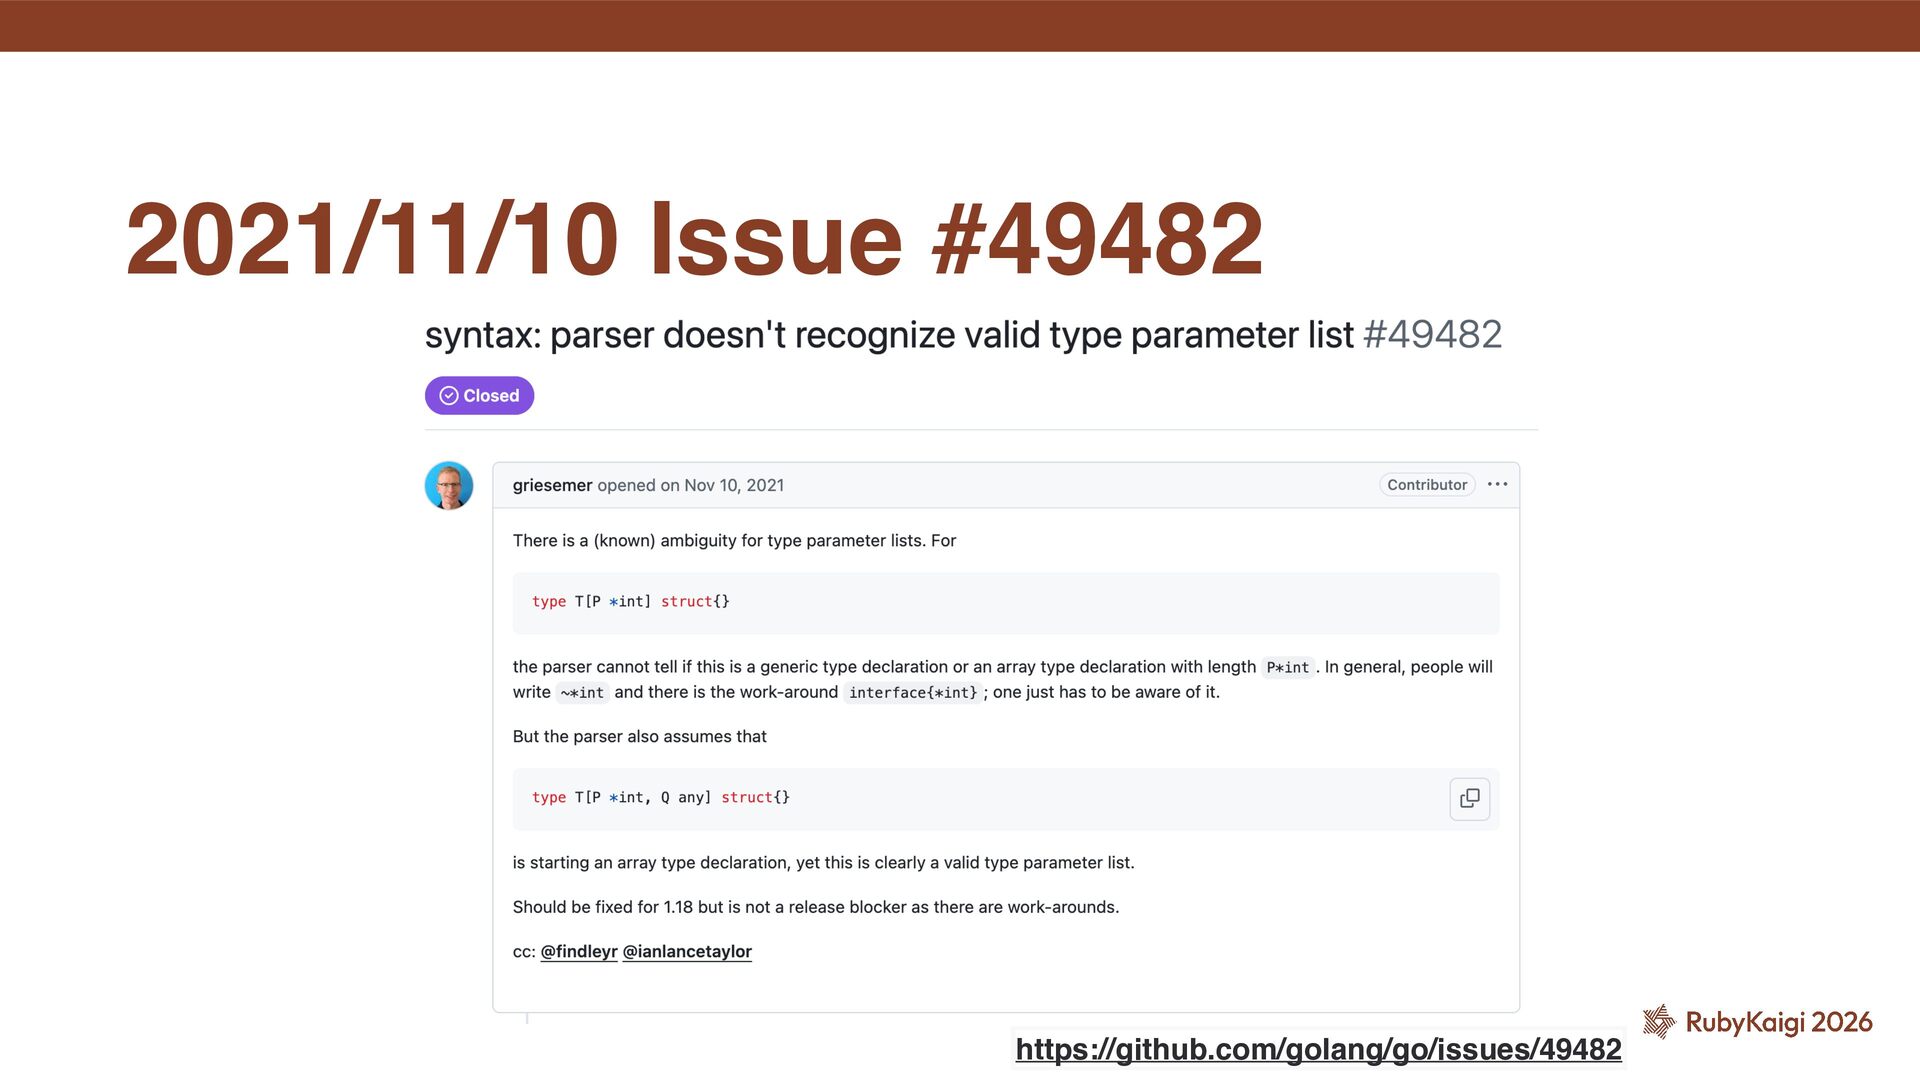
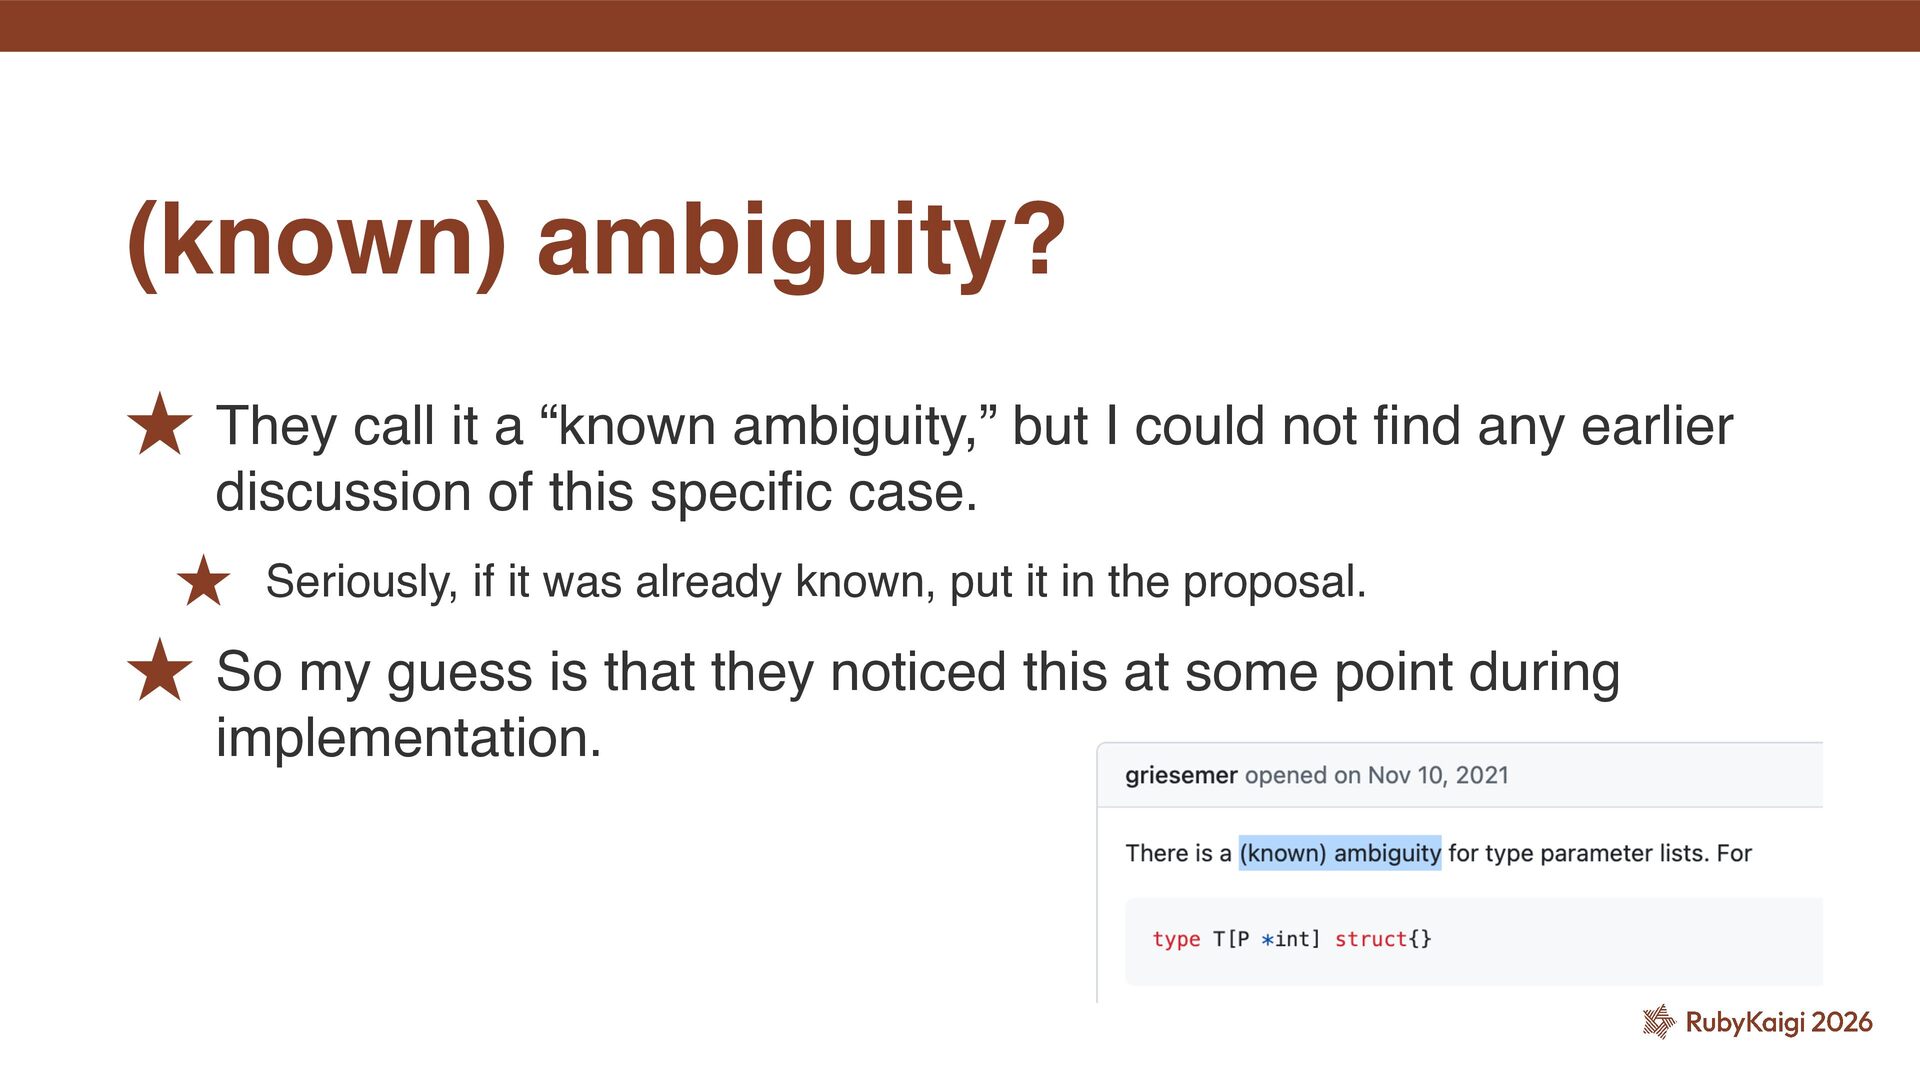
˒ They call it a “known ambiguity,” but I could
not fi nd any earlier discussion of this speci fi c case. ˒ Seriously, if it was already known, put it in the proposal. ˒ So my guess is that they noticed this at some point during implementation. (known) ambiguity? -
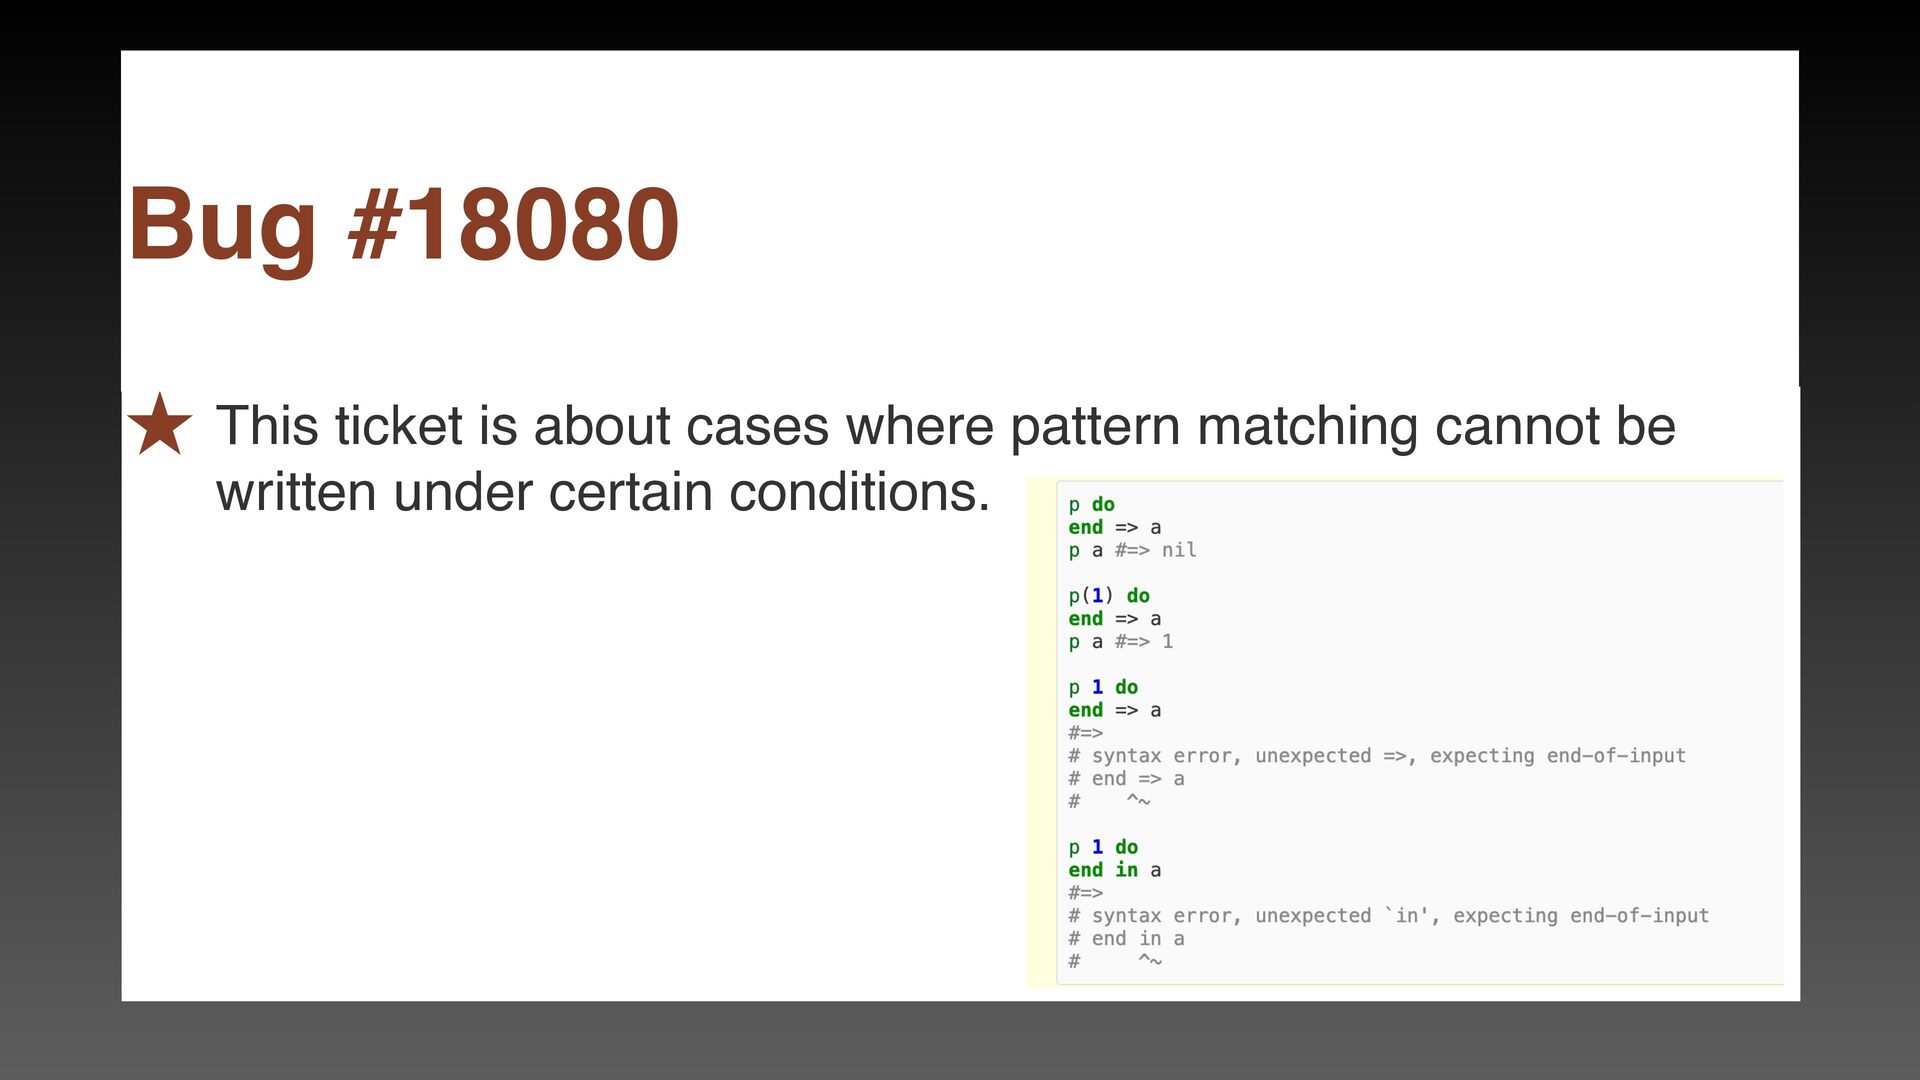
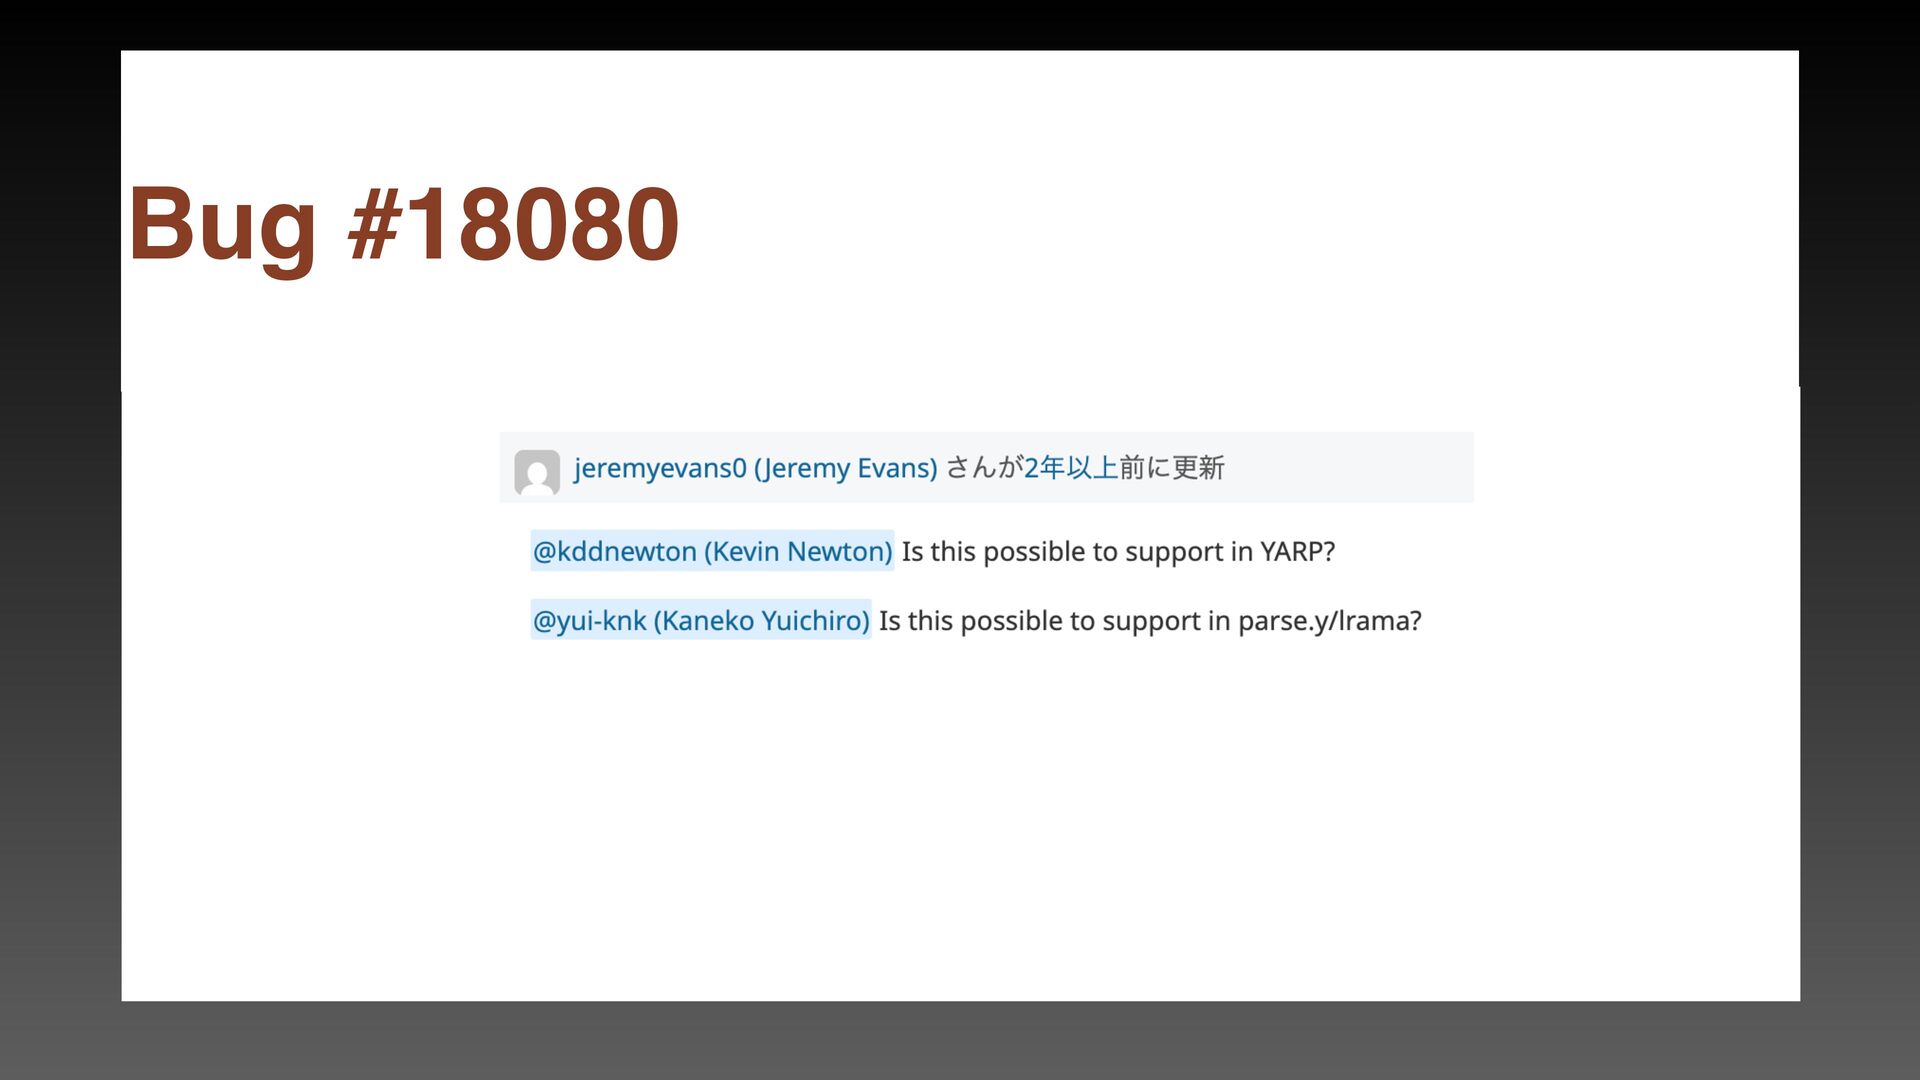
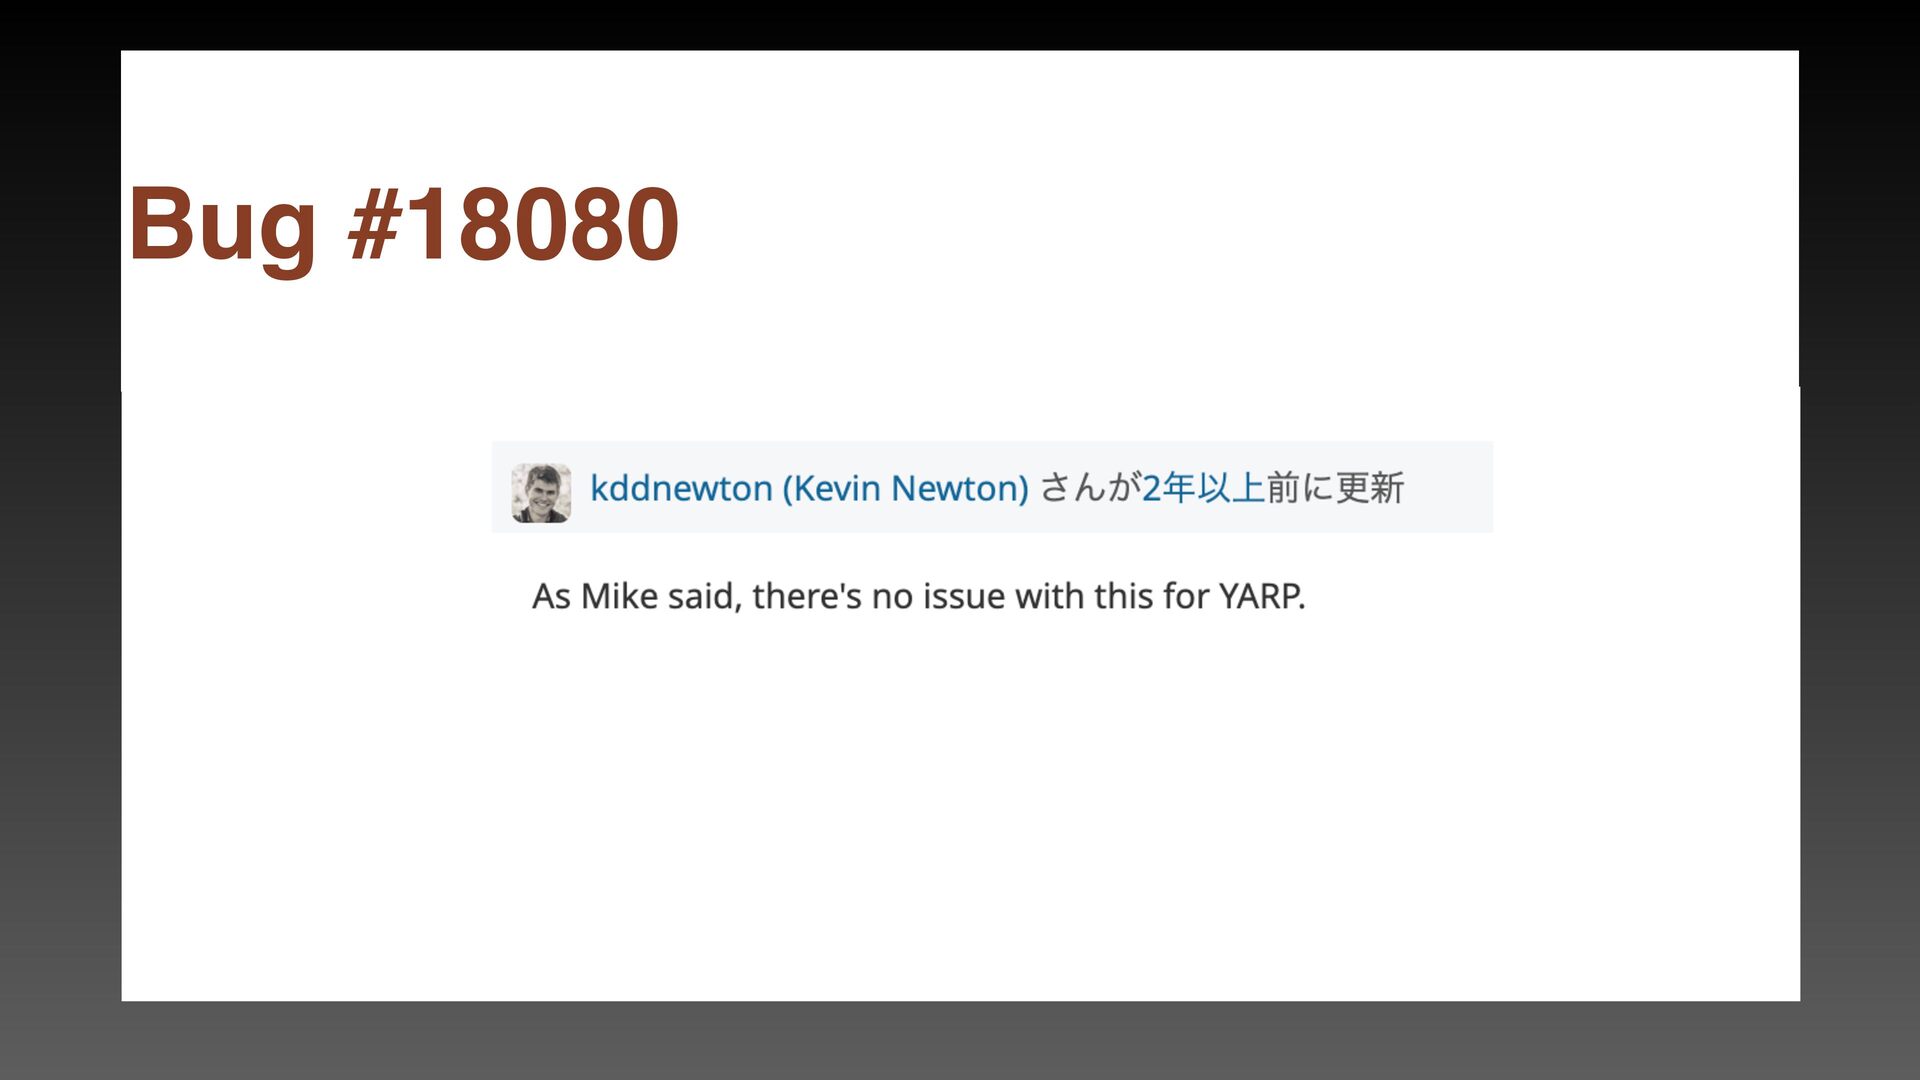
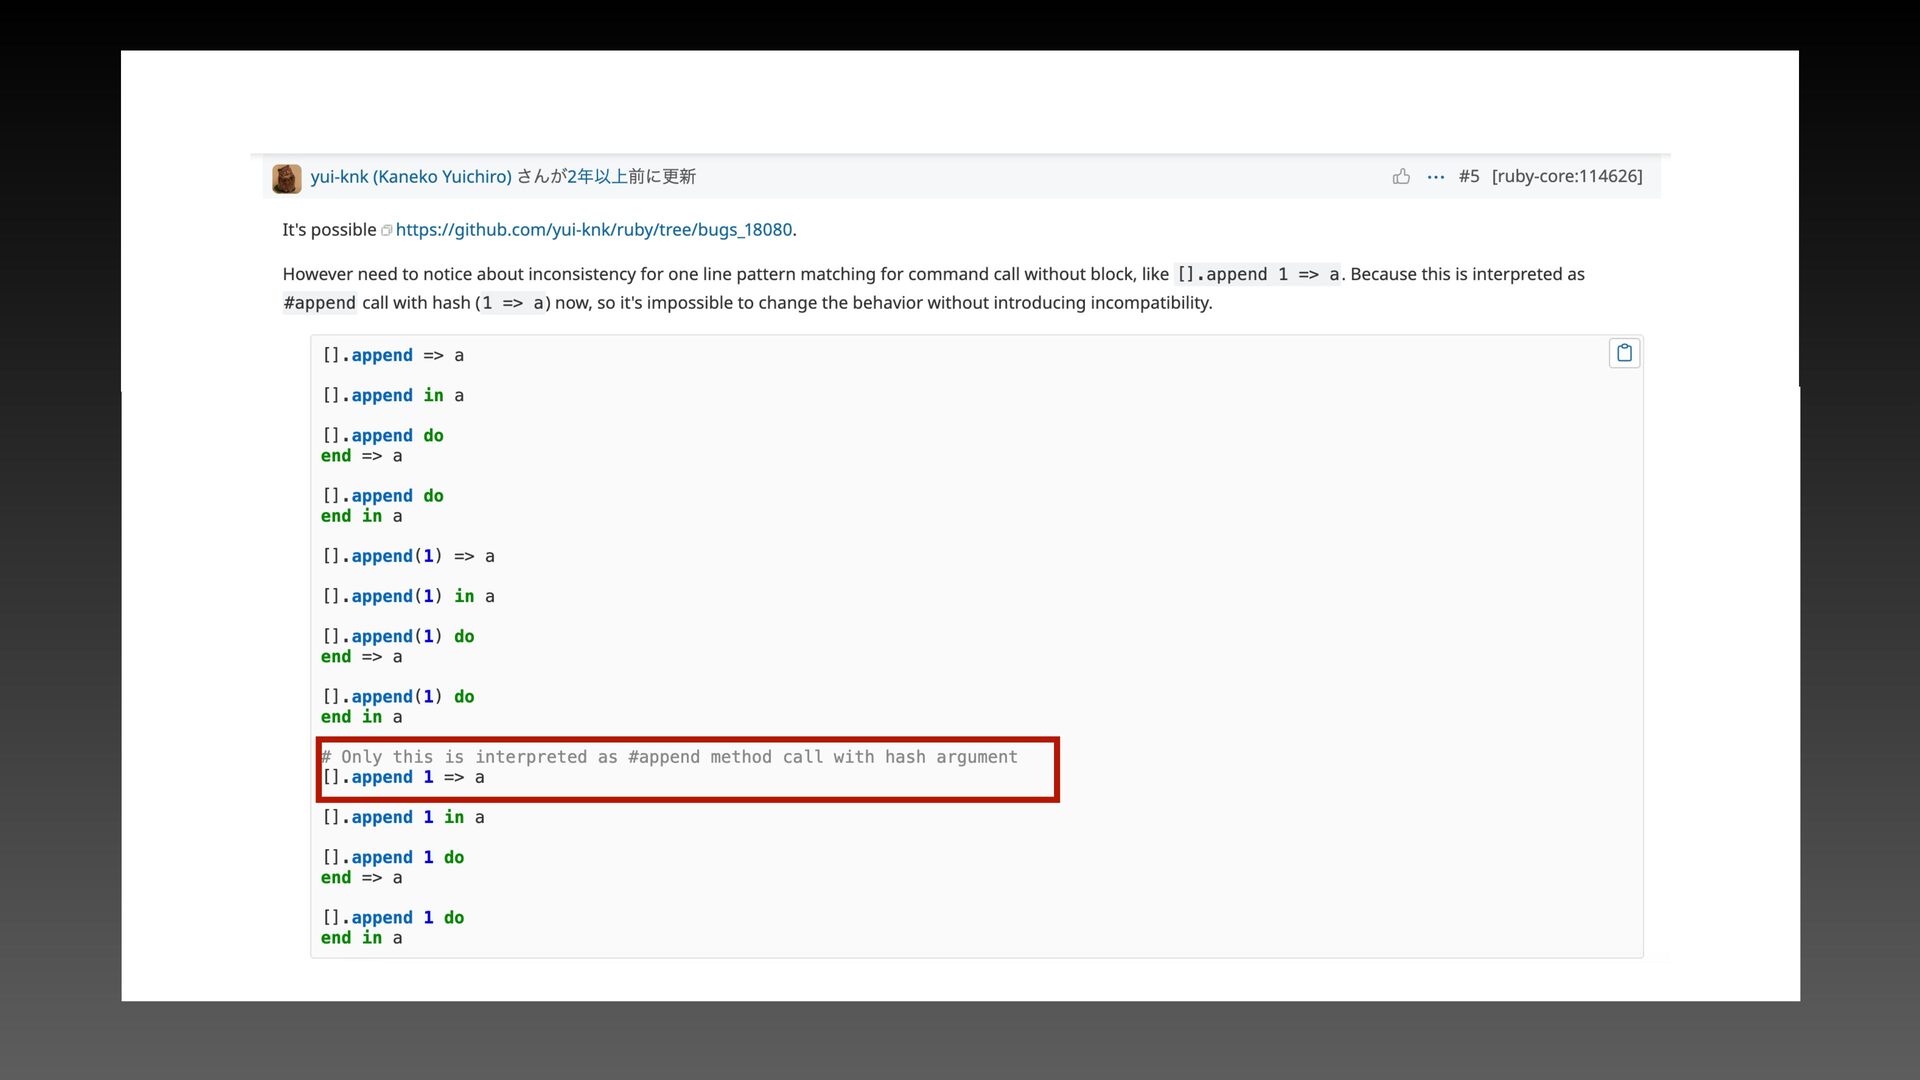
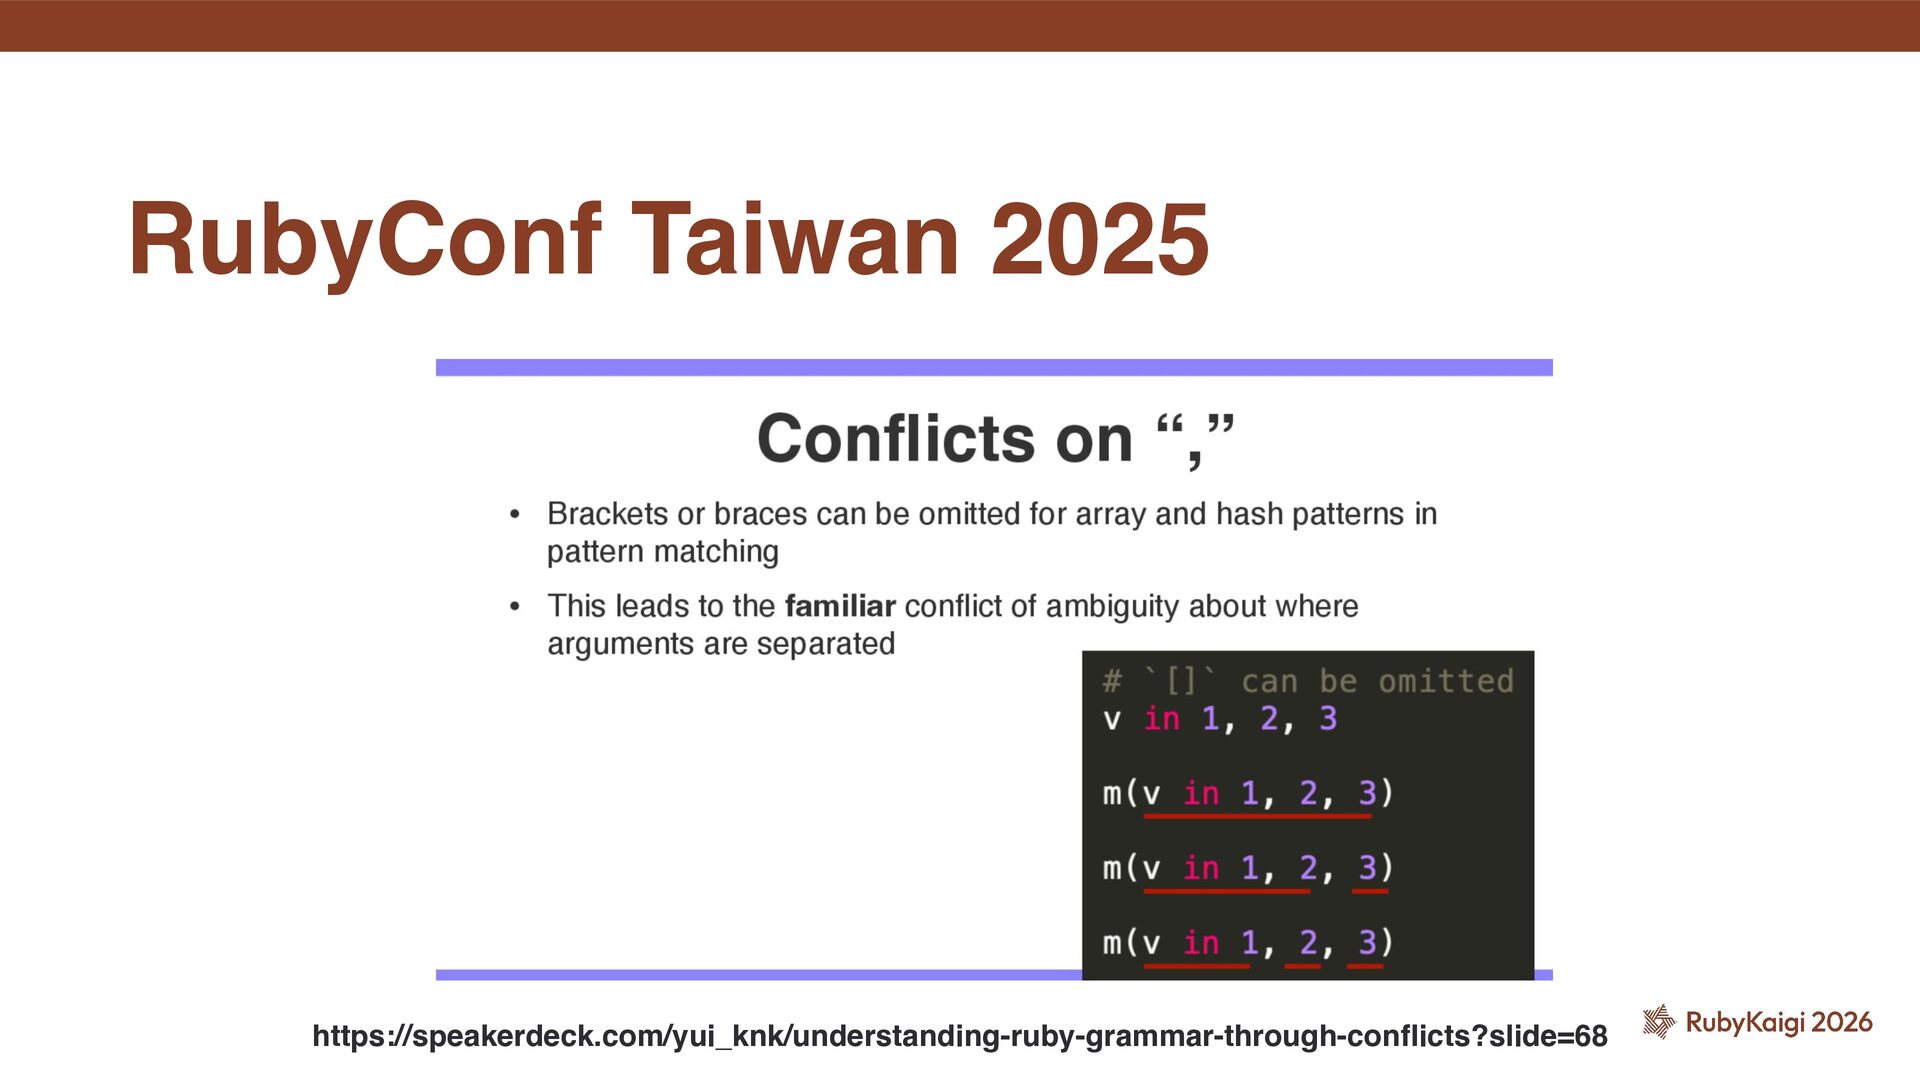
˒ This ticket is about cases where pattern matching cannot
be written under certain conditions. Bug #18080 -
That said, the grammar still has to be managed, and
the syntax still has to be parsed, right? Why not try using AI or something? As they say, use whatever is available—even your parents, if they are standing there. そうは言っても文法は管理しないといけないし 構文は解析しないといけないでしょ? AIとか試してみたら? 立ってるものは親でも使えってね -
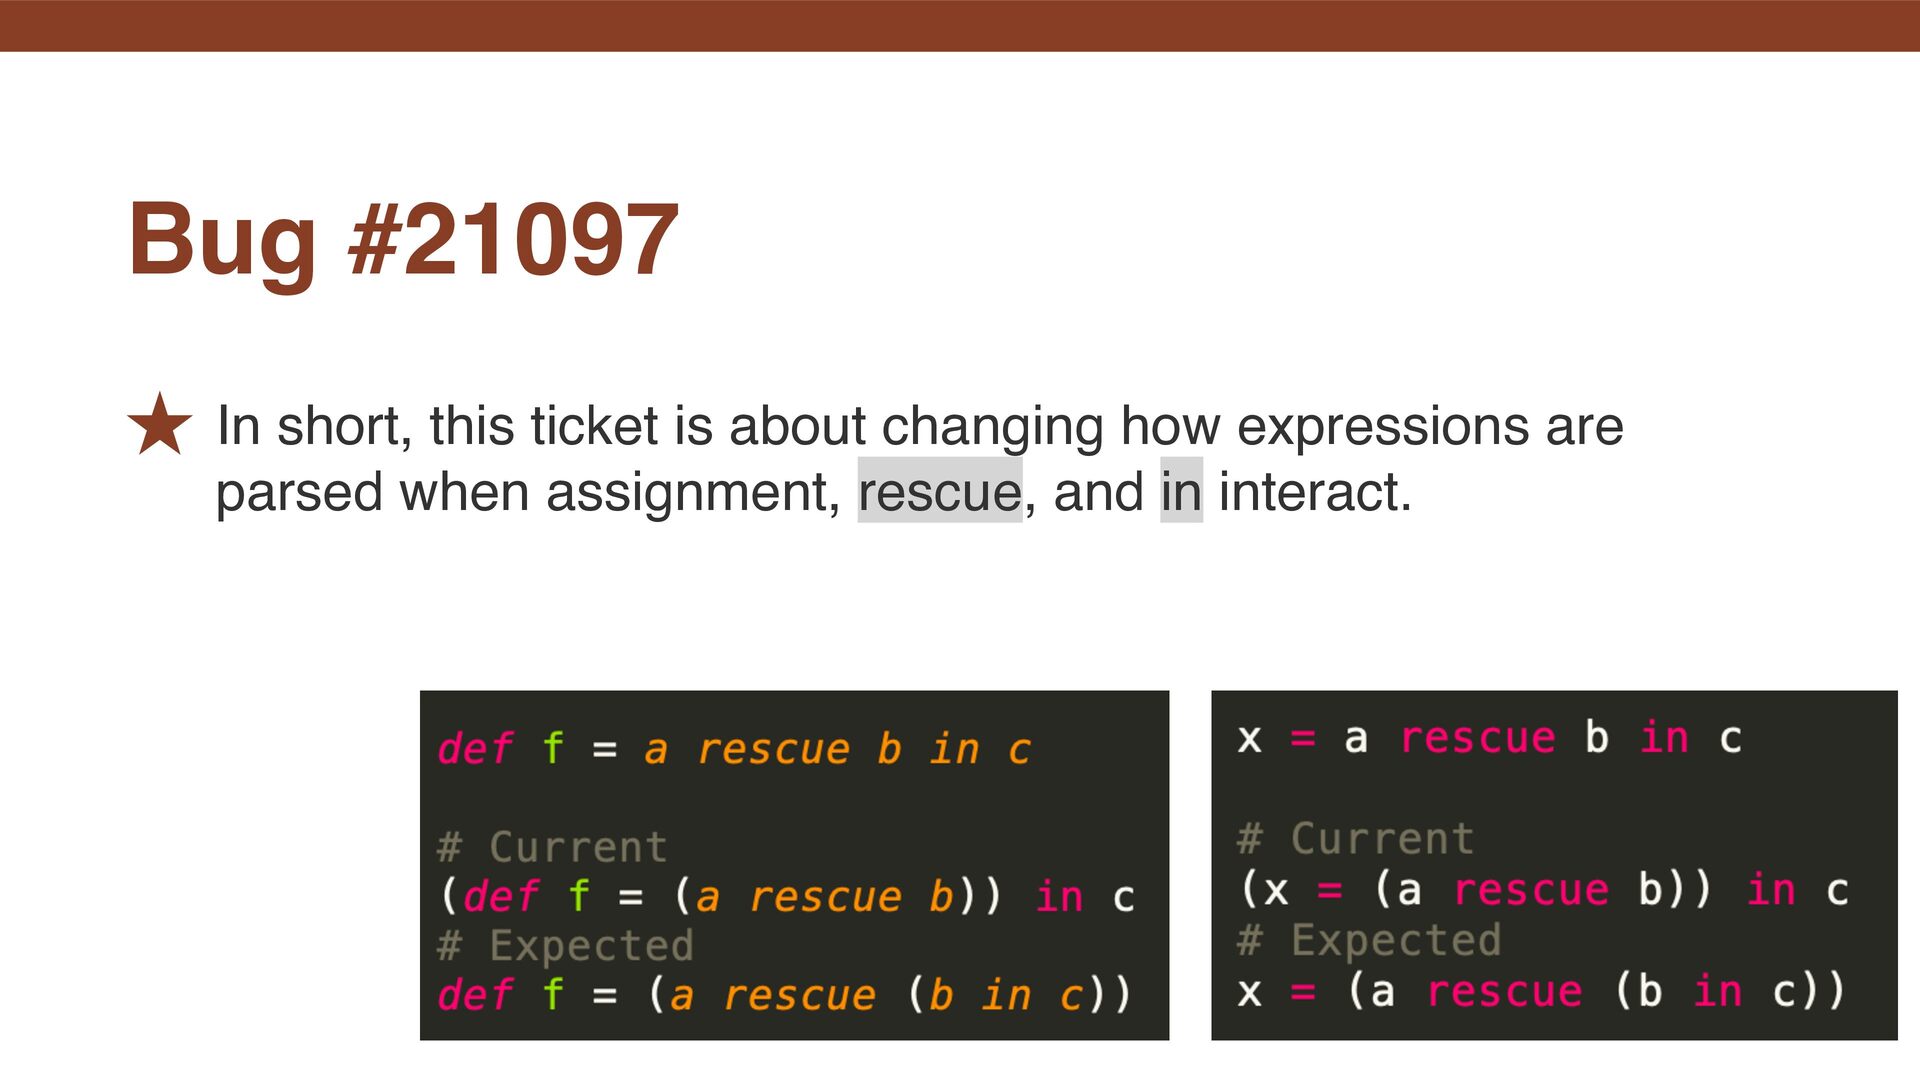
˒ In short, this ticket is about changing how expressions
are parsed when assignment, rescue, and in interact. Bug #21097 -
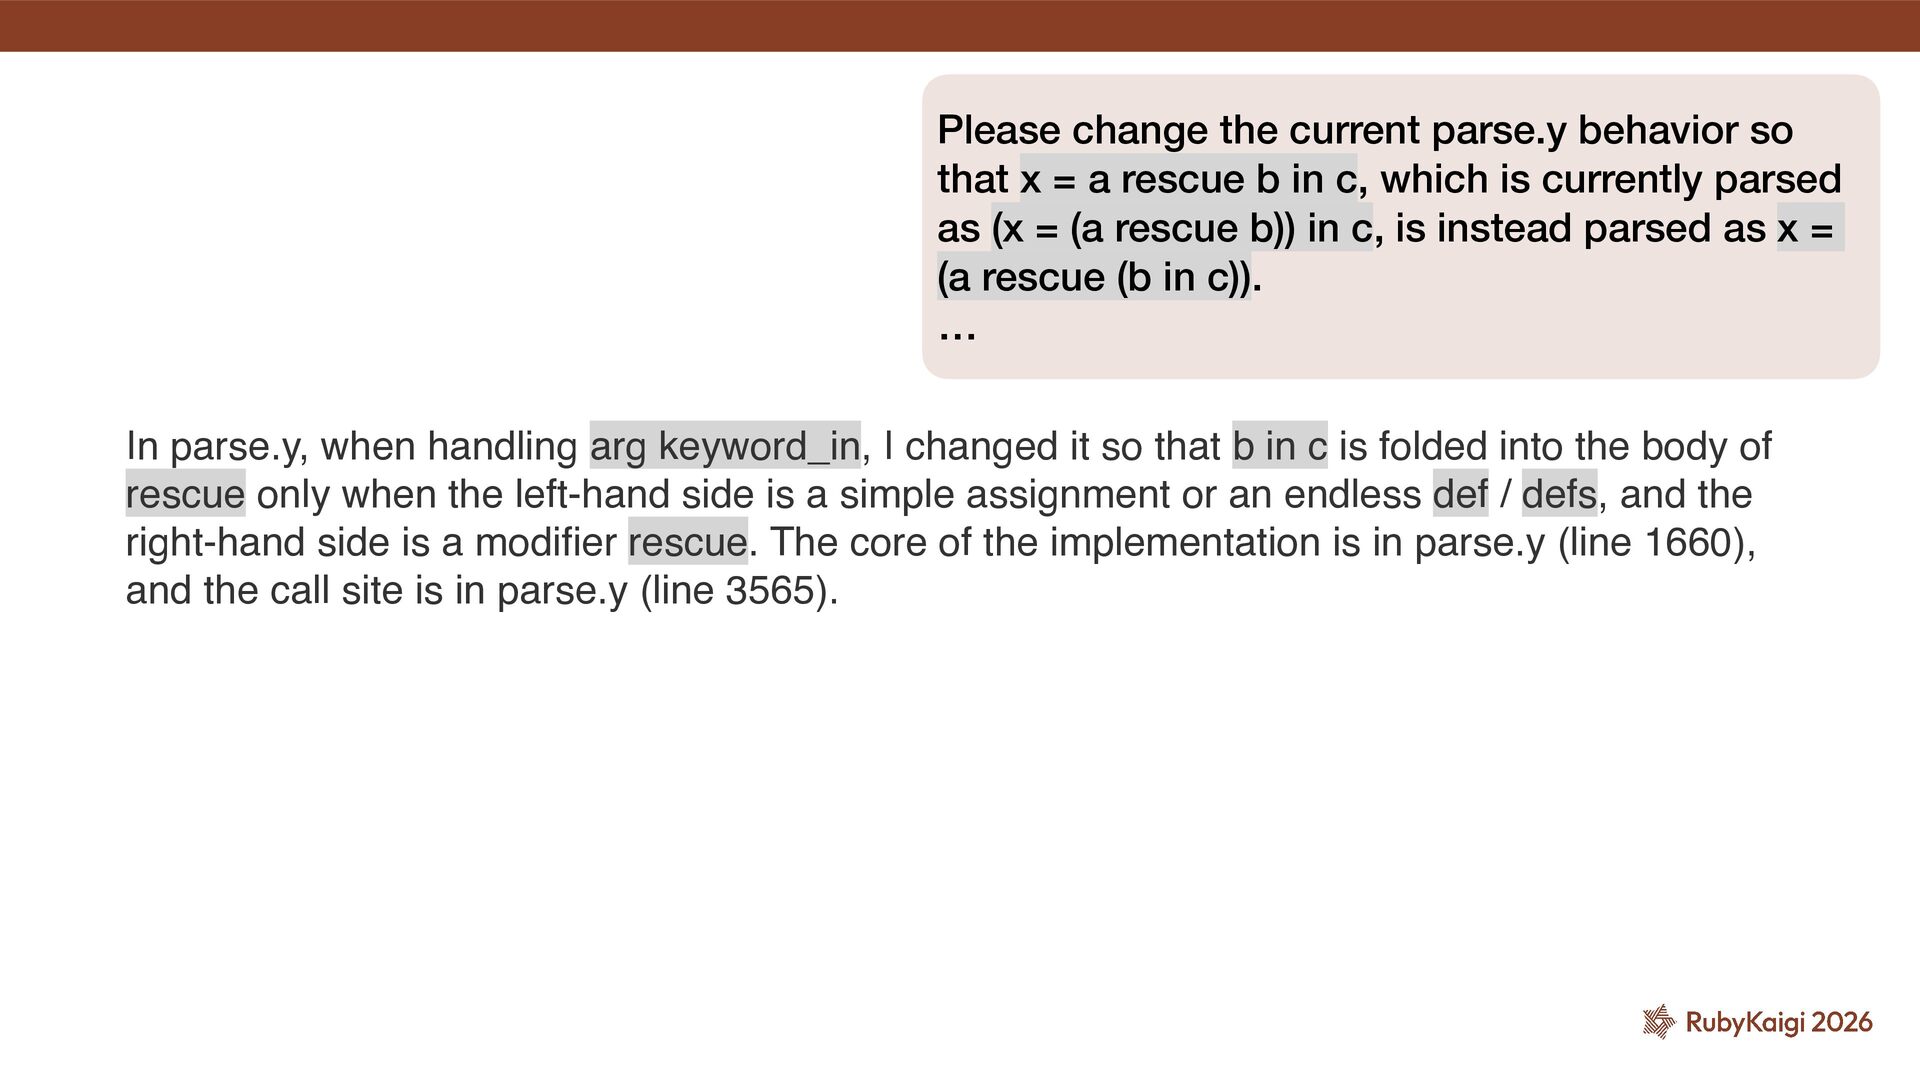
Please change the current parse.y behavior so that x =
a rescue b in c, which is currently parsed as (x = (a rescue b)) in c, is instead parsed as x = (a rescue (b in c)). … In parse.y, when handling arg keyword_in, I changed it so that b in c is folded into the body of rescue only when the left-hand side is a simple assignment or an endless def / defs, and the right-hand side is a modi fi er rescue. The core of the implementation is in parse.y (line 1660), and the call site is in parse.y (line 3565). -
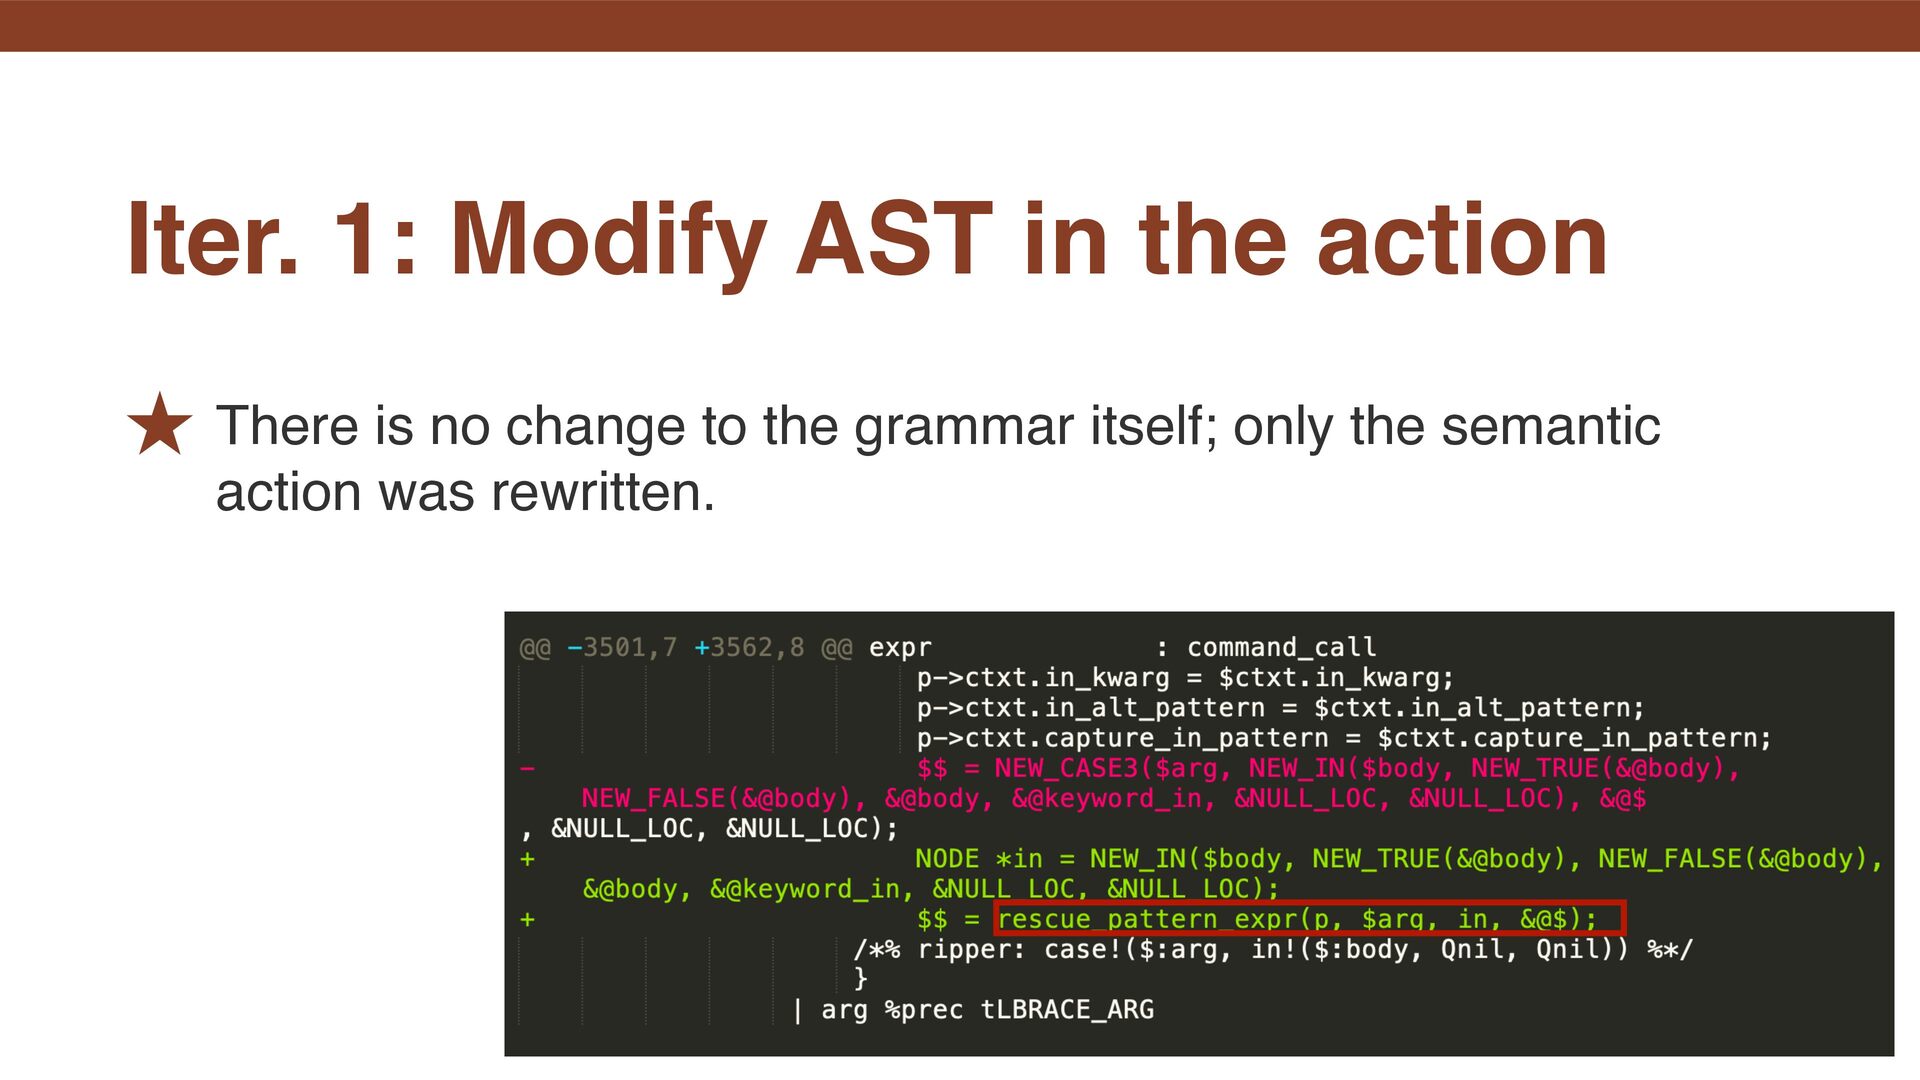
˒ There is no change to the grammar itself; only
the semantic action was rewritten. Iter. 1: Modify AST in the action -
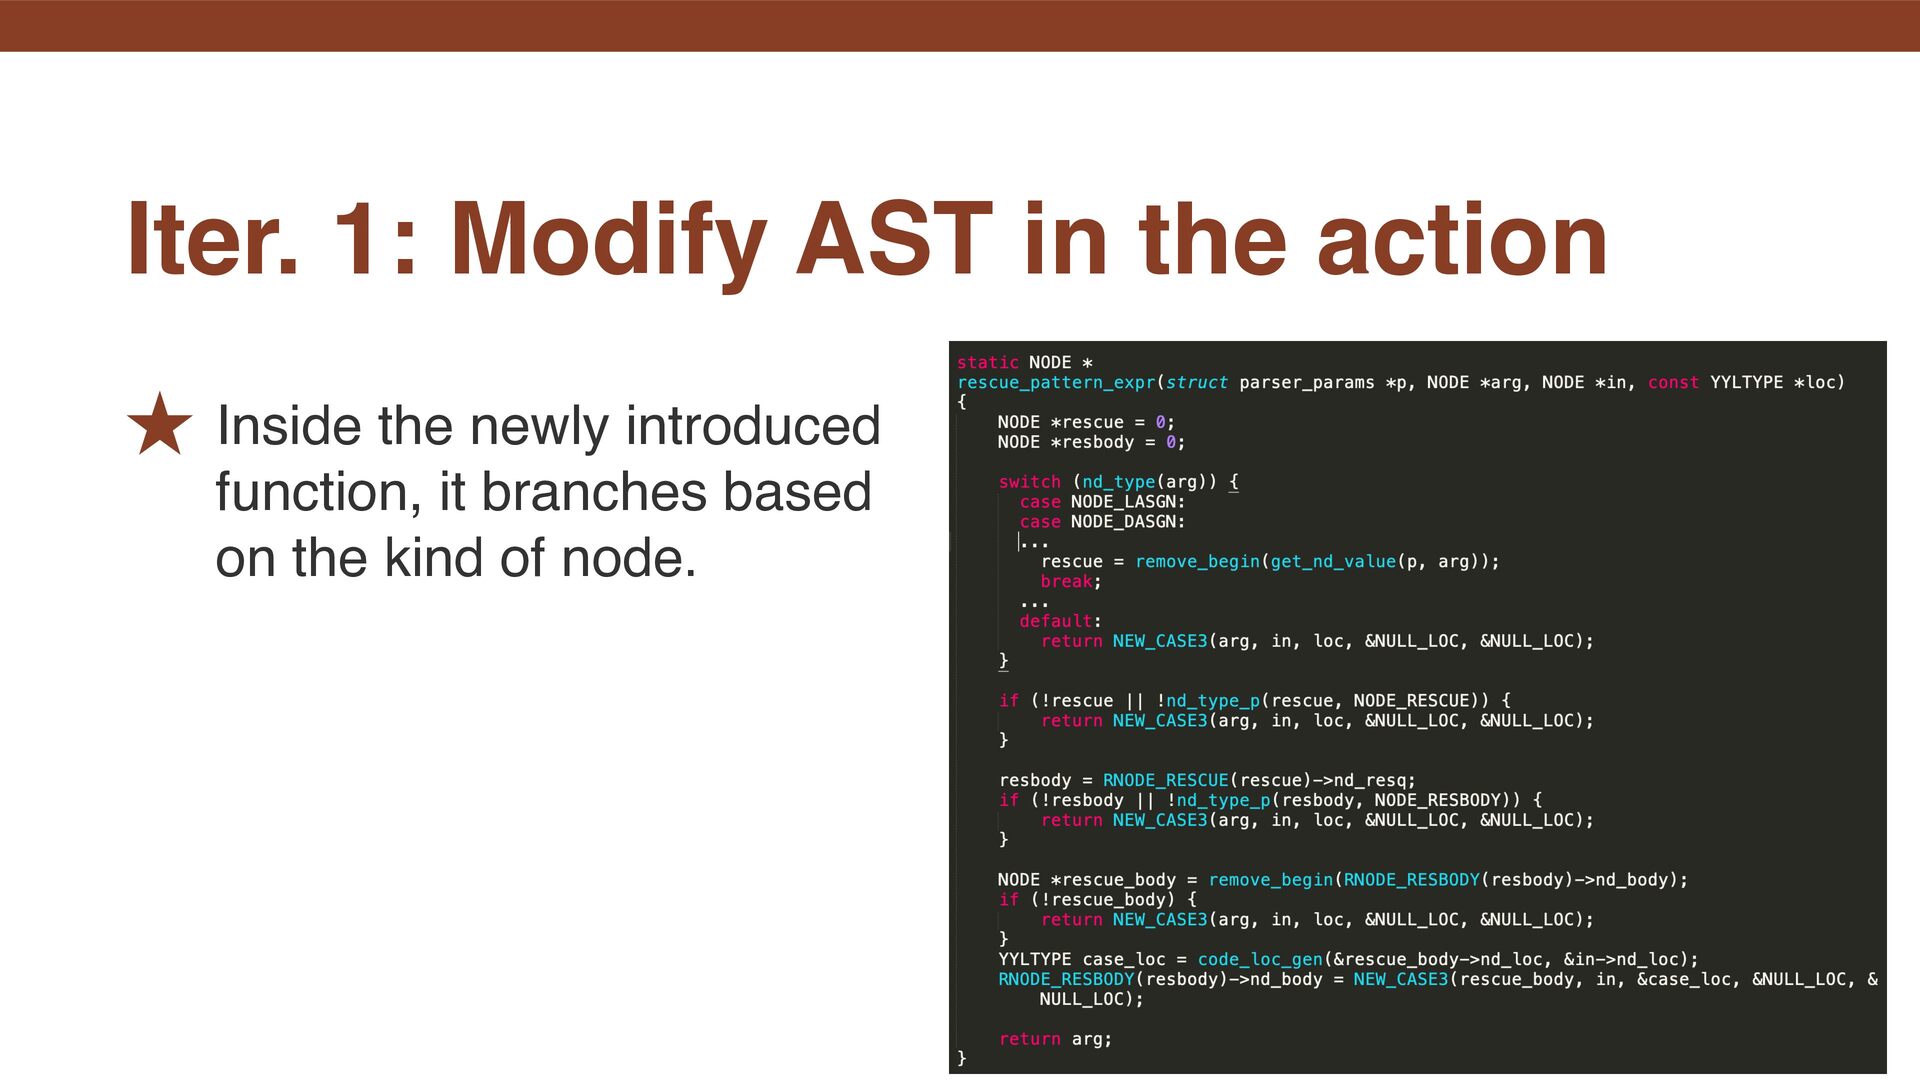
˒ Inside the newly introduced function, it branches based on
the kind of node. Iter. 1: Modify AST in the action -
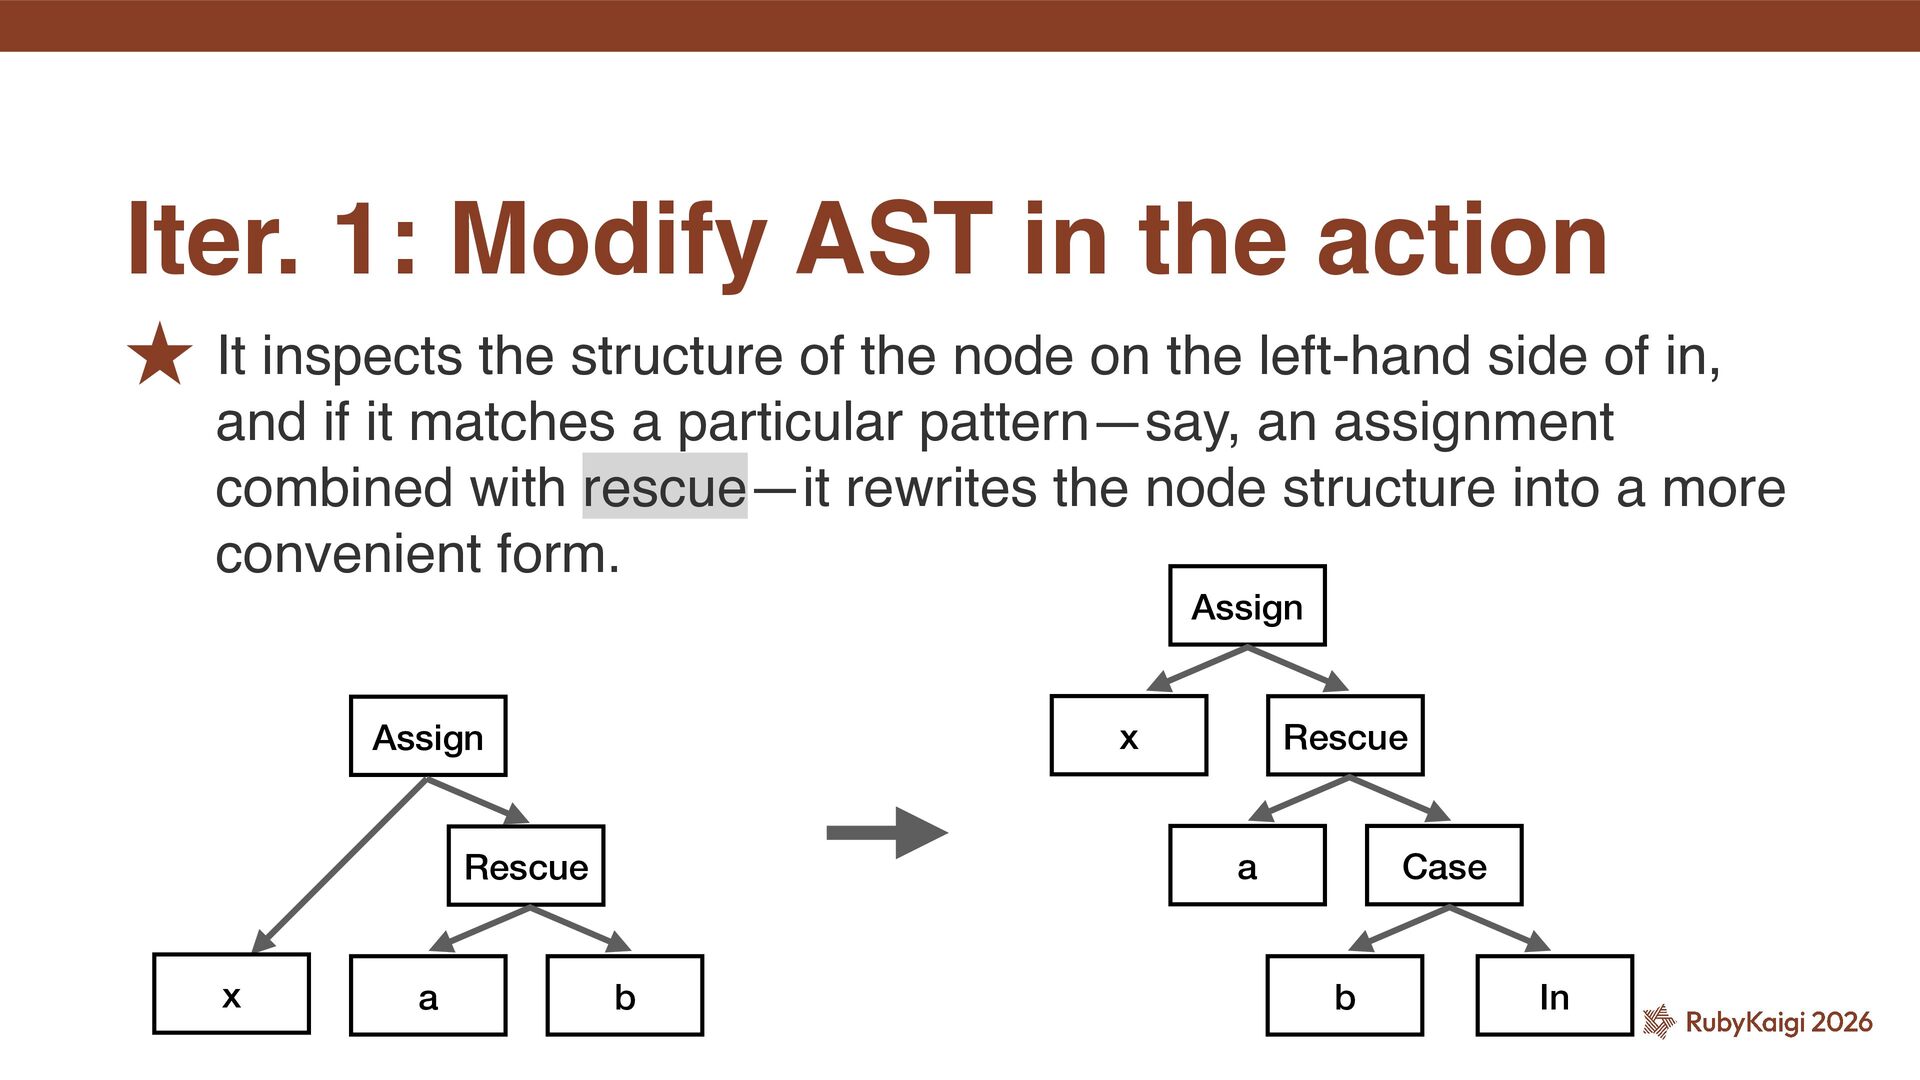
˒ It inspects the structure of the node on the
left-hand side of in, and if it matches a particular pattern—say, an assignment combined with rescue—it rewrites the node structure into a more convenient form. Iter. 1: Modify AST in the action Assign Rescue x a b Rescue a Case b In Assign x -
Instead of achieving this by adjusting the node construction in
the semantic action, try achieving it by changing the production rules themselves. Revised parse.y so that it no longer relies on post hoc AST rewriting, and instead resolves the issue through the production rules alone. I added a long, dedicated rule for rescue ... in ..., and assigned %prec tLOWEST to the shorter ... rescue ... side so that keyword_in is picked up fi rst. At the same time, I introduced a pattern entry point speci fi cally for the right-hand side of rescue, so that |, .., …, and => can be parsed without breaking ordinary pattern matching. -
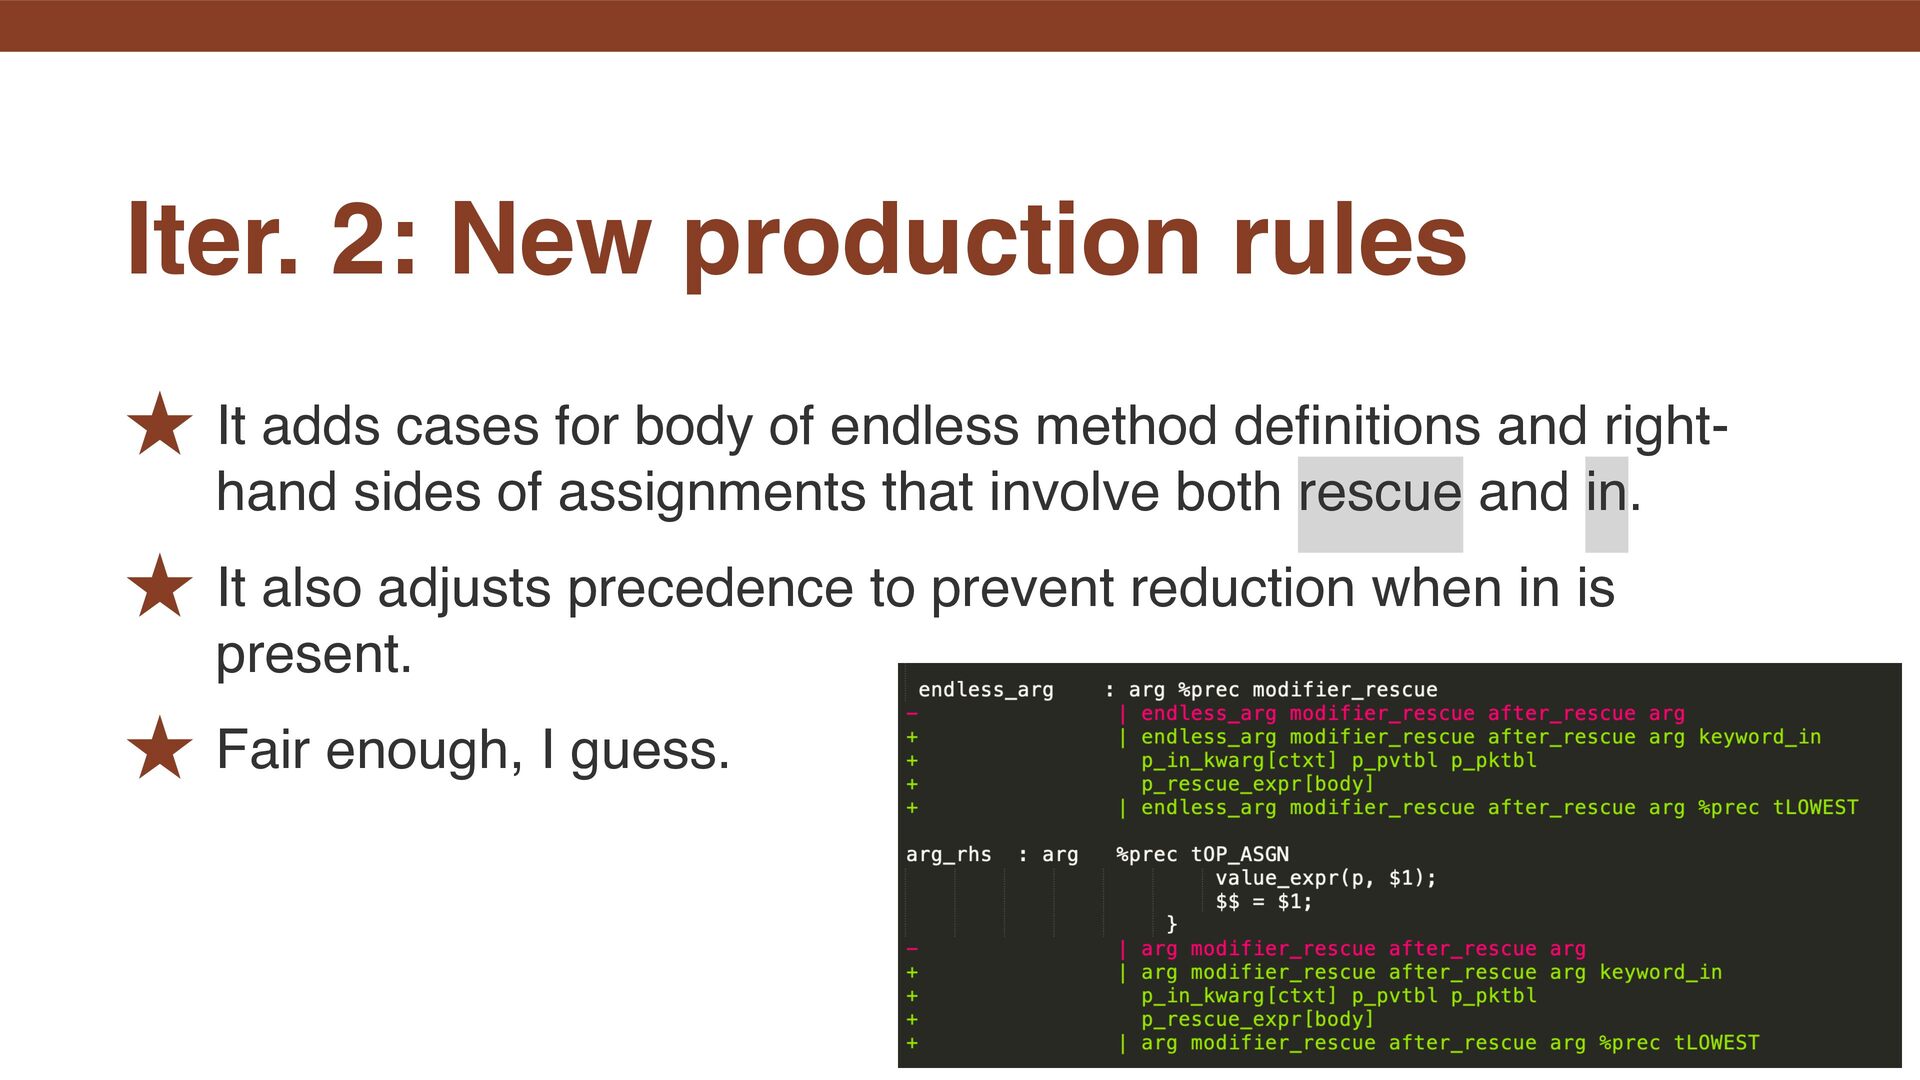
˒ It adds cases for body of endless method de
fi nitions and right- hand sides of assignments that involve both rescue and in. ˒ It also adjusts precedence to prevent reduction when in is present. ˒ Fair enough, I guess. Iter. 2: New production rules -
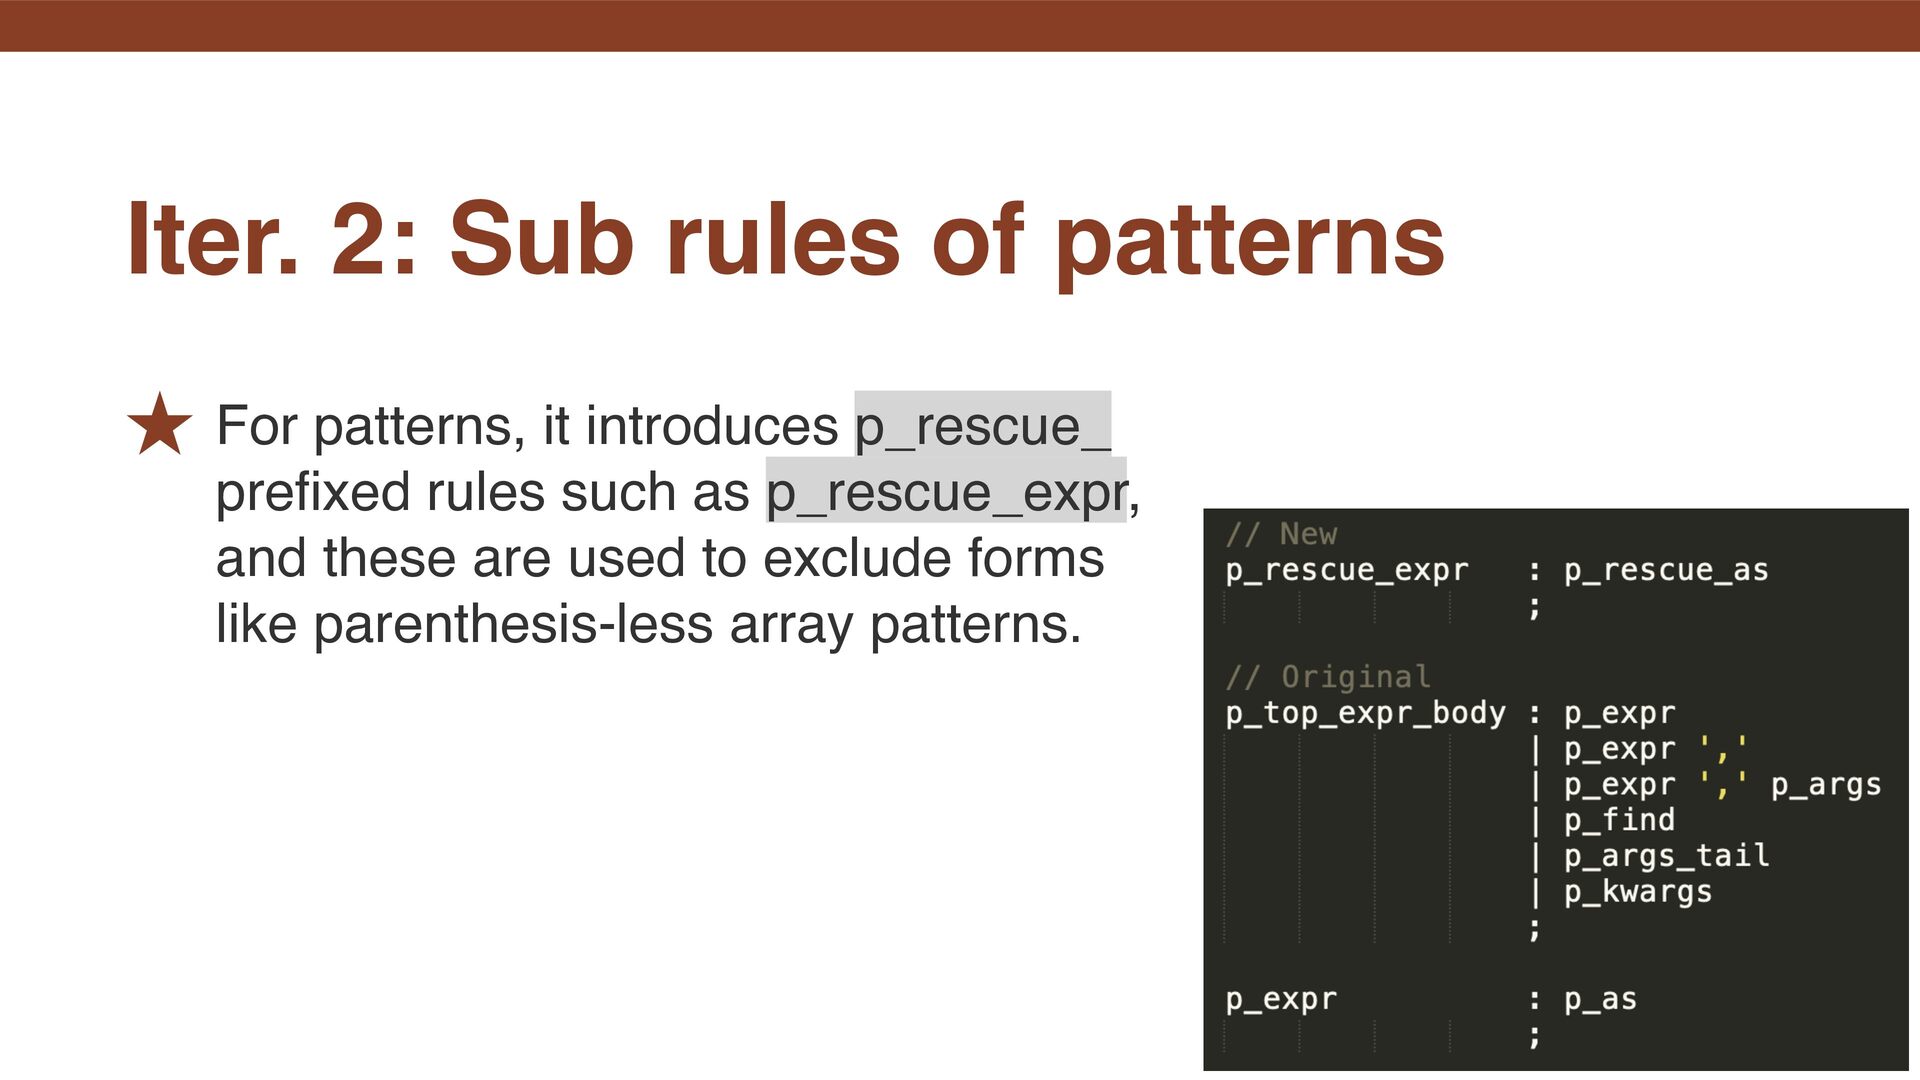
˒ For patterns, it introduces p_rescue_ pre fi xed rules
such as p_rescue_expr, and these are used to exclude forms like parenthesis-less array patterns. Iter. 2: Sub rules of patterns -
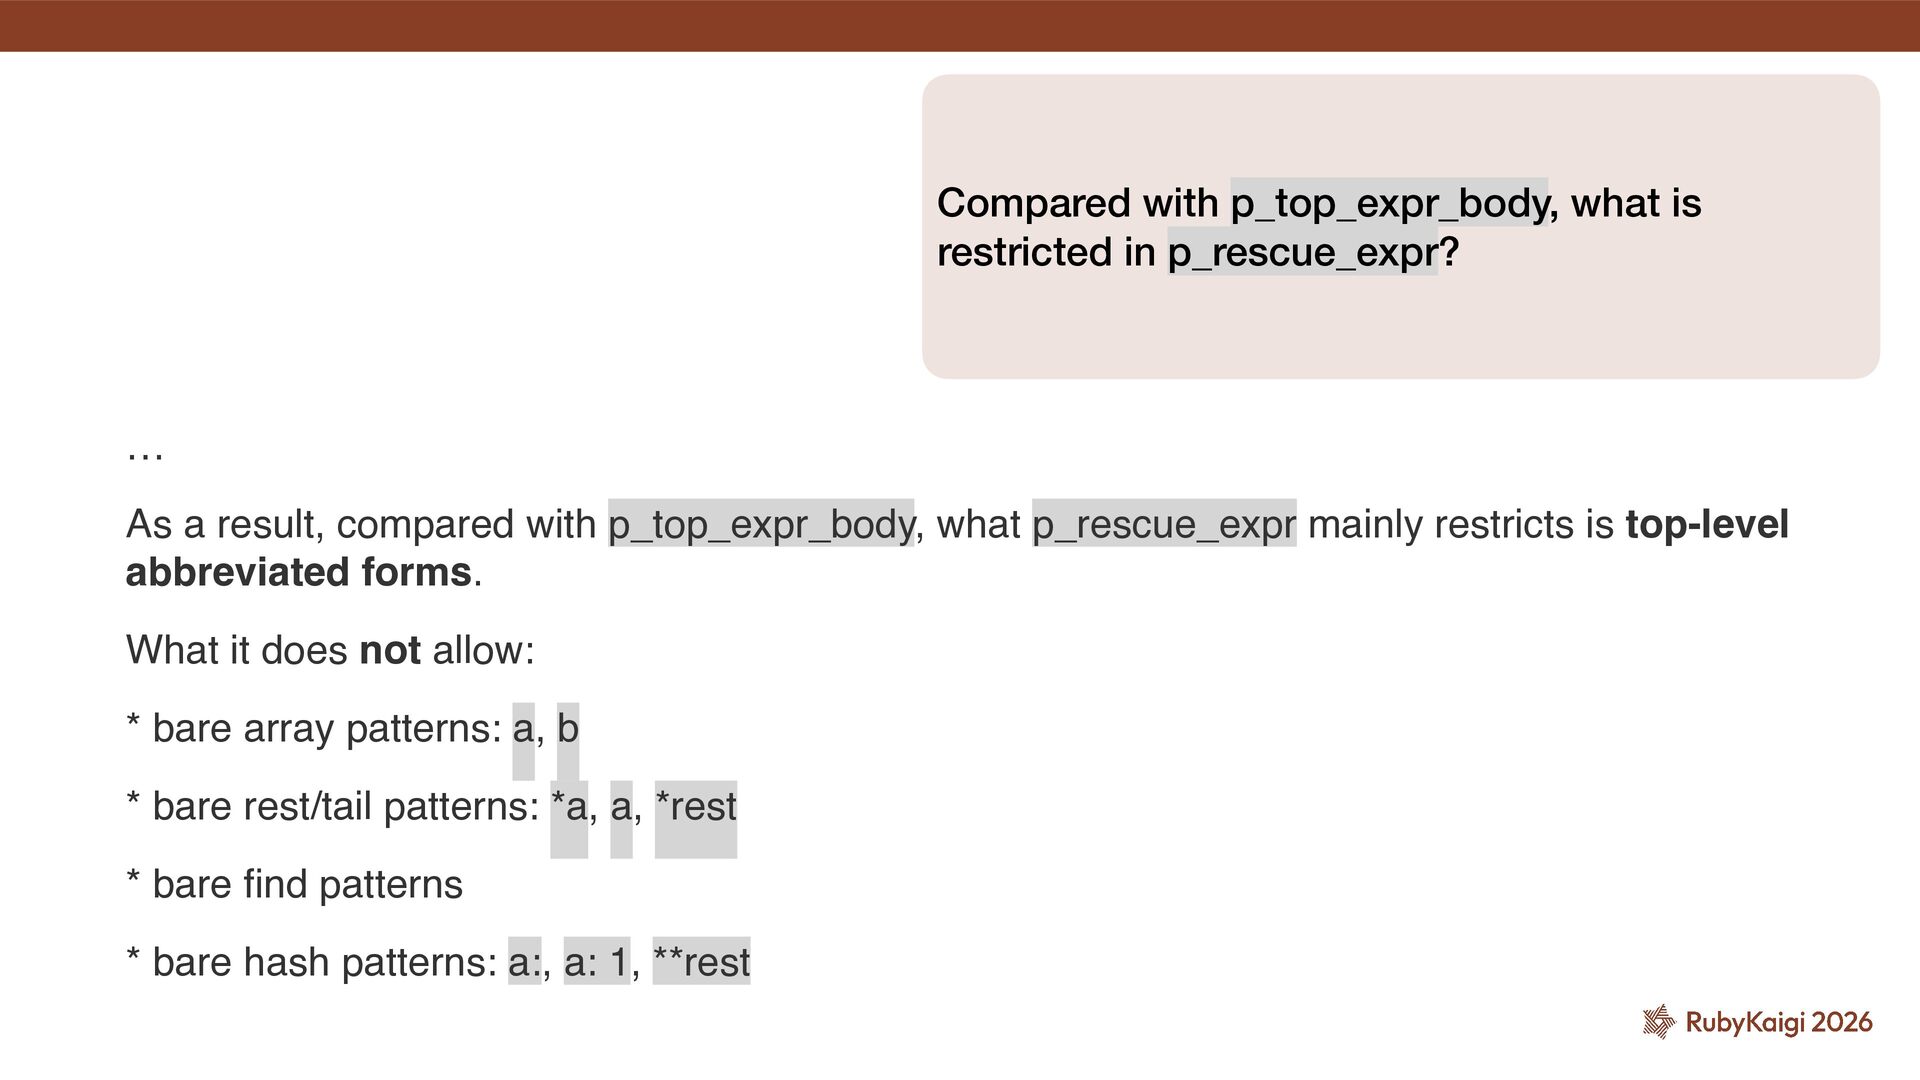
Compared with p_top_expr_body, what is restricted in p_rescue_expr? … As
a result, compared with p_top_expr_body, what p_rescue_expr mainly restricts is top-level abbreviated forms. What it does not allow: * bare array patterns: a, b * bare rest/tail patterns: *a, a, *rest * bare fi nd patterns * bare hash patterns: a:, a: 1, **rest -
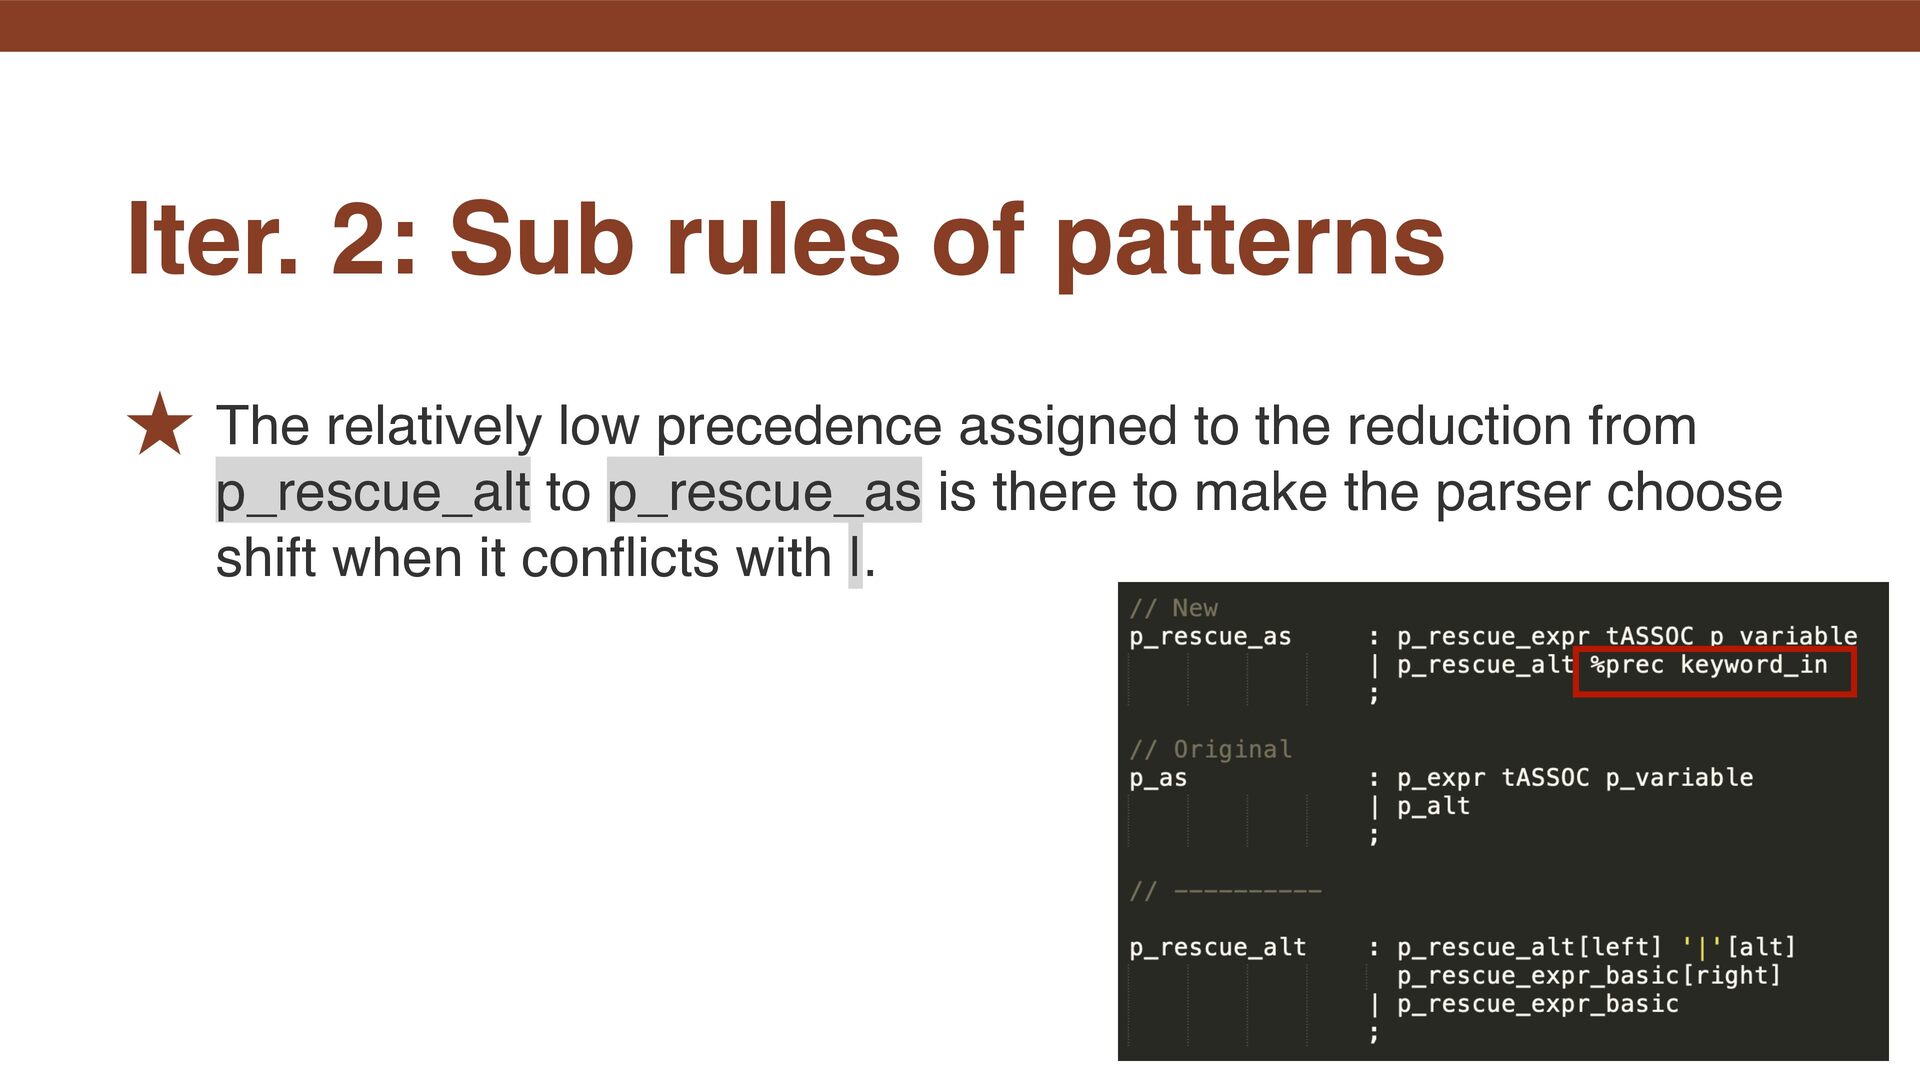
˒ The relatively low precedence assigned to the reduction from
p_rescue_alt to p_rescue_as is there to make the parser choose shift when it con fl icts with |. Iter. 2: Sub rules of patterns -
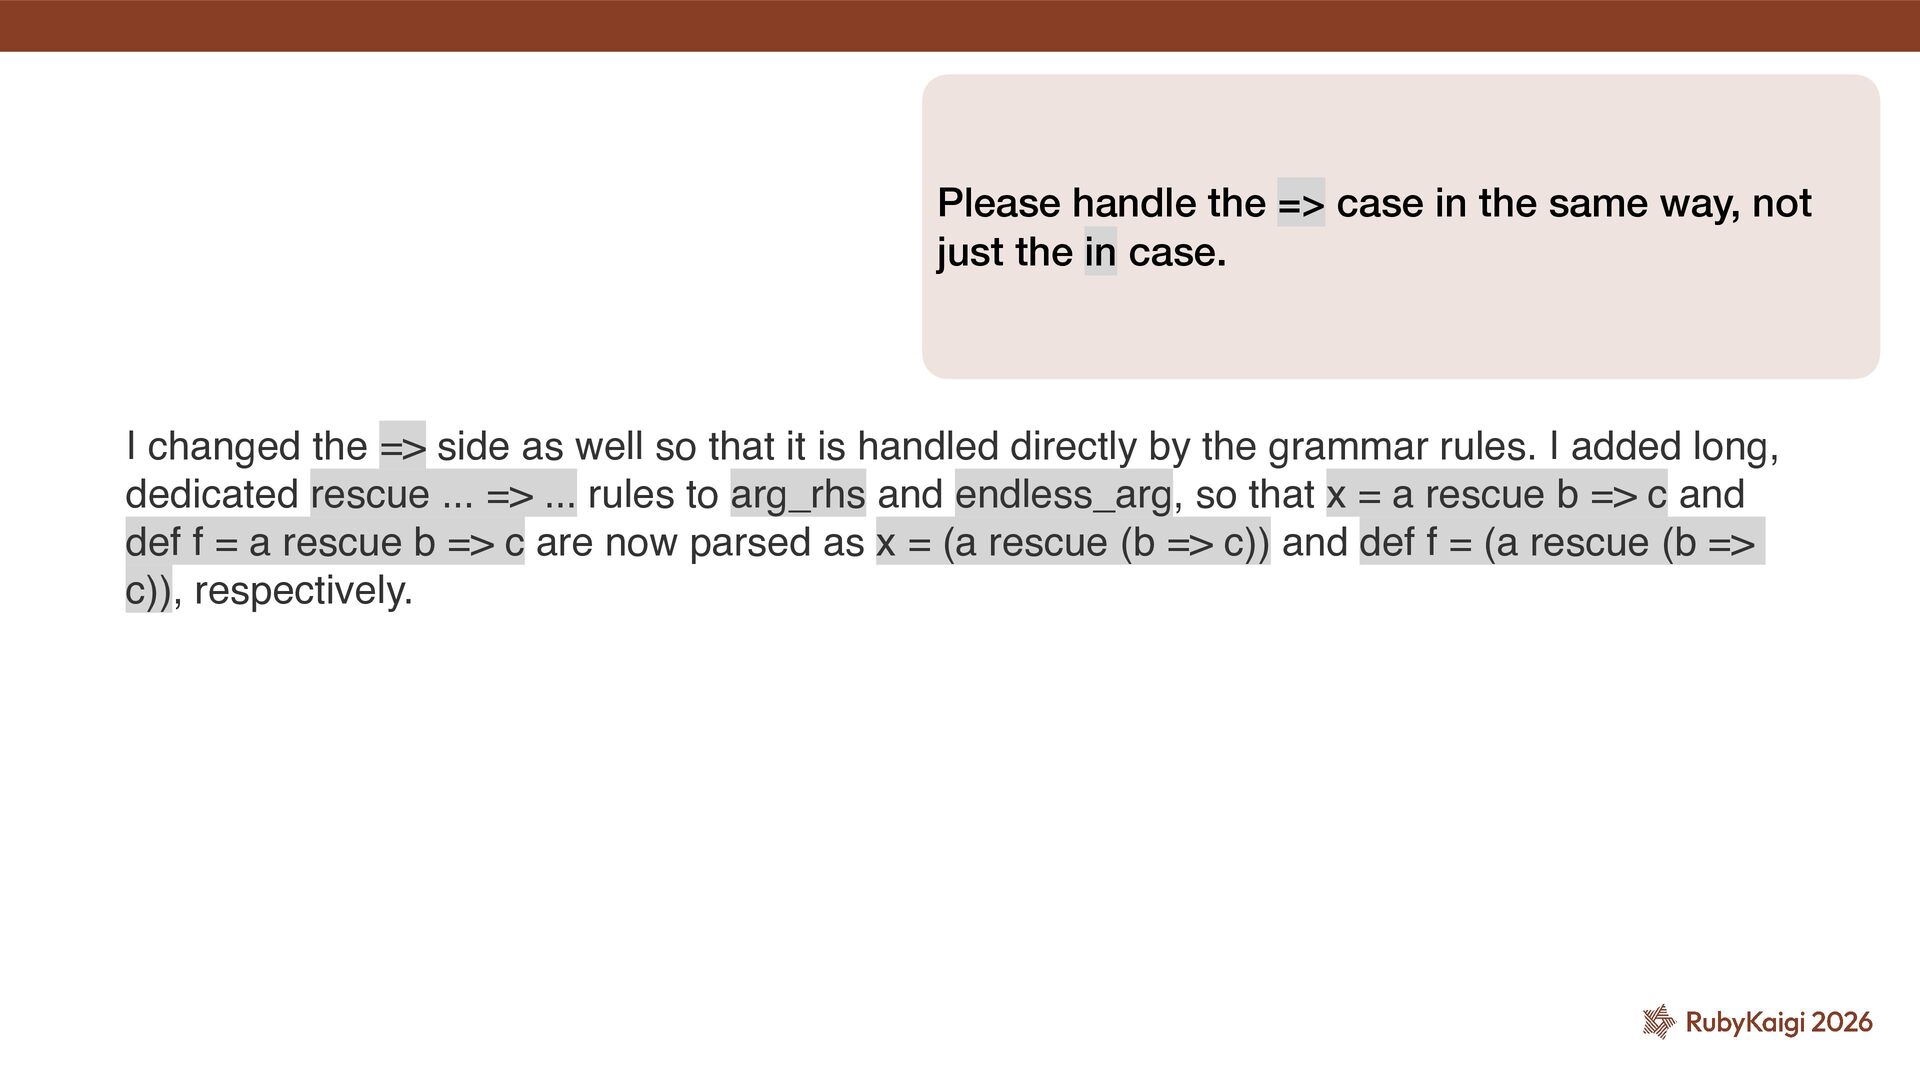
Please handle the => case in the same way, not
just the in case. I changed the => side as well so that it is handled directly by the grammar rules. I added long, dedicated rescue ... => ... rules to arg_rhs and endless_arg, so that x = a rescue b => c and def f = a rescue b => c are now parsed as x = (a rescue (b => c)) and def f = (a rescue (b => c)), respectively. -
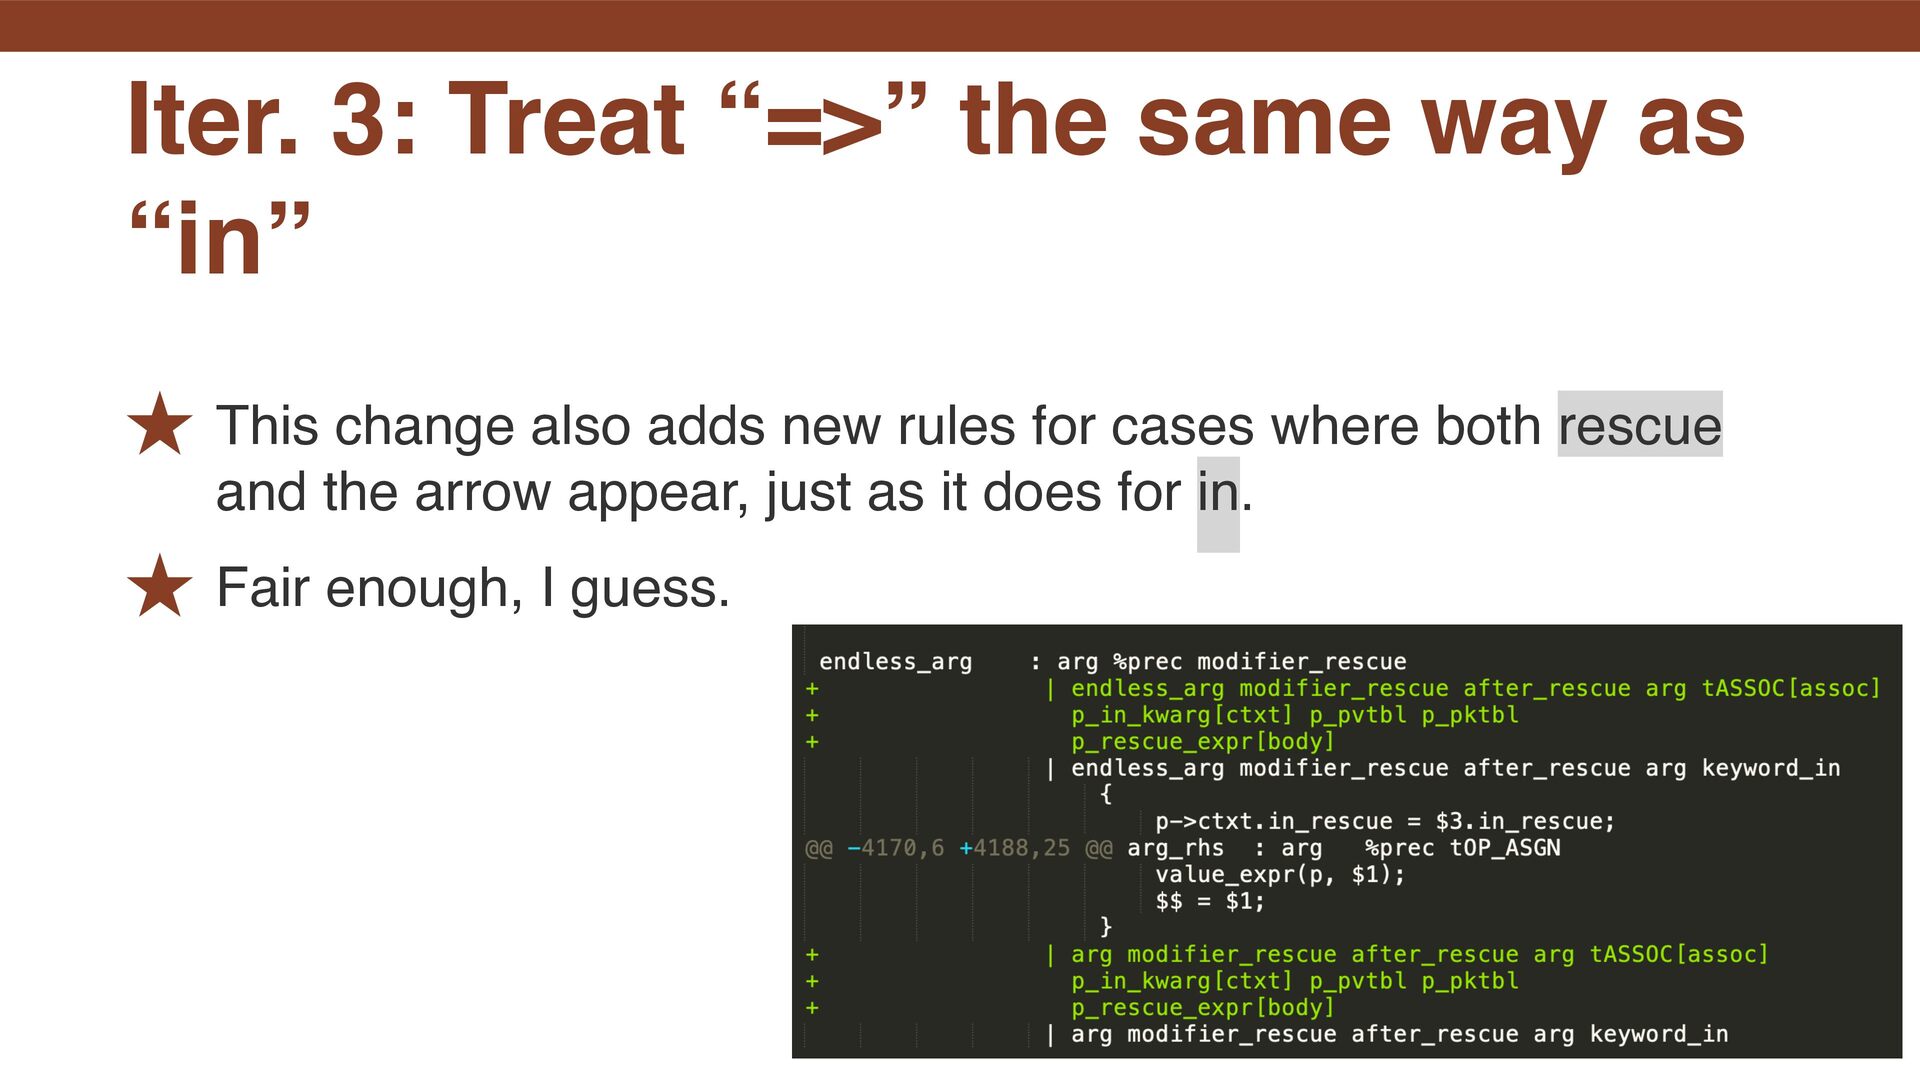
˒ This change also adds new rules for cases where
both rescue and the arrow appear, just as it does for in. ˒ Fair enough, I guess. Iter. 3: Treat “=>” the same way as “in” -
˒ Other approaches are possible, but the approach taken here—
adding restrictions to patterns—is also one worth considering. ˒ Allow it only in assignments that aren't arg rule ˒ As for the implementation, I would like to see it shared a bit more with the existing rules. ˒ That would require adding new functionality to the generator. ˒ Overall, it is not as bad as I expected. Impressions -
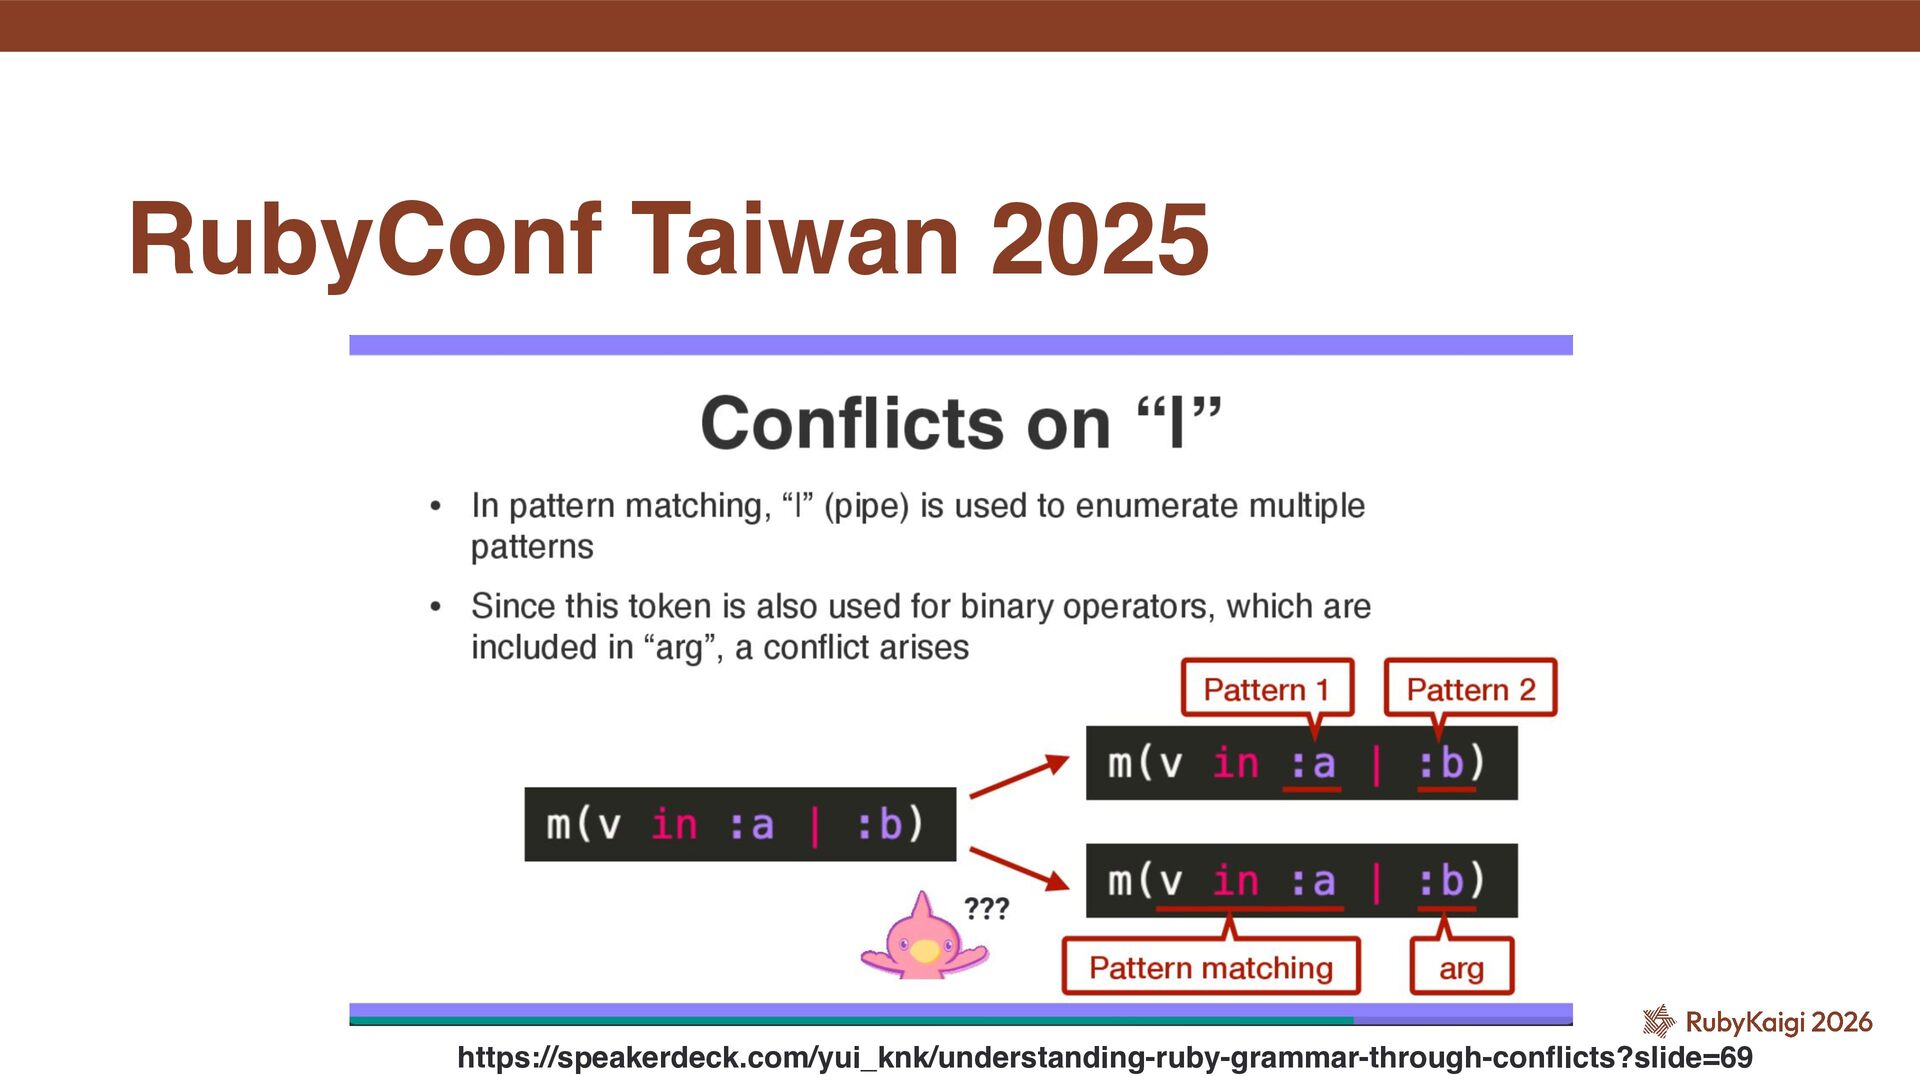
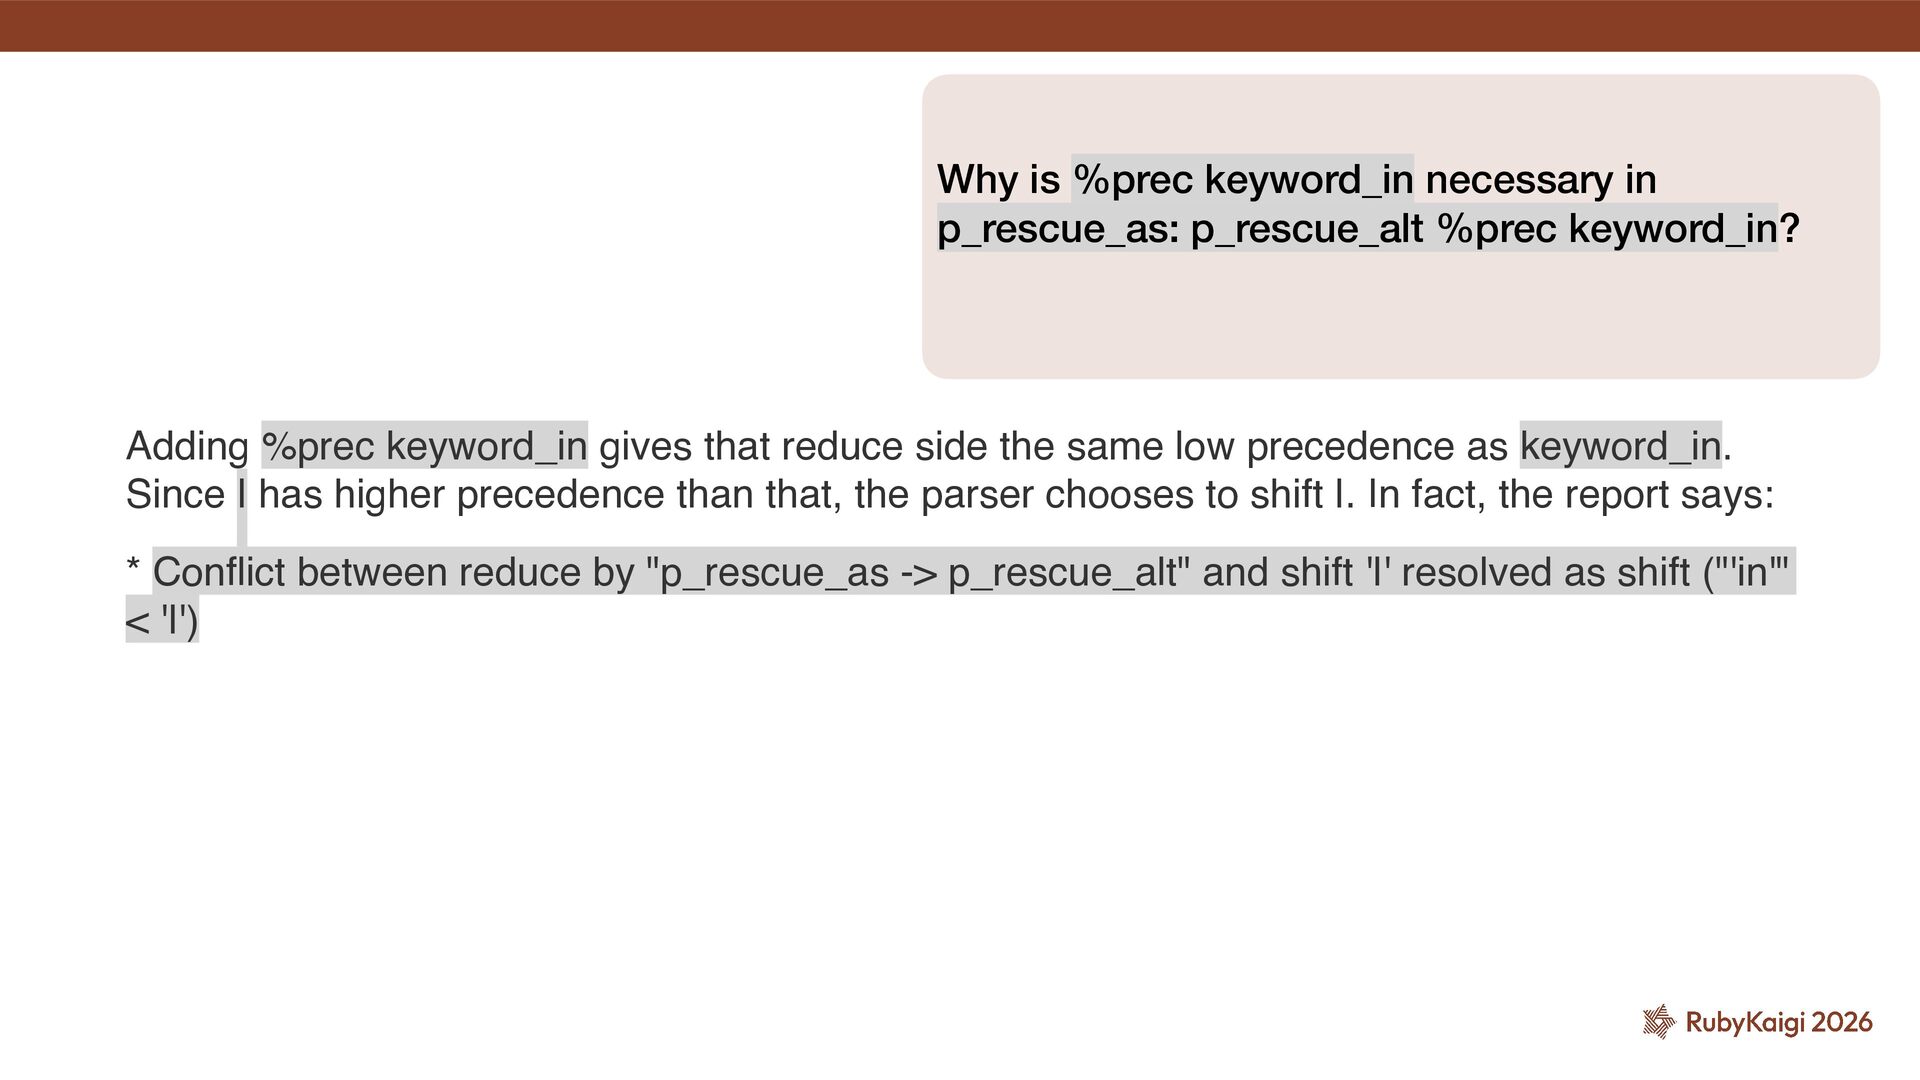
Why is %prec keyword_in necessary in p_rescue_as: p_rescue_alt %prec keyword_in?
Adding %prec keyword_in gives that reduce side the same low precedence as keyword_in. Since | has higher precedence than that, the parser chooses to shift |. In fact, the report says: * Con fl ict between reduce by "p_rescue_as -> p_rescue_alt" and shift '|' resolved as shift ("'in'" < '|') -
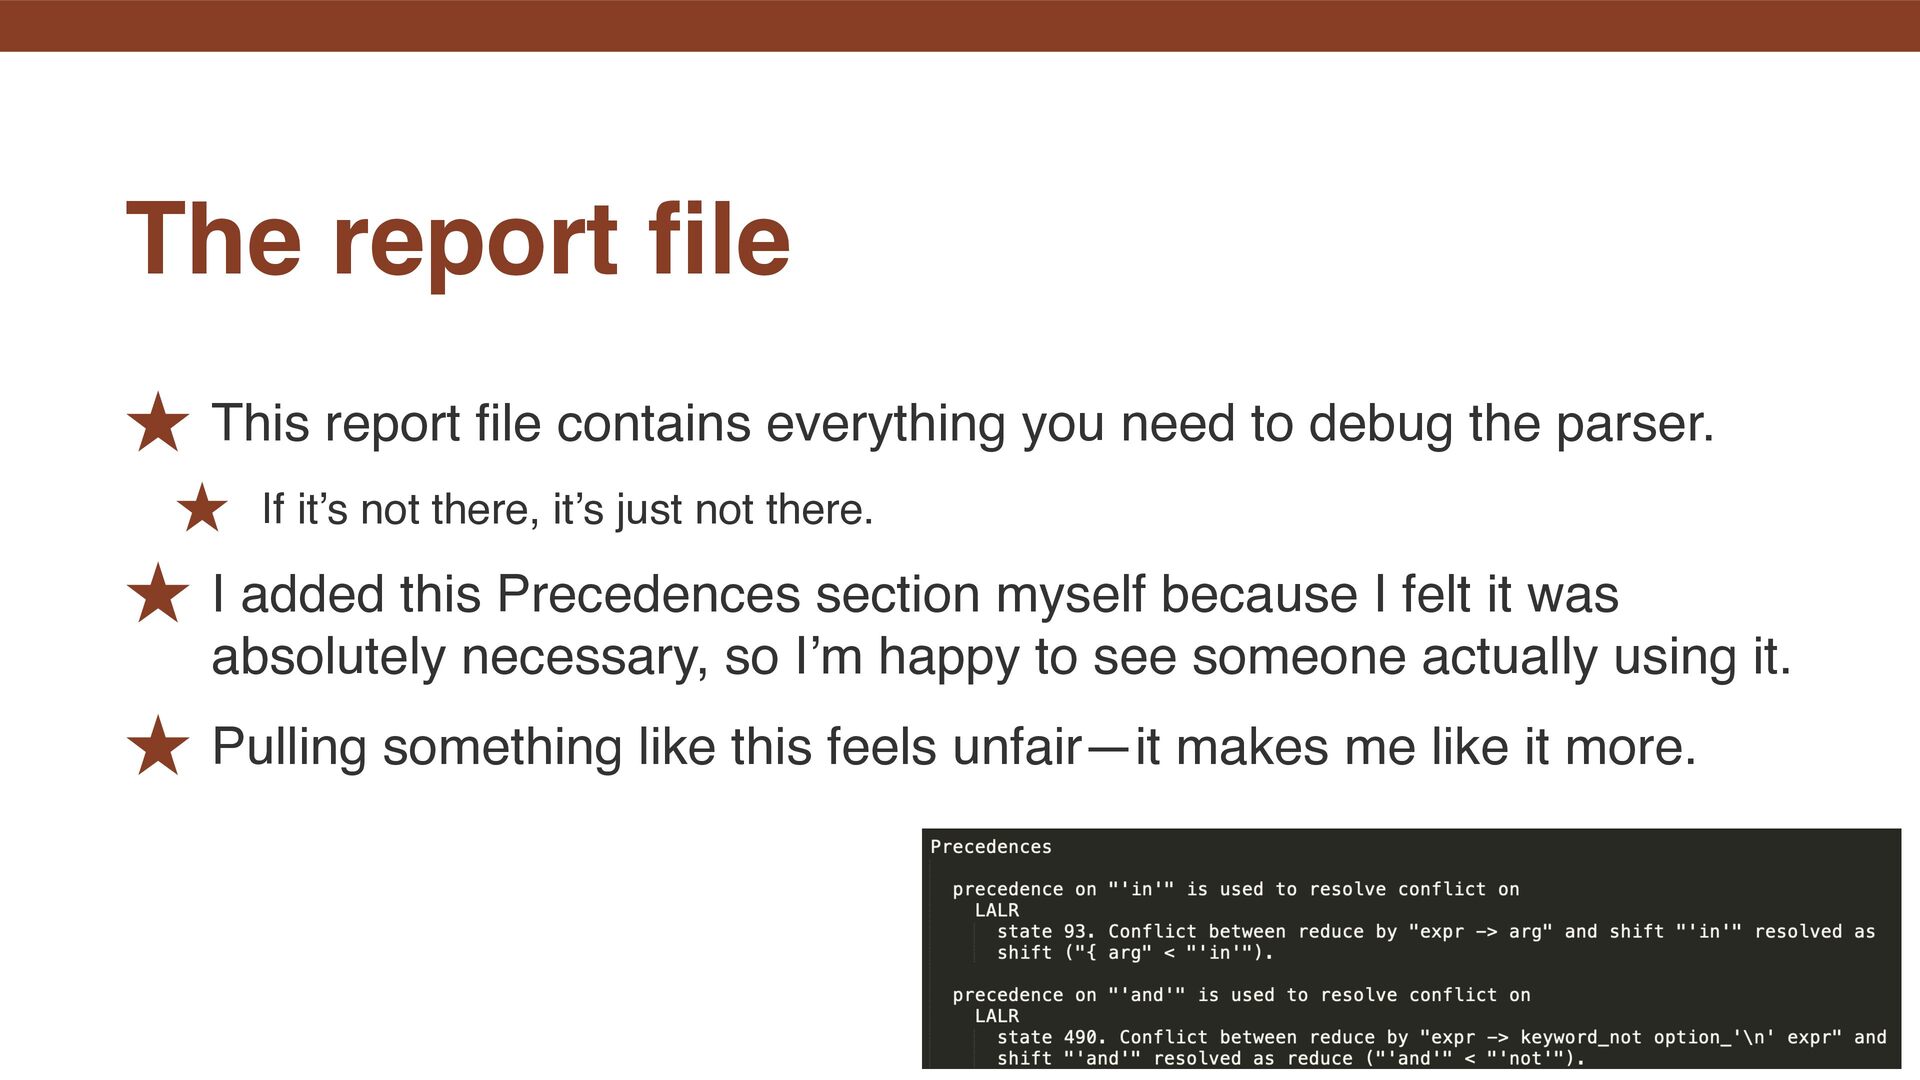
˒ This report fi le contains everything you need to
debug the parser. ˒ If it’s not there, it’s just not there. ˒ I added this Precedences section myself because I felt it was absolutely necessary, so I’m happy to see someone actually using it. ˒ Pulling something like this feels unfair—it makes me like it more. The report fi le
 yui_knk
 kitano_yuichi
 onozaty
 uwabami
 omatty198
 yuuu
 hasutosasaki
 kasacchiful
 ostk0069
 steliosf
 sakawe_ee
 nextbeatdev
 nnaka2992
 dugsong
 akademiya2063
 inesmontani
 nikkihalliwell
 marktimemedia
 addyosmani
 jonrohan
 chriscoyier
 reverentgeek
 raygrieselhuber
 tamaranovitovic
 tmiket