Share
Embed
Introduction to High Performance Computing
Introductory talk on high-performance computing concepts, aimed at an actuarial audience familiar with computational challenges but not with computing at scale.
Given at the Life & Annuity 2011 Symposium of the Society of Actuaries in New Orleans, on behalf of my employer at the time, R Systems NA, Inc. http://www.r-hpc.com/
Adam DeConinck
May 01, 2011
Transcript
24 slides
-
2 Development of models begins at small scale. Working on
your laptop is convenient, simple. Actual analysis, however, is slow. -
3 Development of models begins at small scale. Working on
your laptop is convenient, simple. Actual analysis, however, is slow. “Scaling up” typically means a small server or fast multi-core desktop. Speedup exists, but for very large models, not significant. Single machines don't scale up forever. -
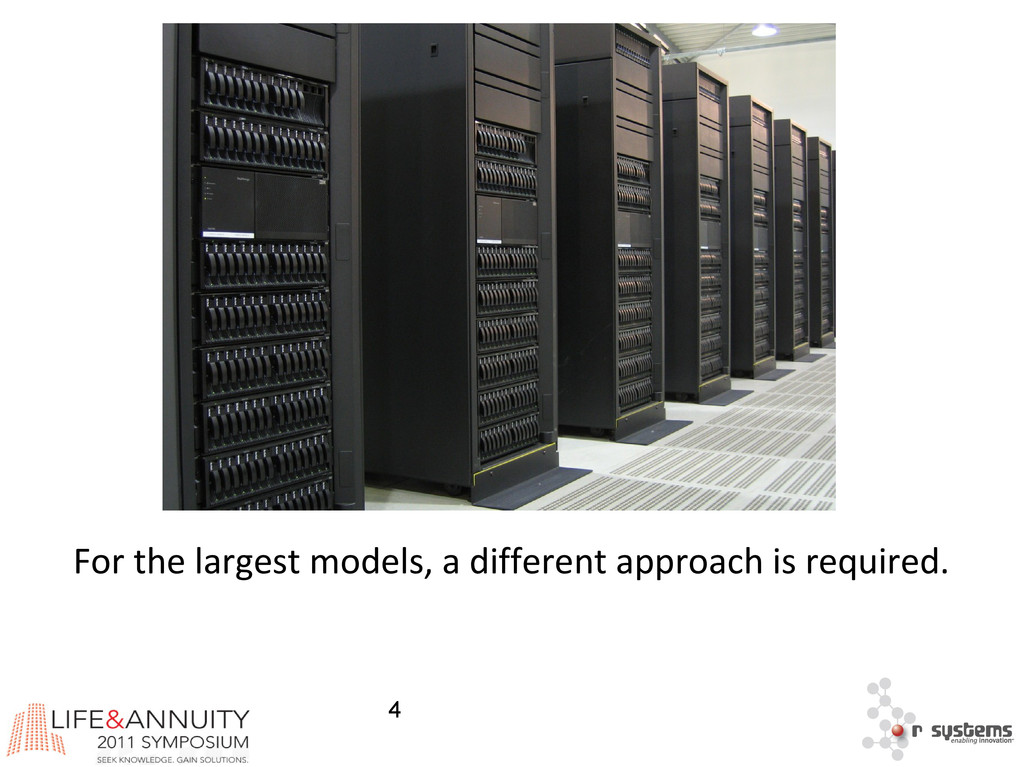
5 High-Performance Computing involves many distinct computer processors working together
on the same calculation. Large problems are divided into smaller parts and distributed among the many computers. Usually clusters of quasi-independent computers which are coordinated by a central scheduler. -
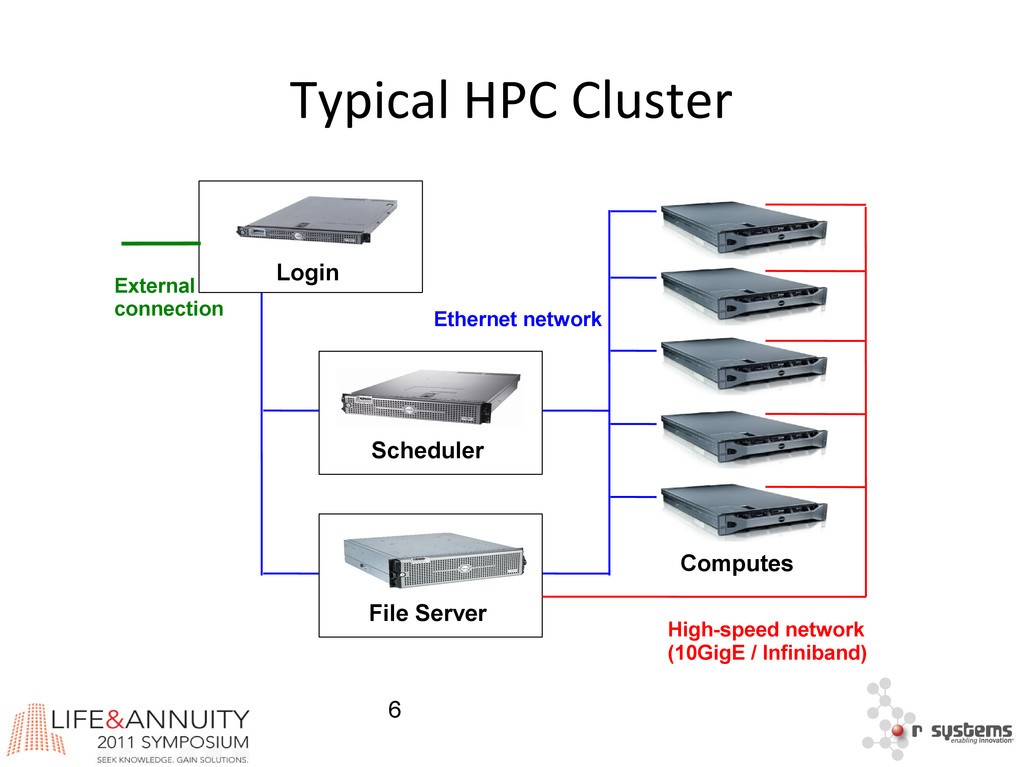
6 Typical HPC Cluster Scheduler File Server Ethernet network High-speed
network (10GigE / Infiniband) Computes Login External connection -
7 Performance test: stochastic finance model on R Systems
cluster High-end workstation: 8 cores. Maximum speedup of 20x: 4.5 hrs → 14 minutes Scale-up heavily model-dependent: 5x – 100x in our tests, can be faster No more performance gain after ~500 cores: why? Some operations can't be parallelized. Additional cores? Run multiple models simultaneously Performance gains Number of cores Duration (s) High-end workstation -
8 Performance comes at a price: complexity. New paradigm:
real-time analysis vs batch jobs. Applications must be written specifically to take advantage of distributed computing. Performance characteristics of applications change. Debugging becomes more of a challenge. -
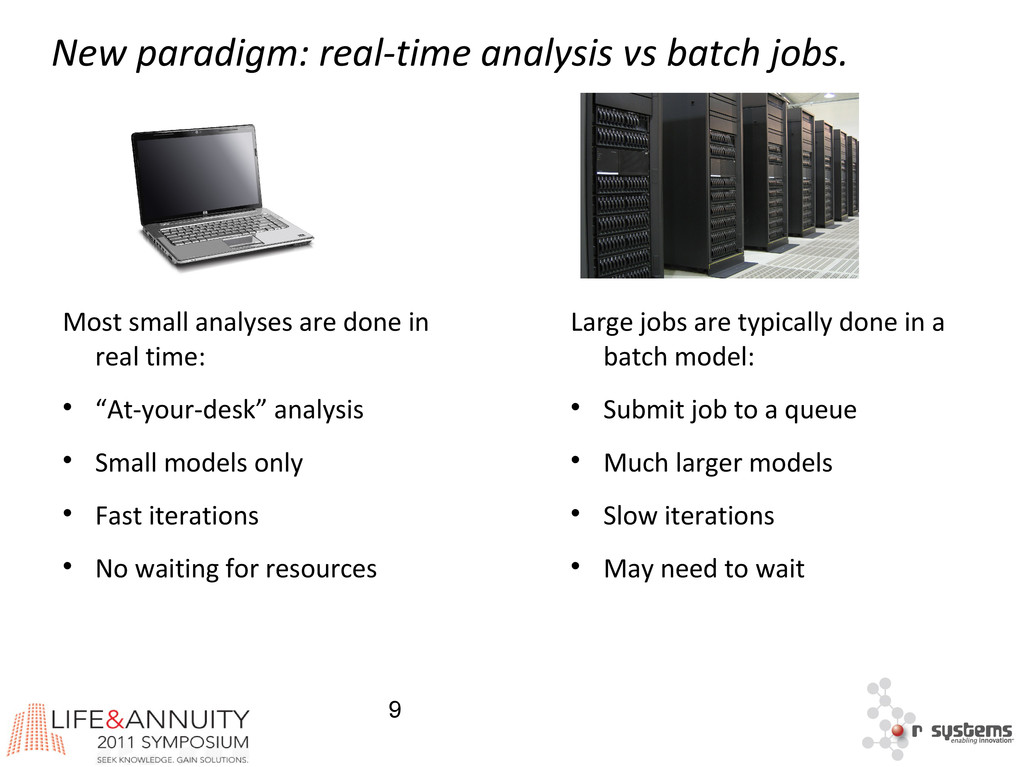
9 New paradigm: real-time analysis vs batch jobs. Most small
analyses are done in real time: “At-your-desk” analysis Small models only Fast iterations No waiting for resources Large jobs are typically done in a batch model: Submit job to a queue Much larger models Slow iterations May need to wait -
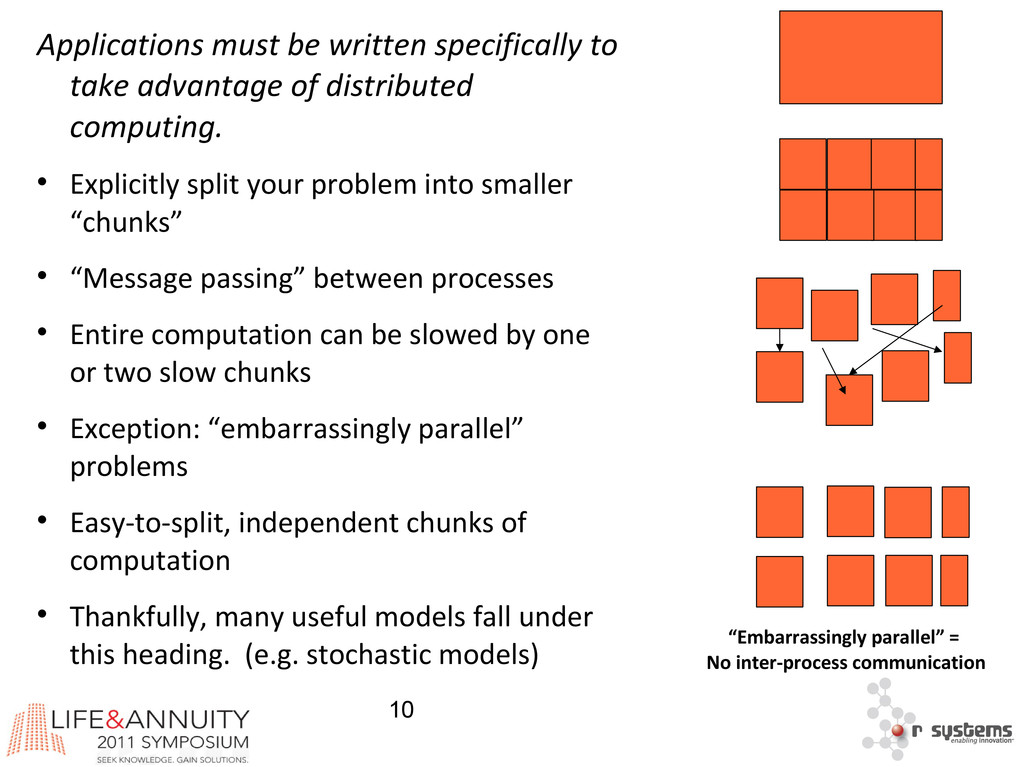
10 Applications must be written specifically to take advantage of
distributed computing. Explicitly split your problem into smaller “chunks” “Message passing” between processes Entire computation can be slowed by one or two slow chunks Exception: “embarrassingly parallel” problems Easy-to-split, independent chunks of computation Thankfully, many useful models fall under this heading. (e.g. stochastic models) “Embarrassingly parallel” = No inter-process communication -
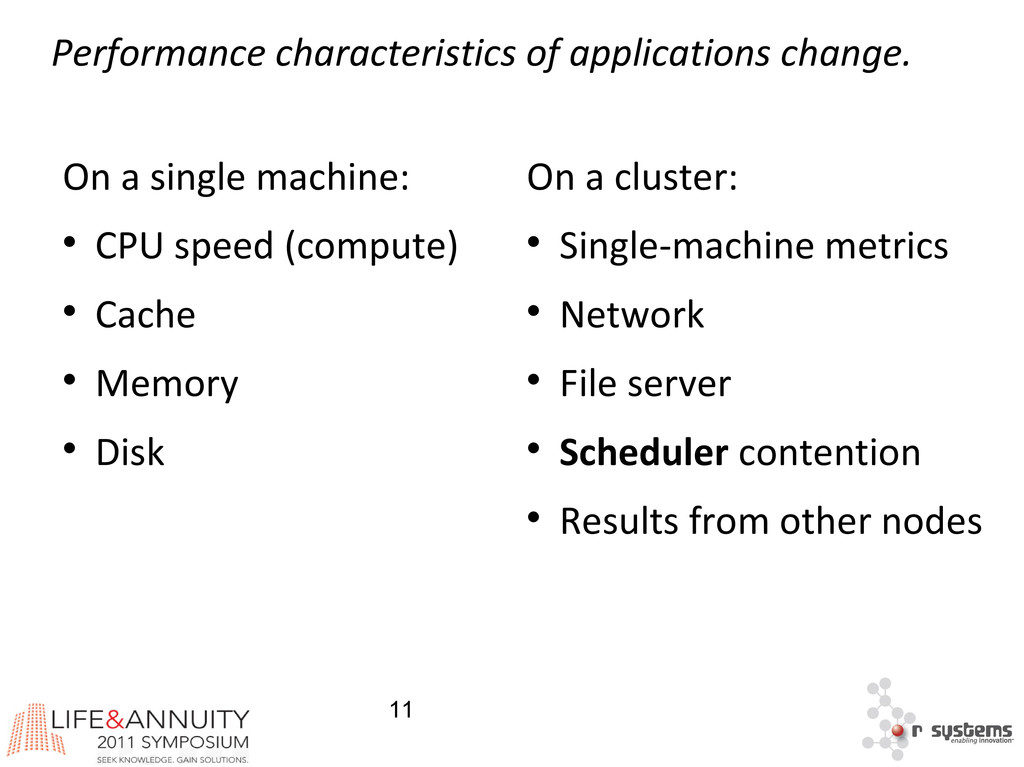
11 Performance characteristics of applications change. On a single machine:
CPU speed (compute) Cache Memory Disk On a cluster: Single-machine metrics Network File server Scheduler contention Results from other nodes -
12 Debugging becomes more of a challenge. More complexity
= more pieces that can fail Race conditions: sequence of events no longer deterministic Single nodes can “stall” and slow the entire computation Scheduler, file server, login server all have their own challenges -
13 External resources One solution to handling complexity: outsource
it! Historical HPC facilities: universities, national labs Often have the most absolute compute capacity, and will sell excess capacity Competition with academic projects, typically do not include SLA or high-level support Dedicated commercial HPC facilities providing “on-demand” compute power. -
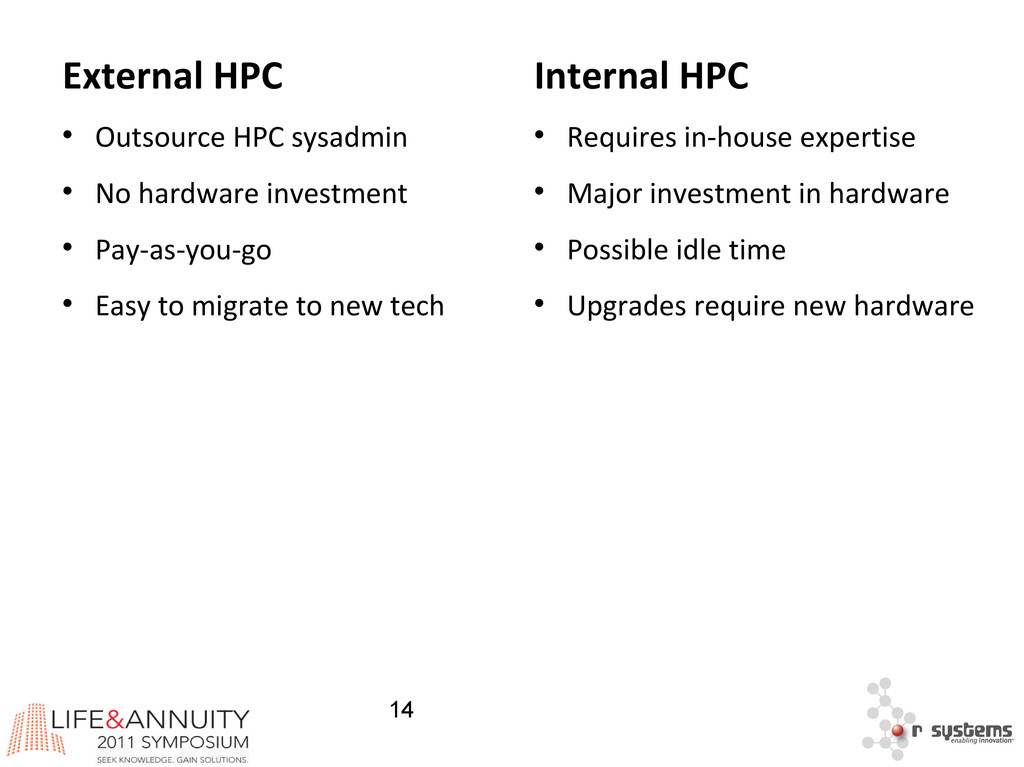
14 External HPC Outsource HPC sysadmin No hardware
investment Pay-as-you-go Easy to migrate to new tech Internal HPC Requires in-house expertise Major investment in hardware Possible idle time Upgrades require new hardware -
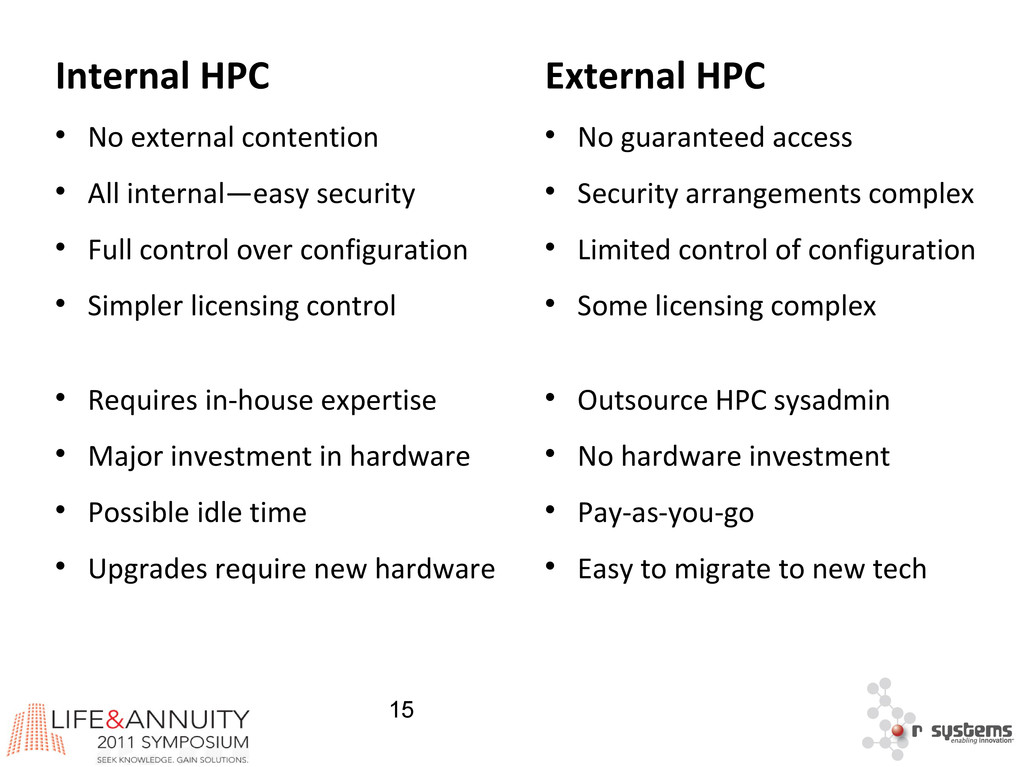
15 External HPC No guaranteed access Security arrangements
complex Limited control of configuration Some licensing complex Outsource HPC sysadmin No hardware investment Pay-as-you-go Easy to migrate to new tech Internal HPC No external contention All internal—easy security Full control over configuration Simpler licensing control Requires in-house expertise Major investment in hardware Possible idle time Upgrades require new hardware -
16 “The Cloud” “Cloud computing”: virtual machines, dynamic allocation
of resources in an external resource Lower performance (virtualization), higher flexibility Usually no contracts necessary: pay with your credit card, get 16 nodes Often have to do all your own sysadmin Low support, high control -
18 Global insurance company Needed 500-1000 cores on a
temporary basis Preferred a utility, “pay-as-you-go” model Experimenting with external resources for “burst” capacity during high-activity periods Commercially licensed and supported application Requested a proof of concept -
19 Cluster configuration Application embarrassingly parallel, small-to-medium data files,
computationally and memory-intensive Prioritize computation (processors), access to fileserver over inter-node communication, large storage Upgraded memory in compute nodes to 2 GB/core 128-node cluster: 3.0 GHz Intel Xeon processors, 8 cores per node for 1024 cores total Windows 2008 HPC R2 operating system Application and fileserver on login node -
20 Stumbling blocks Application optimization Customer had a wide
variety of models which generated different usage patterns. (IO, compute, memory-intensive jobs) Required dynamic reconfiguration for different conditions. Technical issue Iterative testing process. Application turned out to be generating massive fileserver contention. Had to make changes to both software and hardware. Human processes Users were accustomed to internal access model. Required changes both for providers (increase ease-of-use) and users (change workflow) Security Customer had never worked with an external provider before. Complex internal security policy had to be reconciled with remote access. -
21 Lessons learned: Security was the biggest delaying factor.
The initial security setup took over 3 months from the first expression of interest, even though cluster setup was done in less than a week. Only mattered the first time though: subsequent runs started much more smoothly. A low-cost proof-of-concept run was important to demonstrate feasibility, and for working the bugs out. A good relationship with the application vendor was extremely important to solving problems and properly optimizing the model for performance. -
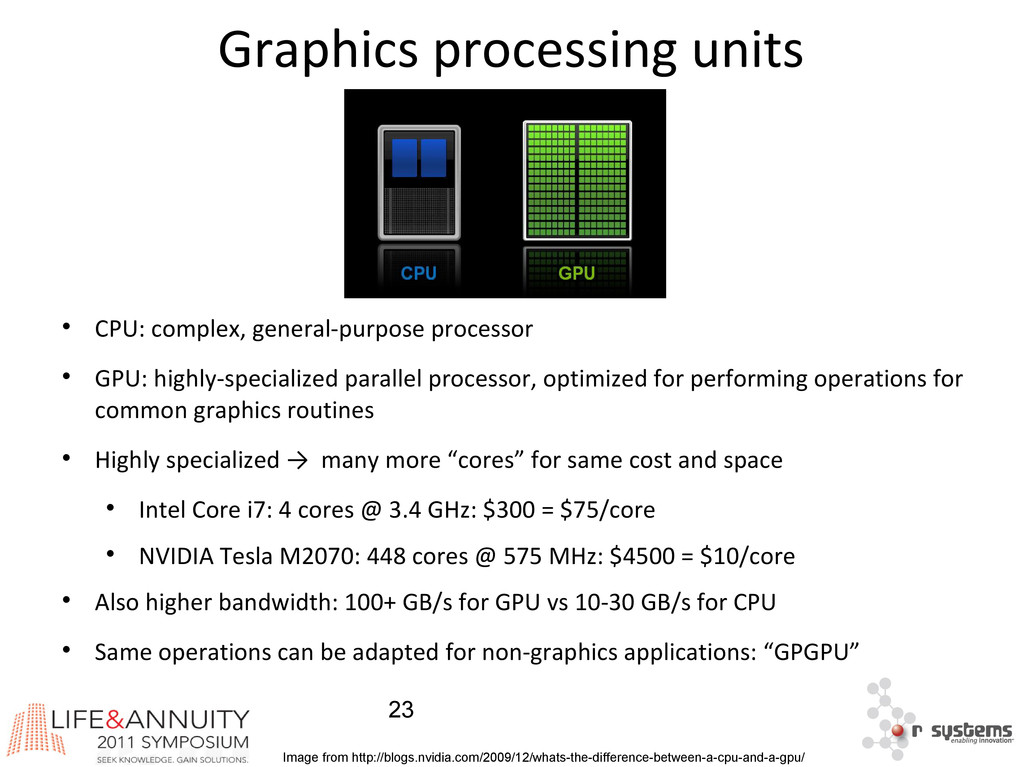
23 Graphics processing units CPU: complex, general-purpose processor
GPU: highly-specialized parallel processor, optimized for performing operations for common graphics routines Highly specialized → many more “cores” for same cost and space Intel Core i7: 4 cores @ 3.4 GHz: $300 = $75/core NVIDIA Tesla M2070: 448 cores @ 575 MHz: $4500 = $10/core Also higher bandwidth: 100+ GB/s for GPU vs 10-30 GB/s for CPU Same operations can be adapted for non-graphics applications: “GPGPU” Image from http://blogs.nvidia.com/2009/12/whats-the-difference-between-a-cpu-and-a-gpu/ -
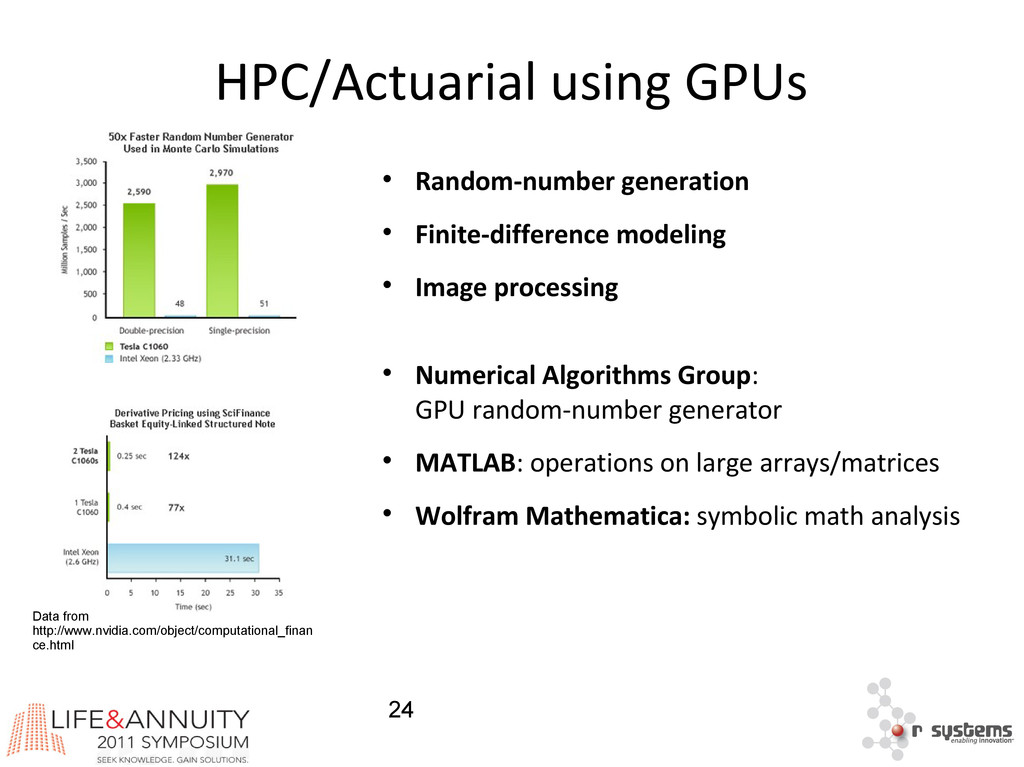
24 HPC/Actuarial using GPUs Random-number generation Finite-difference modeling
Image processing Numerical Algorithms Group: GPU random-number generator MATLAB: operations on large arrays/matrices Wolfram Mathematica: symbolic math analysis Data from http://www.nvidia.com/object/computational_finan ce.html