With reporting & analytics team. • Work on distributed systems • Near* real-time and explorative analytics systems • I also love ops (more like eliminating ops)
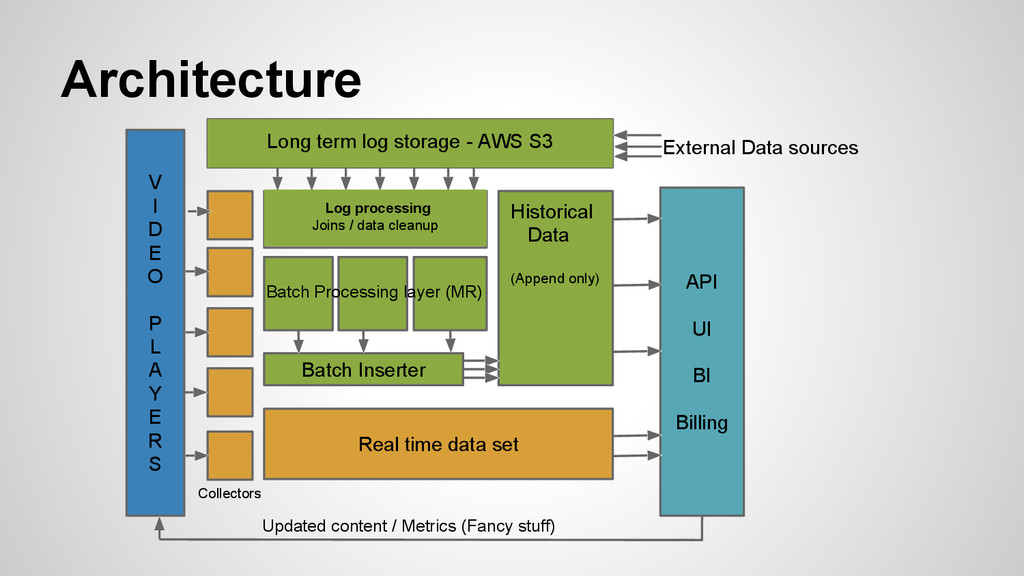
E R S Real time data set API UI BI Billing Historical Data (Append only) Batch Inserter Long term log storage - AWS S3 Log processing Joins / data cleanup Batch Processing layer (MR) Collectors Updated content / Metrics (Fancy stuff) External Data sources
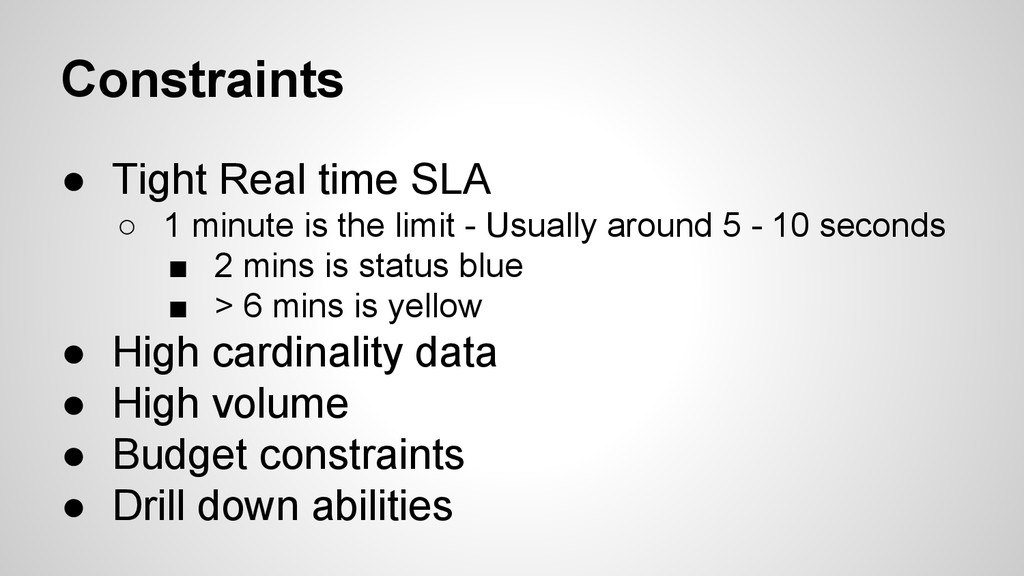
the limit - Usually around 5 - 10 seconds ▪ 2 mins is status blue ▪ > 6 mins is yellow • High cardinality data • High volume • Budget constraints • Drill down abilities
not free • Chunk migrations will kill you • A server restart may kill your oplog • Large datasets will kill you • Indexes will kill you (again) • Even deletes will kill you!
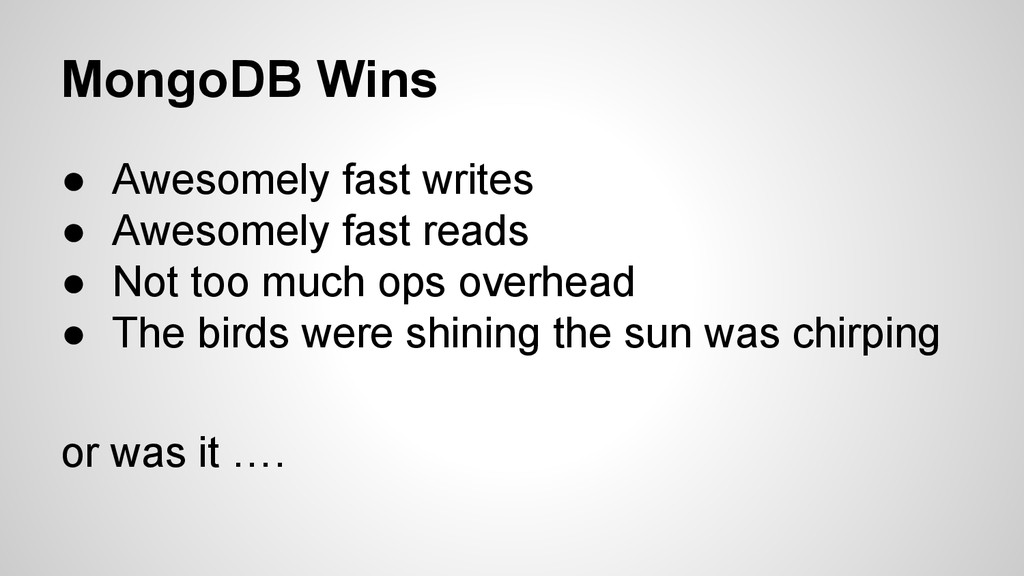
love with em’ but don’t know why! ◦ Simple to understand ◦ Query language makes sense ◦ Freedom to evolve schemas • But we were spending most of our time doing OPS.
◦ Indexes too big ◦ Replication is janky! ◦ We live in the real-world! ◦ Mongo support in general was not very helpful. SPIKE # 2: Find a database that works!
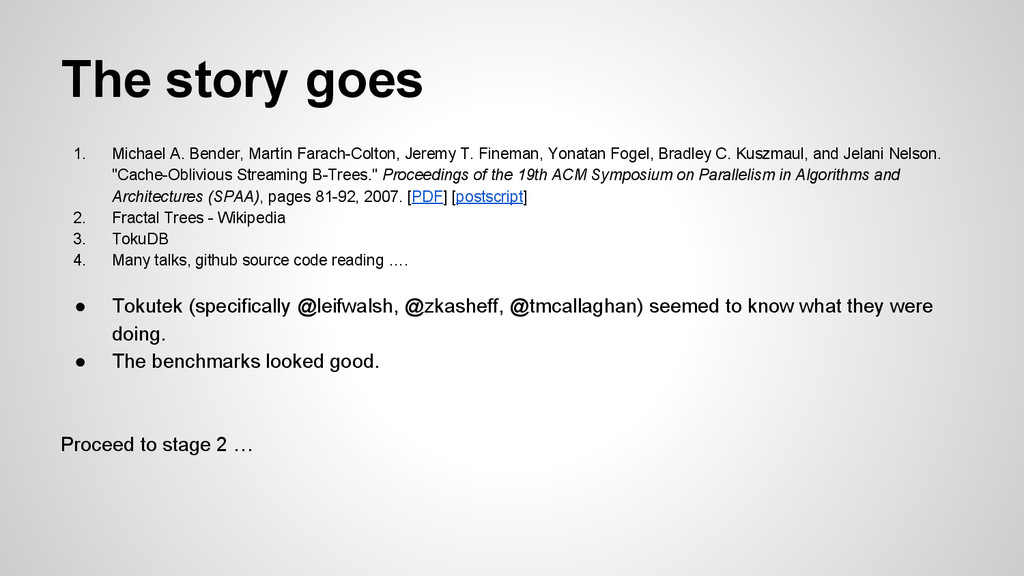
T. Fineman, Yonatan Fogel, Bradley C. Kuszmaul, and Jelani Nelson. "Cache-Oblivious Streaming B-Trees." Proceedings of the 19th ACM Symposium on Parallelism in Algorithms and Architectures (SPAA), pages 81-92, 2007. [PDF] [postscript] 2. Fractal Trees - Wikipedia 3. TokuDB 4. Many talks, github source code reading …. • Tokutek (specifically @leifwalsh, @zkasheff, @tmcallaghan) seemed to know what they were doing. • The benchmarks looked good. Proceed to stage 2 …
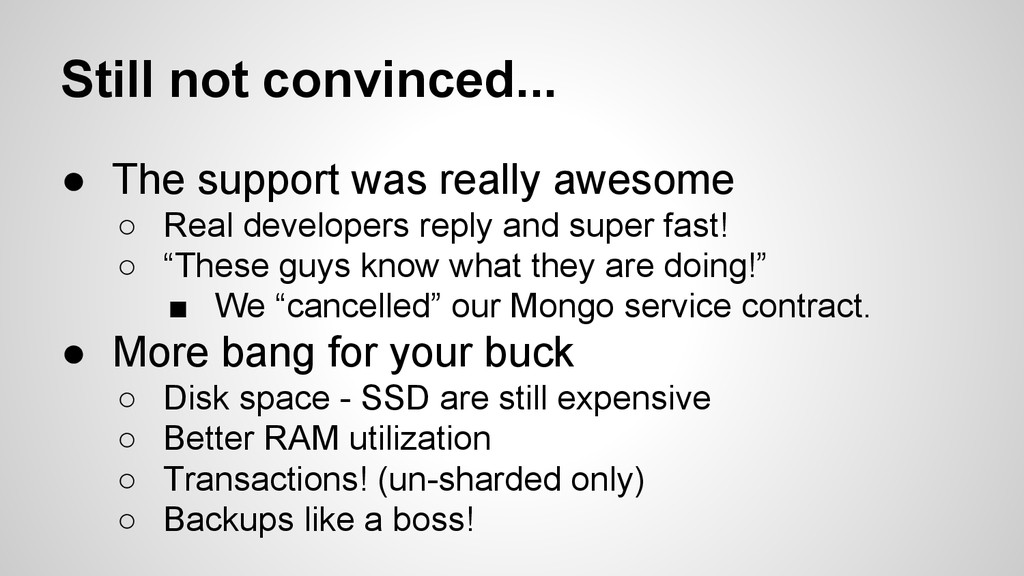
Real developers reply and super fast! ◦ “These guys know what they are doing!” ▪ We “cancelled” our Mongo service contract. • More bang for your buck ◦ Disk space - SSD are still expensive ◦ Better RAM utilization ◦ Transactions! (un-sharded only) ◦ Backups like a boss!
model ◦ Big insert batches make up for faster repl log ◦ Index behaves differently ◦ More CPU is needed for compression • We don’t add replicas like we used to ◦ HotBackup -> fastsync -> done! • We don’t add batches as we used to ◦ BulkLoad command
with reads • Data model makes a huge difference • If you have lots of data and not enough RAM, use FS page cache (compressed) and set --cacheSize • Get more CPU - that’s a good thing! • Partitioned collections help deletes. • There are more …
• Initial sync of replicas is still uncompressed • Replication algorithm is still not correct ◦ Ark algorithm impl. is in a branch • Transactions via the driver needs squinting.


 ankurcha
 dske104
 palkan
 oniak3ibm
 tomokon
 rkaga
 a_matsuda
 colorful12
 sorah
 akase244
 satoshi256kbyte
 rollbear
 artoy
 mraible
 ipullrank
 addyosmani
 tmiket
 jnunemaker
 gurzu
 wayneb77
 notwaldorf
 aleyda
 rkendrick25
 minecr
 jcasabona