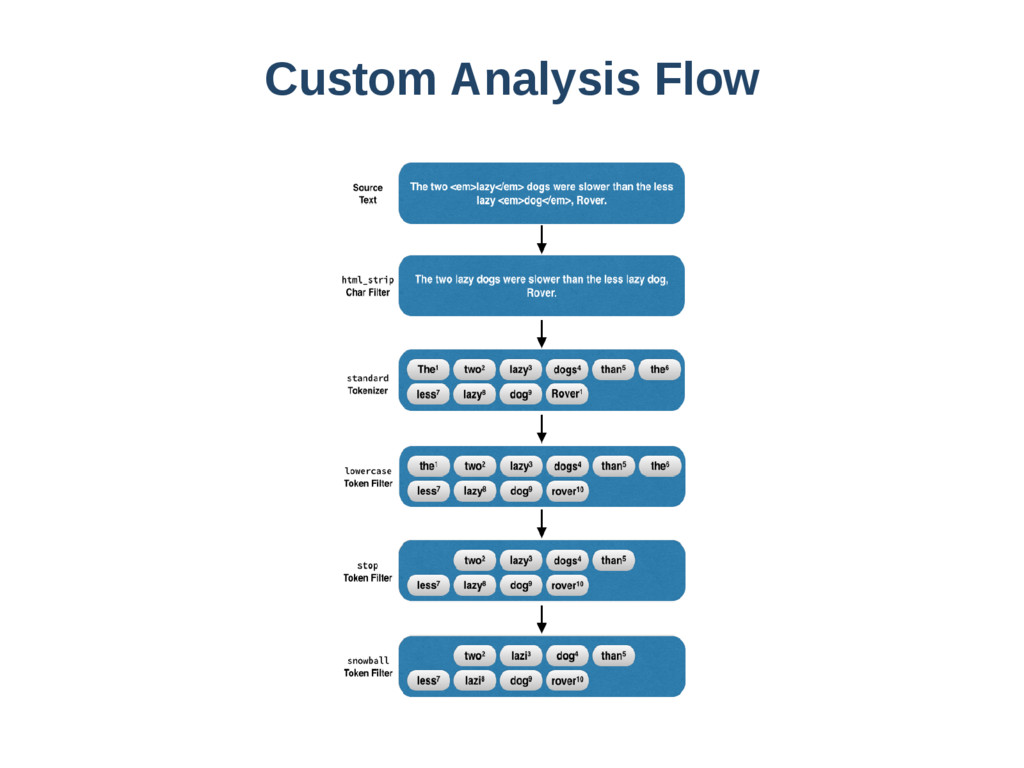
documents that have somewhat similar characteristics[...] An index is like a database in a relational database. It has a mapping which defines multiple types. Mapping A mapping is like a schema definition in a relational database.
table in a relational database. Each type has a list of fields that can be specified for documents of that type. The mapping defines how each field in the document is analyzed. Field A document contains a list of fields, or keyvalue pairs... A field is similar to a column in a table in a relational database.
which is designed to allow very fast fulltext searches. An inverted index consists of a list of all the unique words that appear in any document, and for each word, a list of the documents in which it appears.
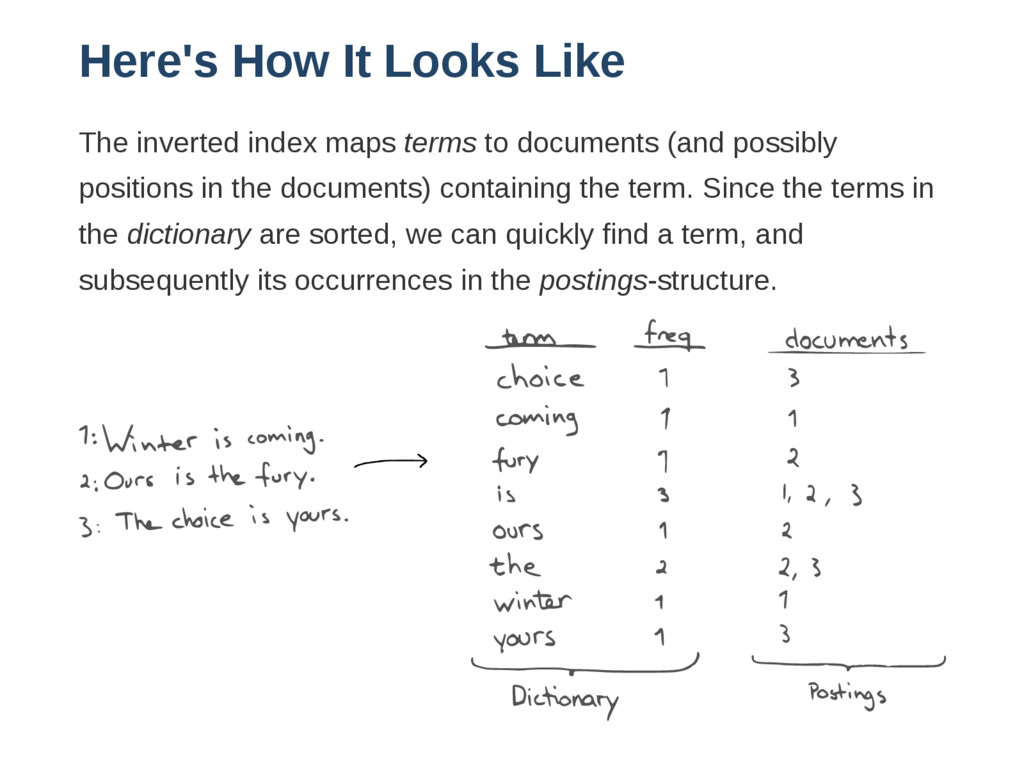
to documents (and possibly positions in the documents) containing the term. Since the terms in the dictionary are sorted, we can quickly find a term, and subsequently its occurrences in the postingsstructure.
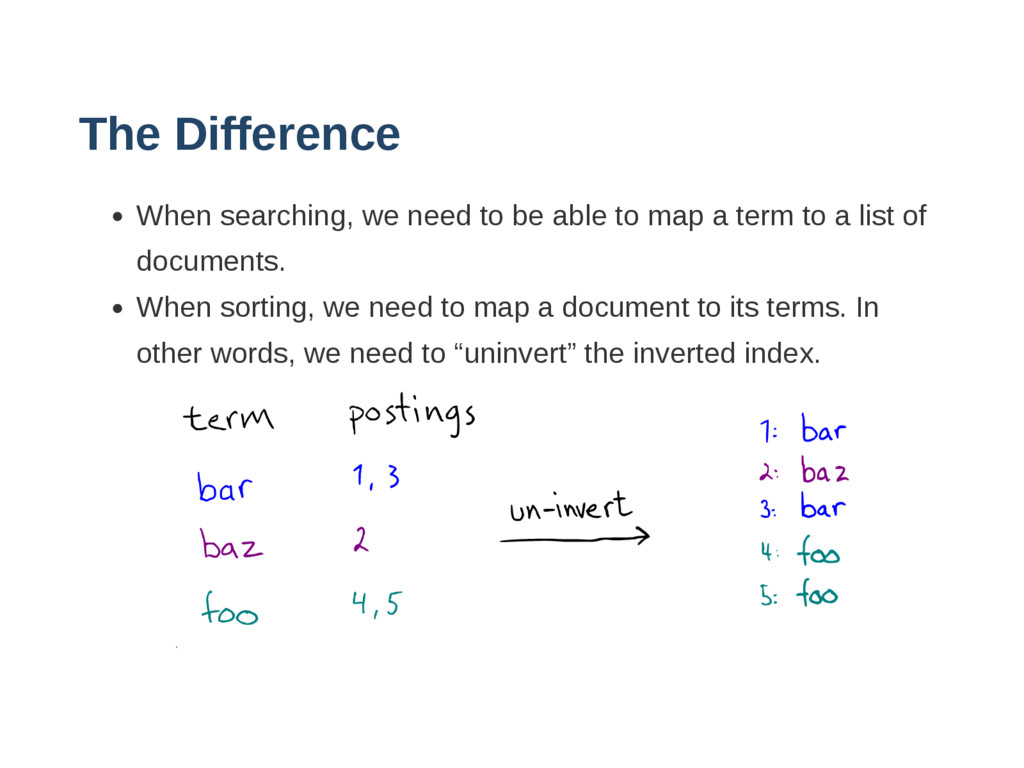
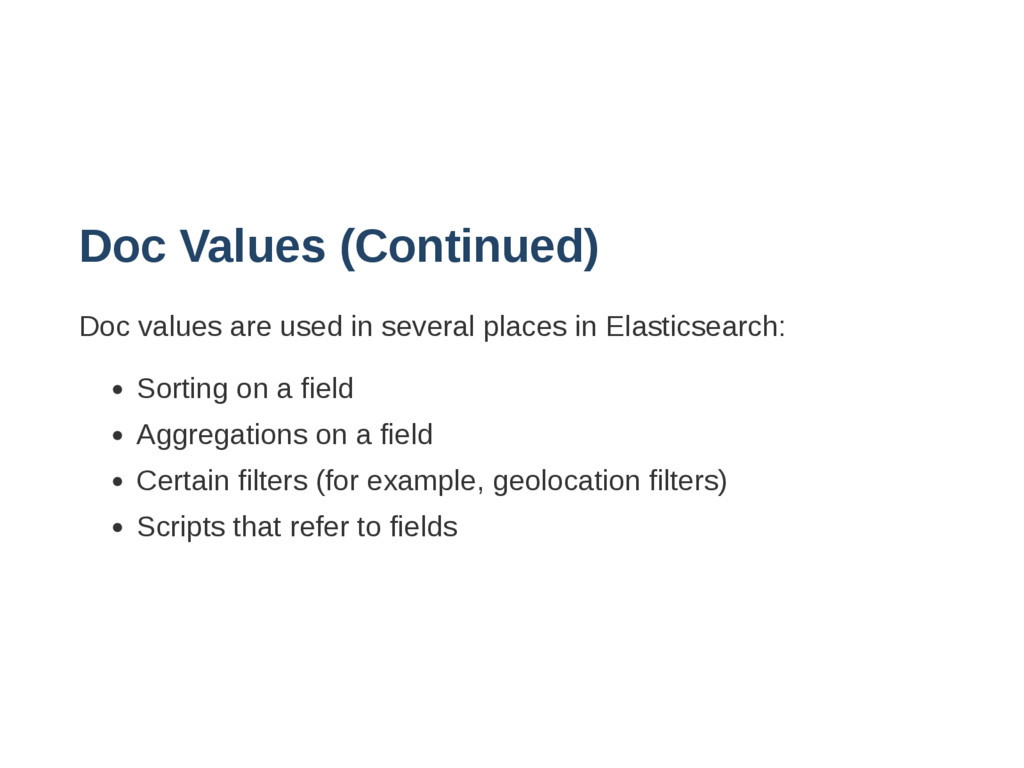
scripts requires a different data access pattern. Instead of looking up the term and finding documents, we need to be able to look up the document and find the terms that it has in a field.
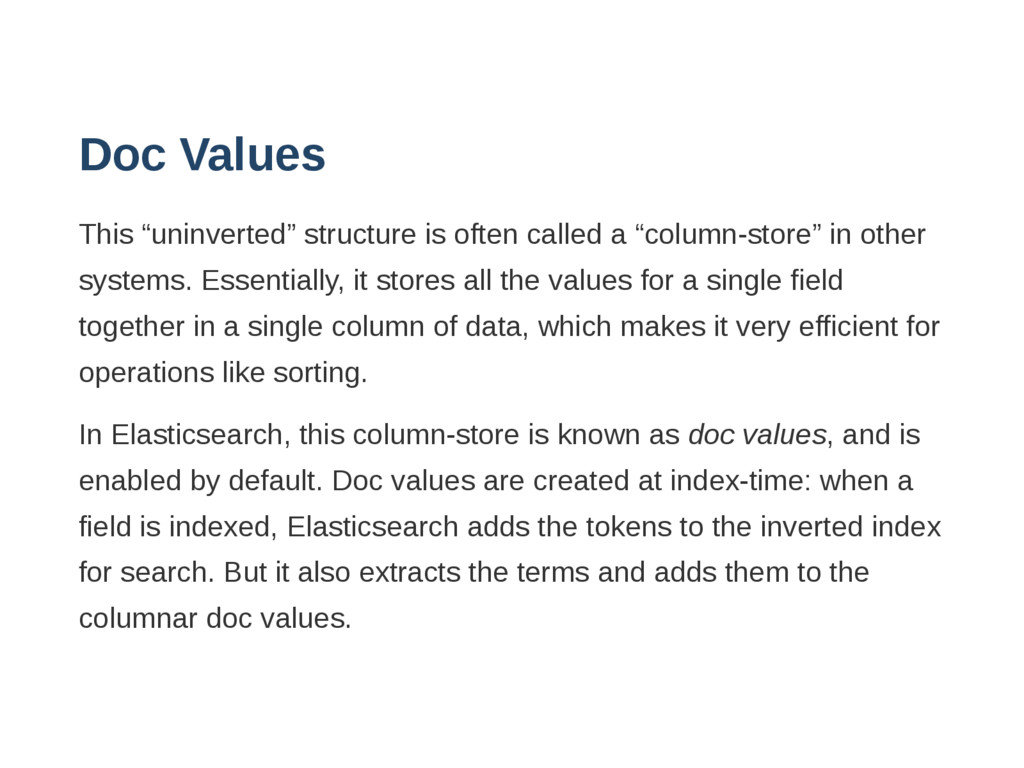
in other systems. Essentially, it stores all the values for a single field together in a single column of data, which makes it very efficient for operations like sorting. In Elasticsearch, this columnstore is known as doc values, and is enabled by default. Doc values are created at indextime: when a field is indexed, Elasticsearch adds the tokens to the inverted index for search. But it also extracts the terms and adds them to the columnar doc values.
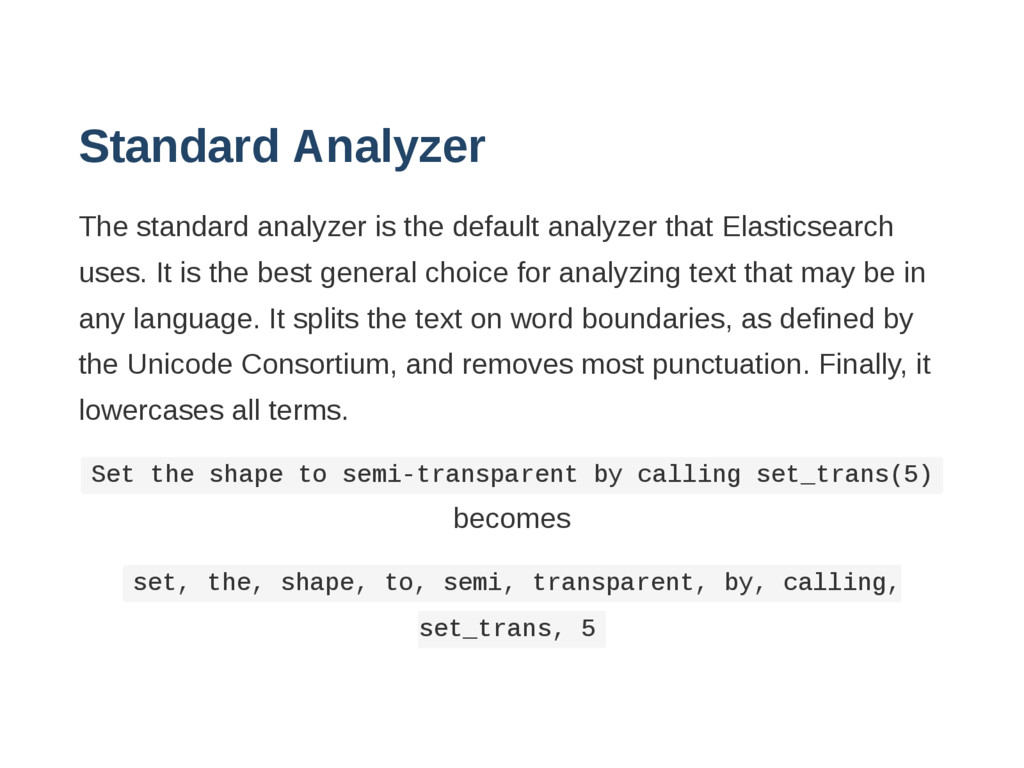
Elasticsearch uses. It is the best general choice for analyzing text that may be in any language. It splits the text on word boundaries, as defined by the Unicode Consortium, and removes most punctuation. Finally, it lowercases all terms. S e t t h e s h a p e t o s e m i t r a n s p a r e n t b y c a l l i n g s e t _ t r a n s ( 5 ) becomes s e t , t h e , s h a p e , t o , s e m i , t r a n s p a r e n t , b y , c a l l i n g , s e t _ t r a n s , 5
the DamerauLevenshtein distance to find all terms with a maximum of two changes, where a change is the insertion, deletion or substitution of a single character, or transposition of two adjacent characters. The default edit distance is 2, but an edit distance of 1 should be sufficient to catch 80% of all human misspellings.
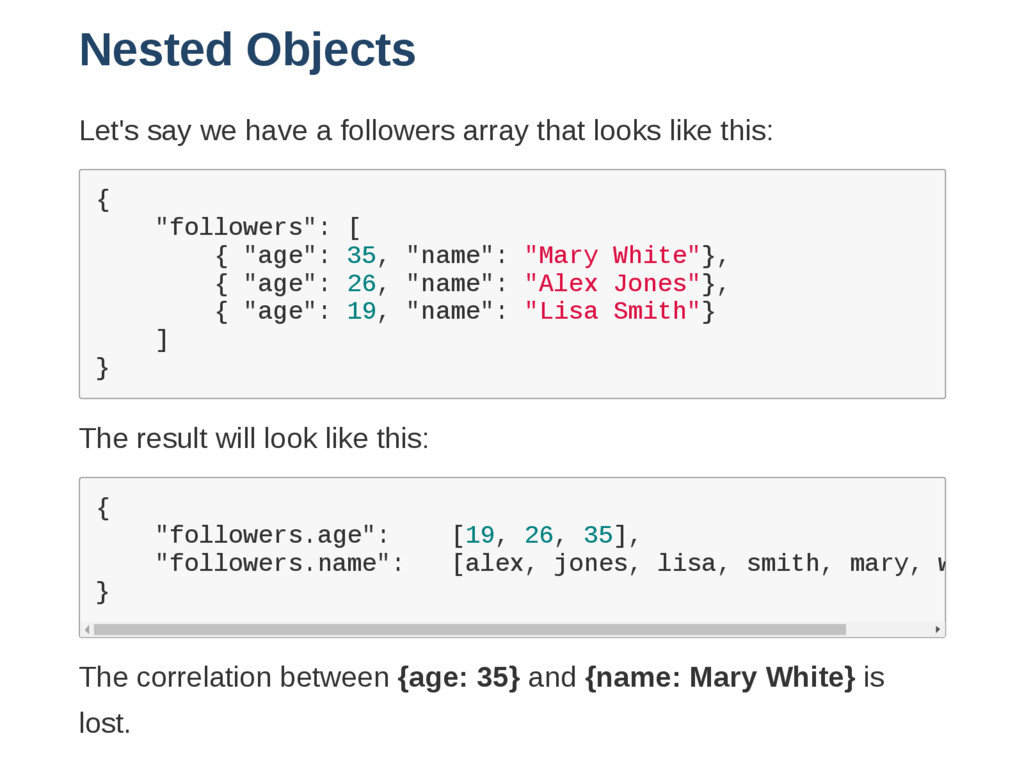
looks like this: { " f o l l o w e r s " : [ { " a g e " : 3 5 , " n a m e " : " M a r y W h i t e " } , { " a g e " : 2 6 , " n a m e " : " A l e x J o n e s " } , { " a g e " : 1 9 , " n a m e " : " L i s a S m i t h " } ] } The result will look like this: { " f o l l o w e r s . a g e " : [ 1 9 , 2 6 , 3 5 ] , " f o l l o w e r s . n a m e " : [ a l e x , j o n e s , l i s a , s m i t h , m a r y , w h i t e ] } The correlation between {age: 35} and {name: Mary White} is lost.
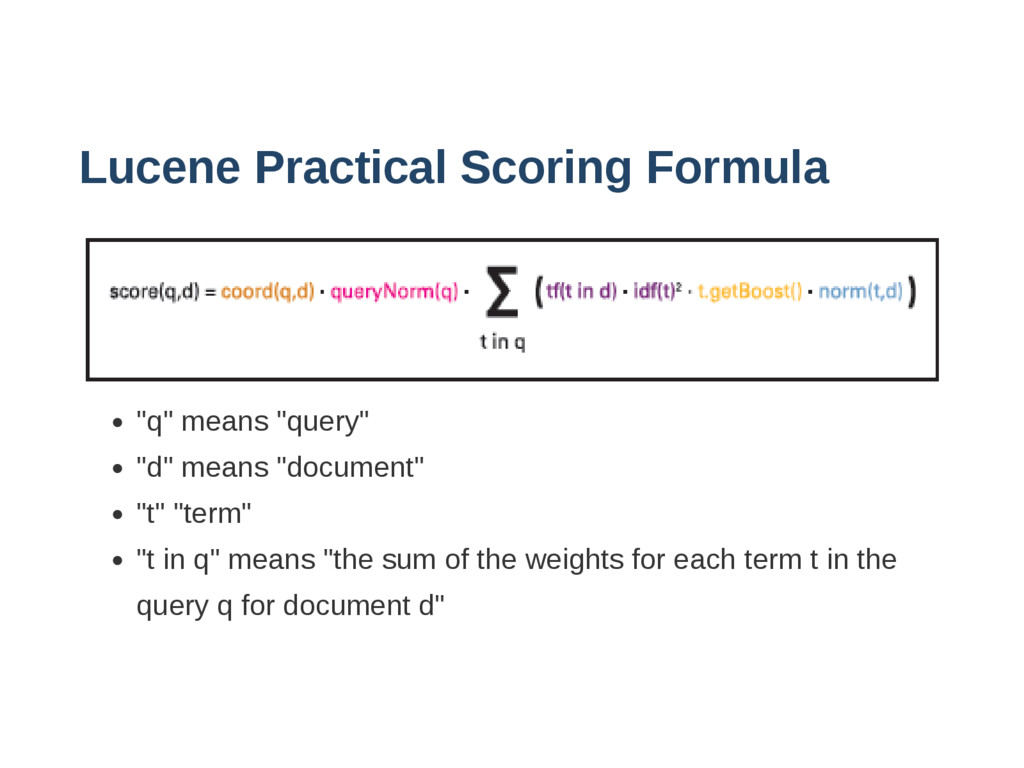
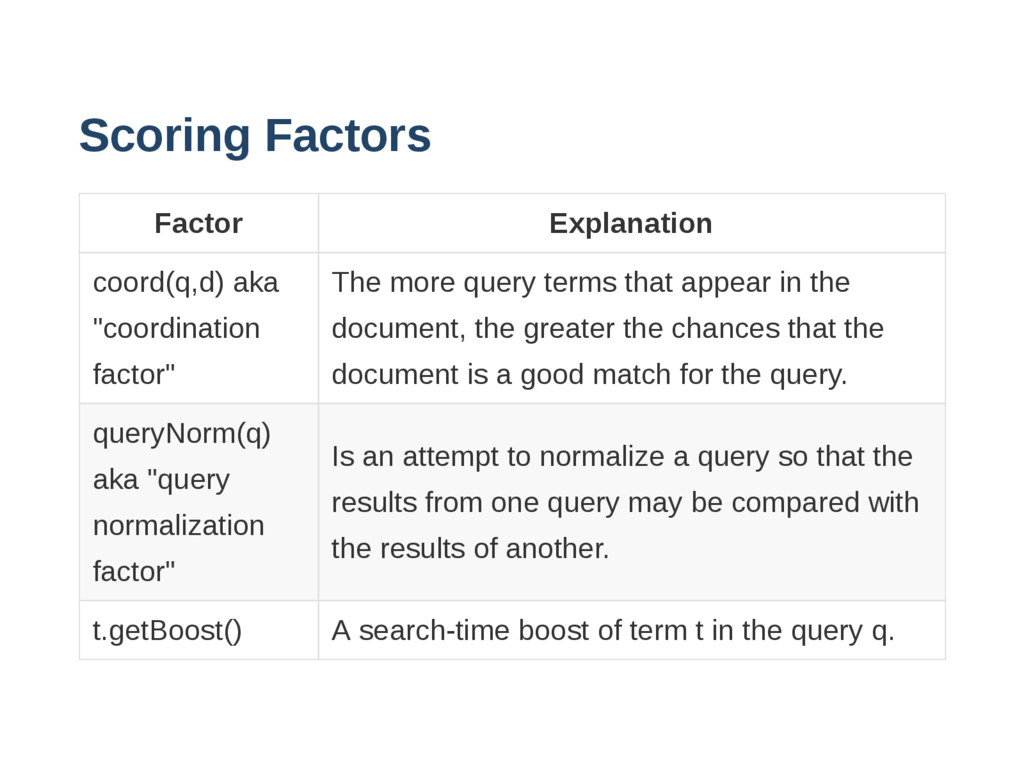
query terms that appear in the document, the greater the chances that the document is a good match for the query. queryNorm(q) aka "query normalization factor" Is an attempt to normalize a query so that the results from one query may be compared with the results of another. t.getBoost() A searchtime boost of term t in the query q.
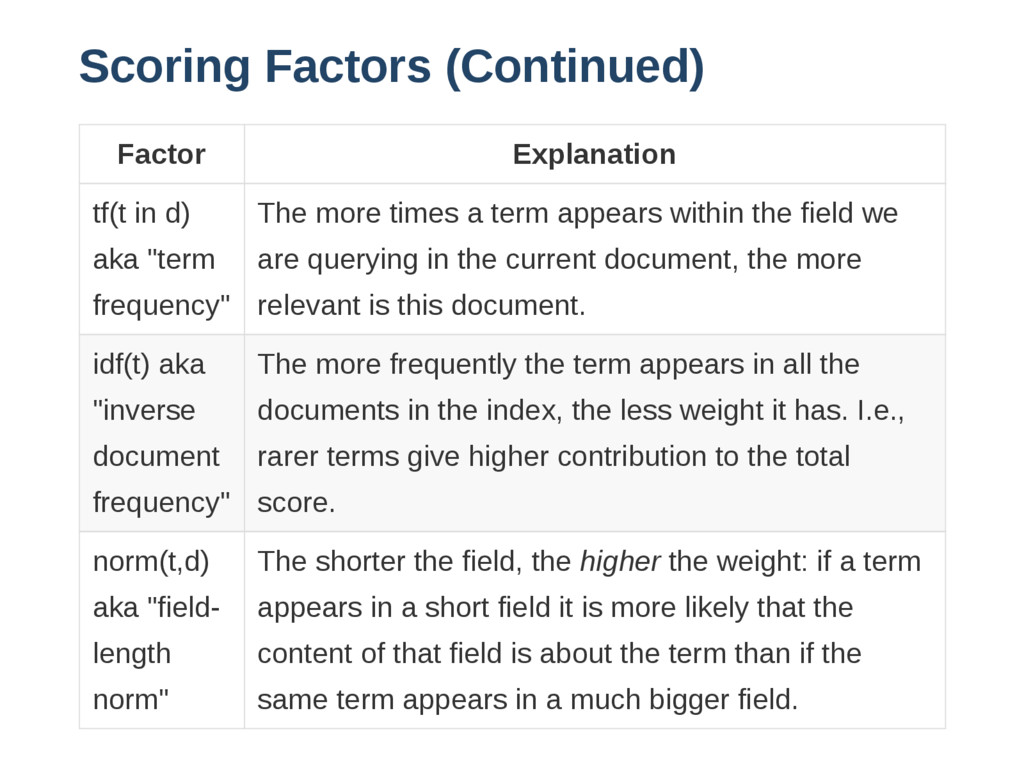
frequency" The more times a term appears within the field we are querying in the current document, the more relevant is this document. idf(t) aka "inverse document frequency" The more frequently the term appears in all the documents in the index, the less weight it has. I.e., rarer terms give higher contribution to the total score. norm(t,d) aka "field length norm" The shorter the field, the higher the weight: if a term appears in a short field it is more likely that the content of that field is about the term than if the same term appears in a much bigger field.


 hiccupps
 tsukuboshi
 itosoft
 yuutosi
 yama3133
 jacopen
 yahonda
 cscengineer
 inariku
 kazzpapa3
 hatahata021
 z63d
 codingconduct
 hannesfritz
 reverentgeek
 samlambert
 takai
 mkilby
 chrislema
 aleyda
 palkan
 kimpetersen
 morganepeng
 sarafernandez