Share
Embed
Transcript
35 slides
-
My Background • Solutions Architect at 10gen • Background in
software engineering • Written code for – Graph processing – Social network analysis – Sentiment analysis – Text similarity • @crcsmnky on Twitter -
Modern Data • Sick of saying “big data” • Three
main attributes – Volume: • The amount of data we work with daily is growing and is only getting larger – Variety • Data comes in all shapes, sizes, layouts, formats – often changing mid-stream – Velocity • Being collected at an astounding pace, need answers from it just as quickly -
Background • Scalability using commodity systems • Rich data modeling,
ad-hoc queries, full indexes • No multi-row transactions, no joins • Heterogeneous APIs • Dynamic schemas for iterative development • Elastic approaches to deployment -
Features • Data stored as JSON documents – Each document
has it’s own schema • Create, Read, Update, Delete (CRUD) – Ad-hoc queries: equality, range, regex – Atomic in-place updates • Secondary indexes – Single, compound, geospatial, unique, sparse, TTL • Replication: redundancy, failover, availability • Sharding: auto-partitioning, linear r/w scale -
Analysis Types • Aggregations • Projections • Transformations • Statistics
• Reporting • “Deeper” mining – Recommendations, similarity, graph metrics -
Analysis Approaches • Custom application code – You know your
data but might not scale • Aggregation framework – Declarative, pipeline-based approach, ad-hoc • Native Map-Reduce in MongoDB – JS functions that run over your data • Other systems – Hadoop, R, ETL, Reporting -
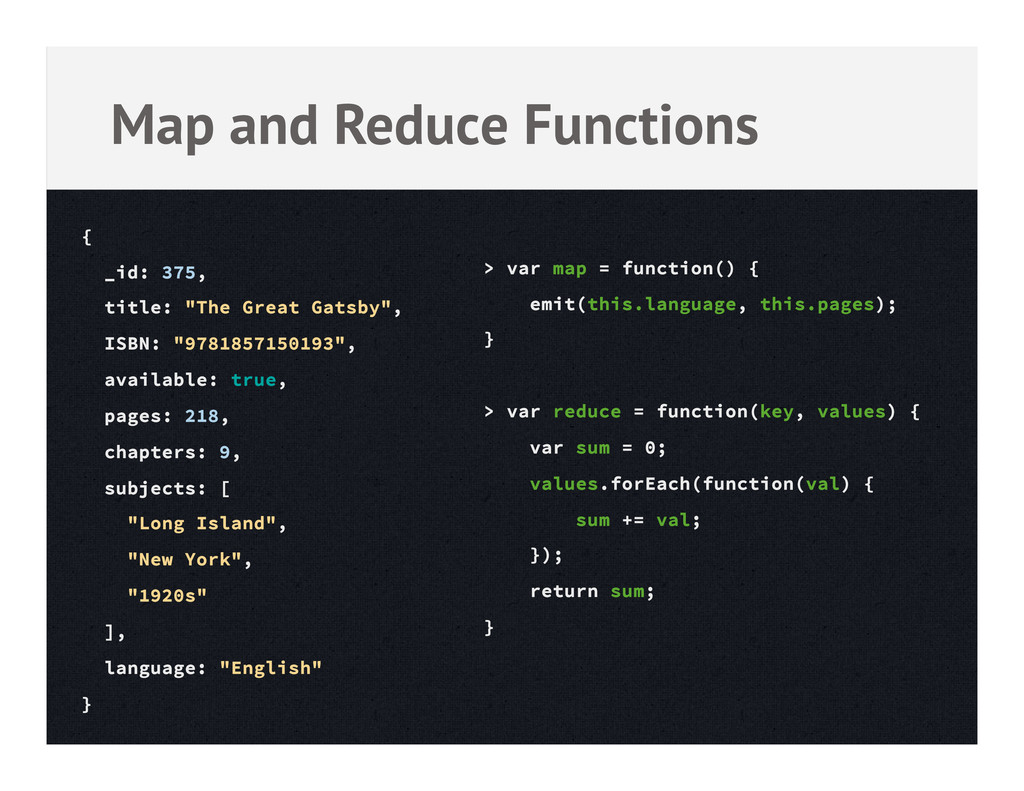
> var map = function() { emit(this.language, this.pages); } >
var reduce = function(key, values) { var sum = 0; values.forEach(function(val) { sum += val; }); return sum; } Map and Reduce Functions { _id: 375, title: "The Great Gatsby", ISBN: "9781857150193", available: true, pages: 218, chapters: 9, subjects: [ "Long Island", "New York", "1920s" ], language: "English" } -
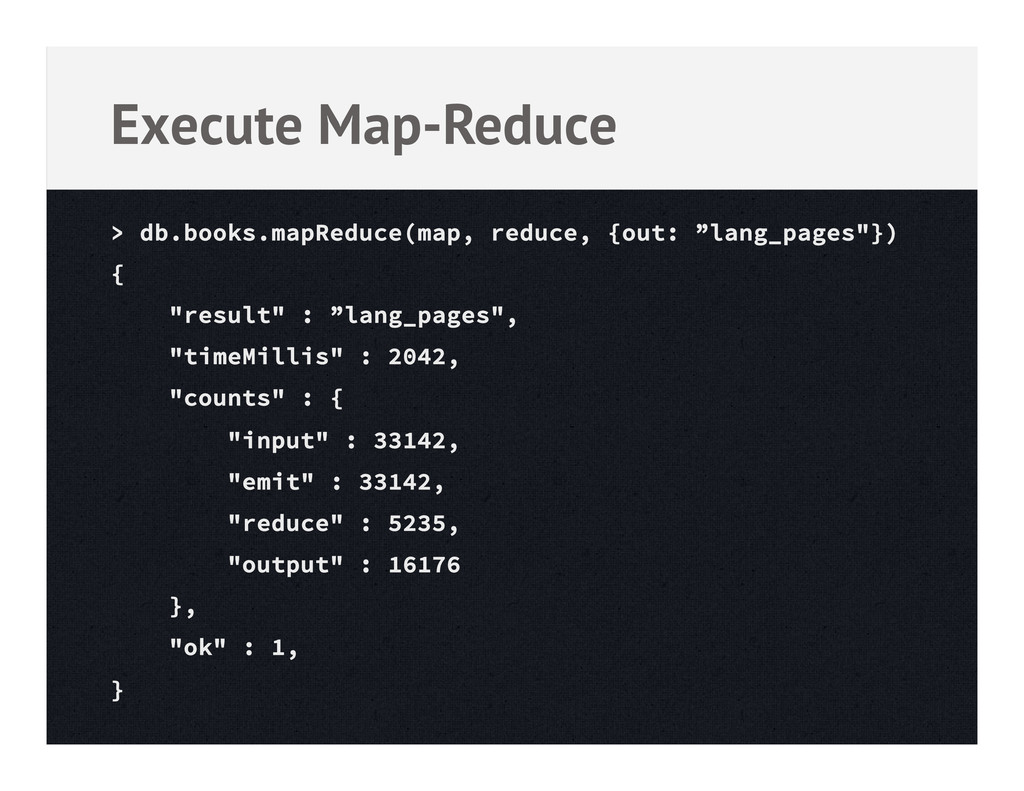
> db.books.mapReduce(map, reduce, {out: ”lang_pages"}) { "result" : ”lang_pages", "timeMillis"
: 2042, "counts" : { "input" : 33142, "emit" : 33142, "reduce" : 5235, "output" : 16176 }, "ok" : 1, } Execute Map-Reduce -
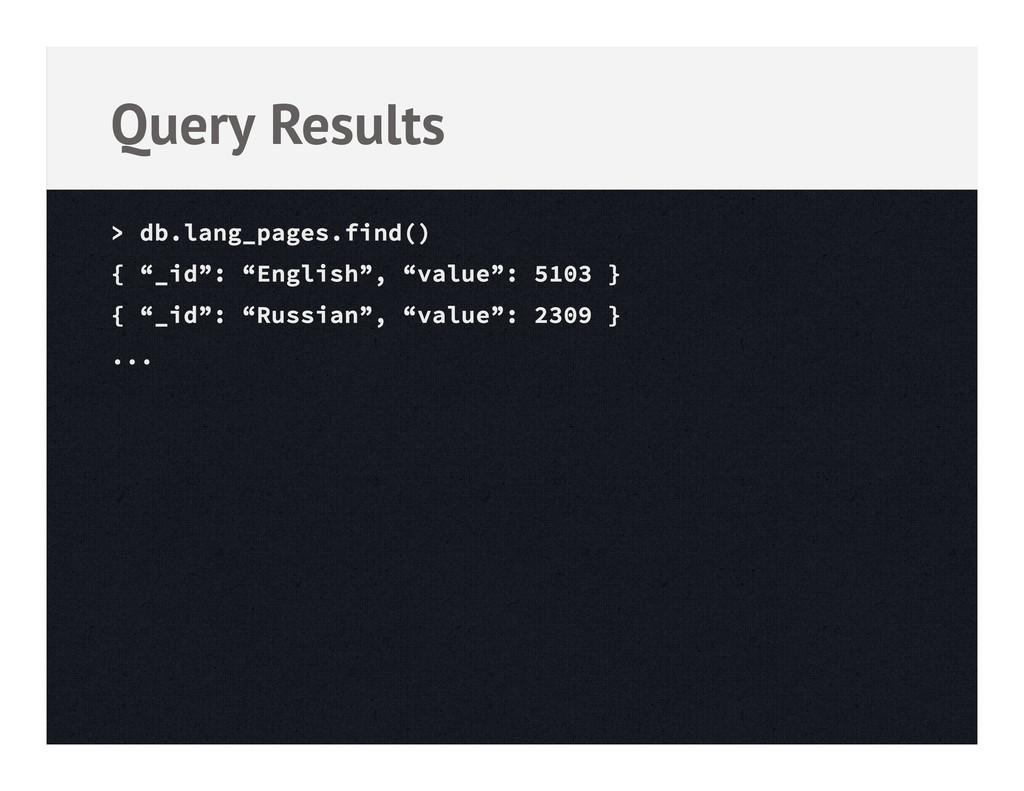
> db.lang_pages.find() { “_id”: “English”, “value”: 5103 } { “_id”:
“Russian”, “value”: 2309 } ... Query Results -
Aggregation Framework • Processes documents as a “stream” – Input
is a collection, output is a document • Pipeline is a series of operations – Filter, transform data – Output of one stage is input to the next – $ ps ax | grep mongod | head -n 1 -
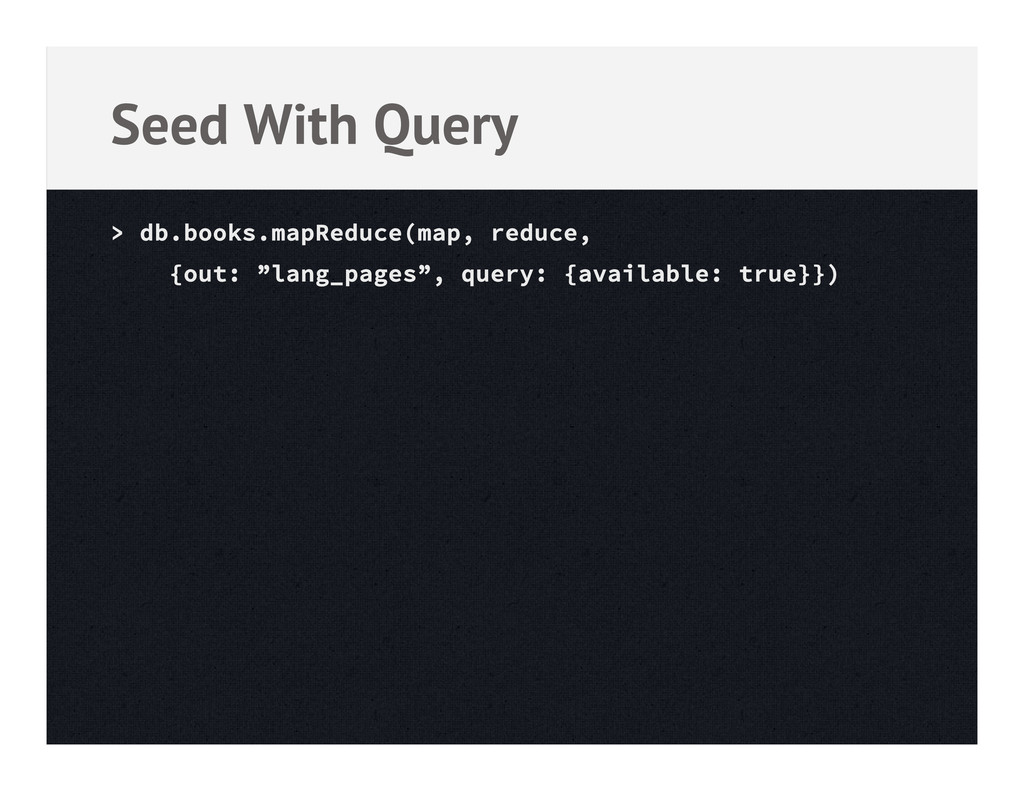
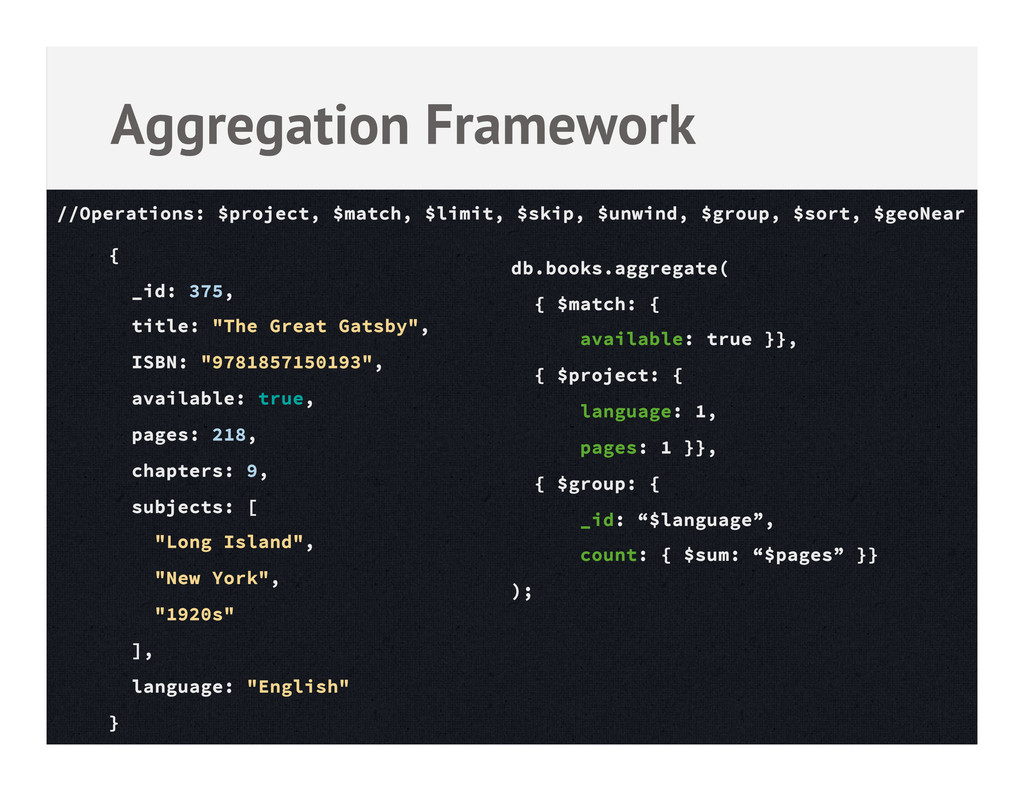
db.books.aggregate( { $match: { available: true }}, { $project: {
language: 1, pages: 1 }}, { $group: { _id: “$language”, count: { $sum: “$pages” }} ); Aggregation Framework { _id: 375, title: "The Great Gatsby", ISBN: "9781857150193", available: true, pages: 218, chapters: 9, subjects: [ "Long Island", "New York", "1920s" ], language: "English" } //Operations: $project, $match, $limit, $skip, $unwind, $group, $sort, $geoNear -
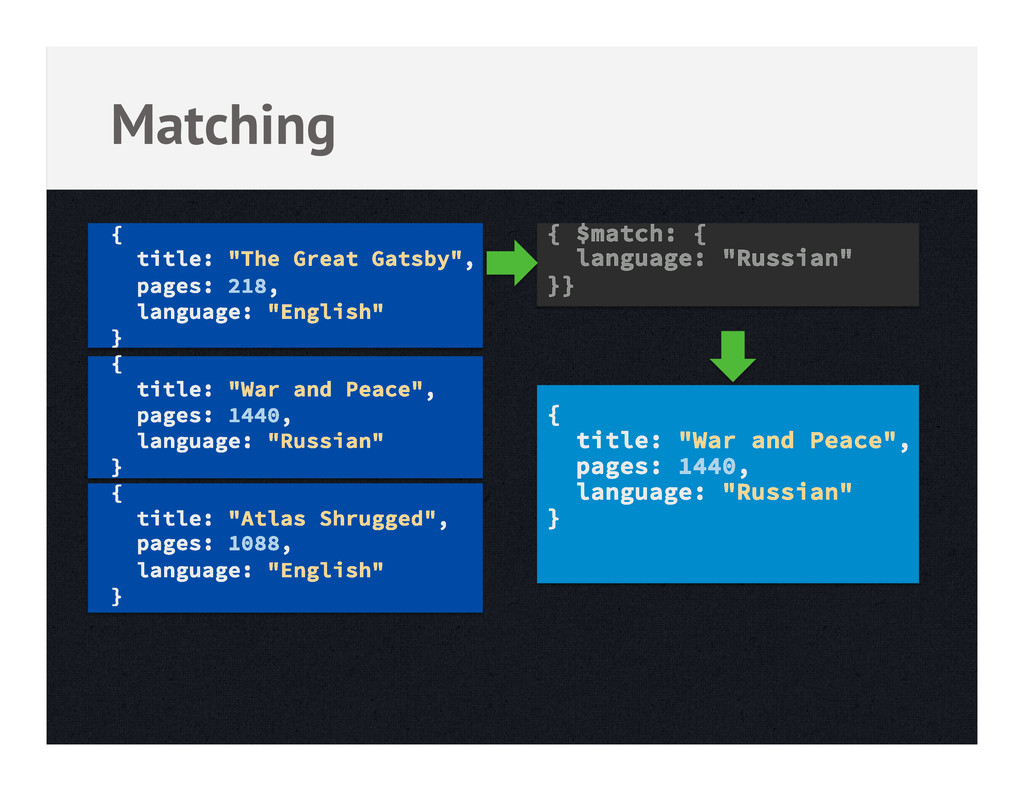
{ title: "The Great Gatsby", pages: 218, language: "English" }
{ title: "War and Peace", pages: 1440, language: "Russian" } { title: "Atlas Shrugged", pages: 1088, language: "English" } Matching { $match: { language: "Russian" }} { title: "War and Peace", pages: 1440, language: "Russian" } -
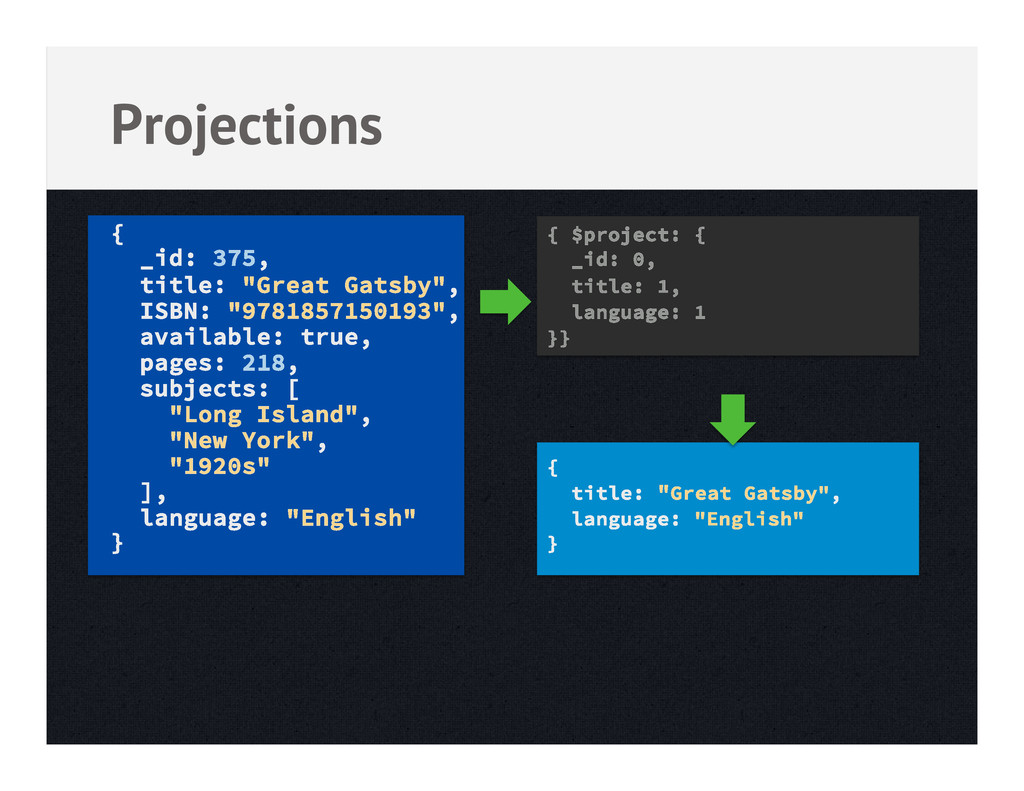
{ _id: 375, title: "Great Gatsby", ISBN: "9781857150193", available: true,
pages: 218, subjects: [ "Long Island", "New York", "1920s" ], language: "English" } Projections { $project: { _id: 0, title: 1, language: 1 }} { title: "Great Gatsby", language: "English" } -
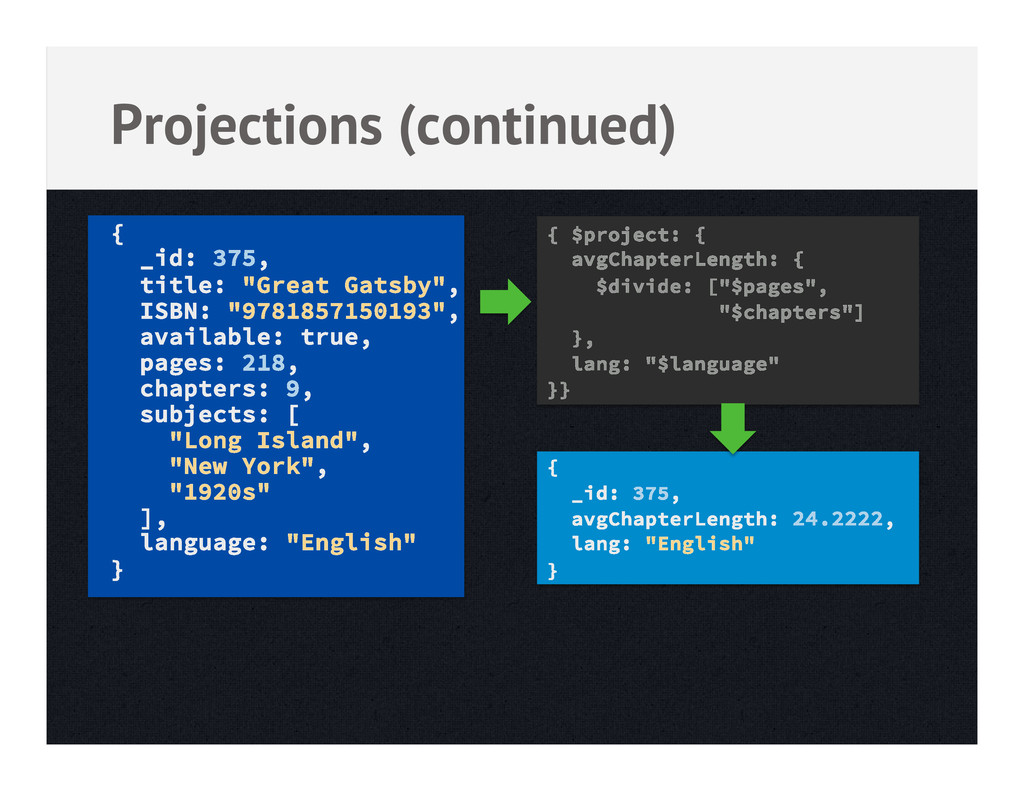
{ _id: 375, title: "Great Gatsby", ISBN: "9781857150193", available: true,
pages: 218, chapters: 9, subjects: [ "Long Island", "New York", "1920s" ], language: "English" } Projections (continued) { $project: { avgChapterLength: { $divide: ["$pages", "$chapters"] }, lang: "$language" }} { _id: 375, avgChapterLength: 24.2222, lang: "English" } -
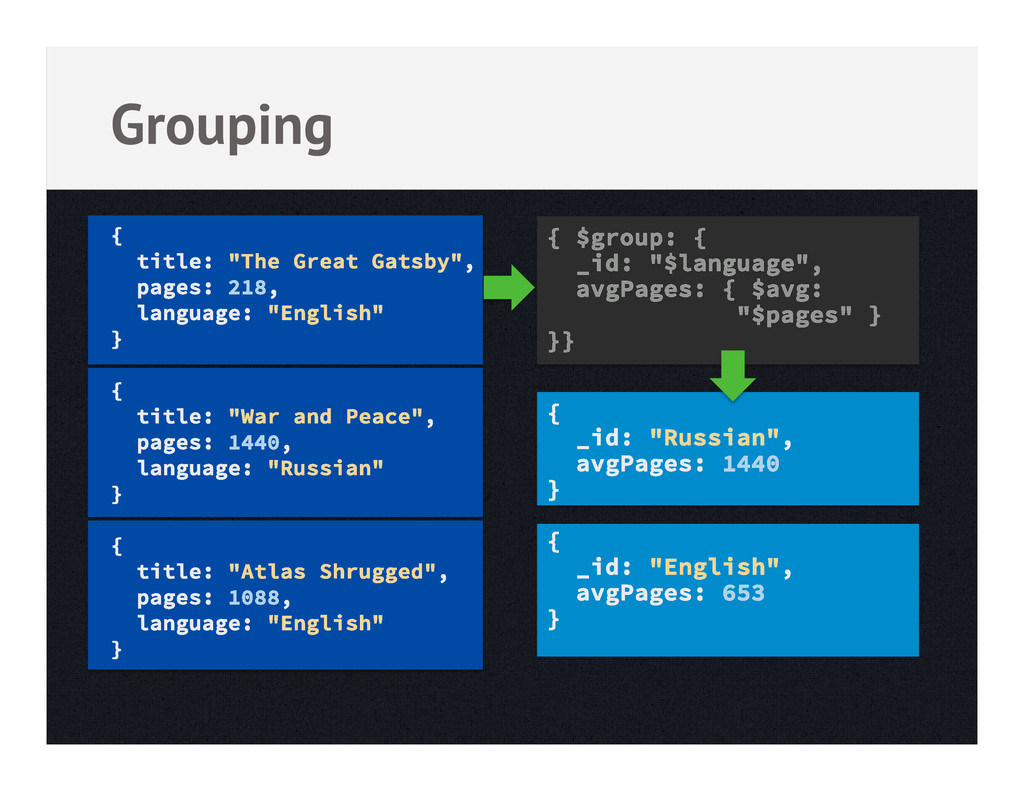
{ title: "The Great Gatsby", pages: 218, language: "English" }
{ title: "War and Peace", pages: 1440, language: "Russian" } { title: "Atlas Shrugged", pages: 1088, language: "English" } Grouping { $group: { _id: "$language", avgPages: { $avg: "$pages" } }} { _id: "Russian", avgPages: 1440 } { _id: "English", avgPages: 653 } -
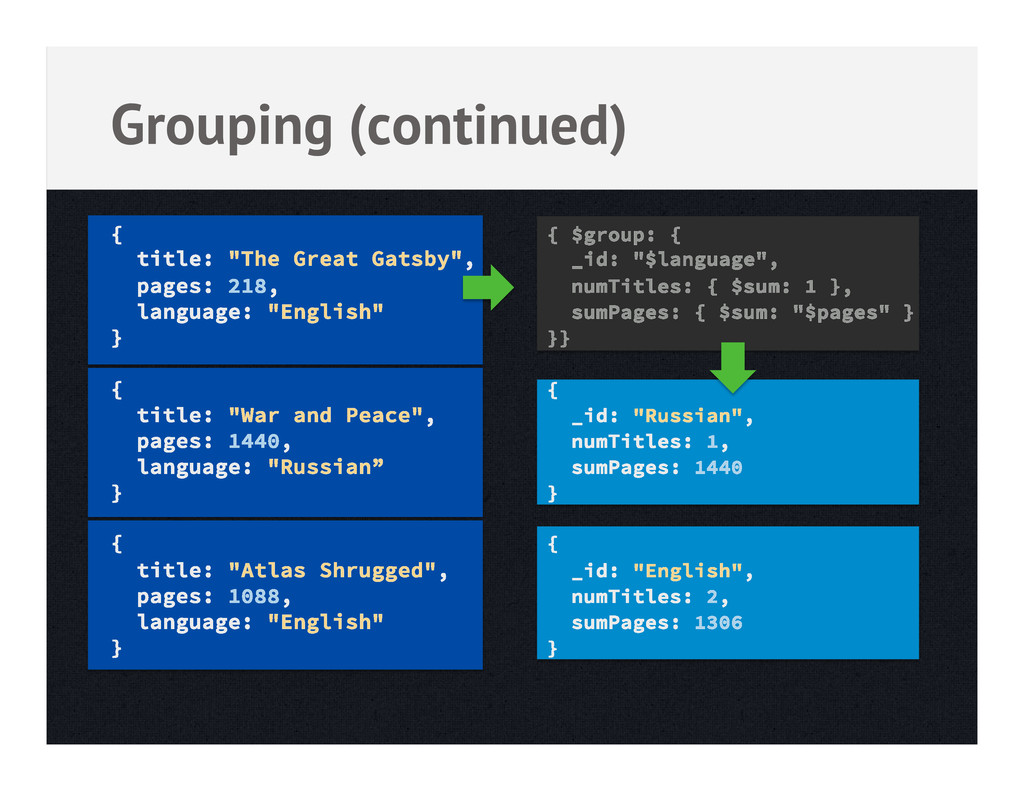
{ title: "The Great Gatsby", pages: 218, language: "English" }
{ title: "War and Peace", pages: 1440, language: "Russian” } { title: "Atlas Shrugged", pages: 1088, language: "English" } Grouping (continued) { $group: { _id: "$language", numTitles: { $sum: 1 }, sumPages: { $sum: "$pages" } }} { _id: "Russian", numTitles: 1, sumPages: 1440 } { _id: "English", numTitles: 2, sumPages: 1306 } -
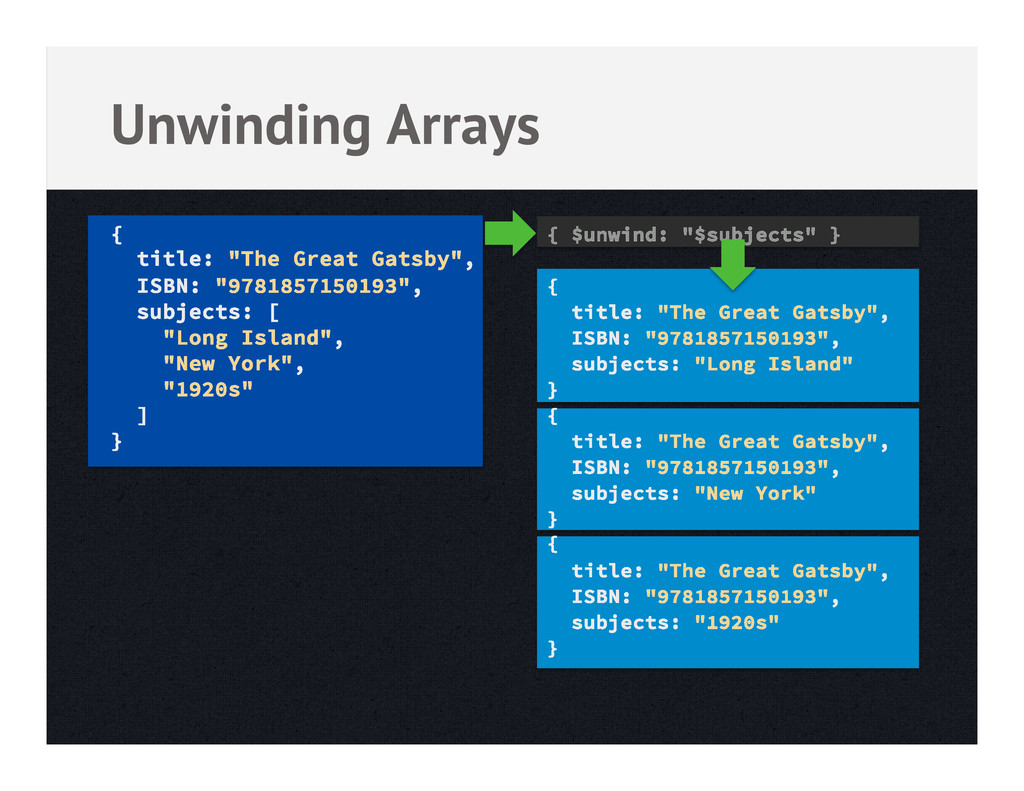
{ title: "The Great Gatsby", ISBN: "9781857150193", subjects: [ "Long
Island", "New York", "1920s" ] } Unwinding Arrays { $unwind: "$subjects" } { title: "The Great Gatsby", ISBN: "9781857150193", subjects: "Long Island" } { title: "The Great Gatsby", ISBN: "9781857150193", subjects: "New York" } { title: "The Great Gatsby", ISBN: "9781857150193", subjects: "1920s" } -
Yelp Dataset Challenge • http://www.yelp.com/dataset_challenge/ • Data contains around –
11,000 business – 8,000 checkins – 43,000 users – 229,000 reviews • Tweaked data model a bit from original form • Script to process downloaded data – https://gist.github.com/crcsmnky/5675588 -
Some Ideas… • When are reviews posted? • Most popular
categories by city? • Funniest users? Most helpful? -
Pros and Cons • For “simple” tasks, the aggregation framework
is best – Map-Reduce is slower and more work • Aggregation Framework output limited to 16MB document – Map-Reduce can output to a collection • Vote on SERVER-3253 to bring $out to aggregation -
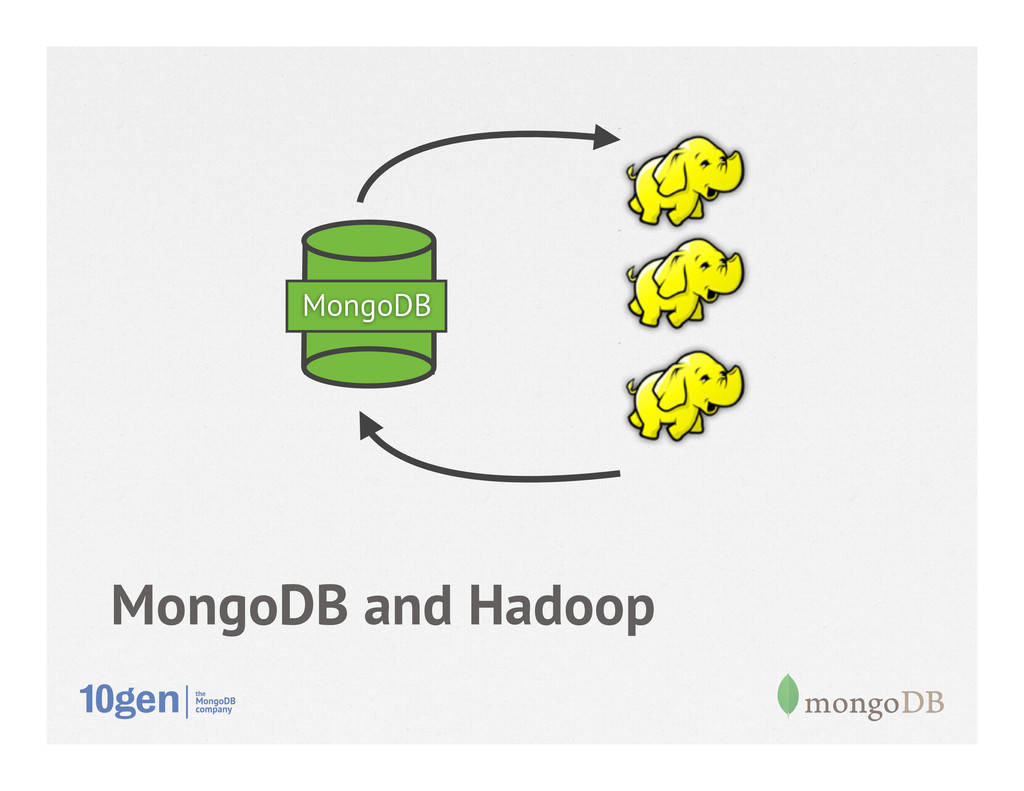
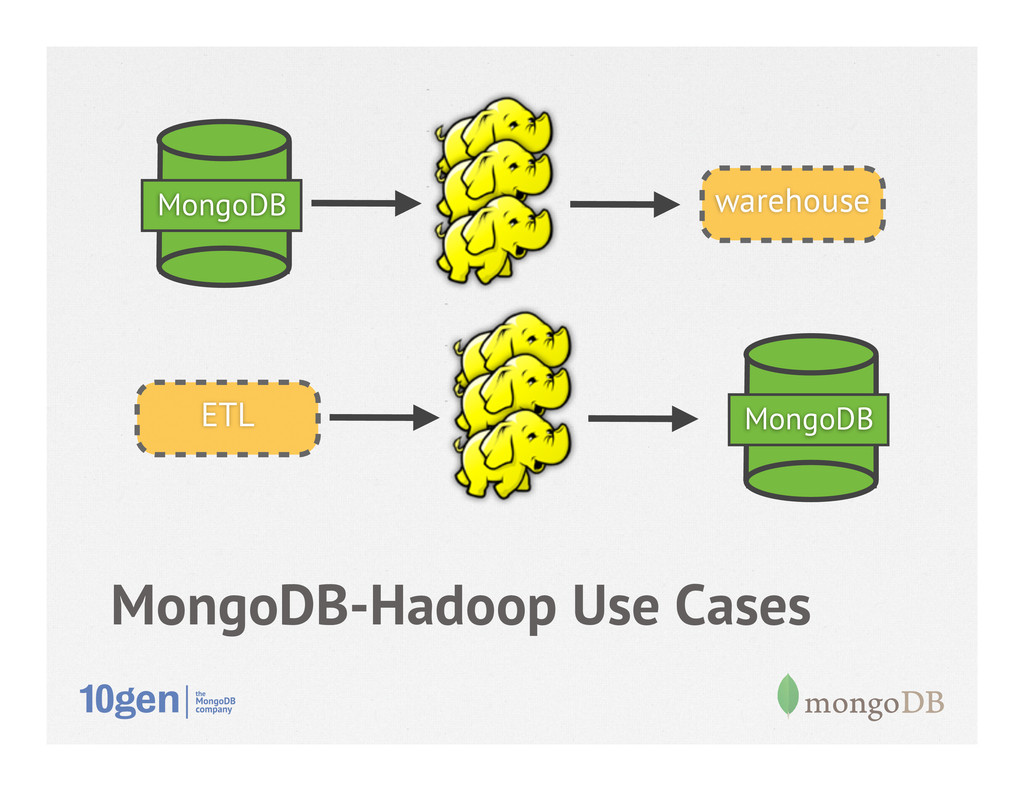
MongoDB-Hadoop Adapter • MongoDB as input/output storage for Hadoop jobs
• Supports MapReduce, Pig, Streaming • Batch, offline processing • 1.0 released, 1.1 active development • Leverage Hadoop ecosystem against operational data in MongoDB -
Other • Business intelligence tools – Jaspersoft – Alteryx •
ETL tools – Pentaho – Talend -
Thanks! • Sandeep Parikh, @crcsmnky • www.mongodb.org – Downloads, docs,
drivers, use cases – @mongodb • www.10gen.com – Presentations, subscriptions, monitoring – @10gen