Share
Embed
Online Workflow Performance Management with Stampede
Presented at CNSM11 Paris, France
Dan Gunter
October 25, 2011
Transcript
35 slides
-
Online Workflow Management and Performance Analysis with Stampede Dan Gunter1,
Taghrid Samak1, Monte Goode1, Ewa Deelman2, Gaurang Mehta2, Fabio Silva2, Karan Vahi2 Christopher Brooks3 Priscilla Moraes4, Martin Swany4 1 1 Lawrence Berkeley National Laboratory 2 University of Southern California, Information Sciences Institute 3 University of San Francisco 4 University of Delaware -
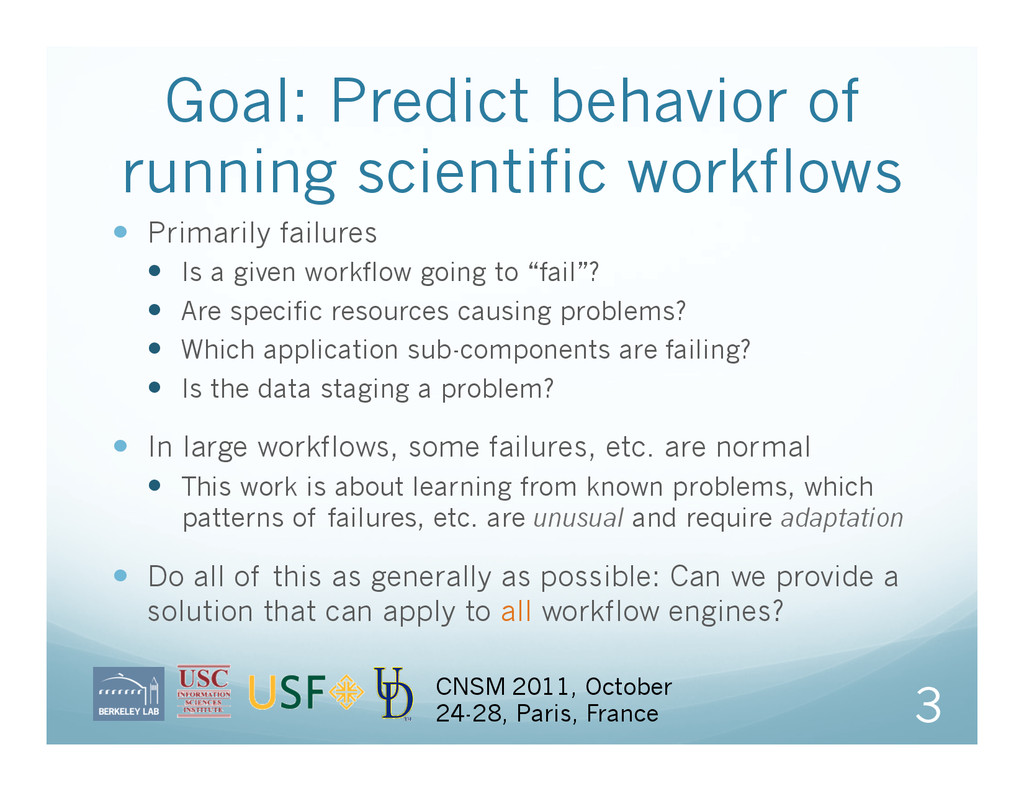
Goal: Predict behavior of running scientific workflows Primarily failures
Is a given workflow going to “fail”? Are specific resources causing problems? Which application sub-components are failing? Is the data staging a problem? In large workflows, some failures, etc. are normal This work is about learning from known problems, which patterns of failures, etc. are unusual and require adaptation Do all of this as generally as possible: Can we provide a solution that can apply to all workflow engines? 3 CNSM 2011, October 24-28, Paris, France -
Approach Model the monitoring data from running workflows
Collect all the data in real-time Run analysis, also in real-time, on the collected data map low-level failures to application-level characteristics Feed back analysis to user, workflow engine 4 CNSM 2011, October 24-28, Paris, France -
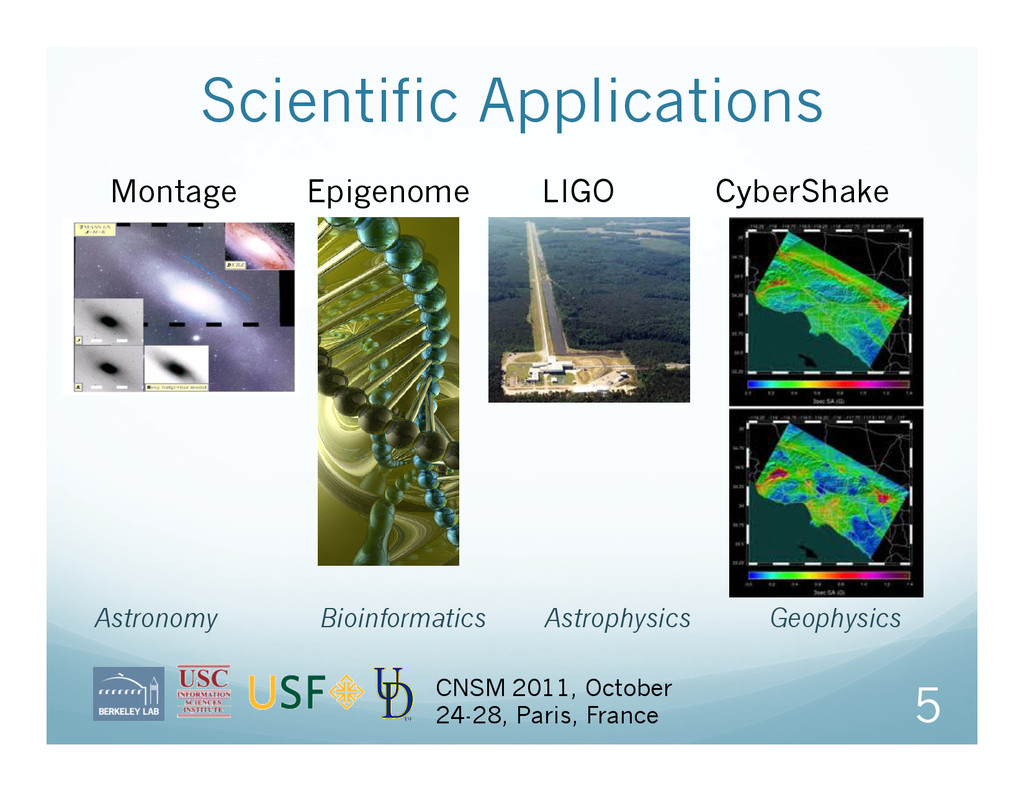
Scientific Applications 5 Montage CyberShake Epigenome LIGO CNSM 2011, October
24-28, Paris, France Astronomy Bioinformatics Astrophysics Geophysics -
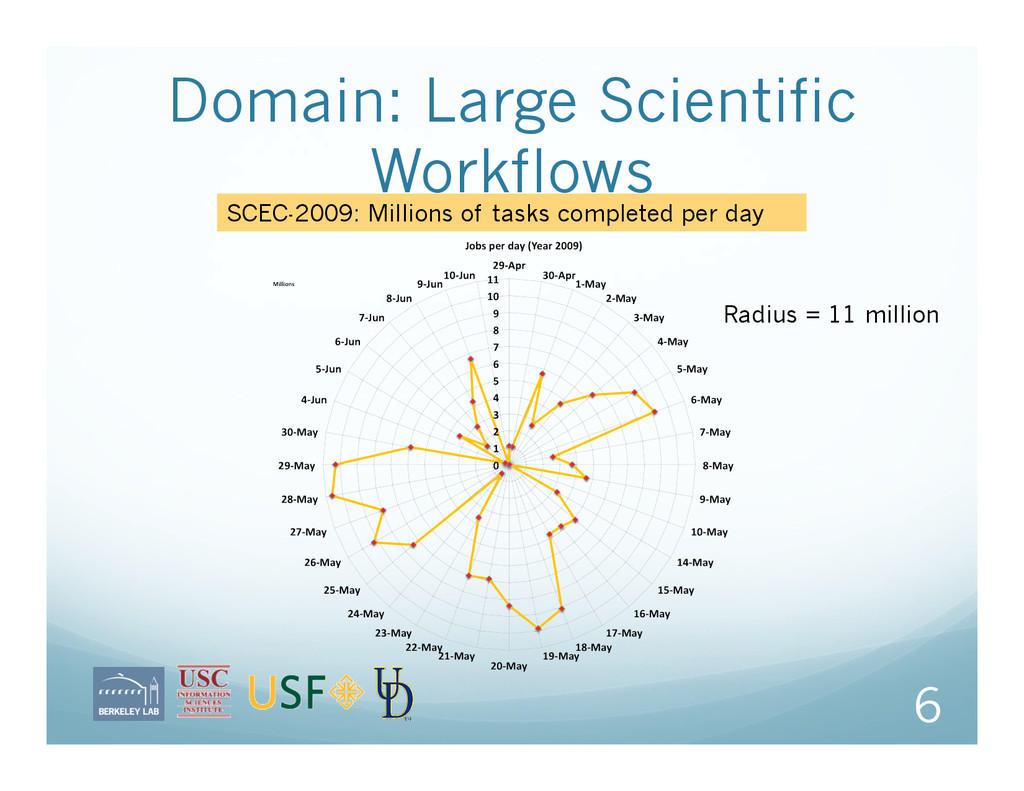
Domain: Large Scientific Workflows 6 SCEC-2009: Millions of tasks completed
per day Radius = 11 million -
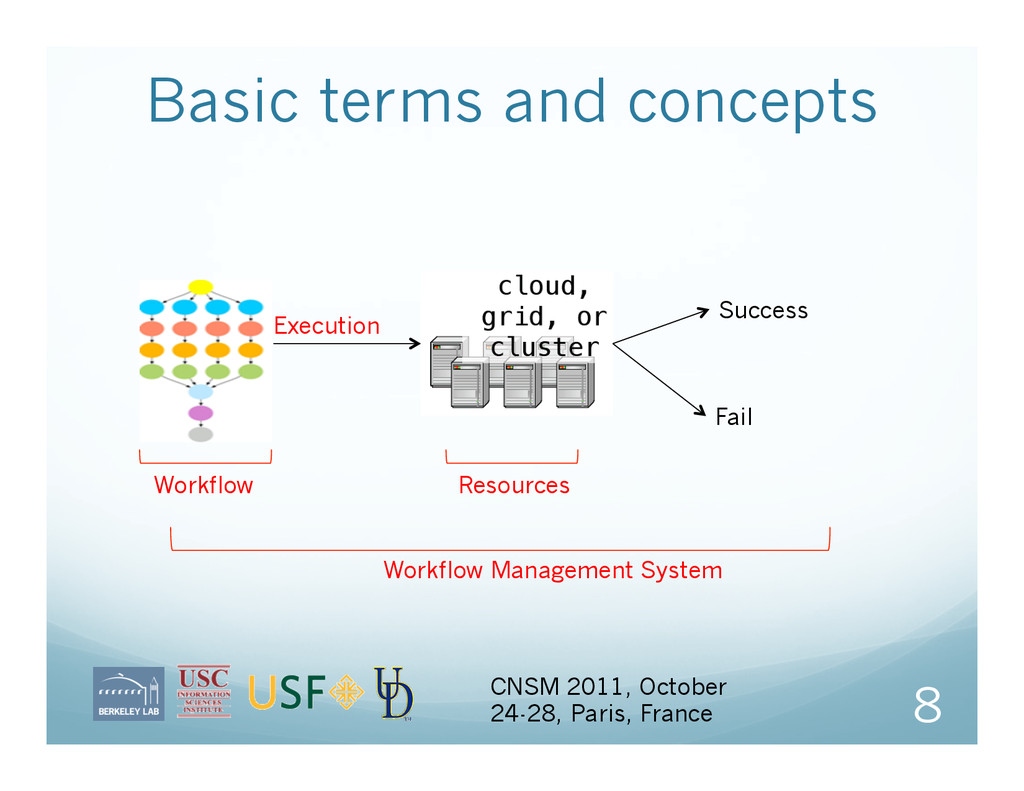
Basic terms and concepts 8 Success Fail Execution Workflow Resources
Workflow Management System CNSM 2011, October 24-28, Paris, France -
Base technologies Workflow management systems Pegasus www.pegasus.isi.edu
Monitoring and data analysis NetLogger www.netlogger.lbl.gov 9 CNSM 2011, October 24-28, Paris, France + -
Data Model Goals Be widely applicable: there are many
workflow engines out there that could benefit. Provide everything we need for Pegasus workflows 10/27/11 CNSM 2011, October 24-28, Paris, France 11 -
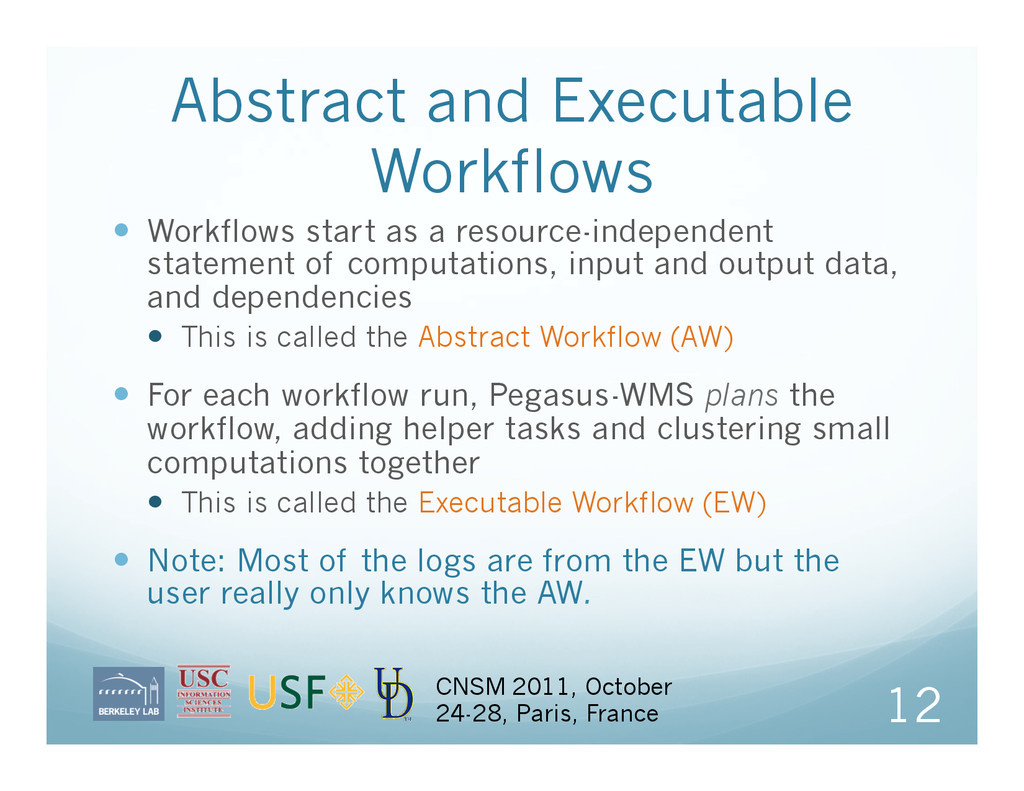
Abstract and Executable Workflows 12 CNSM 2011, October 24-28, Paris,
France Workflows start as a resource-independent statement of computations, input and output data, and dependencies This is called the Abstract Workflow (AW) For each workflow run, Pegasus-WMS plans the workflow, adding helper tasks and clustering small computations together This is called the Executable Workflow (EW) Note: Most of the logs are from the EW but the user really only knows the AW. -
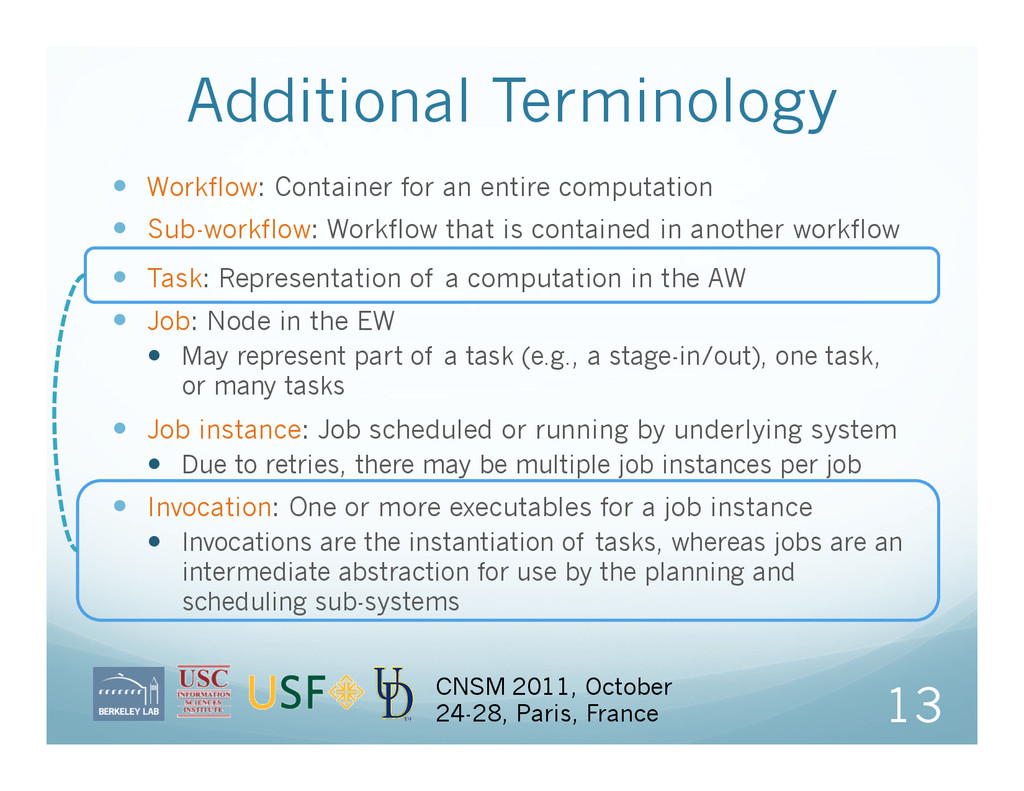
Additional Terminology Workflow: Container for an entire computation
Sub-workflow: Workflow that is contained in another workflow Task: Representation of a computation in the AW Job: Node in the EW May represent part of a task (e.g., a stage-in/out), one task, or many tasks Job instance: Job scheduled or running by underlying system Due to retries, there may be multiple job instances per job Invocation: One or more executables for a job instance Invocations are the instantiation of tasks, whereas jobs are an intermediate abstraction for use by the planning and scheduling sub-systems 13 CNSM 2011, October 24-28, Paris, France -
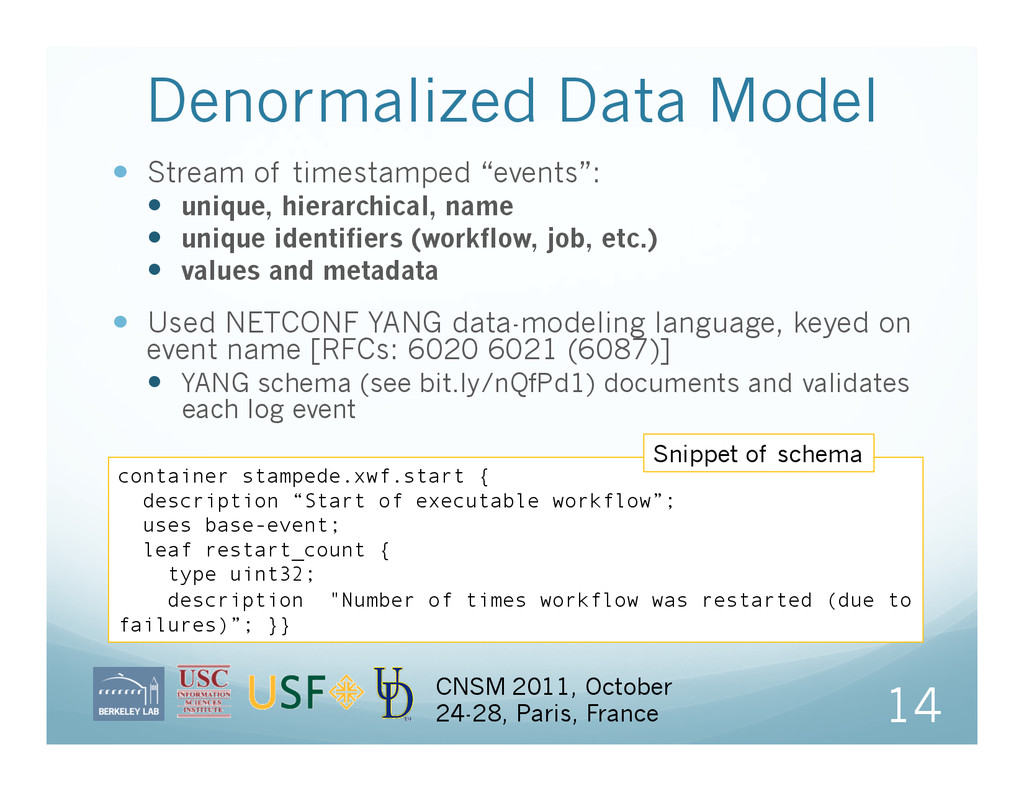
Denormalized Data Model Stream of timestamped “events”: unique,
hierarchical, name unique identifiers (workflow, job, etc.) values and metadata Used NETCONF YANG data-modeling language, keyed on event name [RFCs: 6020 6021 (6087)] YANG schema (see bit.ly/nQfPd1) documents and validates each log event 14 CNSM 2011, October 24-28, Paris, France container stampede.xwf.start { description “Start of executable workflow”; uses base-event; leaf restart_count { type uint32; description "Number of times workflow was restarted (due to failures)”; }} Snippet of schema -
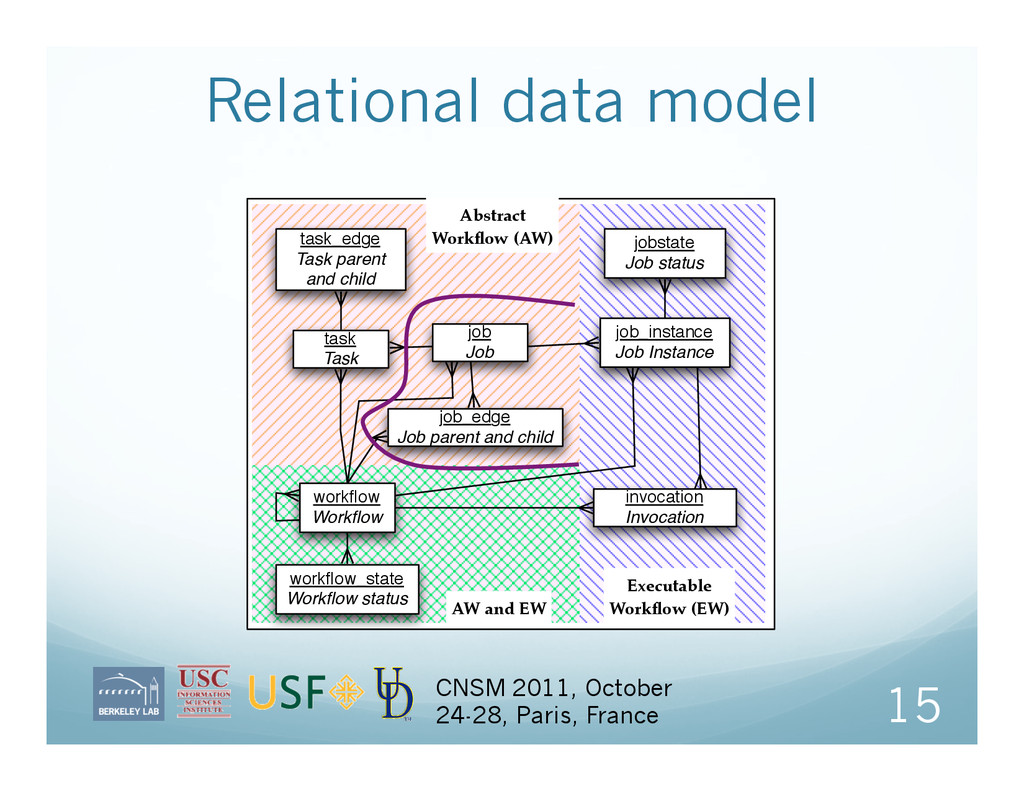
Relational data model 15 Abstract Workflow (AW) Executable Workflow (EW)
AW and EW task_edge Task parent and child task Task job Job jobstate Job status job_instance Job Instance workflow Workflow job_edge Job parent and child workflow_state Workflow status invocation Invocation CNSM 2011, October 24-28, Paris, France -
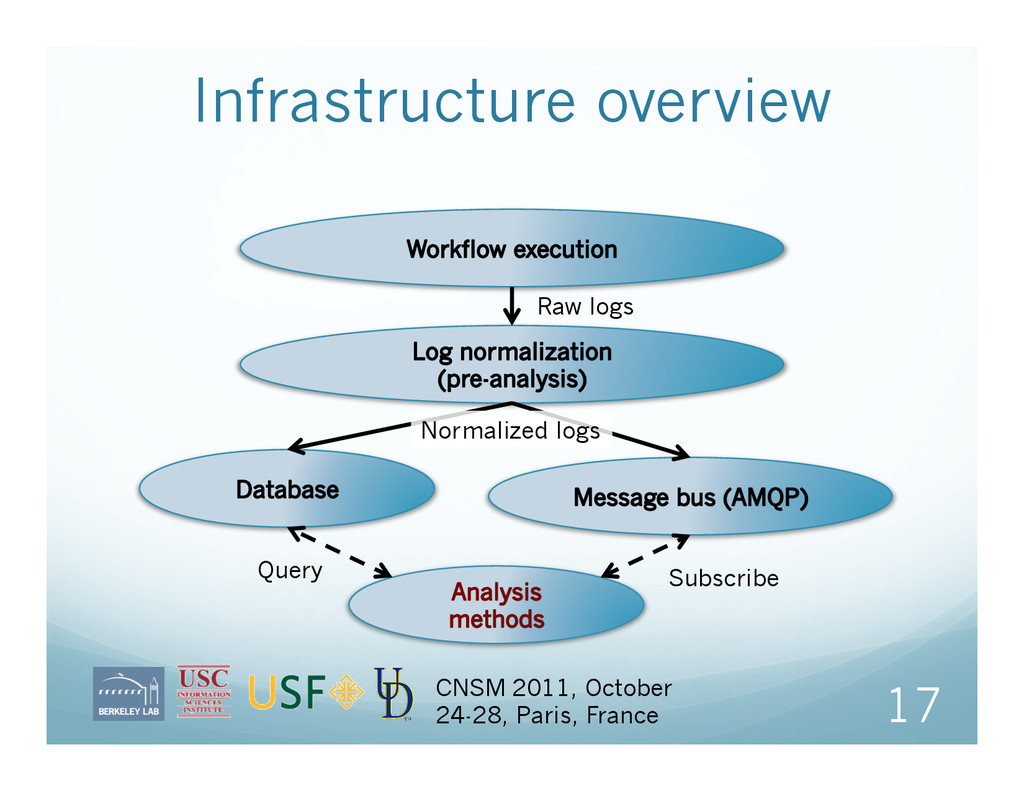
Infrastructure overview 17 Raw logs Normalized logs Query Subscribe CNSM
2011, October 24-28, Paris, France -
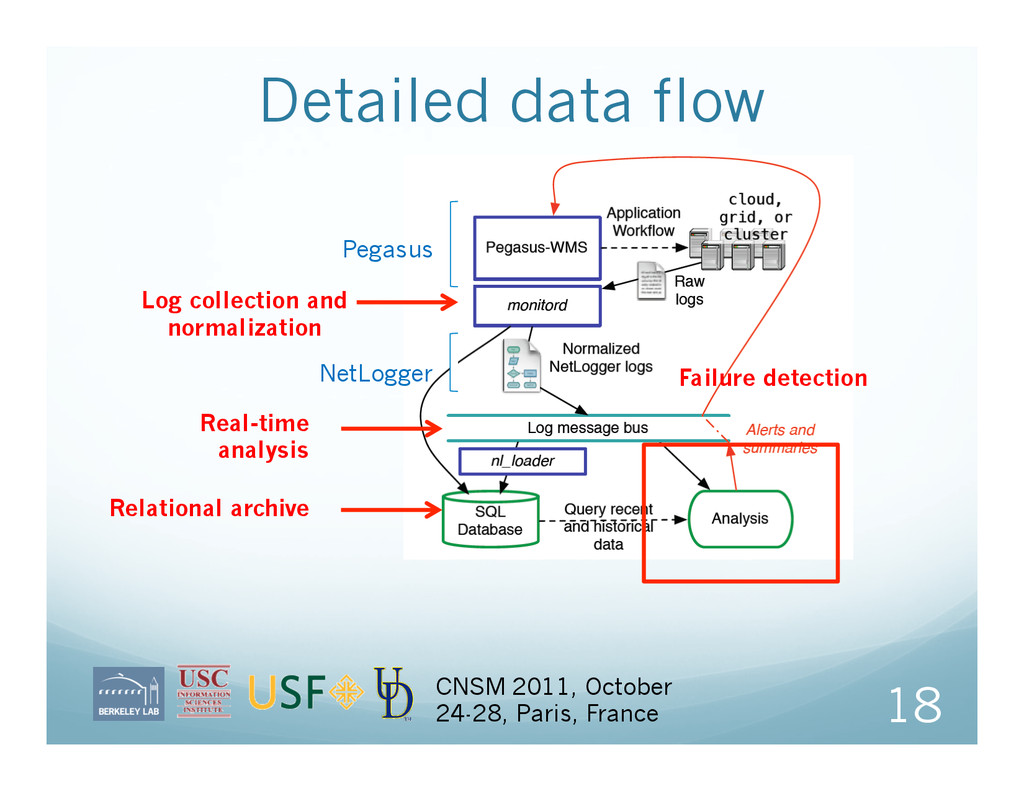
Detailed data flow CNSM 2011, October 24-28, Paris, France 18
Pegasus NetLogger Log collection and normalization Real-time analysis Relational archive Failure detection -
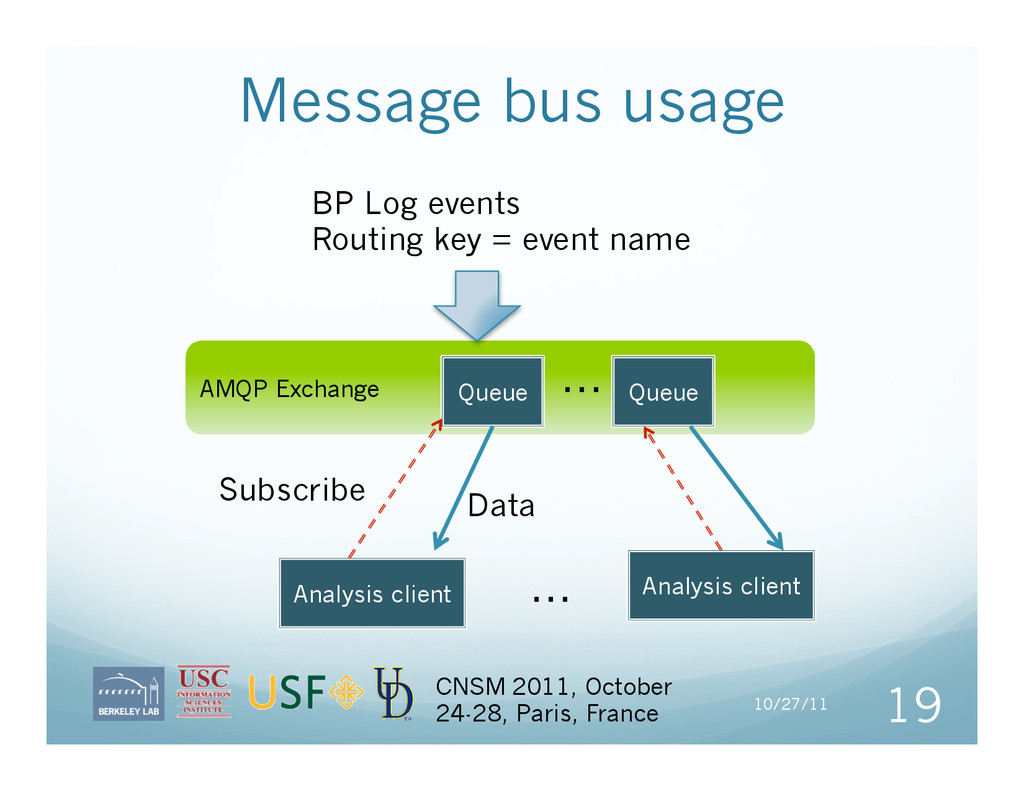
Message bus usage 10/27/11 CNSM 2011, October 24-28, Paris, France
19 AMQP Exchange Queue Queue … Analysis client Analysis client … BP Log events Routing key = event name Subscribe Data -
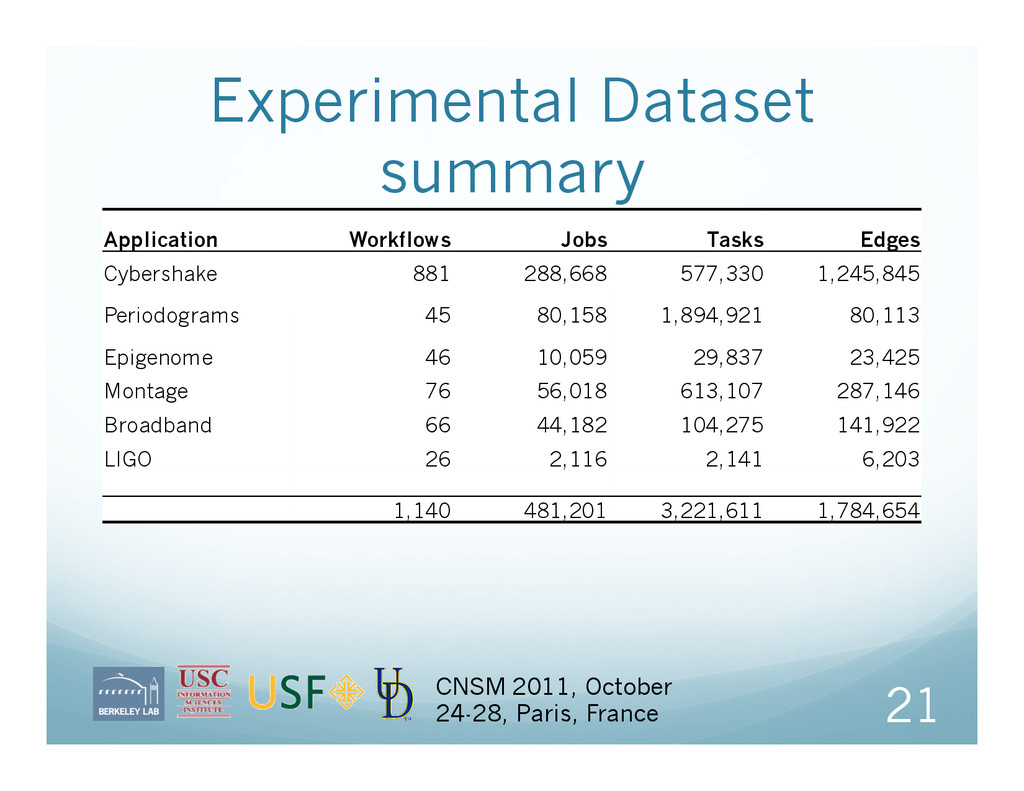
Experimental Dataset summary Application Workflows Jobs Tasks
Edges Cybershake 881 288,668 577,330 1,245,845 Periodograms 45 80,158 1,894,921 80,113 Epigenome 46 10,059 29,837 23,425 Montage 76 56,018 613,107 287,146 Broadband 66 44,182 104,275 141,922 LIGO 26 2,116 2,141 6,203 1,140 481,201 3,221,611 1,784,654 21 CNSM 2011, October 24-28, Paris, France -
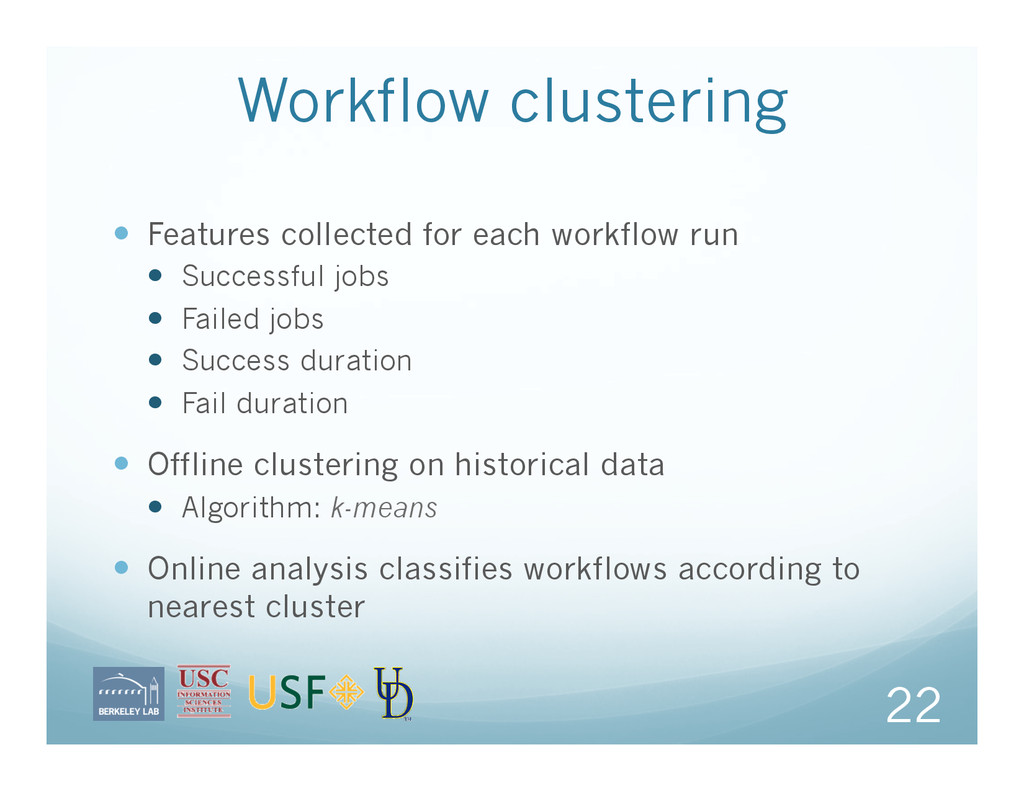
Workflow clustering Features collected for each workflow run
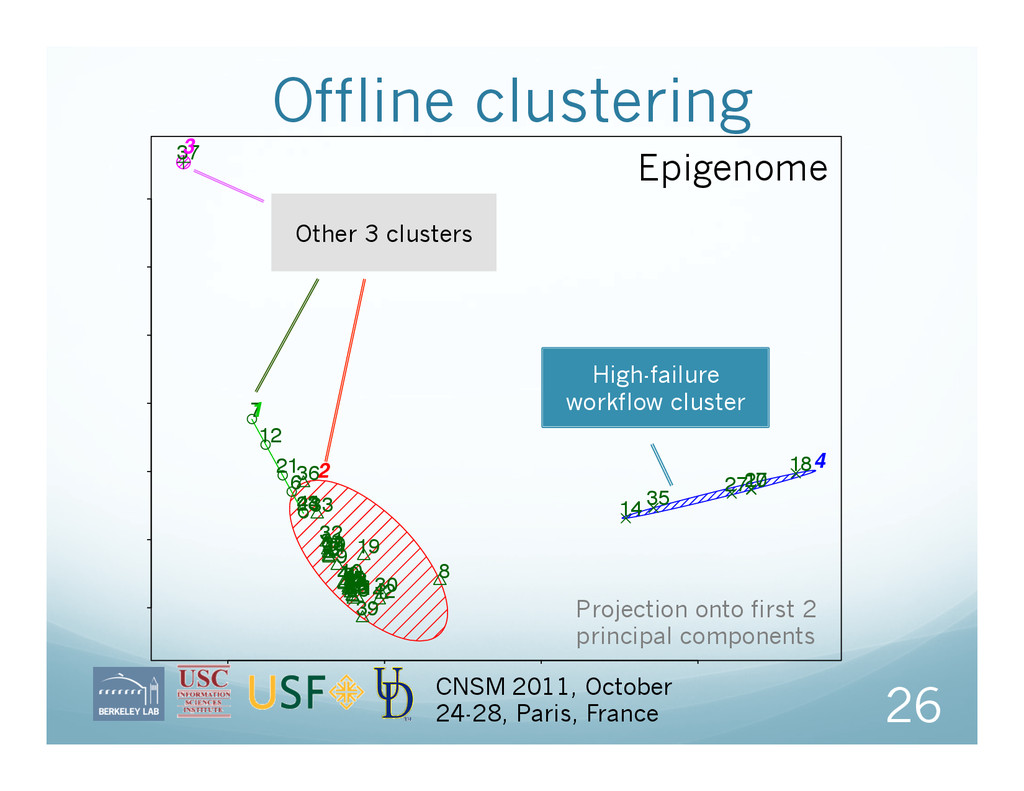
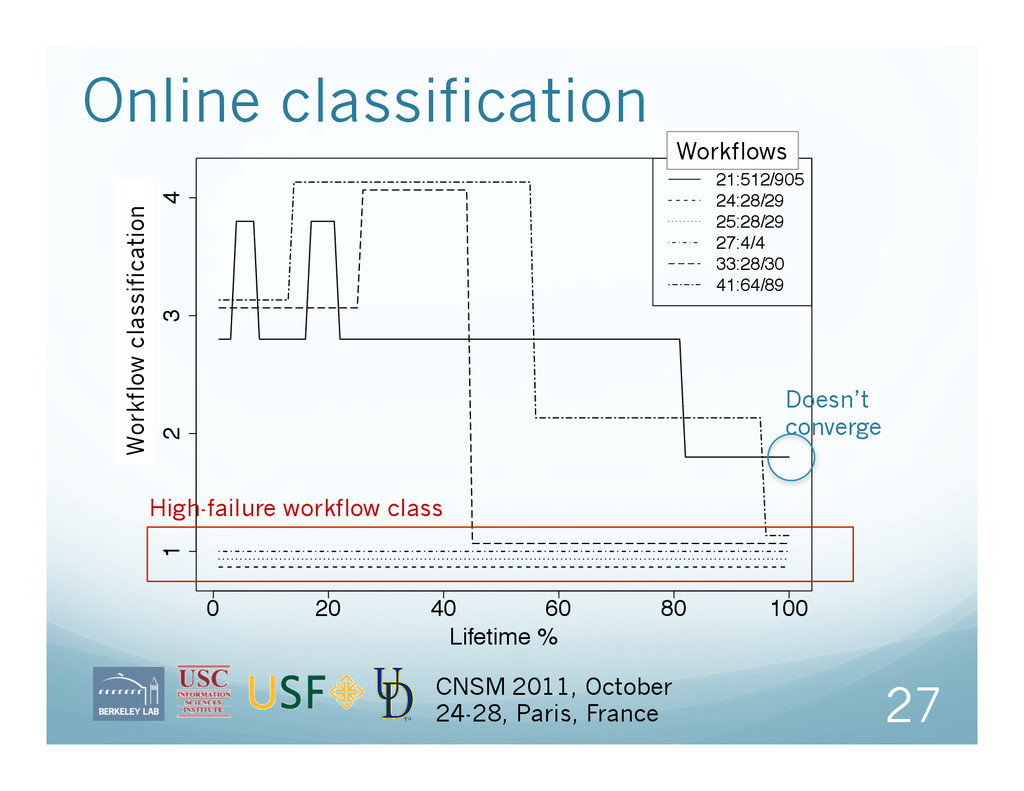
Successful jobs Failed jobs Success duration Fail duration Offline clustering on historical data Algorithm: k-means Online analysis classifies workflows according to nearest cluster 22 -
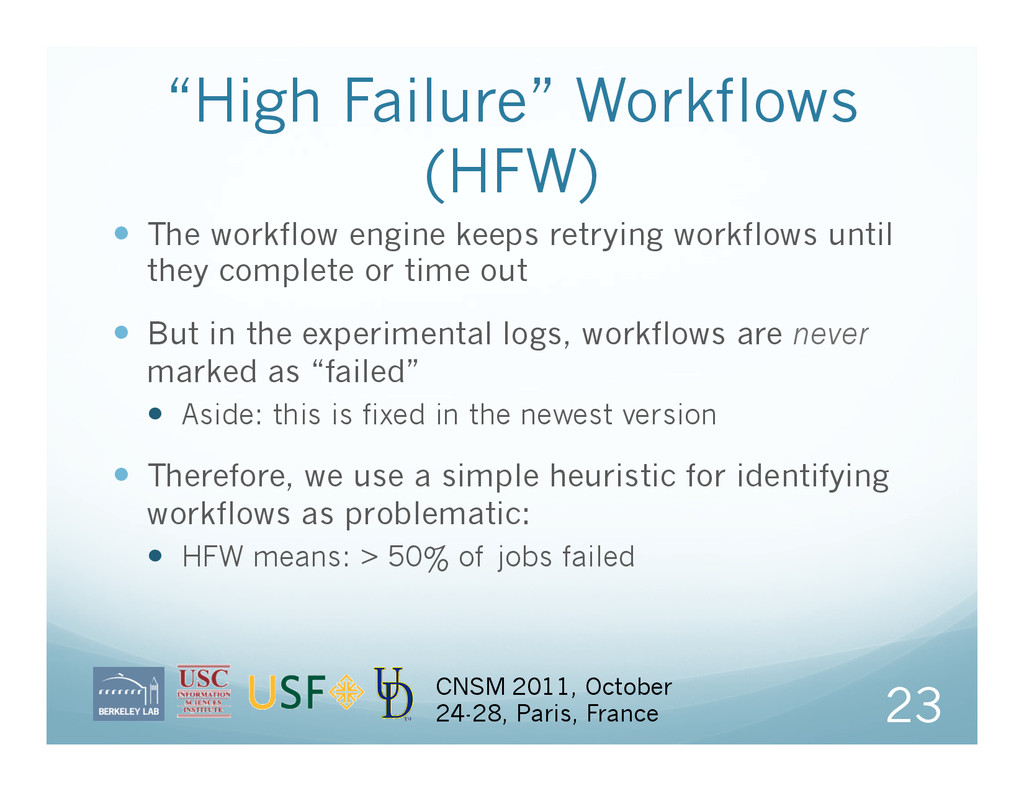
“High Failure” Workflows (HFW) The workflow engine keeps retrying
workflows until they complete or time out But in the experimental logs, workflows are never marked as “failed” Aside: this is fixed in the newest version Therefore, we use a simple heuristic for identifying workflows as problematic: HFW means: > 50% of jobs failed 23 CNSM 2011, October 24-28, Paris, France -
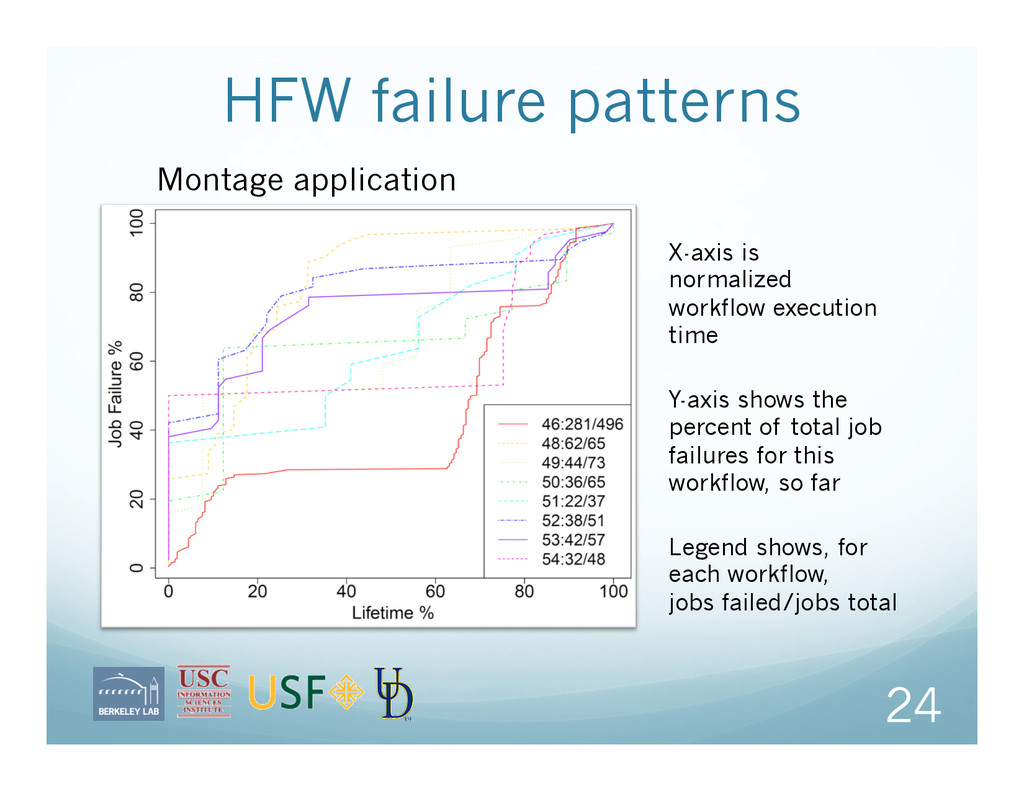
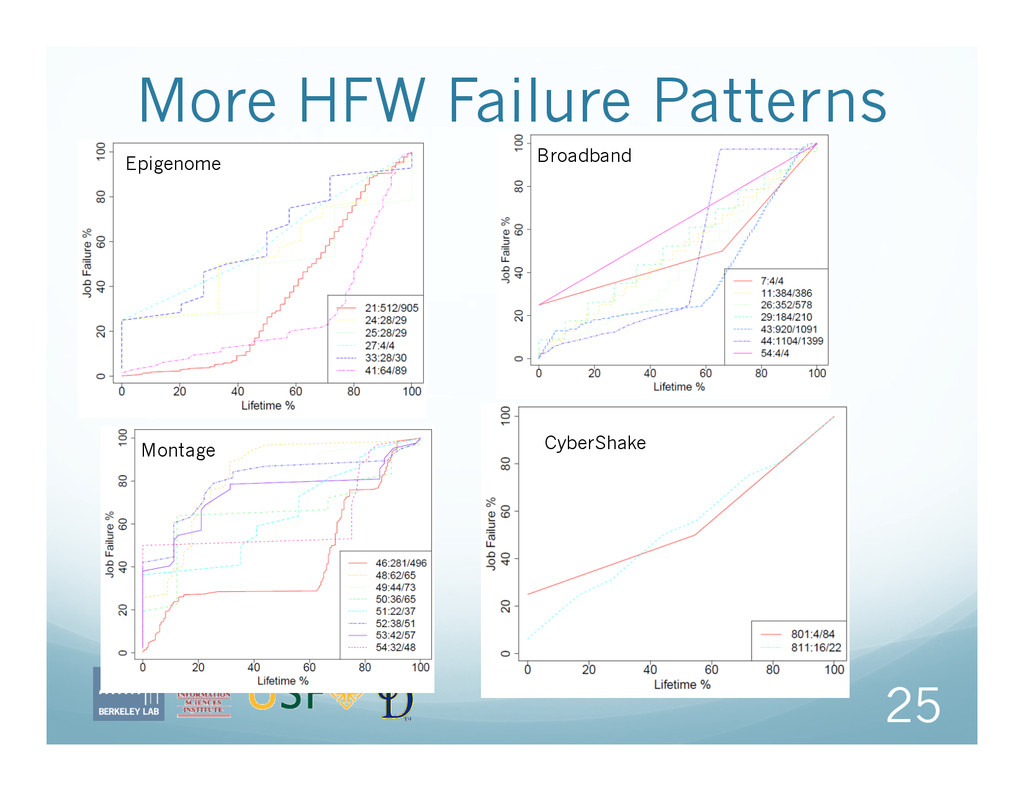
HFW failure patterns 24 Y-axis shows the percent of total
job failures for this workflow, so far Legend shows, for each workflow, jobs failed/jobs total X-axis is normalized workflow execution time Montage application -
Offline clustering −2 0 2 4 −1 0 1 2
3 4 5 Component 1 Component 2 • • • • • • • 1 12 23 34 40 4142 43 44 2 3 4 5 6 7 8 9 10 11 13 14 15 16 17 18 19 20 21 22 24 25 26 27 28 29 30 31 32 33 35 36 37 38 39 1 2 3 4 26 CNSM 2011, October 24-28, Paris, France High-failure workflow cluster Other 3 clusters Projection onto first 2 principal components Epigenome -
Online classification 0 20 40 60 80 100 Lifetime %
Class 1 2 3 4 21:512/905 24:28/29 25:28/29 27:4/4 33:28/30 41:64/89 27 CNSM 2011, October 24-28, Paris, France Workflows Workflow classification High-failure workflow class Doesn’t converge -
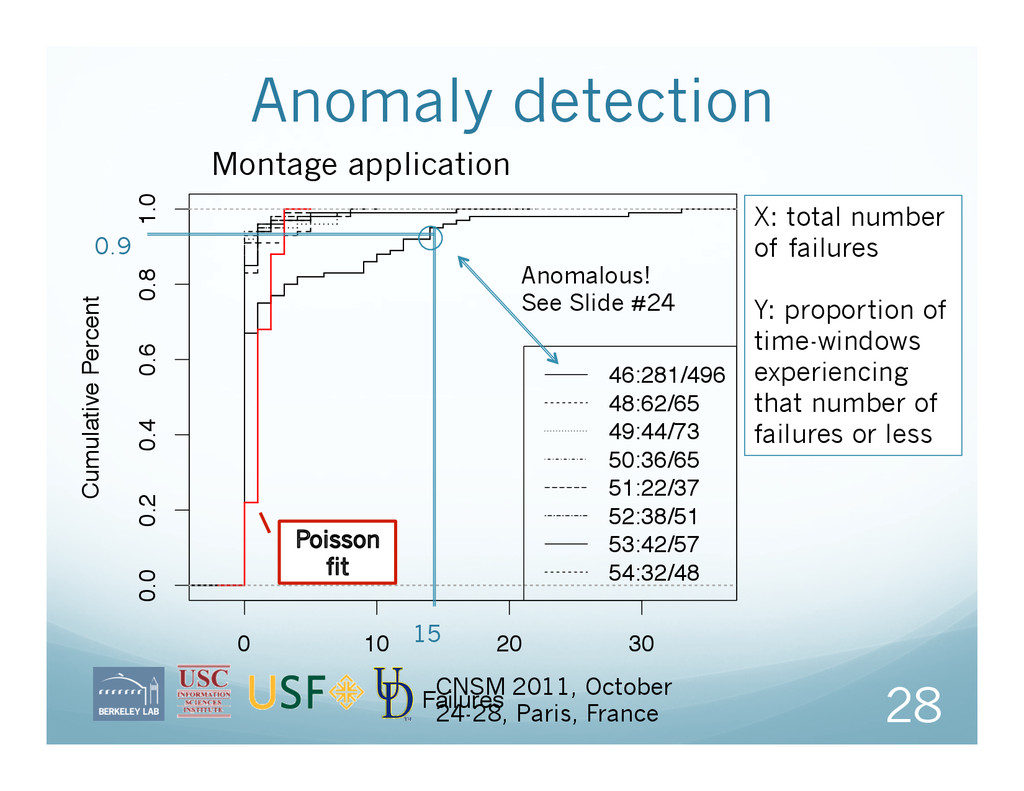
Anomaly detection 0 10 20 30 0.0 0.2 0.4 0.6
0.8 1.0 Failures Cumulative Percent 46:281/496 48:62/65 49:44/73 50:36/65 51:22/37 52:38/51 53:42/57 54:32/48 28 CNSM 2011, October 24-28, Paris, France X: total number of failures Y: proportion of time-windows experiencing that number of failures or less 0.9 15 Montage application Anomalous! See Slide #24 -
System performance CNSM 2011, October 24-28, Paris, France 29 Query
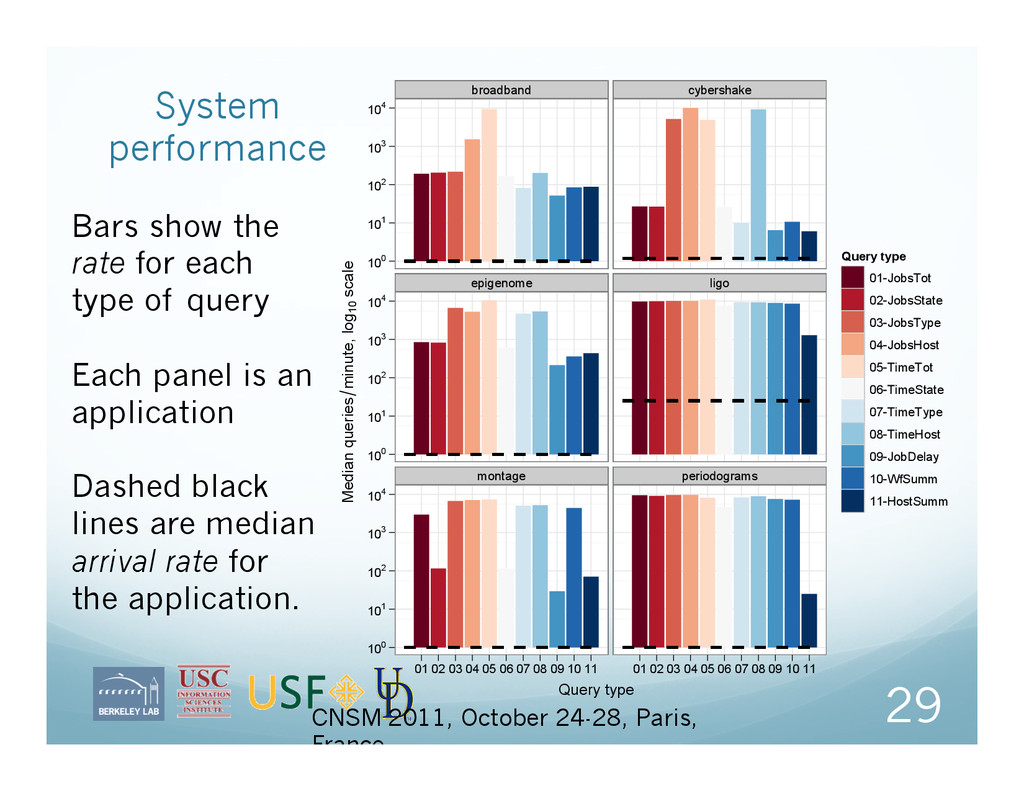
type Median queries minute, log10 scale 100 101 102 103 104 100 101 102 103 104 100 101 102 103 104 broadband epigenome montage 01 02 03 04 05 06 07 08 09 10 11 cybershake ligo periodograms 01 02 03 04 05 06 07 08 09 10 11 Query type 01-JobsTot 02-JobsState 03-JobsType 04-JobsHost 05-TimeTot 06-TimeState 07-TimeType 08-TimeHost 09-JobDelay 10-WfSumm 11-HostSumm Bars show the rate for each type of query Each panel is an application Dashed black lines are median arrival rate for the application. -
Summary Real-time failure prediction for scientific workflows is a
challenging but important task Unsupervised learning can be used to model high- level workflow failures from historical data High failure classes of workflows can be predicted in real-time with high accuracy Future directions Analysis; root-cause investigation System; notifications and updates Working with data from other workflow systems CNSM 2011, October 24-28, Paris, France 30 -
Thank you! For more information, visit the Stampede wiki at:
https://confluence.pegasus.isi.edu/display/stampede/ -
Pegasus Maps from abstract to concrete workflow Algorithmic
and AI-based techniques Automatically locates physical locations for both workflow components and data Finds appropriate resources to execute Reuses existing data products where applicable Publishes newly derived data products Provides provenance information 34 CNSM 2011, October 24-28, Paris, France -
NetLogger Logging Methodology Timestamped, named, messages at the
start and end of significant events, with additional identifiers and metadata in a std. line-oriented ASCII format (Best Practices or BP) APIs are provided, incl. in-memory log aggregation for high frequency events; but message generation is often best done within an existing framework Logging and Analysis Tools Parse many existing formats to BP Load BP into message bus, MySQL, MongoDB, etc. Generate profiles, graphs, and CSV from BP data 35 CNSM 2011, October 24-28, Paris, France