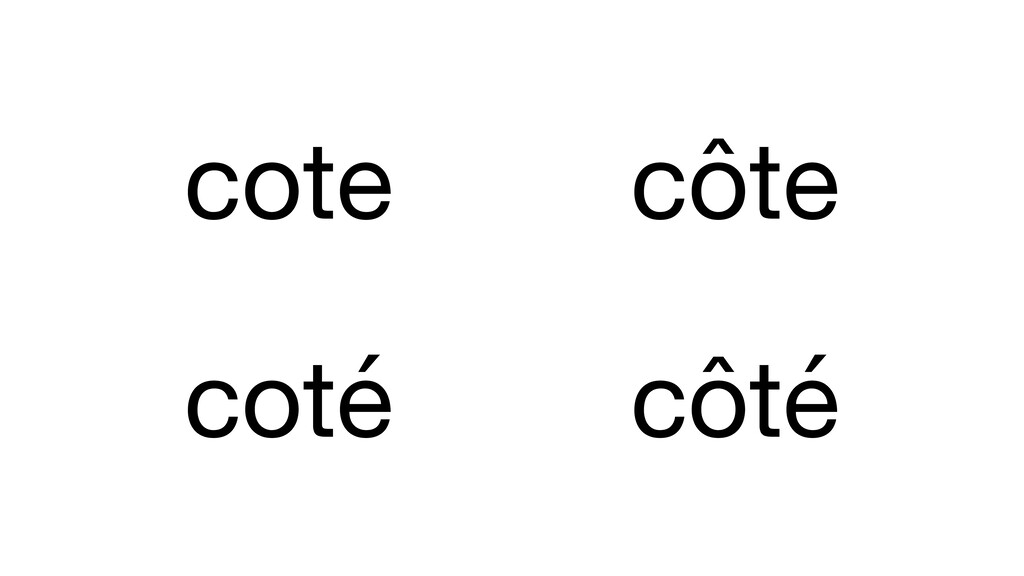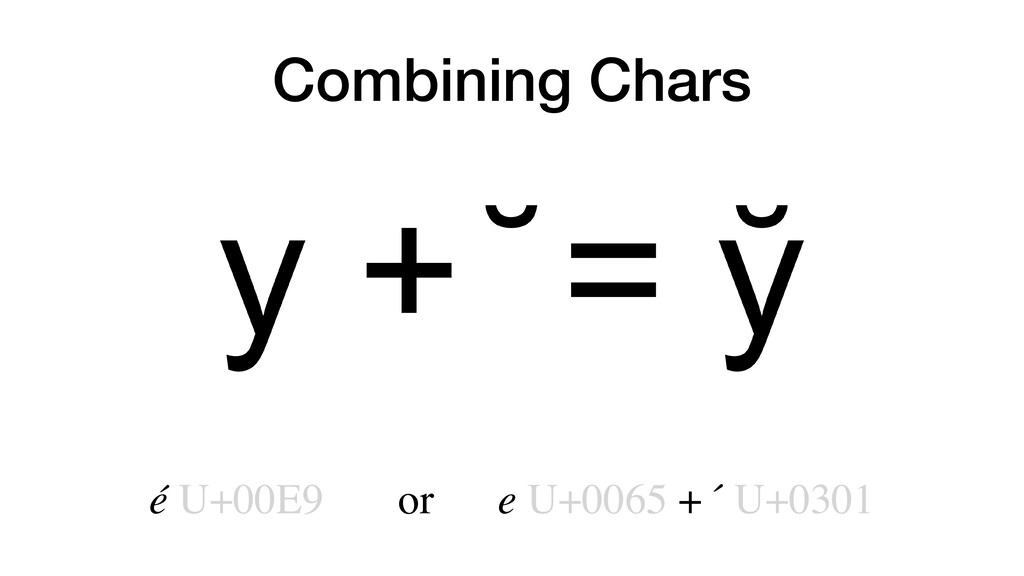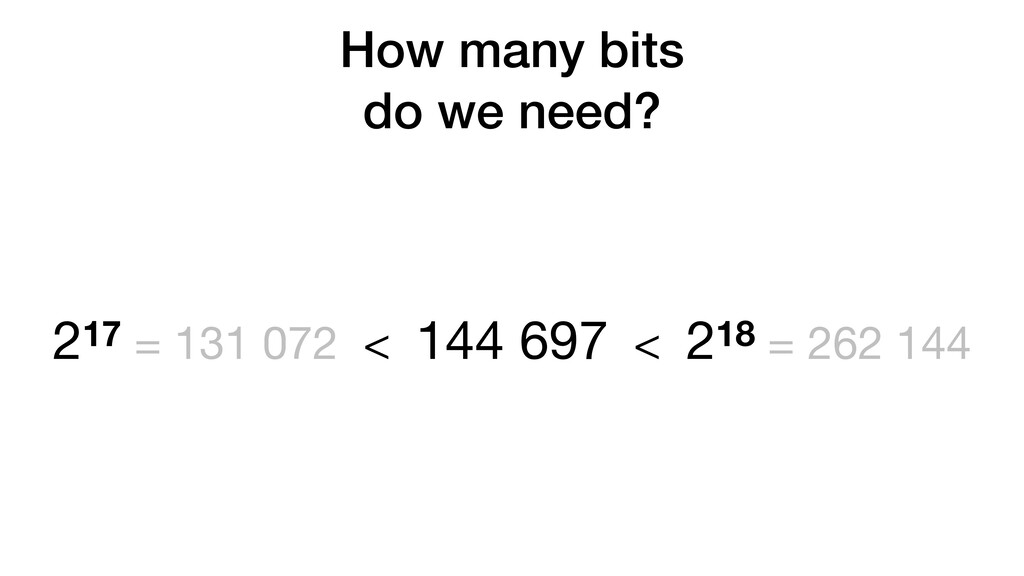Upgrade to Pro — share decks privately, control downloads, hide ads and more …

I � Unicode (DevoxxFr 2021)

I � Unicode (DevoxxFr 2021)

Slides de la conférence du 2021/10/01 à l'occasion du DevoxxFr.

"L'insoupçonnable complexité du texte. Comment votre langage de programmation prend-il en charge le média humain qu'est l'écriture ? Comment votre OS fait-il pour afficher toutes ces langues et alphabets différents ? Pourquoi parler de la "longueur d'une chaîne de caractères" est aussi pertinent qu'évoquer sa hauteur ? Avec Unicode, je vous propose un fascinant voyage à travers la modélisation du texte et sa représentation à l'écran, où tout est plus compliqué qu'il n'y paraît."

Avatar for David Blanchet

David Blanchet

October 01, 2021

Other Decks in Programming

Transcript

  1. Who Am I? David Blanchet Orange Labs • Developer •

    Trainings • Software Community • Playing with @davidblanchet iOS/Swift, Kotlin/SpringBoot/µServices/K8s Python, Git, web services Coding Dojo, technical blog, internal events Rust, Arduino, ESP8266, image generation…
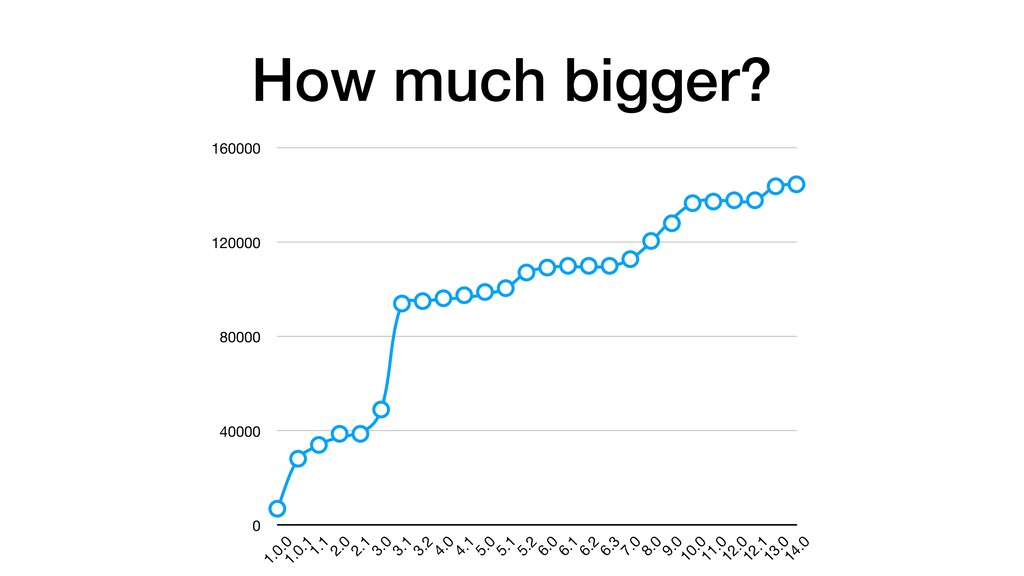
  2. How much bigger? 0 40000 80000 120000 160000 1.0.0 1.0.1

    1.1 2.0 2.1 3.0 3.1 3.2 4.0 4.1 5.0 5.1 5.2 6.0 6.1 6.2 6.3 7.0 8.0 9.0 10.0 11.0 12.0 12.1 13.0 14.0
  3. Diacritics â, ê, î, ô, û, ŵ, ŷ, ä, ë,

    ï, ö, ü, ẅ, ÿ, á, é, í, ó, ú, ẃ, ý, à, è, ì, ò, ù, ẁ, ỳ, ē, ī, ū, č, ģ, ķ, ļ, ņ, š, ž, ā, ä, ǟ, ḑ, ē, ī, ļ, ņ, ō, ȯ, ȱ, õ, ȭ, ŗ, š, ț, ū, ž…
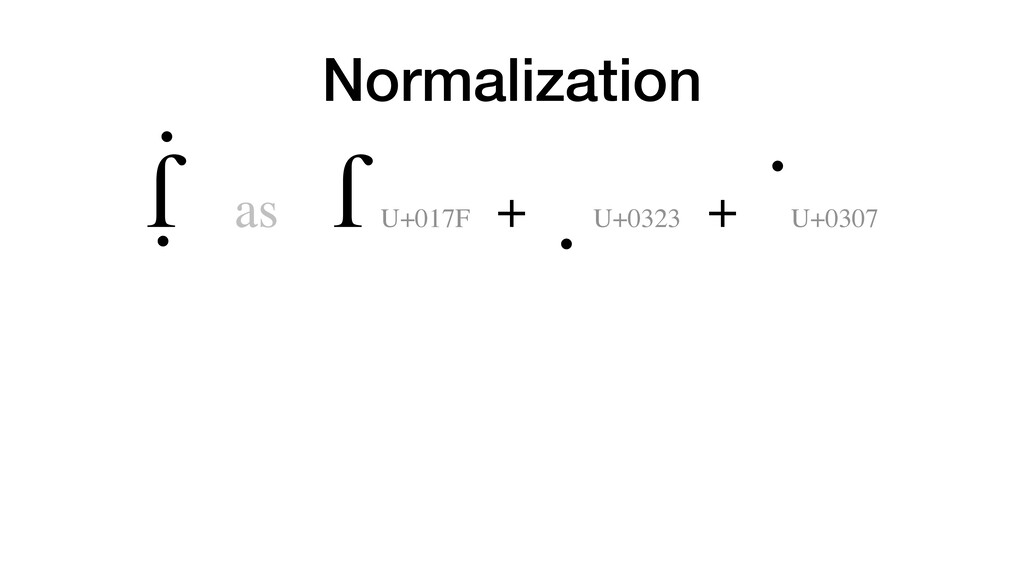
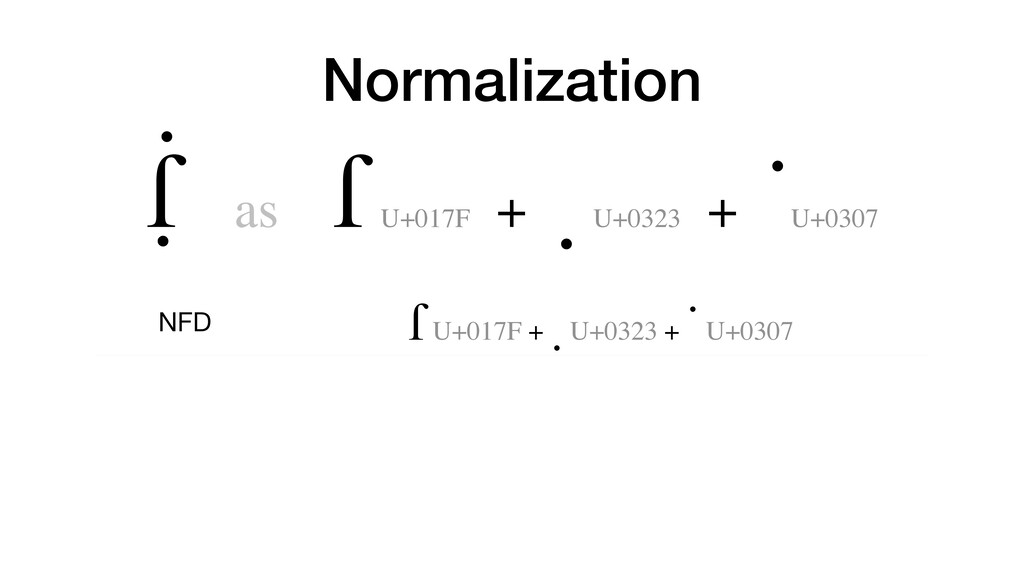
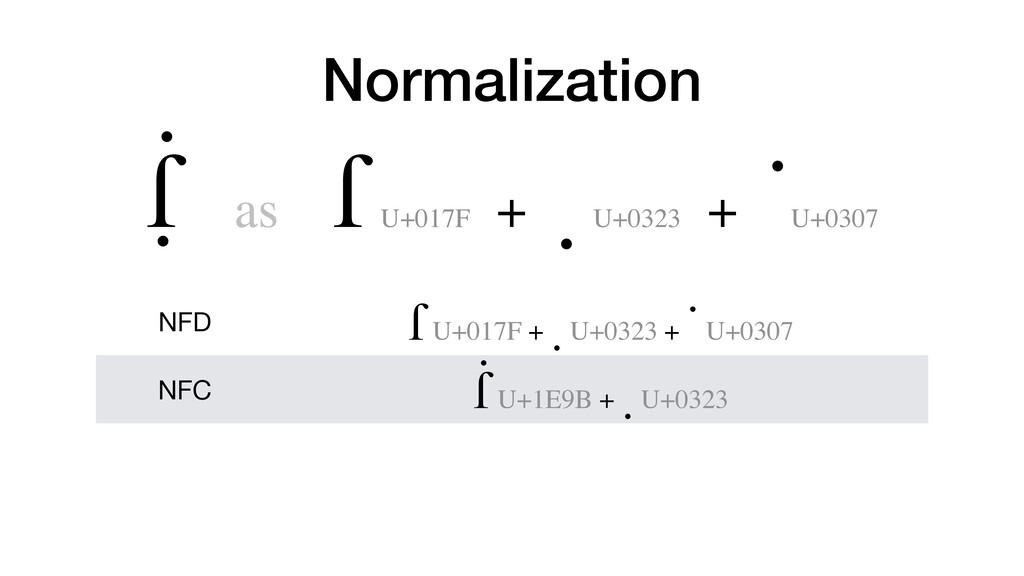
  4. Normalization ẛ ̣ as ſ U+017F + ̣ U+0323 +

    ̇U+0307 NFD ſ U+017F + ̣ U+0323 + ̇ U+0307
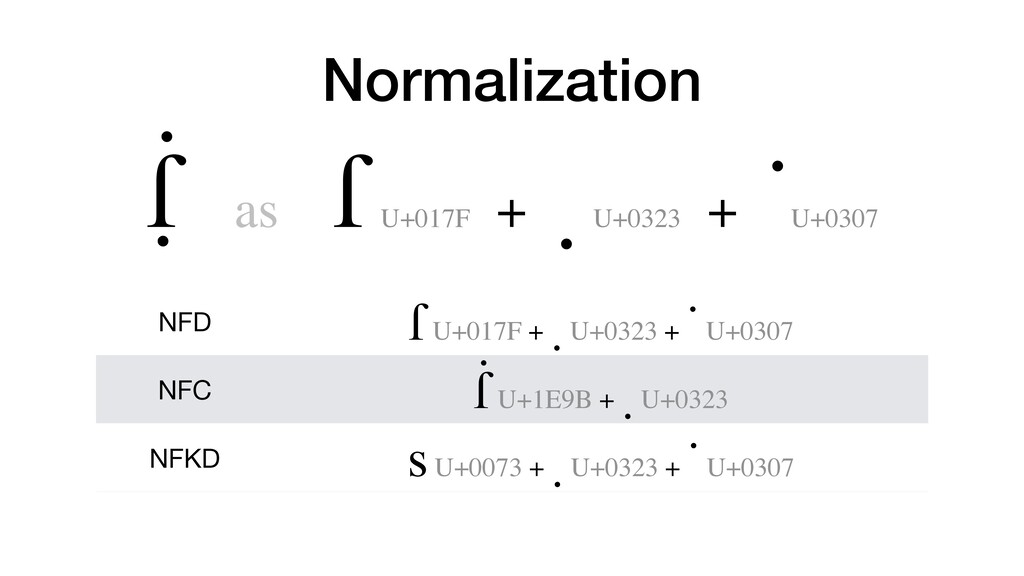
  5. Normalization ẛ ̣ as ſ U+017F + ̣ U+0323 +

    ̇U+0307 NFD ſ U+017F + ̣ U+0323 + ̇ U+0307 NFC ẛ U+1E9B + ̣ U+0323
  6. Normalization ẛ ̣ as ſ U+017F + ̣ U+0323 +

    ̇U+0307 NFD ſ U+017F + ̣ U+0323 + ̇ U+0307 NFC ẛ U+1E9B + ̣ U+0323 NFKD s U+0073 + ̣ U+0323 + ̇ U+0307
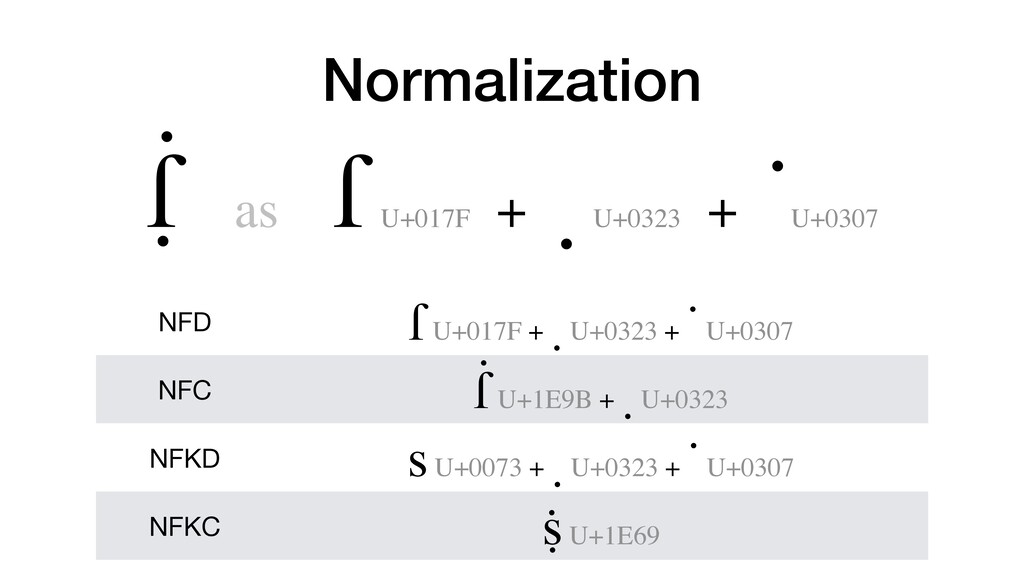
  7. Normalization ẛ ̣ as ſ U+017F + ̣ U+0323 +

    ̇U+0307 NFD ſ U+017F + ̣ U+0323 + ̇ U+0307 NFC ẛ U+1E9B + ̣ U+0323 NFKD s U+0073 + ̣ U+0323 + ̇ U+0307 NFKC ṩ U+1E69
  8. More… • Clusters and segmentation • Ligatures and digraphs •

    Contextual forms • 🥳 🧠 💥 🎺 🥰 😭 Yes, we are text!
  9. More… • Clusters and segmentation • Ligatures and digraphs •

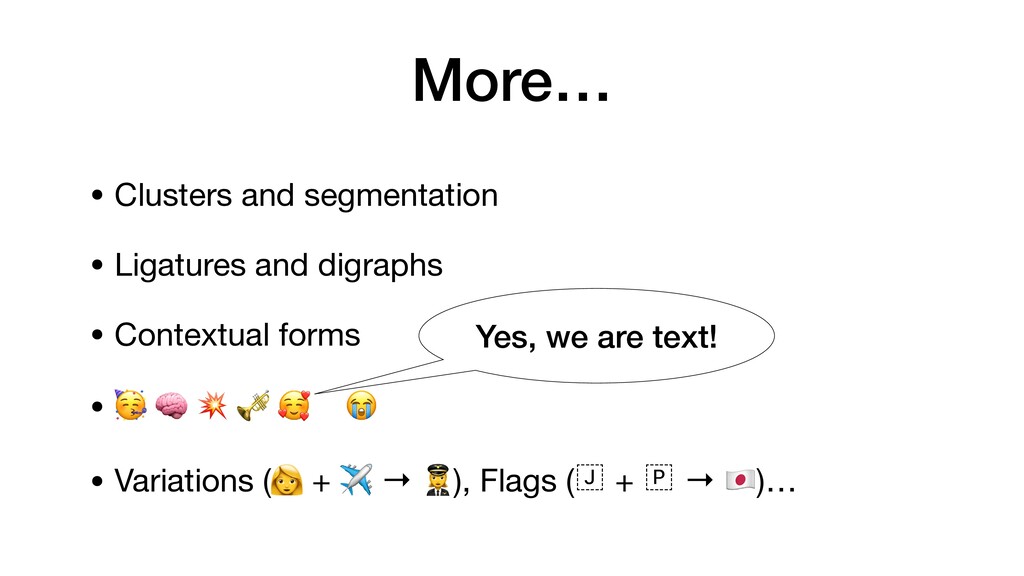
    Contextual forms • 🥳 🧠 💥 🎺 🥰 😭 • Variations (👩 + ✈ → 👩✈), Flags (🇯 + 🇵 → 🇯🇵)… Yes, we are text!
  10. Even More… • ASCII compatibility • Compatibility chars • Reference

    data fi les • Standard encodings • Rendering
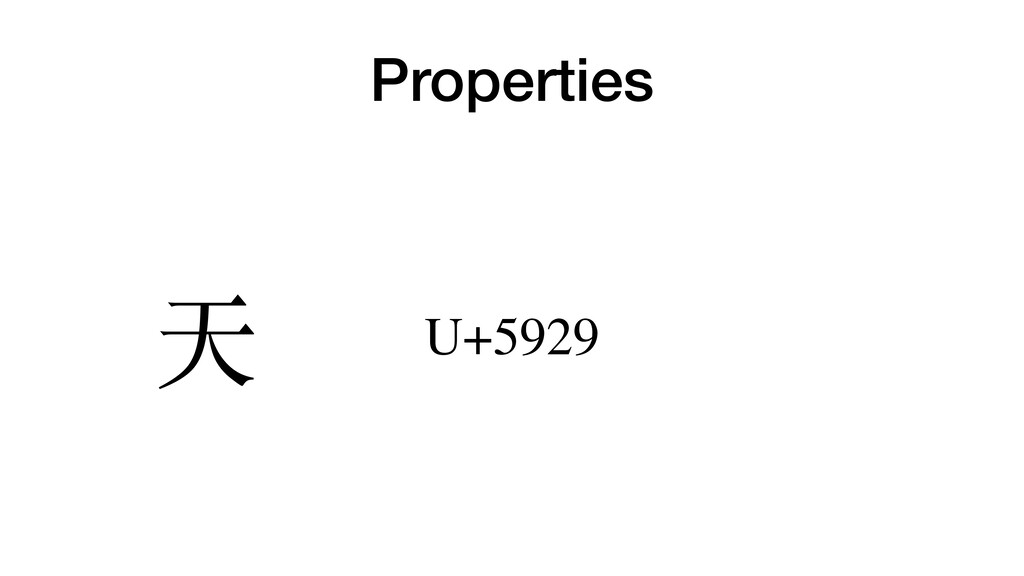
  11. Unicode • Big table of codepoints with properties • Reference
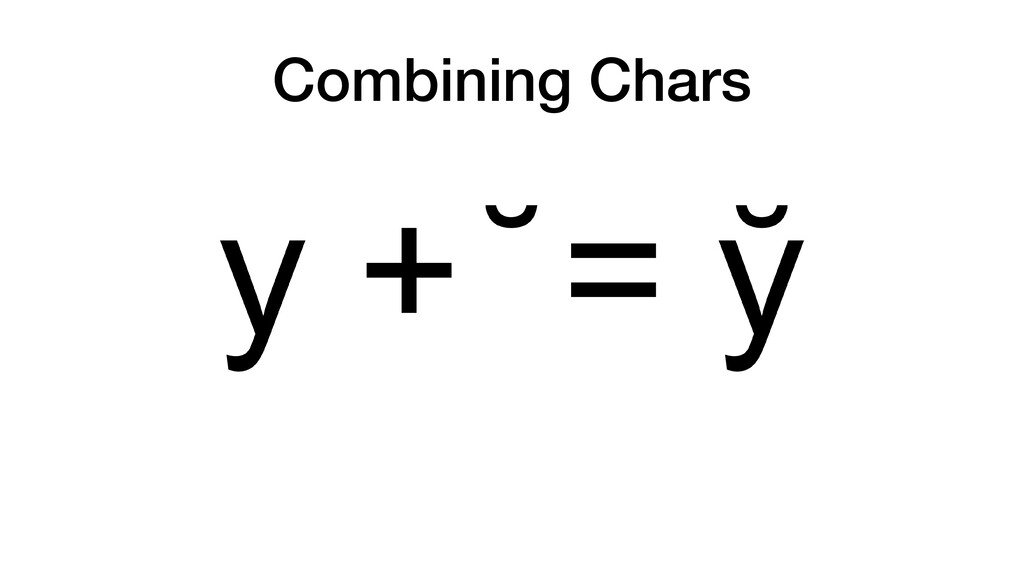
    data fi les • Algorithms Unicode support in Rust binaries is ~50 Ko
  12. Unicode • Big table of codepoints with properties • Reference

    data fi les • Algorithms Unicode support in Rust binaries is ~50 Ko « Bloat or feature? »
  13. « Unicode is a fascinating mess. It's fascinating in many

    ways, but one of the most interesting one is how well it works given the complexity. » Armin Ronacher - 2014
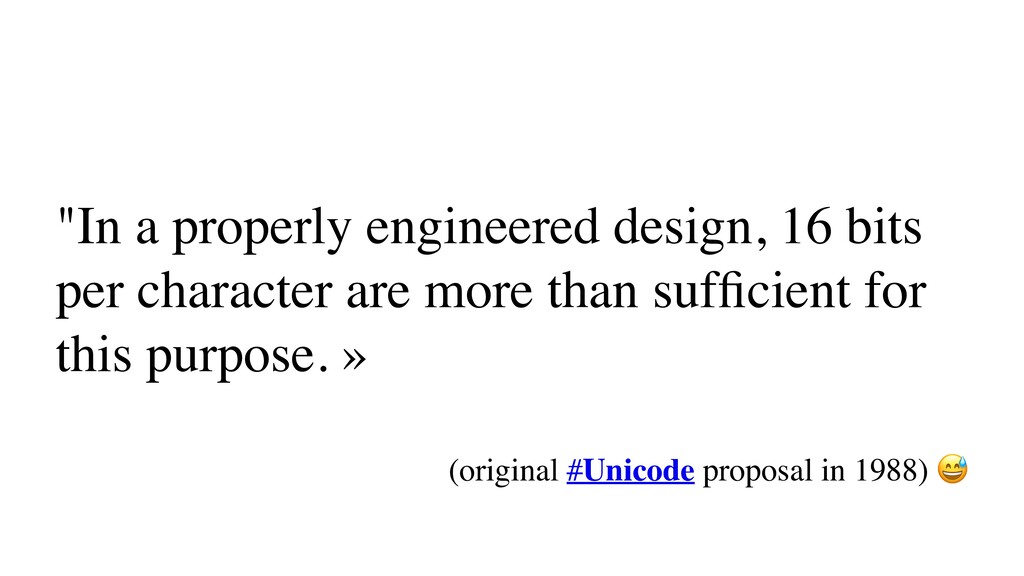
  14. "In a properly engineered design, 16 bits per character are

    more than suf fi cient for this purpose. » (original #Unicode proposal in 1988) 😅
  15. How many bits do we need? 217 = 131 072

    < 144 697 < 218 = 262 144
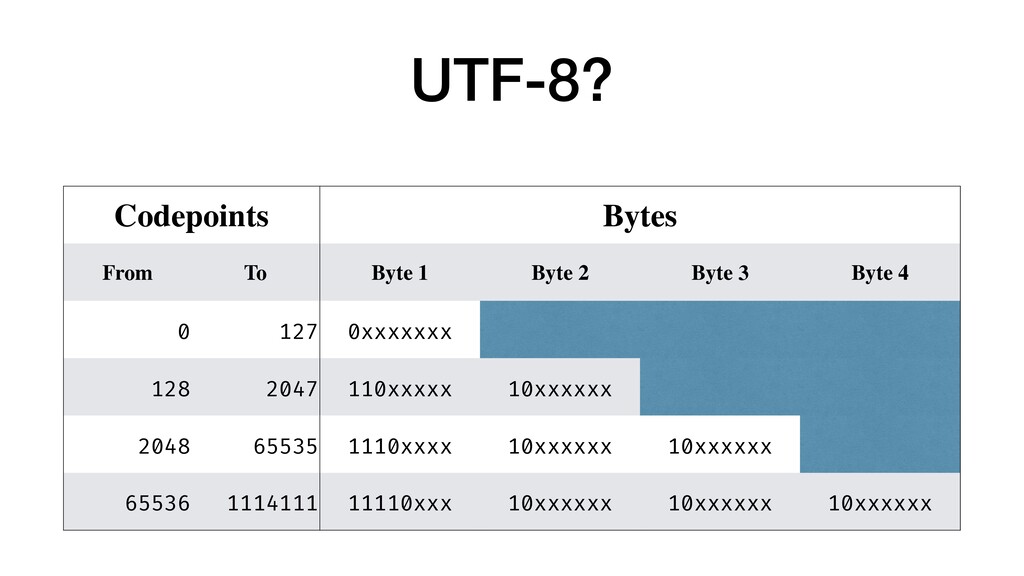
  16. UTF-8? Codepoints Bytes From To Byte 1 Byte 2 Byte

    3 Byte 4 0 127 0xxxxxxx 128 2047 110xxxxx 10xxxxxx 2048 65535 1110xxxx 10xxxxxx 10xxxxxx 65536 1114111 11110xxx 10xxxxxx 10xxxxxx 10xxxxxx
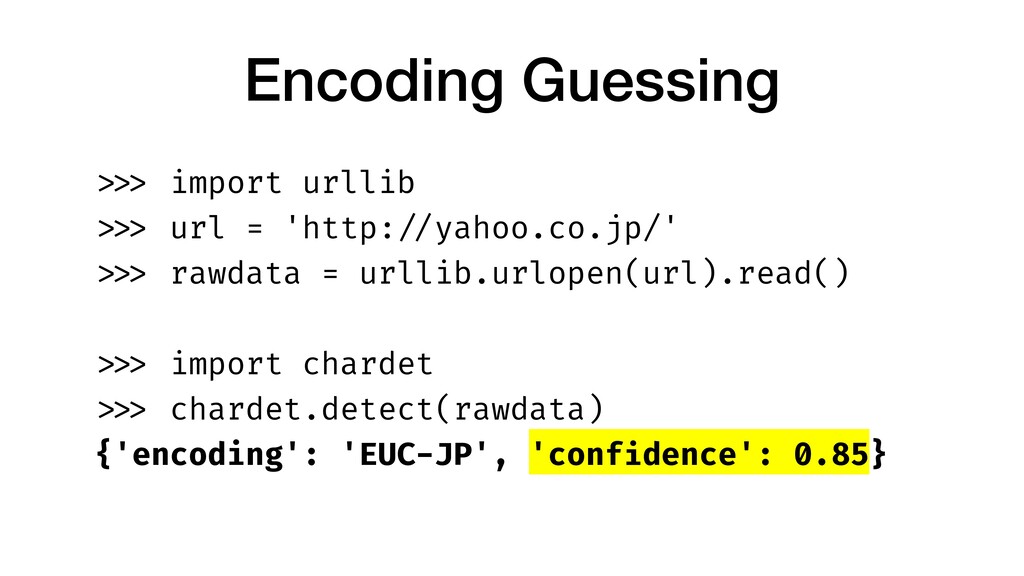
  17. Encoding Guessing > > > import urllib > > >

    url = 'http: / / yahoo.co.jp/' > > > rawdata = urllib.urlopen(url).read() > > > import chardet > > > chardet.detect(rawdata) {'encoding': 'EUC-JP', 'conf i dence': 0.85}
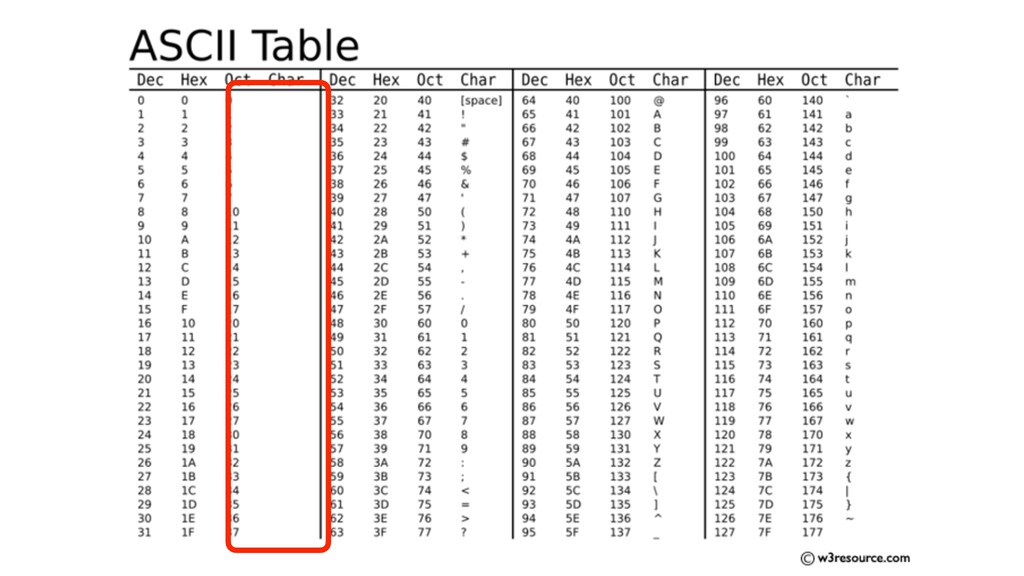
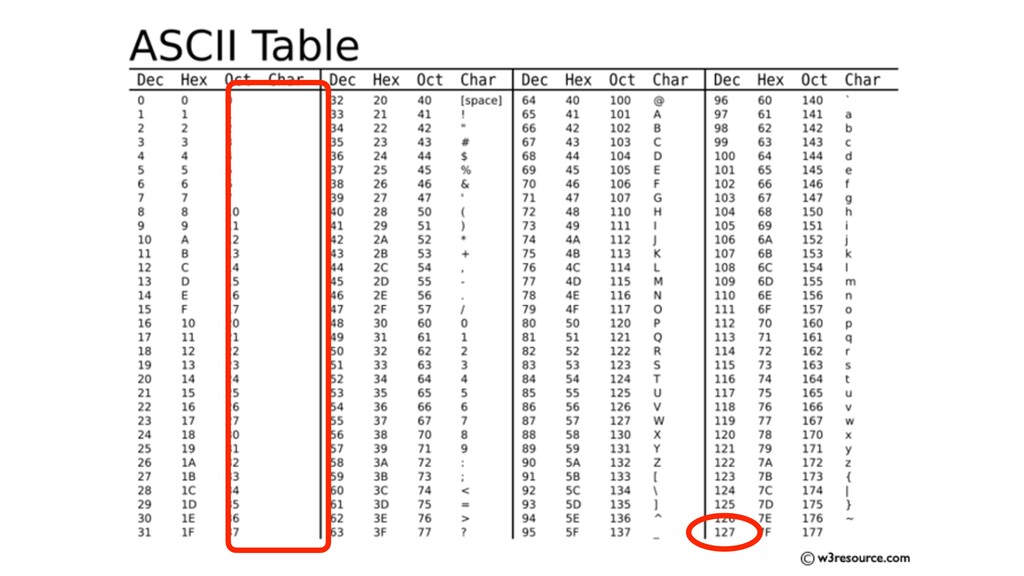
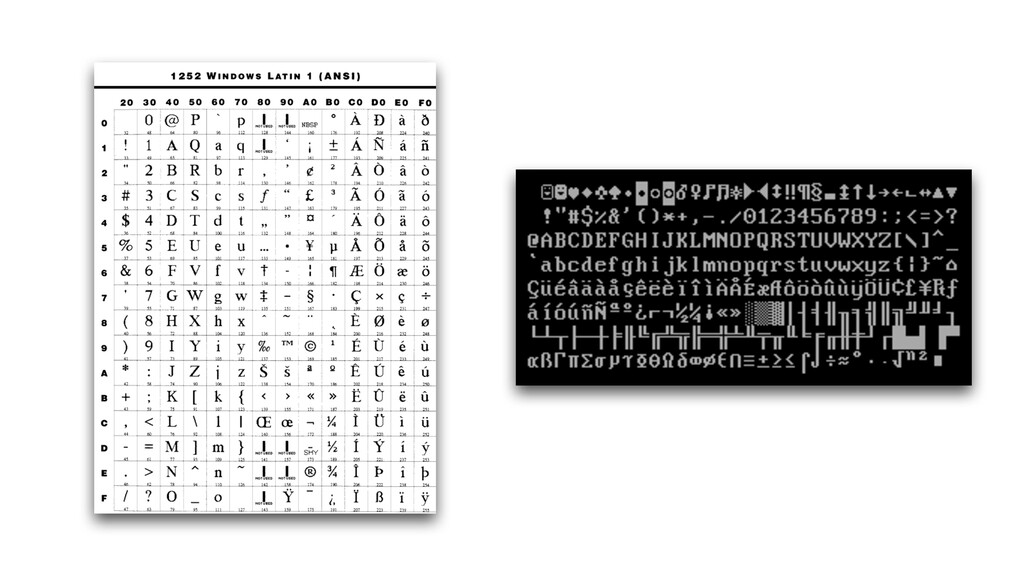
  18. Easy Solution « blob », i.e. opaque byte sequence •

    No peeking inside • No changes • (No display, obviously)
  19. Less Easy Solution So you want to know what is

    inside? Say… • char access? • substring? • parsing? • displaying?
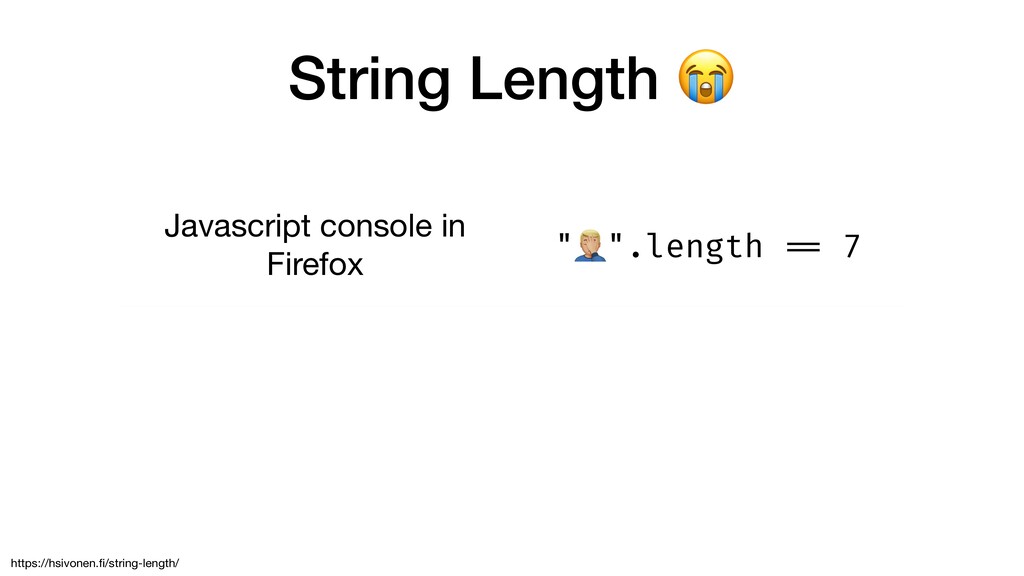
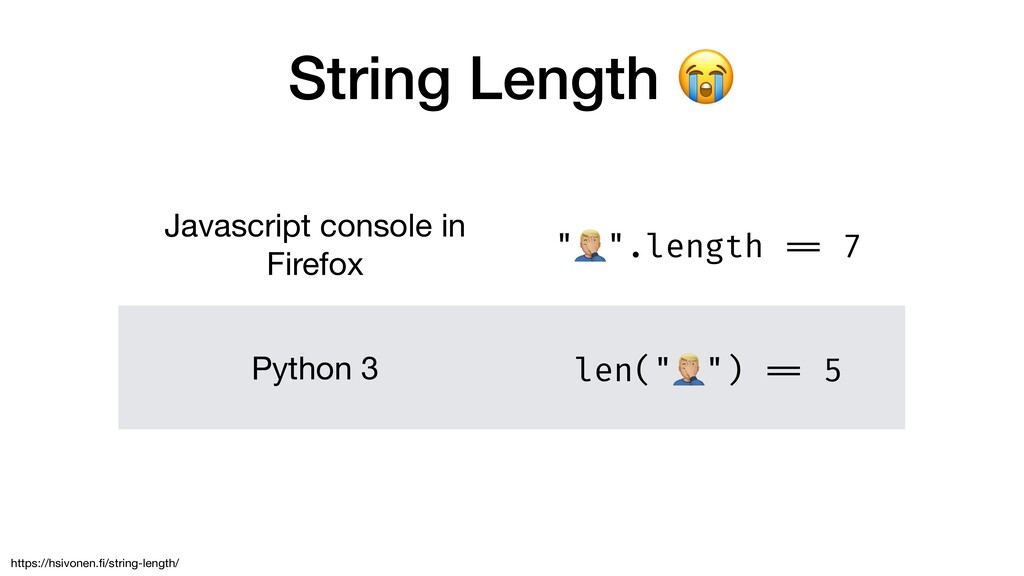
  20. String Length 😭 Javascript console in Firefox "🤦".length = =

    7 Python 3 len("🤦") = = 5 https://hsivonen. fi /string-length/
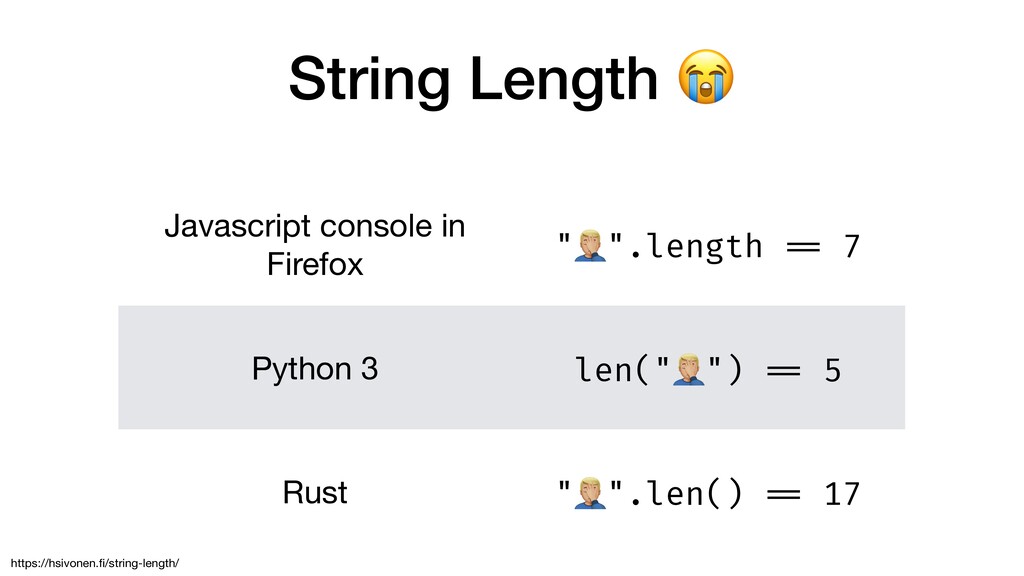
  21. String Length 😭 Javascript console in Firefox "🤦".length = =

    7 Python 3 len("🤦") = = 5 Rust "🤦".len() = = 17 https://hsivonen. fi /string-length/
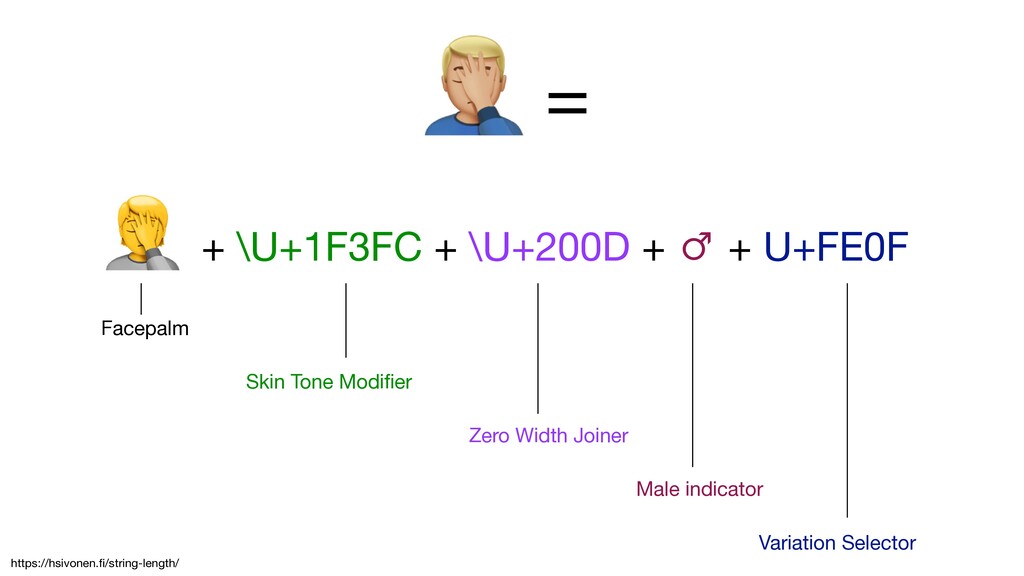
  22. 🤦 = 🤦 + \U+1F3FC + \U+200D + ♂ +

    U+FE0F Facepalm Skin Tone Modi fi er Zero Width Joiner Male indicator Variation Selector https://hsivonen. fi /string-length/
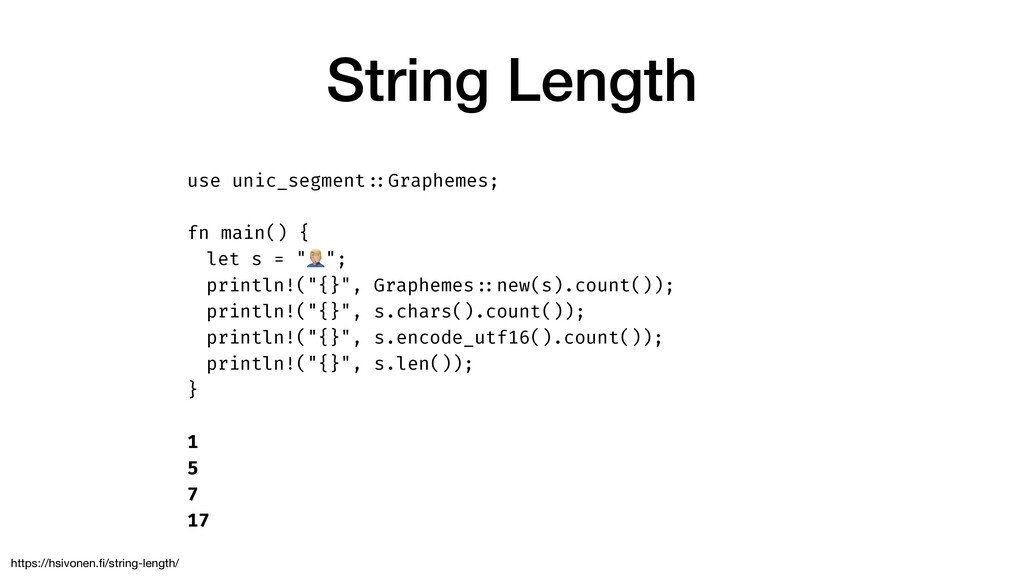
  23. String Length use unic_segment : : Graphemes; fn main() {

    let s = "🤦"; println!("{}", Graphemes : : new(s).count()); println!("{}", s.chars().count()); println!("{}", s.encode_utf16().count()); println!("{}", s.len()); } 1 5 7 17 https://hsivonen. fi /string-length/
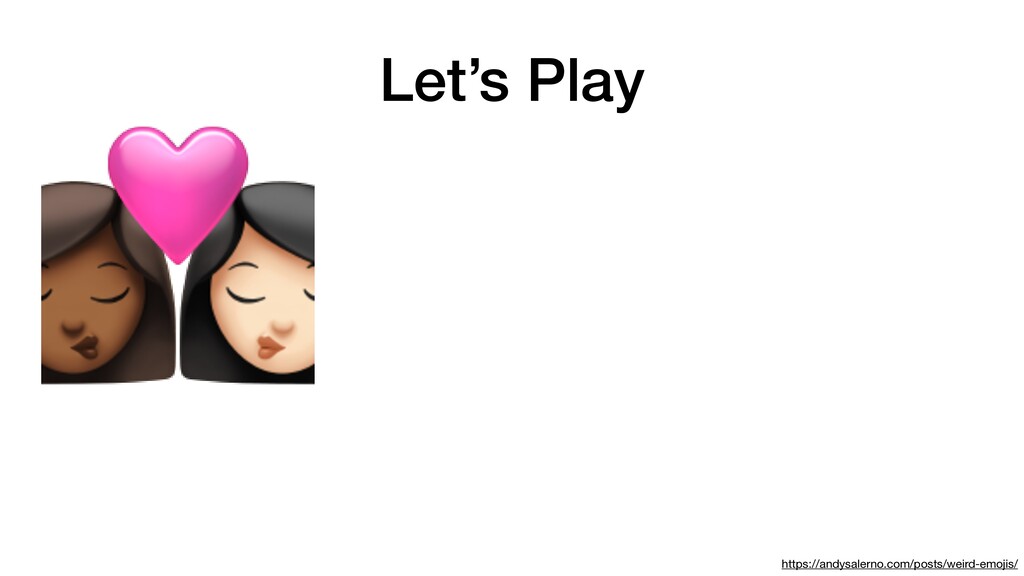
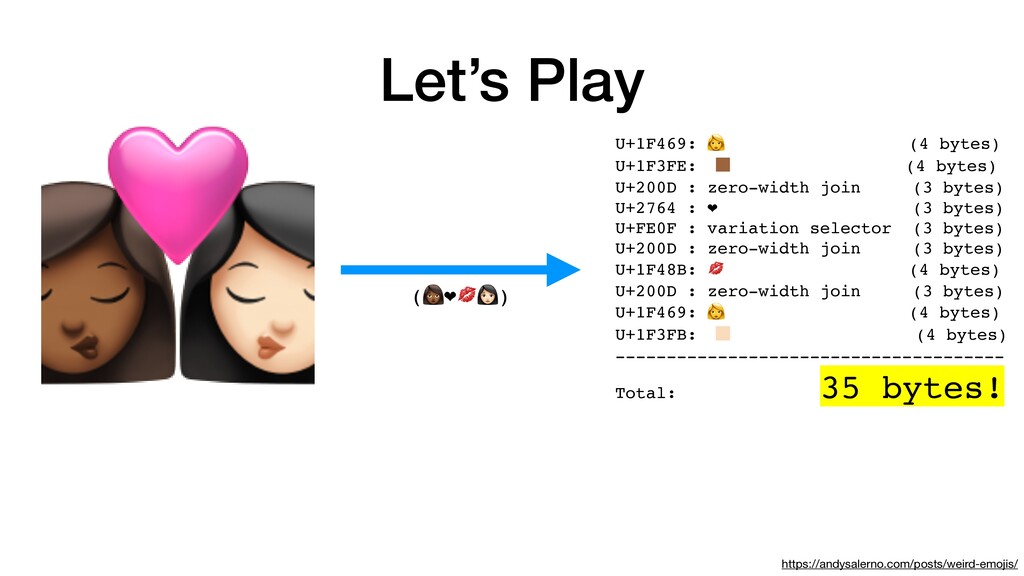
  24. Let’s Play U+1F469: 👩 (4 bytes ) U+1F3FE: 🏾 (4

    bytes ) U+200D : zero-width join (3 bytes ) U+2764 : ❤ (3 bytes ) U+FE0F : variation selector (3 bytes ) U+200D : zero-width join (3 bytes ) U+1F48B: 💋 (4 bytes ) U+200D : zero-width join (3 bytes ) U+1F469: 👩 (4 bytes ) U+1F3FB: 🏻 (4 bytes ) -------------------------------------- Total: 35 bytes! 👩 👩 (👩❤💋👩) https://andysalerno.com/posts/weird-emojis/
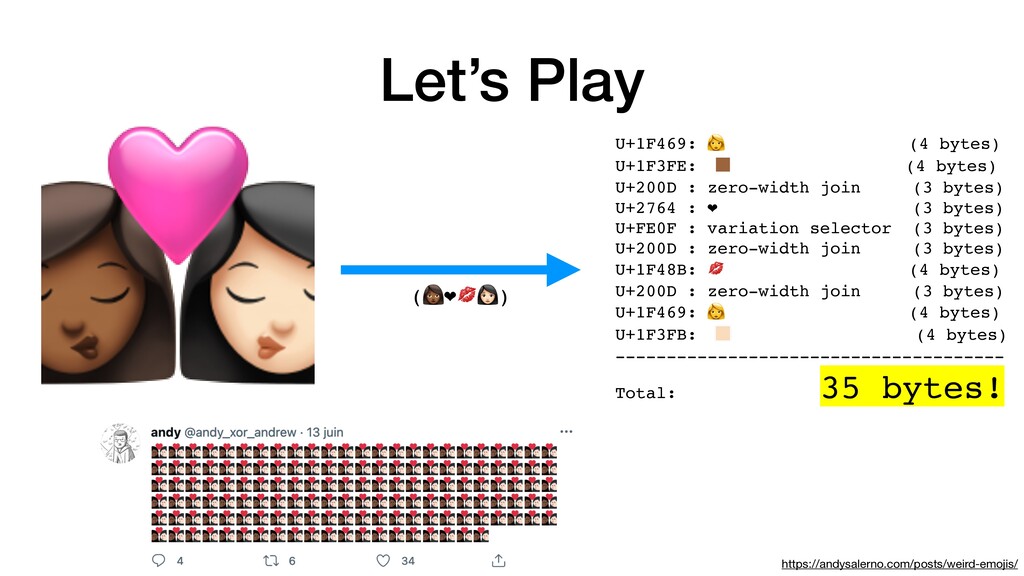
  25. Let’s Play U+1F469: 👩 (4 bytes ) U+1F3FE: 🏾 (4

    bytes ) U+200D : zero-width join (3 bytes ) U+2764 : ❤ (3 bytes ) U+FE0F : variation selector (3 bytes ) U+200D : zero-width join (3 bytes ) U+1F48B: 💋 (4 bytes ) U+200D : zero-width join (3 bytes ) U+1F469: 👩 (4 bytes ) U+1F3FB: 🏻 (4 bytes ) -------------------------------------- Total: 35 bytes! 👩 👩 (👩❤💋👩) https://andysalerno.com/posts/weird-emojis/
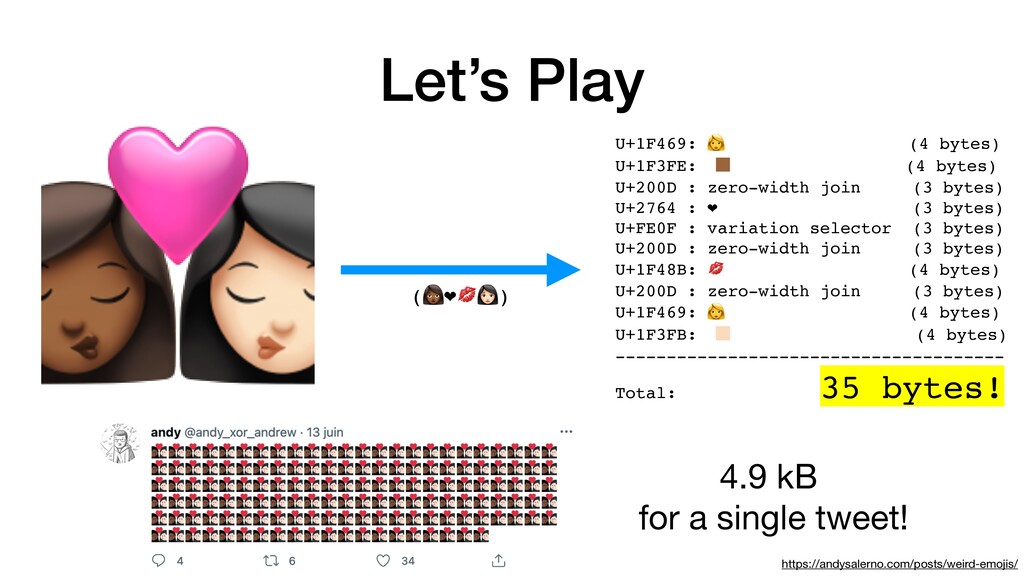
  26. Let’s Play 4.9 kB for a single tweet! U+1F469: 👩

    (4 bytes ) U+1F3FE: 🏾 (4 bytes ) U+200D : zero-width join (3 bytes ) U+2764 : ❤ (3 bytes ) U+FE0F : variation selector (3 bytes ) U+200D : zero-width join (3 bytes ) U+1F48B: 💋 (4 bytes ) U+200D : zero-width join (3 bytes ) U+1F469: 👩 (4 bytes ) U+1F3FB: 🏻 (4 bytes ) -------------------------------------- Total: 35 bytes! 👩 👩 (👩❤💋👩) https://andysalerno.com/posts/weird-emojis/
  27. Risk, in 6 simple steps 1. len(data) > len(buffer) 2.

    Bu ff er over fl ow 3. (Arbitrary) code execution
  28. Risk, in 6 simple steps 1. len(data) > len(buffer) 2.

    Bu ff er over fl ow 3. (Arbitrary) code execution 4. Intrusion
  29. Risk, in 6 simple steps 1. len(data) > len(buffer) 2.

    Bu ff er over fl ow 3. (Arbitrary) code execution 4. Intrusion 5. Massive data leak
  30. Risk, in 6 simple steps 1. len(data) > len(buffer) 2.

    Bu ff er over fl ow 3. (Arbitrary) code execution 4. Intrusion 5. Massive data leak 6. End of the world
  31. Risk, in 6 simple steps 1. len(data) > len(buffer) 2.

    Bu ff er over fl ow 3. (Arbitrary) code execution 4. Intrusion 5. Massive data leak 6. End of the world of your customer and your fi nancial trust, and huge PR headaches
  32. So what? • Rely on modern, high-level Unicode-aware libraries, OSes,

    applications • Be explicit (encoding, locale…)
  33. So what? • Rely on modern, high-level Unicode-aware libraries, OSes,

    applications • Be explicit (encoding, locale…) • Know what you are doing
  34. So what? • Rely on modern, high-level Unicode-aware libraries, OSes,

    applications • Be explicit (encoding, locale…) • Know what you are doing • Test!
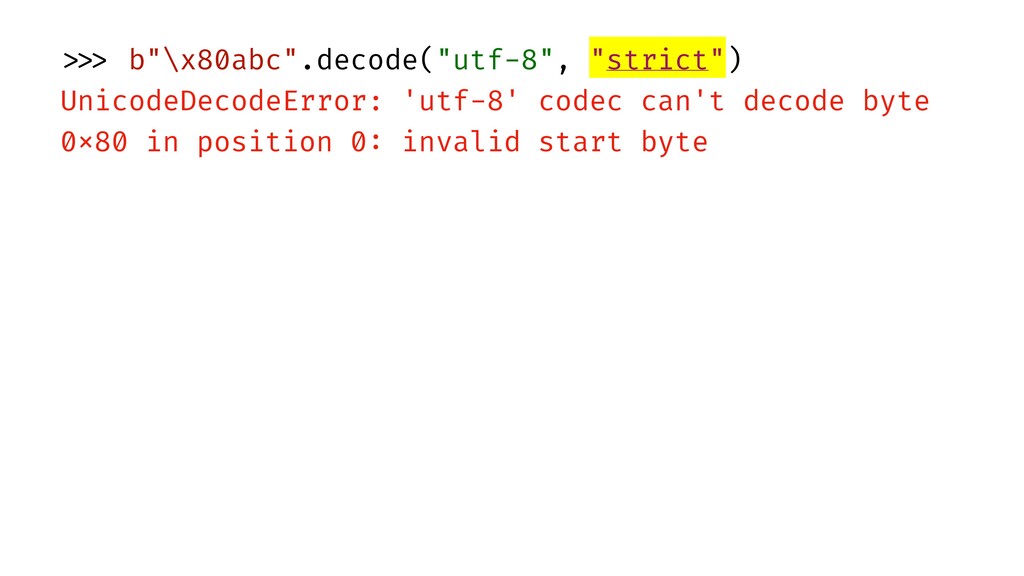
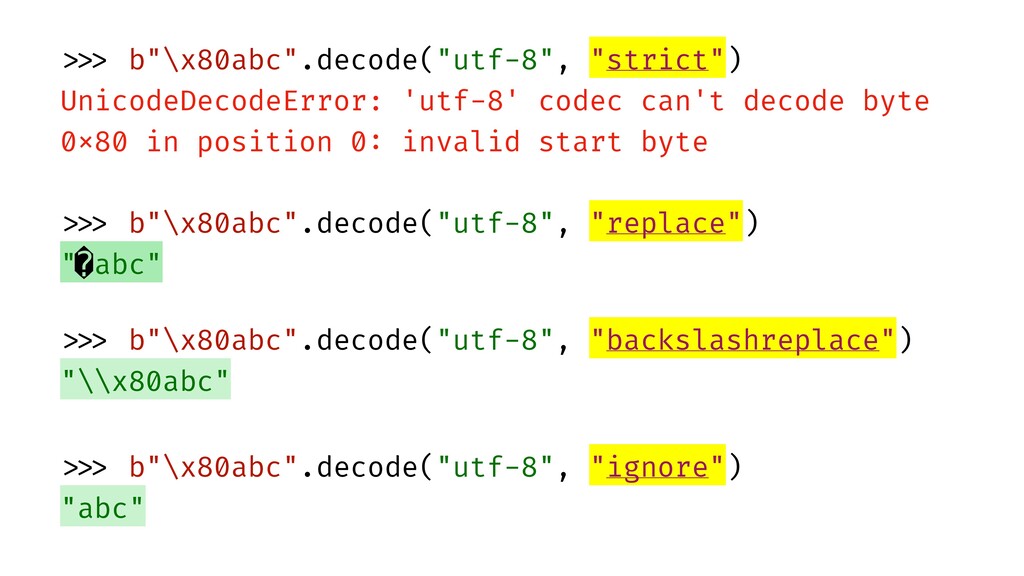
  35. > > > b"\x80abc".decode("utf-8", "strict") 
 UnicodeDecodeError: 'utf-8' codec can't

    decode byte 
 0 x 80 in position 0 : invalid start byte
  36. > > > b"\x80abc".decode("utf-8", "strict") 
 UnicodeDecodeError: 'utf-8' codec can't

    decode byte 
 0 x 80 in position 0 : invalid start byte 


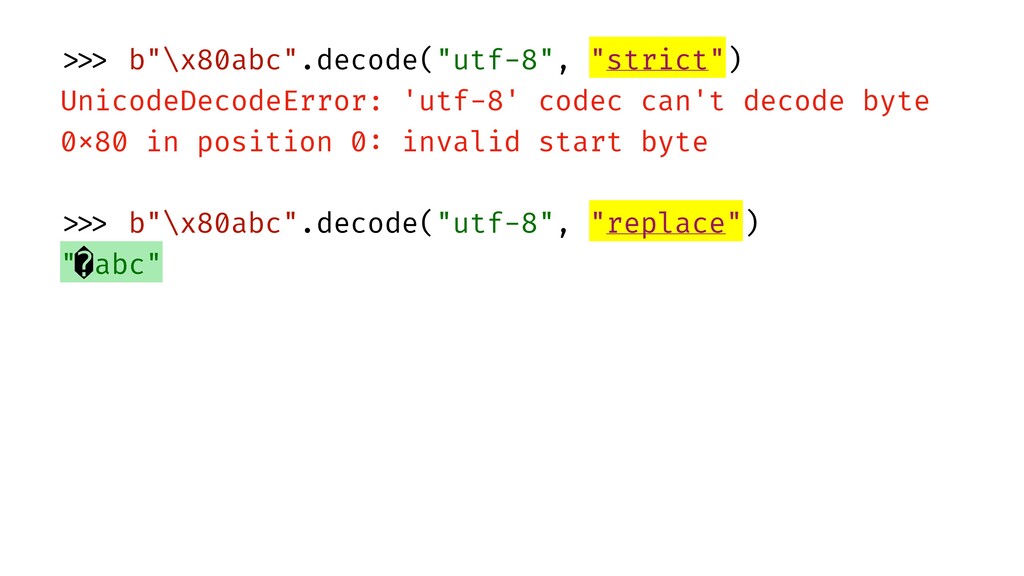
 > > > b"\x80abc".decode("utf-8", "replace") 
 " abc"
  37. > > > b"\x80abc".decode("utf-8", "strict") 
 UnicodeDecodeError: 'utf-8' codec can't

    decode byte 
 0 x 80 in position 0 : invalid start byte 


 > > > b"\x80abc".decode("utf-8", "replace") 
 " abc" 
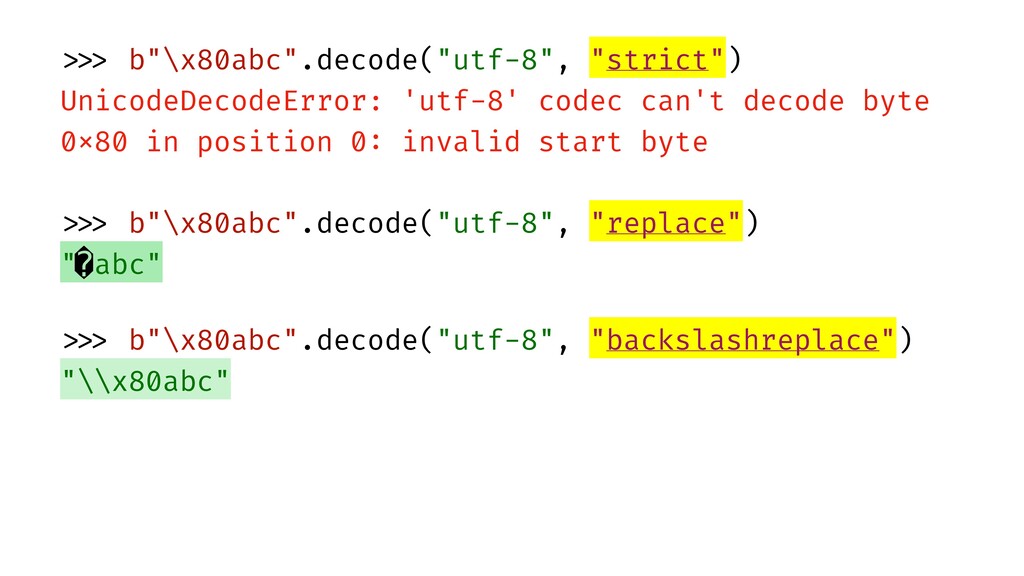
 > > > b"\x80abc".decode("utf-8", "backslashreplace") 
 "\\x80abc"
  38. > > > b"\x80abc".decode("utf-8", "strict") 
 UnicodeDecodeError: 'utf-8' codec can't

    decode byte 
 0 x 80 in position 0 : invalid start byte 
 > > > b"\x80abc".decode("utf-8", "ignore") 
 "abc" 


 > > > b"\x80abc".decode("utf-8", "replace") 
 " abc" 
 > > > b"\x80abc".decode("utf-8", "backslashreplace") 
 "\\x80abc"
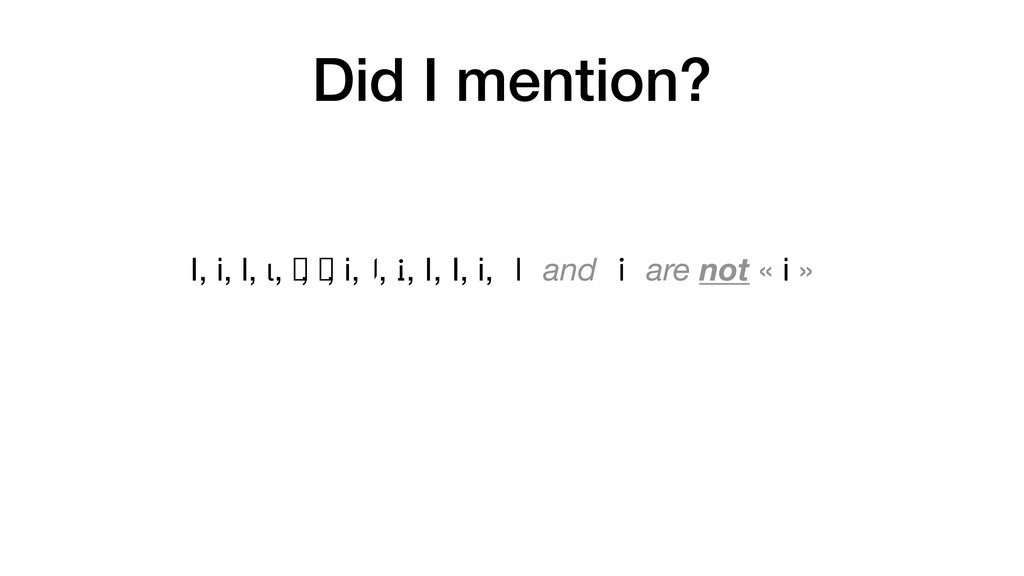
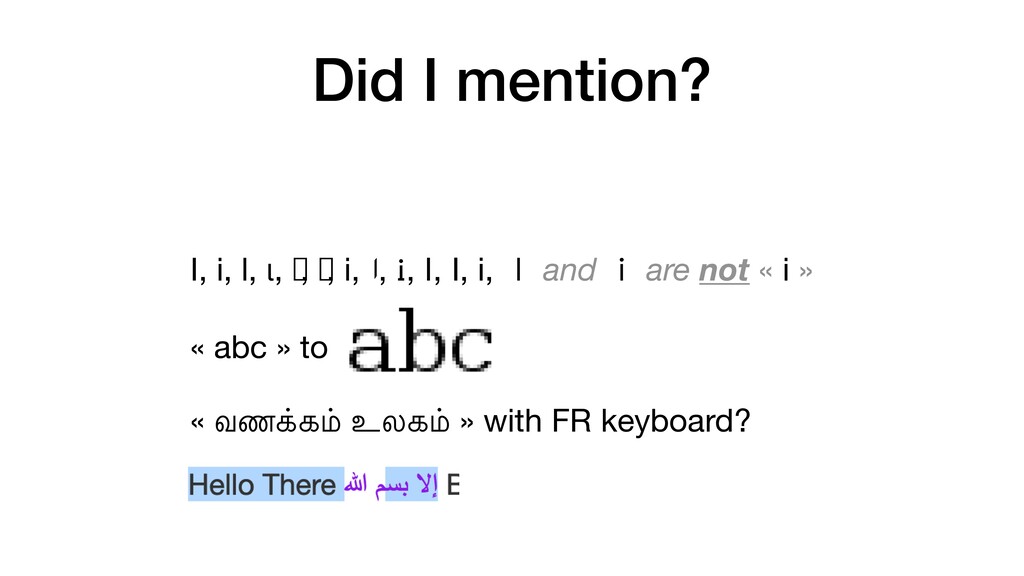
  39. I, i, l, ɩ, Ι, І, і, ا, Ꭵ, ᛁ,

    Ⅰ, ⅰ, I and i are not « i » Did I mention?
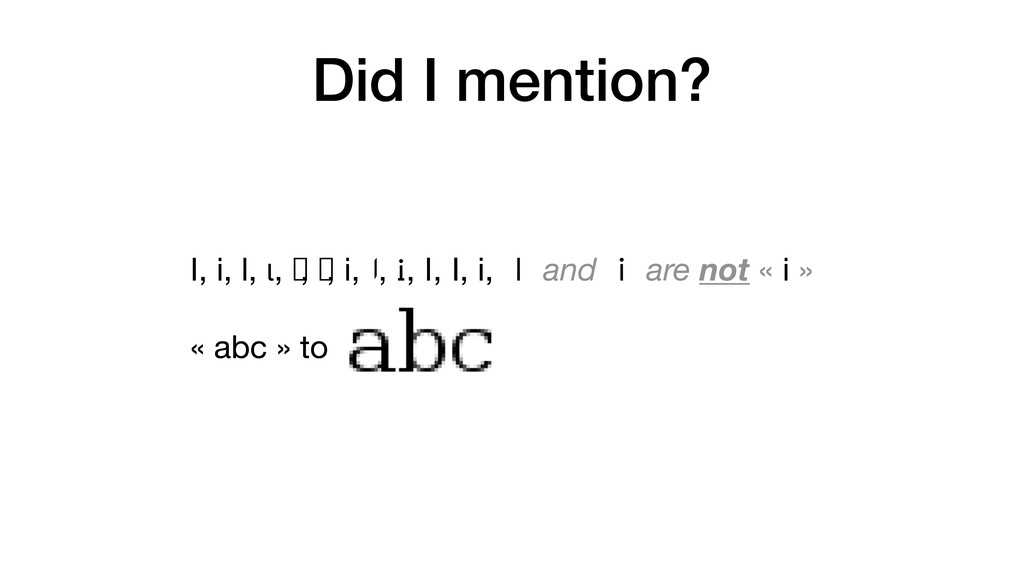
  40. I, i, l, ɩ, Ι, І, і, ا, Ꭵ, ᛁ,

    Ⅰ, ⅰ, I and i are not « i » « abc » to Did I mention?
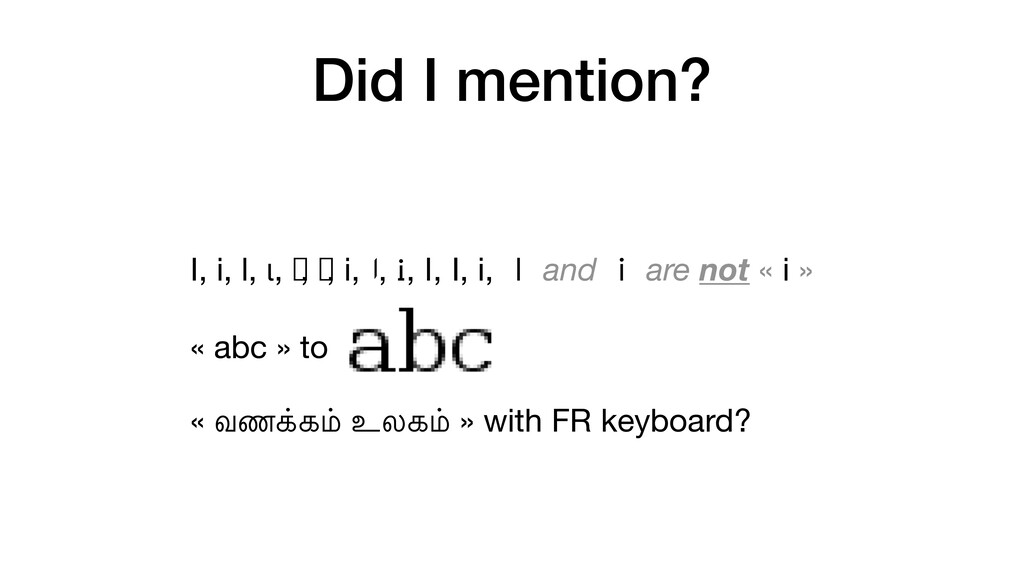
  41. I, i, l, ɩ, Ι, І, і, ا, Ꭵ, ᛁ,

    Ⅰ, ⅰ, I and i are not « i » « abc » to « வண க் க ம் உலக ம் » with FR keyboard? Did I mention?
  42. I, i, l, ɩ, Ι, І, і, ا, Ꭵ, ᛁ,

    Ⅰ, ⅰ, I and i are not « i » « abc » to « வண க் க ம் உலக ம் » with FR keyboard? Did I mention?
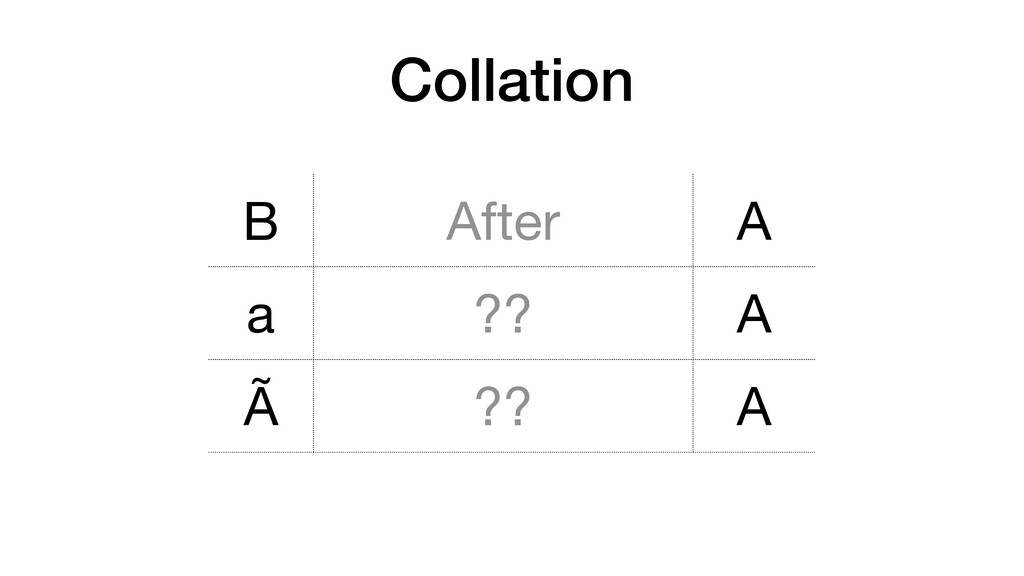
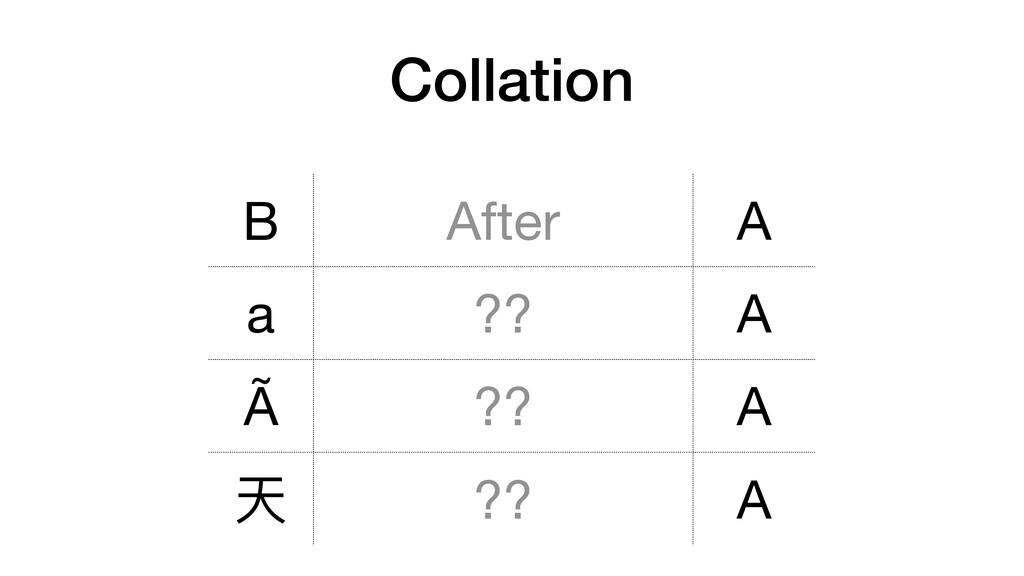
  43. Links you might fi nd interesting: - Locale can ruin

    you build https://stackover fl ow.com/questions/53987359/gradle-couldnt-connect-to-kotlin-daemon-on-windows - About case https://www.b-list.org/weblog/2018/nov/26/case/ - https://nedbatchelder.com/text/unipain.html - https://nedbatchelder.com/blog/201604/latos_unfortunate_ligatures.html - Collation: https://twitter.com/GPoPesie/status/1254358841292214274 L'oeuf et la poule, façon Unicode. - Systèmes d'écriture : https://twitter.com/_Eikyo/status/1260964982453403650 - Known Anomalies in Unicode Character Names : http://unicode.org/notes/tn27/ - A Python's guide to Unicode: https://youtu.be/olhKTHFYNxA - Morse code! - Python unicodedata module - digits and regex - confusable_homoglyphs - Not everything is UTF-8: https://octobus.net/blog/2020-06-05-not-everything-is-utf8.html - UniView: Lookup and see characters, https://r12a.github.io/applist - 3 stages of path and Unicode https://twitter.com/jperras/status/1276585192367493120 - UTF-8 history (Rob Pike to Ken Thompson): http://doc.cat-v.org/bell_labs/utf-8_history - Unicode in 5 minutes, 2013, https://richardjharris.github.io/unicode-in- fi ve-minutes.html - What does Unicode support mean? https://boyter.org/posts/unicode-support-what-does-that-actually-mean/ - Last Resort Font https://github.com/unicode-org/last-resort-font/ - French citation https://twitter.com/lesjoiesducode/status/1317906591321104384 - Very fast UTF-8 Unicode validation https://lemire.me/blog/2020/10/20/ridiculously-fast-unicode-utf-8-validation/ - About Text layout https://raphlinus.github.io/text/2020/10/26/text-layout.html and more speci fi cally japanese text layout https://www.w3.org/TR/jlreq/ - About Unicode and strings in Python and various languages https://tenthousandmeters.com/blog/python-behind-the-scenes-9-how-python-strings-work/ - https://www.freecodecamp.org/news/everything-you-need-to-know-about-encoding/ - About Emoji and codepoint combinations https://tonsky.me/blog/emoji/ "Please be aware": grapheme length, proper lib to extract, measure, reverse. - About string length: https://hsivonen. fi /string-length/, that may depend on the system! - Playing with (bug) emojis https://andysalerno.com/posts/weird-emojis/# - Unicode 14 beta https://home.unicode.org/unicode-14-0-beta-review/ - Subscript and superscript, class by class https://en.wikipedia.org/wiki/Unicode_subscripts_and_superscripts - Sorting in browsers and emojis https://devlog.hexops.com/2021/unicode-sorting-why-browsers-added-special-emoji-matching - Unicode data fi le compression https://devlog.hexops.com/2021/unicode-data- fi le-compression - Decoding Unicode at high speed https://nullprogram.com/blog/2017/10/06/ - Japanese typewriter https://blog.gatunka.com/2009/09/30/japanese-typewriters/ - Another (funny) Unicode operation https://twitter.com/farmostwood/status/1419700700901163013 - About input https://blog.gtk.org/2021/03/24/input-revisited/ and https://blog.gtk.org/2021/08/02/more-on-input/ - C++ with class https://twitter.com/shipilev/status/1424641425916968960 - Unicode and brands https://twitter.com/FakeUnicode/status/1425632884312793088 - underscore vs. overscore https://twitter.com/gvwilson/status/1429066291516747778 - Fix Mojibake https://github.com/rspeer/python-ftfy - Abusing diacritics https://lingojam.com/CursedText - About centering text in a terminal https://twitter.com/willmcgugan/status/1428435905518489608 - Life before Unicode https://baturin.org/blog/life-before-unicode/ - Failing ligatures https://twitter.com/xlerb/status/1435289762756108288 - Unicode 14 https://www.bortzmeyer.org/unicode-14-0.html