to the NYC Taxi & Limo commission - http://bit.ly/chris_wong • Data was put on Google Bigquery • Columnar datastore with a SQL (like) interface • Fast, easy to use and cheap :)
D U R AT I O N • features: month, day of the week, hour, working day, pickup location (lon, lat) • duration as the outcome • train a Random Forest model - R
S T ? • is a set of n decision trees • each decision tree is trained independently • a random subset of m features is selected at each candidate split • each tree can grow until the stop condition is reached or until maxnodes is reached • prediction phase: each tree cast a vote
T U F F • data is big, but not that big • 16 CPUs, 104 GB mem - Google Cloud Instance (RStudio Server) - AWS EC2 • Random Forest training is easy to parallelize (each decision tree is trained independently) • choose n, m to get good accuracy - (chose them empirically) • choose maxnodes to have manageable models in memory (~200 MB instead of 9 GB)
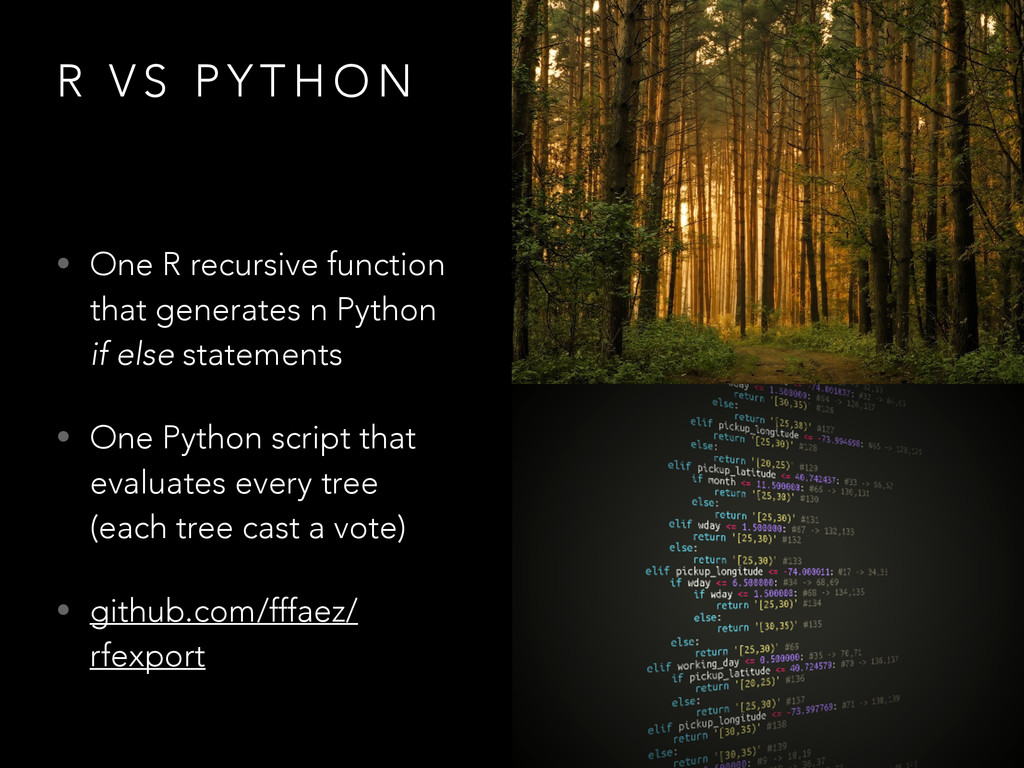
H E M O D E L • if you are using R, stay with R (shiny) • Predictive Model Markup Language (XML-based) • convert every tree in a huge if else statement (i.e. in Python) and write a prediction function
One R recursive function that generates n Python if else statements • One Python script that evaluates every tree (each tree cast a vote) • github.com/fffaez/ rfexport


 daidaidai
 takonda
 yahonda
 namiki64
 masakiokuda
 rfdnxbro
 sh_fk2
 usanchuu
 nttcom
 willnet
 grimoh
 ishikawa_satoru
 scottboms
 codingconduct
 axbom
 mkilby
 lauravandoore
 pwiseman
 frankvandijk
 samlambert
 kevinliebholz
 destraynor
 tammyeverts