Share
Embed
Apache Spark Declarative Pipelines (SDP) Conference Talk
OSS Apache SDP and Databricks Lakeflow on Free Edition
Frank Munz
April 30, 2026
Transcript
51 slides
-
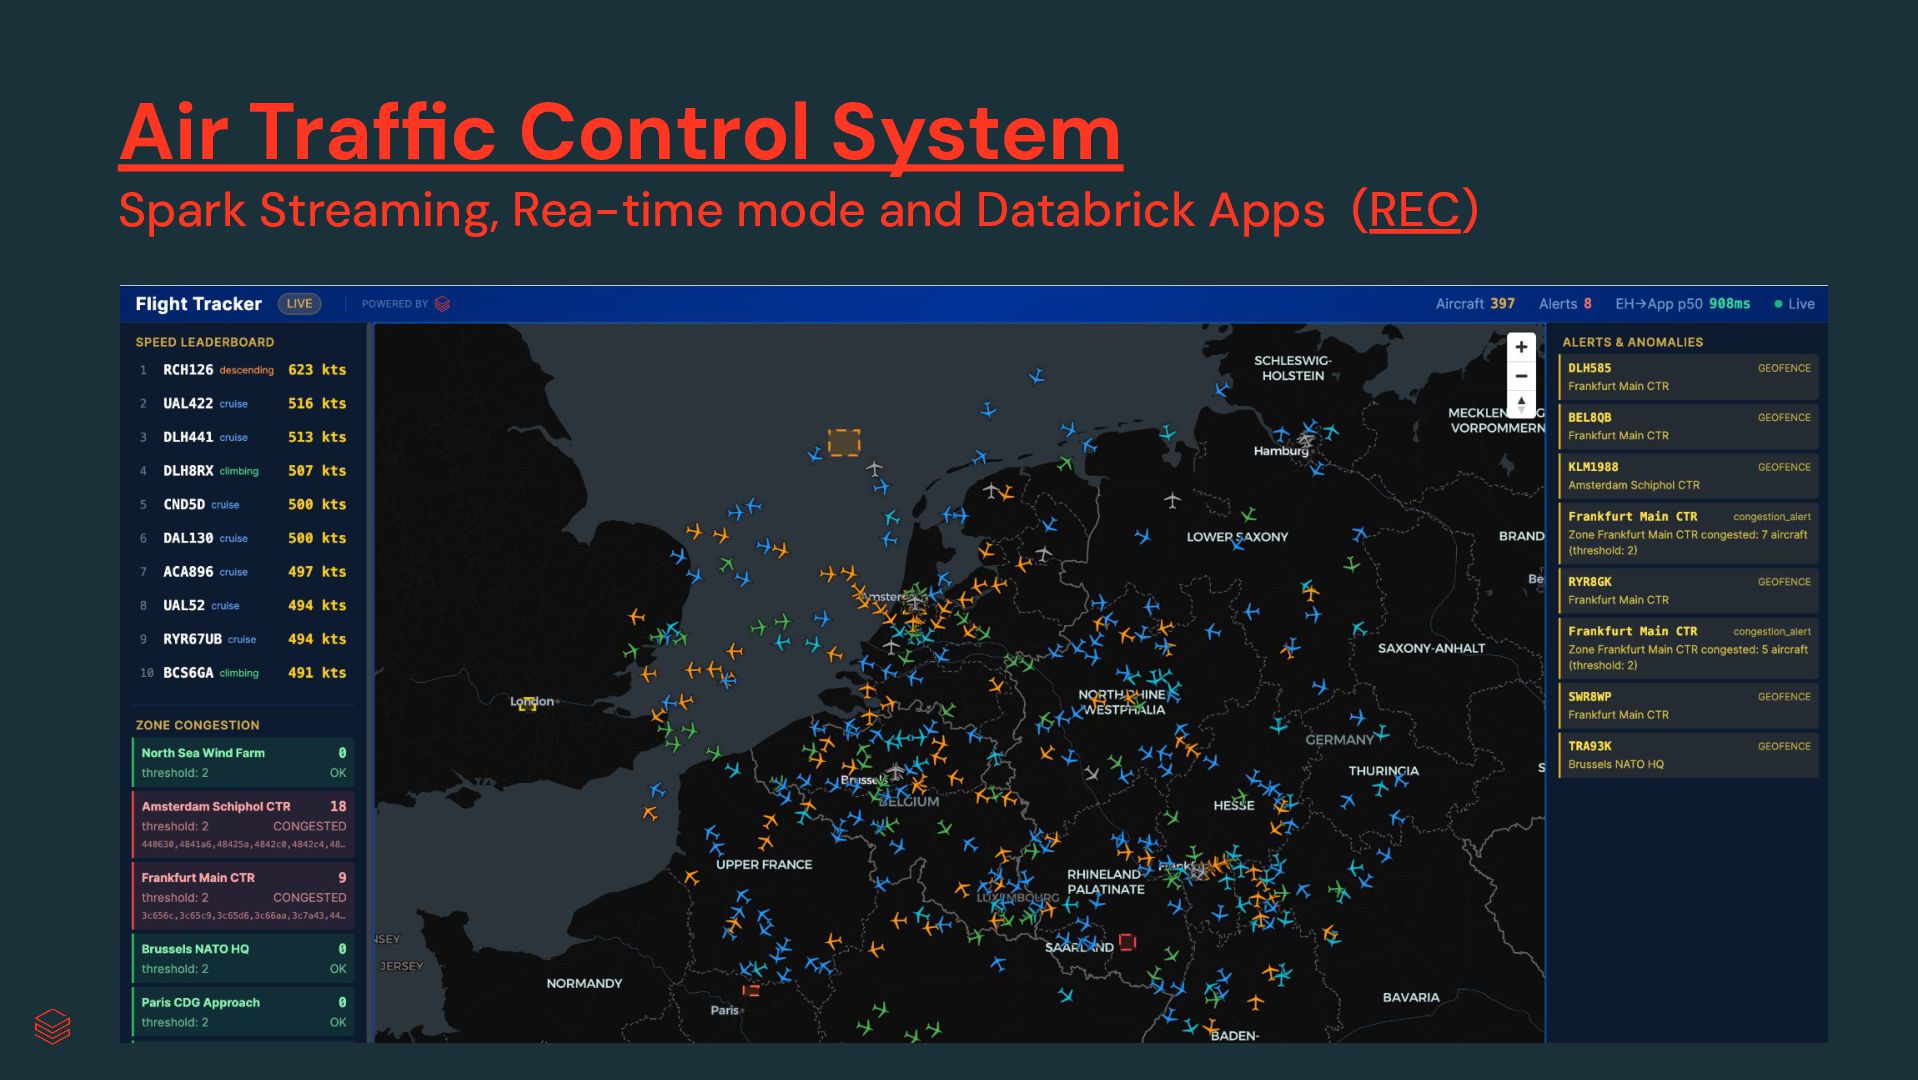
Apache Spark Declarative Pipelines (SDP) In Action Avionics Demo Frank
Munz, Databricks 2026 -
About me • I am Frank Munz • Principal TM
Engineer @ Databricks: Data and AI • My past: large scale data & compute • Based in • Built up AWS Tech Evangelism in Central Europe • SW architect, data scientist, published author etc. ⛰🥨🍻 -
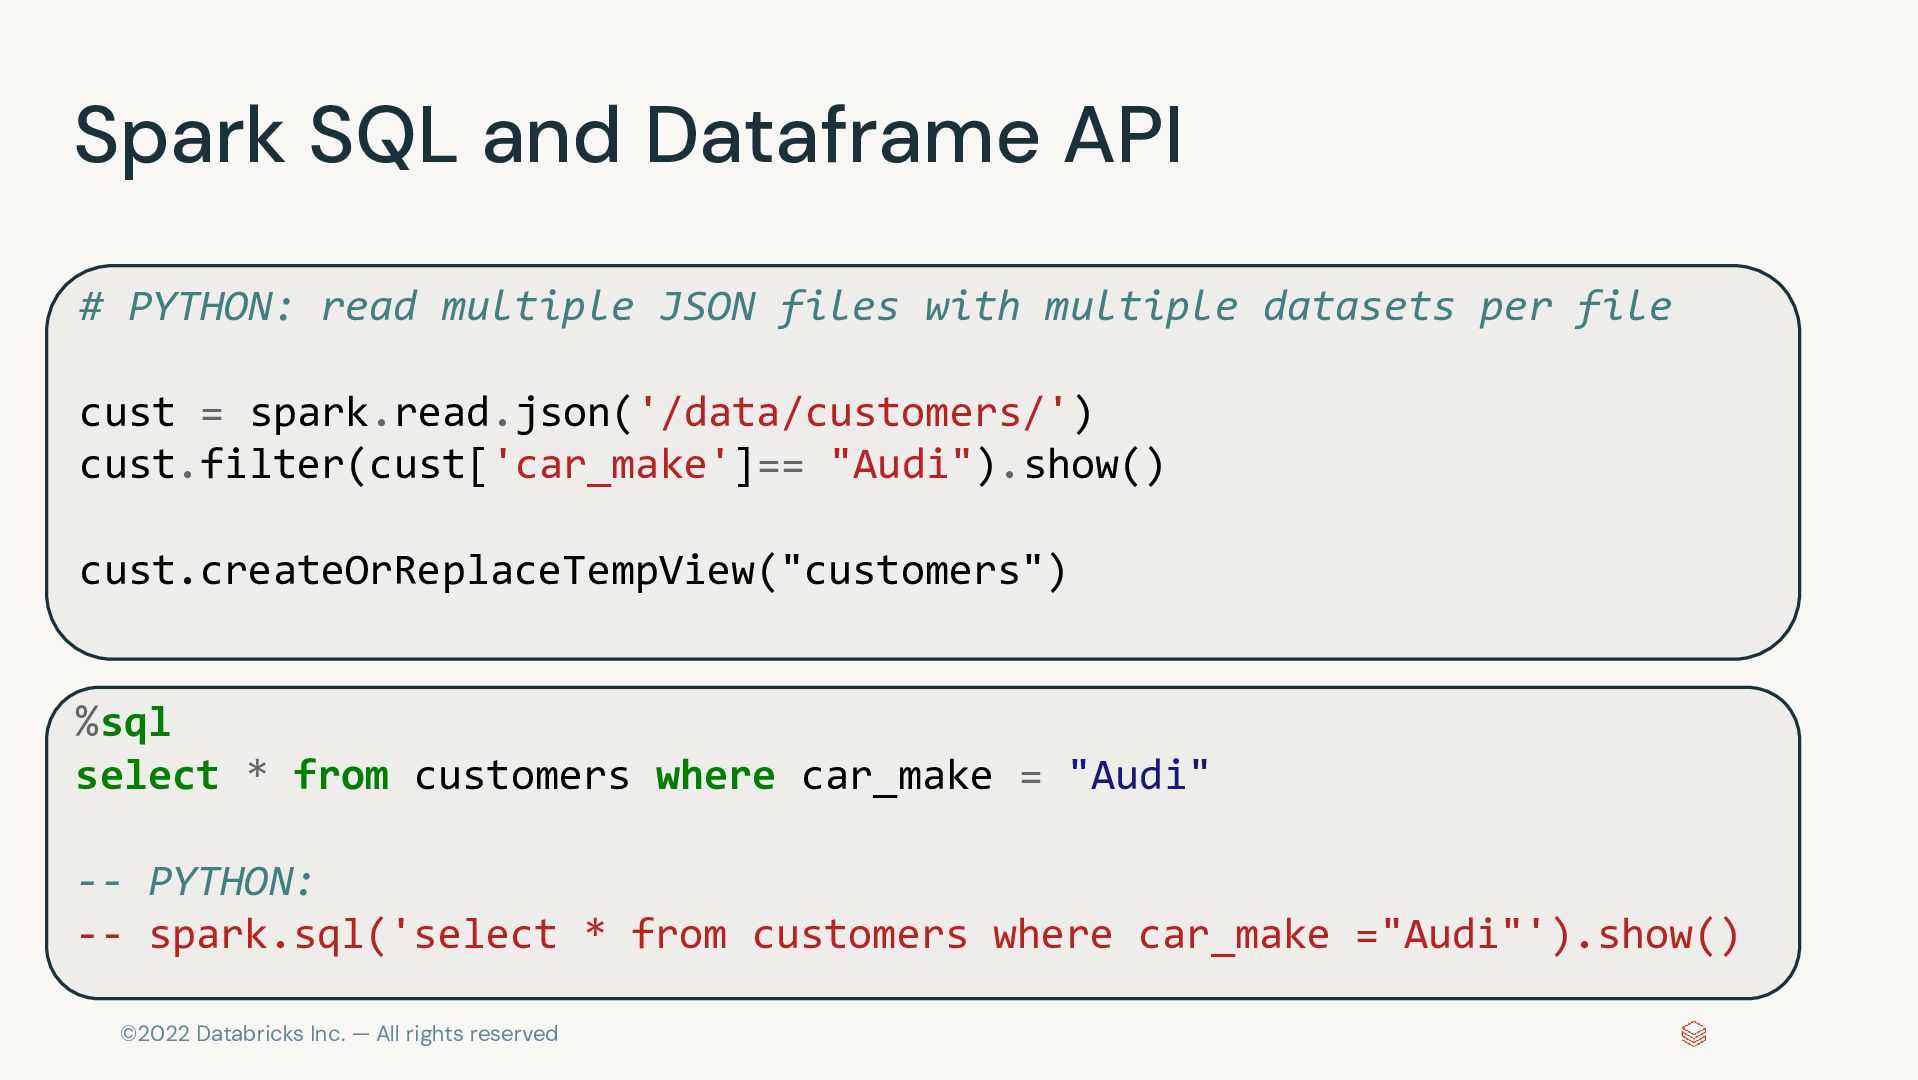
Spark SQL and Dataframe API # PYTHON: read multiple JSON
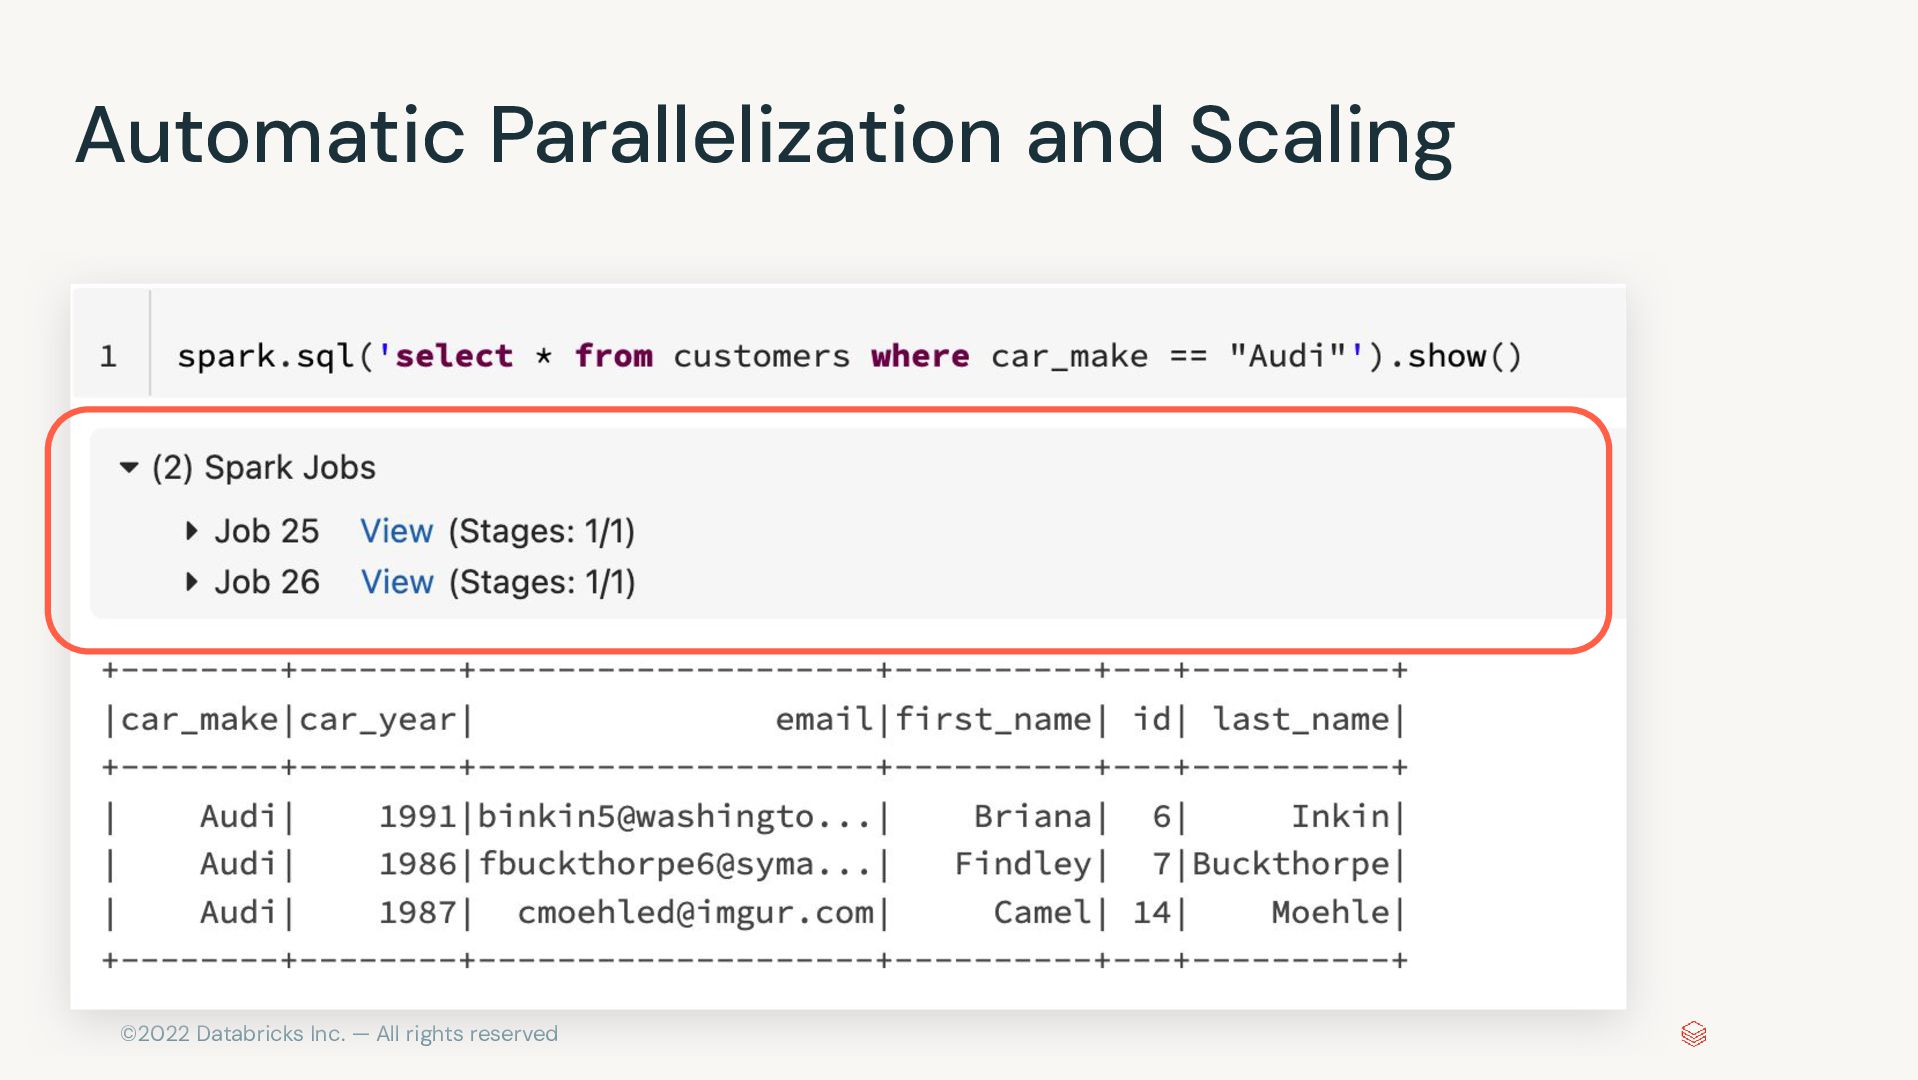
files with multiple datasets per file cust = spark.read.json('/data/customers/') cust.filter(cust['car_make']== "Audi").show() cust.createOrReplaceTempView("customers") %sql select * from customers where car_make = "Audi" -- PYTHON: -- spark.sql('select * from customers where car_make ="Audi"').show() ©2022 Databricks Inc. — All rights reserved -
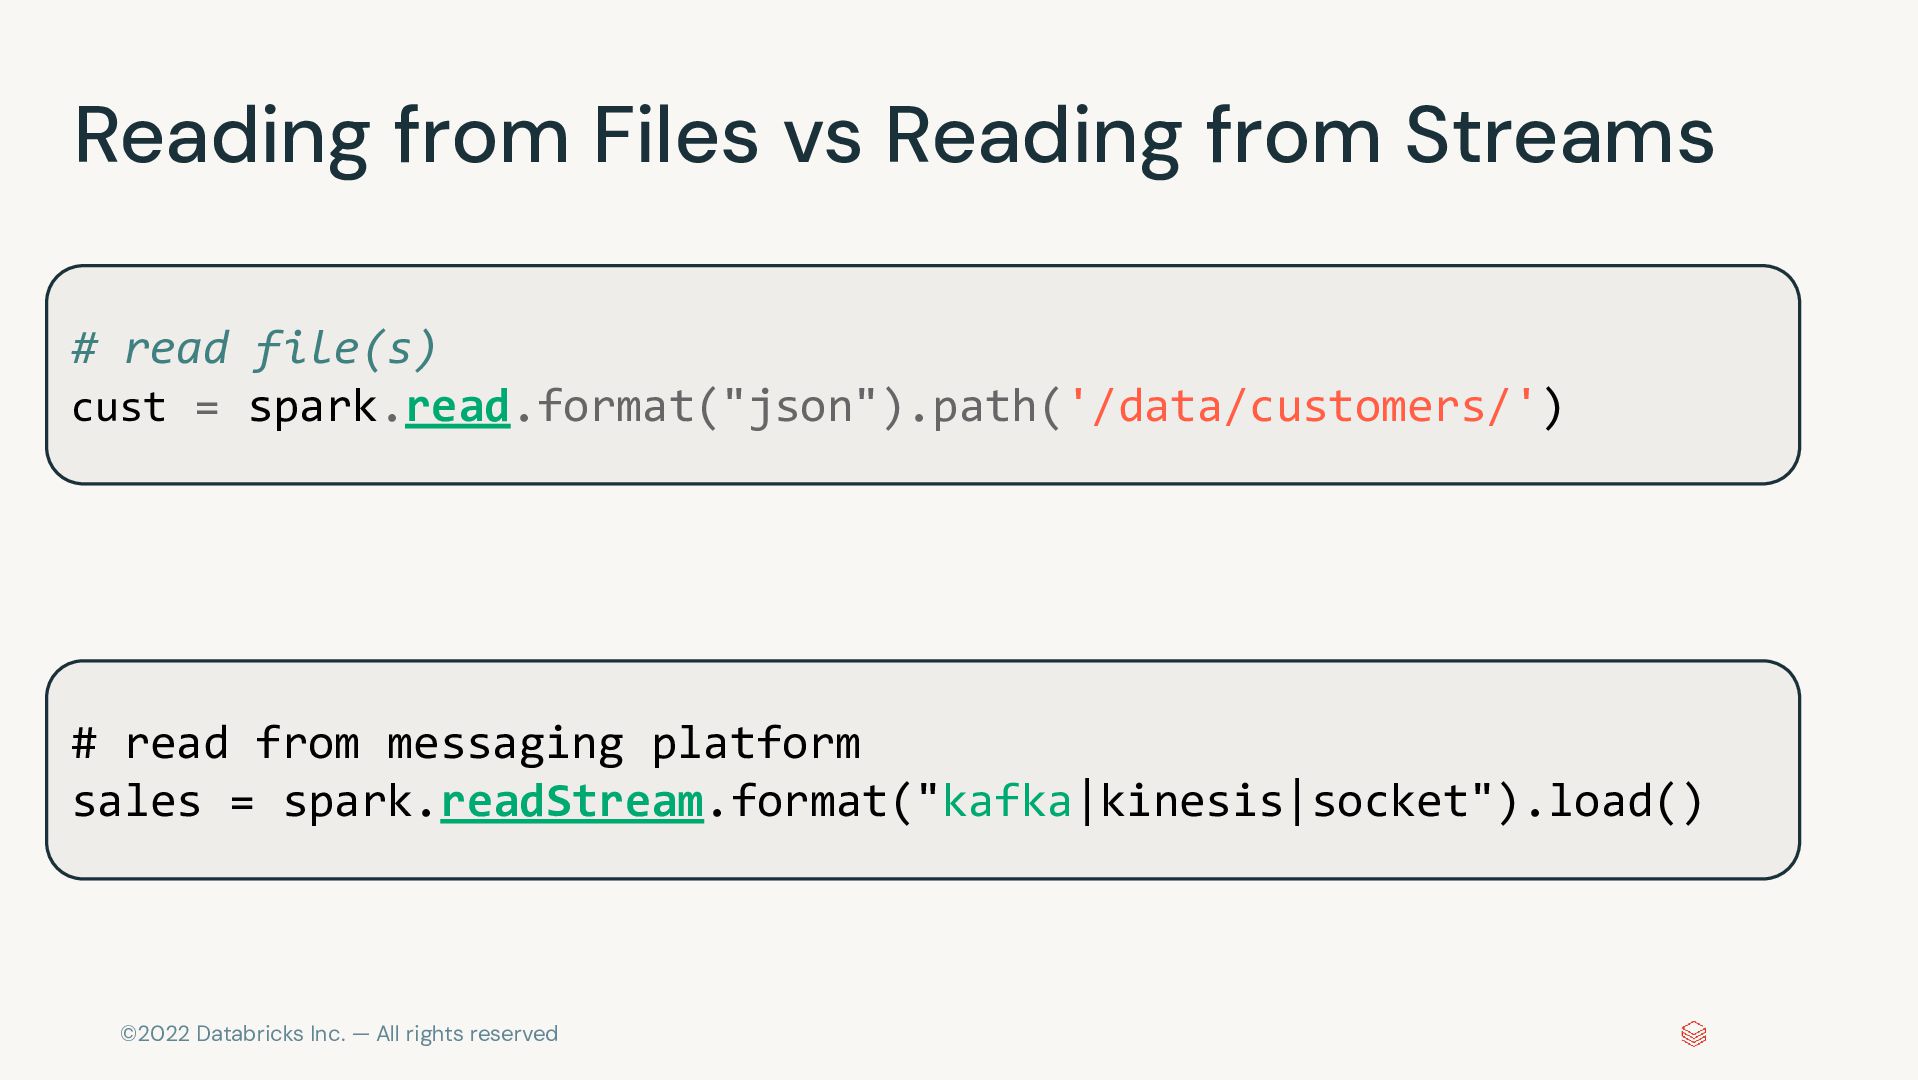
Reading from Files vs Reading from Streams # read file(s)
cust = spark.read.format("json").path('/data/customers/') # read from messaging platform sales = spark.readStream.format("kafka|kinesis|socket").load() ©2022 Databricks Inc. — All rights reserved -
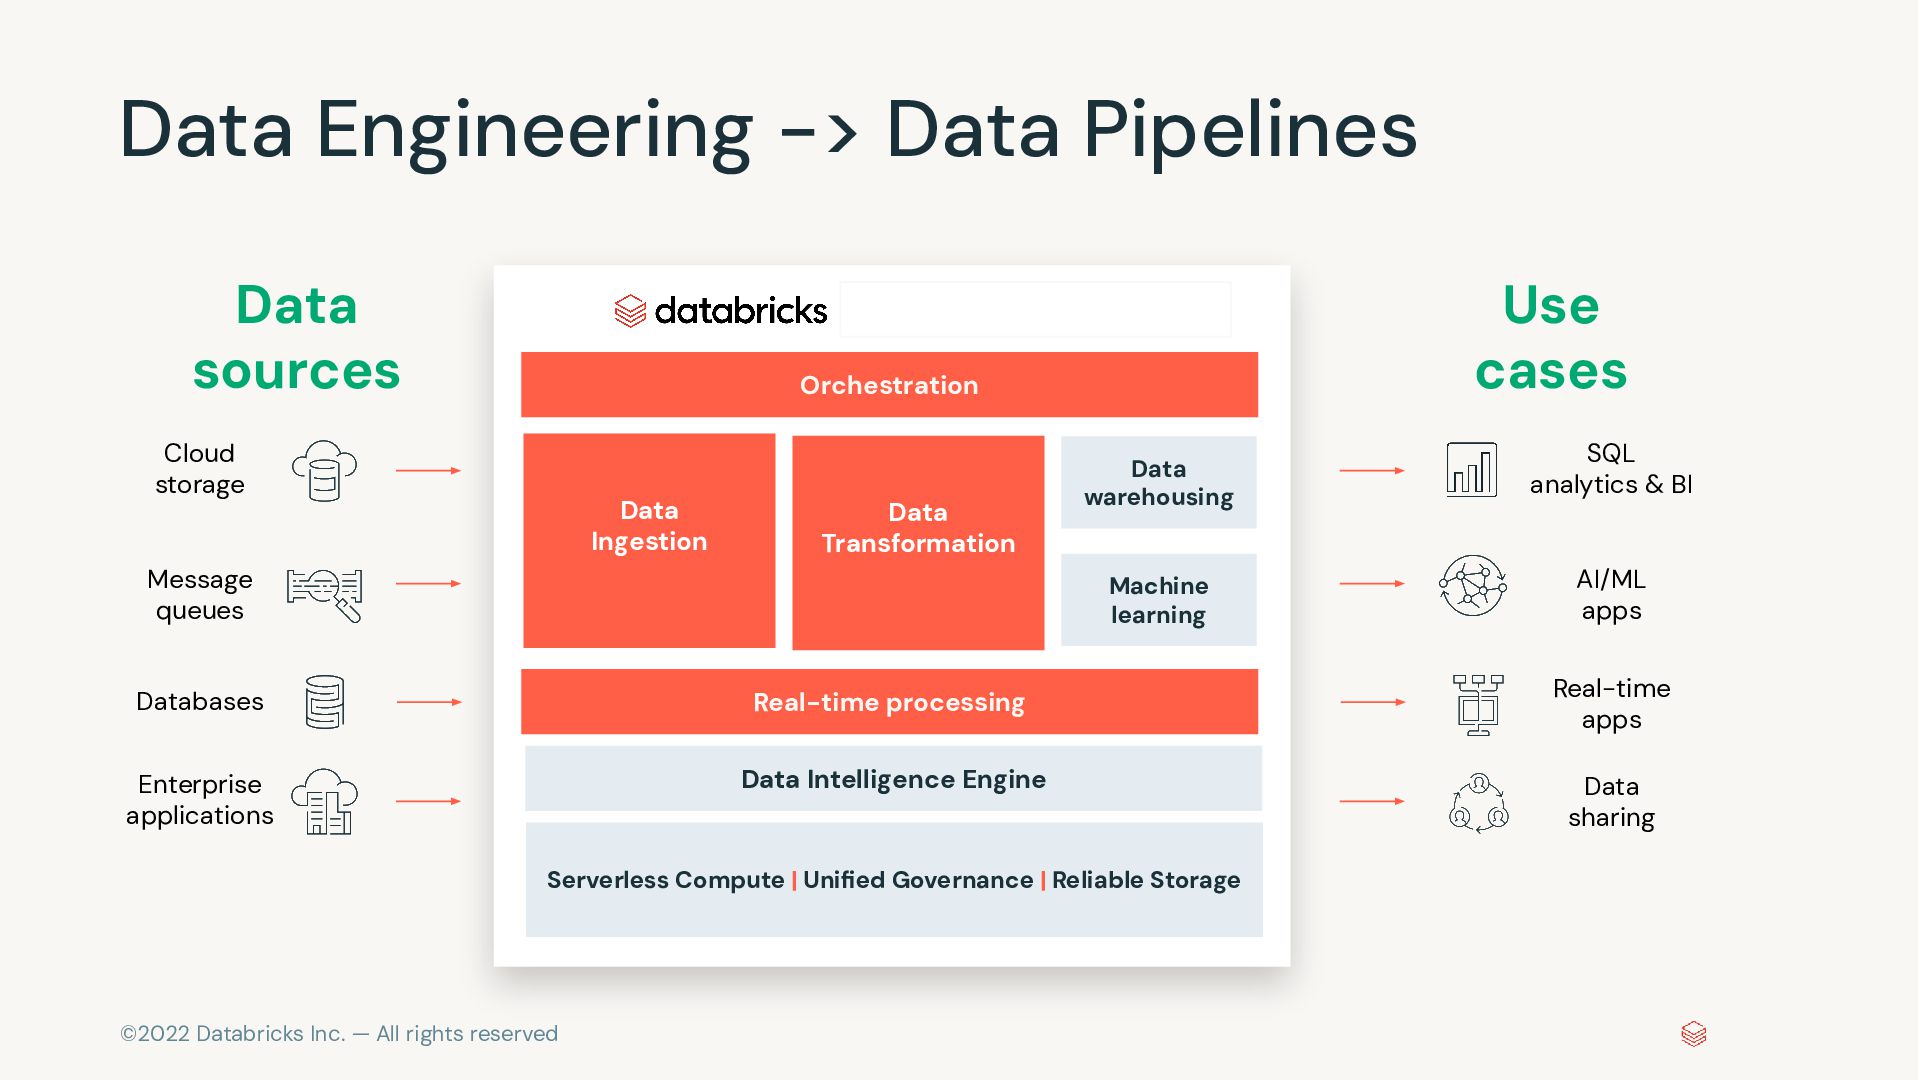
Data Engineering: The destination is simple. The journey is hard
Data Sources Data Consumers Message Queues Real-time Operations Enterprise Apps Databases Unstructured Data Cloud Storage Data Lake ??? Agents Apps Dashboards Analytics -
>>10y of Simplifying Apache Spark™ ©2022 Databricks Inc. — All
rights reserved 9 -
What is … a data pipeline ? ©2022 Databricks Inc.
— All rights reserved 12 -
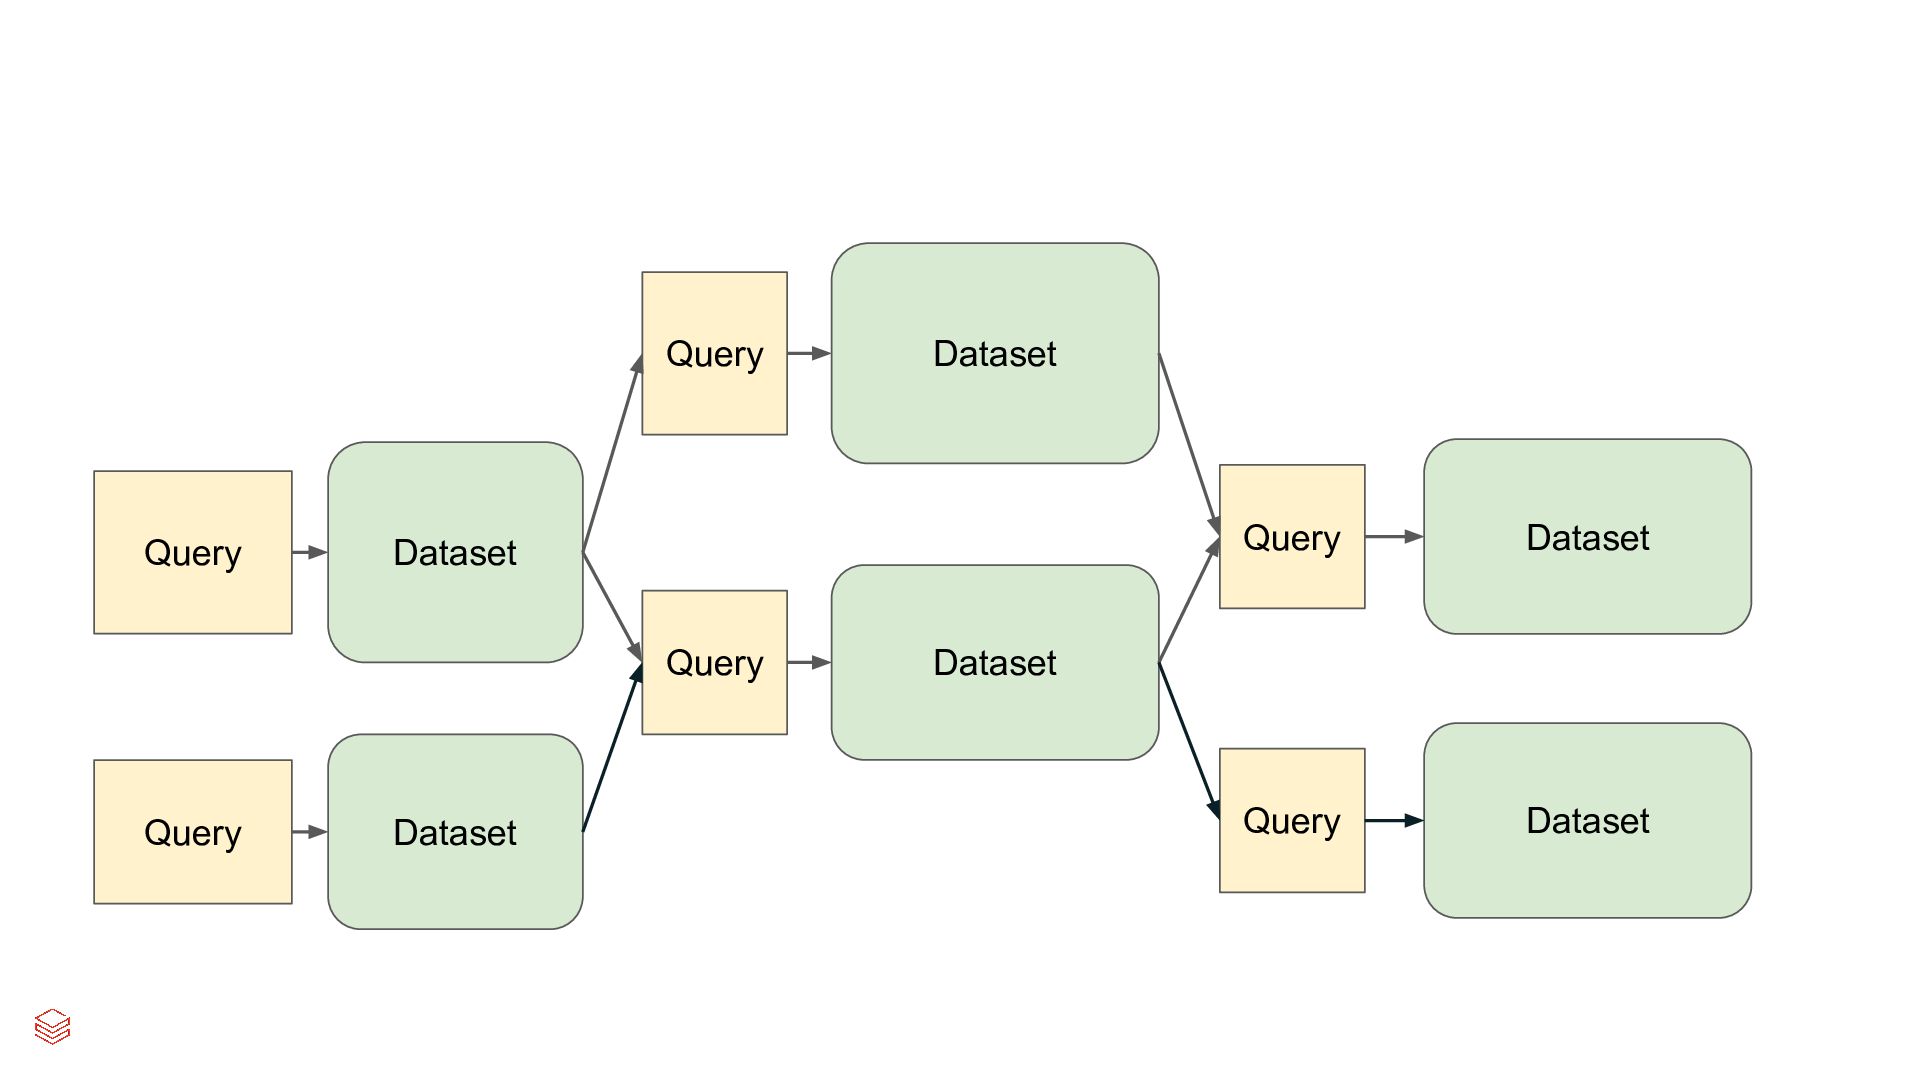
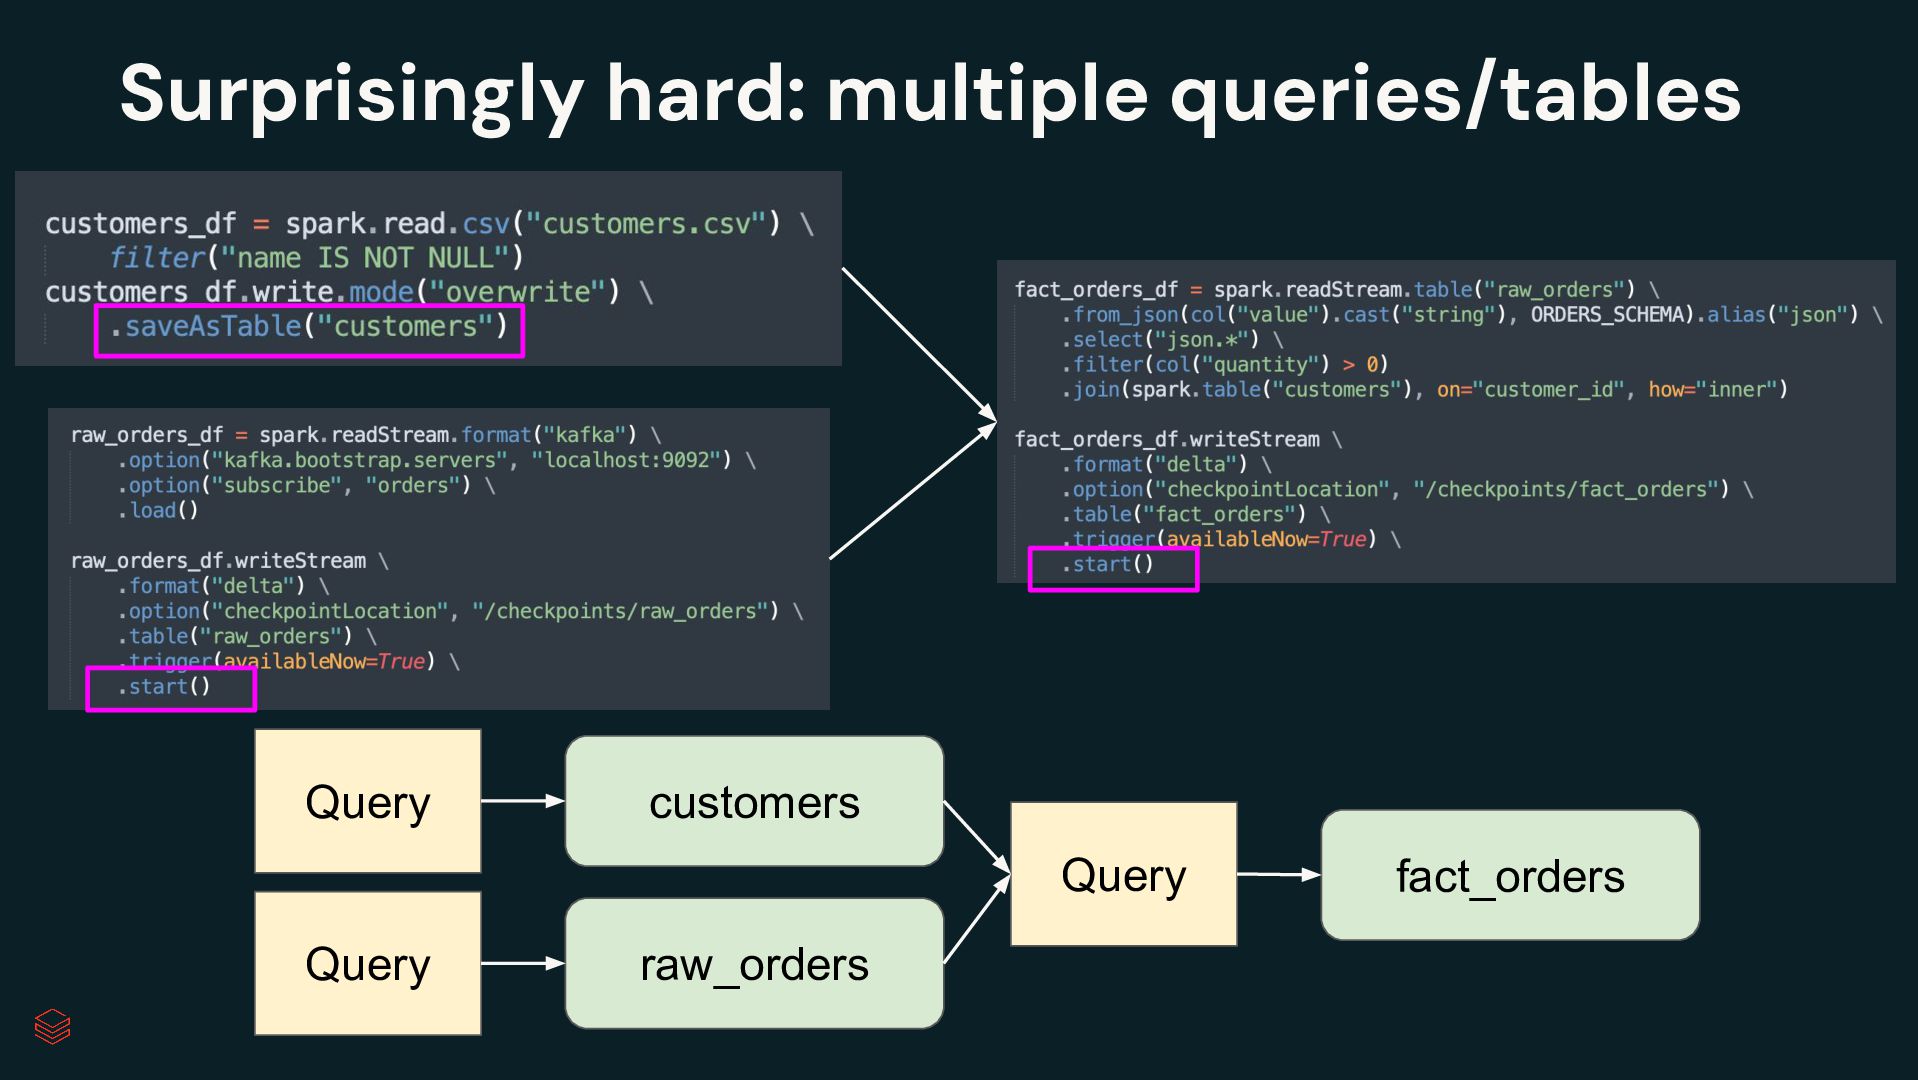
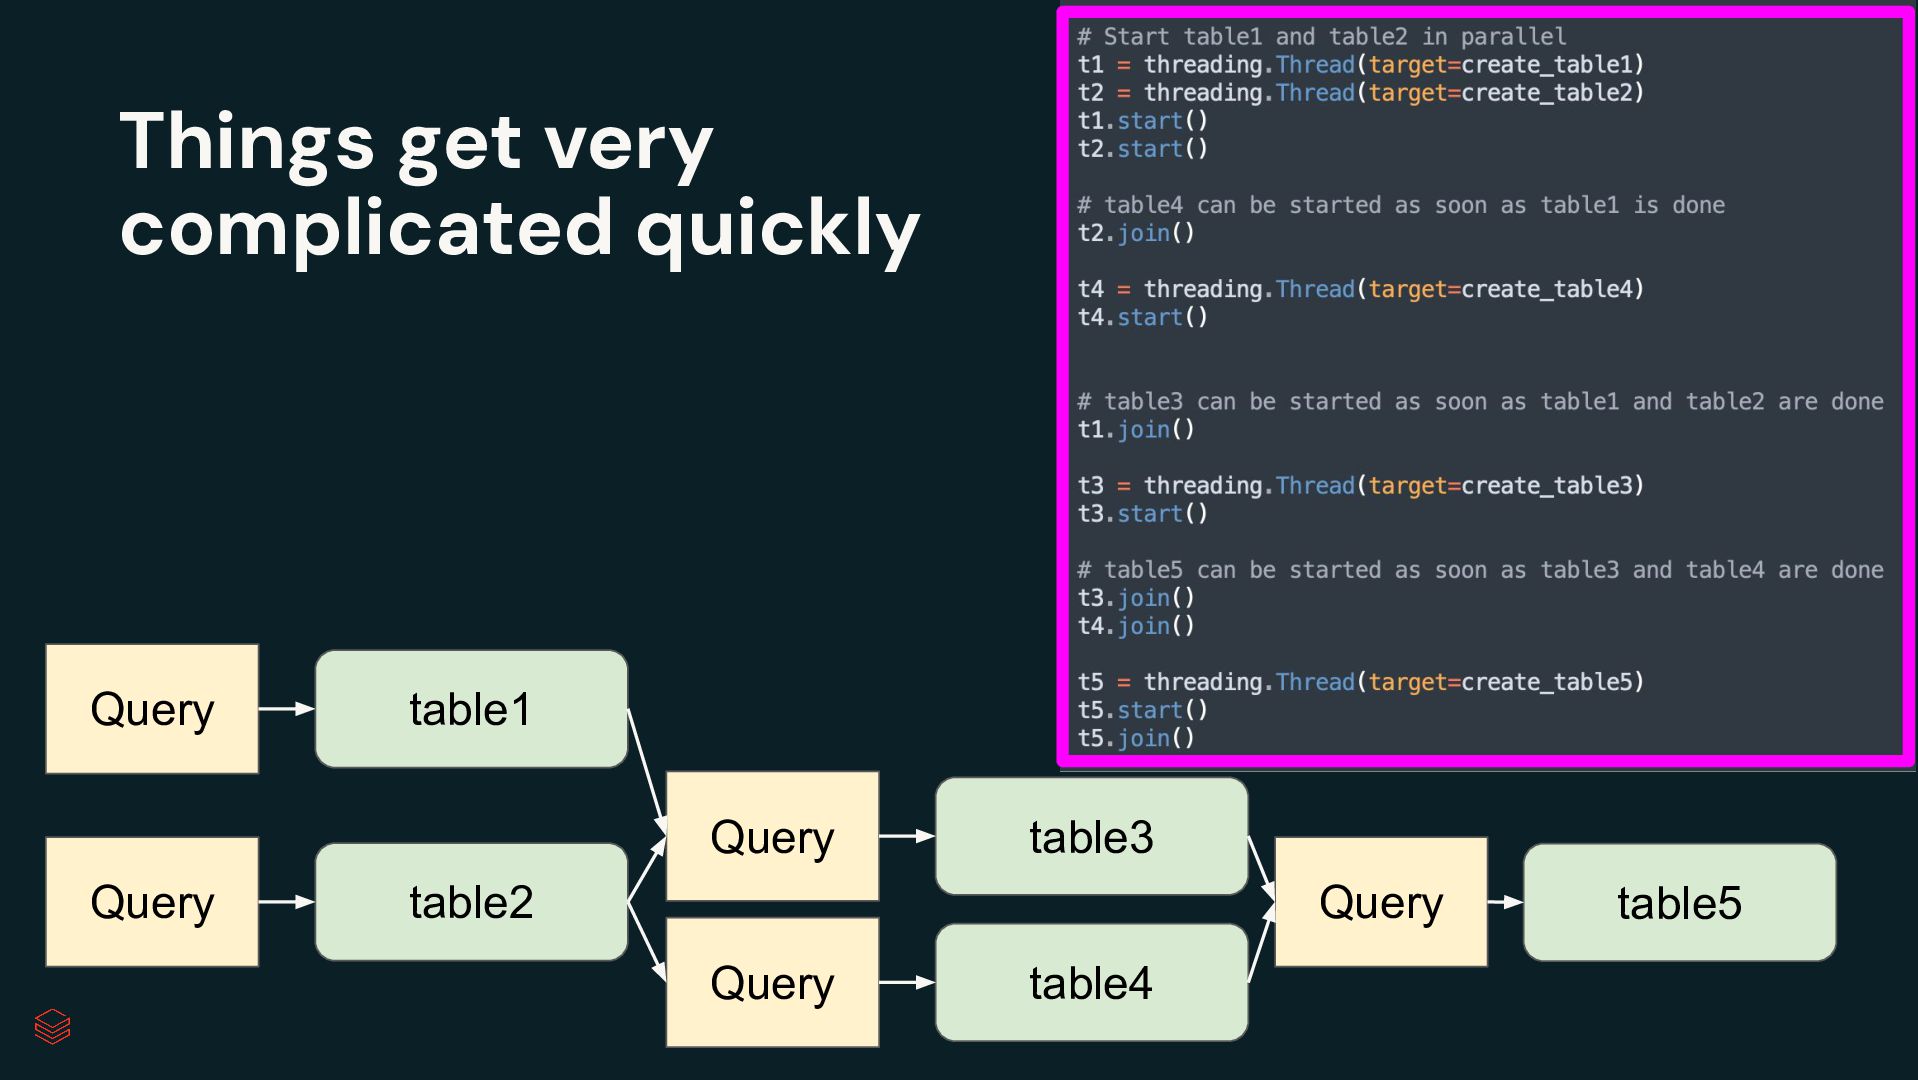
Things get very complicated quickly Query table1 Query Query table3
Query table2 Query table4 table5 -
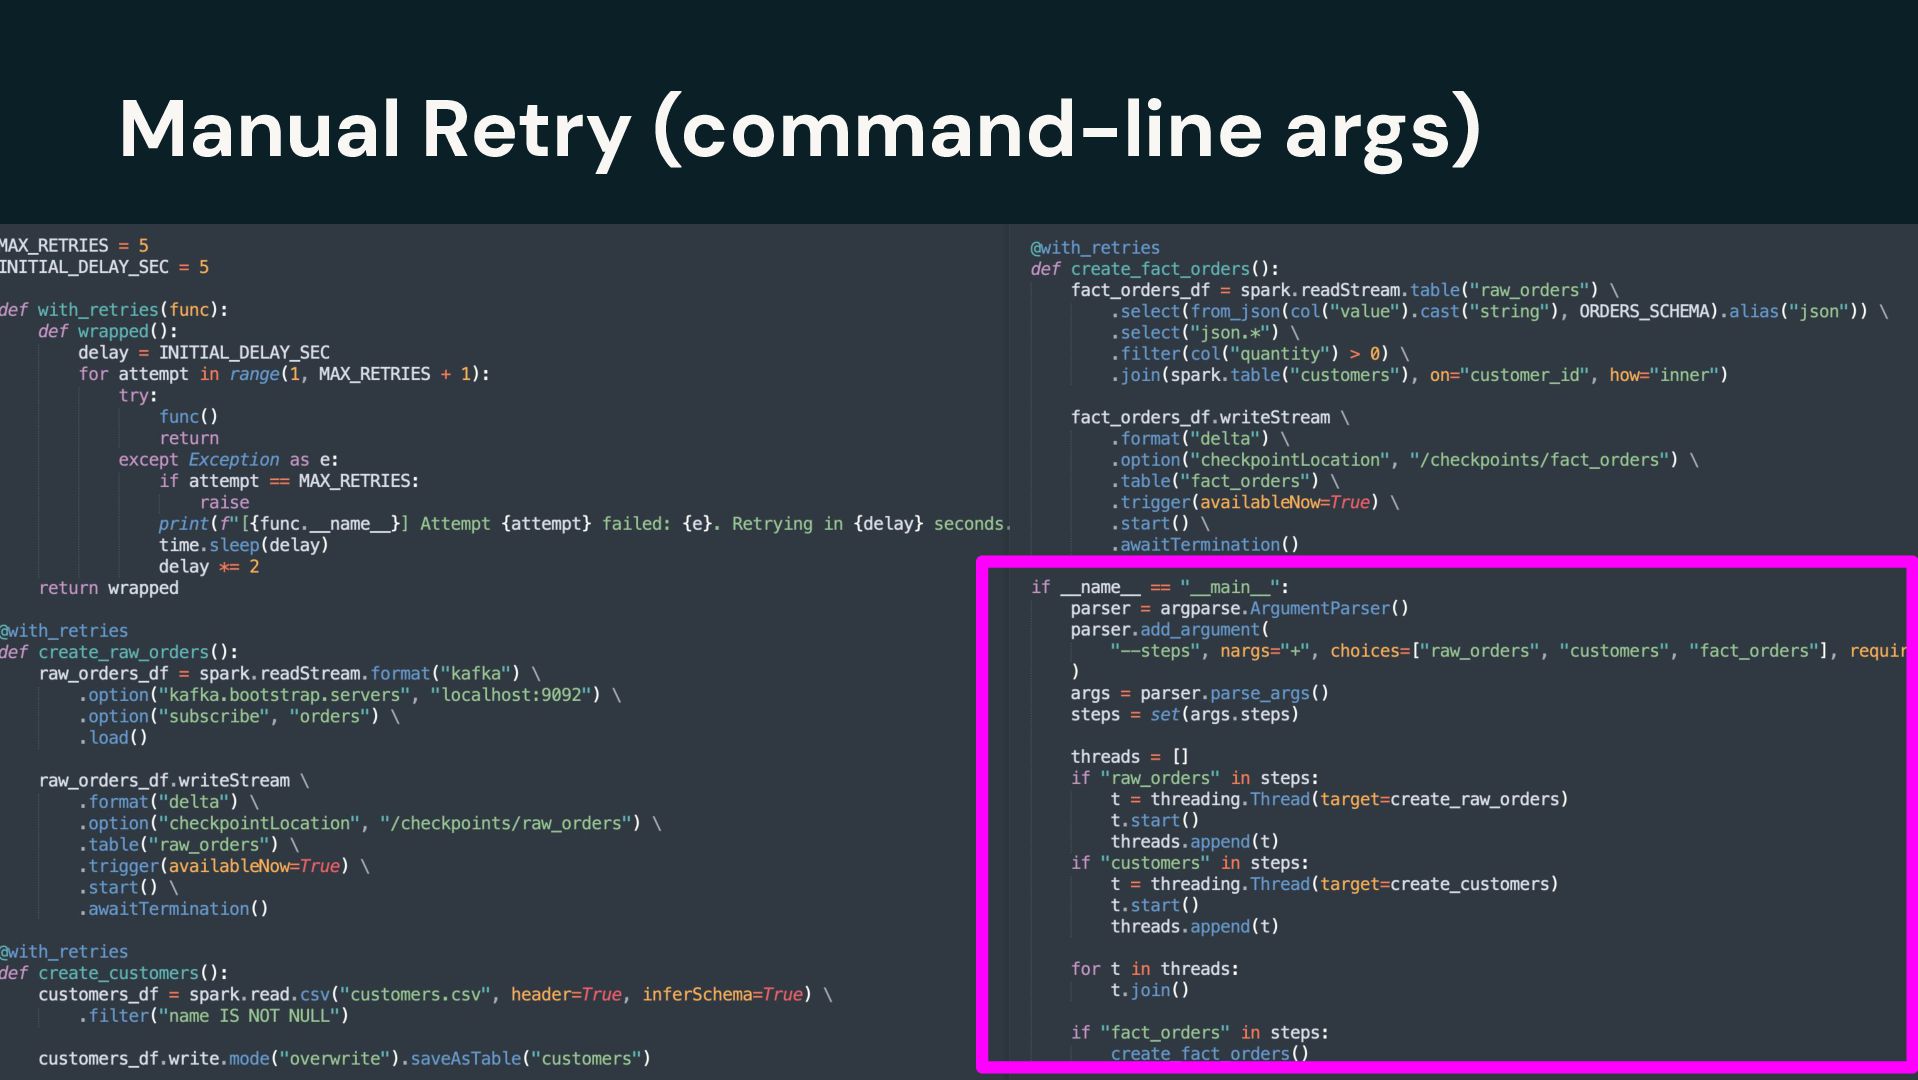
What if there is an error? ©2022 Databricks Inc. —
All rights reserved 21 -
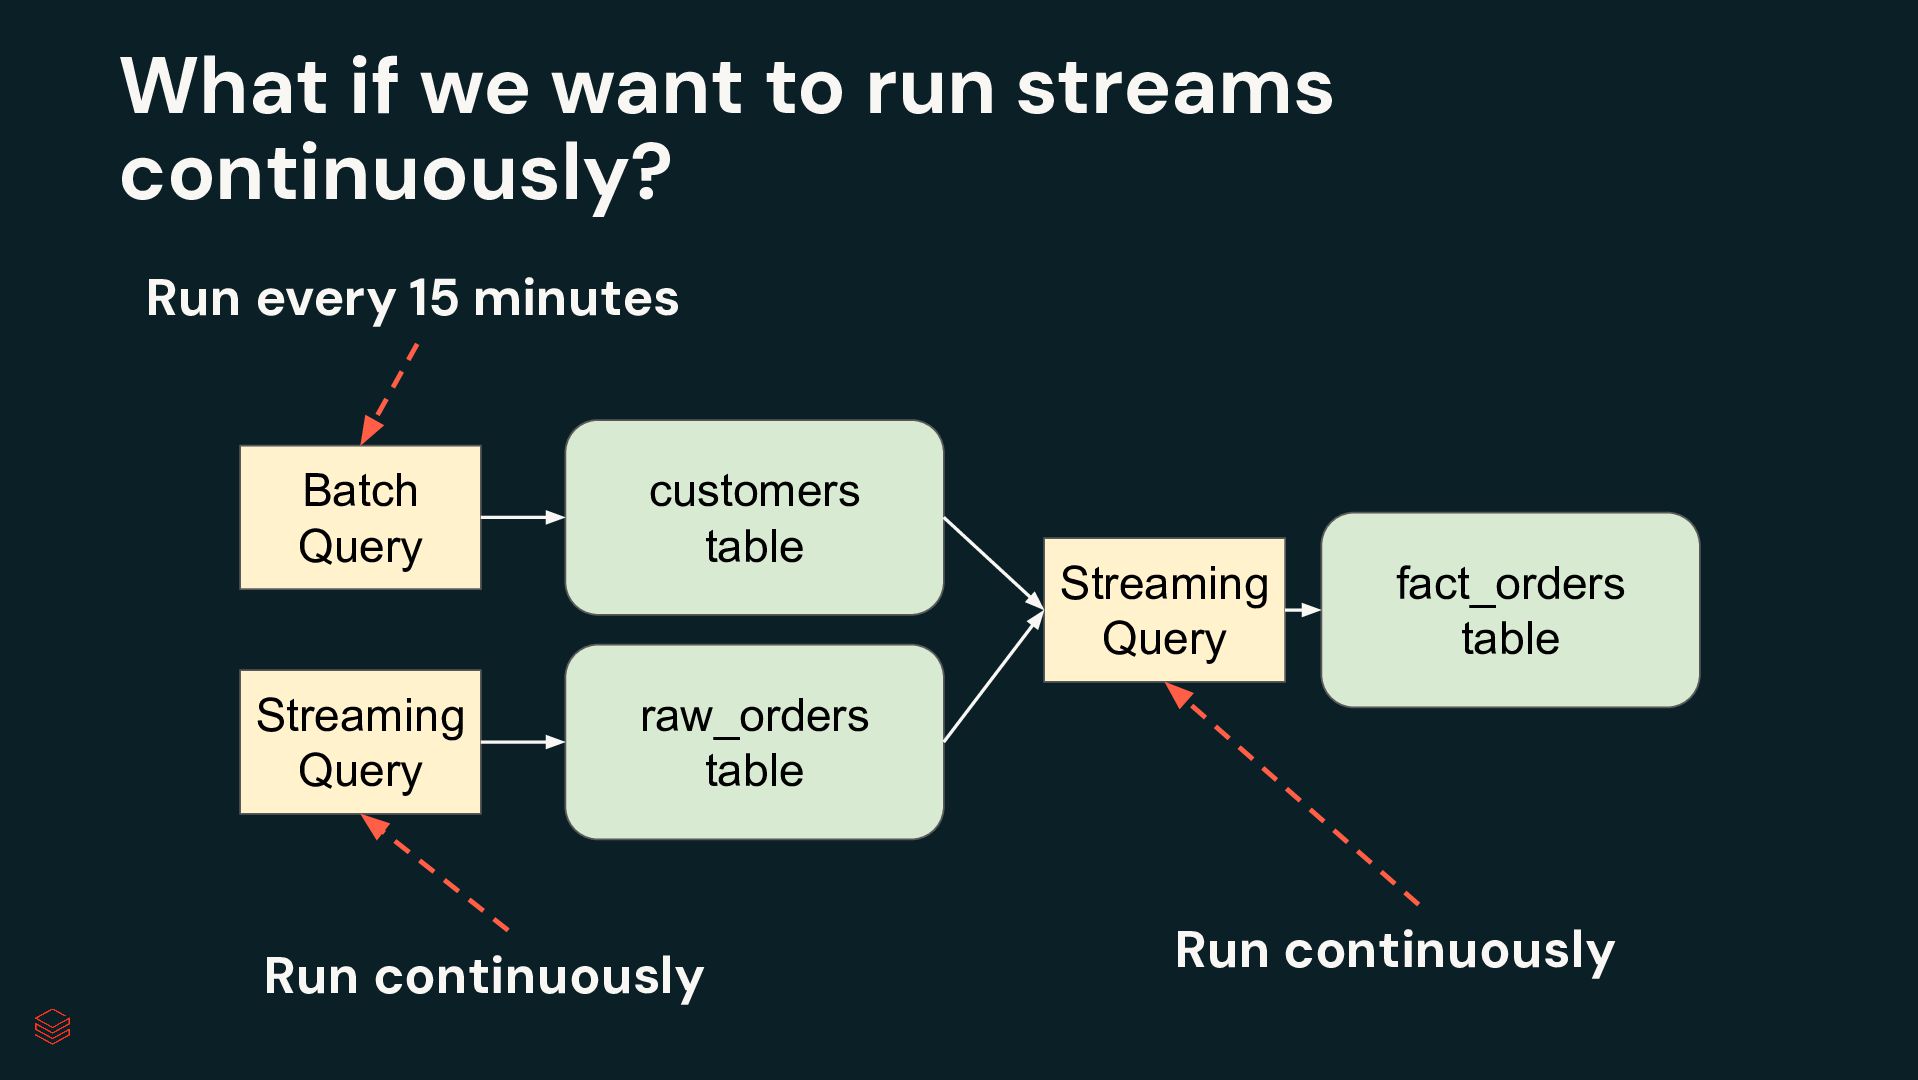
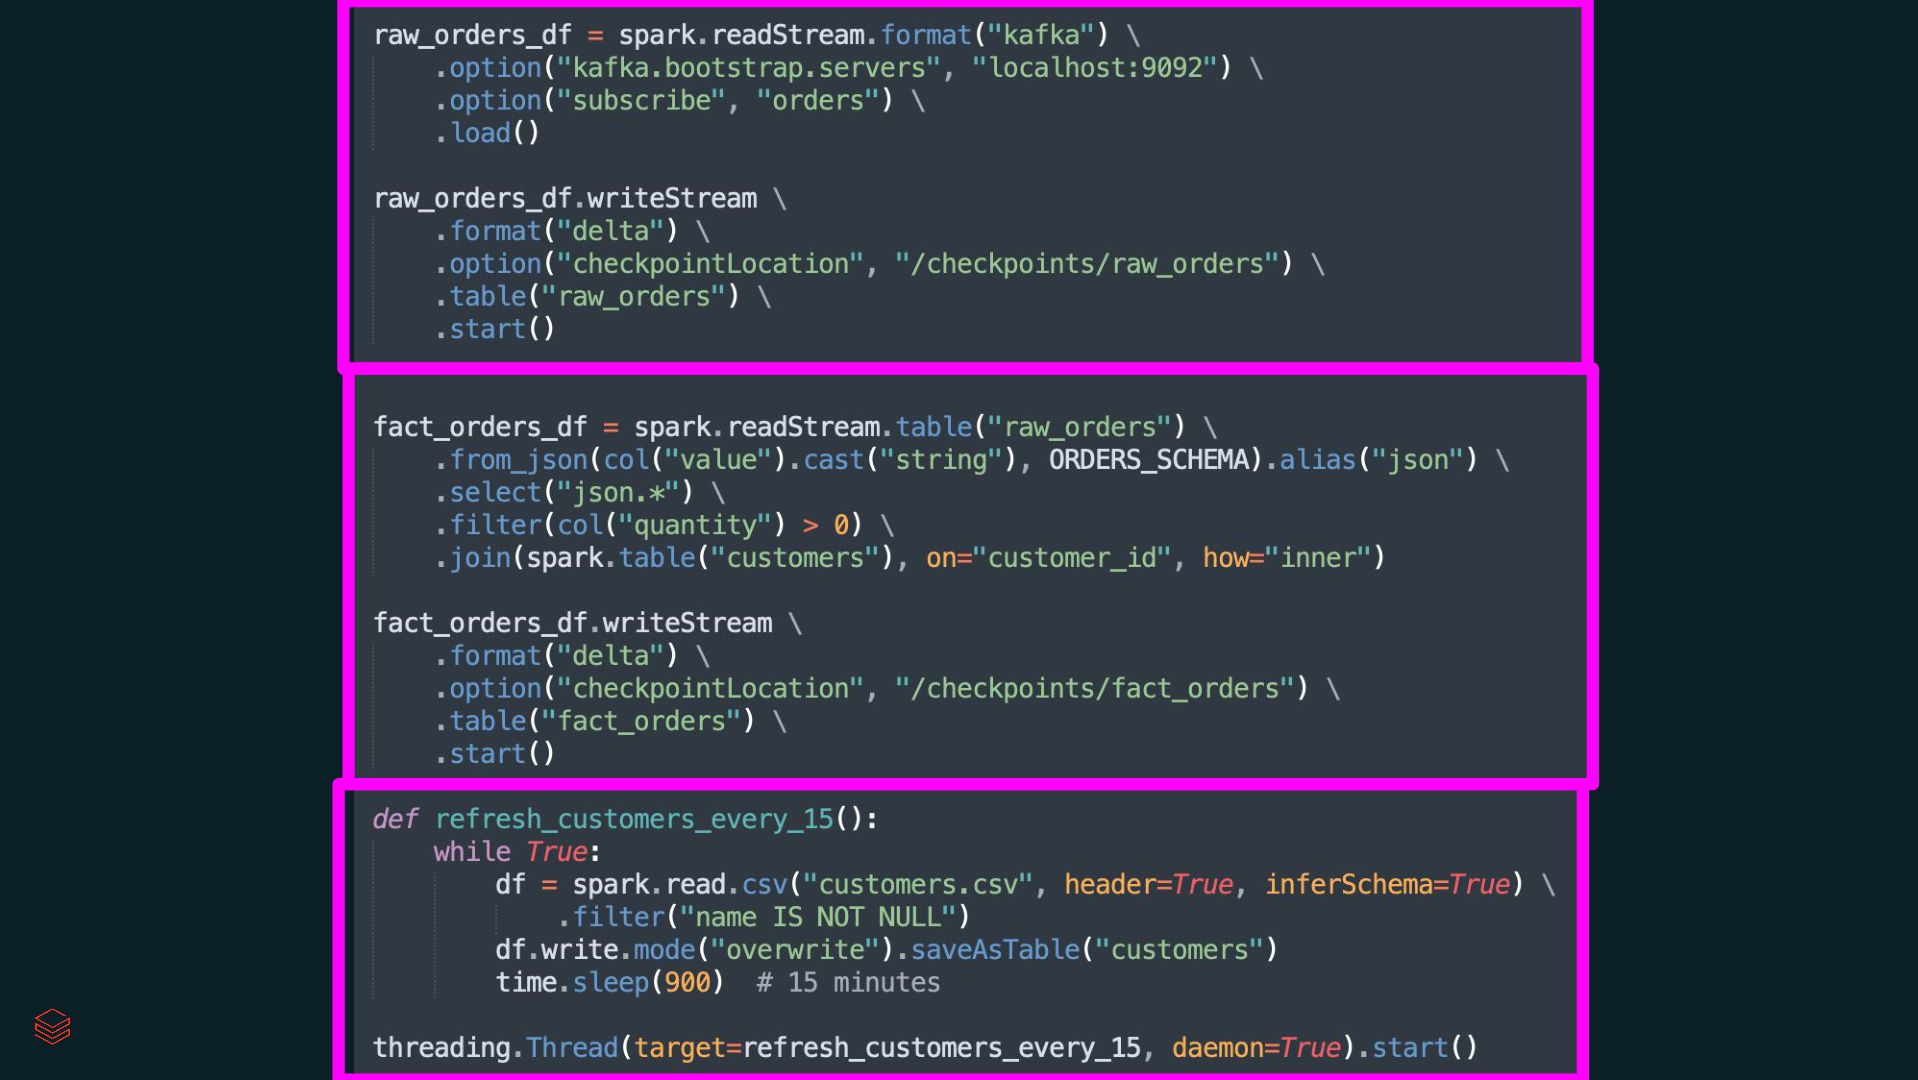
What if we want to run streams continuously? Run every
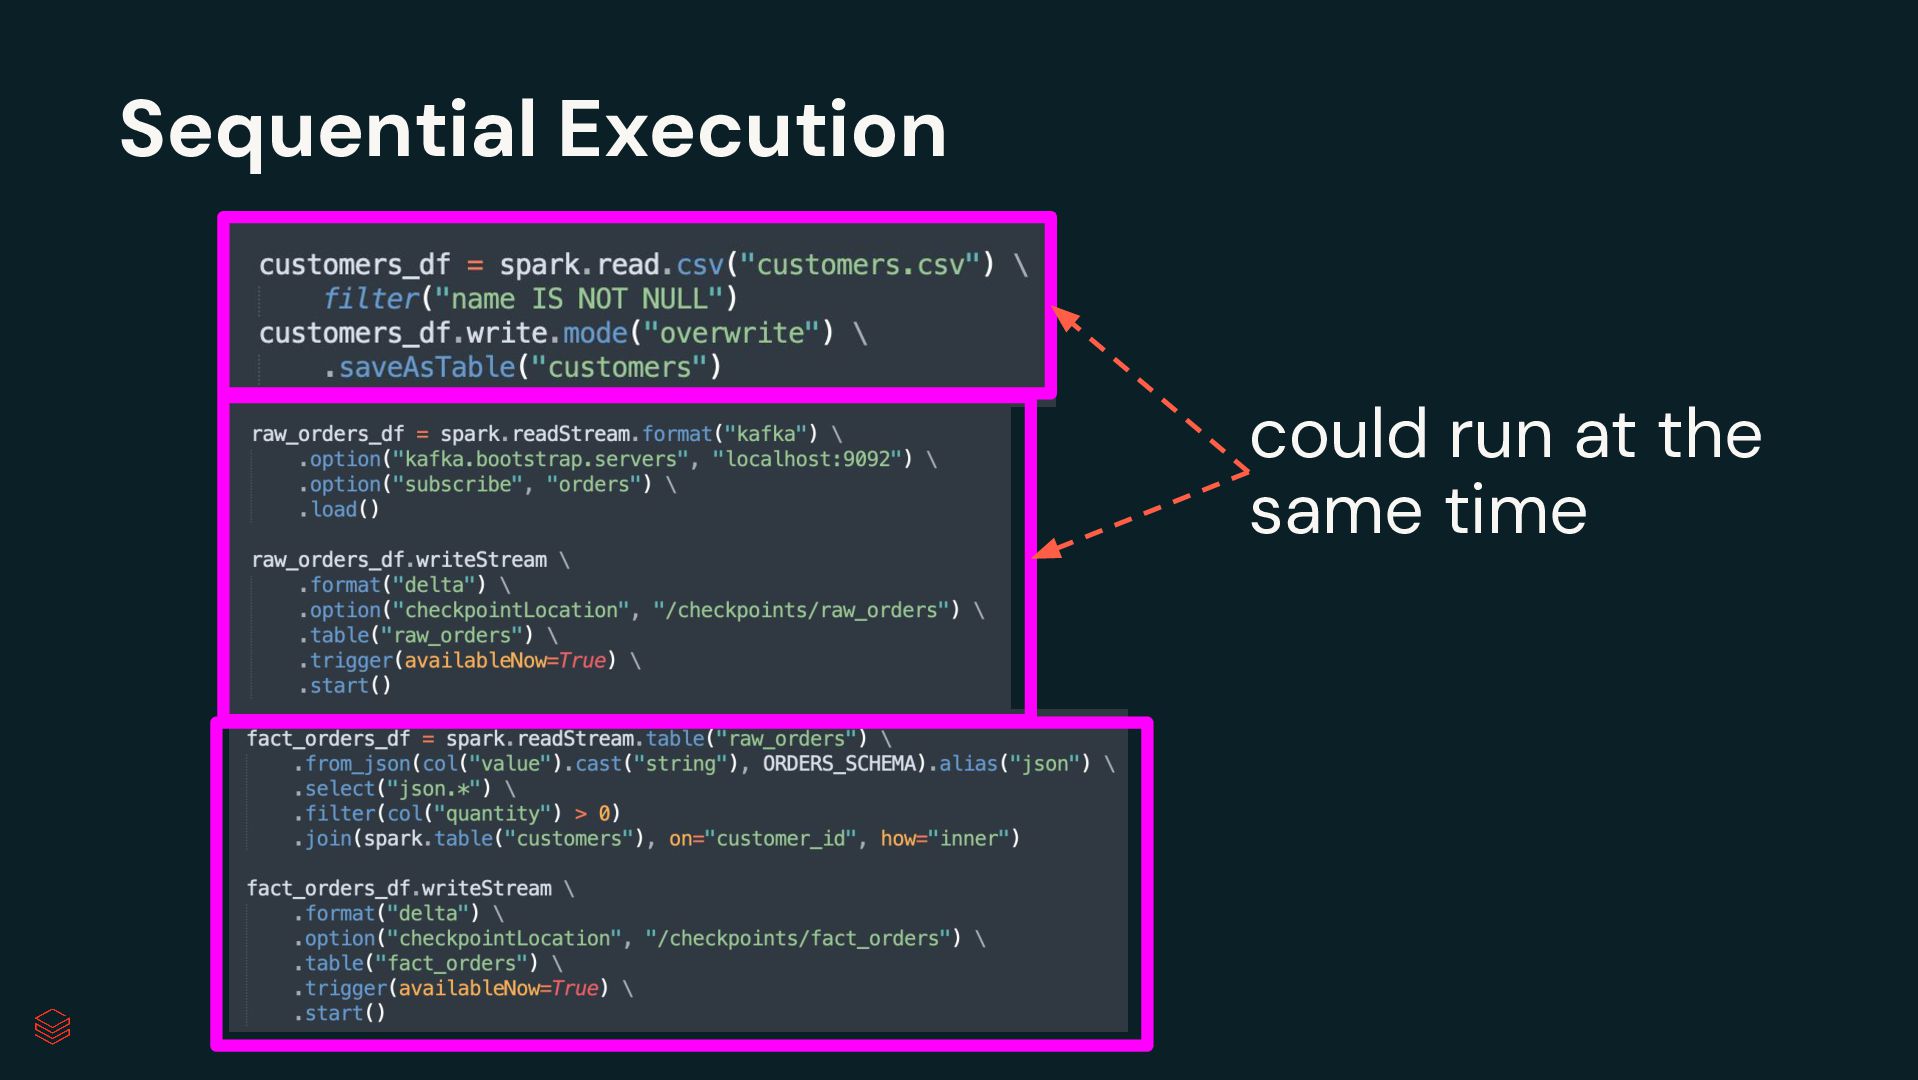
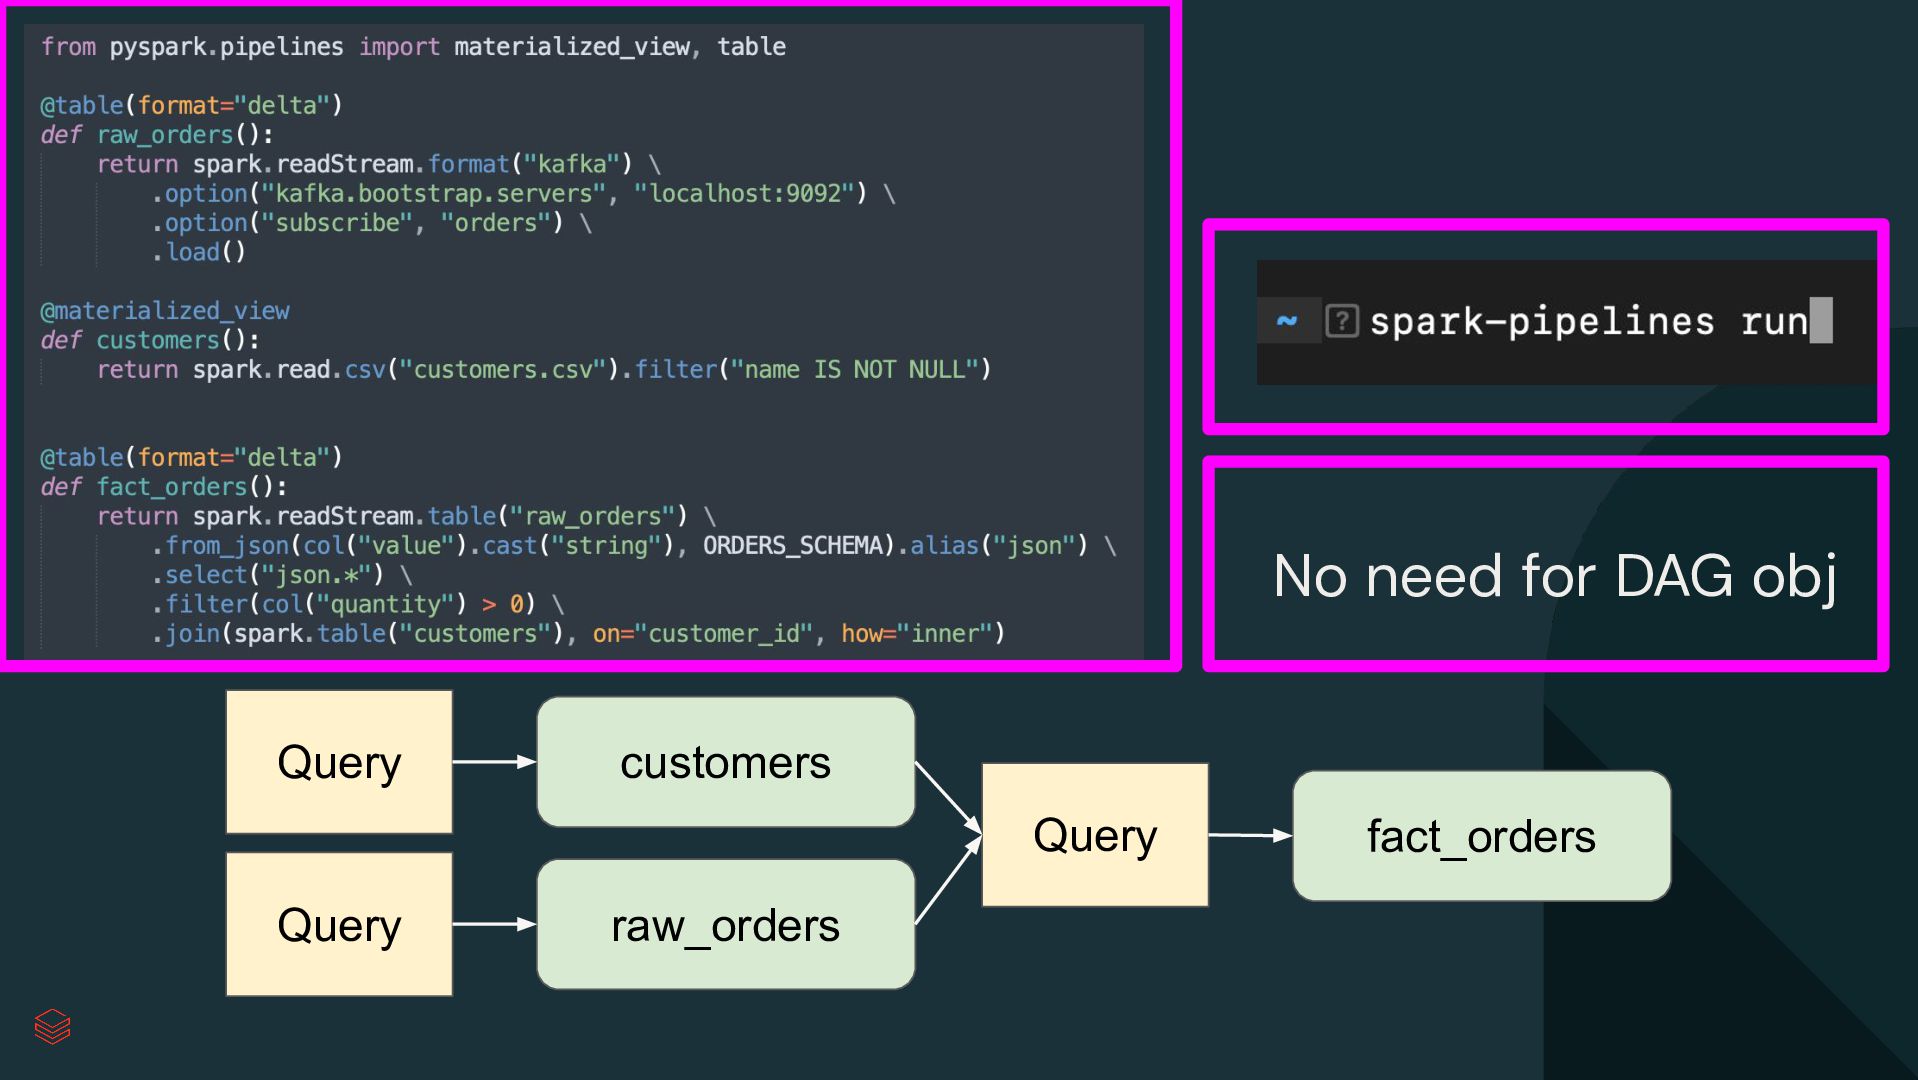
15 minutes Batch Query customers table Streaming Query raw_orders table Run continuously Streaming Query fact_orders table Run continuously -
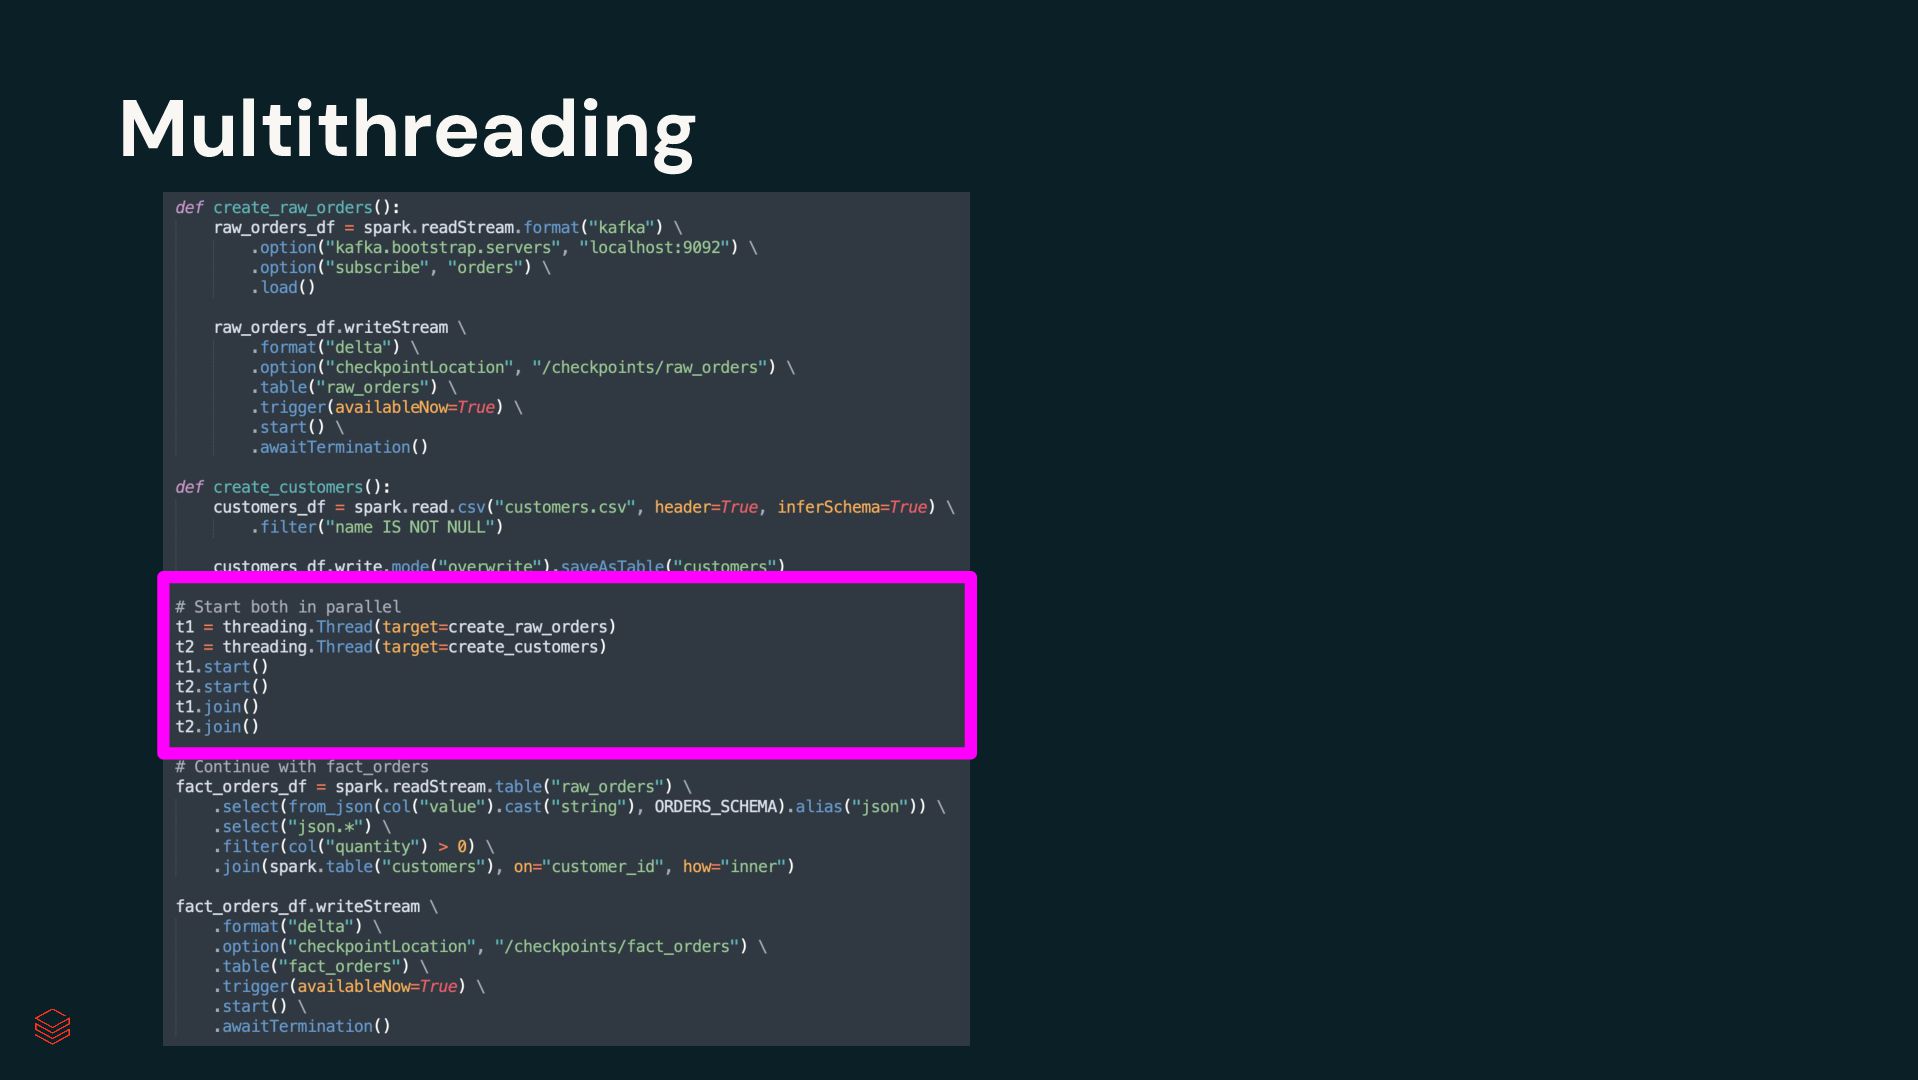
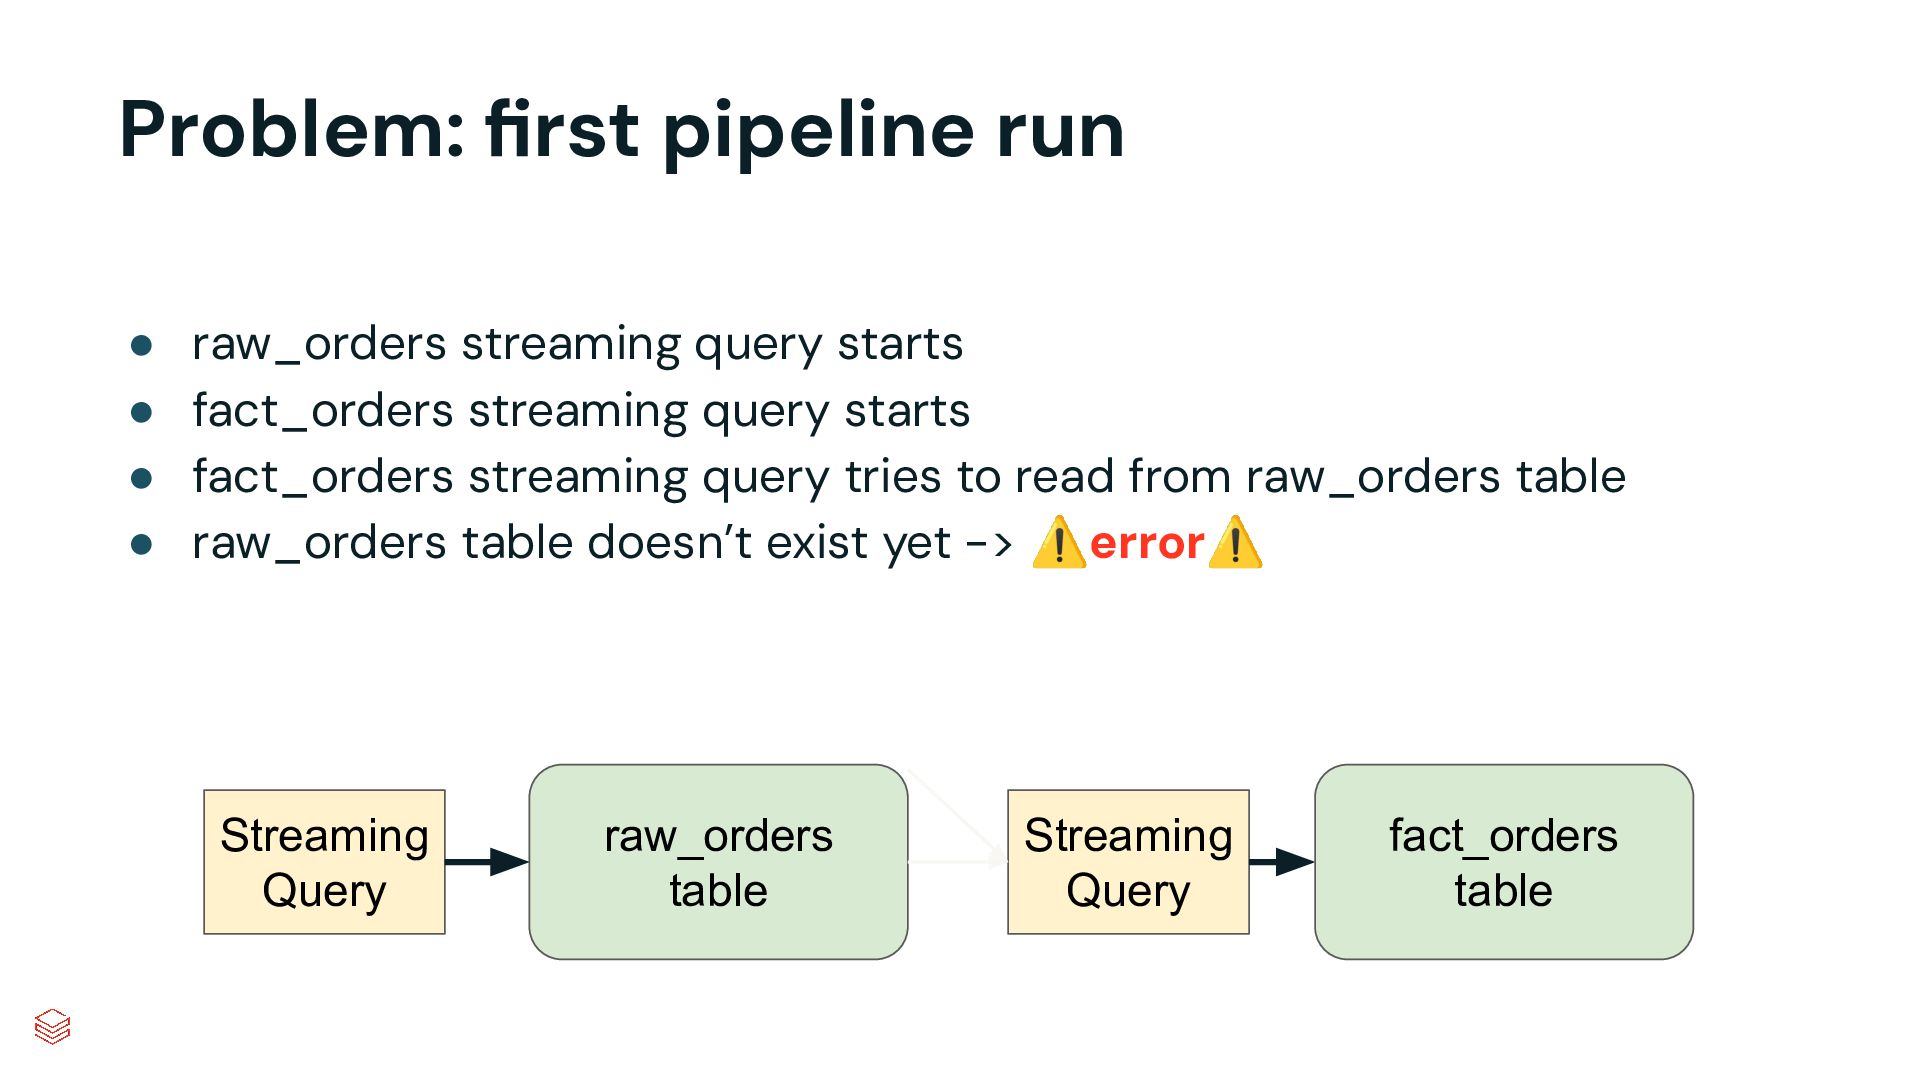
Problem: first pipeline run • • • • raw_orders streaming
query starts async fact_orders streaming query starts fact_orders streaming query tries to read from raw_orders table raw_orders table doesn’t exist yet -> ⚠error⚠ Streaming Query raw_orders table Streaming Query fact_orders table -
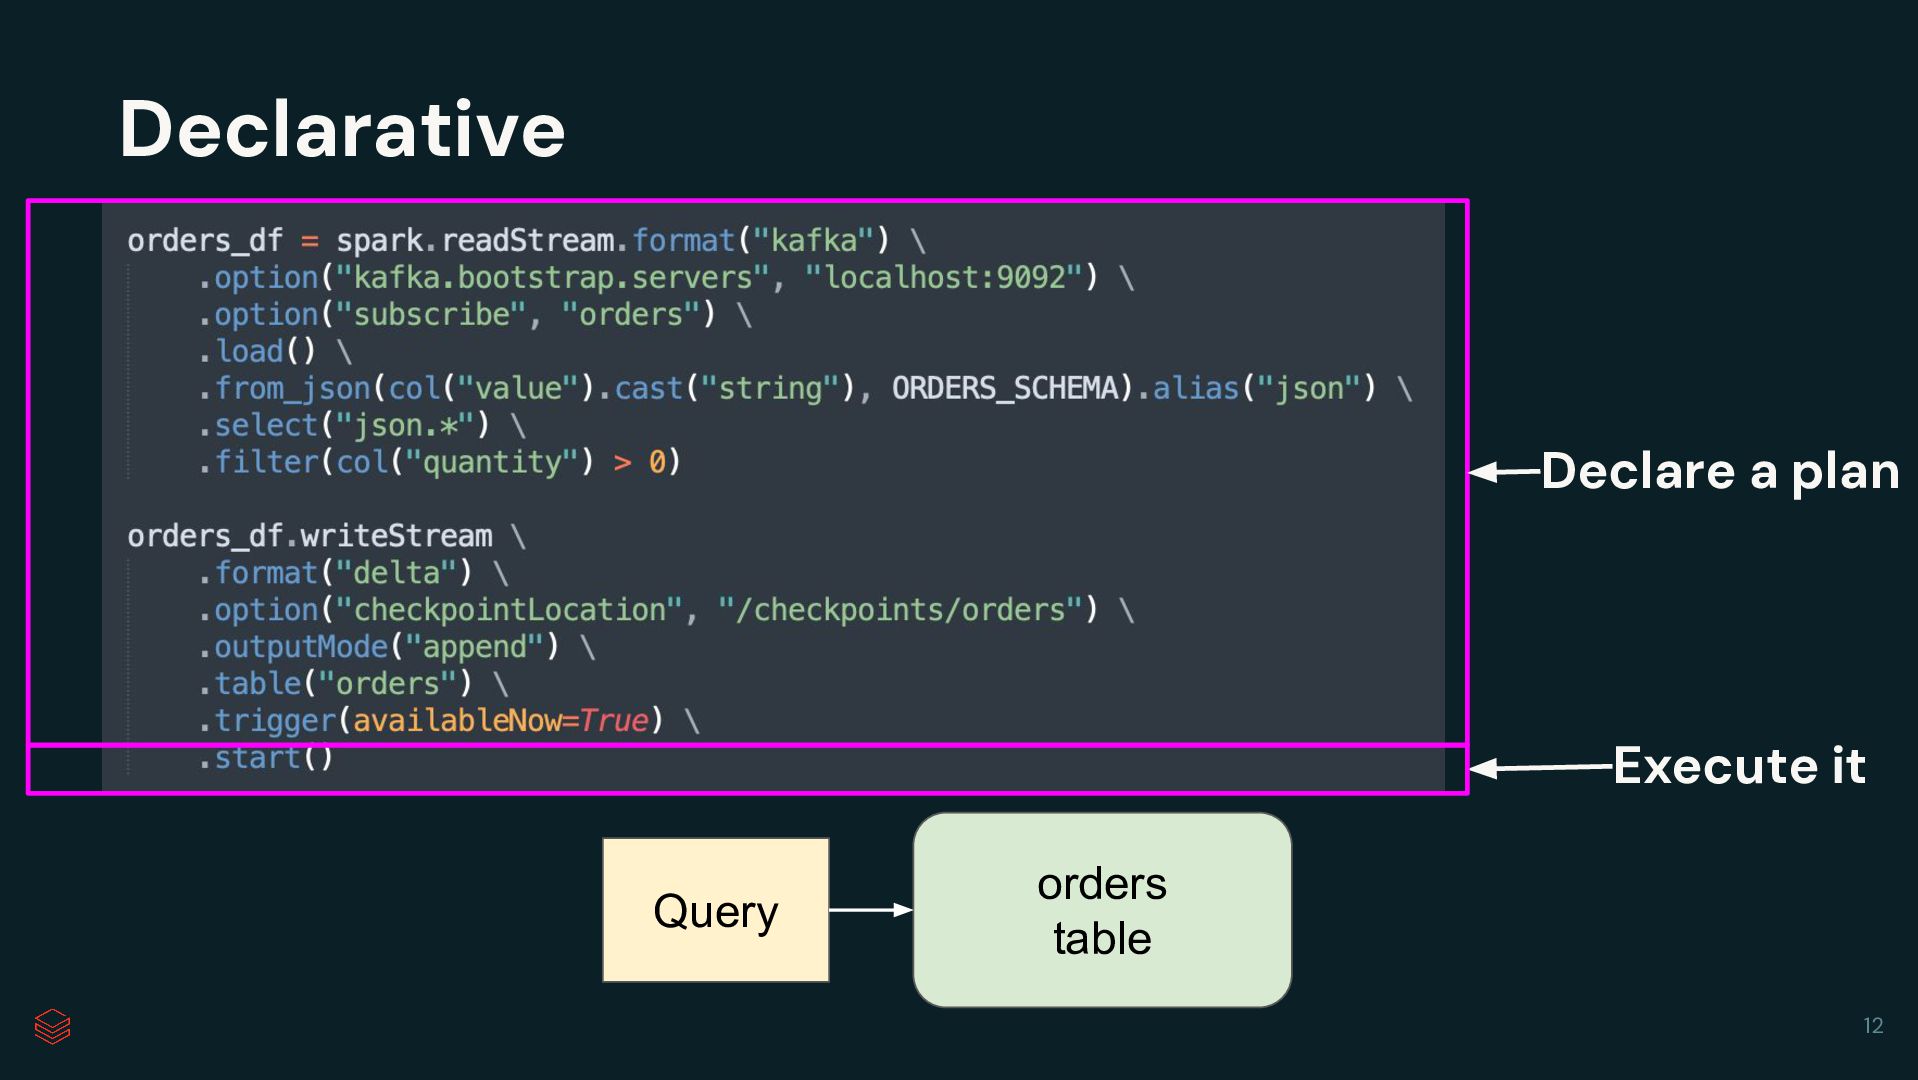
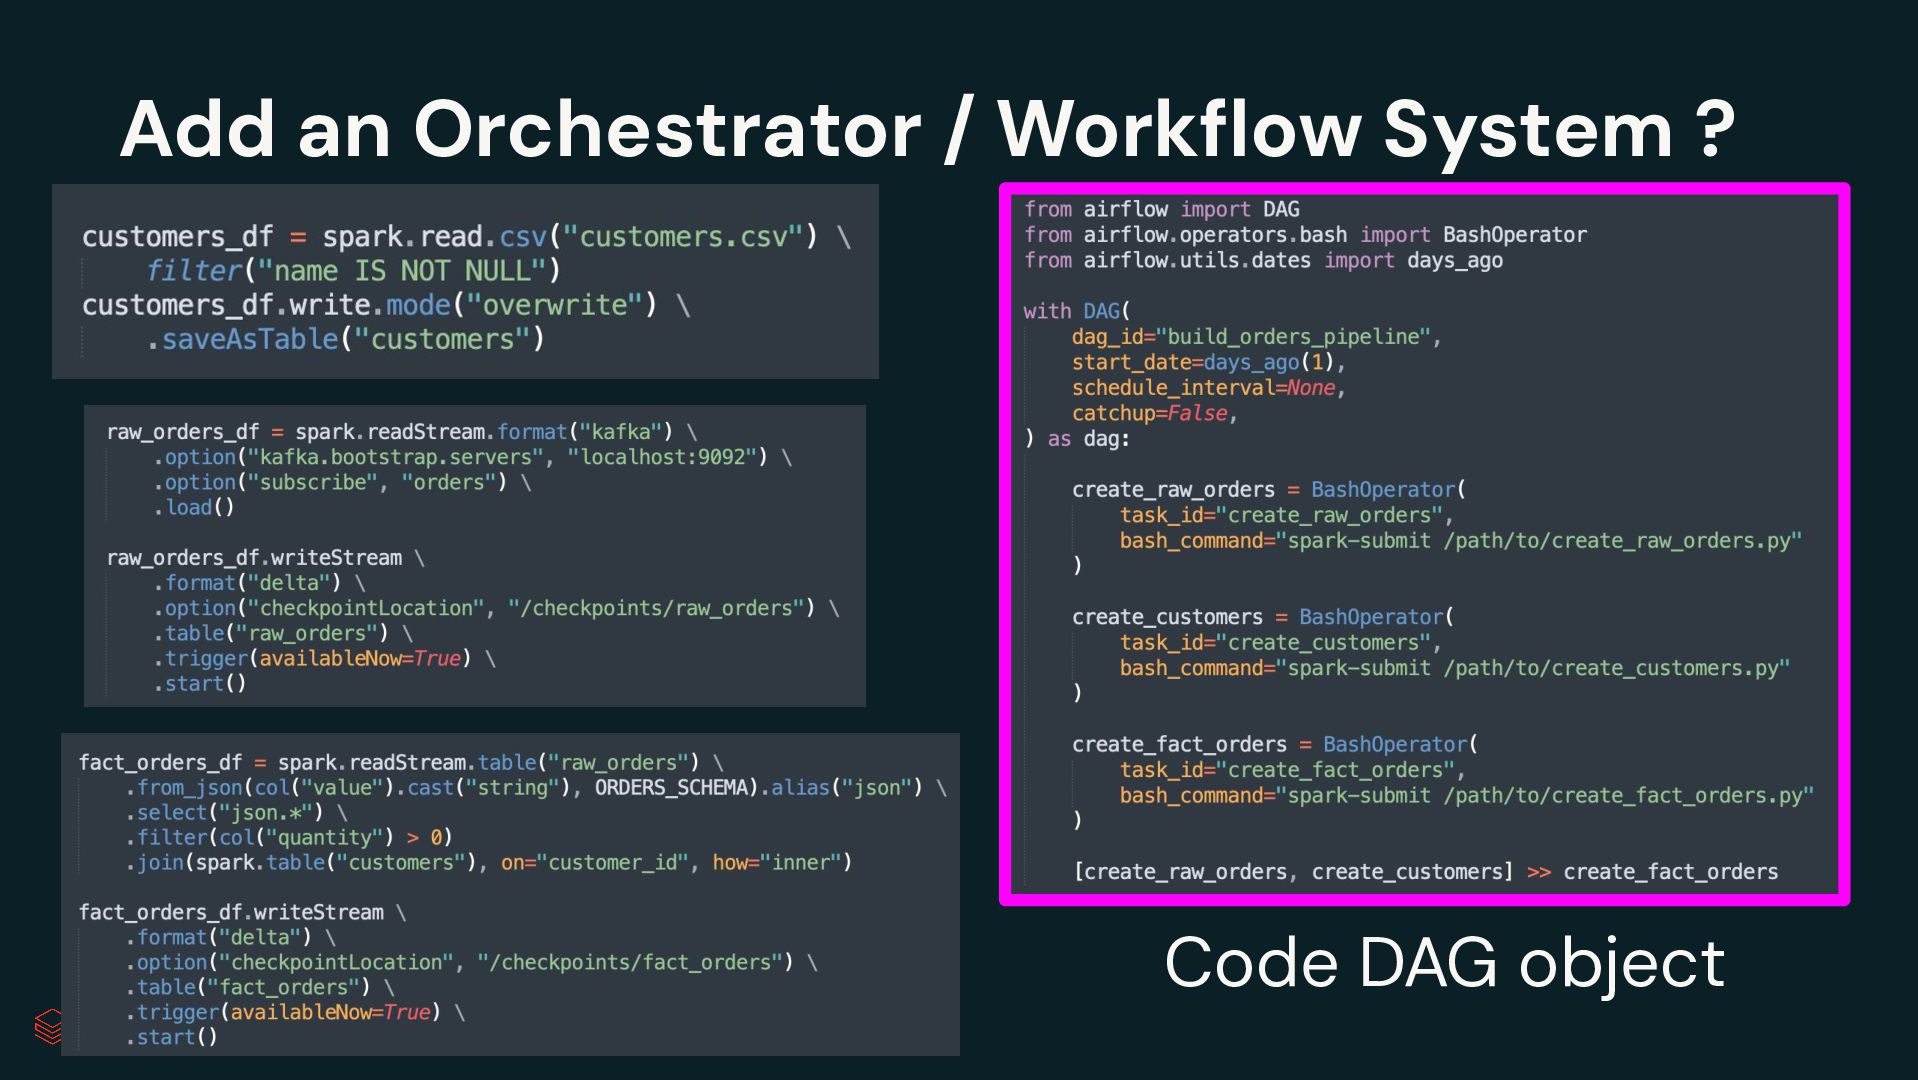
What if we make the whole pipeline declarative? Build plan
-> execute it ©2022 Databricks Inc. — All rights reserved 29 -
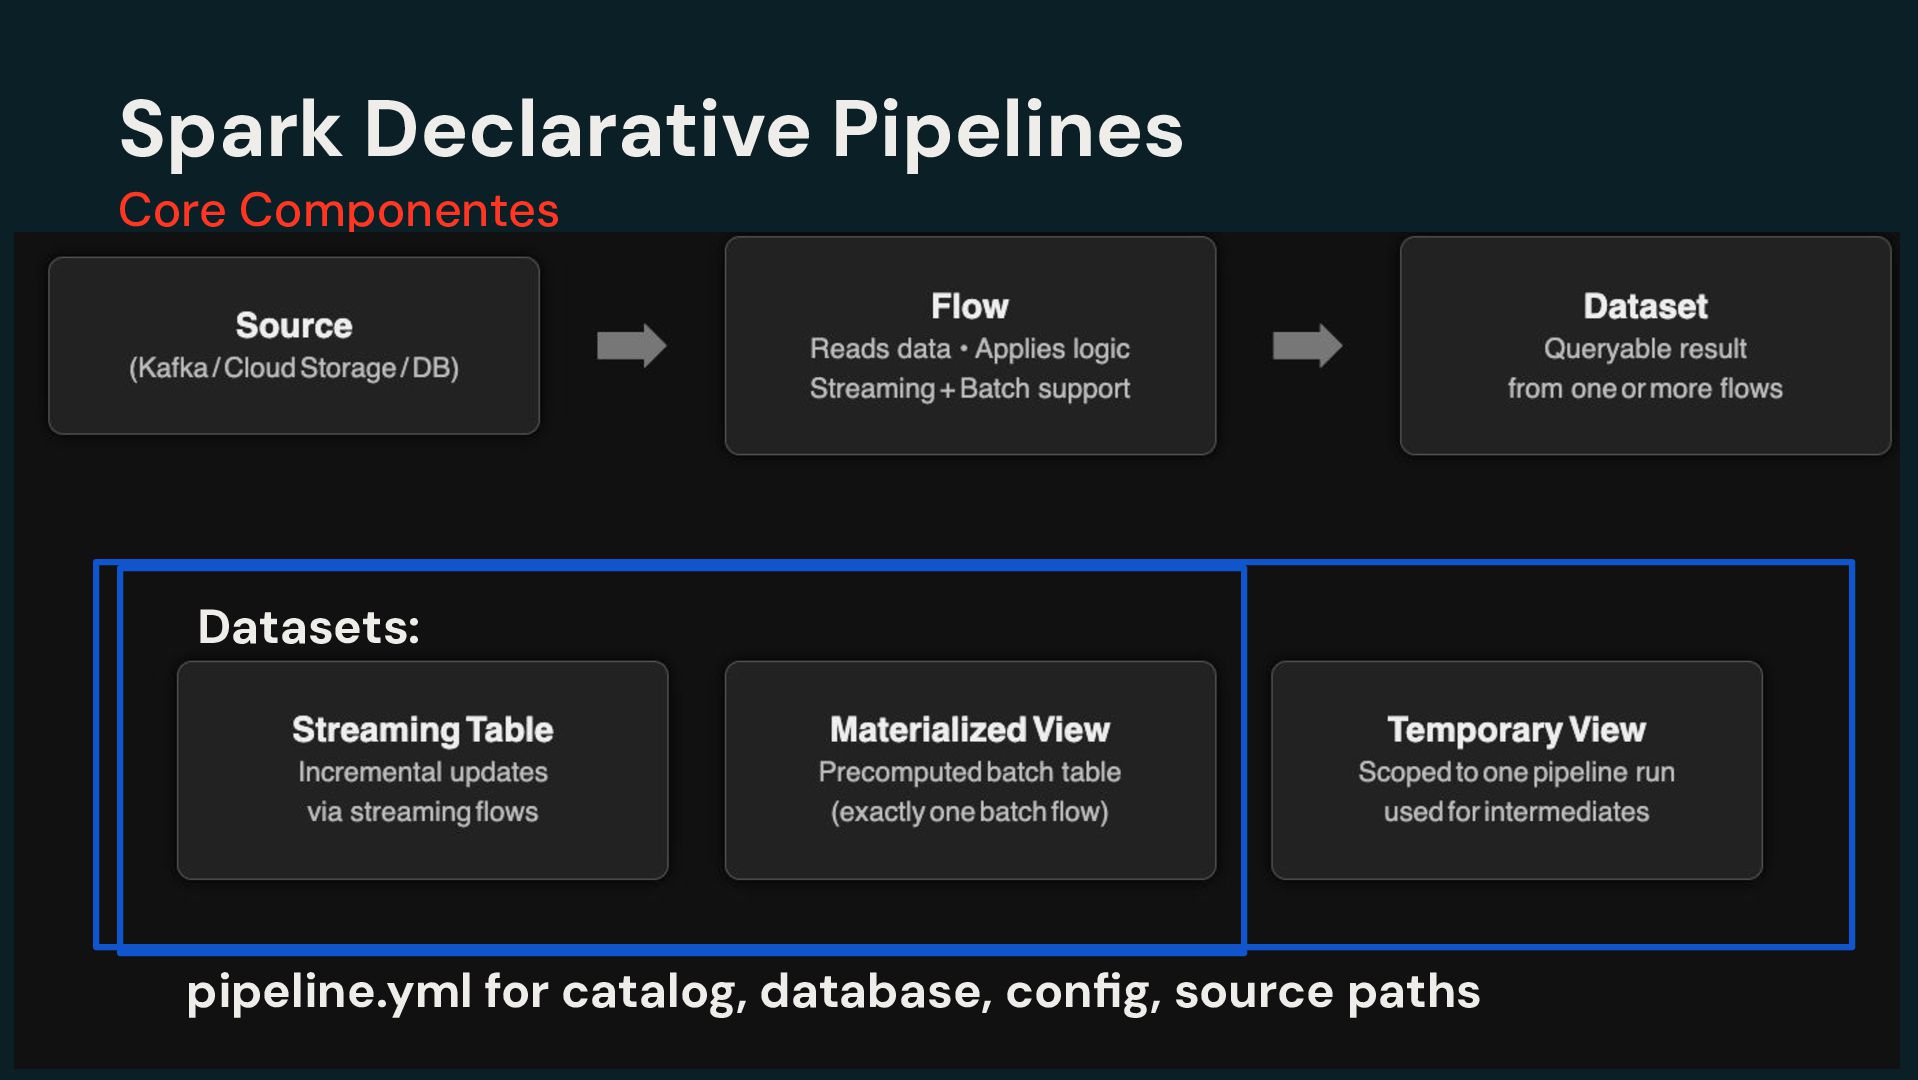
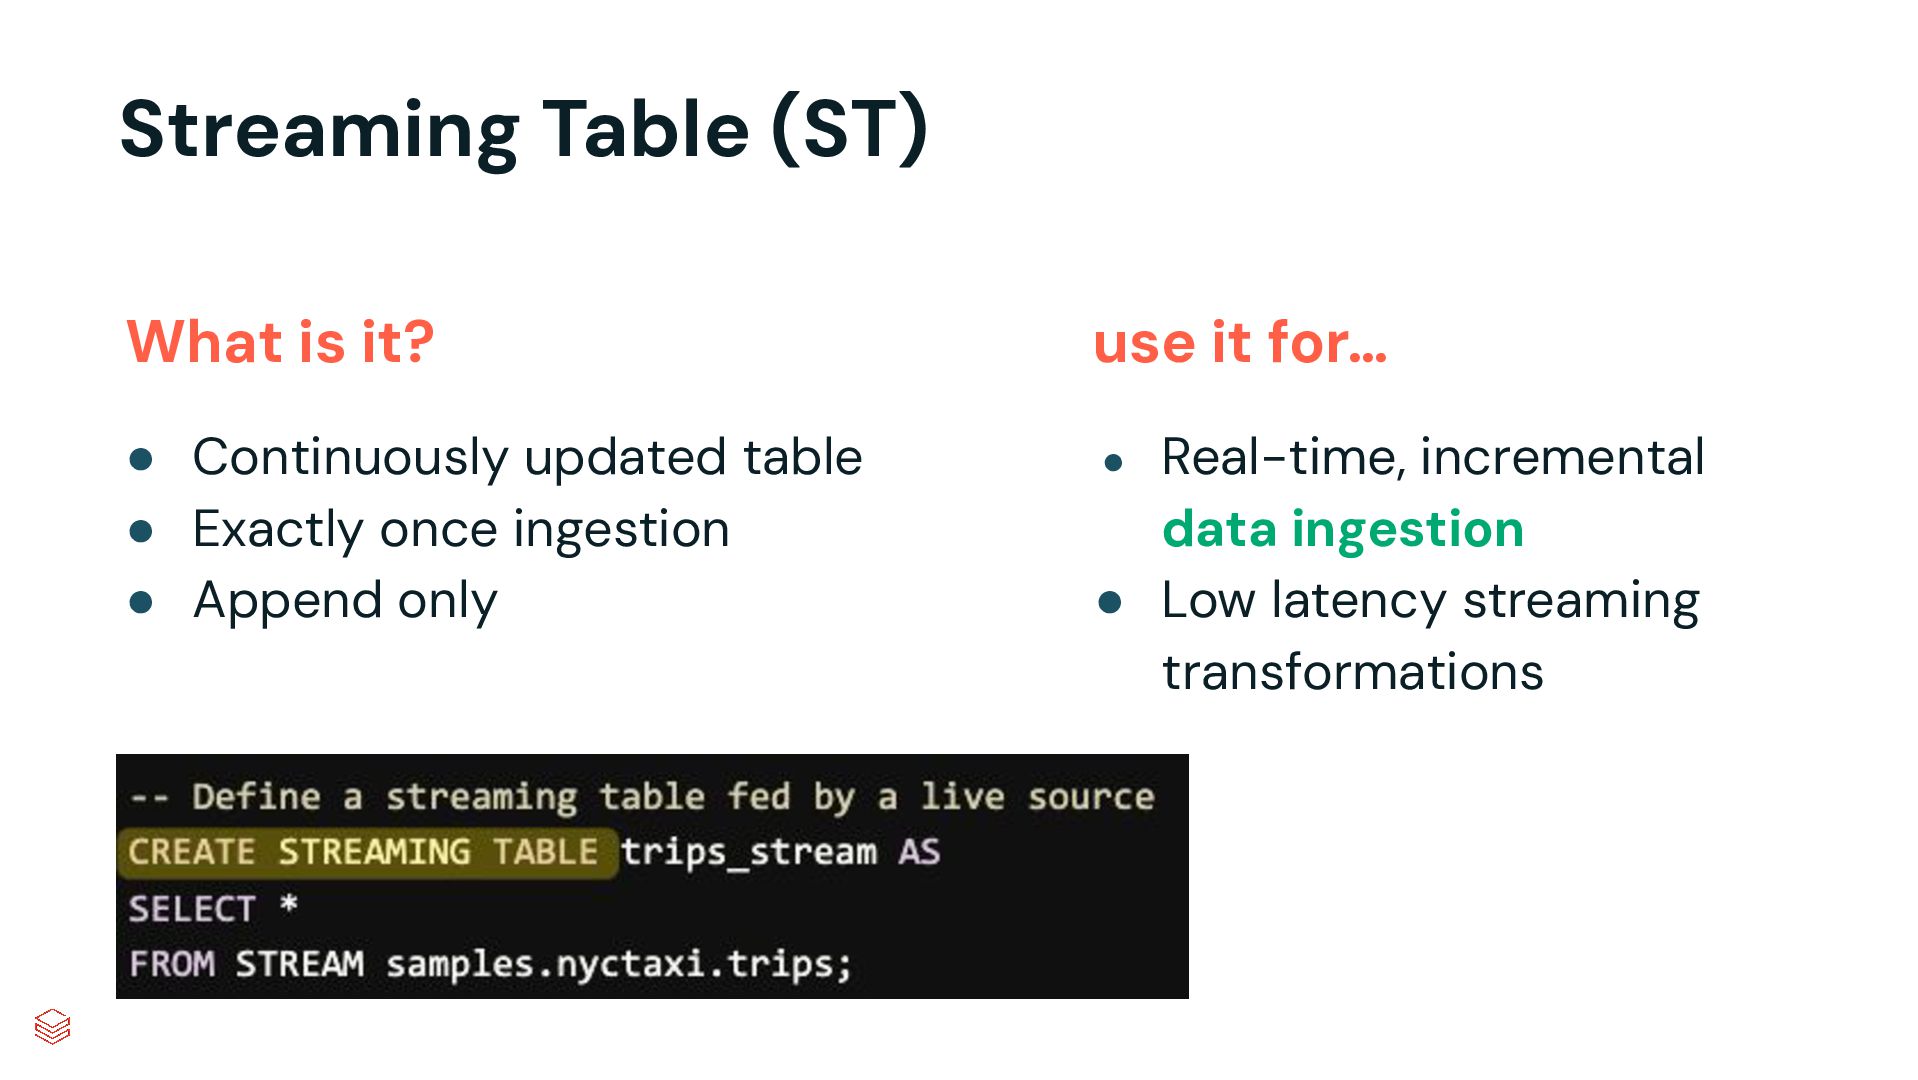
Streaming Table (ST) What is it? use it for… •
Built for incremental processing • Source row handled exactly-once (remembers internal progress) • Append-only sources /event stream Real-time, incremental data ingestion • Low latency streaming transformations • Bronze/silver layers • -
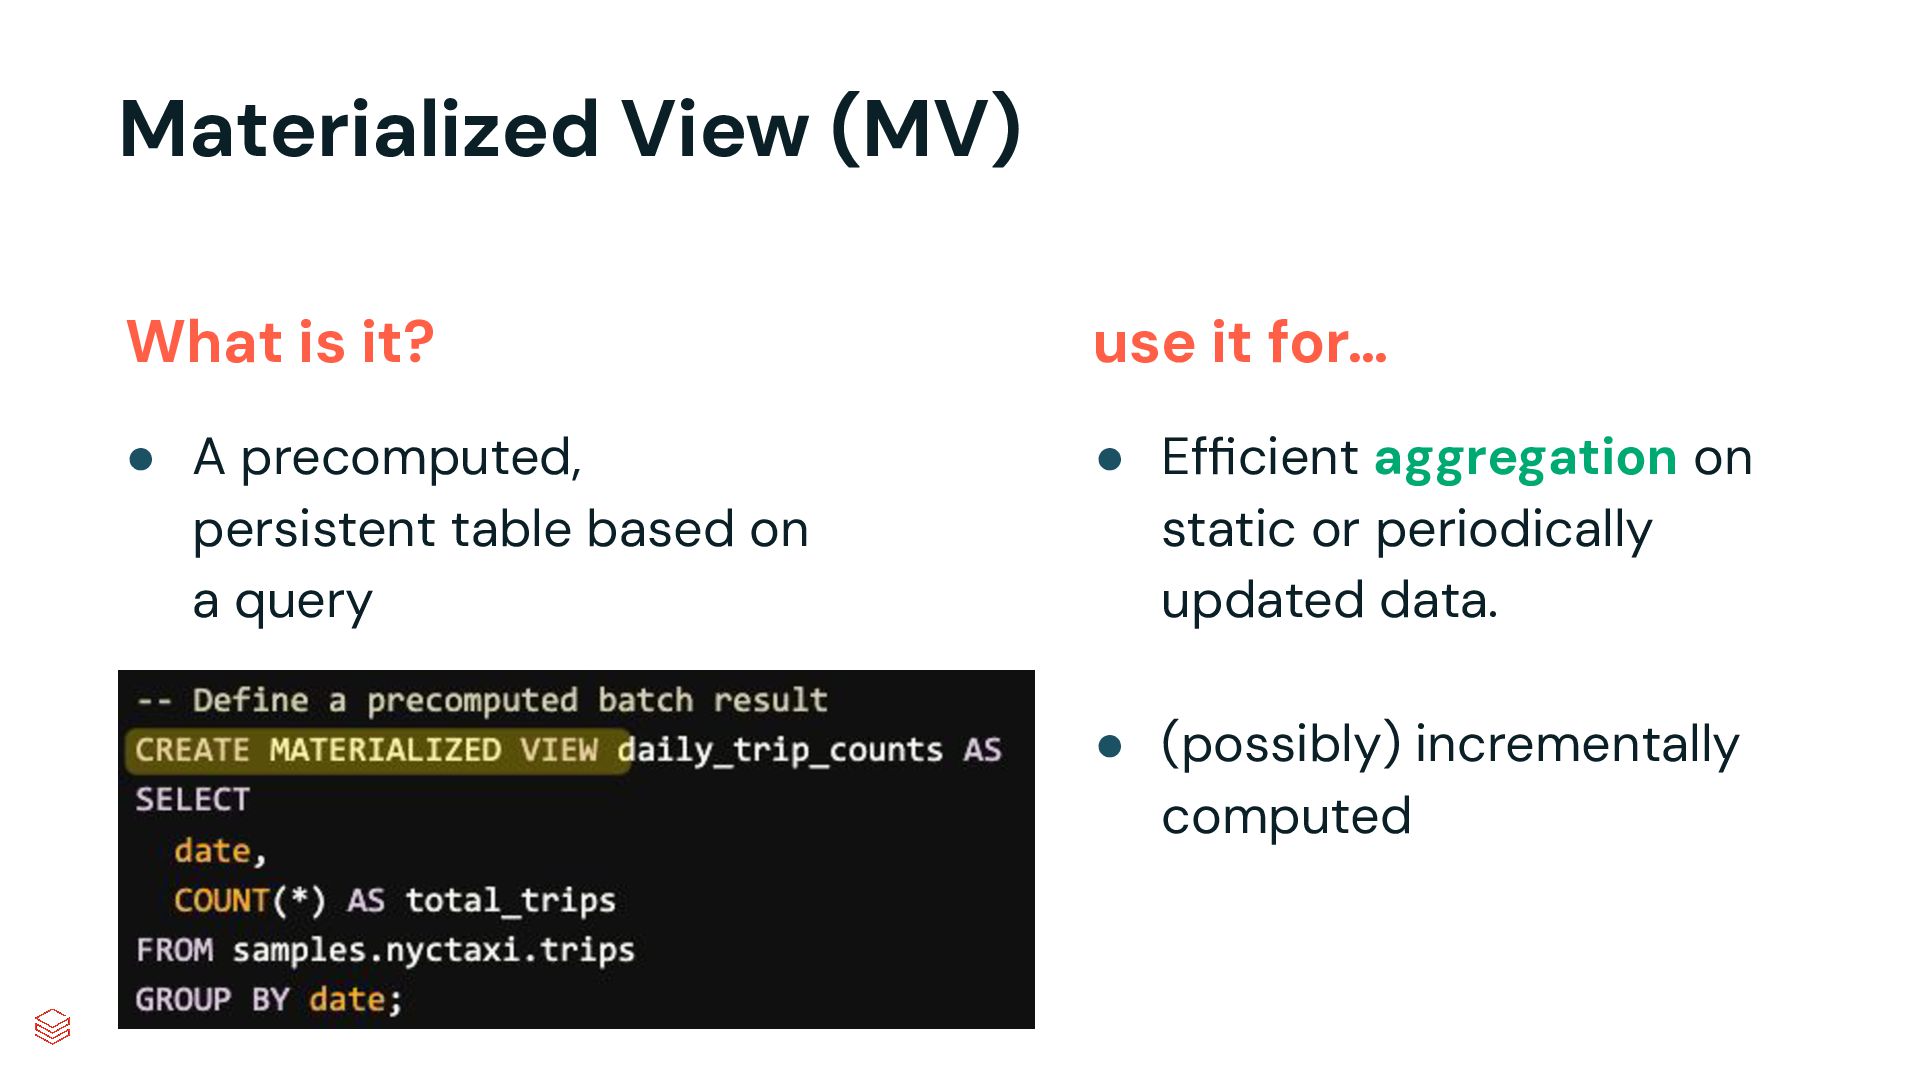
Materialized View (MV) What is it? use it for… •
Precomputed query result (joins, aggregations, anything SQL can express) • Servering layer: gold, BI, dashboards, app views • Guaranteed correct at every refresh • Incremental when possible, full recompute when needed -
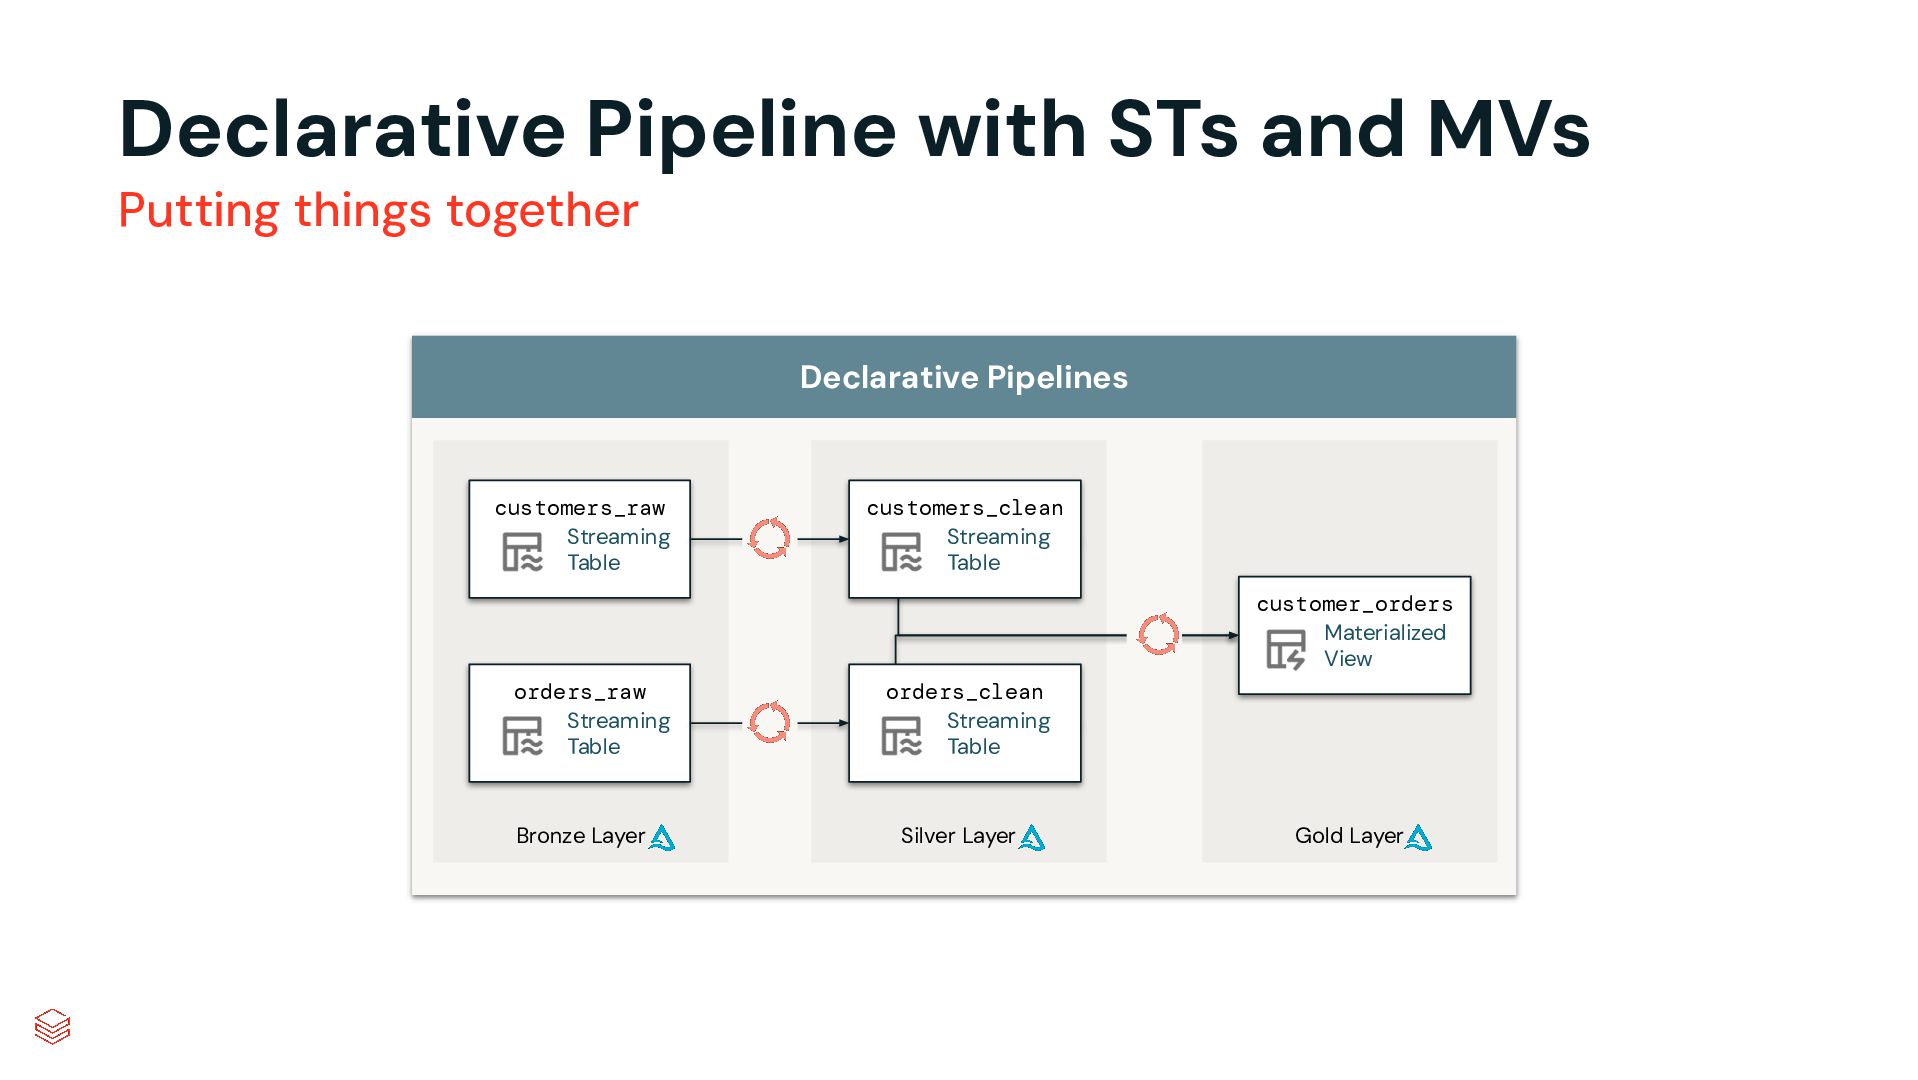
Declarative Pipeline with STs and MVs Putting things together Declarative
Pipelines customers_raw Streaming Table customers_clean Streaming Table customer_orders Materialized View orders_raw Streaming Table orders_clean Streaming Table Bronze Layer Silver Layer Gold Layer -
Flows (not needed for this talk/demo) What is it? use
it for… • Flows are implicit for ST and MV • AUTO CDC • A flow is the processing unit: moves data to table -> how • Table is the target -> what • Flows support batch and streaming • ST with several flows "Stream 2 Kafka topics into a ST" • Syntax: CREATE FLOW F AS [AUTO CDC | … more to come] -
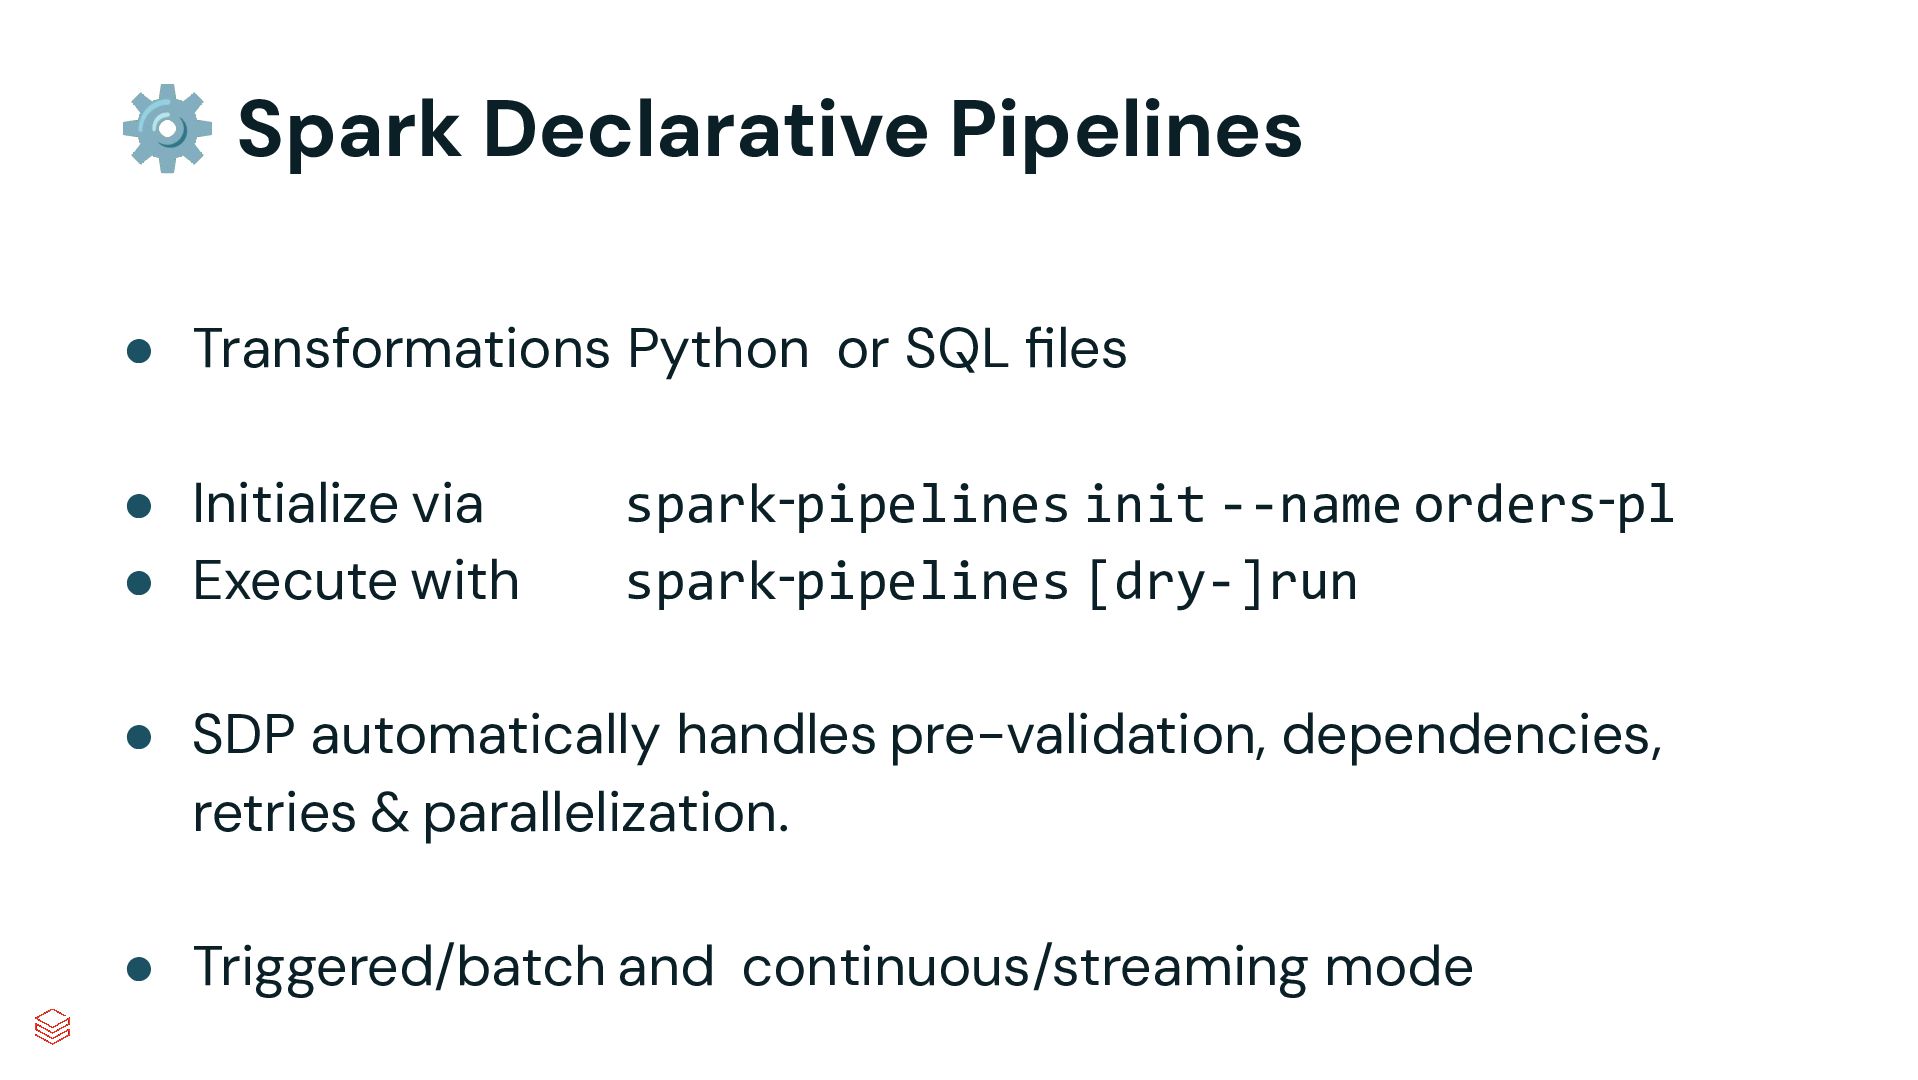
⚙ Spark Declarative Pipelines • Transformations are Python or SQL
files • Initialize via • Execute with spark‑pipelines init --name orders‑pl spark‑pipelines [dry-]run • SDP automatically handles pre-validation, dependencies, retries & parallelization. • Triggered/batch and continuous/streaming mode -
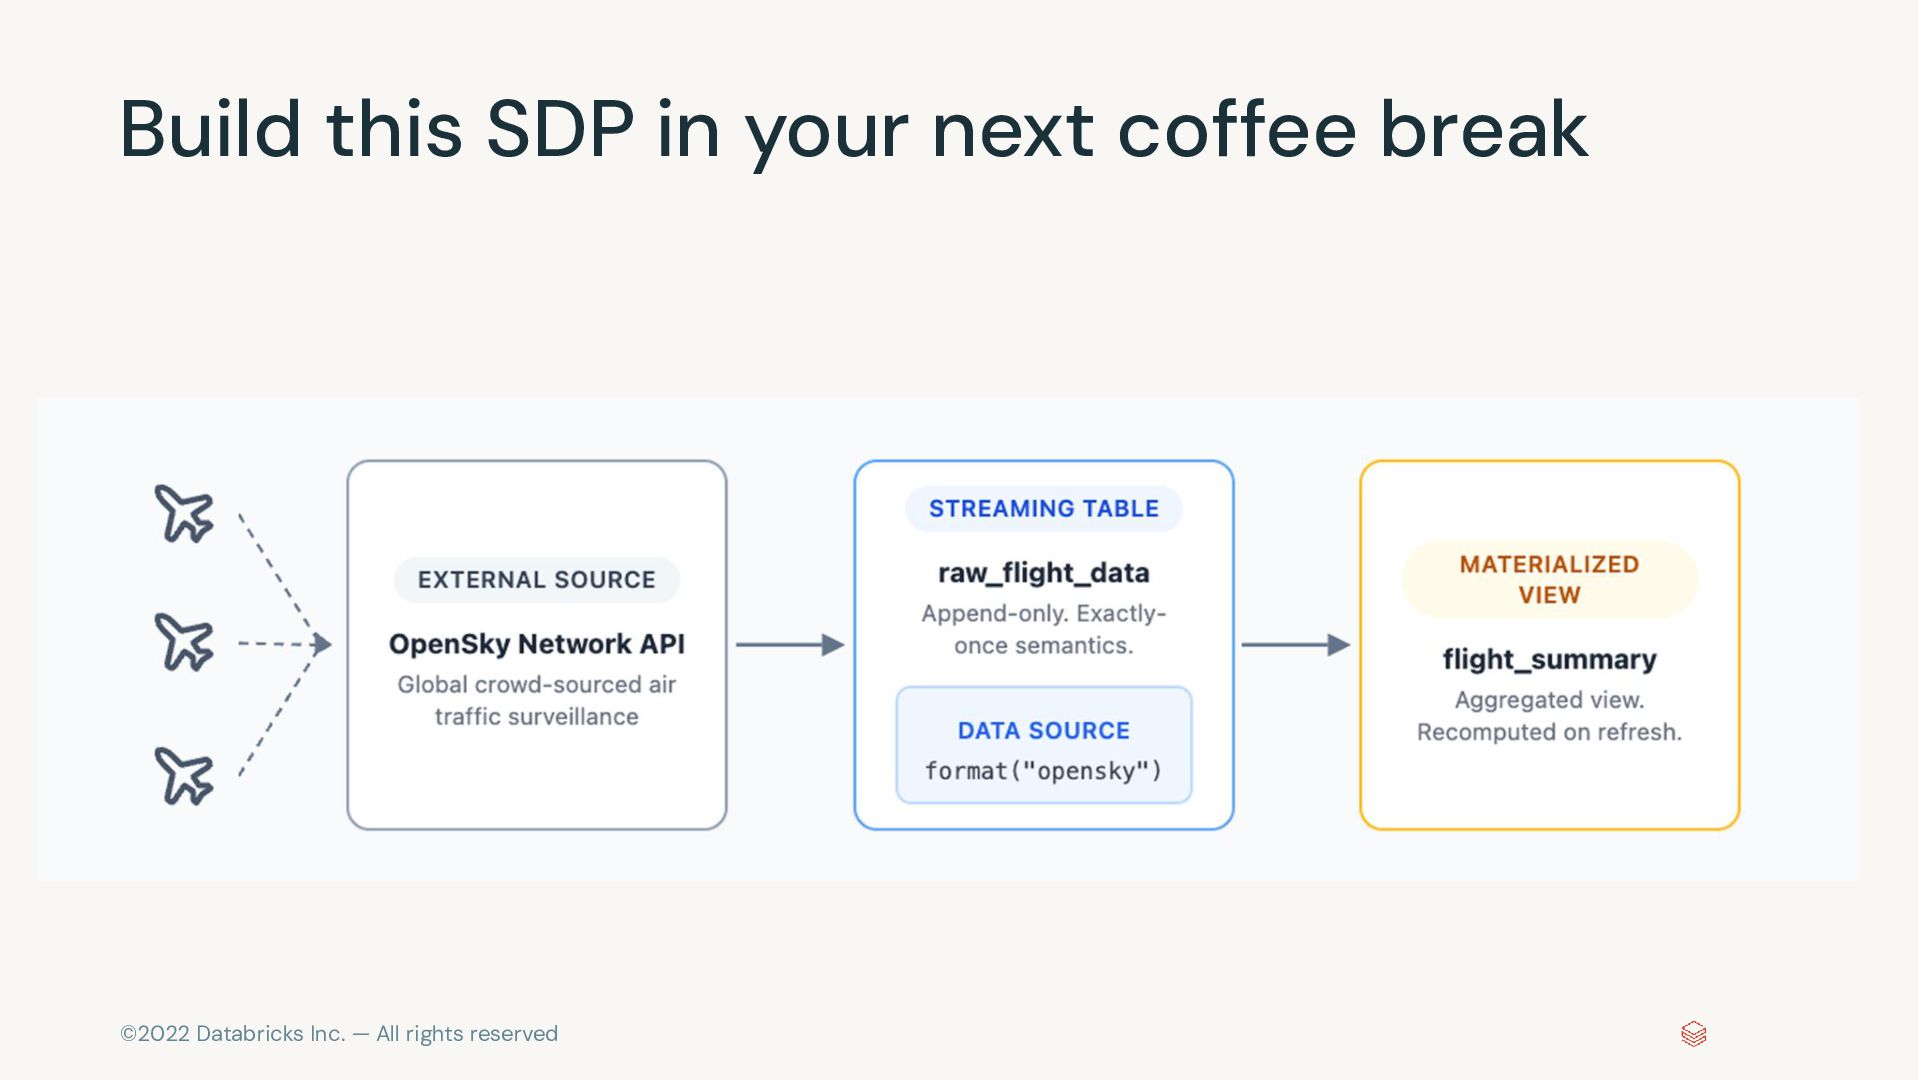
Build this SDP in your next coffee break OSS or
Lakeflow (try both!) ©2022 Databricks Inc. — All rights reserved -
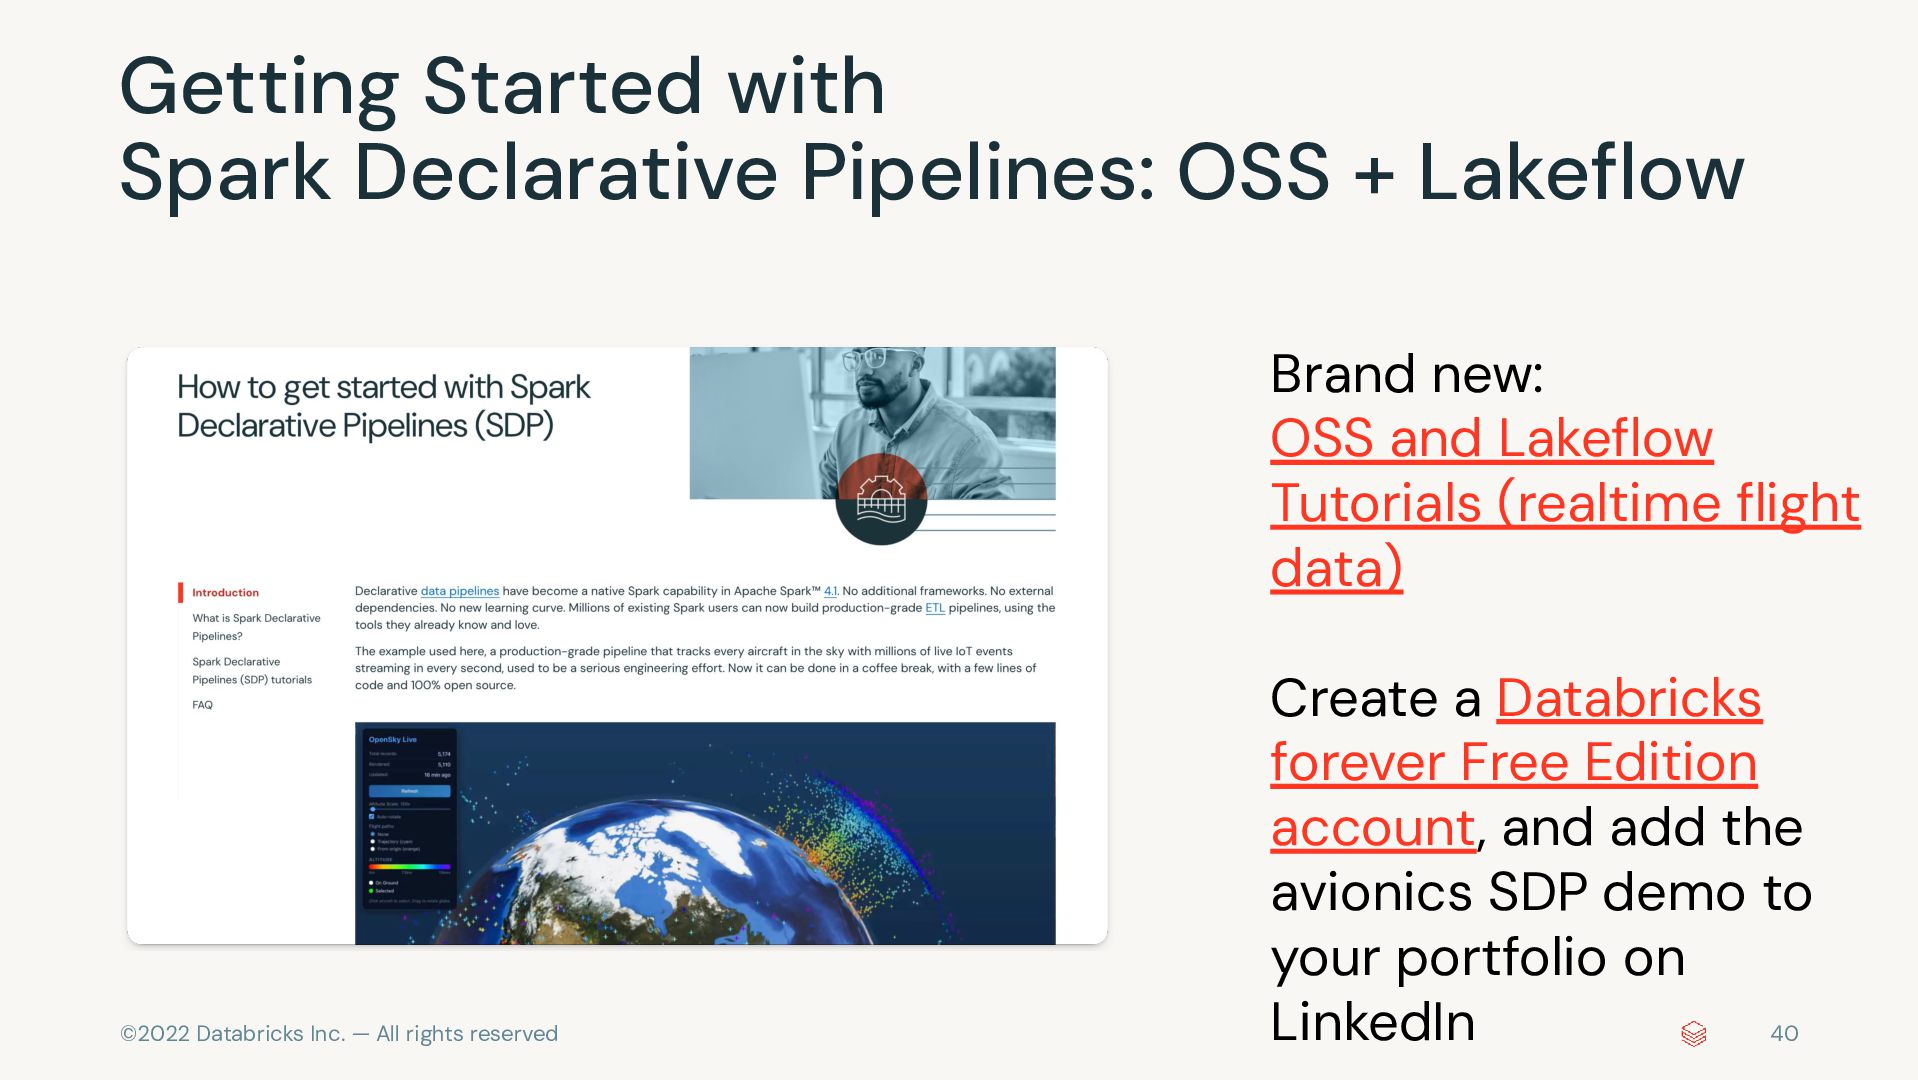
Getting Started with Spark Declarative Pipelines: OSS + Lakeflow OSS
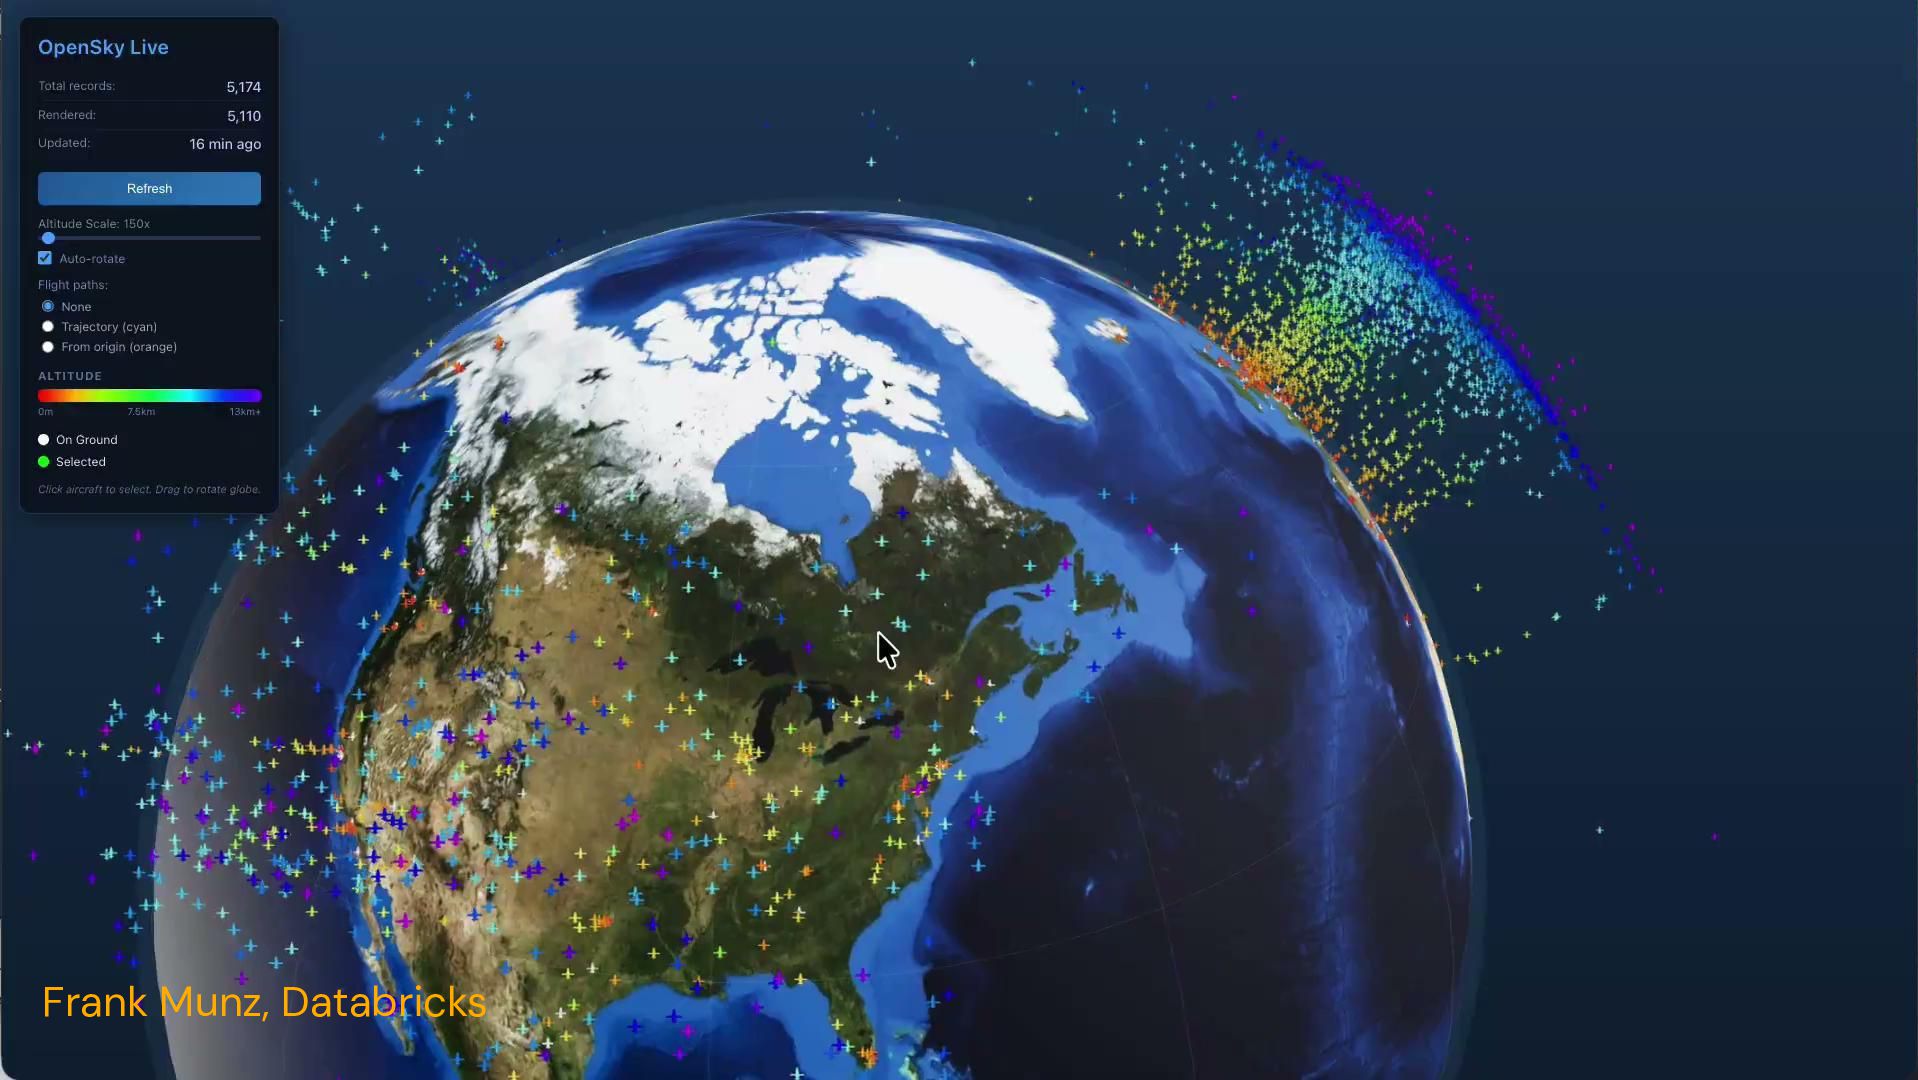
and Lakeflow Tutorials (realtime flight data) Create a Databricks forever Free Edition account, and add the avionics SDP demo to your portfolio on LinkedIn ©2022 Databricks Inc. — All rights reserved 40 -
Custom Python Datasource for OpenSky API ©2022 Databricks Inc. —
All rights reserved 41 -
🚀 Python Data Source API spark.readstream.format("opensky") • Use familiar spark.read.format()
and write.format() • OSS • simple pip install • Supports batch + streaming -
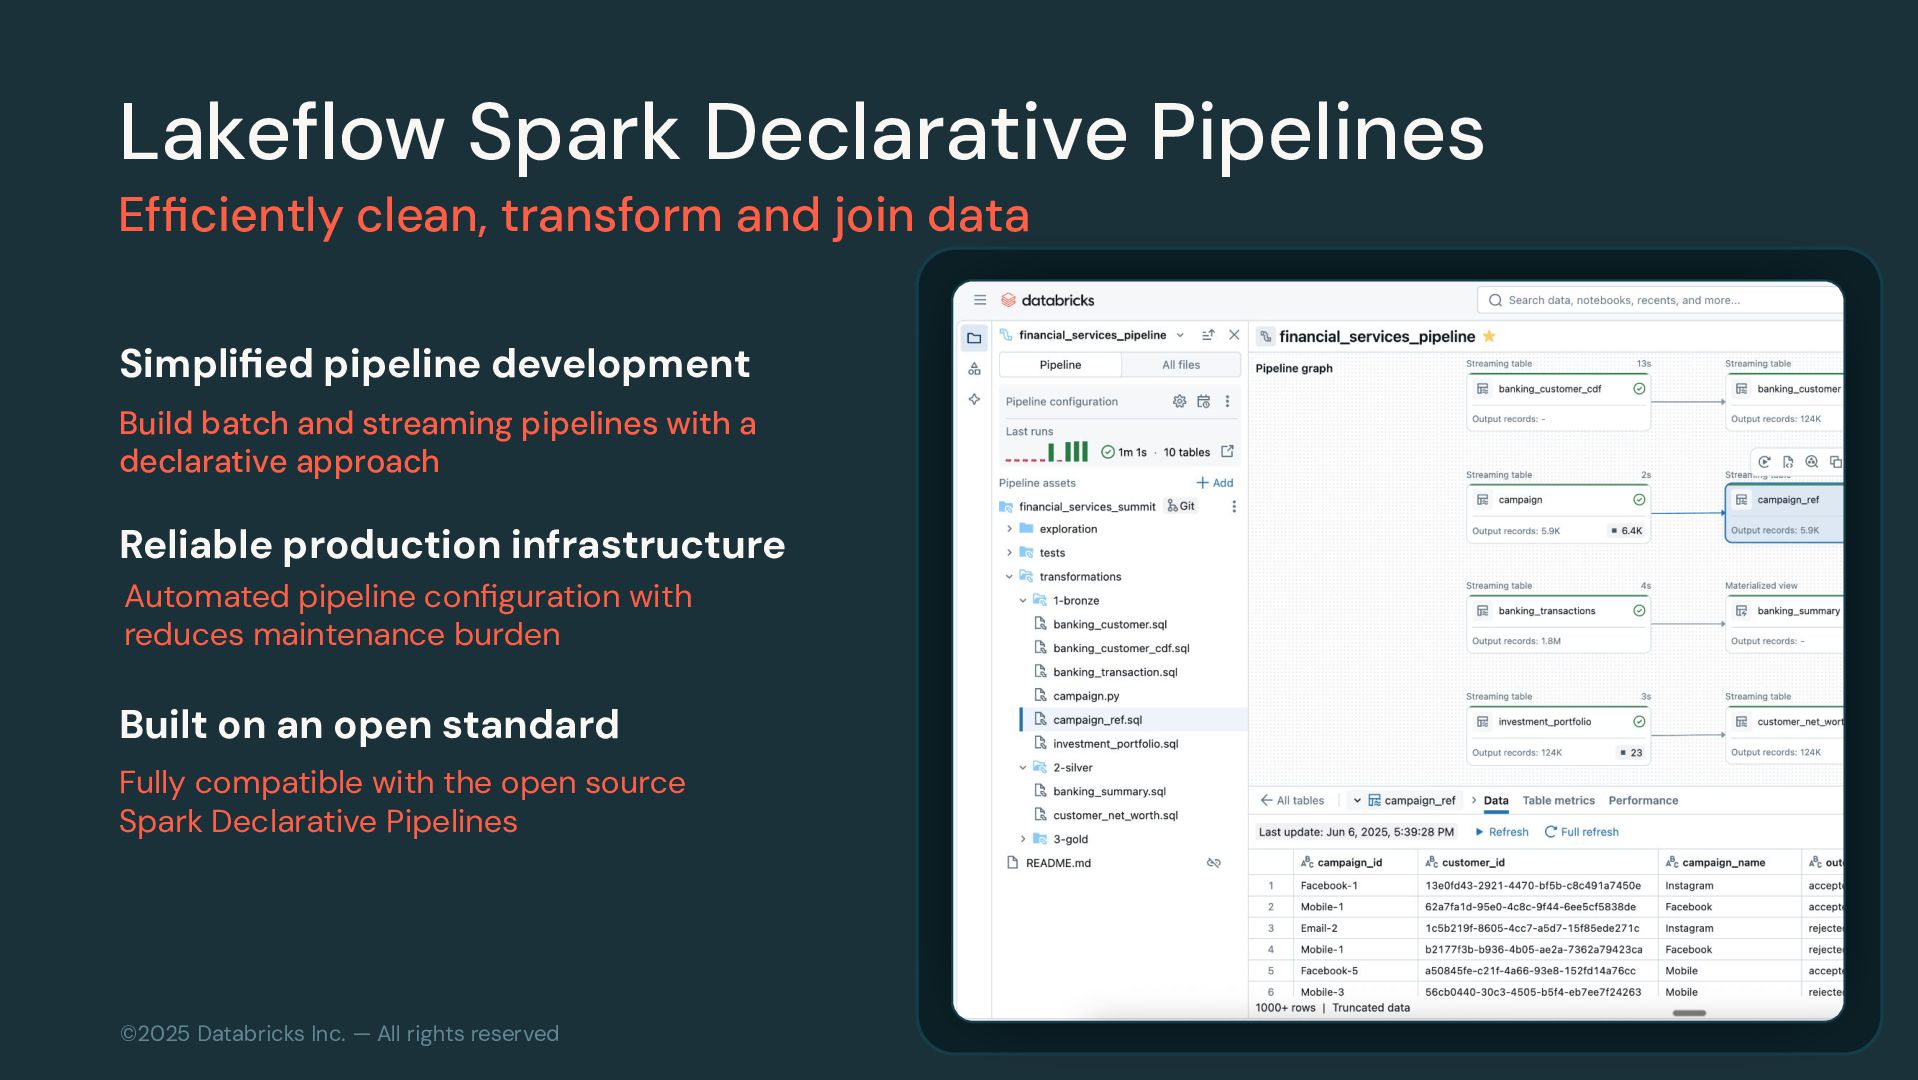
Lakeflow Spark Declarative Pipelines Efficiently clean, transform and join data
Simplified pipeline development Build batch and streaming pipelines with a declarative approach Reliable production infrastructure Automated pipeline configuration with reduces maintenance burden Built on an open standard Fully compatible with the open source Spark Declarative Pipelines ©2025 Databricks Inc. — All rights reserved -
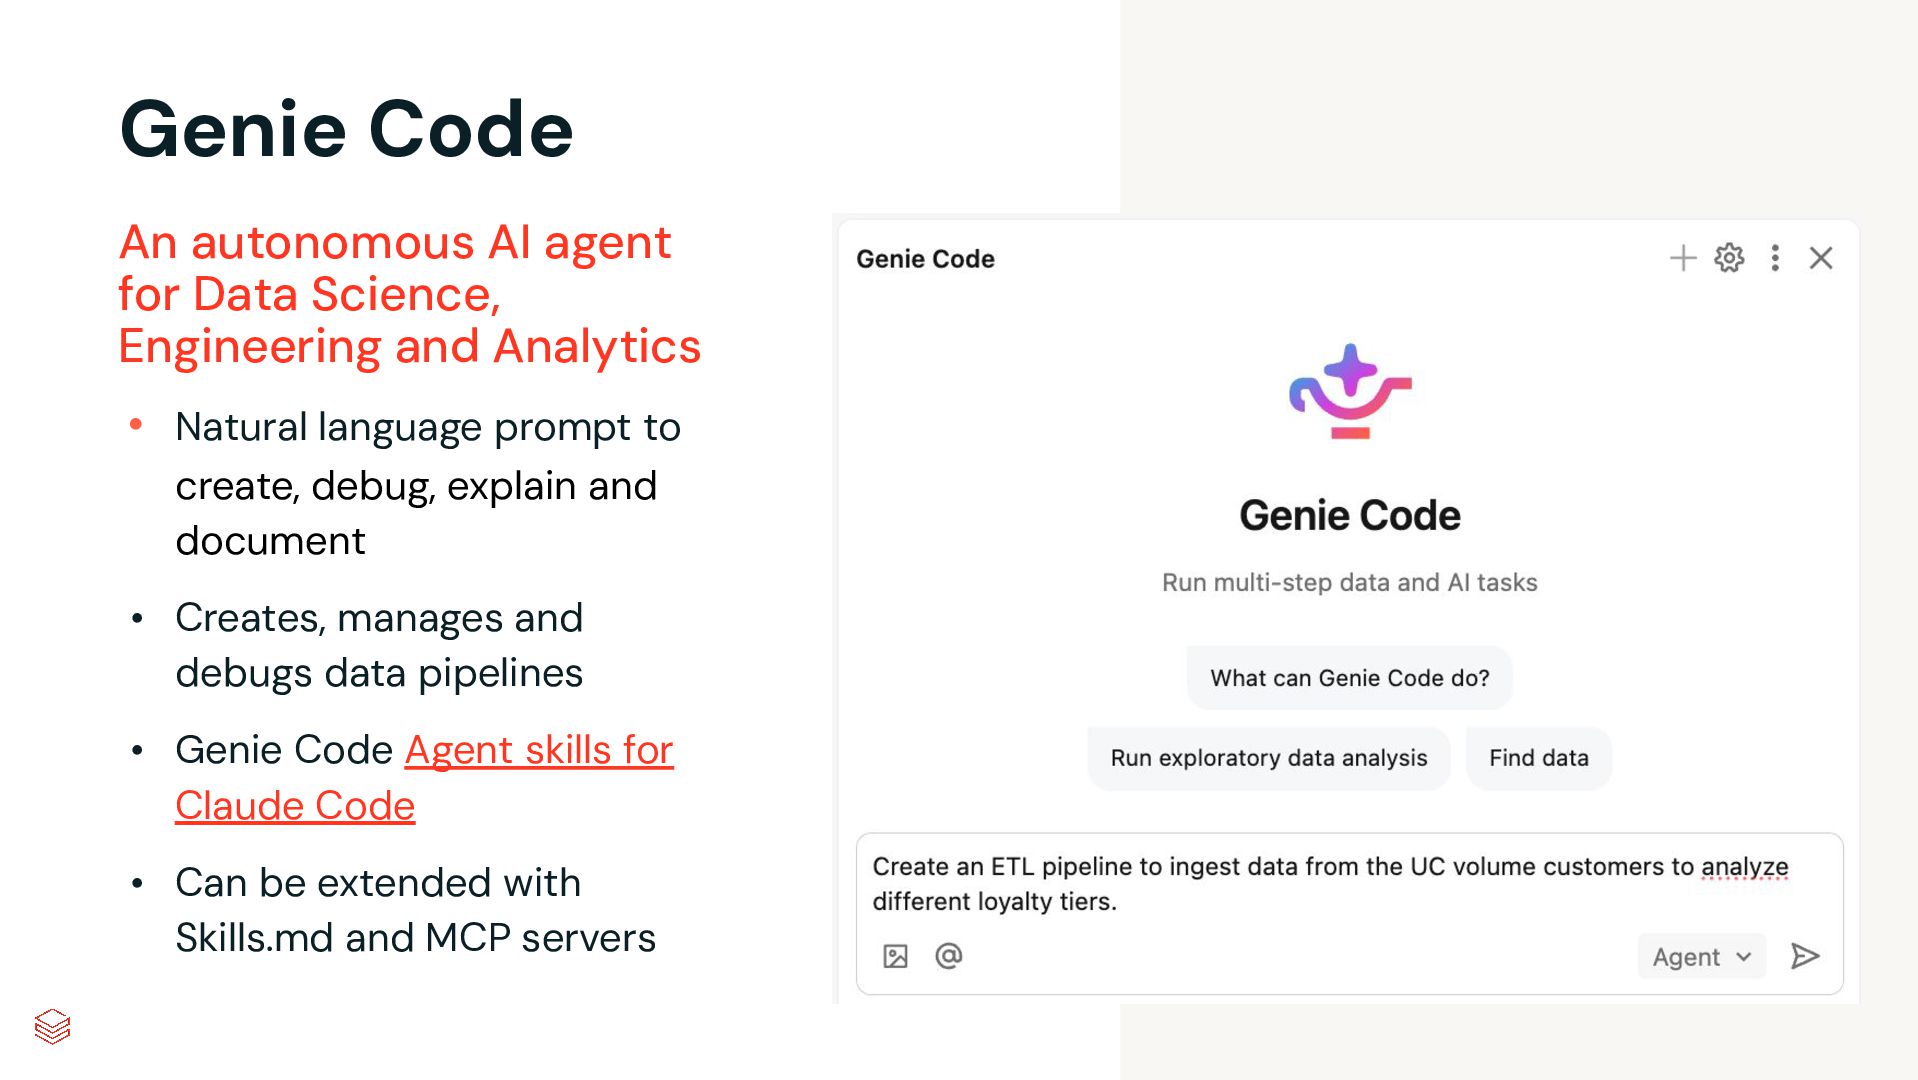
Genie Code An autonomous AI agent for Data Science, Engineering
and Analytics • Natural language prompt to create, debug, explain and document • Creates, manages and debugs data pipelines • Genie Code Agent skills for Claude Code • Can be extended with Skills.md and MCP servers -
Spark & SDP Real-time Mode ©2022 Databricks Inc. — All
rights reserved 46 -
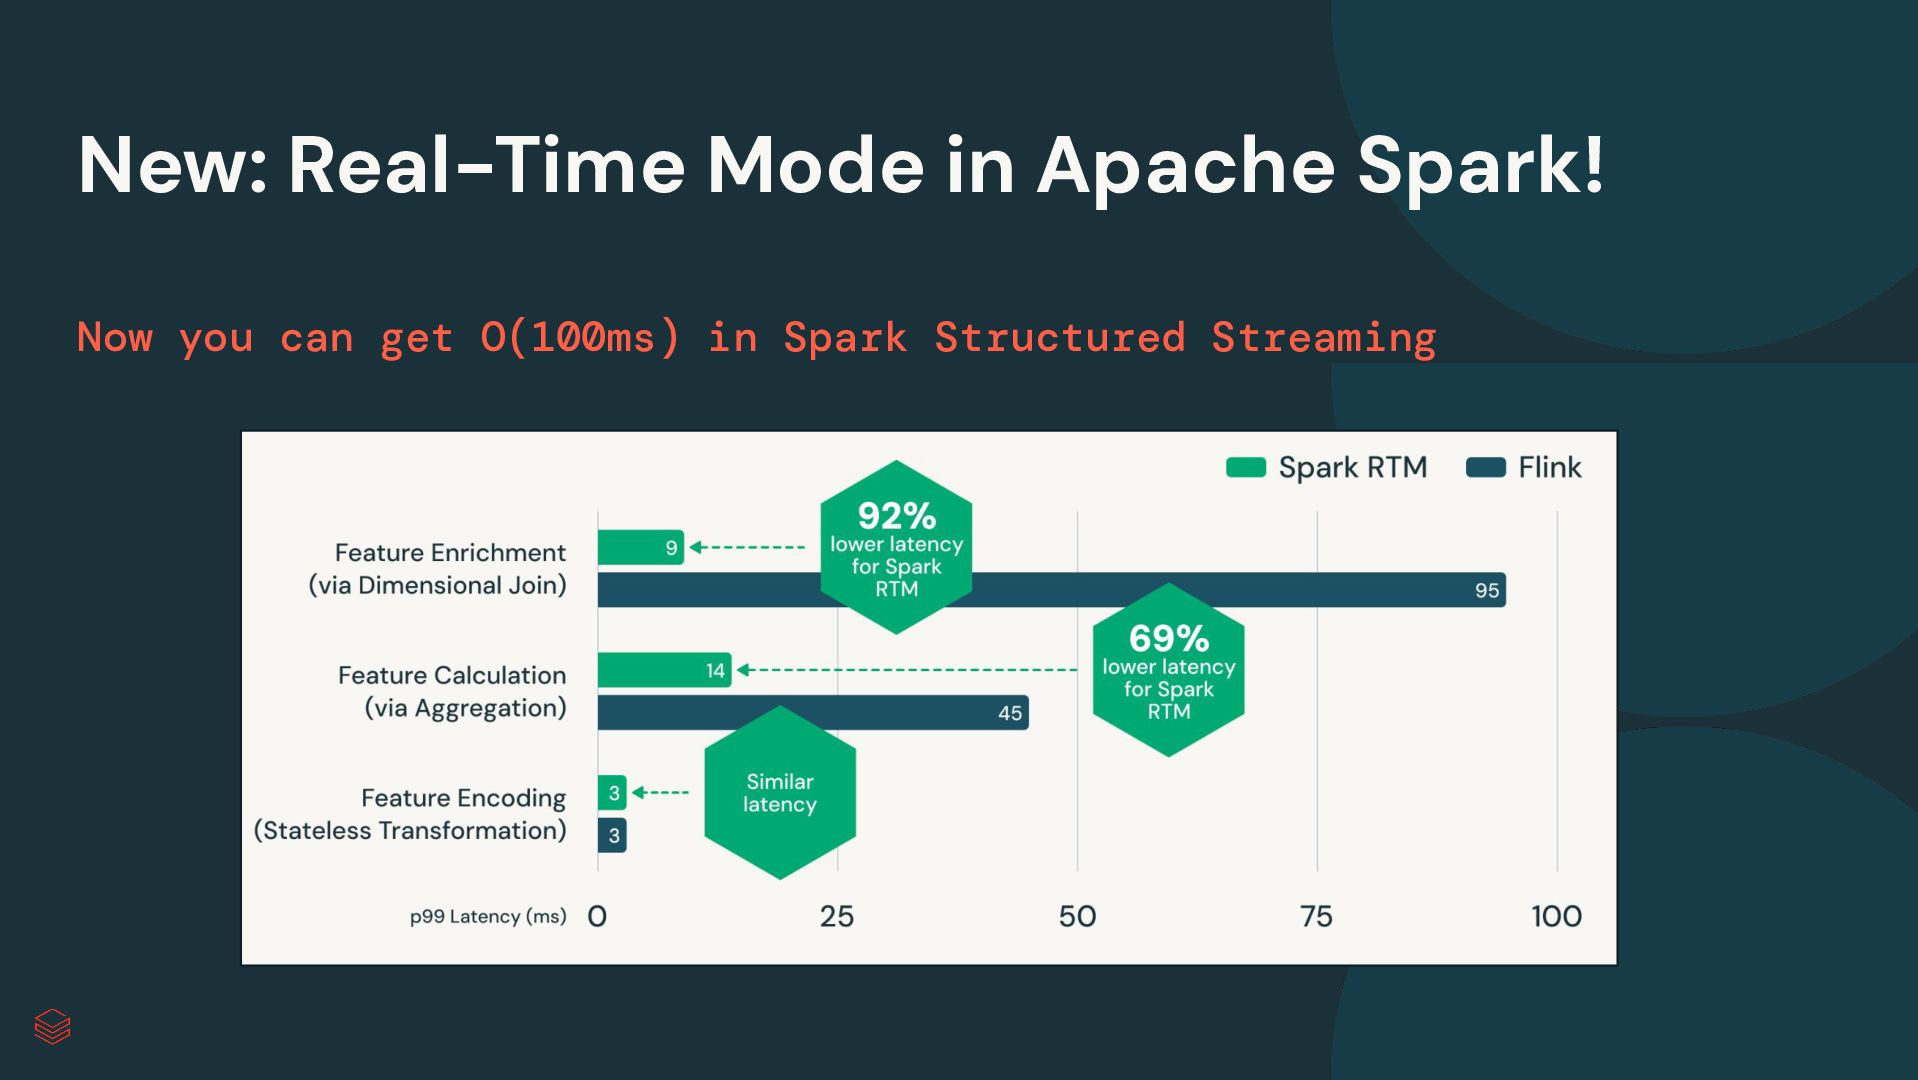
SDP with Real-time Mode (RTM) • 5 ms latency •
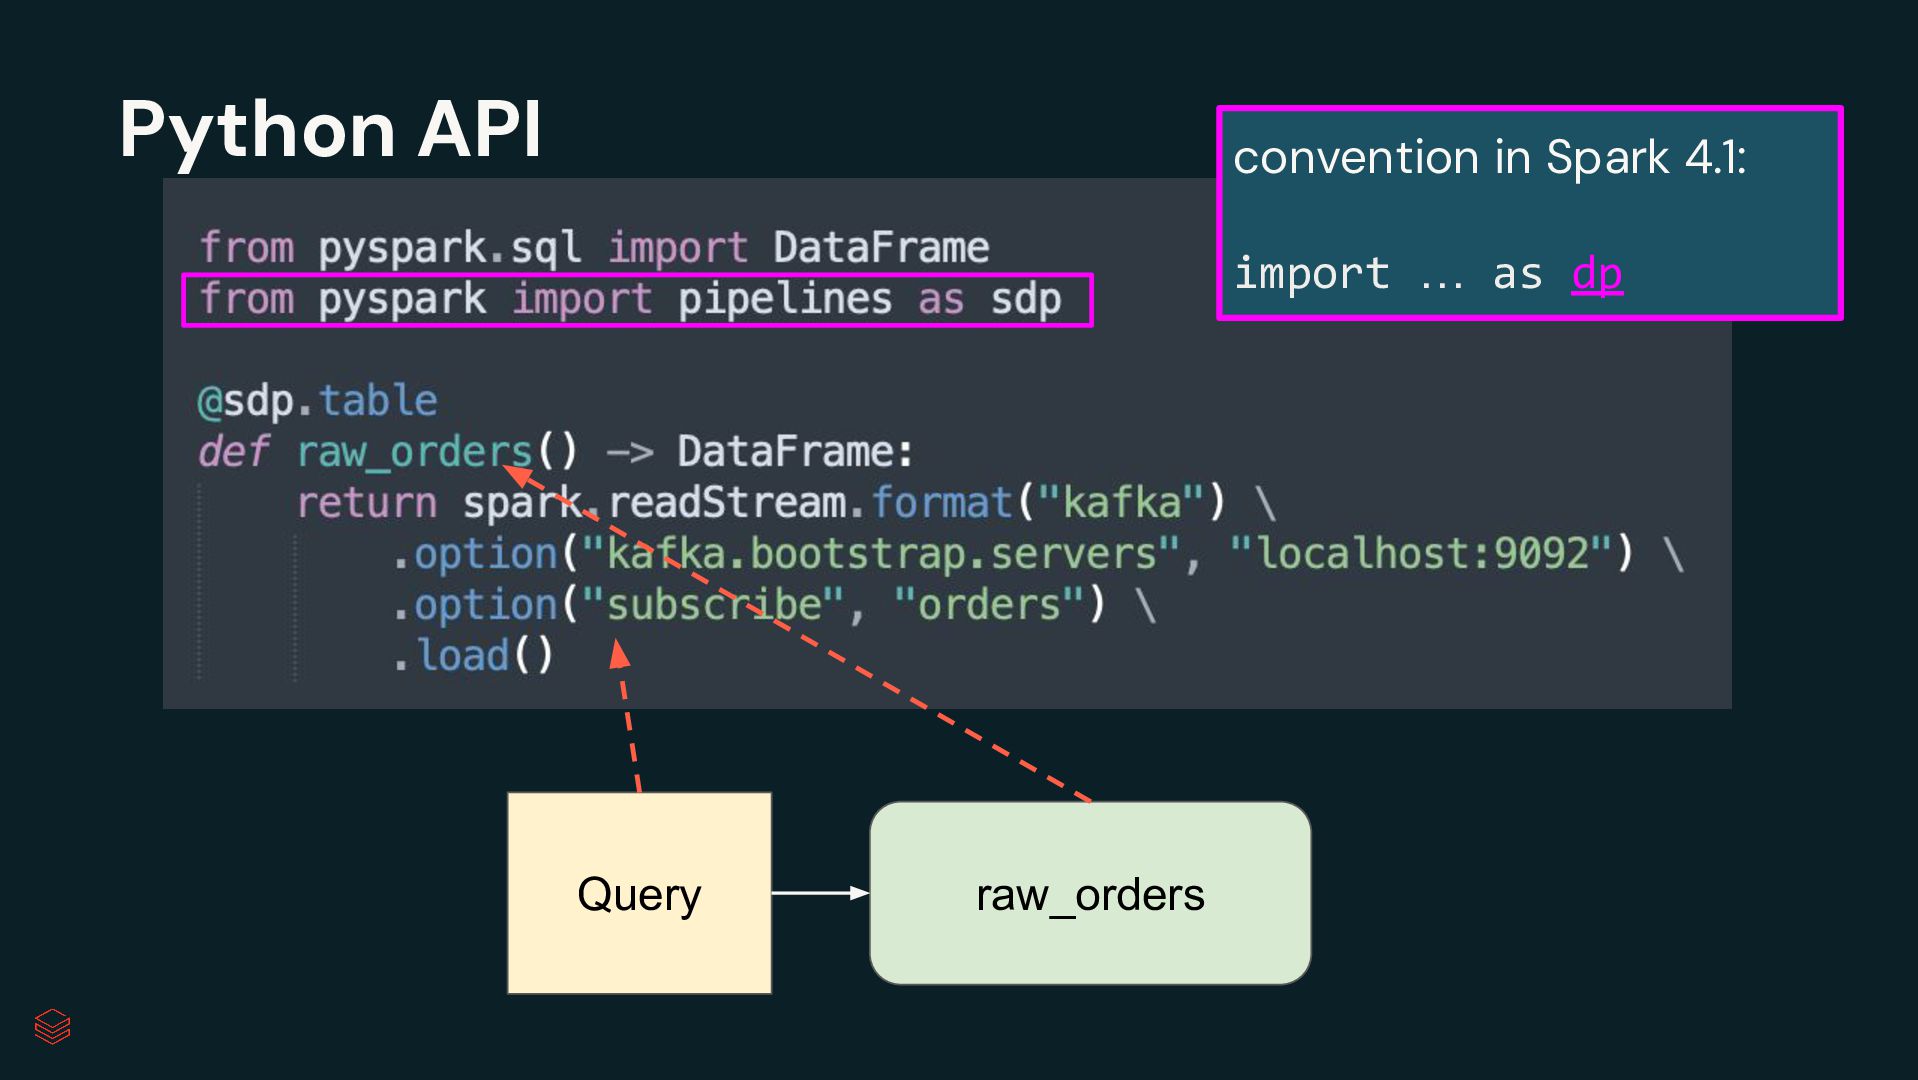
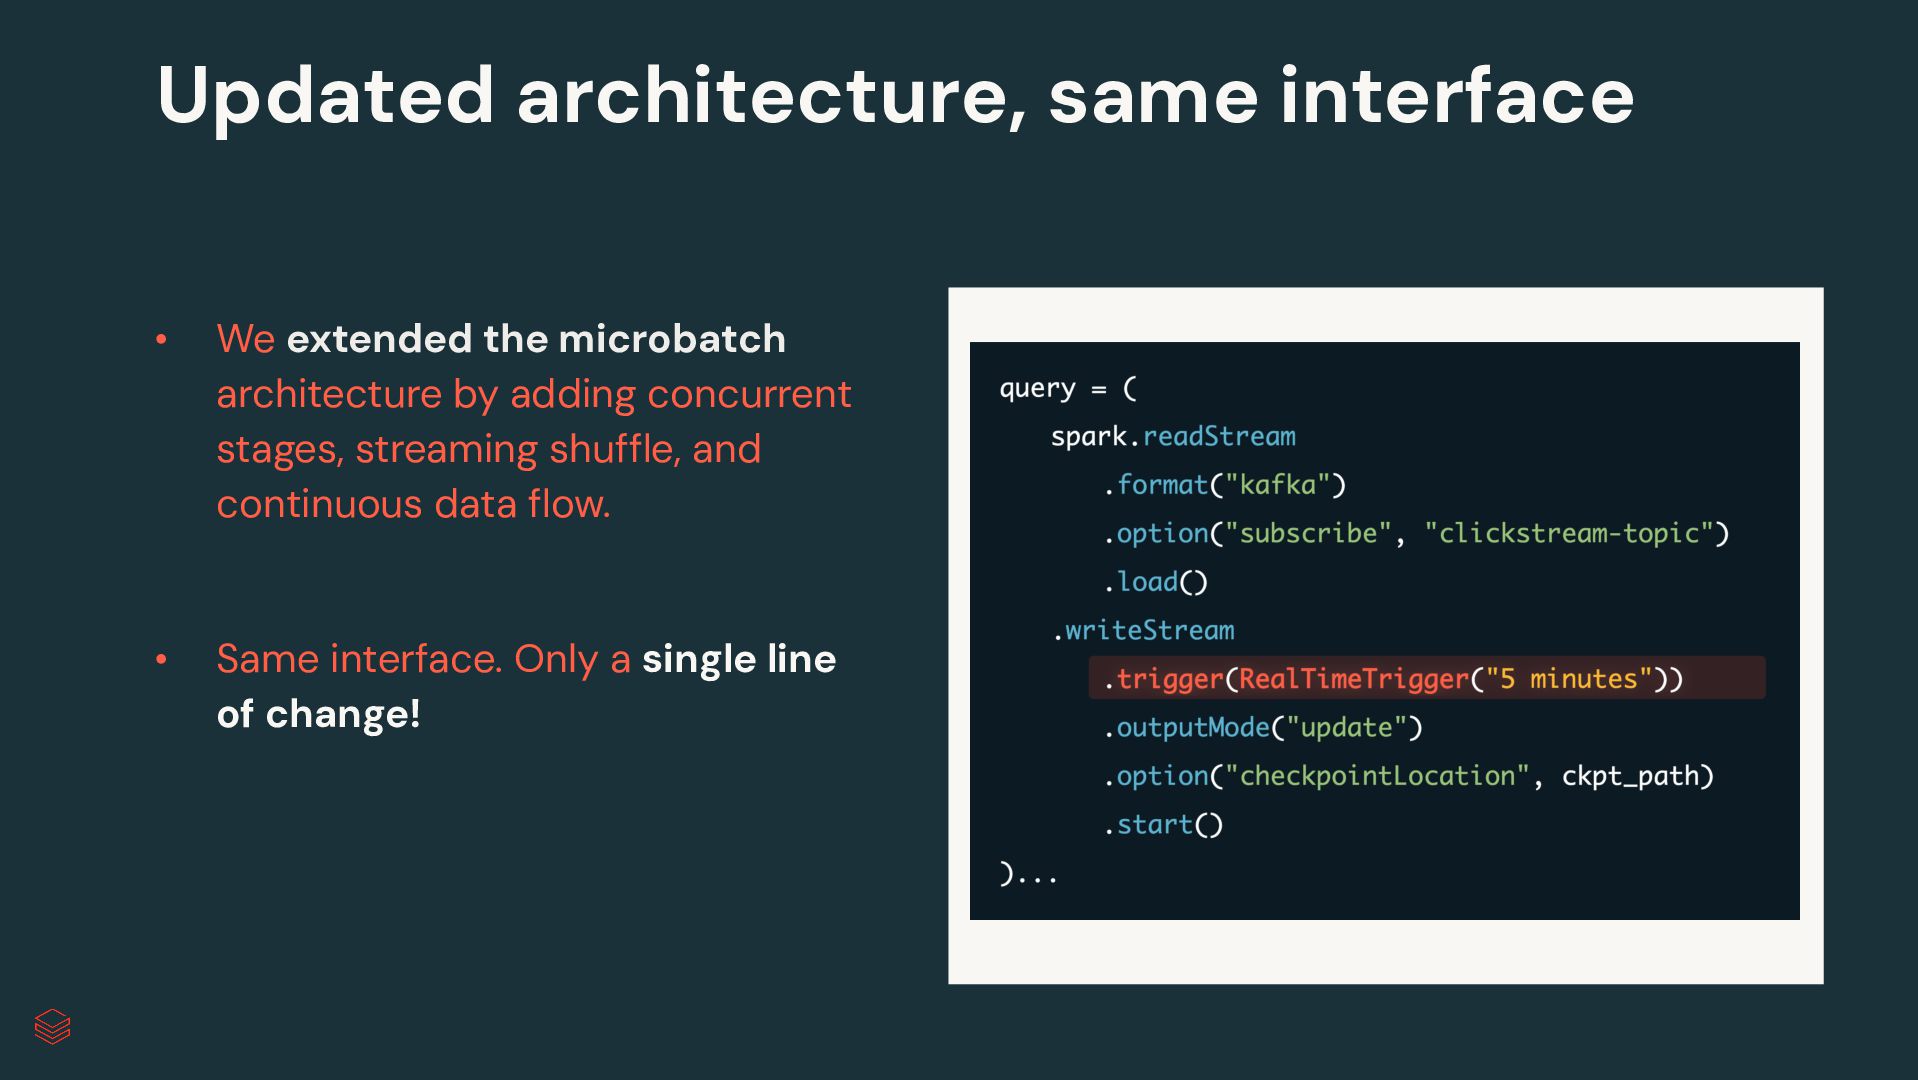
Built on concurrent stages, streaming shuffle, and continuous data flow • Same Spark platform -> makes external systems like Flink redundant • Building blocks: ◦ a source (message bus, rate) ◦ sinks (message bus, Lakebase, console) ◦ transformation use @dp.update_flow(...) -
Convert Messy Sales Data to AI insights databricks.com/demos Use Lakeflow
Connect, Jobs and SDP to create a marketing solution with AI for a global food corporation. Video Walkthrough with GitHub Repo + DABs 49 -
Get to know Genie Code Genie Code data engineering video
demo: Use Genie Code to create a complete SDP pipeline from a prompt. With Auto Loader, JSON ingestion, and medallion architecture. Genie Code Step by Step Guide 50 -
Zerobus Ingest Demo Zerobus Ingest demo: ingest streaming IoT events
without Kafka from all over the world