Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Dutch Data Summit - Set up your company for big...

Dutch Data Summit - Set up your company for big data product development

Set up your company for big data product development. 3 Lessons learnt at Adyen

Avatar for Guido Tournois

Guido Tournois

April 13, 2023

Other Decks in Technology

Transcript

  1. Our scale Global footprint: EMEA, NA, LATAM, APAC Volume: €767.5

    Billion processed volume Customers: 200k+ merchants Last peak season, we served 1B+ API events per day
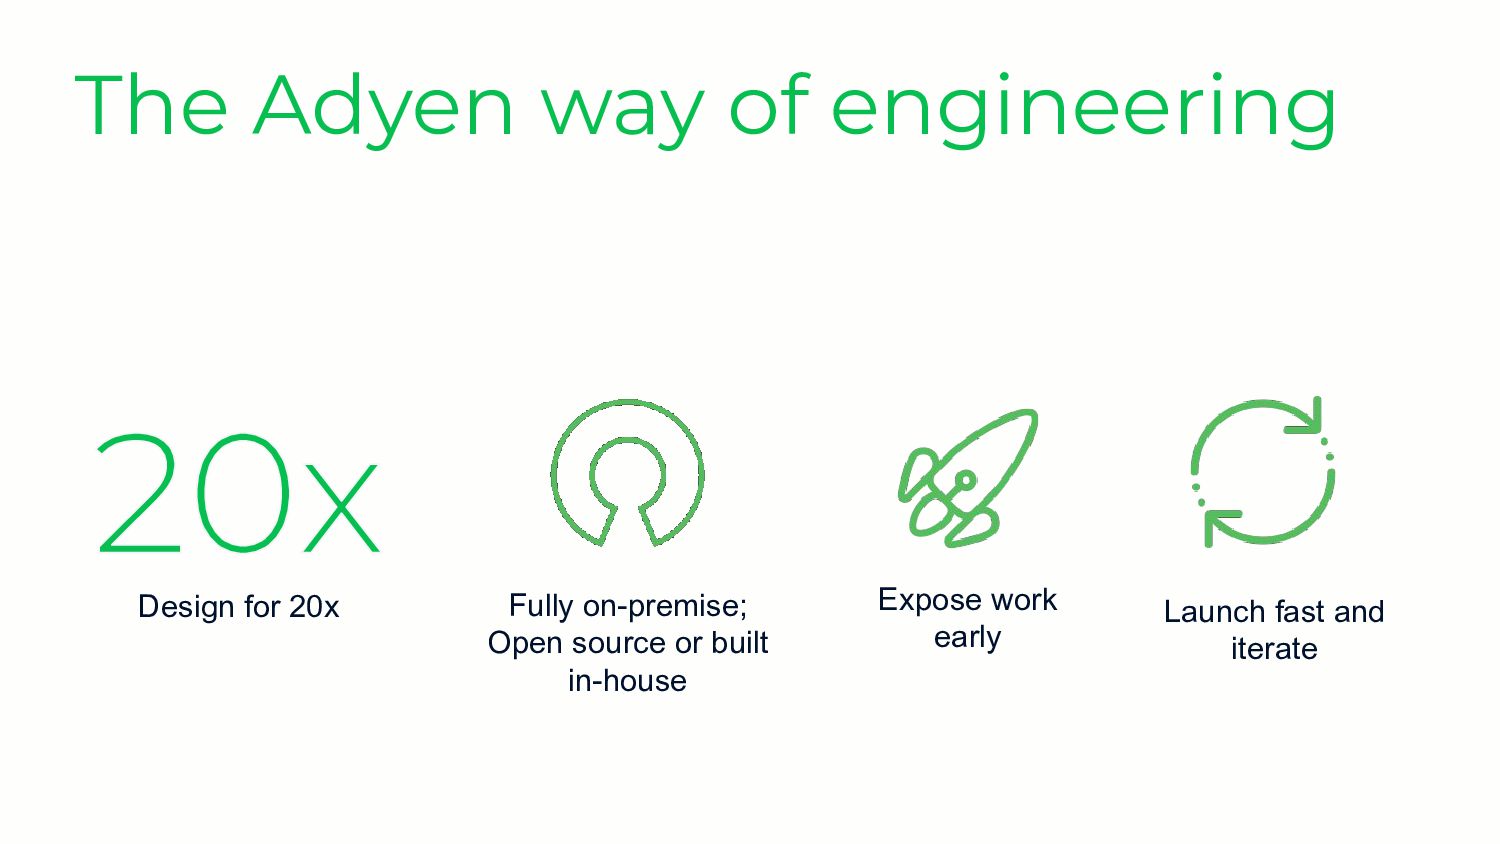
  2. The Adyen way of engineering Expose work early Design for

    20x Fully on-premise; Open source or built in-house Launch fast and iterate
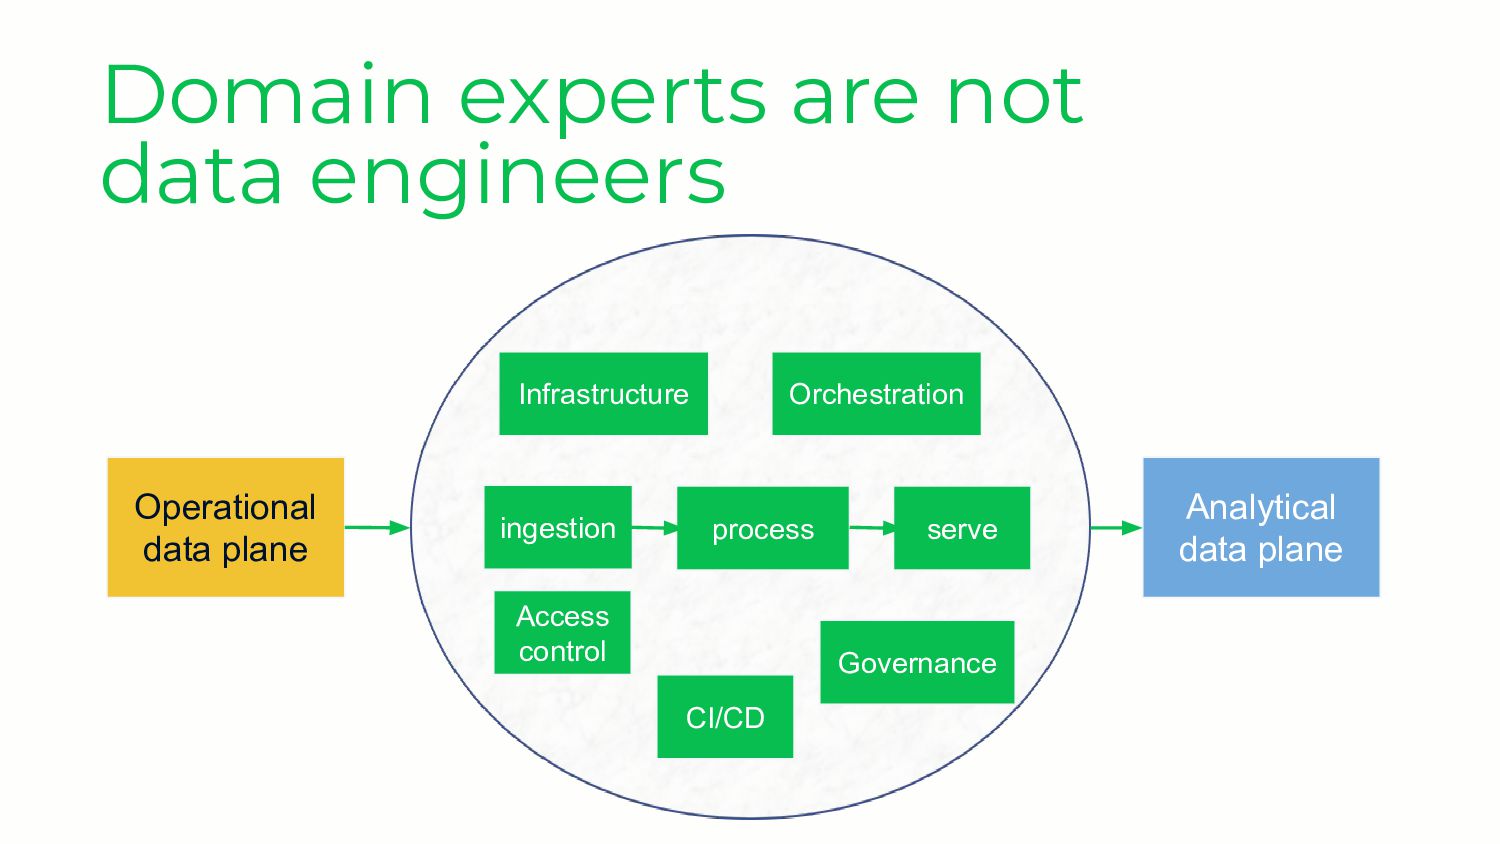
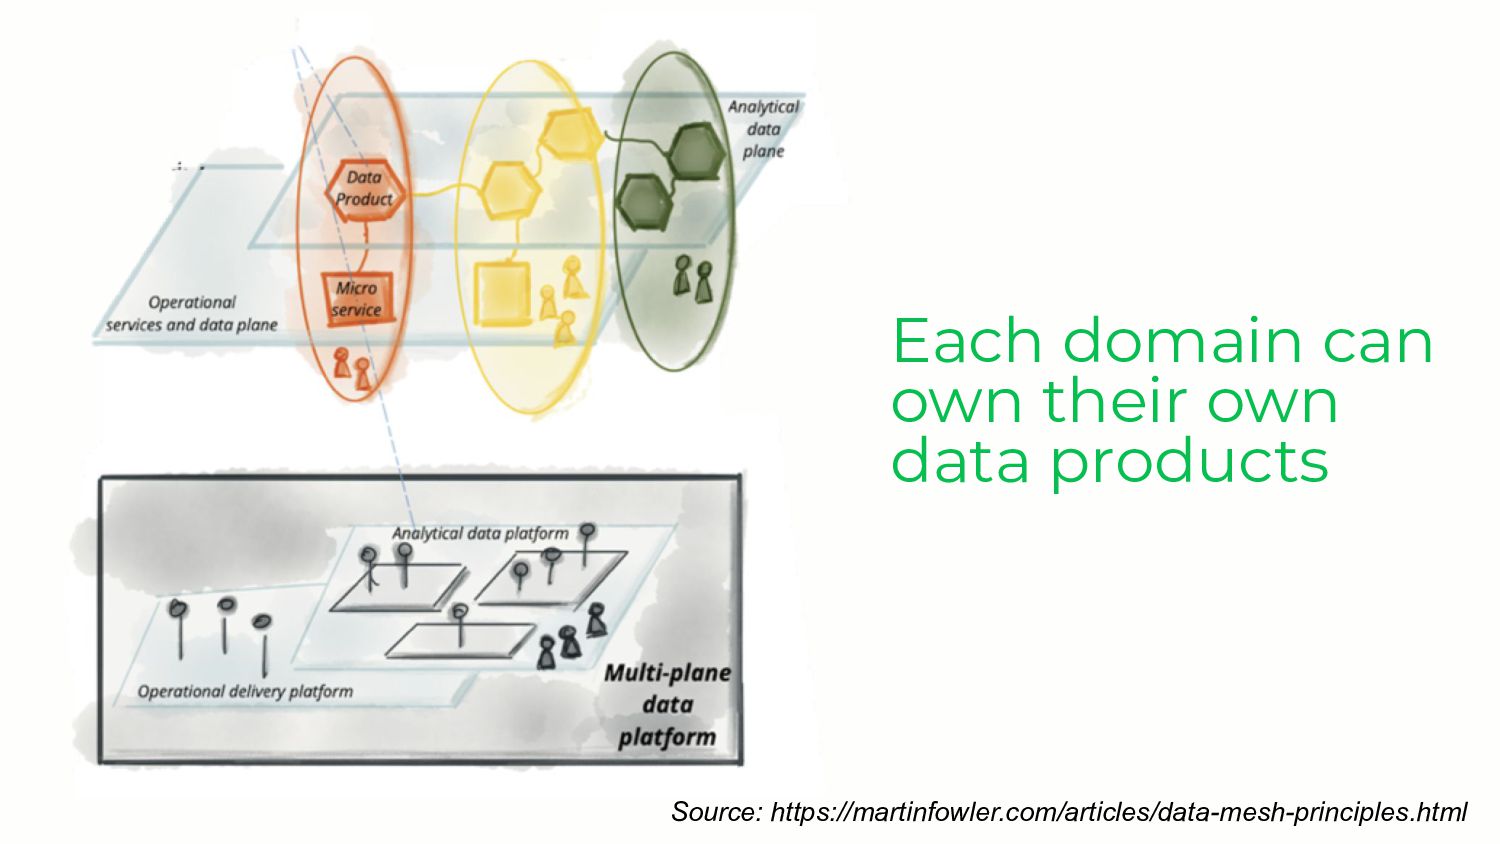
  3. Domain experts are not data engineers Operational data plane Analytical

    data plane ingestion process Governance serve Access control CI/CD Infrastructure Orchestration
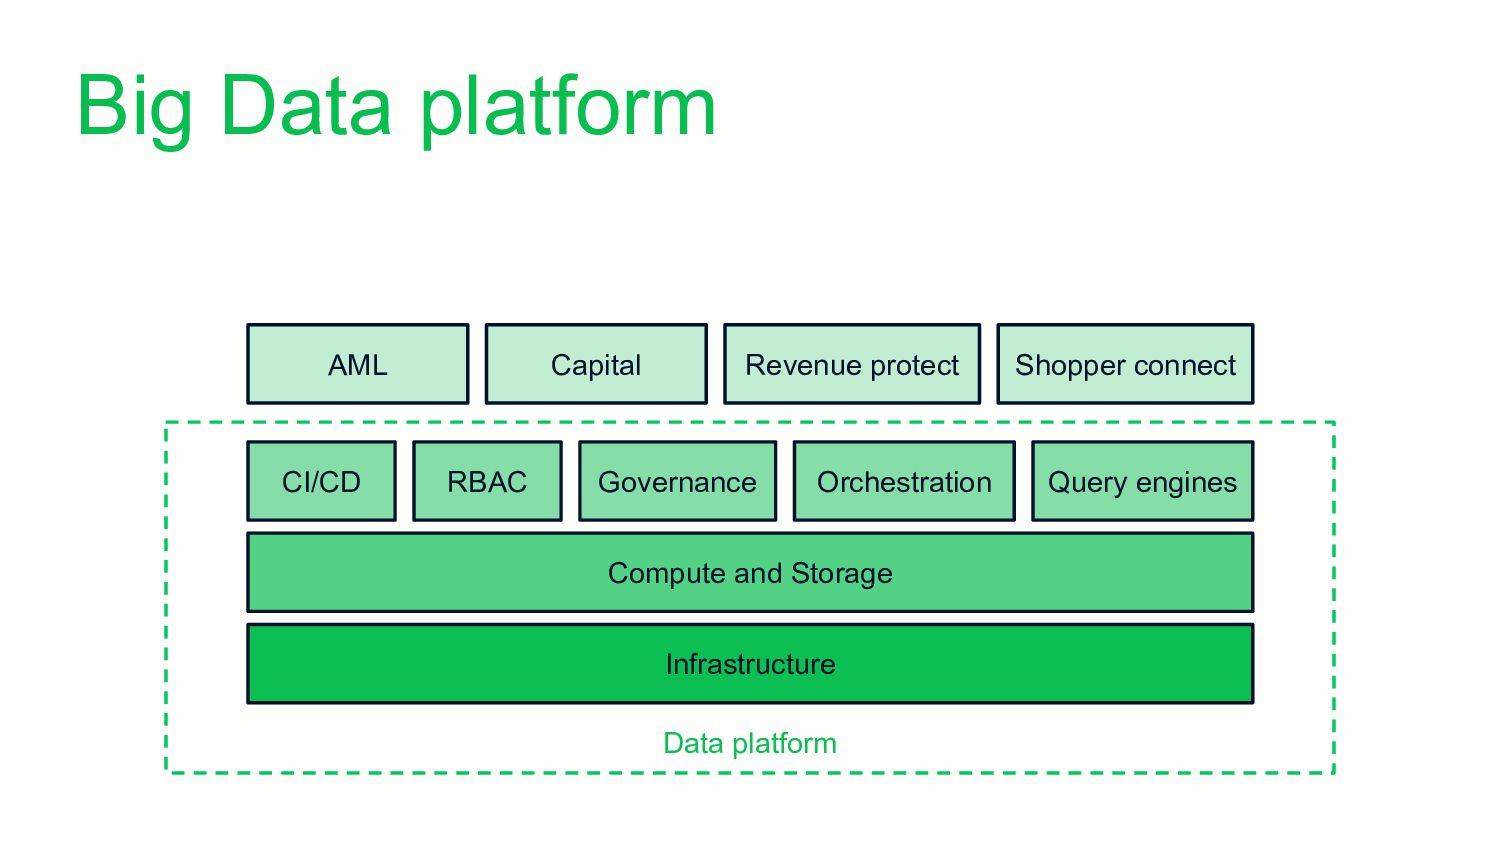
  4. Data platform Big Data platform Infrastructure Compute and Storage CI/CD

    RBAC Governance Orchestration Query engines AML Capital Revenue protect Shopper connect
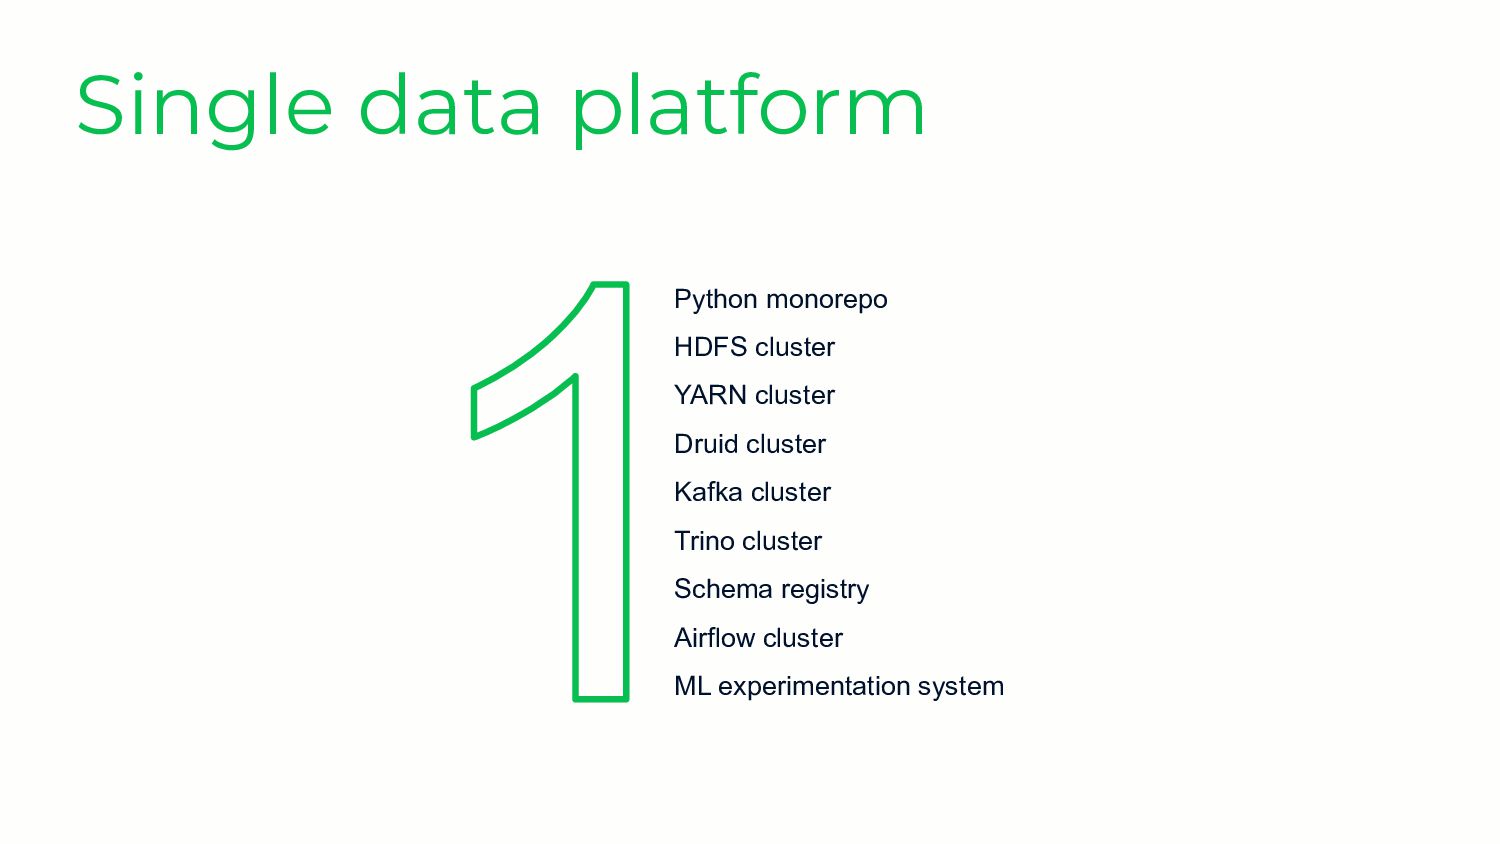
  5. Single data platform Python monorepo HDFS cluster YARN cluster Druid

    cluster Kafka cluster Trino cluster Schema registry Airflow cluster ML experimentation system
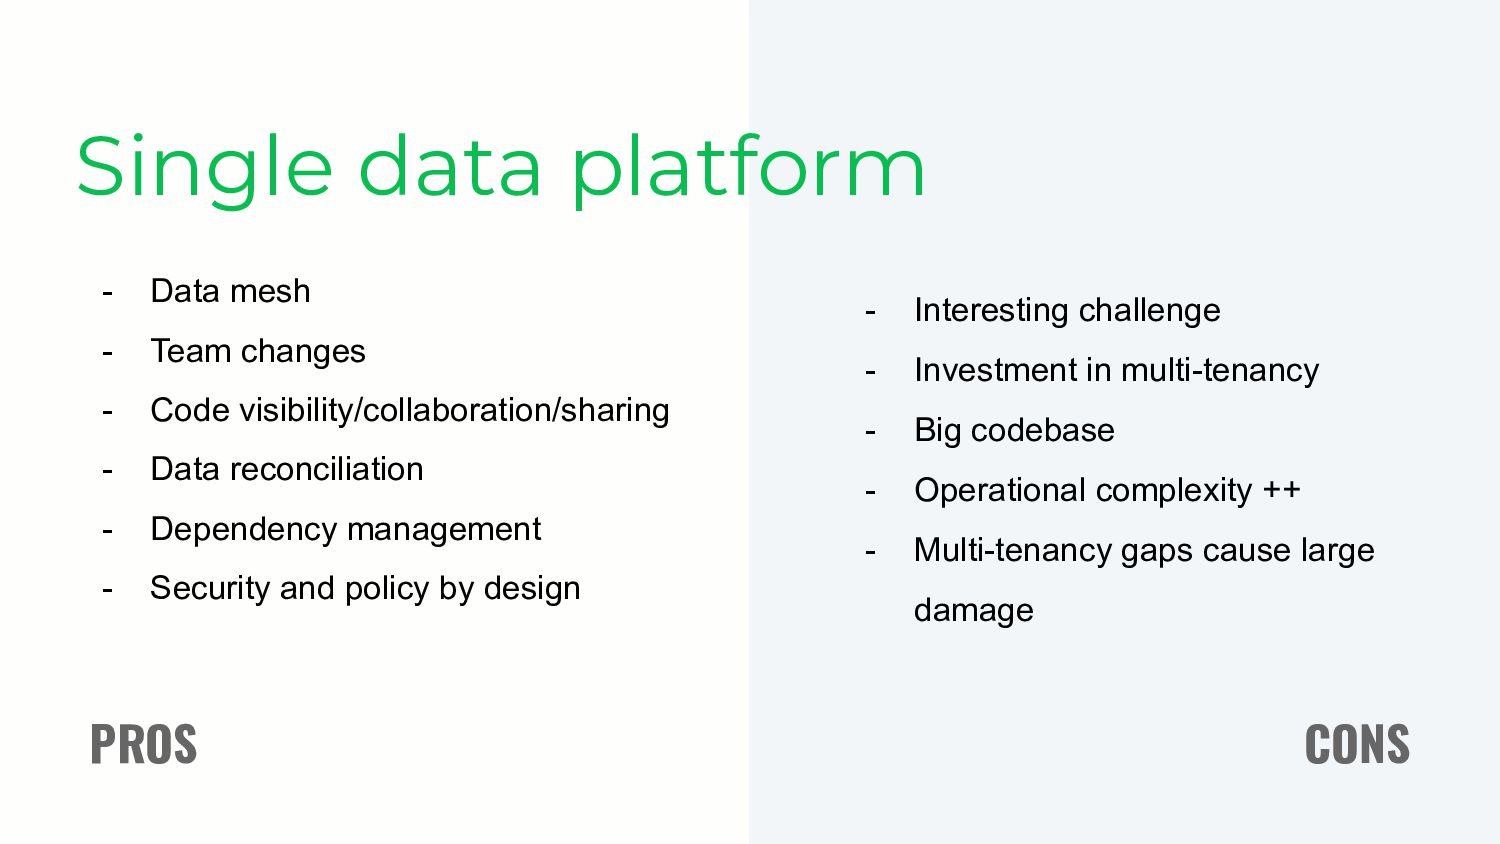
  6. - Data mesh - Team changes - Code visibility/collaboration/sharing -

    Data reconciliation - Dependency management - Security and policy by design Single data platform PROS CONS - Interesting challenge - Investment in multi-tenancy - Big codebase - Operational complexity ++ - Multi-tenancy gaps cause large damage
  7. Adyen’s big data Platform 25+ live data products 10s of

    ML models 200+ daily developers (39 teams) 2000+ daily active users And some numbers Hundreds of machines Thousands of CPU cores Terabytes of RAM Petabytes of storage capacity
  8. Self-service the platform teams Product success requires platform success Product

    speed requires platform speed Product scalability requires platform scalability Product security requires platform security
  9. Self-service the platform teams - Self-servicing ourselves - Infra-as-a-service -

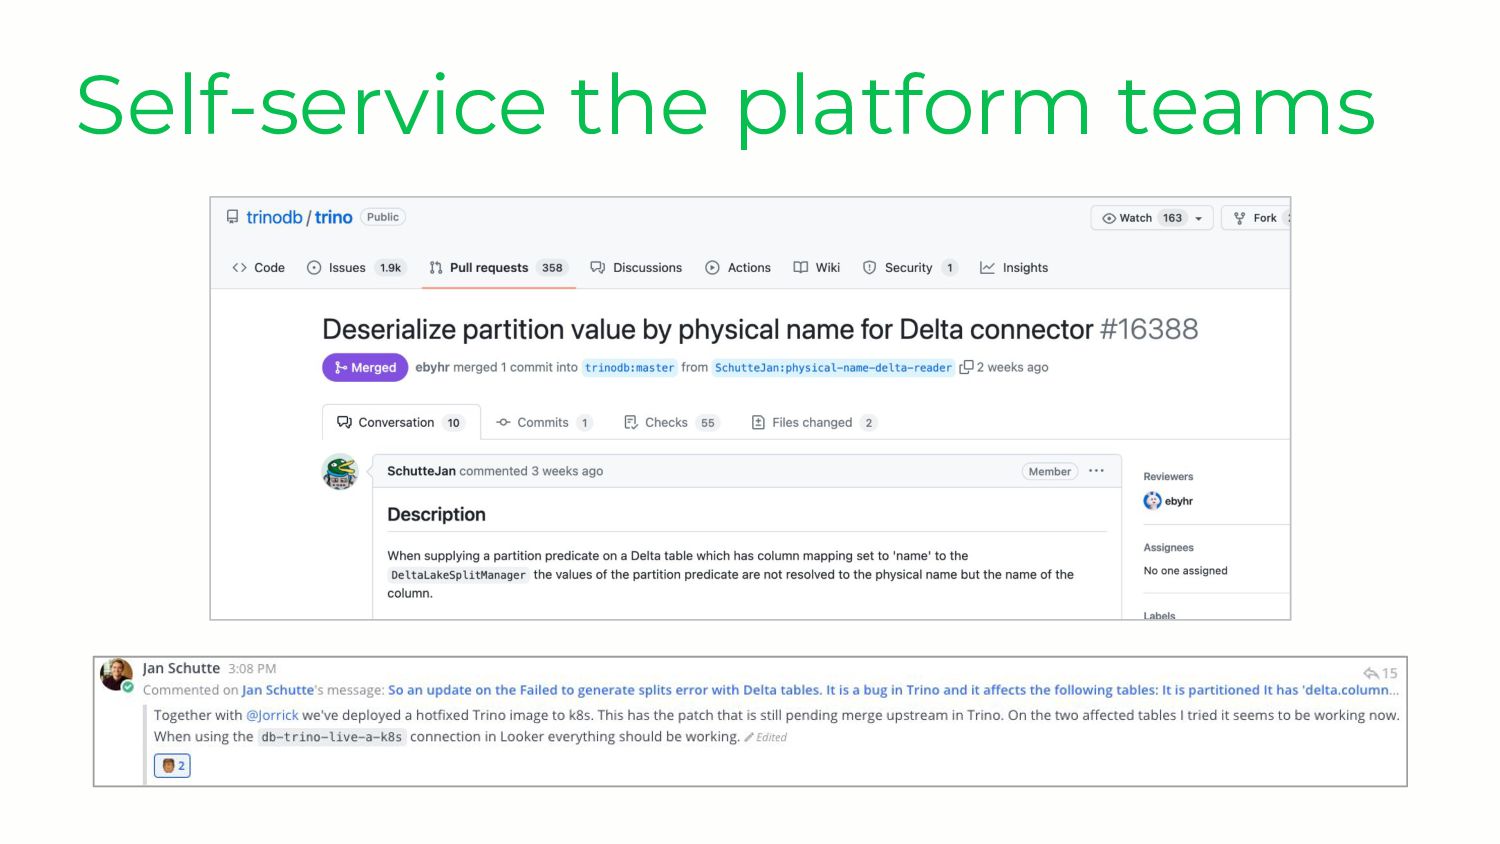
    Virtualization and orchestration e.g. Kubernetes - We are a bank, heavily regulated; elevated access is not possible - Experimentation is expensive, if you direct access to hardware/networking/firewalls/etc - Started a migration to Kubernetes - 7 months in, 40% done, already big wins. - Current focus is compute (Trino, Spark) and services
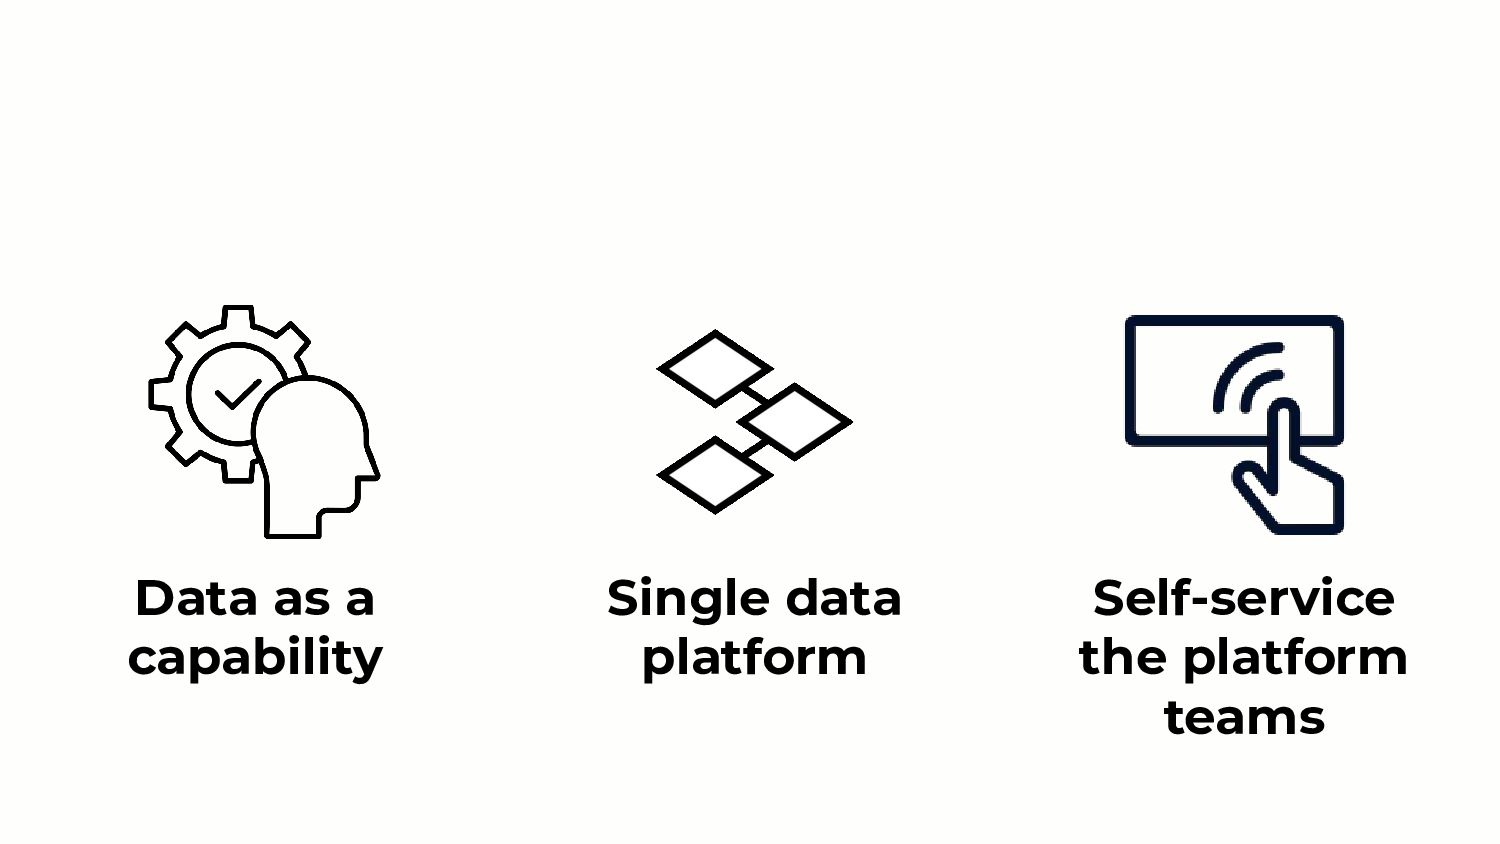
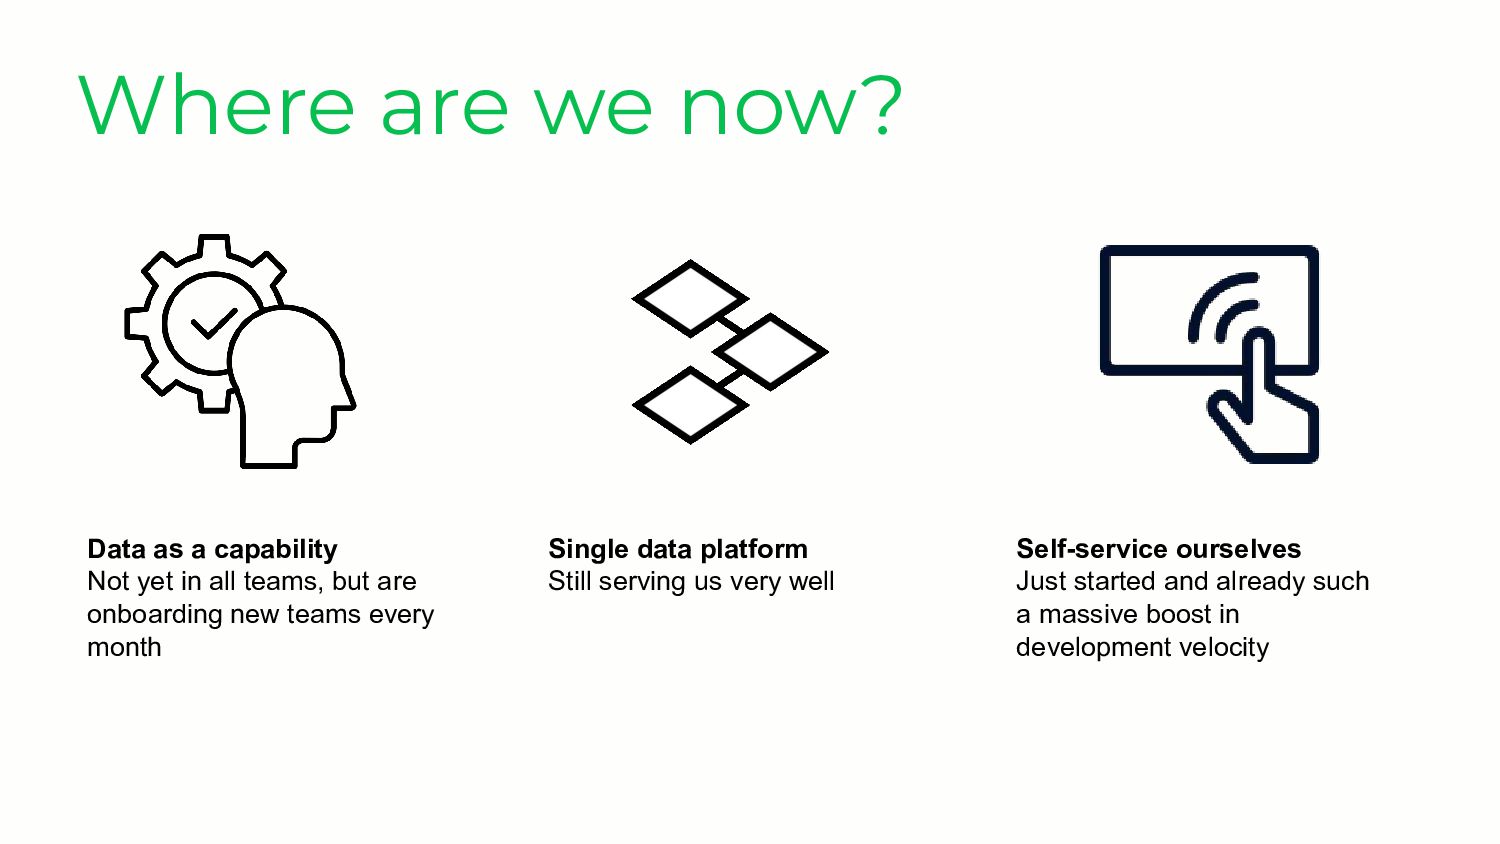
  10. Where are we now? Data as a capability Not yet

    in all teams, but are onboarding new teams every month Single data platform Still serving us very well Self-service ourselves Just started and already such a massive boost in development velocity