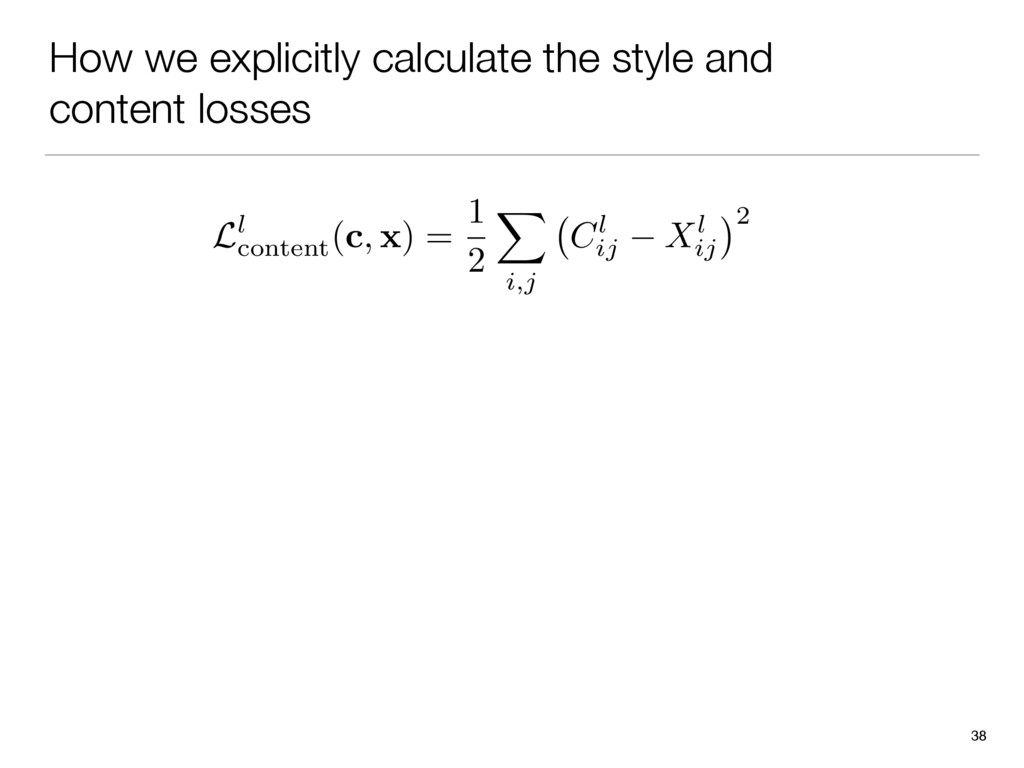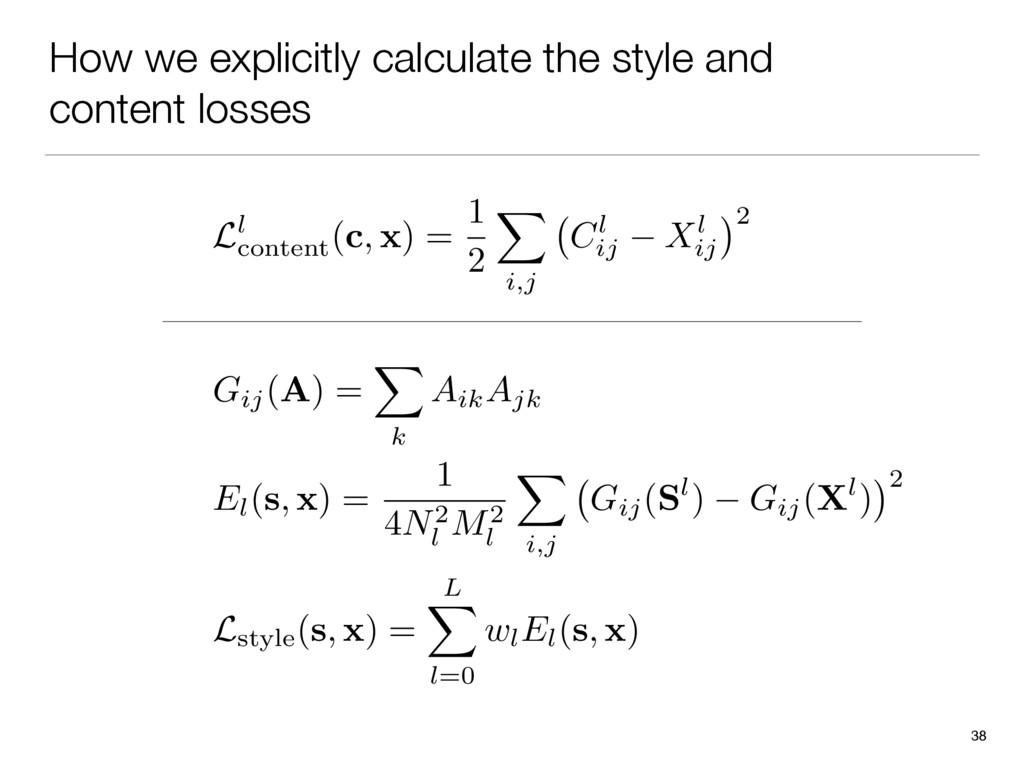Share
Embed
Convolutional Neural Networks for Artistic Style Transfer
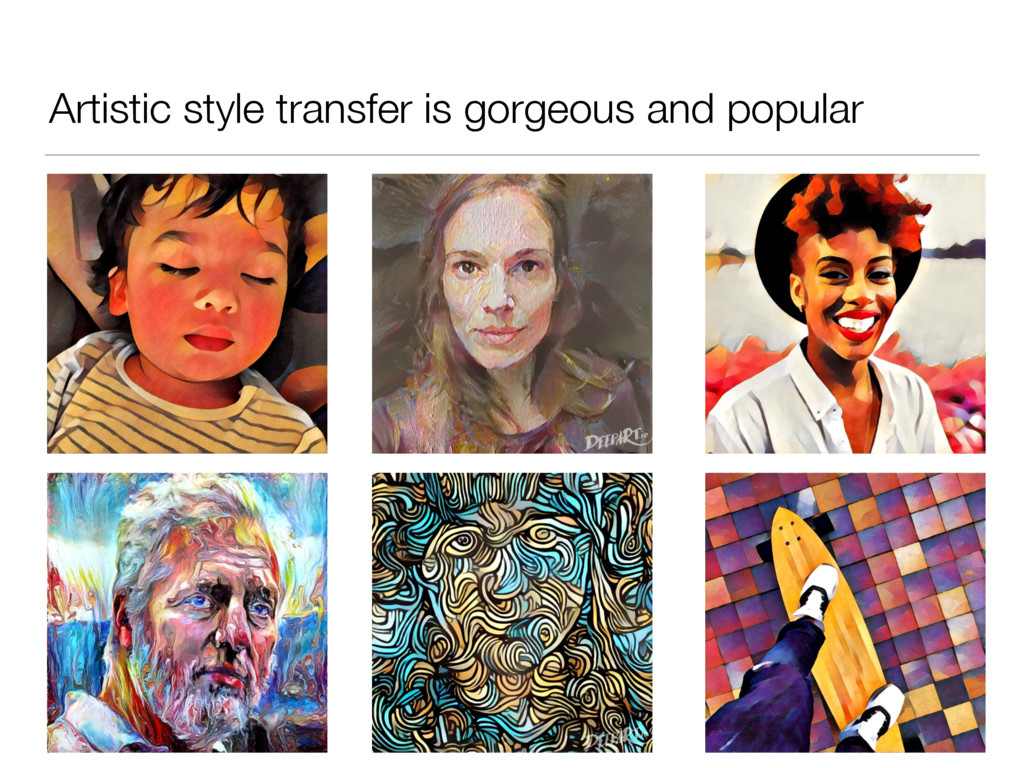
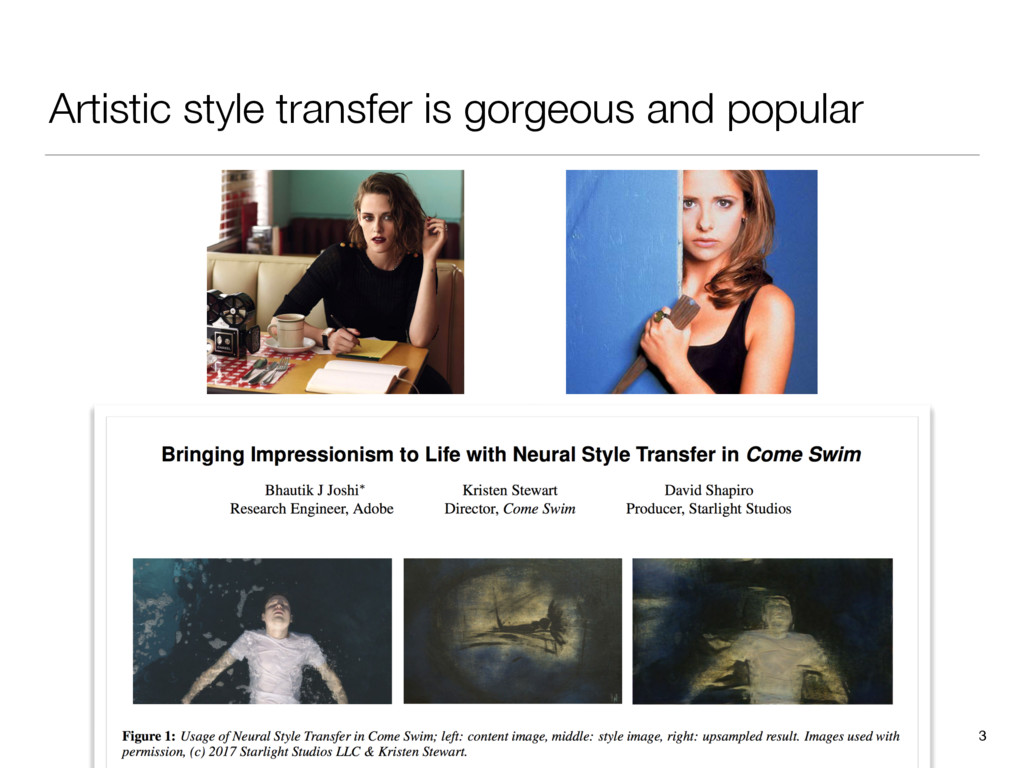
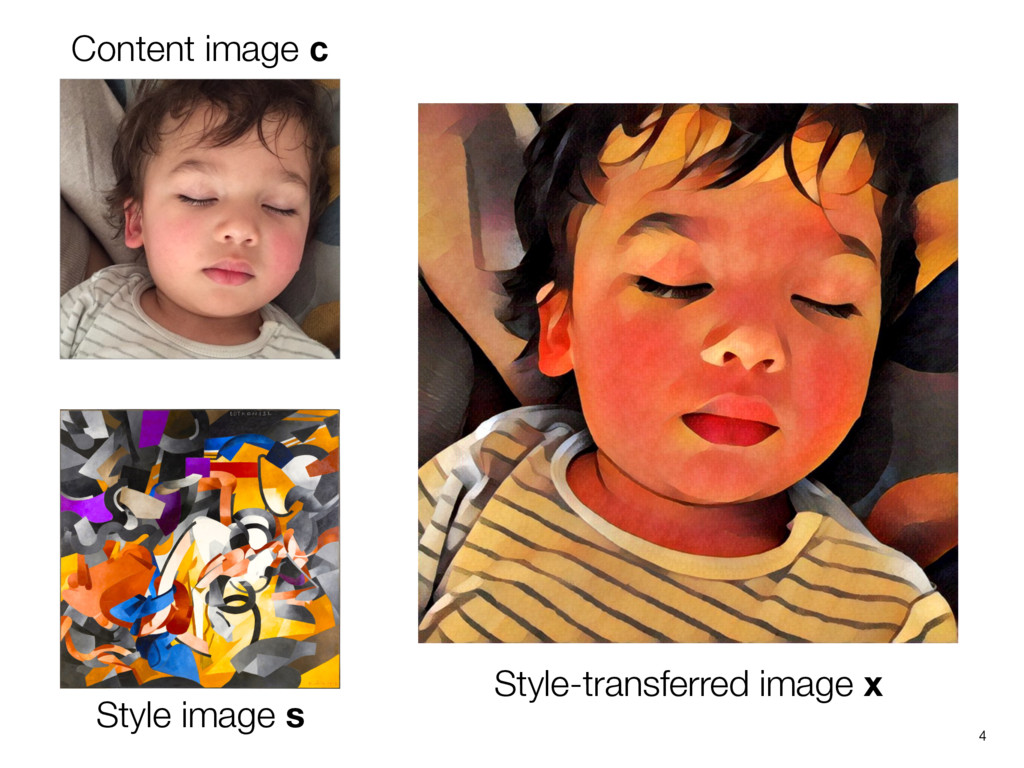
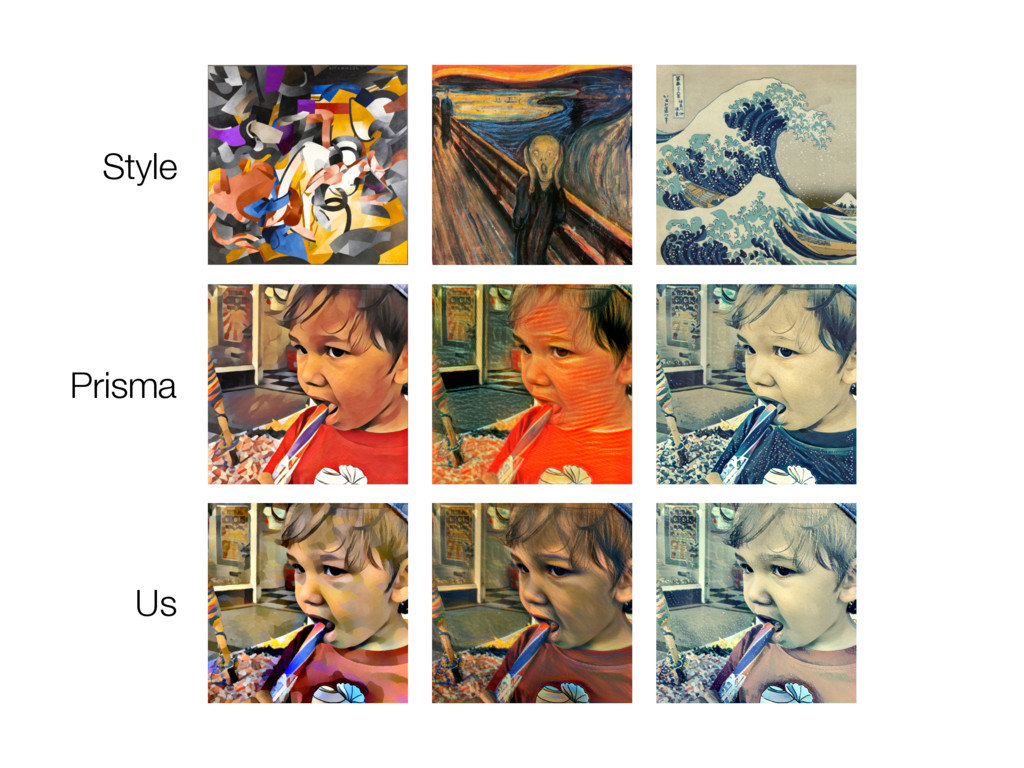
There’s an amazing app out right now called Prisma that transforms your photos into works of art using the styles of famous artwork and motifs. The app performs this style transfer with the help of a branch of machine learning called convolutional neural networks. In this talk we take a journey through the world of convolutional neural networks from theory to practice, as we systematically reproduce Prisma’s core visual effect.
Harish Narayanan
February 21, 2017
Transcript
103 slides
-
Convolutional Neural Networks for Artistic Style Transfer Harish Narayanan @copingbear
harishnarayanan.org/writing/artistic-style-transfer github.com/hnarayanan/artistic-style-transfer -
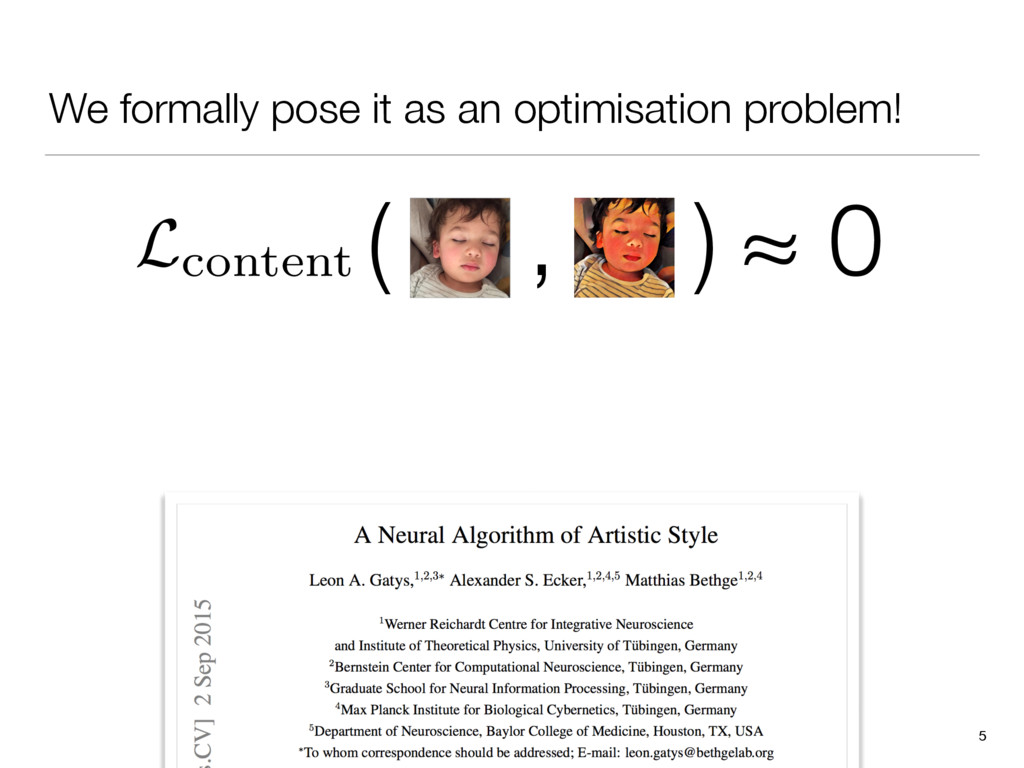
We formally pose it as an optimisation problem! 5 L
content ( ) ≈ 0 , -
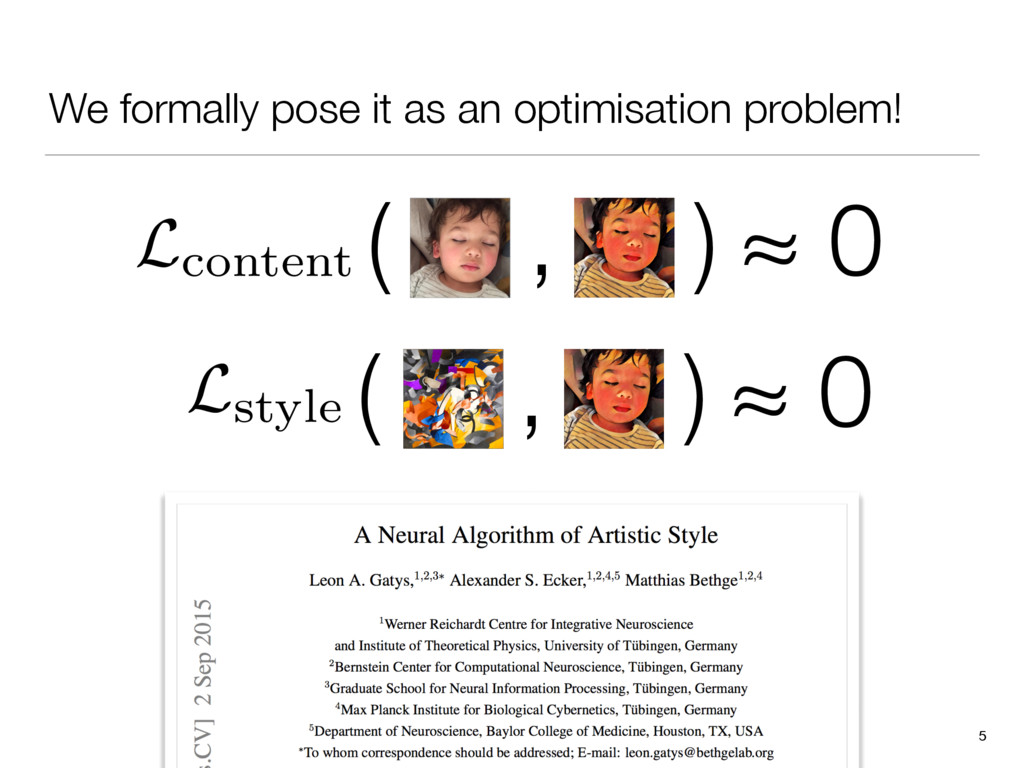
We formally pose it as an optimisation problem! 5 L
content ( ) ≈ 0 , ( ) ≈ 0 , Lstyle -
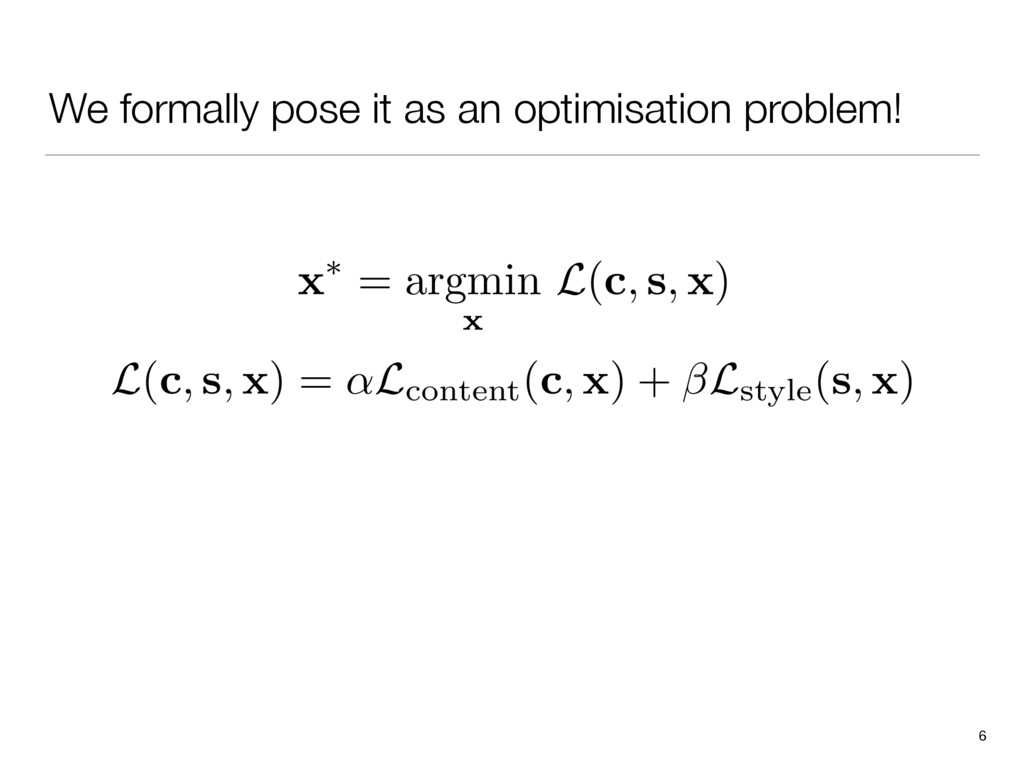
We formally pose it as an optimisation problem! L( c
, s , x ) = ↵L content ( c , x ) + L style ( s , x ) 6 x ⇤ = argmin x L( c , s , x ) -
We formally pose it as an optimisation problem! L( c
, s , x ) = ↵L content ( c , x ) + L style ( s , x ) 6 x ⇤ = argmin x L( c , s , x ) ⭐ Content and style losses are not defined in a per-pixel difference sense, but higher-level semantic differences! -
But then how does one write a program to perceive
semantic differences?!? 7 -
But then how does one write a program to perceive
semantic differences?!? 7 ⭐ We don’t! We turn to machine learning. -
But then how does one write a program to perceive
semantic differences?!? • Image classification problem (linear ➞ neural network ➞ convnet) 7 ⭐ We don’t! We turn to machine learning. -
But then how does one write a program to perceive
semantic differences?!? • Image classification problem (linear ➞ neural network ➞ convnet) • Break 7 ⭐ We don’t! We turn to machine learning. -
But then how does one write a program to perceive
semantic differences?!? • Image classification problem (linear ➞ neural network ➞ convnet) • Break • Download a pre-trained convnet classifier, and repurpose it for style transfer 7 ⭐ We don’t! We turn to machine learning. -
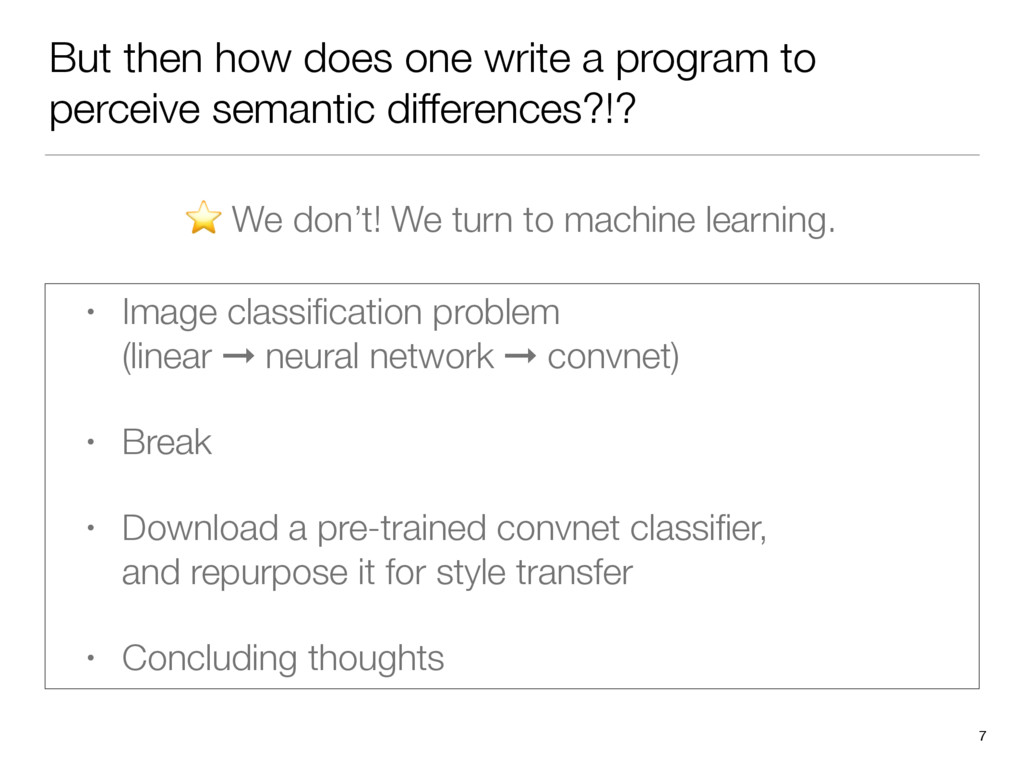
But then how does one write a program to perceive
semantic differences?!? • Image classification problem (linear ➞ neural network ➞ convnet) • Break • Download a pre-trained convnet classifier, and repurpose it for style transfer • Concluding thoughts 7 ⭐ We don’t! We turn to machine learning. -
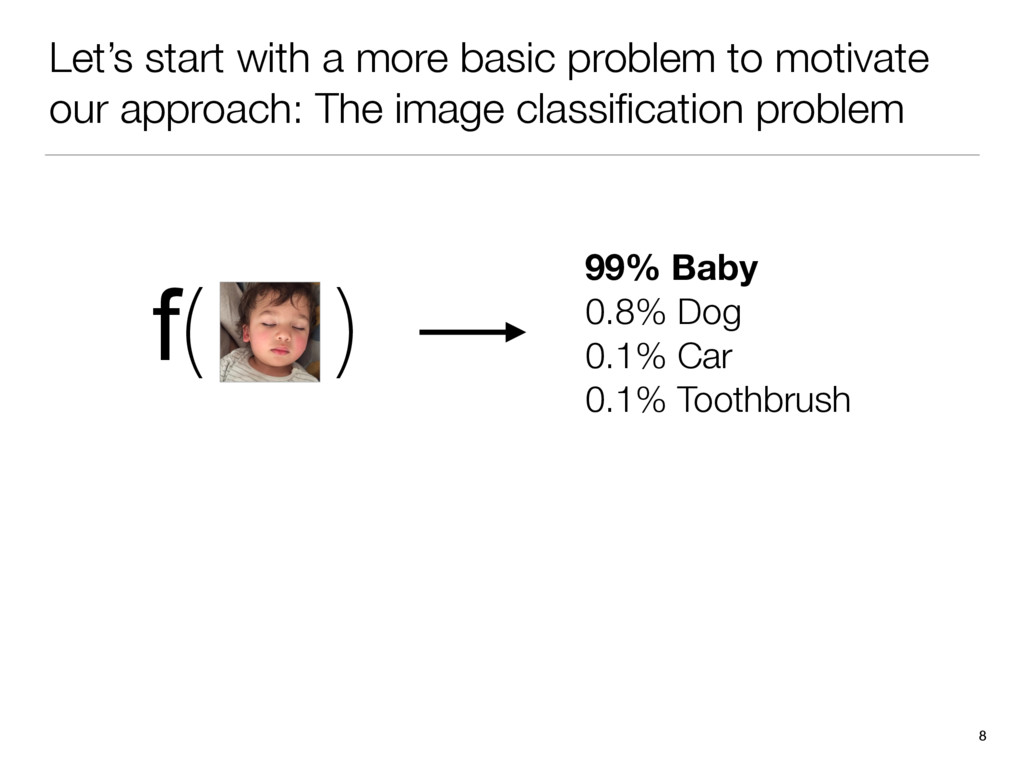
Let’s start with a more basic problem to motivate our
approach: The image classification problem 8 f( ) 99% Baby 0.8% Dog 0.1% Car 0.1% Toothbrush -
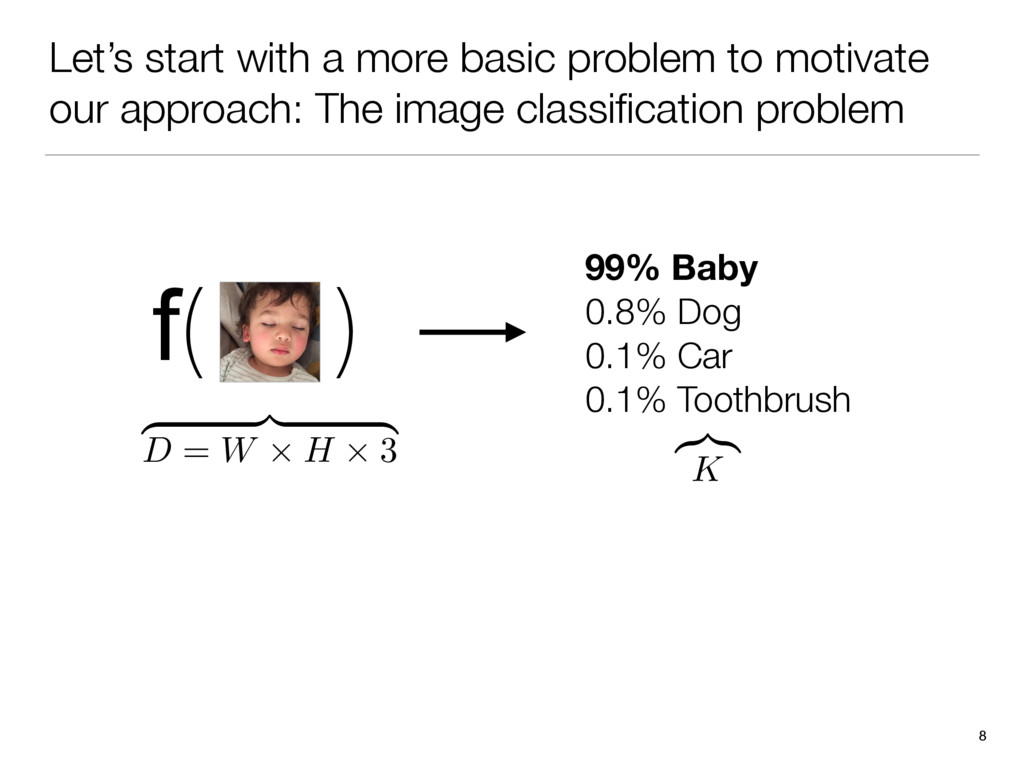
Let’s start with a more basic problem to motivate our
approach: The image classification problem 8 f( ) 99% Baby 0.8% Dog 0.1% Car 0.1% Toothbrush z }| { D = W ⇥ H ⇥ 3 z}|{ K -
⭐ There is a semantic gap between the input representation
and the task at hand -
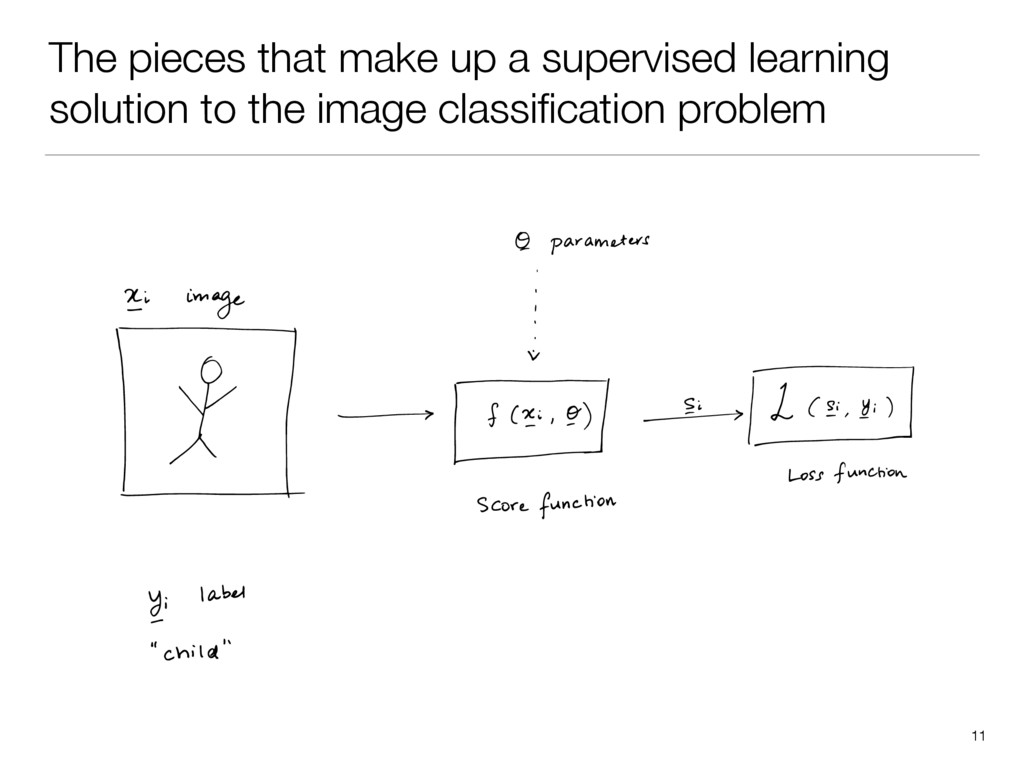
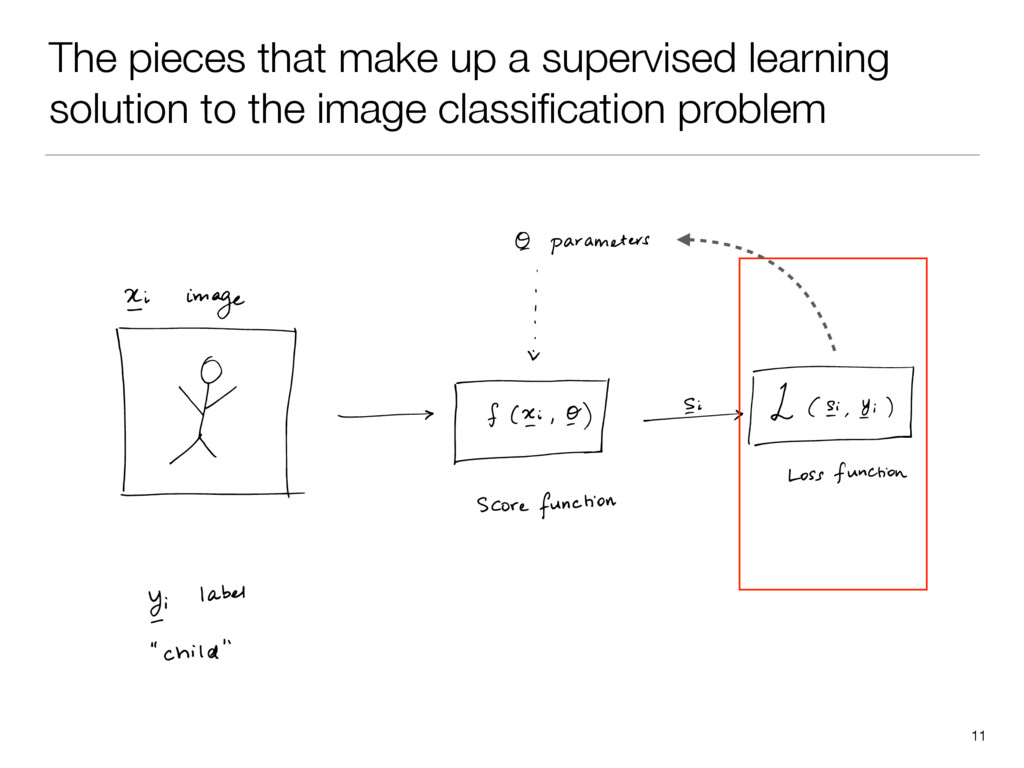
The pieces that make up a supervised learning solution to
the image classification problem 11 -
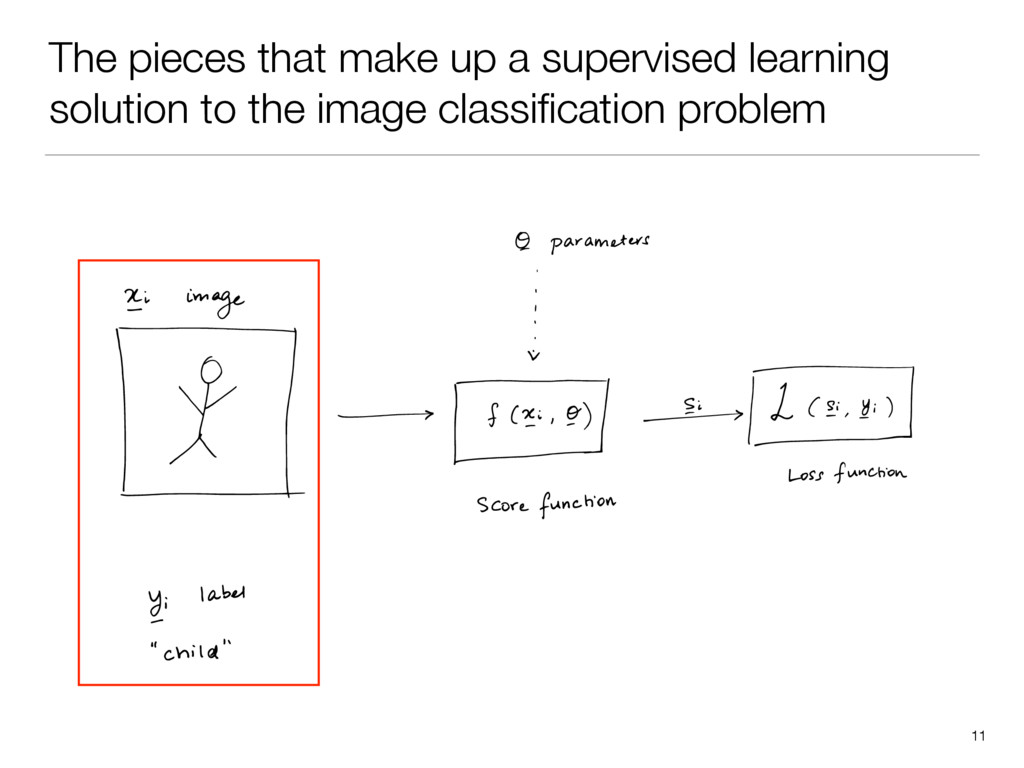
The pieces that make up a supervised learning solution to
the image classification problem 11 -
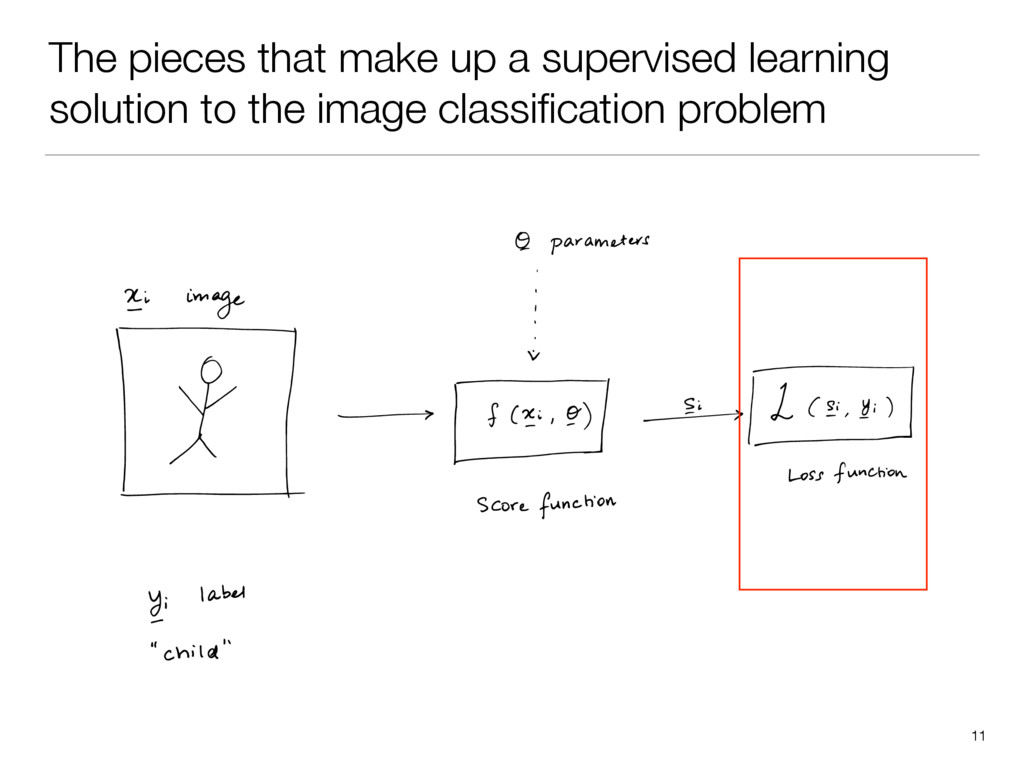
The pieces that make up a supervised learning solution to
the image classification problem 11 -
The pieces that make up a supervised learning solution to
the image classification problem 11 -
The pieces that make up a supervised learning solution to
the image classification problem 11 -
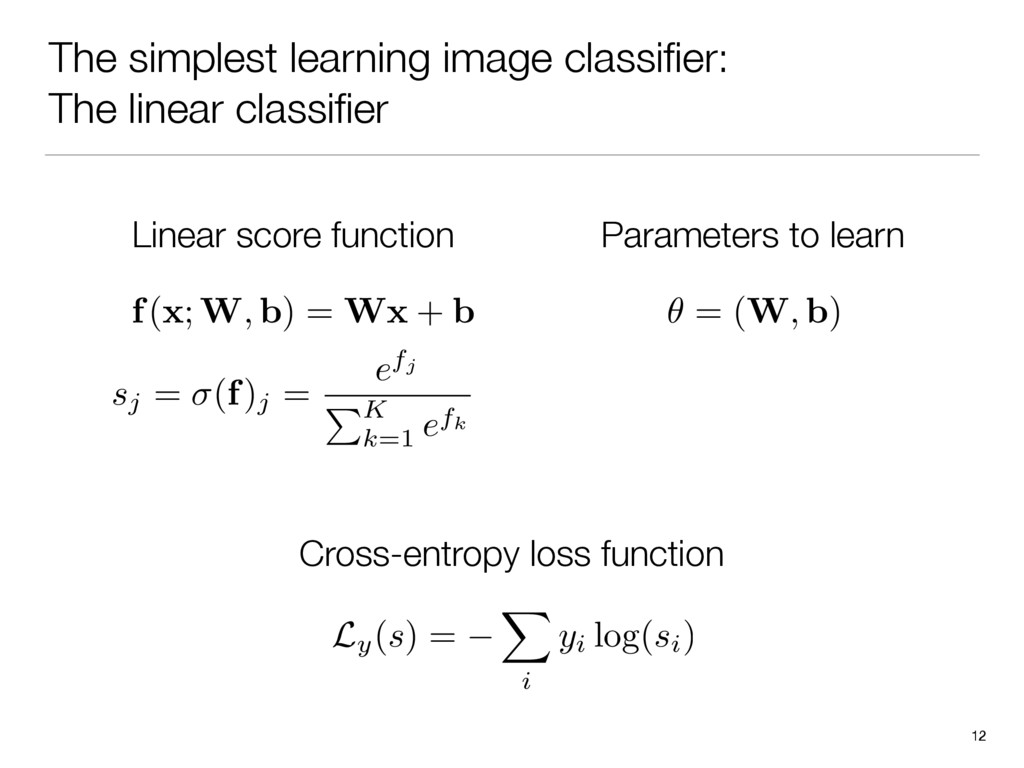
The simplest learning image classifier: The linear classifier 12 f
( x ; W , b ) = Wx + b sj = ( f )j = efj PK k=1 efk ✓ = (W, b) Linear score function Parameters to learn -
The simplest learning image classifier: The linear classifier 12 f
( x ; W , b ) = Wx + b sj = ( f )j = efj PK k=1 efk ✓ = (W, b) Linear score function Parameters to learn Cross-entropy loss function Ly( s ) = X i yi log( si) -
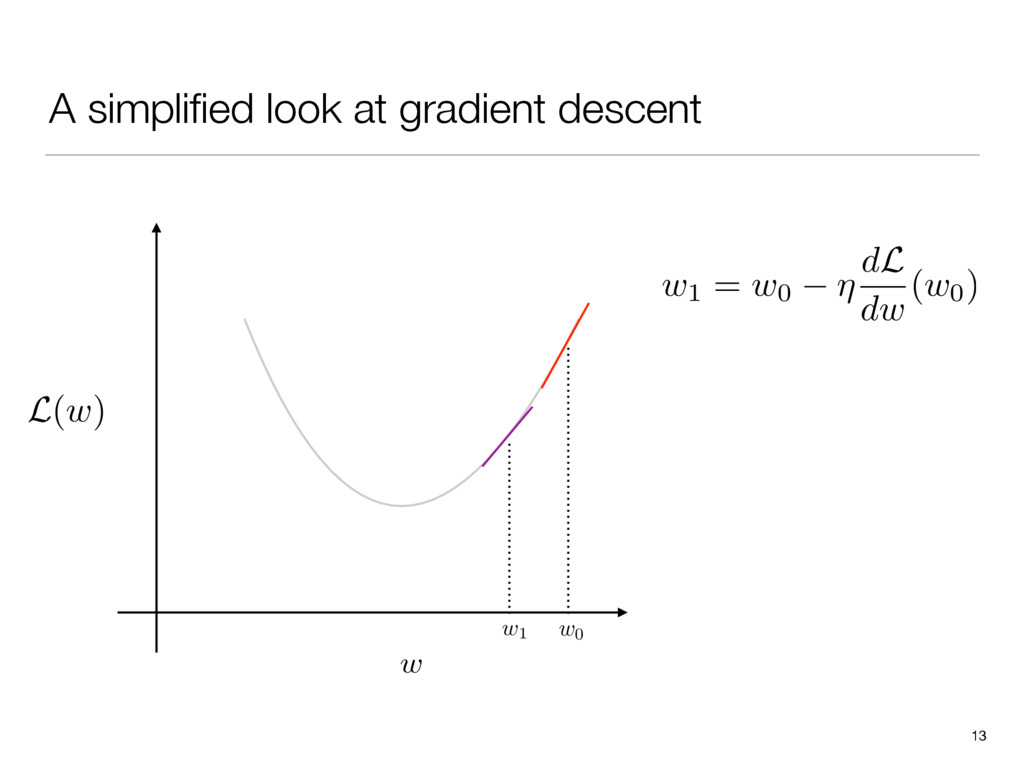
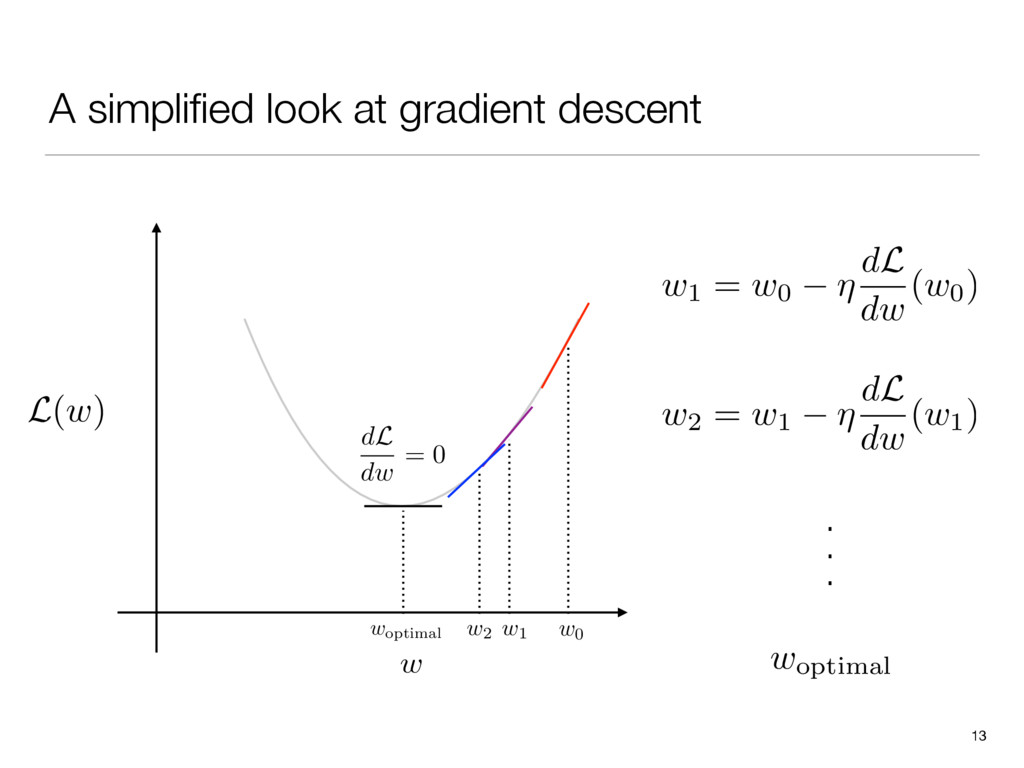
A simplified look at gradient descent 13 L(w) w w0
w1 w1 = w0 ⌘ dL dw (w0) -
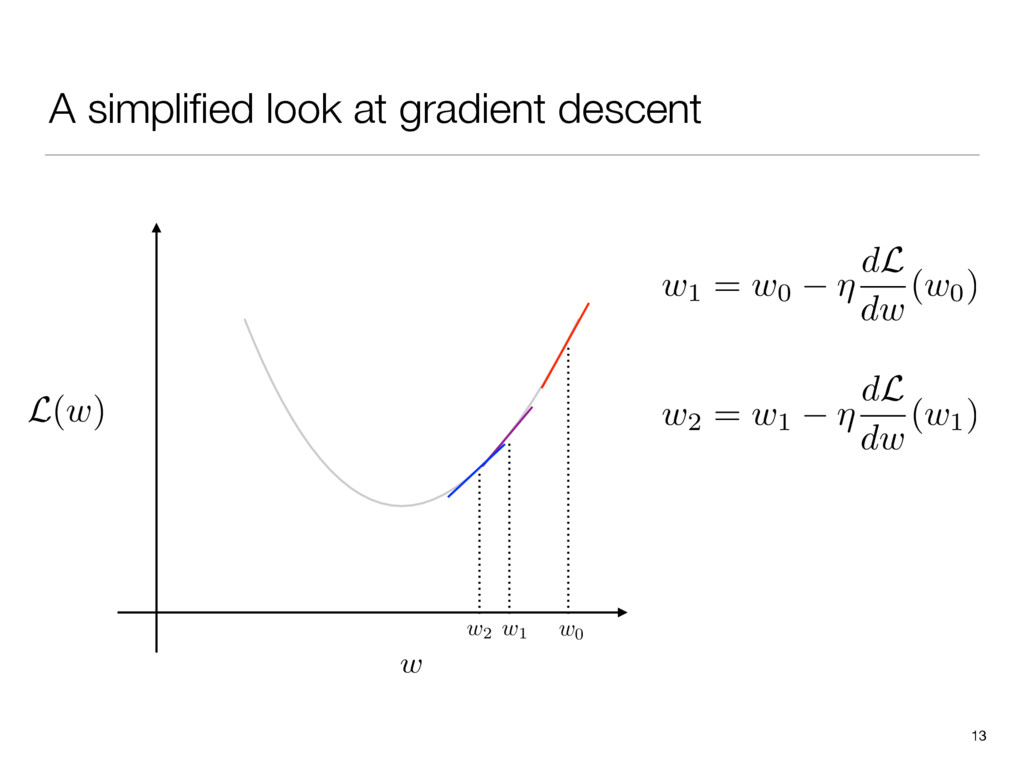
A simplified look at gradient descent 13 L(w) w w0
w1 w1 = w0 ⌘ dL dw (w0) w2 w2 = w1 ⌘ dL dw (w1) -
A simplified look at gradient descent 13 L(w) w w0
w1 w1 = w0 ⌘ dL dw (w0) w2 w2 = w1 ⌘ dL dw (w1) w optimal dL dw = 0 . . . w optimal -
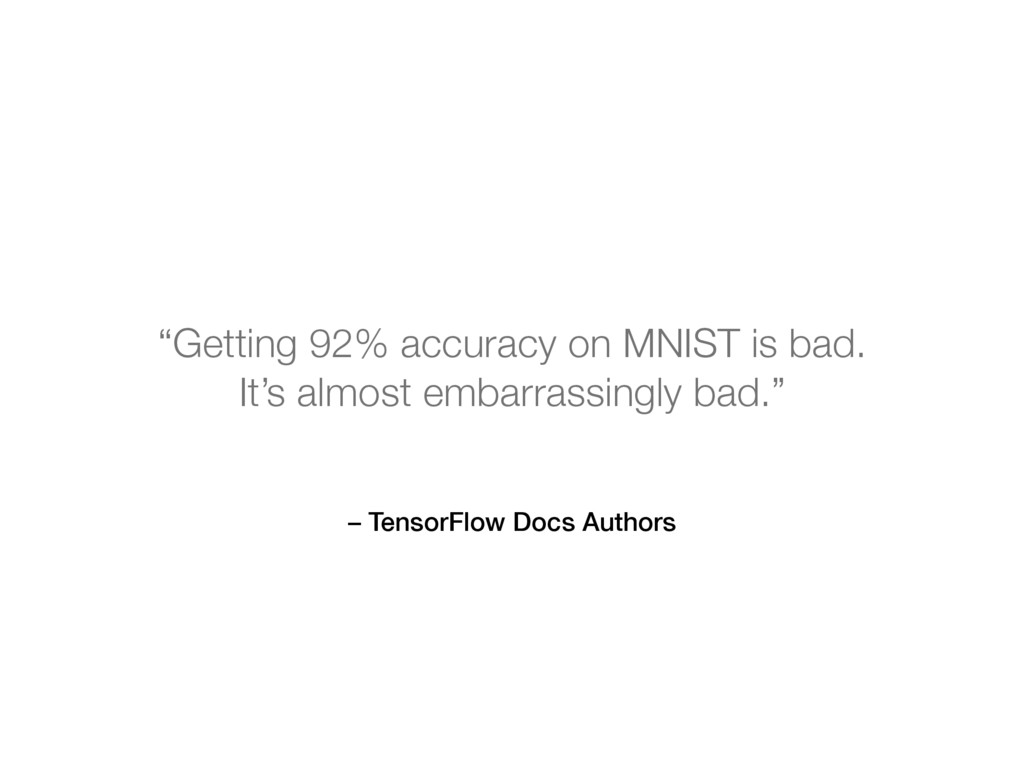
– TensorFlow Docs Authors “Getting 92% accuracy on MNIST is
bad. It’s almost embarrassingly bad.” -
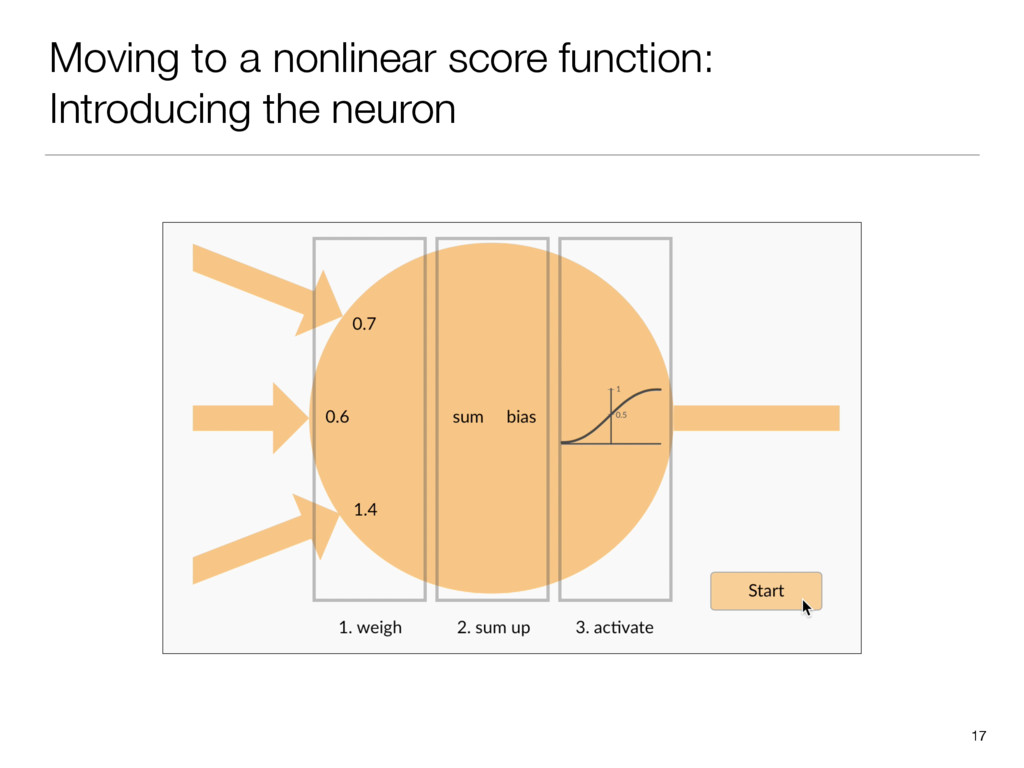
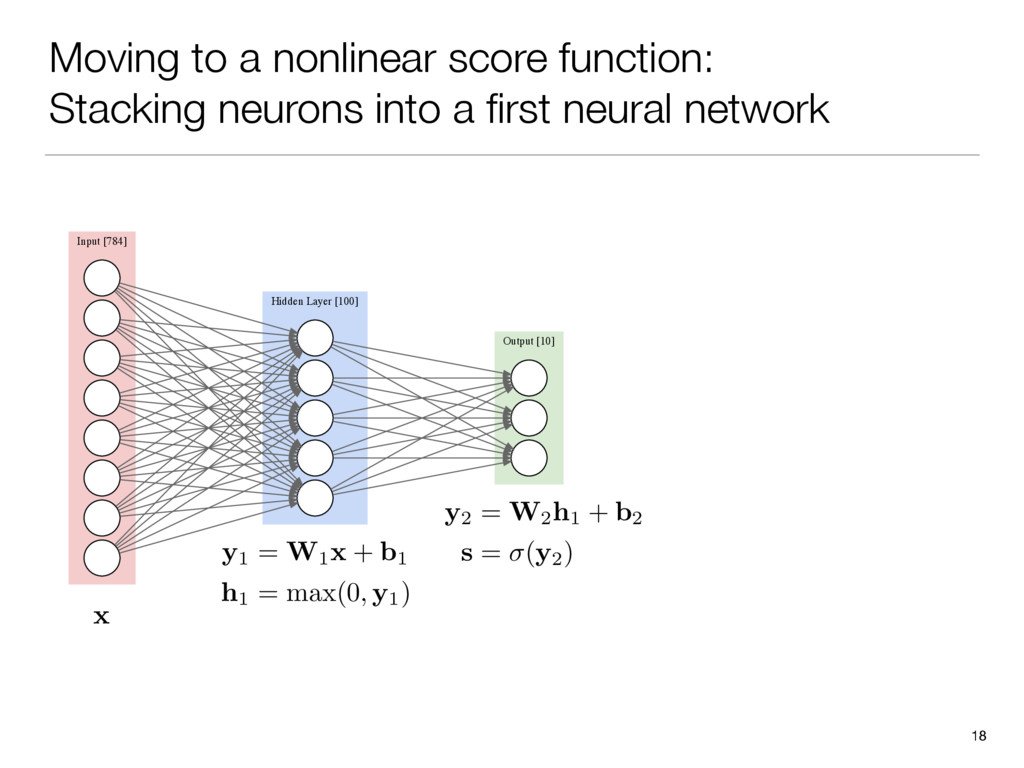
Moving to a nonlinear score function: Stacking neurons into a
first neural network 18 ����� ����� ������ ����� ����� ������ ���� x y1 = W1x + b1 h1 = max(0 , y1) y2 = W2h1 + b2 s = (y2) -
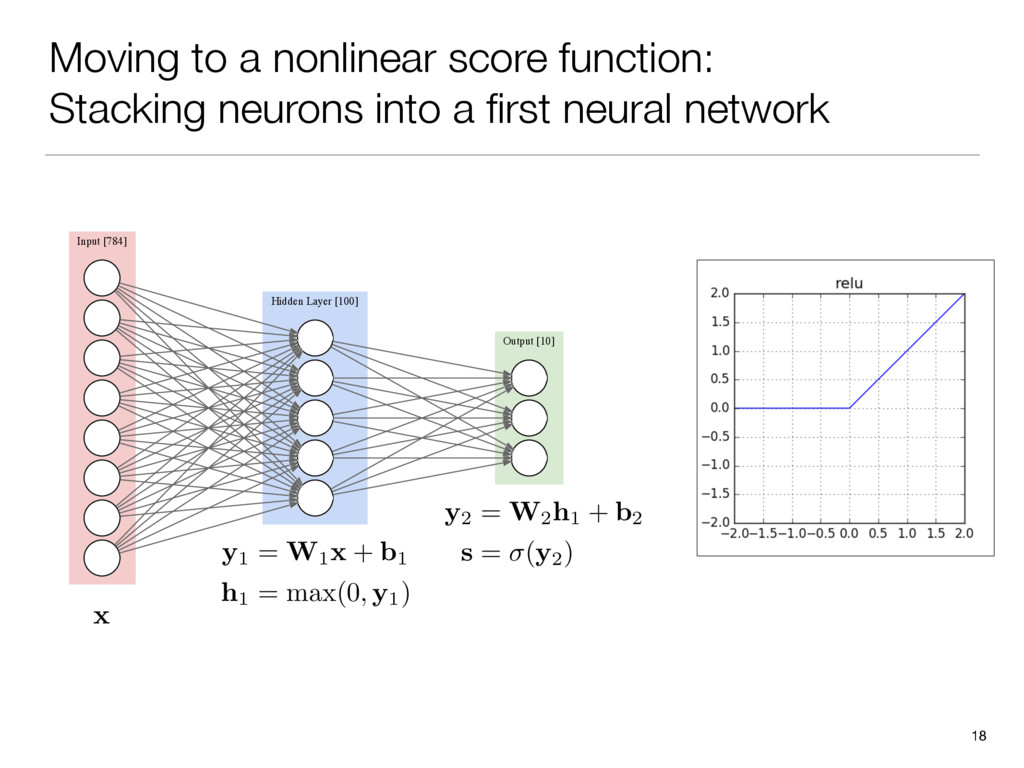
Moving to a nonlinear score function: Stacking neurons into a
first neural network 18 ����� ����� ������ ����� ����� ������ ���� x y1 = W1x + b1 h1 = max(0 , y1) y2 = W2h1 + b2 s = (y2) -
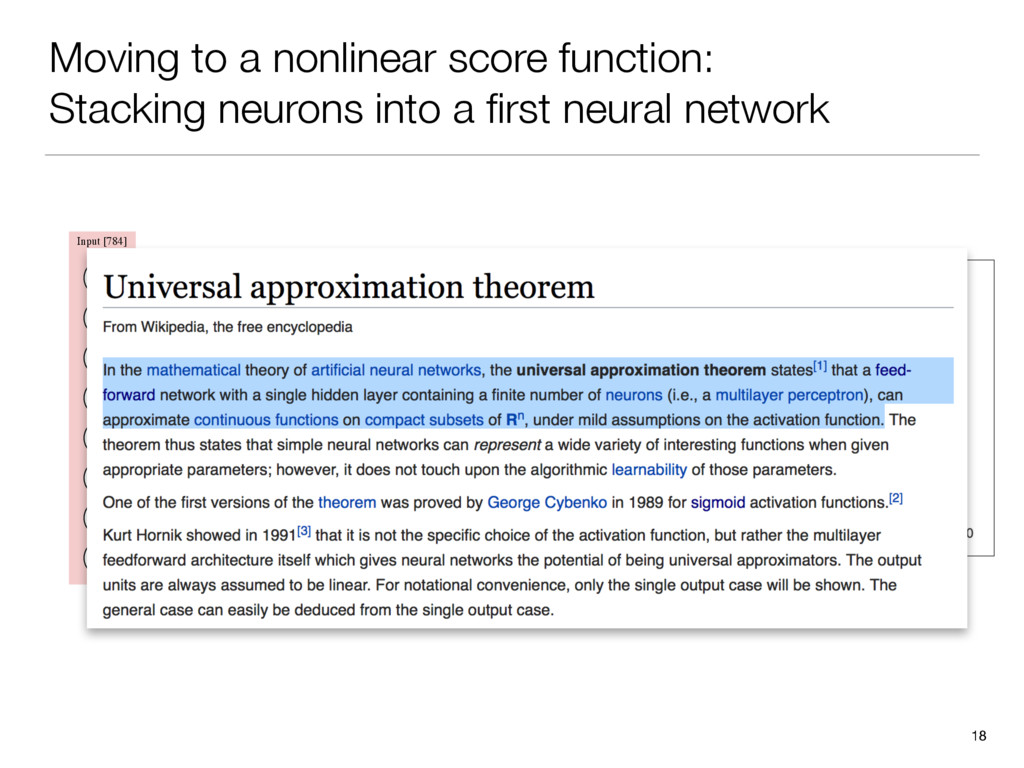
Moving to a nonlinear score function: Stacking neurons into a
first neural network 18 ����� ����� ������ ����� ����� ������ ���� x y1 = W1x + b1 h1 = max(0 , y1) y2 = W2h1 + b2 s = (y2) -
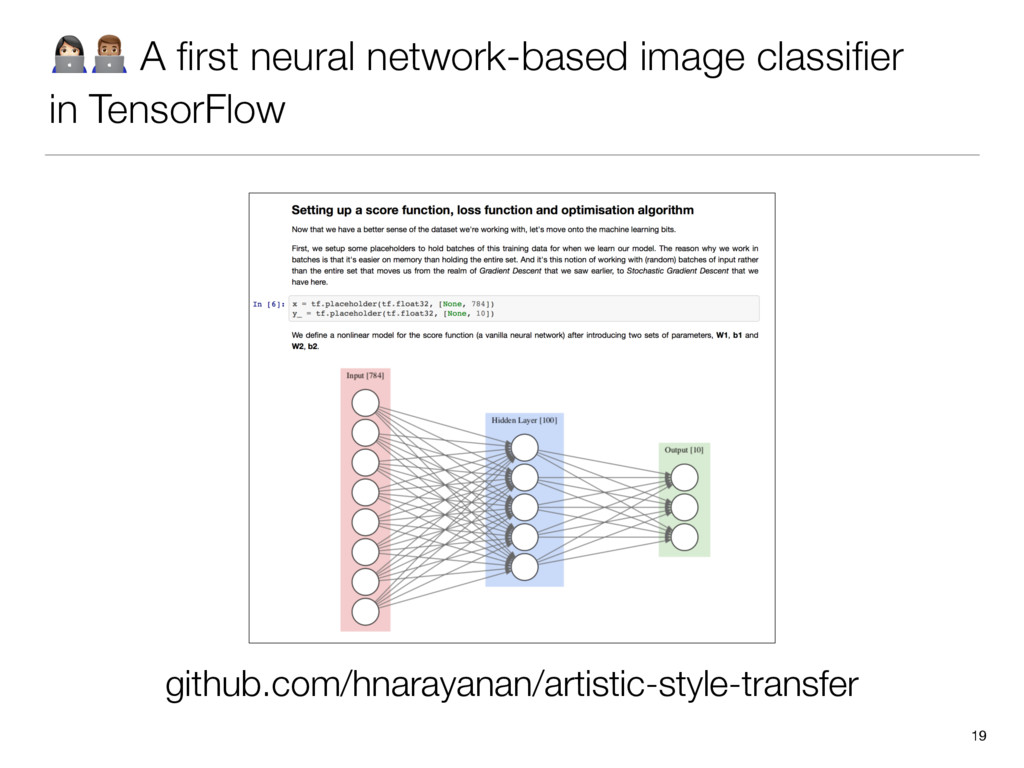
"# A first neural network-based image classifier in TensorFlow 19
github.com/hnarayanan/artistic-style-transfer -
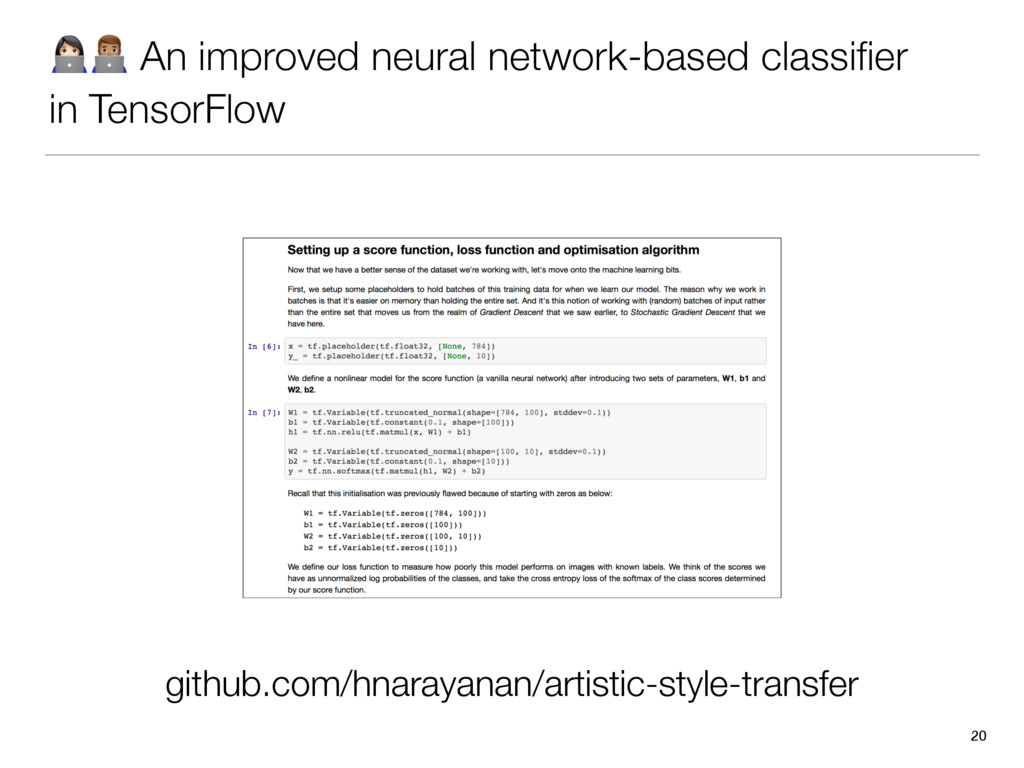
"# An improved neural network-based classifier in TensorFlow 20 ⭐
Just because we can fit anything doesn’t mean our learning algorithm will find that fit! -
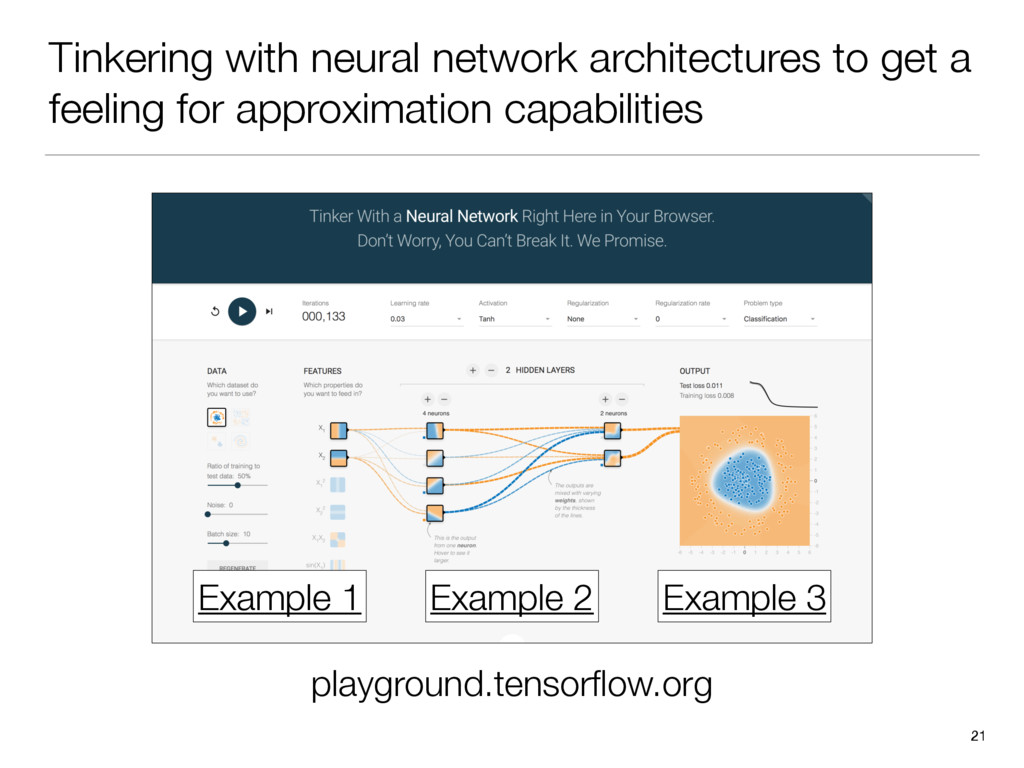
Tinkering with neural network architectures to get a feeling for
approximation capabilities 21 Example 1 Example 2 Example 3 playground.tensorflow.org -
⭐ Neural networks can learn features we’d otherwise need to
hand-engineer with domain knowledge. -
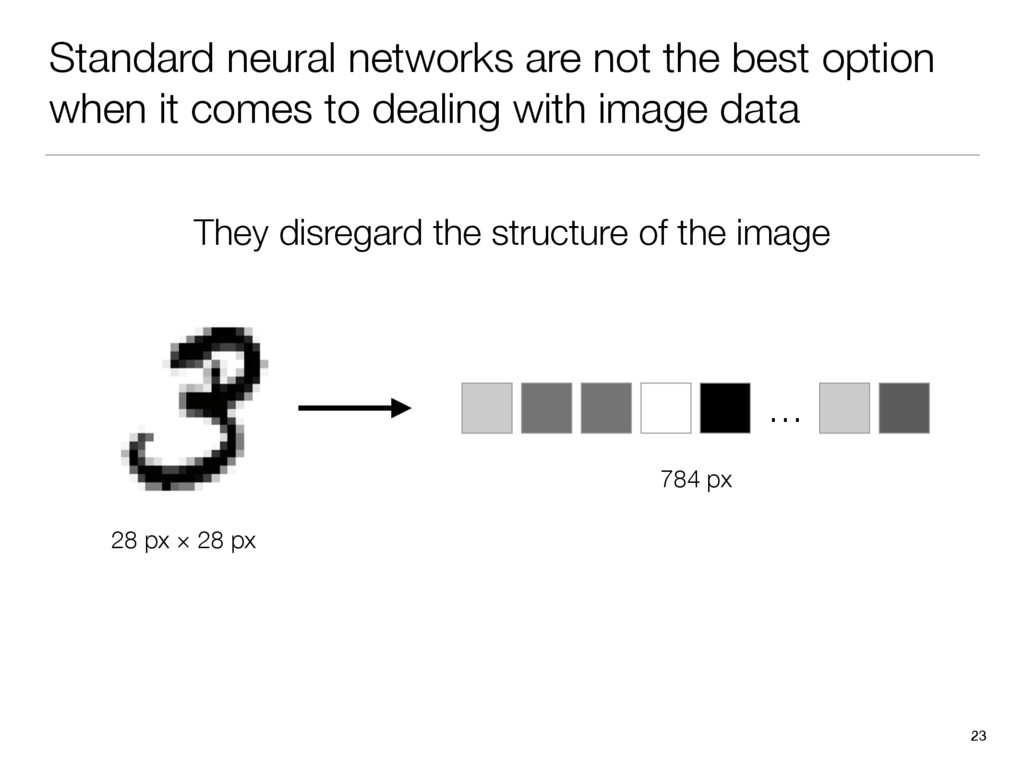
Standard neural networks are not the best option when it
comes to dealing with image data 23 28 px × 28 px 784 px … They disregard the structure of the image -
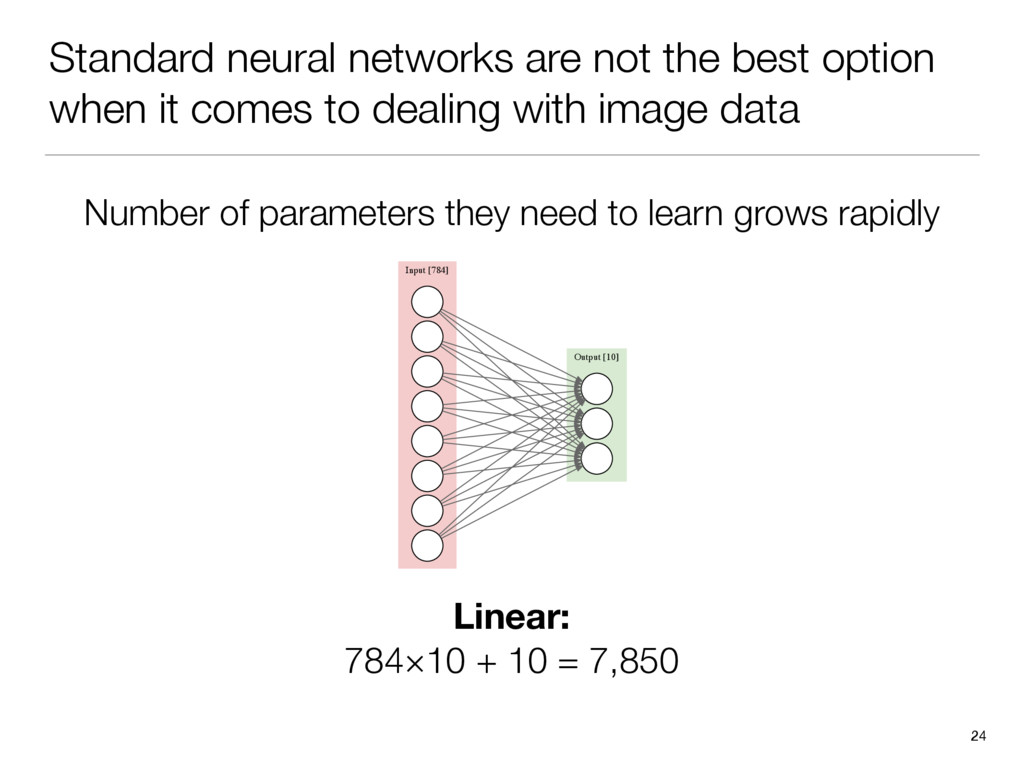
Standard neural networks are not the best option when it
comes to dealing with image data 24 Number of parameters they need to learn grows rapidly Linear: 784×10 + 10 = 7,850 ����� ����� ������ ���� -
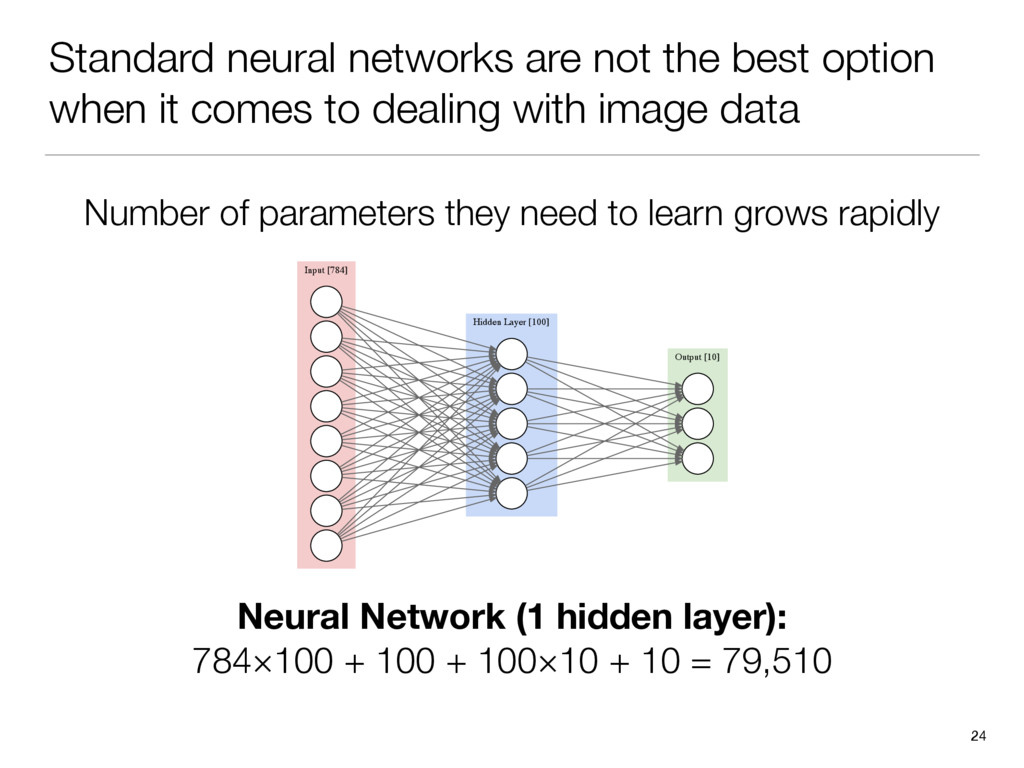
Standard neural networks are not the best option when it
comes to dealing with image data 24 Number of parameters they need to learn grows rapidly Neural Network (1 hidden layer): 784×100 + 100 + 100×10 + 10 = 79,510 ����� ����� ������ ����� ����� ������ ���� -
Standard neural networks are not the best option when it
comes to dealing with image data 24 Number of parameters they need to learn grows rapidly Neural Network (2 hidden layers): 784×400 + 400 + 400×100 + 100 + 100×10 + 10 = 355,110 ����� ����� ������ ����� � ����� ������ ����� � ����� ������ ���� -
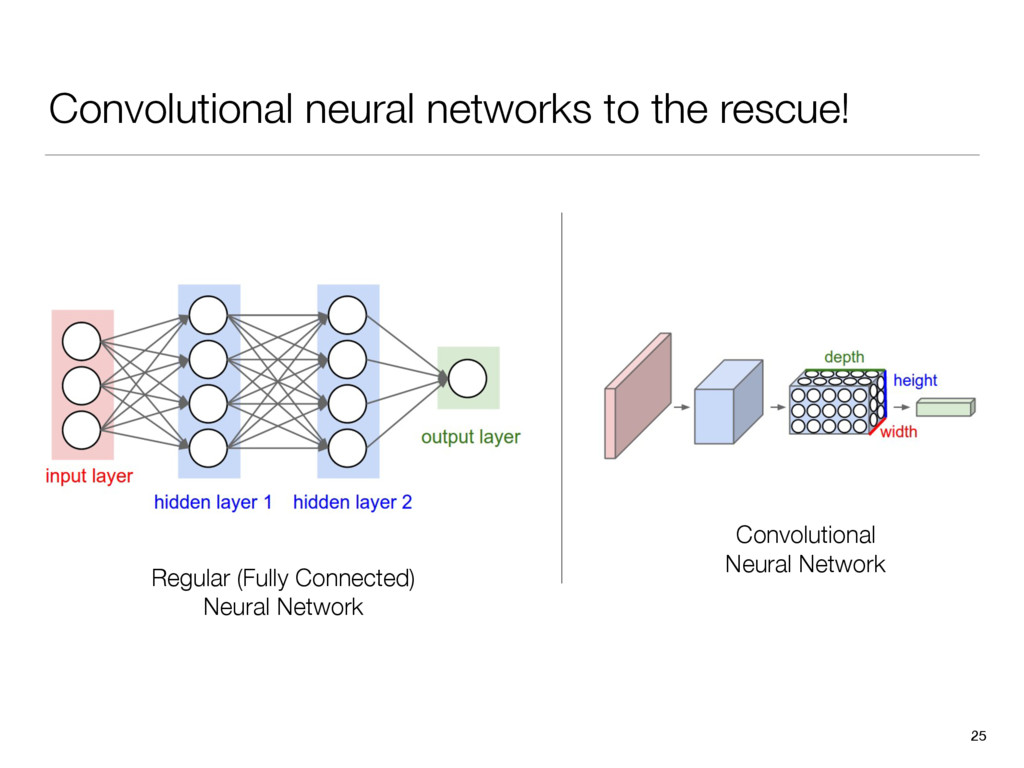
Convolutional neural networks to the rescue! 25 Regular (Fully Connected)
Neural Network Convolutional Neural Network -
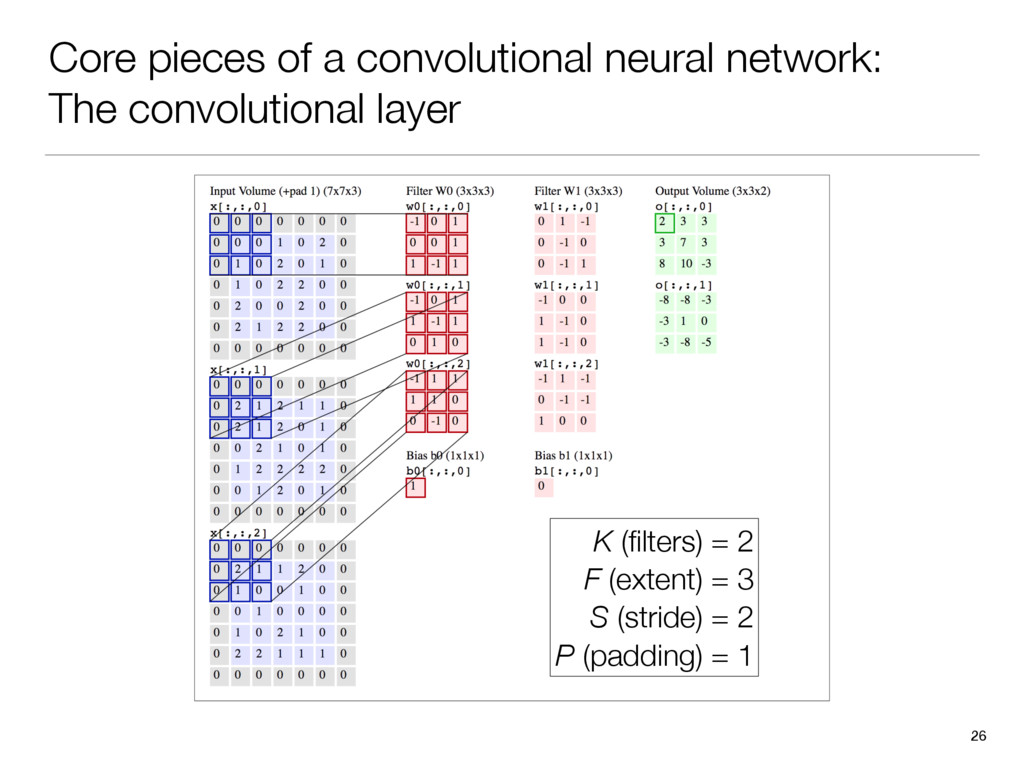
Core pieces of a convolutional neural network: The convolutional layer
26 K (filters) = 2 F (extent) = 3 S (stride) = 2 P (padding) = 1 -
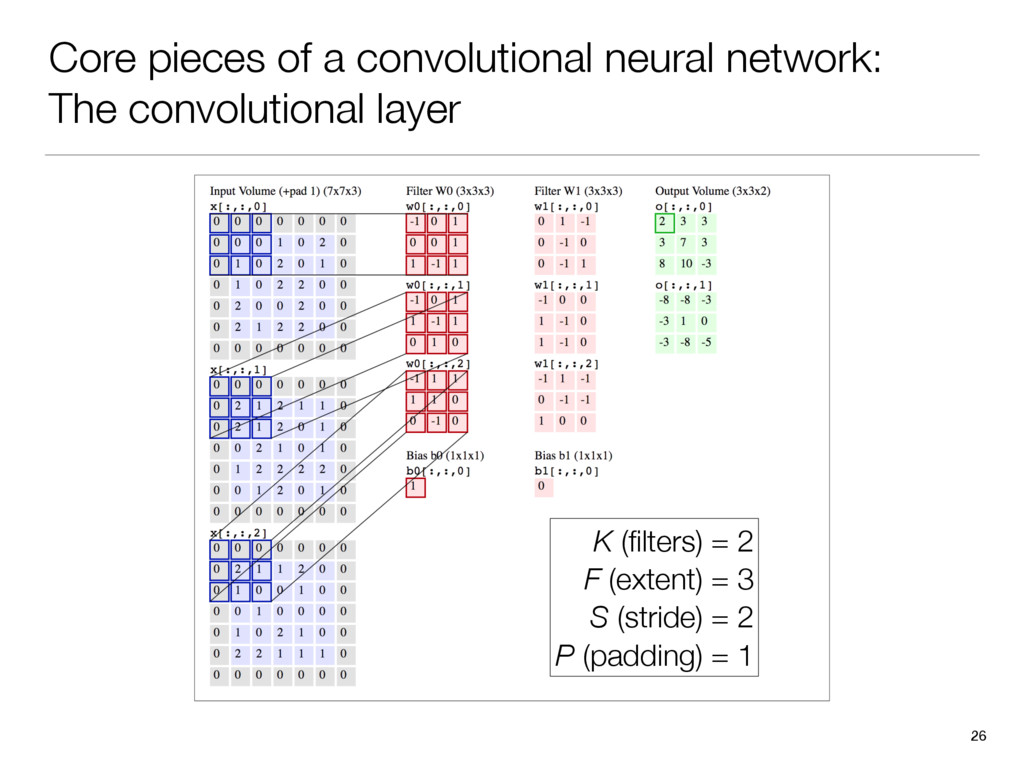
Core pieces of a convolutional neural network: The convolutional layer
26 K (filters) = 2 F (extent) = 3 S (stride) = 2 P (padding) = 1 -
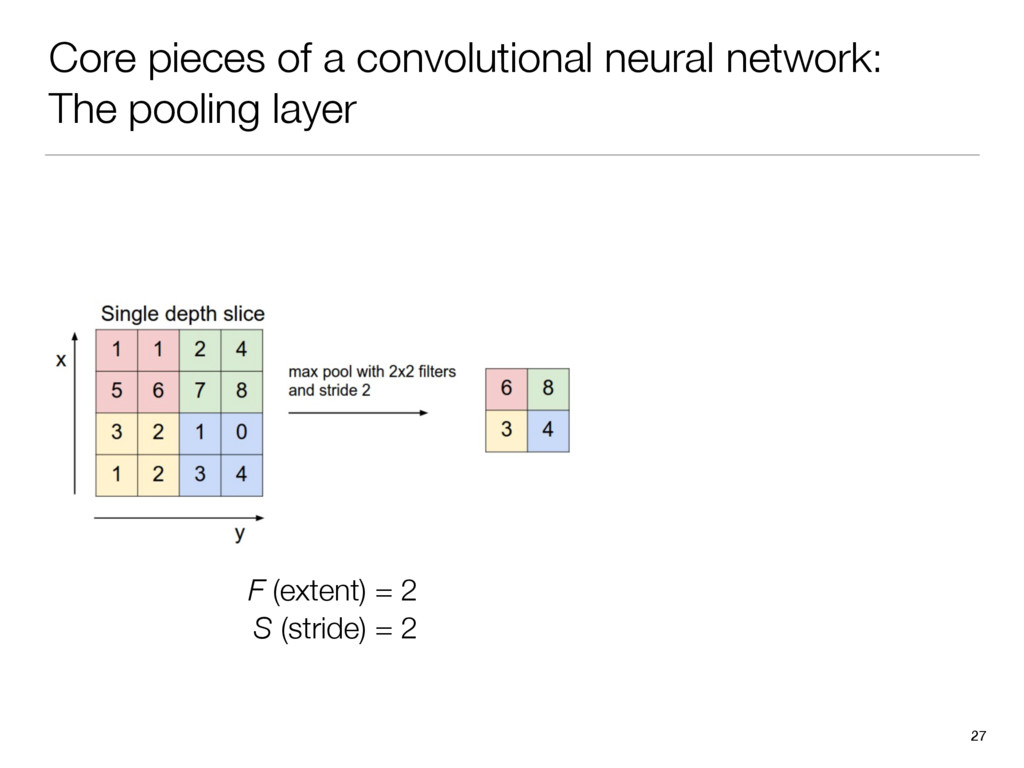
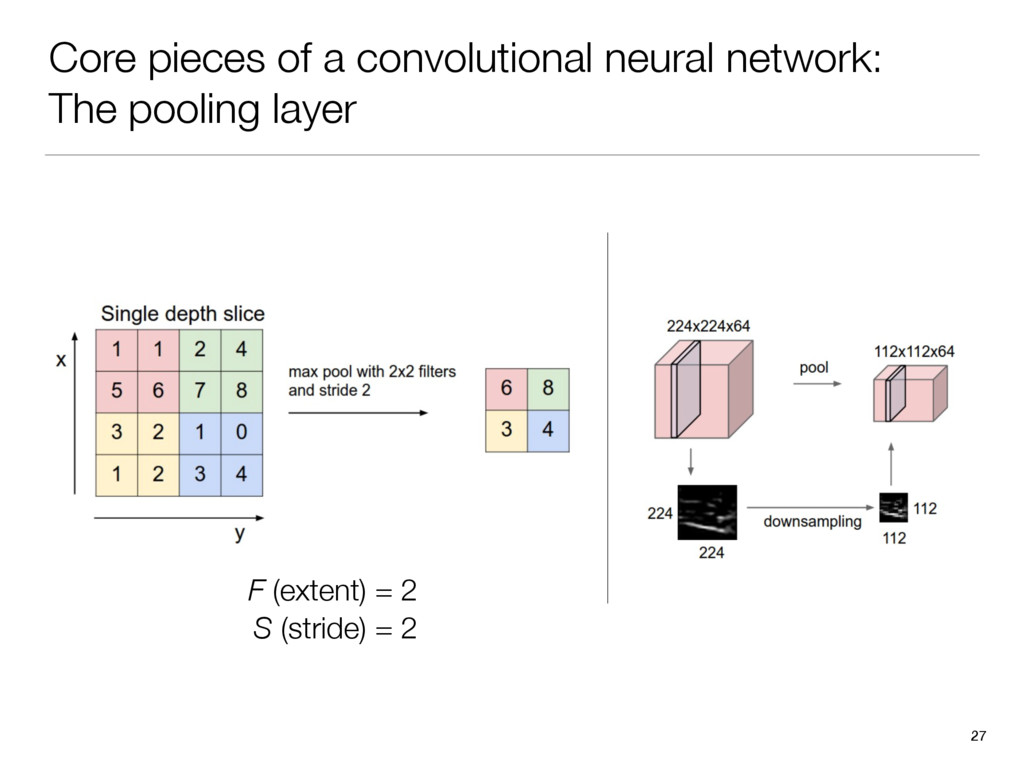
Core pieces of a convolutional neural network: The pooling layer
27 F (extent) = 2 S (stride) = 2 -
Core pieces of a convolutional neural network: The pooling layer
27 F (extent) = 2 S (stride) = 2 -
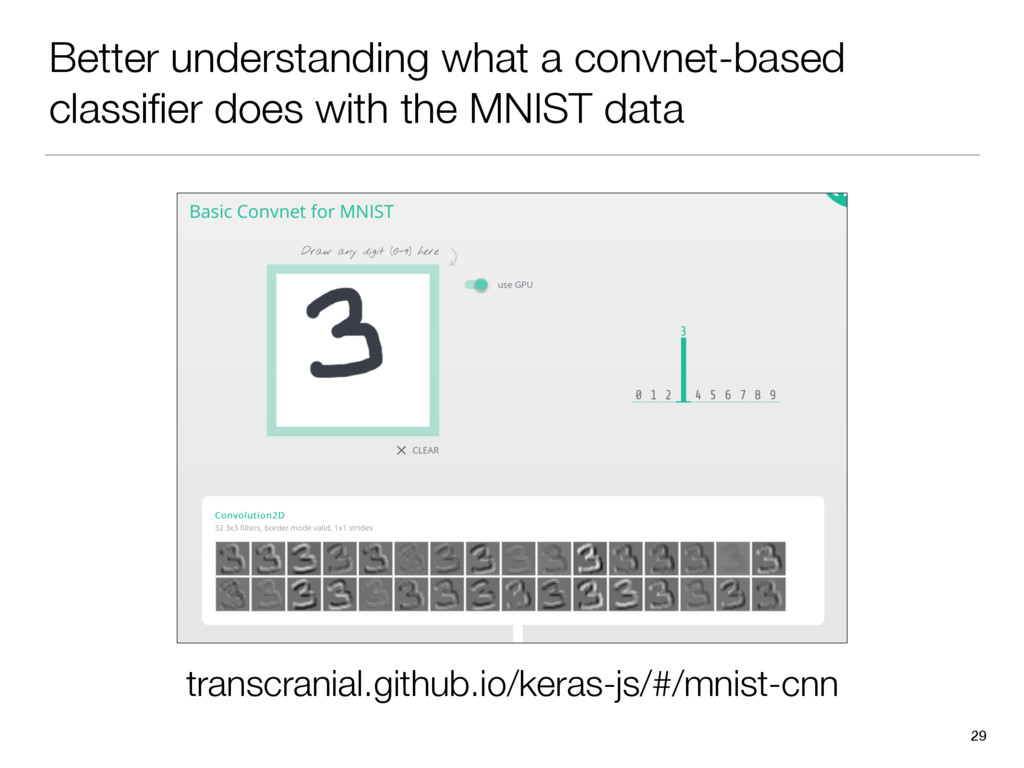
Better understanding what a convnet-based classifier does with the MNIST
data 29 transcranial.github.io/keras-js/#/mnist-cnn -
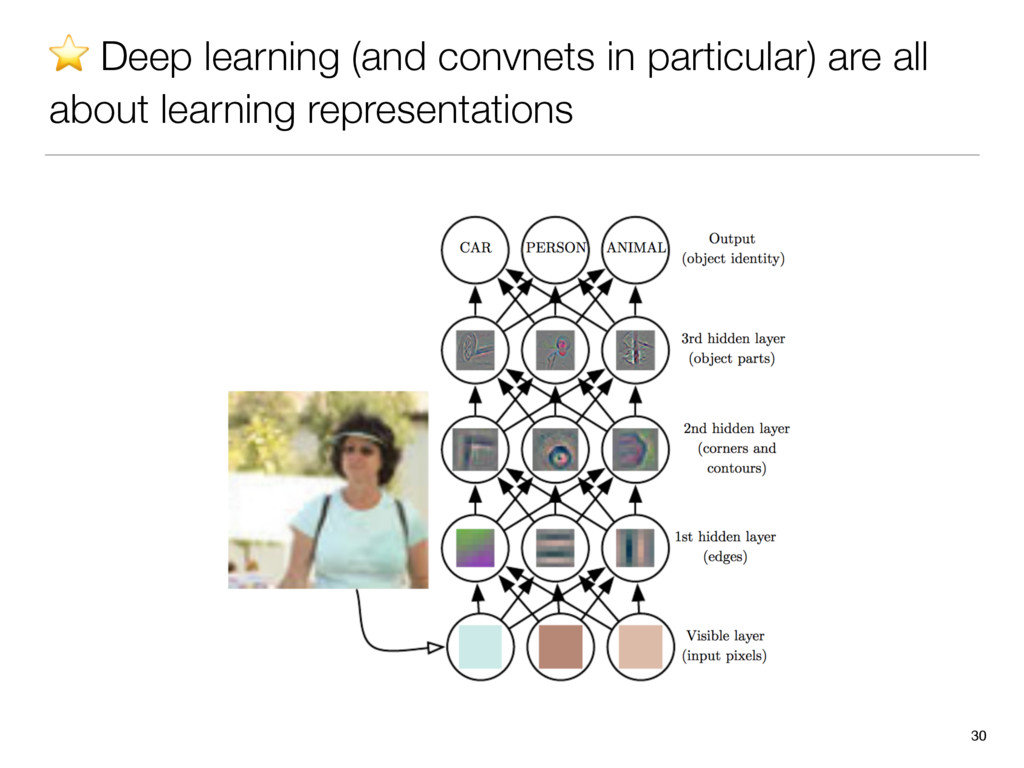
⭐ Deep learning (and convnets in particular) are all about
learning representations 30 -
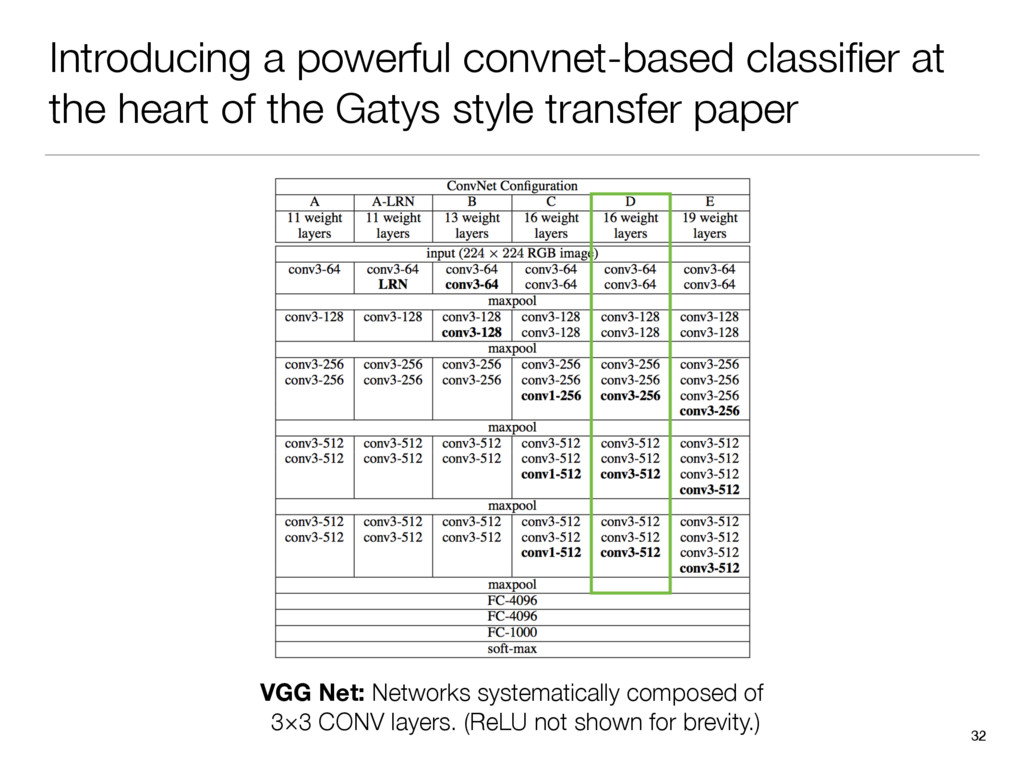
Introducing a powerful convnet-based classifier at the heart of the
Gatys style transfer paper 32 VGG Net: Networks systematically composed of 3×3 CONV layers. (ReLU not shown for brevity.) -
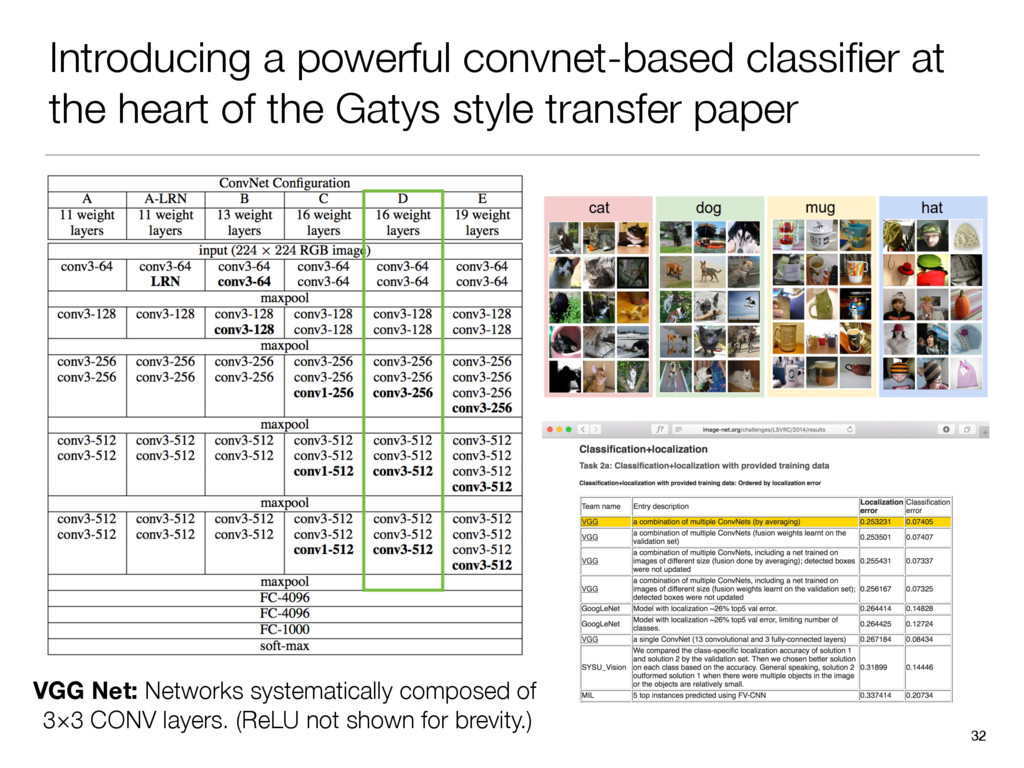
Introducing a powerful convnet-based classifier at the heart of the
Gatys style transfer paper 32 VGG Net: Networks systematically composed of 3×3 CONV layers. (ReLU not shown for brevity.) -
Let’s start with a pre-trained VGG Net in Keras 33
138 million parameters (VGG16) trained on ImageNet -
Let’s start with a pre-trained VGG Net in Keras 33
Keras coming to TensorFlow core in 1.2! -
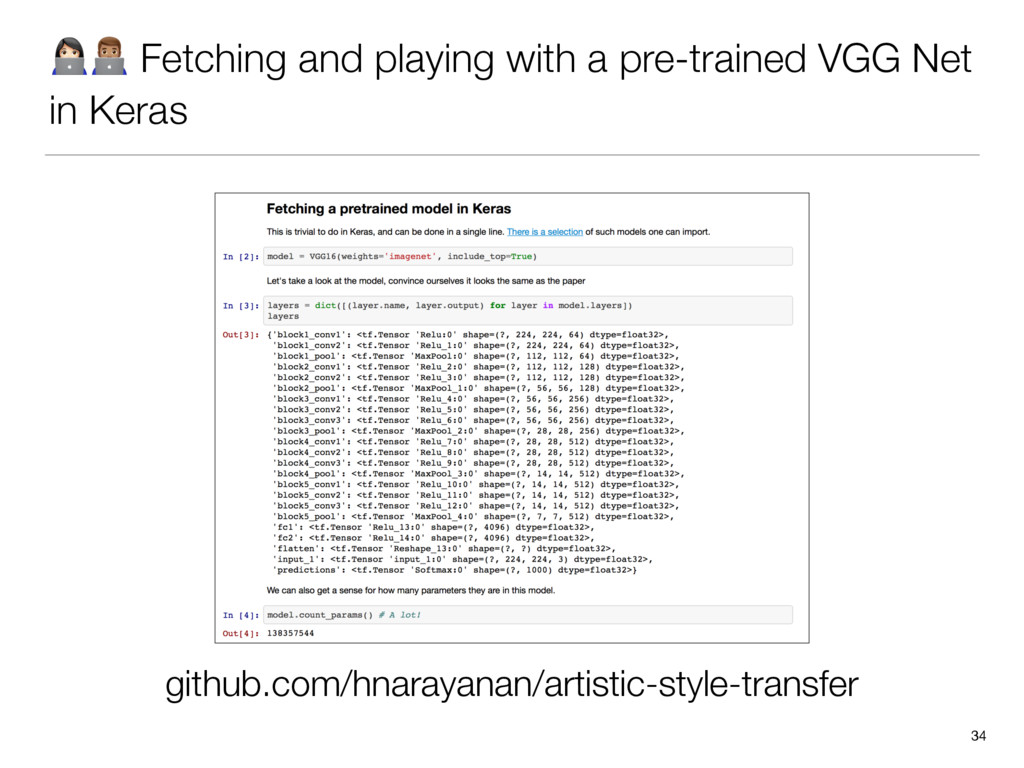
"# Fetching and playing with a pre-trained VGG Net in
Keras 34 github.com/hnarayanan/artistic-style-transfer -
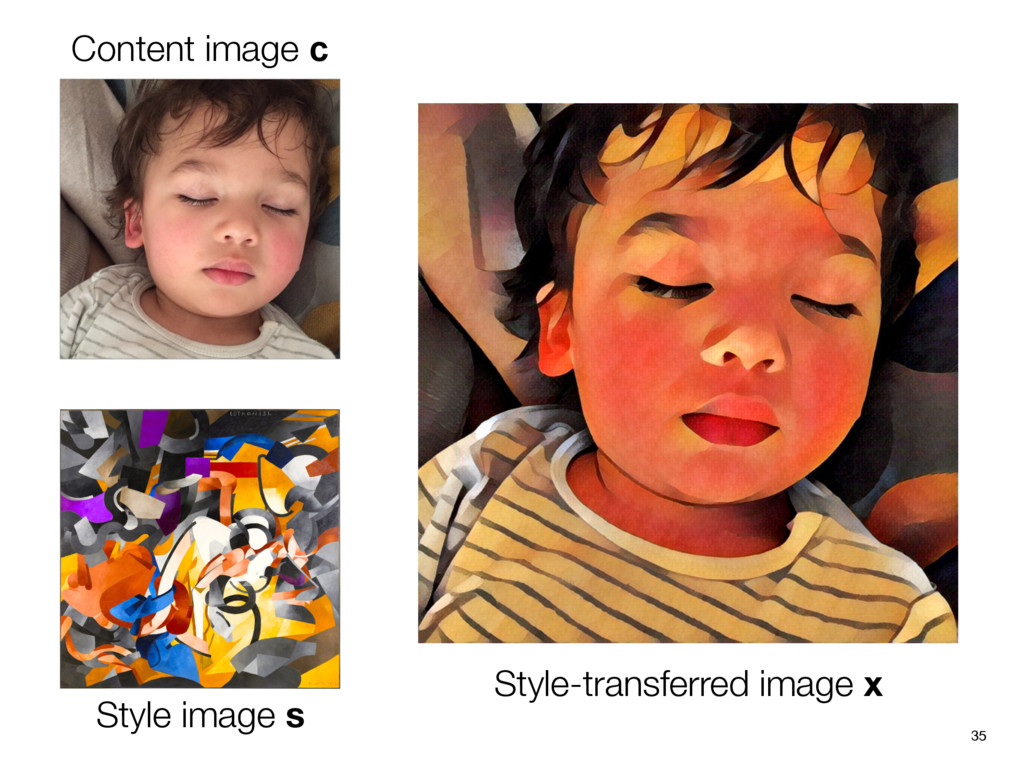
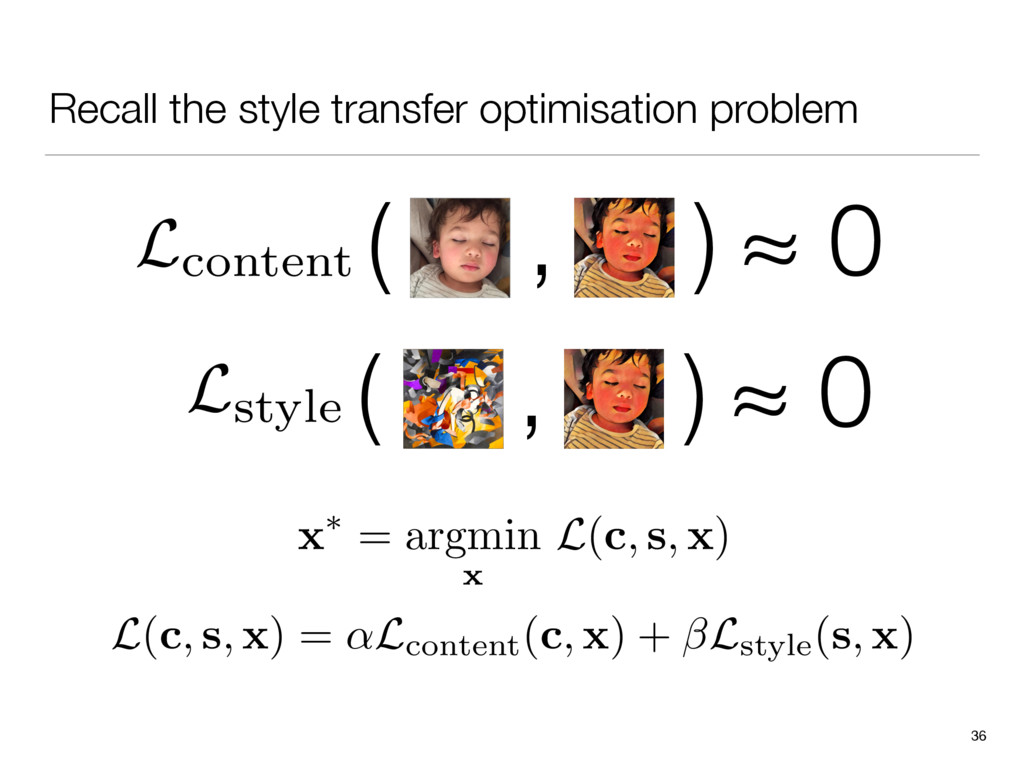
Recall the style transfer optimisation problem 36 L content (
) ≈ 0 , ( ) ≈ 0 , Lstyle L( c , s , x ) = ↵L content ( c , x ) + L style ( s , x ) x ⇤ = argmin x L( c , s , x ) -
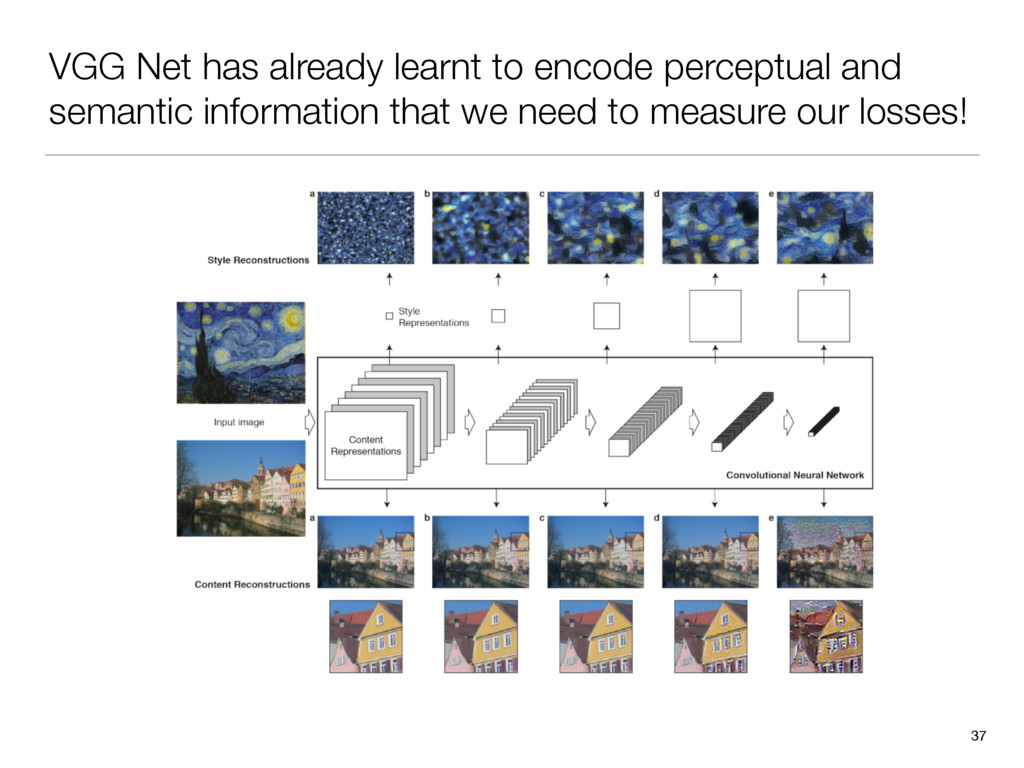
VGG Net has already learnt to encode perceptual and semantic
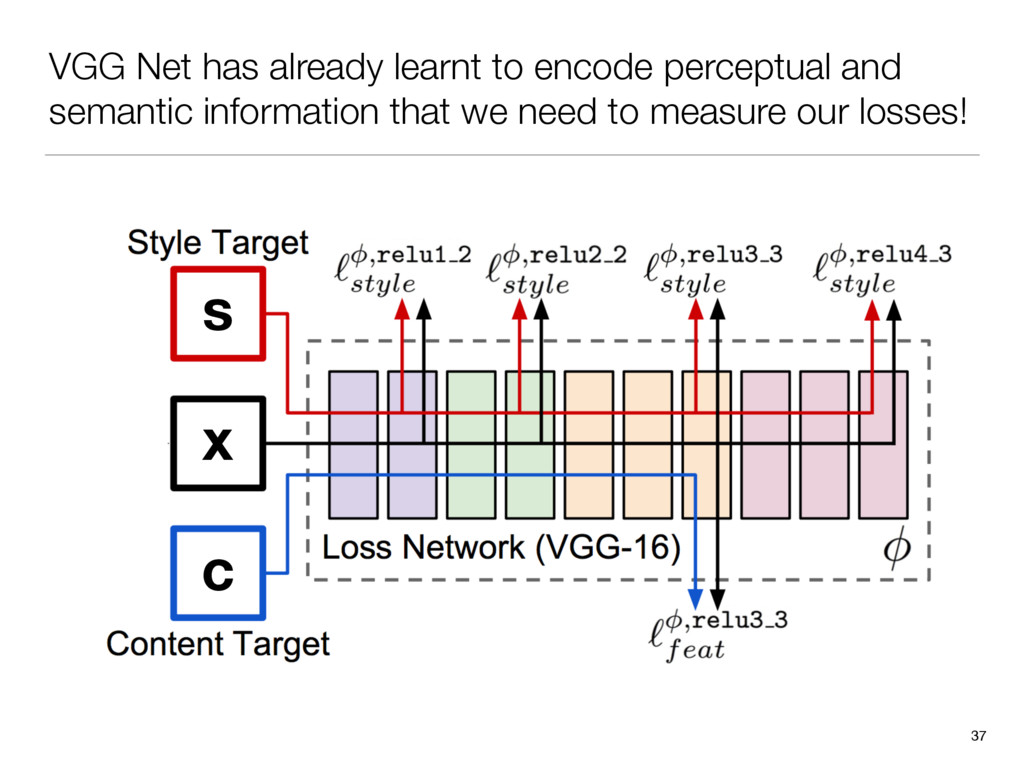
information that we need to measure our losses! 37 -
VGG Net has already learnt to encode perceptual and semantic
information that we need to measure our losses! 37 x s c -
How we explicitly calculate the style and content losses 38
Ll content ( c , x ) = 1 2 X i,j Cl ij Xl ij 2 -
How we explicitly calculate the style and content losses 38
Ll content ( c , x ) = 1 2 X i,j Cl ij Xl ij 2 Gij( A ) = X k AikAjk El( s , x ) = 1 4N2 l M2 l X i,j Gij( S l) Gij( X l) 2 Lstyle( s , x ) = L X l=0 wlEl( s , x ) -
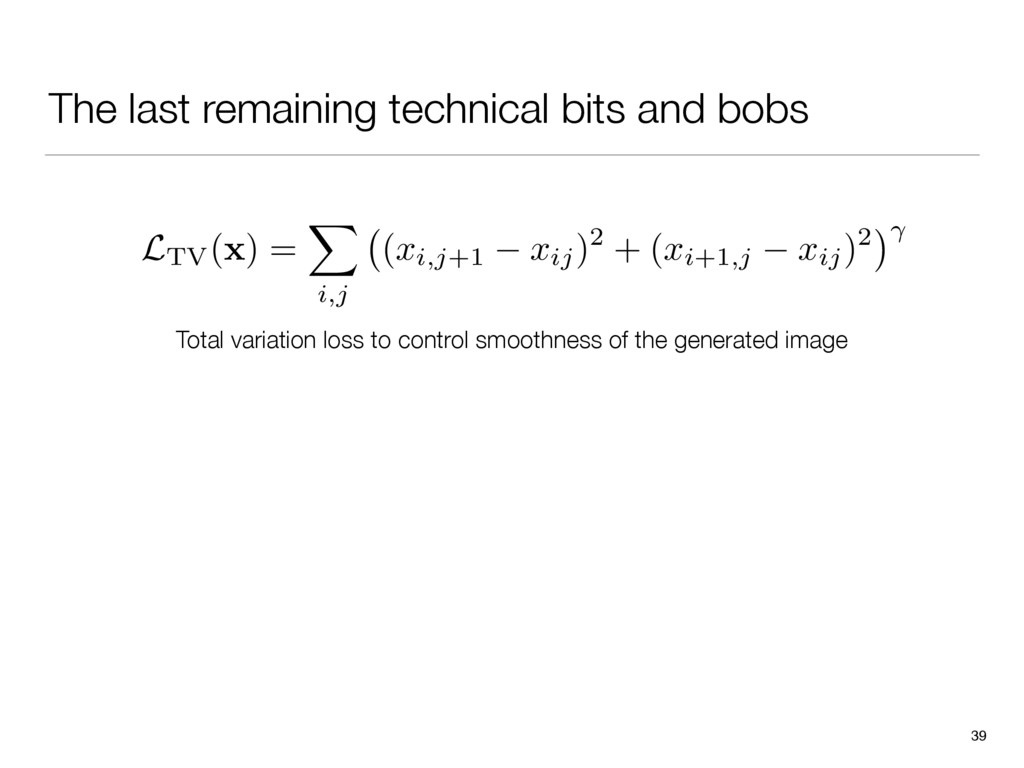
The last remaining technical bits and bobs 39 Total variation
loss to control smoothness of the generated image LTV( x ) = X i,j ( xi,j+1 xij)2 + ( xi+1,j xij)2 -
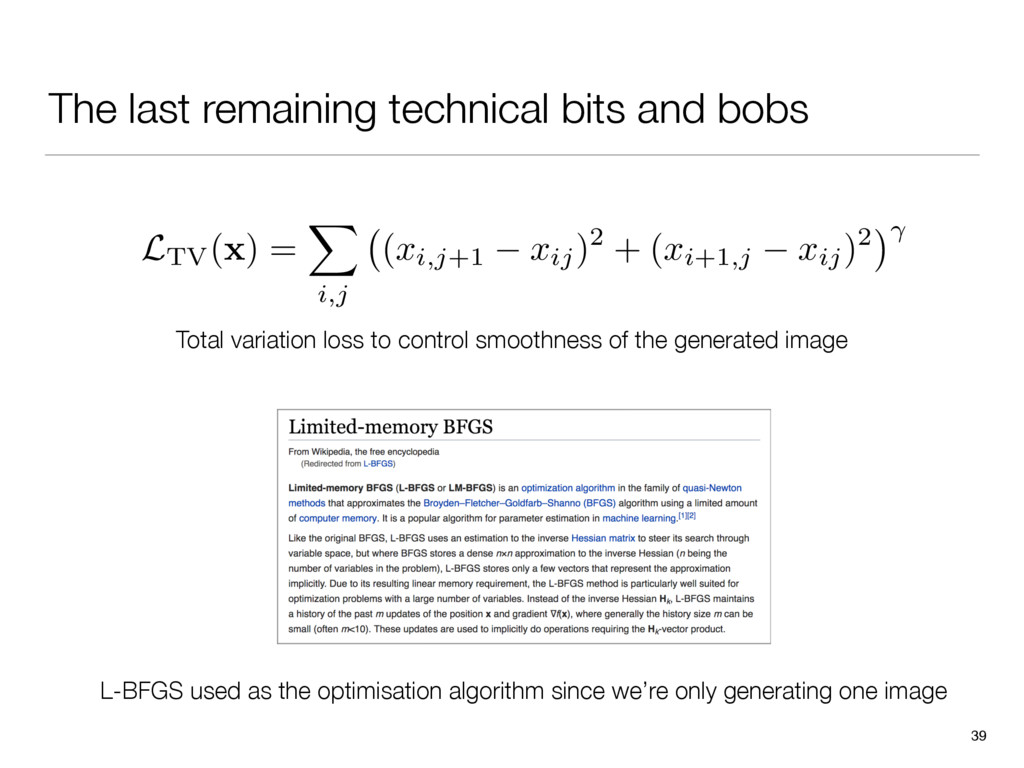
The last remaining technical bits and bobs 39 Total variation
loss to control smoothness of the generated image LTV( x ) = X i,j ( xi,j+1 xij)2 + ( xi+1,j xij)2 L-BFGS used as the optimisation algorithm since we’re only generating one image -
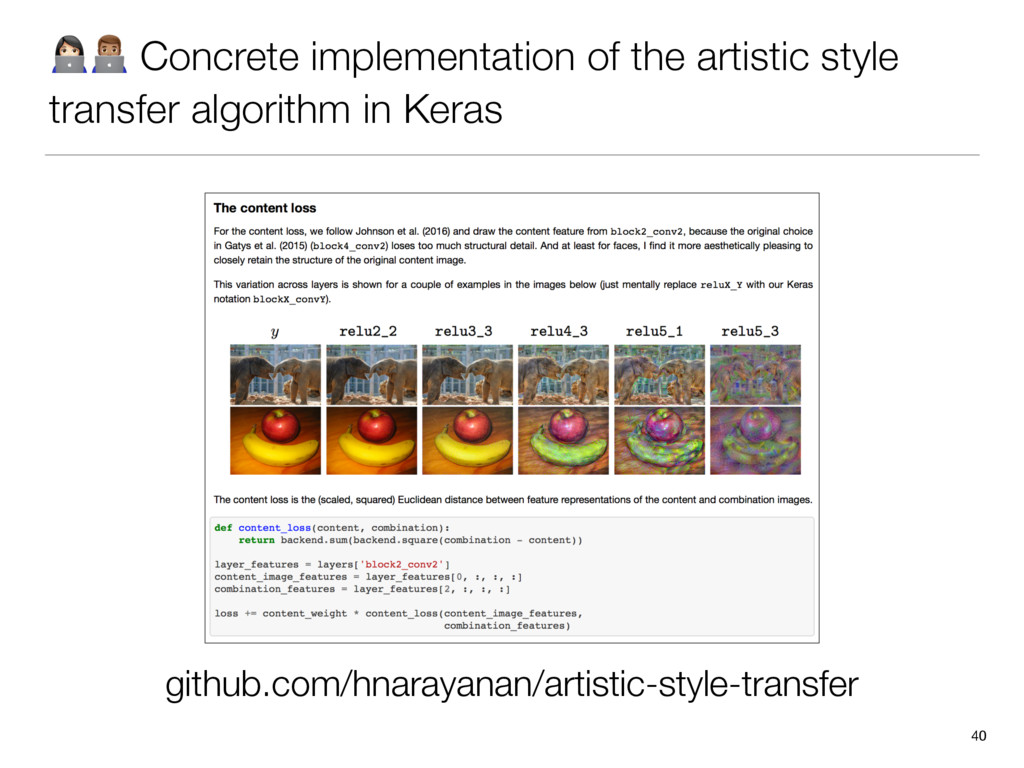
"# Concrete implementation of the artistic style transfer algorithm in
Keras 40 github.com/hnarayanan/artistic-style-transfer -
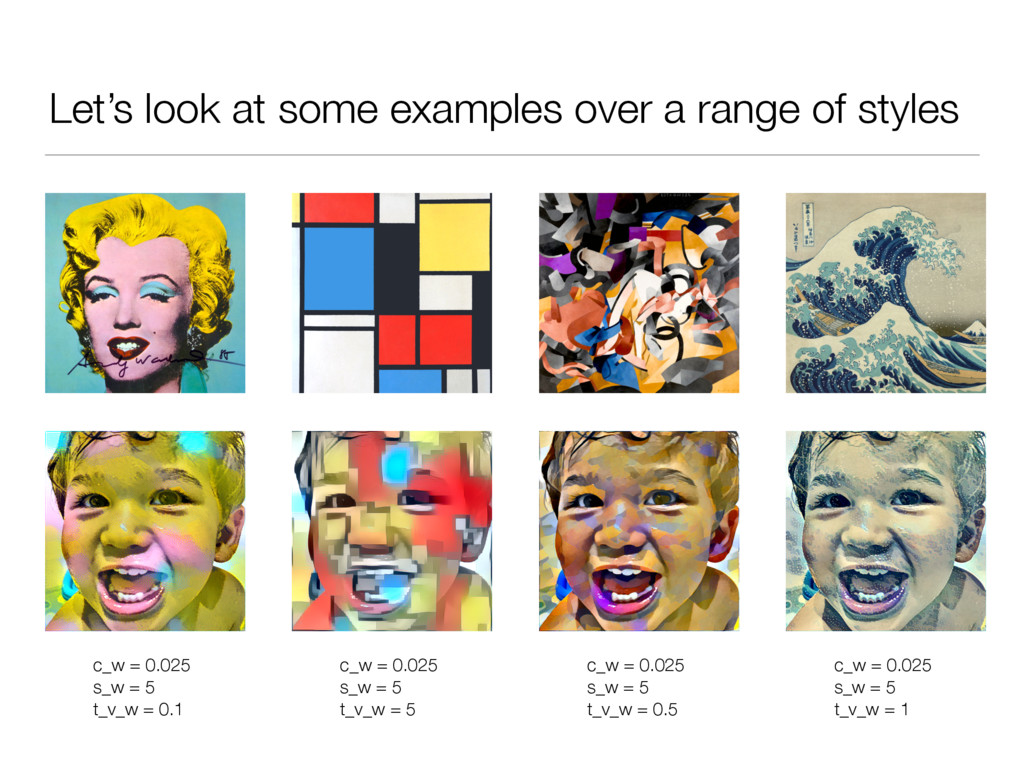
Let’s look at some examples over a range of styles
c_w = 0.025 s_w = 5 t_v_w = 0.1 c_w = 0.025 s_w = 5 t_v_w = 5 c_w = 0.025 s_w = 5 t_v_w = 0.5 c_w = 0.025 s_w = 5 t_v_w = 1 -
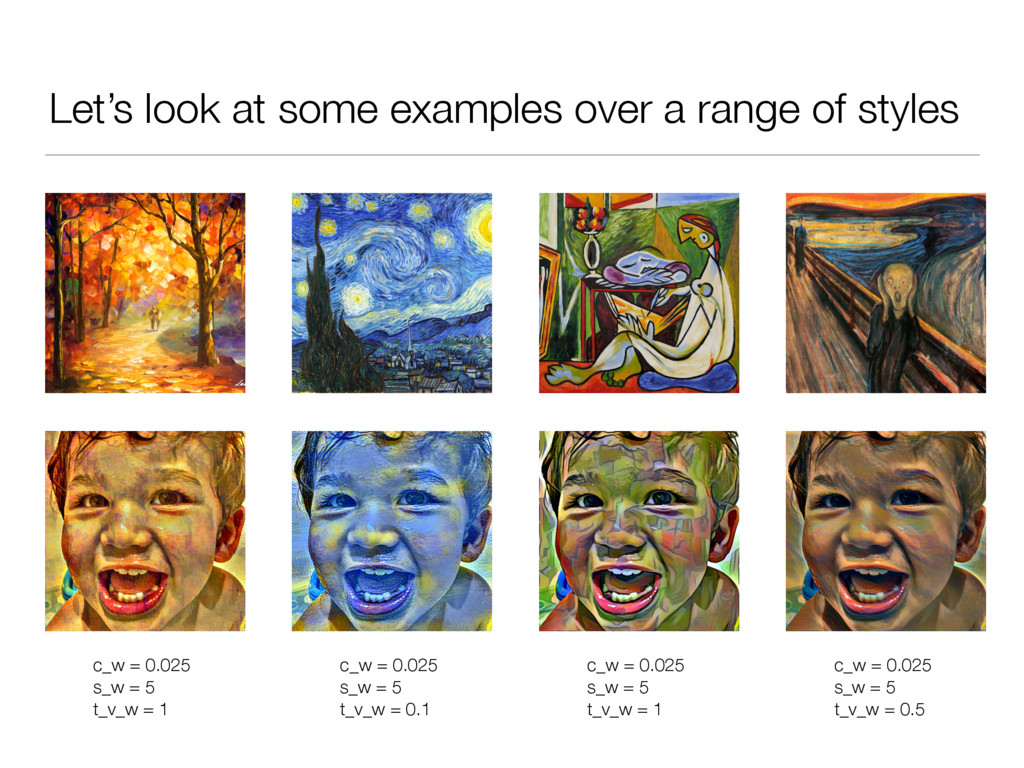
Let’s look at some examples over a range of styles
c_w = 0.025 s_w = 5 t_v_w = 1 c_w = 0.025 s_w = 5 t_v_w = 0.1 c_w = 0.025 s_w = 5 t_v_w = 1 c_w = 0.025 s_w = 5 t_v_w = 0.5 -
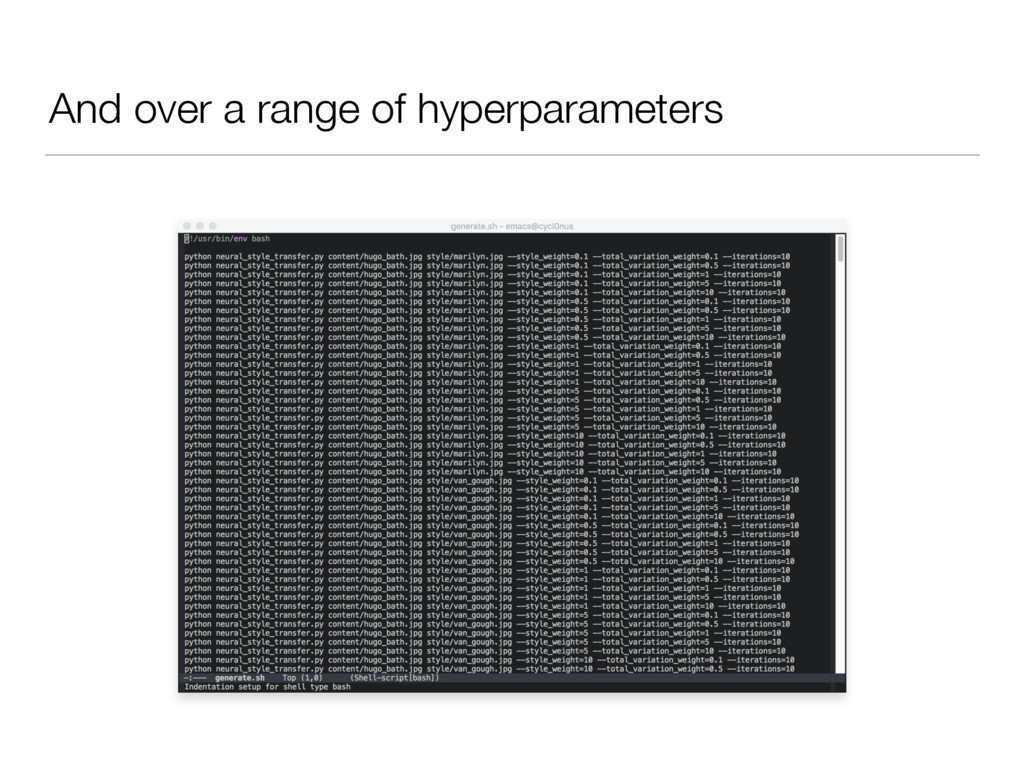
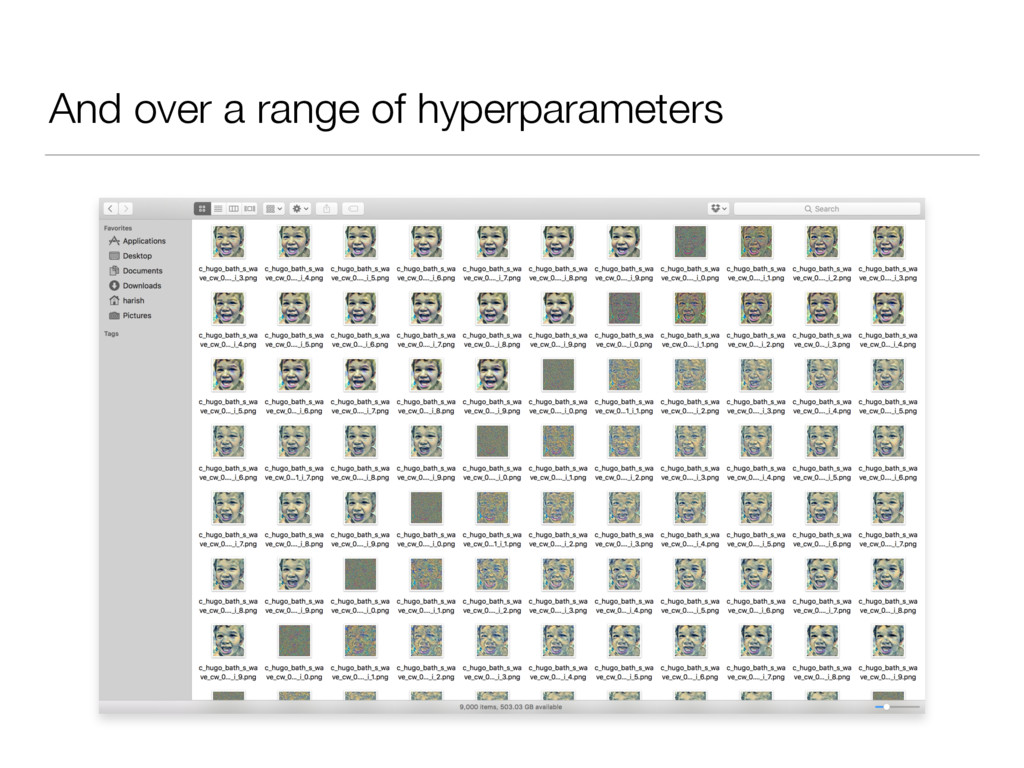
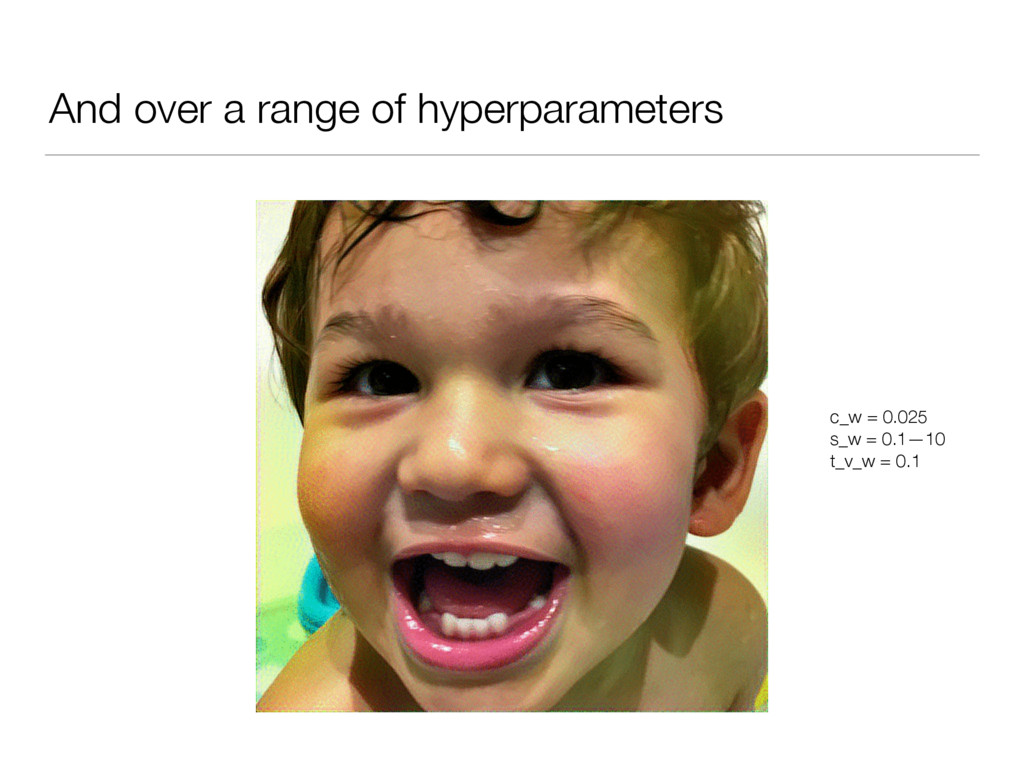
And over a range of hyperparameters c_w = 0.025 s_w
= 0.1—10 t_v_w = 0.1 -
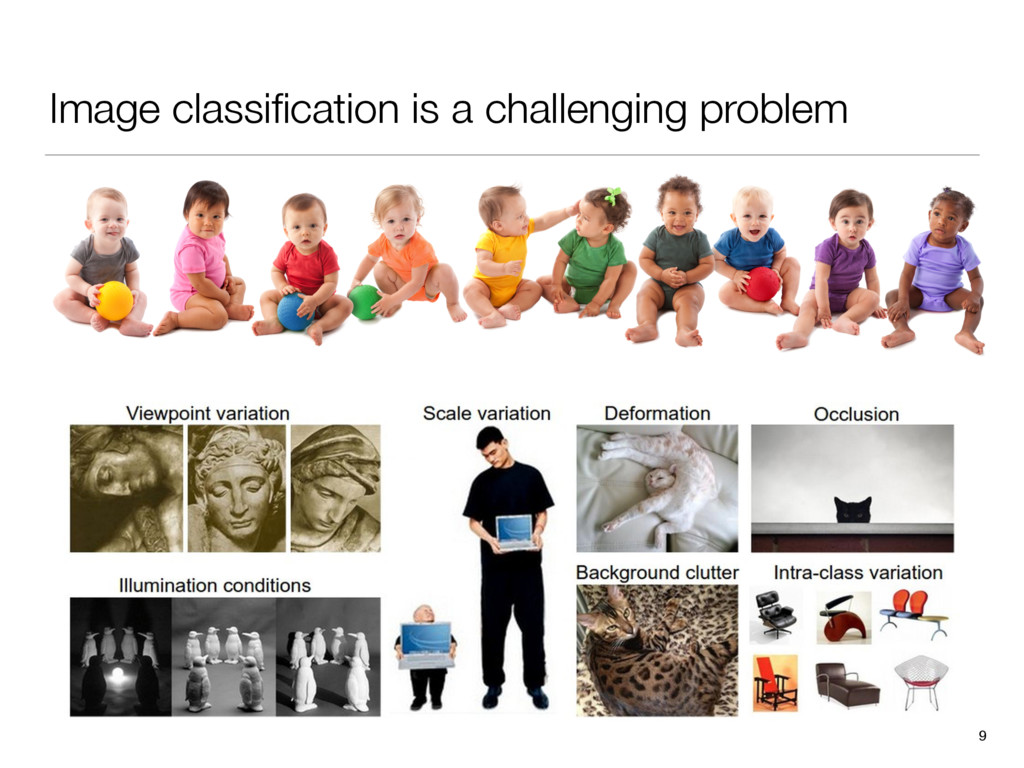
Some broad concluding thoughts • Turn to machine learning when
you have general problems that seem intuitive to state, but where it’s hard to explicitly write down all the solution steps • Note that this difficulty often stems from a semantic gap between the input representation and the task at hand 46 -
Some broad concluding thoughts • Turn to machine learning when
you have general problems that seem intuitive to state, but where it’s hard to explicitly write down all the solution steps • Note that this difficulty often stems from a semantic gap between the input representation and the task at hand • Just because a function can fit something doesn’t mean the learning algorithm will always find that fit 46 -
Some broad concluding thoughts • Turn to machine learning when
you have general problems that seem intuitive to state, but where it’s hard to explicitly write down all the solution steps • Note that this difficulty often stems from a semantic gap between the input representation and the task at hand • Just because a function can fit something doesn’t mean the learning algorithm will always find that fit • Deep learning is all about representation learning. They can learn features we’d otherwise need to hand-engineer with domain knowledge. 46 -
… and closer to this evening’s workshop • In studying
the problem of cat vs. baby deeply, you’ve learnt how to see. You can repurpose this knowledge! 47 -
… and closer to this evening’s workshop • In studying
the problem of cat vs. baby deeply, you’ve learnt how to see. You can repurpose this knowledge! • Convnets are really good at computer vision tasks, but they’re not infallible 47 -
… and closer to this evening’s workshop • In studying
the problem of cat vs. baby deeply, you’ve learnt how to see. You can repurpose this knowledge! • Convnets are really good at computer vision tasks, but they’re not infallible • TensorFlow is great, but Keras is what you likely want to be using to experiment quickly 47 -
… and closer to this evening’s workshop • In studying
the problem of cat vs. baby deeply, you’ve learnt how to see. You can repurpose this knowledge! • Convnets are really good at computer vision tasks, but they’re not infallible • TensorFlow is great, but Keras is what you likely want to be using to experiment quickly • Instead of solving an optimisation problem, train a network to approximate solutions to it for 1000x speedup 47 -
References and further reading 1. https://harishnarayanan.org/writing/artistic-style-transfer/; https://github.com/hnarayanan/artistic-style-transfer 2. http://prisma-ai.com; https://deepart.io;
http://www.pikazoapp.com 3. https://arxiv.org/abs/1701.04928 4. http://www.artic.edu/aic/collections/artwork/80062 5. https://arxiv.org/abs/1508.06576 6. https://arxiv.org/abs/1508.06576 7. — 8. http://cs231n.github.io/classification/ 9. http://cs231n.github.io/classification/ 10.— 11.http://cs231n.stanford.edu/slides/winter1516_lecture2.pdf 12.http://cs231n.github.io/linear-classify/; https://www.tensorflow.org/tutorials/mnist/beginners/ 13.http://cs231n.github.io/optimization-1/ -
References and further reading 14.https://github.com/hnarayanan/artistic-style-transfer/blob/master/notebooks/1_Linear_Image_Classifier.ipynb; https://www.tensorflow.org/tutorials/mnist/beginners/ 15.http://cs231n.github.io/linear-classify/ 16.https://www.tensorflow.org/get_started/mnist/pros 17.https://appliedgo.net/perceptron/ 18.http://cs231n.github.io/neural-networks-1/;
https://en.wikipedia.org/wiki/Universal_approximation_theorem 19.https://github.com/hnarayanan/artistic-style-transfer/blob/master/notebooks/2_Neural_Network- based_Image_Classifier-1.ipynb 20.https://github.com/hnarayanan/artistic-style-transfer/blob/master/notebooks/3_Neural_Network- based_Image_Classifier-2.ipynb 21.http://playground.tensorflow.org/; http://www.sciencedirect.com/science/article/pii/089360809190009T 22.— 23.http://cs231n.github.io/convolutional-networks/; https://www.youtube.com/watch?v=LxfUGhug-iQ 24.http://cs231n.github.io/convolutional-networks/ 25.http://cs231n.github.io/convolutional-networks/ 26.http://cs231n.github.io/convolutional-networks/ -
References and further reading 27.http://cs231n.github.io/convolutional-networks/ 28.https://github.com/hnarayanan/artistic-style-transfer/blob/master/notebooks/4_Convolutional_Neural_Network- based_Image_Classifier.ipynb; https://www.tensorflow.org/get_started/mnist/pros 29.https://transcranial.github.io/keras-js/#/mnist-cnn 30.http://www.deeplearningbook.org/contents/intro.html;
https://www.youtube.com/watch?v=AgkfIQ4IGaM; http://www.matthewzeiler.com/pubs/arxive2013/arxive2013.pdf 31.— 32.https://arxiv.org/abs/1409.1556; http://image-net.org/challenges/LSVRC/2014/results 33.http://www.image-net.org; http://www.fast.ai/2017/01/03/keras/; https://www.youtube.com/watch?v=UeheTiBJ0Io 34.https://github.com/hnarayanan/artistic-style-transfer/blob/master/notebooks/5_VGG_Net_16_the_easy_way.ipynb; https://keras.io/applications/ 35.https://arxiv.org/abs/1508.06576 36.https://arxiv.org/abs/1508.06576 37.https://arxiv.org/abs/1508.06576; https://arxiv.org/abs/1603.08155 38.https://arxiv.org/abs/1508.06576 39.https://arxiv.org/pdf/1412.0035.pdf; https://en.wikipedia.org/wiki/Limited-memory_BFGS -
References and further reading 40.https://github.com/hnarayanan/artistic-style-transfer/blob/master/notebooks/ 6_Artistic_style_transfer_with_a_repurposed_VGG_Net_16.ipynb https://github.com/fchollet/keras/blob/master/examples/neural_style_transfer.py 41.— 42.— 43.—
44.— 45.https://arxiv.org/abs/1603.08155 46.— 47.— 48.https://harishnarayanan.org/writing/artistic-style-transfer/; https://github.com/hnarayanan/artistic-style-transfer 49.— 50.— 51.— 52.—