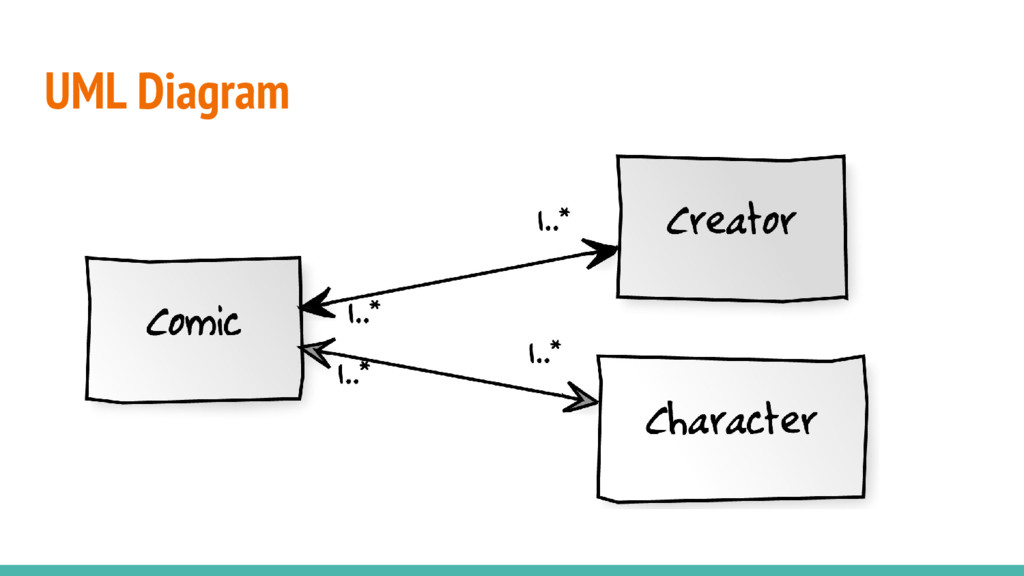
favorite comics, learn more about them • May discover a comic or related series they missed • Can learn who created their favorite comics Curious comic novices: • Can discover the origins and adventures of their favorite characters
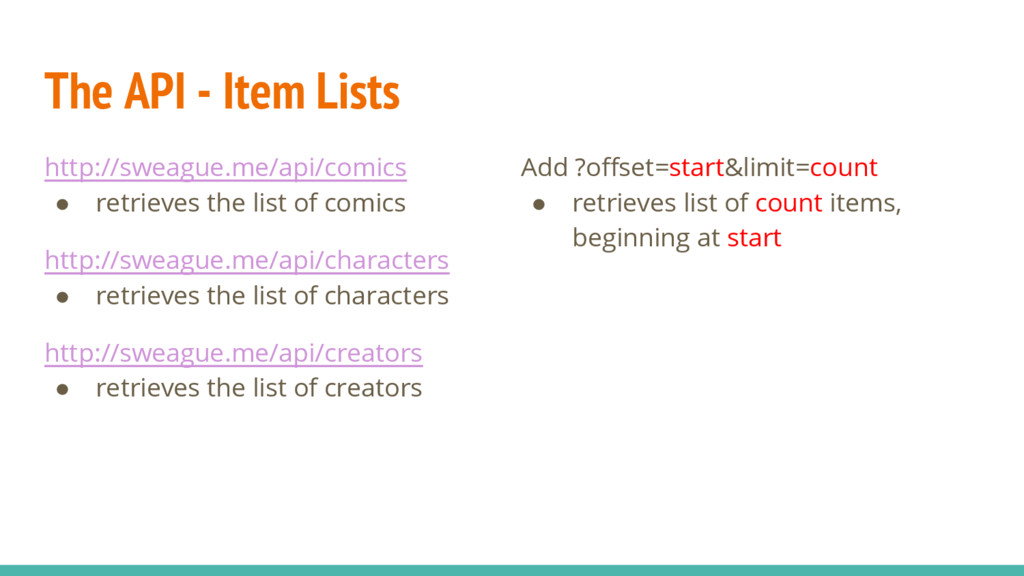
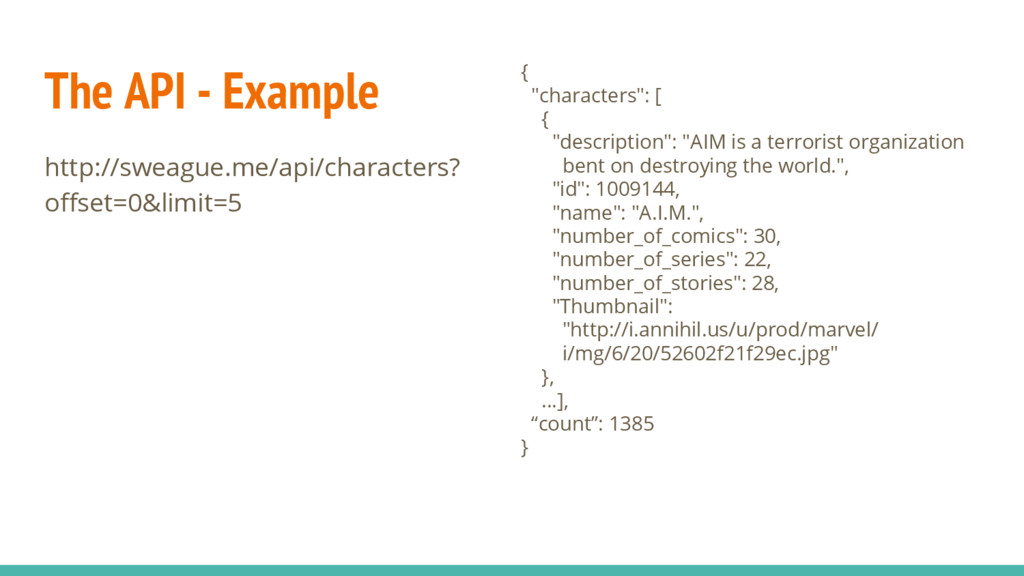
of comics http://sweague.me/api/characters • retrieves the list of characters http://sweague.me/api/creators • retrieves the list of creators Add ?offset=start&limit=count • retrieves list of count items, beginning at start
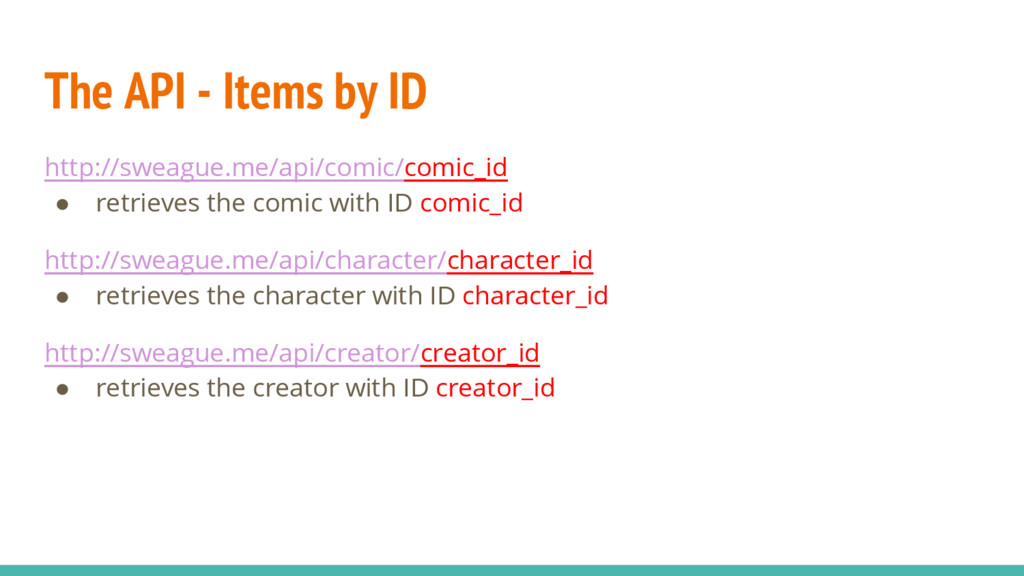
comic with ID comic_id http://sweague.me/api/character/character_id • retrieves the character with ID character_id http://sweague.me/api/creator/creator_id • retrieves the creator with ID creator_id
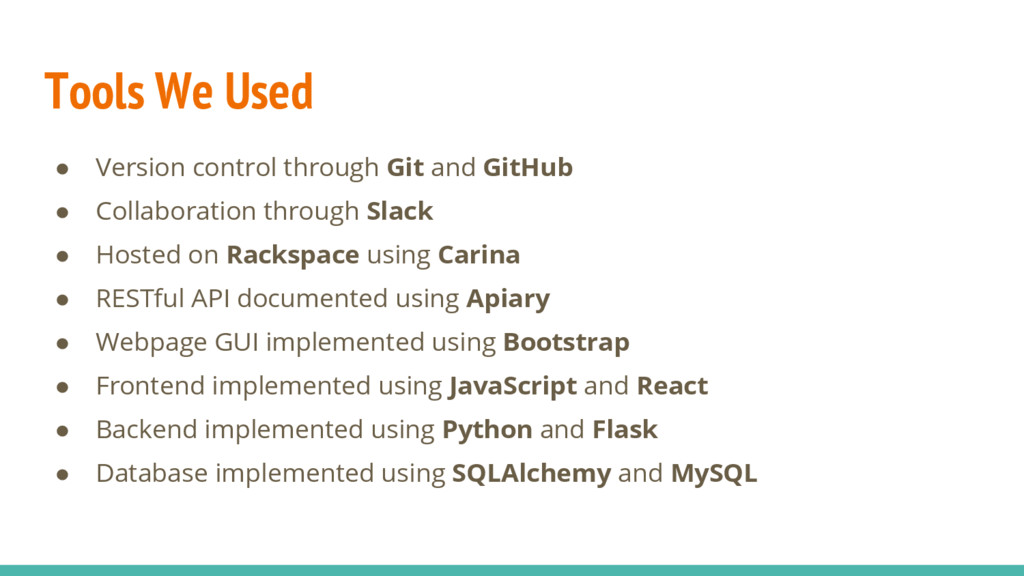
• Collaboration through Slack • Hosted on Rackspace using Carina • RESTful API documented using Apiary • Webpage GUI implemented using Bootstrap • Frontend implemented using JavaScript and React • Backend implemented using Python and Flask • Database implemented using SQLAlchemy and MySQL
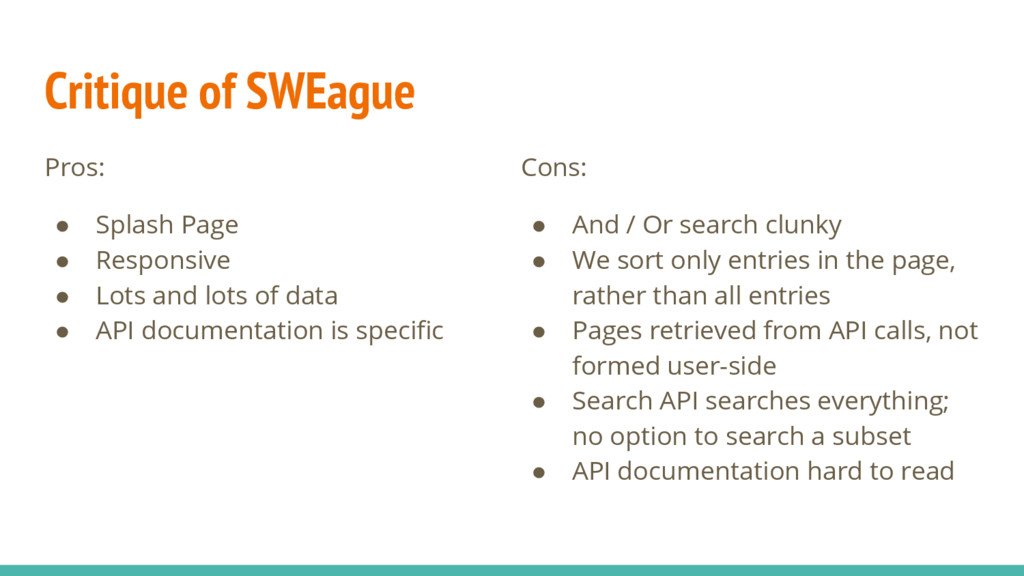
Lots and lots of data • API documentation is specific Cons: • And / Or search clunky • We sort only entries in the page, rather than all entries • Pages retrieved from API calls, not formed user-side • Search API searches everything; no option to search a subset • API documentation hard to read
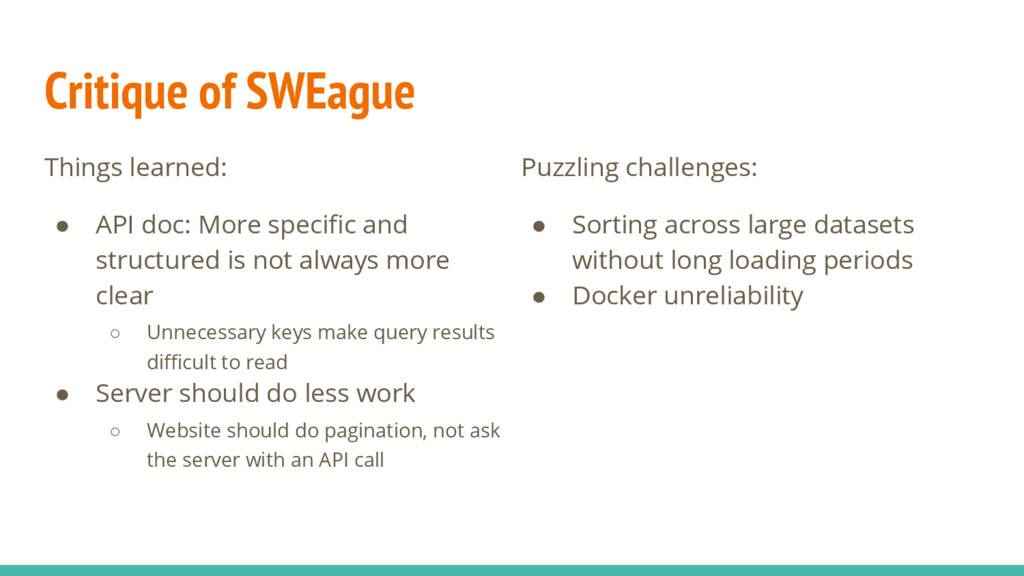
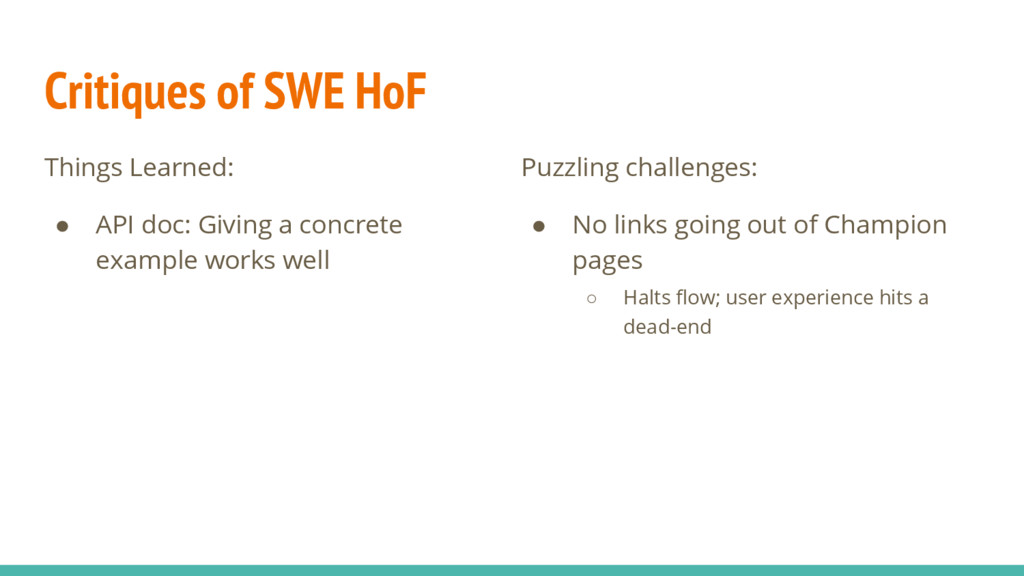
and structured is not always more clear ◦ Unnecessary keys make query results difficult to read • Server should do less work ◦ Website should do pagination, not ask the server with an API call Puzzling challenges: • Sorting across large datasets without long loading periods • Docker unreliability
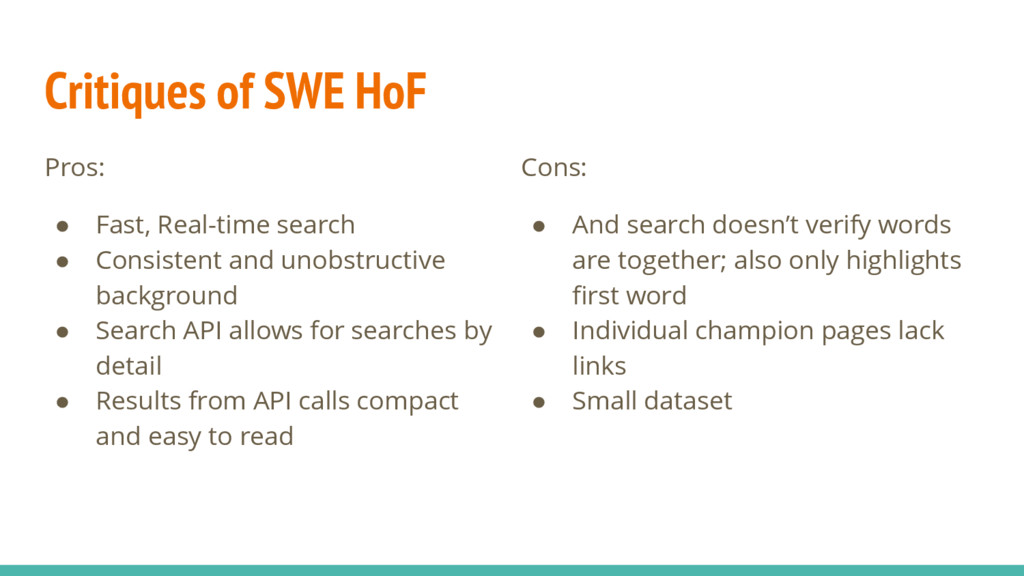
Consistent and unobstructive background • Search API allows for searches by detail • Results from API calls compact and easy to read Cons: • And search doesn’t verify words are together; also only highlights first word • Individual champion pages lack links • Small dataset


 jozono
 ykanoh
 y0hgi
 yu23ki14
 occhi
 teamlab
 masakiokuda
 kakehashi
 gionn
 codmoninc
 tetsuya28
 akitoshiga
 morganepeng
 rkendrick25
 geoffreycrofte
 khoart
 marketingsoph
 wjessup
 vanstee
 akashhashmi
 aleyda
 colly
 frankvandijk