the time." —Werner Vogels, Amazon CTO In distributed systems, failure isn't just possible—it's inevitable. The question isn't if your systems will fail, but when, how, and at what cost. Key Point: In systems with thousands of components, something is always failing
are no longer sufficient to ensure system reliability. Modern infrastructures must plan for failure proactively. Resilience Over Redundancy It's not about avoiding failure entirely—it's about recovering fast and minimizing impact. Resilience is a design goal, not an afterthought. Preparing for the Unknown System complexity means failures are unpredictable. Strategies that embrace this uncertainty are now critical for survival.
failure, antifragile systems grow stronger through disruptions. They use adversity to evolve and adapt. Incorporating chaos inputs, real-time feedback, and diversification to create systems that optimize under stress.
Monkey tool, which randomly terminates production instances. This wasn't madness—it was survival. Practical chaos engineering involves • Starting small with controlled experiments in staging environments • Advancing to "game days" where teams respond to simulated failures • Implementing continuous chaos testing in production with appropriate safeguards • Documenting and learning from each induced failure
Deliberately terminates random instances in production • Ensures systems can handle component failures • Transformed into an entire discipline: Chaos Engineering
and safety mechanism that prevents your application from continuously making requests to a service that has problems or is down. Isolation as a Strategy Circuit breakers prevent cascading failures by failing fast when downstream services degrade
• Kubernetes Pod Autoscaling that scale based on custom metrics • Predictive scaling systems that analyze historical patterns and scale preemptively • Resource quotas that automatically redistribute capacity during degraded performance • Intelligent load shedding that prioritizes traffic based on business impact
Logs, traces, and metrics together form the backbone of modern observability stacks that give engineers actionable insights. Monitoring must always establish baseline behaviour and detect anomalies automatically. It should also distinguish between noise and actionable signals.
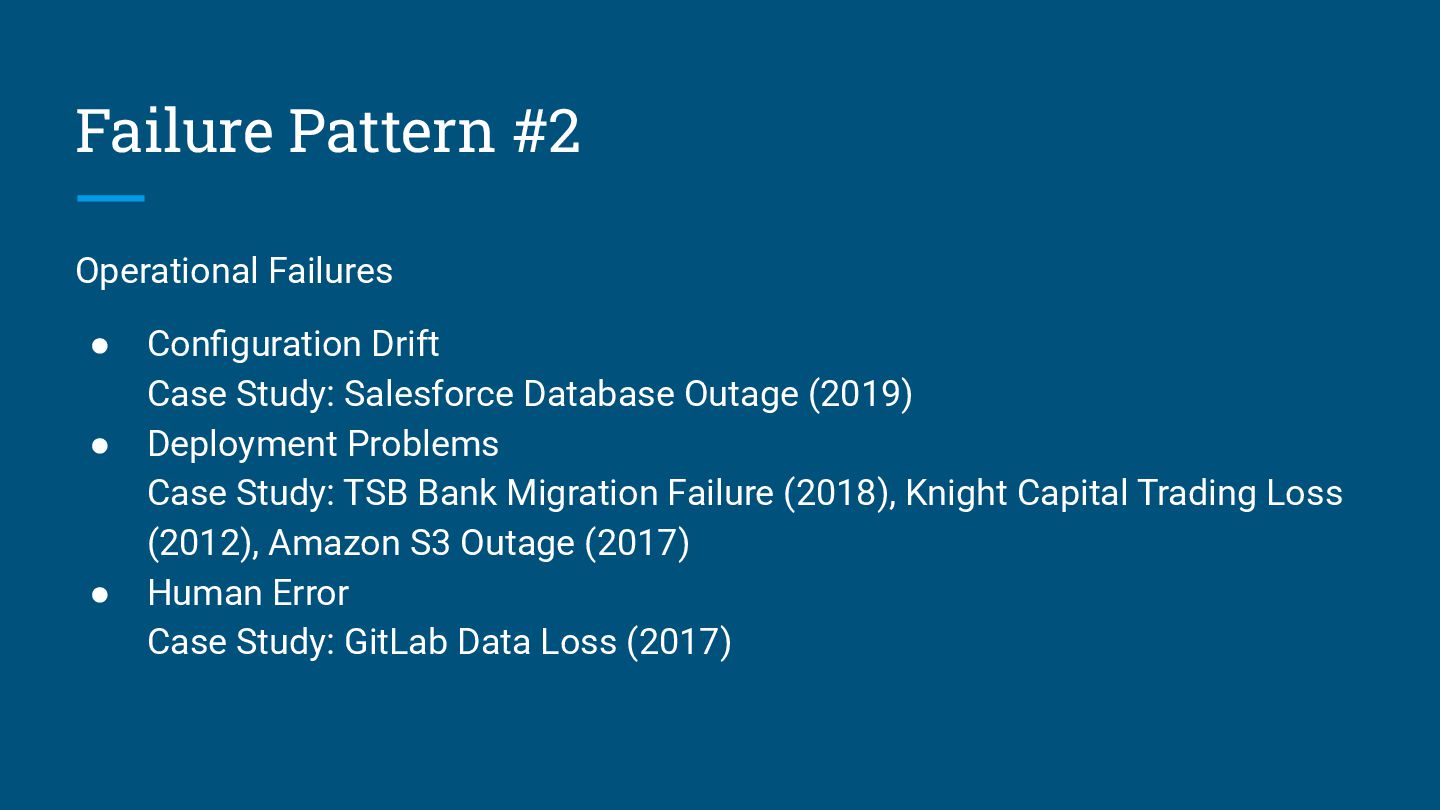
Salesforce Database Outage (2019) • Deployment Problems Case Study: TSB Bank Migration Failure (2018), Knight Capital Trading Loss (2012), Amazon S3 Outage (2017) • Human Error Case Study: GitLab Data Loss (2017)
of downtime per year. Achieving this requires • Eliminating all single points of failure • Implementing zero-downtime deployments and rollbacks • Designing for partial availability during degradation • Redundant Infrastructure • Resilient Network Architecture • Comprehensive Monitoring • Microservice design with resilience patterns
Measure Use architecture reviews and failure modelling to locate single points of failure and fragile dependencies. Apply retry mechanisms, bulkheads, circuit breakers, and timeouts as foundational patterns in distributed systems. Define SLIs, SLOs, and error budgets; use dashboards and tracing to observe system health in real time.
bounce back stronger? Failure is not a risk—it's a certainty. Building failure-resilient distributed systems requires bold design, continuous experimentation, and a culture of resilience. With the right tools and mindset, we can build systems that don't just survive chaos but thrive in it.


 infraplumber0
 teamlab
 odashi
 tetsuya28
 puhitaku
 hiracky16
 codmoninc
 makocchi
 ykanoh
 shuta13
 yazm
 kairim0
 sansantech
 katarinadahlin
 marcelosomers
 csswizardry
 sabderemane
 swwweet
 ipullrank
 mlcsv
 ryanjones
 jonoalderson
 tmiket
 asonas
 davetheseo