Share
Embed
Find me quickly... and simply.
A talk on basics of text search on webpages and basic usage of Apache Solr for it.
Jernej Virag
April 26, 2014
Transcript
25 slides
-
– Johnny, newbie developer “What do you mean with ‘different
words can mean the same things?’” “It takes HOW long to find results?” “It takes HOW much work to group results?” -
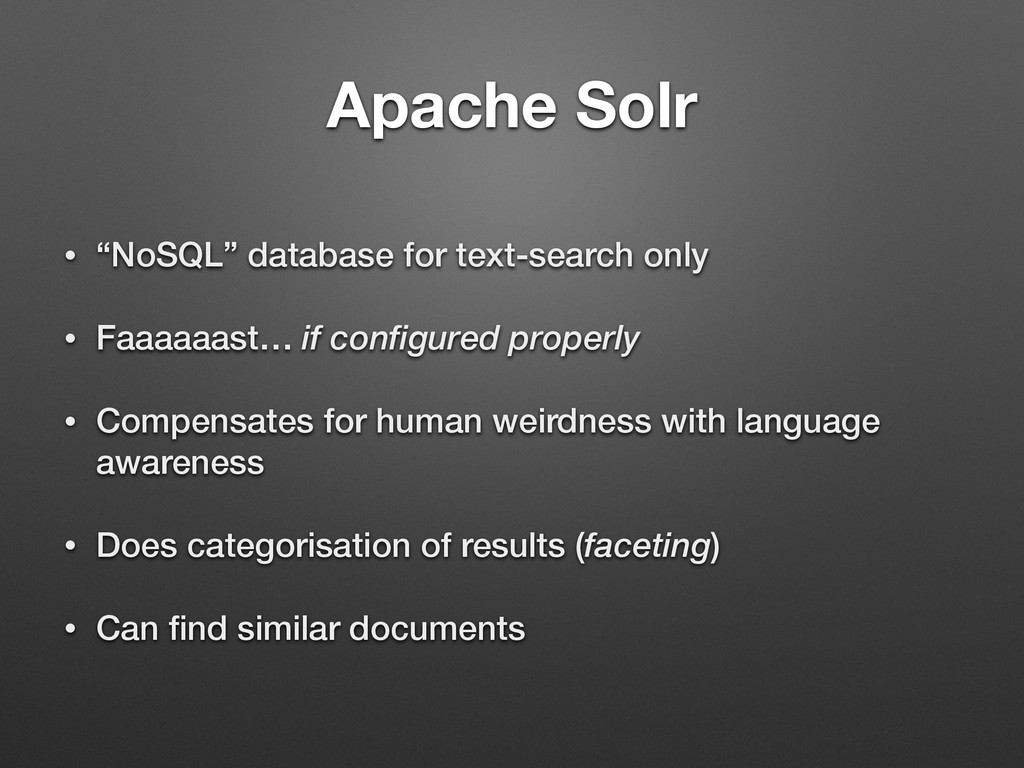
Apache Solr • “NoSQL” database for text-search only • Faaaaaast…
if configured properly • Compensates for human weirdness with language awareness • Does categorisation of results (faceting) • Can find similar documents -
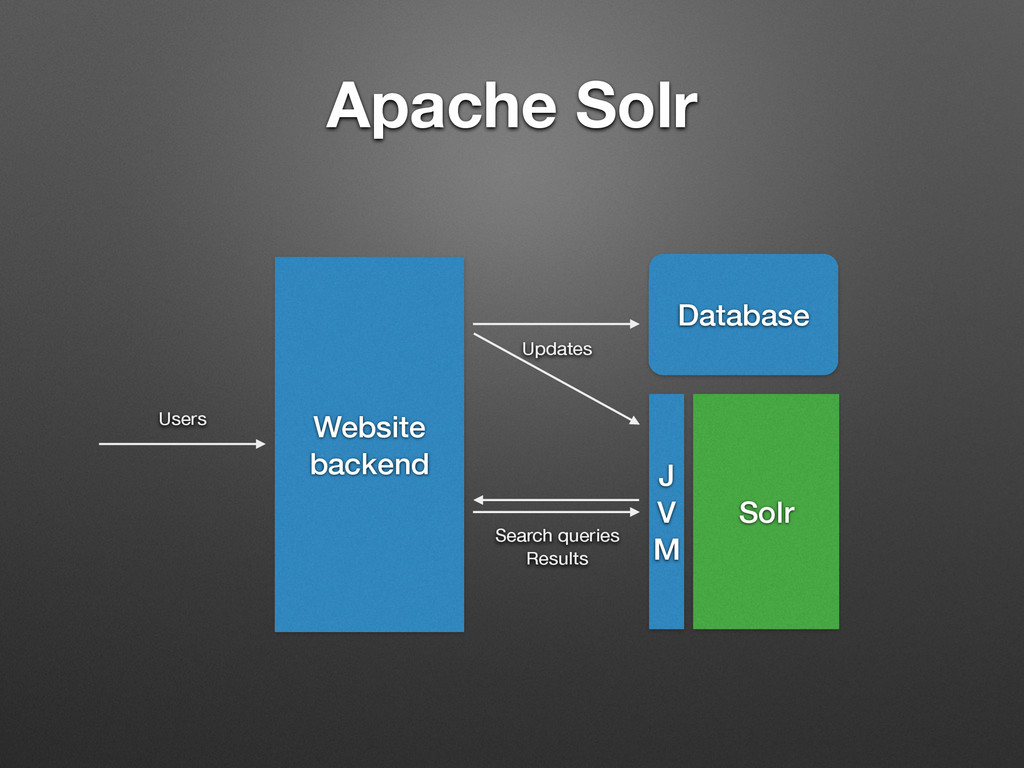
Apache Solr Website backend Database Solr J V M Users
Search queries Results Updates -
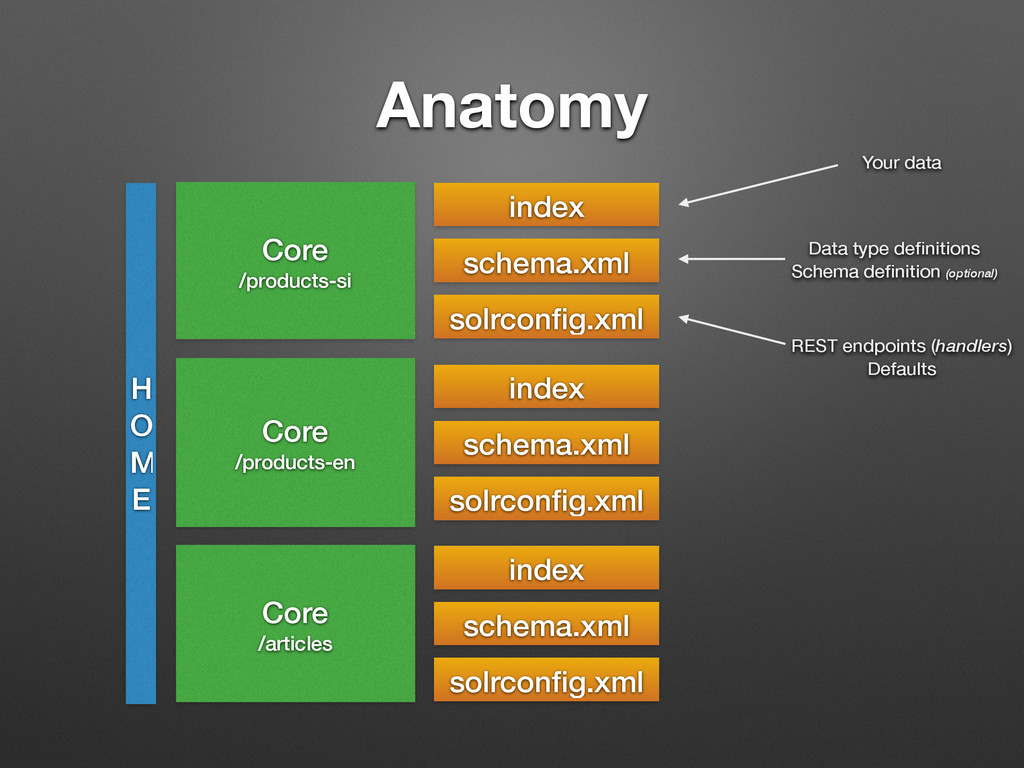
Anatomy H O M E Core /products-si Core /products-en Core
/articles index schema.xml solrconfig.xml index schema.xml solrconfig.xml index schema.xml solrconfig.xml Your data Data type definitions Schema definition (optional) REST endpoints (handlers) Defaults -
Schema.xml • Datatypes in your index - <fieldType> • (!)
Defines how language gets processed - <analyzer> / <query> • Fields (columns) and their types - <fields> • Defines which data is kept • See NewsBuddy/solr/config/schema.xml Your CREATE TABLES -
Solrconfig.xml • Sets handlers which handle REST endpoints • Sets
default parameters so you don’t have to send them with each request • Here you • Set field importance • Enable highlighting, faceting, more-like-this and other functionality • Customise other search parameters • See NewsBuddy/solr/config/solrconfig.xml Your search defaults -
– Johnny, newbie developer “Woo it runs! … Why are
search results bad?” -
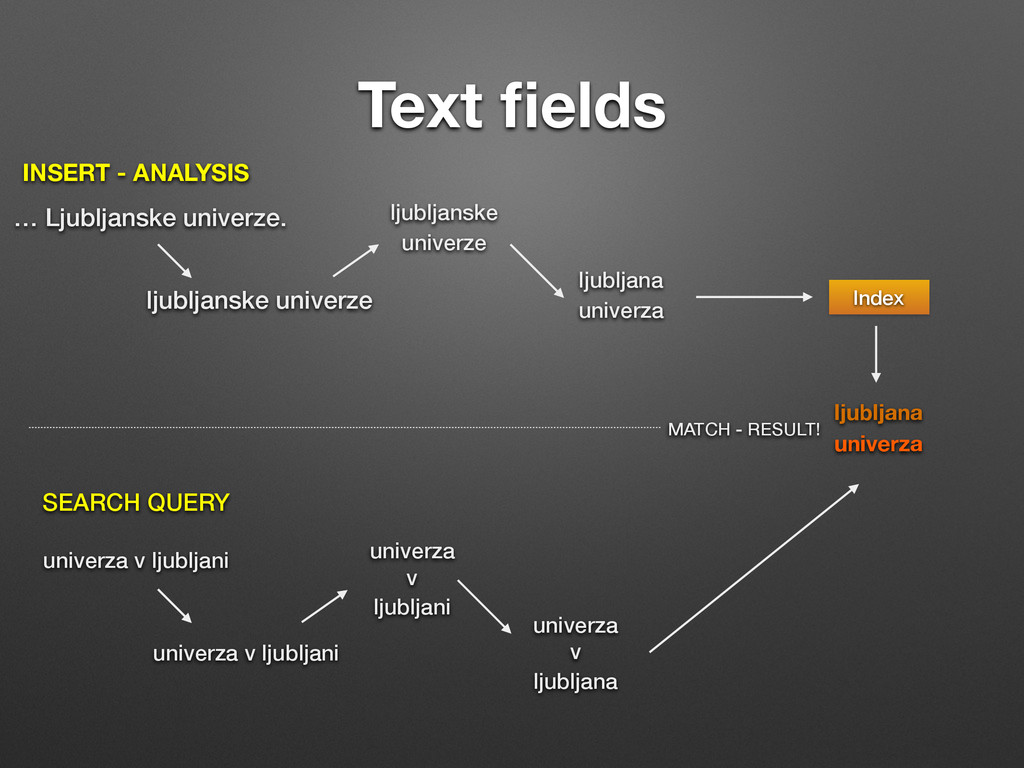
Text fields … Ljubljanske univerze. univerza v ljubljani ljubljanske univerze
ljubljanske univerze ljubljana univerza Index univerza v ljubljani univerza v ljubljani univerza v ljubljana ljubljana univerza MATCH - RESULT! INSERT - ANALYSIS SEARCH QUERY -
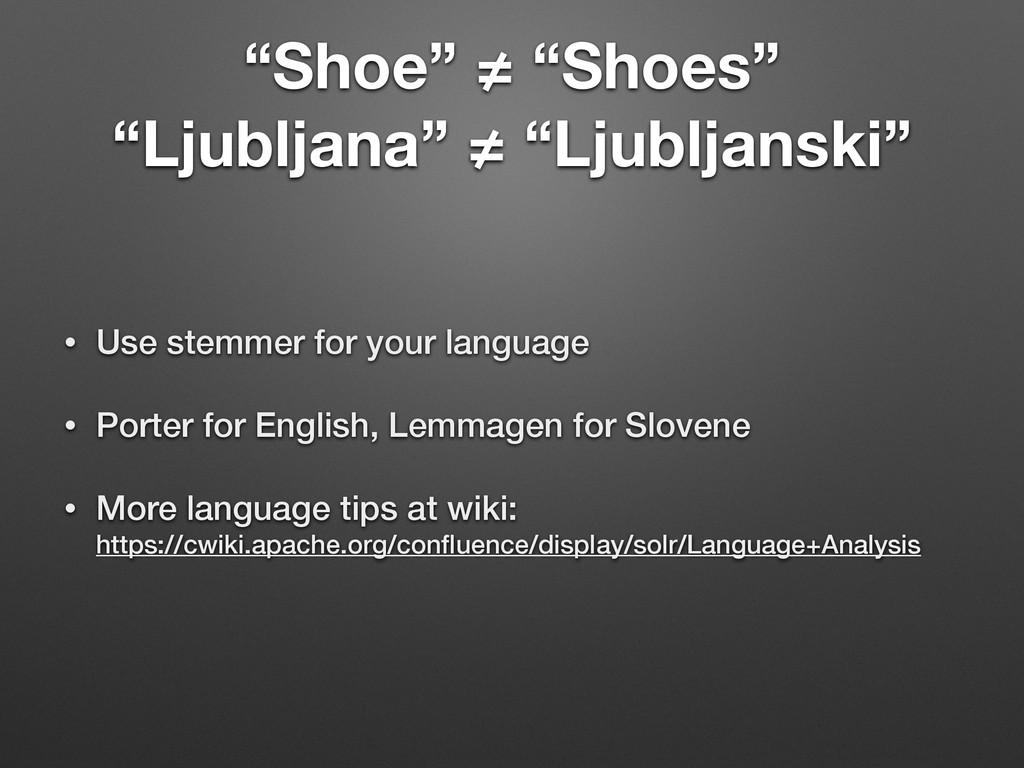
“Shoe” ≠ “Shoes” “Ljubljana” ≠ “Ljubljanski” • Use stemmer for
your language • Porter for English, Lemmagen for Slovene • More language tips at wiki: https://cwiki.apache.org/confluence/display/solr/Language+Analysis -
“zagreb” ≠ “Zagreb” • Solr is case-sensitive • If you
want to make it case insensitive use LowerCaseFilterFactory • If you want to boost correct case, generate lower AND proper case tokens in analysis and at query time. -
Sanitize your text • Break compound words at analysis and
query time (e.g. DropBox -> Drop box so both “dropbox” and “drop box” match) • Clean HTML with HTMLStripCharFilterFactory • Collapse special characters to ASCII with ASCIIFoldingFilter (e.g. Sežana => Sezana so “Sezana” and “Sežana” will be hits) • More tools: https://cwiki.apache.org/confluence/display/solr/Filter+Descriptions https://cwiki.apache.org/confluence/display/solr/CharFilterFactories -
Analyze, analyze, analyze! • Analyze queries users are making on
your site • Pay special attention to queries with no results • Use SynonymFilterFactory to map common “wrong” words (e.g. “kitty” => “cat”, “aple” => “Apple”, …) -
The holy bible • Apache Solr Reference Guide https://cwiki.apache.org/confluence/display/solr/ Getting+Started
• ! Most Google hits will lead you to http://wiki.apache.org/solr which is significantly worse and commonly outdated! -
What else? • Highlighting • Faceting • Similar documents •
Autocomplete suggestions -
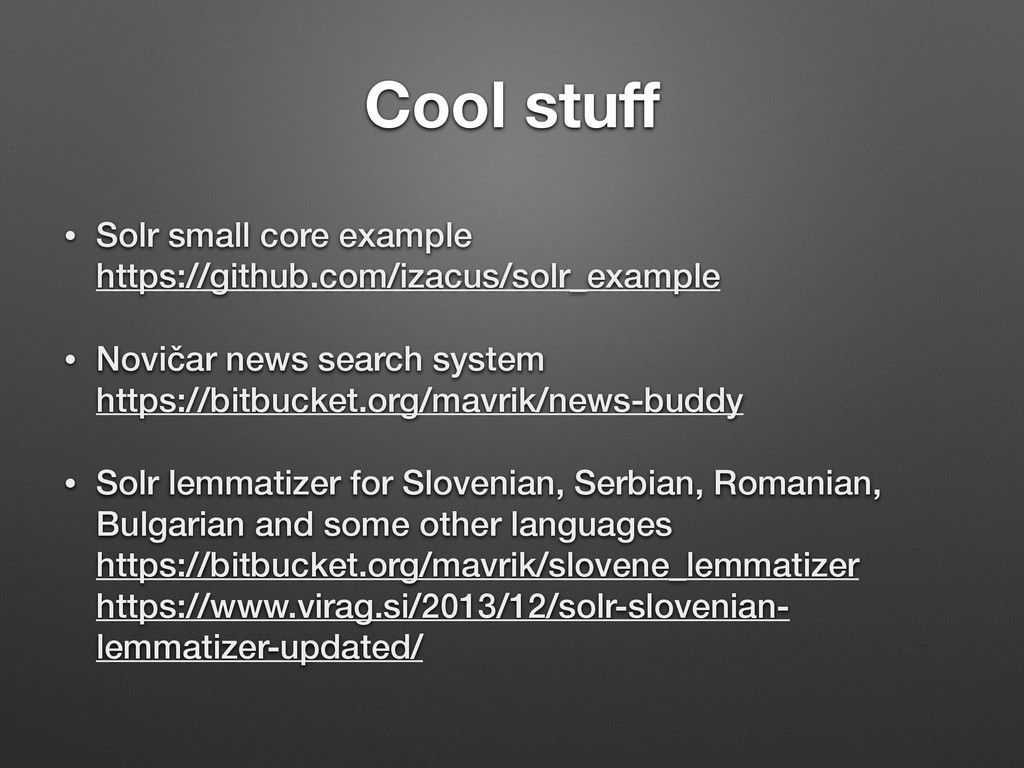
Cool stuff • Solr small core example https://github.com/izacus/solr_example • Novičar
news search system https://bitbucket.org/mavrik/news-buddy • Solr lemmatizer for Slovenian, Serbian, Romanian, Bulgarian and some other languages https://bitbucket.org/mavrik/slovene_lemmatizer https://www.virag.si/2013/12/solr-slovenian- lemmatizer-updated/ -
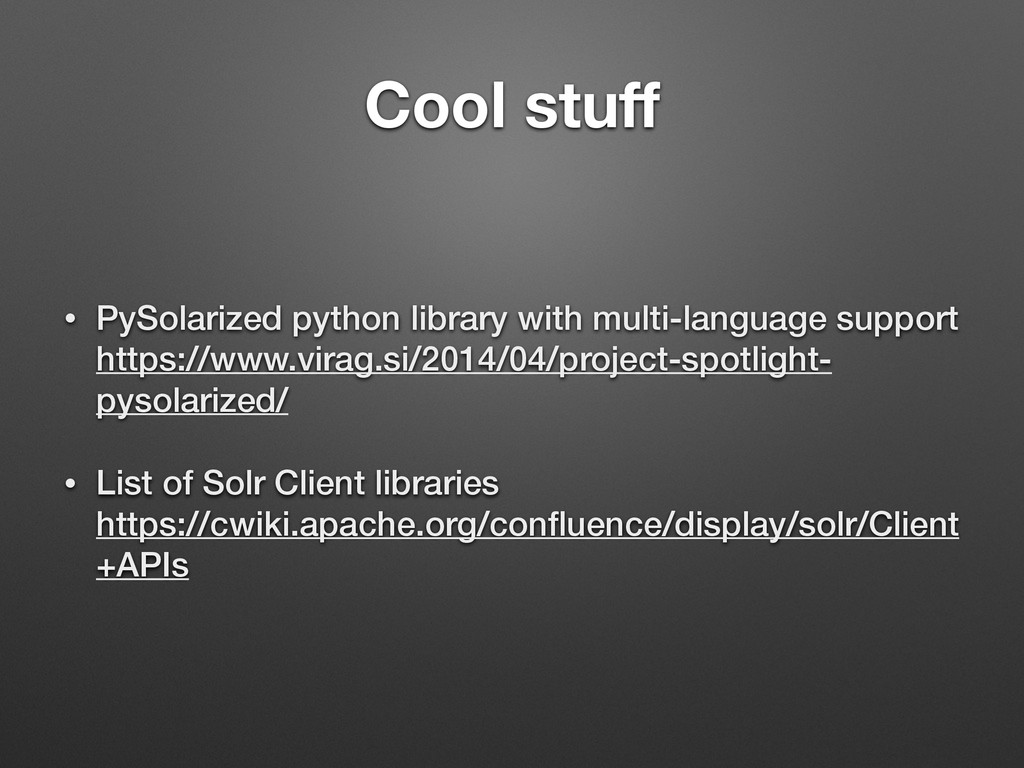
Cool stuff • PySolarized python library with multi-language support https://www.virag.si/2014/04/project-spotlight-
pysolarized/ • List of Solr Client libraries https://cwiki.apache.org/confluence/display/solr/Client +APIs