Share
Embed
[Journal club] MDETR - Modulated Detection for End-to-End Multi-Modal Understanding
Semantic Machine Intelligence Lab., Keio Univ. PRO
July 20, 2021
Transcript
16 slides
-
MDETR - Modulated Detection for End-to-End Multi-Modal Understanding Aishwarya Kamath(NYU),
Mannat Singh(Facebook), Yann LeCun(NYU), Ishan Misra(Facebook), Gabriel Synnaeve(Facebook), Nicolas Carion(NYU) 杉浦孔明研究室 九曜克之 Kamath, A., Singh, M., LeCun, Y., Misra, I., Synnaeve, G., & Carion, N. (2021). MDETR--Modulated Detection for End-to-End Multi-Modal Understanding. arXiv preprint arXiv:2104.12763. -
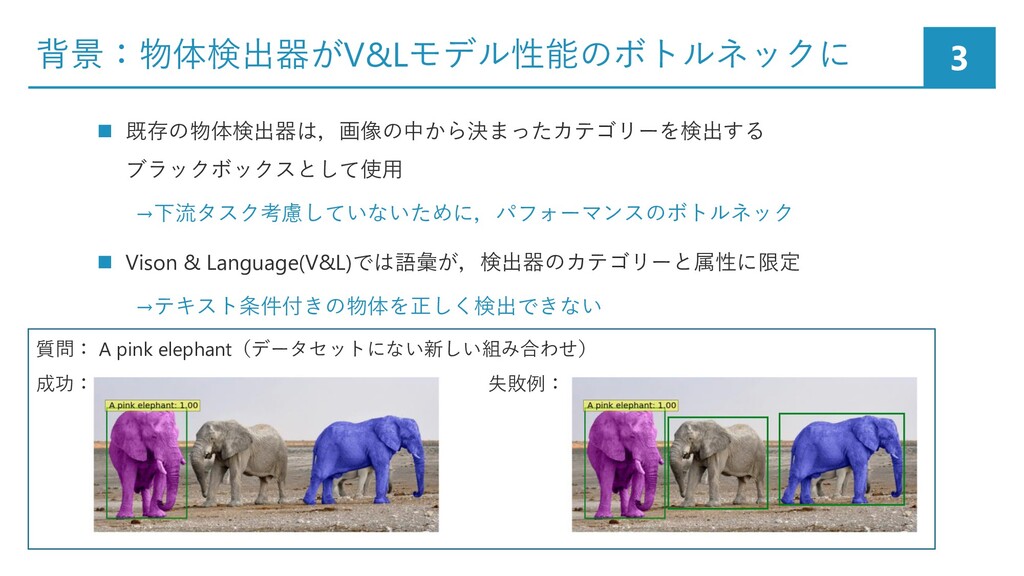
背景:物体検出器がV&Lモデル性能のボトルネックに 3 ◼ 既存の物体検出器は,画像の中から決まったカテゴリーを検出する ブラックボックスとして使用 →下流タスク考慮していないために,パフォーマンスのボトルネック ◼ Vison & Language(V&L)では語彙が,検出器のカテゴリーと属性に限定
→テキスト条件付きの物体を正しく検出できない 質問: A pink elephant(データセットにない新しい組み合わせ) 成功: 失敗例: -
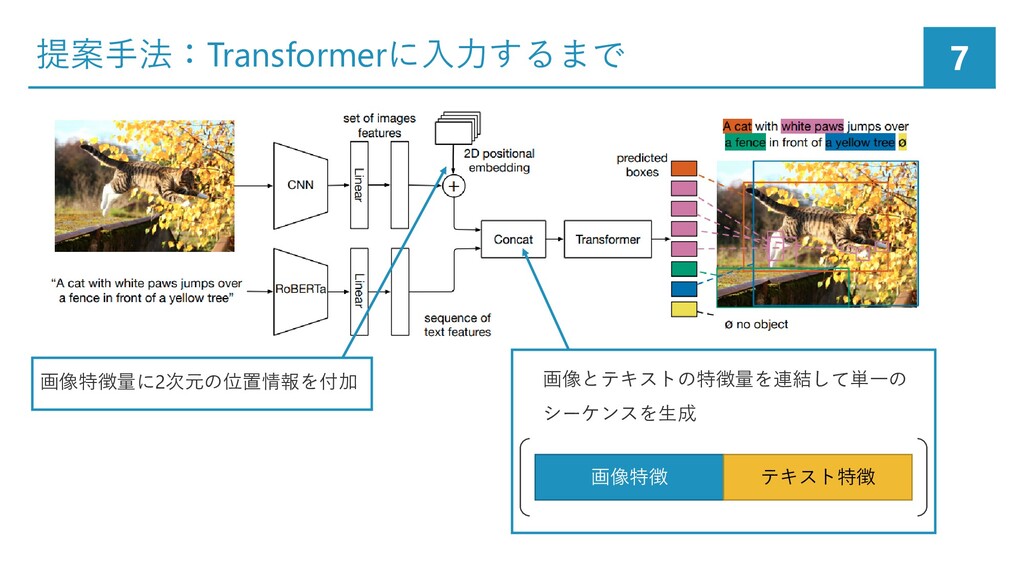
関連研究:下流タスクの性能向上は実証されていない 4 カテゴリ 文献 概要 物体検出 [Carion+,ECCV20] Transformerを用いた物体検出モデルDETRを提案 テキスト 条件付き
物体検出 [Yang+, ICCV19] テキストの埋め込みベクトルをYOLOv3に組み込む [Hinami+, EMNLP18] Faster R-CNNをオープンボキャブラリークエリに適応させたQuery-Adaptive R-CNNを提案 テキスト埋め込みベクトルをオブジェクト分類器と回帰器に変換 ◼ Visiual Question Answering(VQA)などの下流タスクのパフォーマンスを向上させることは 実証されていない -
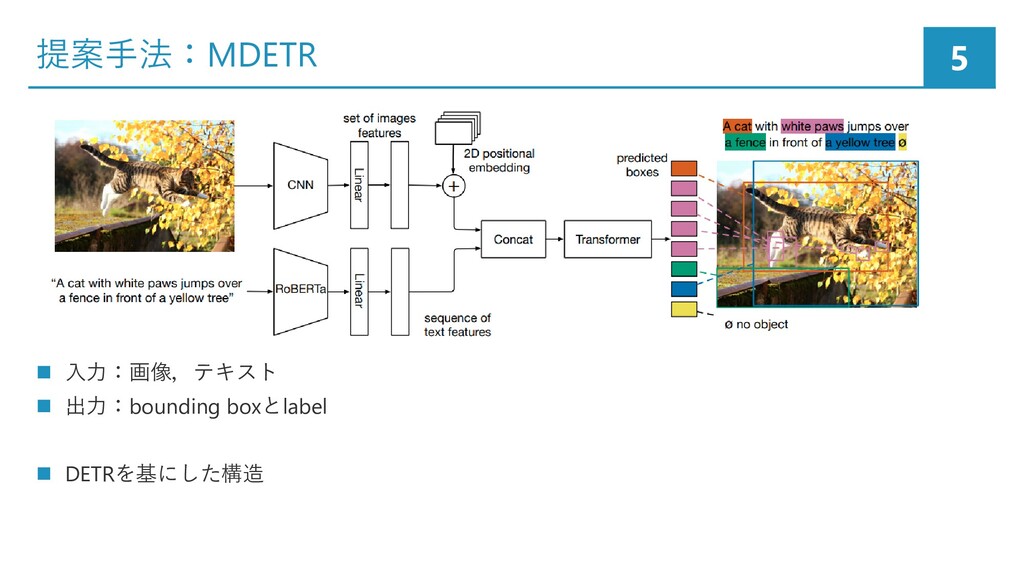
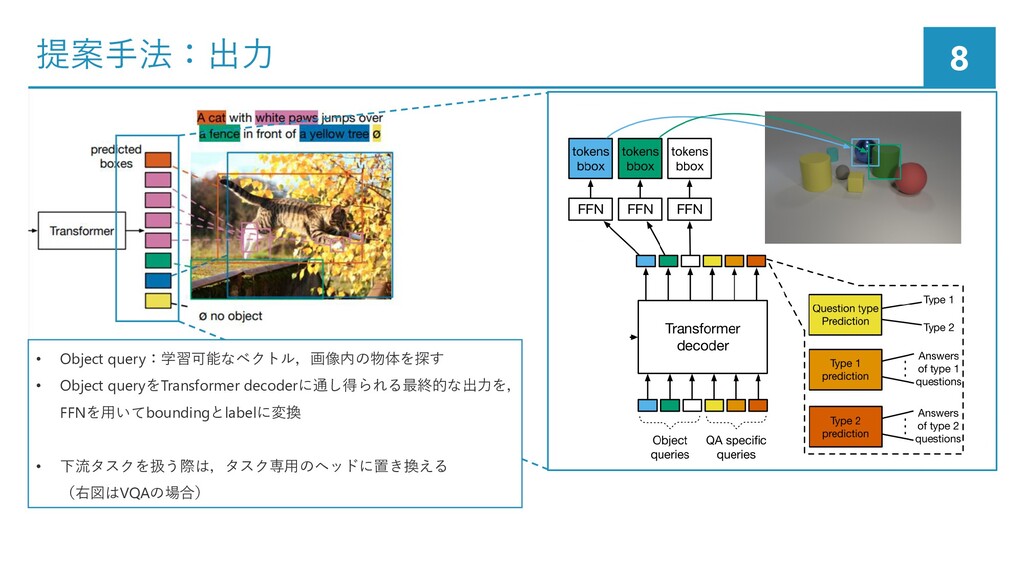
提案手法:出力 8 • Object query:学習可能なベクトル,画像内の物体を探す • Object queryをTransformer decoderに通し得られる最終的な出力を, FFNを用いてboundingとlabelに変換
• 下流タスクを扱う際は,タスク専用のヘッドに置き換える (右図はVQAの場合) -
実験設定 9 ◼ 事前学習 ◼ テキスト条件付き物体検出:自由形式のテキストの中で言及されているすべての オブジェクトを画像内から検出する ◼ 下流タスク ◼
参照表現理解,参照表現付セグメンテーション,VQA -
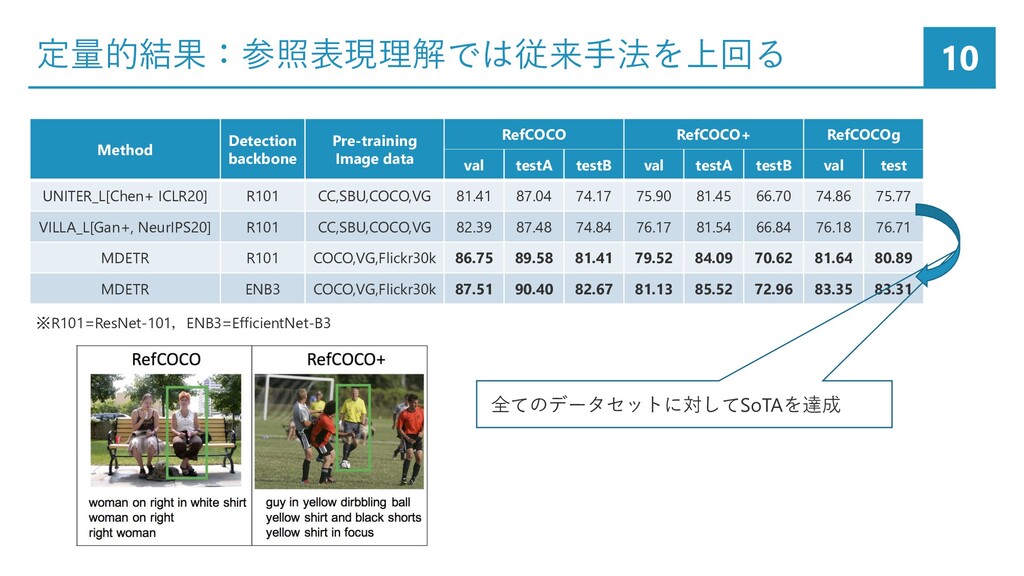
定量的結果:参照表現理解では従来手法を上回る 10 Method Detection backbone Pre-training Image data RefCOCO RefCOCO+
RefCOCOg val testA testB val testA testB val test UNITER_L[Chen+ ICLR20] R101 CC,SBU,COCO,VG 81.41 87.04 74.17 75.90 81.45 66.70 74.86 75.77 VILLA_L[Gan+, NeurIPS20] R101 CC,SBU,COCO,VG 82.39 87.48 74.84 76.17 81.54 66.84 76.18 76.71 MDETR R101 COCO,VG,Flickr30k 86.75 89.58 81.41 79.52 84.09 70.62 81.64 80.89 MDETR ENB3 COCO,VG,Flickr30k 87.51 90.40 82.67 81.13 85.52 72.96 83.35 83.31 全てのデータセットに対してSoTAを達成 ※R101=ResNet-101,ENB3=EfficientNet-B3 -
Method Backbone PhraseCut M-IoU [email protected] [email protected] [email protected] RMI[Chen+,ICCV19] R101 21.1
22.0 11.6 1.5 HULANet[Wu+,CVPR20] R101 41.3 42.4 27.0 5.7 MDETR R101 53.1 56.1 38.9 11.9 MDETR ENB3 53.7 57.5 39.9 11.9 定量的結果:セグメンテーションでも従来手法を上回る 11 ◼ PhraseCut[Wu+, CVPR20]:VG上で収集 した参照表現付セグメンテーション用 データセット ResNet-101を用いた既存モデル HULANetに比べ,すべての指標で 上回る EfficientNetを用いると,更なる向上 Pr@x: IoU>x を成功とした場合のPrecision -
Method Pre-training img data Test-dev Test-std LXMERT[Tan+, 19] VG, COCO(180k)
60.0 60.32 VL-T5[Cho, 21] VG, COCO(180k) - 60.80 OSCAR[Li+, ECCV20] VG, COCO, Flicker, SBU(4.3M) 61.58 61.62 VinVL[Zhang+, 21] VG, COCO, Onject365, SBU, Flicker30k, CC, VQA, OpenImagesV5(5.65M) 65.05 64.65 MDETR-R101 VG, COCO, Flicker30k(200k) 62.48 61.99 MDETR-ENB5 VG, COCO, Flicker30k(200k) 62.95 62.45 定量的結果:VQAでは従来手法に匹敵 12 同程度のデータ量を使用する LXMERTとVL-T5の性能を上回る ◼ GQA[Hudson+, CVPR19]:VG上で収集したVQA用データセット A B 事前学習でより多くのデータを 使用するOSCARの性能も上回る -
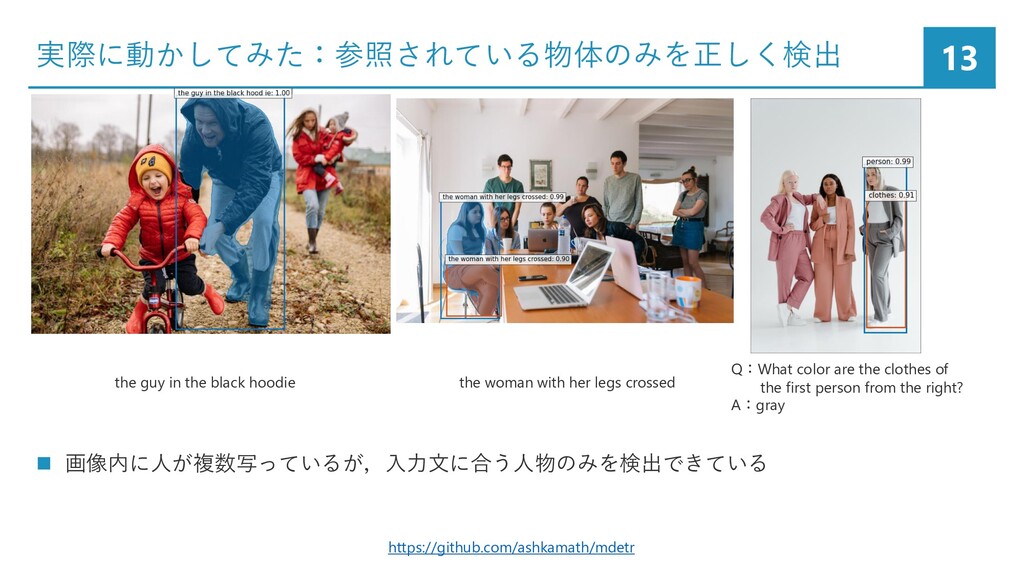
実際に動かしてみた:参照されている物体のみを正しく検出 13 the guy in the black hoodie the woman
with her legs crossed Q:What color are the clothes of the first person from the right? A:gray ◼ 画像内に人が複数写っているが,入力文に合う人物のみを検出できている https://github.com/ashkamath/mdetr -
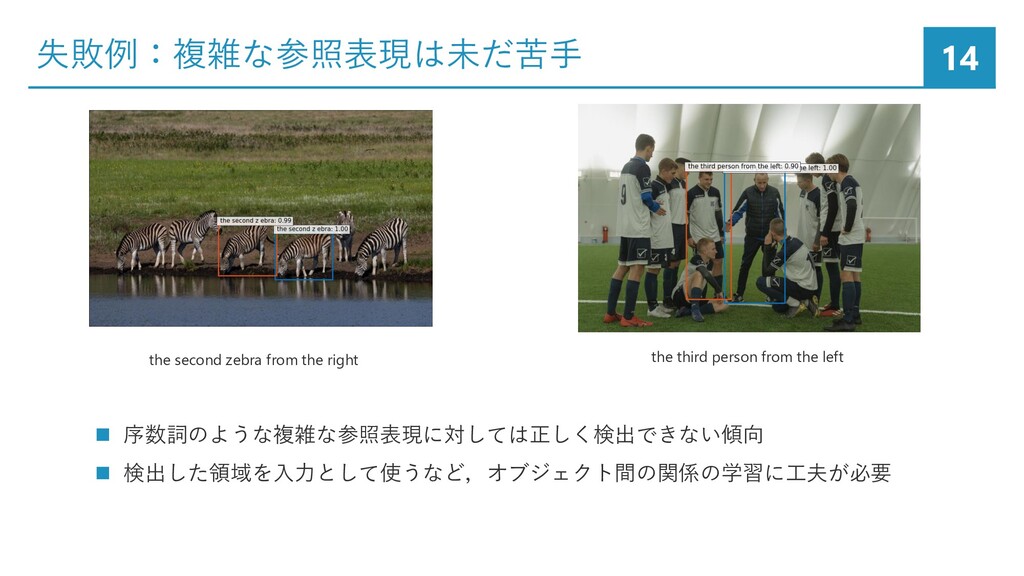
失敗例:複雑な参照表現は未だ苦手 14 ◼ 序数詞のような複雑な参照表現に対しては正しく検出できない傾向 ◼ 検出した領域を入力として使うなど,オブジェクト間の関係の学習に工夫が必要 the second zebra from
the right the third person from the left -
参考文献 16 1. Carion, N., Massa, F., Synnaeve, G., Usunier,
N., Kirillov, A., & Zagoruyko, S. (2020, August). End-to-end object detection with transformers. In European Conference on Computer Vision (pp. 213-229). Springer, Cham. 2. Yang, Z., Gong, B., Wang, L., Huang, W., Yu, D., & Luo, J. (2019). A fast and accurate one-stage approach to visual grounding. In Proceedings of the IEEE/CVF International Conference on Computer Vision (pp. 4683-4693) 3. Hinami, R., & Satoh, S. I. (2017). Discriminative learning of open-vocabulary object retrieval and localization by negative phrase augmentation. arXiv preprint arXiv:1711.09509. 4. Yu, L., Poirson, P., Yang, S., Berg, A. C., & Berg, T. L. (2016, October). Modeling context in referring expressions. In European Conference on Computer Vision (pp. 69-85). Springer, Cham. 5. Wu, C., Lin, Z., Cohen, S., Bui, T., & Maji, S. (2020). Phrasecut: Language-based image segmentation in the wild. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (pp. 10216-10225). 6. Hudson, D. A., & Manning, C. D. (2019). Gqa: A new dataset for real-world visual reasoning and compositional question answering. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition (pp. 6700-6709). 7. Johnson, J., Hariharan, B., Van Der Maaten, L., Fei-Fei, L., Lawrence Zitnick, C., & Girshick, R. (2017). Clevr: A diagnostic dataset for compositional language and elementary visual reasoning. In Proceedings of the IEEE conference on computer vision and pattern recognition (pp. 2901-2910). 8. Plummer, B. A., Wang, L., Cervantes, C. M., Caicedo, J. C., Hockenmaier, J., & Lazebnik, S. (2015). Flickr30k entities: Collecting region-to-phrase correspondences for richer image-to-sentence models. In Proceedings of the IEEE international conference on computer vision (pp. 2641-2649).