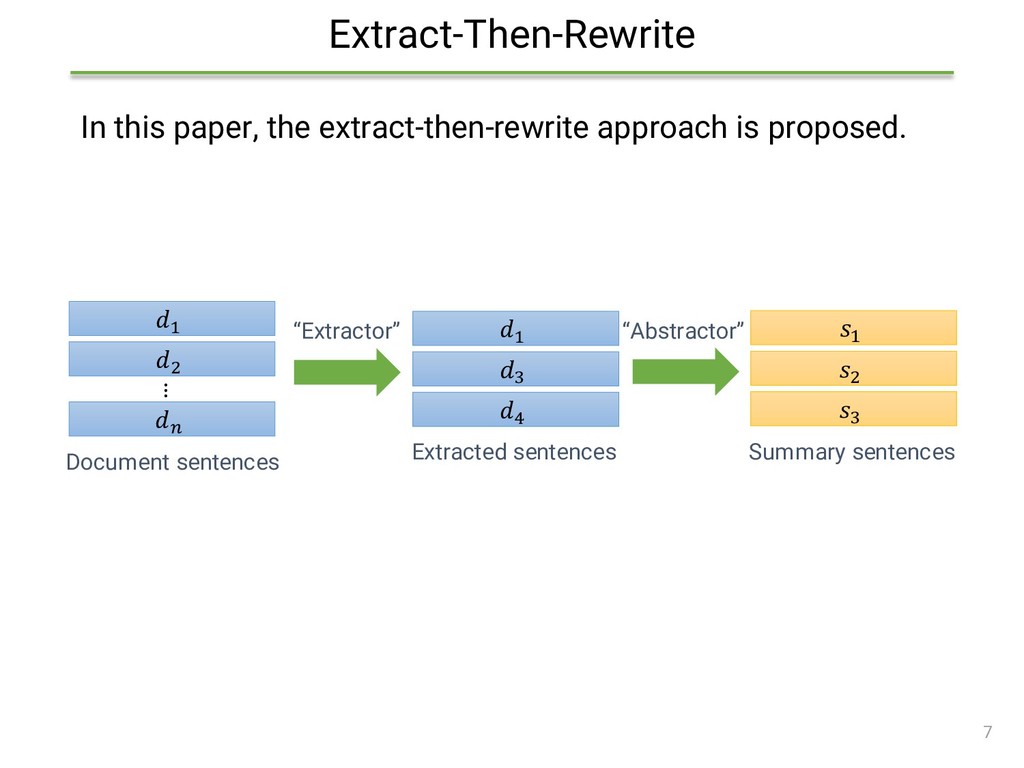
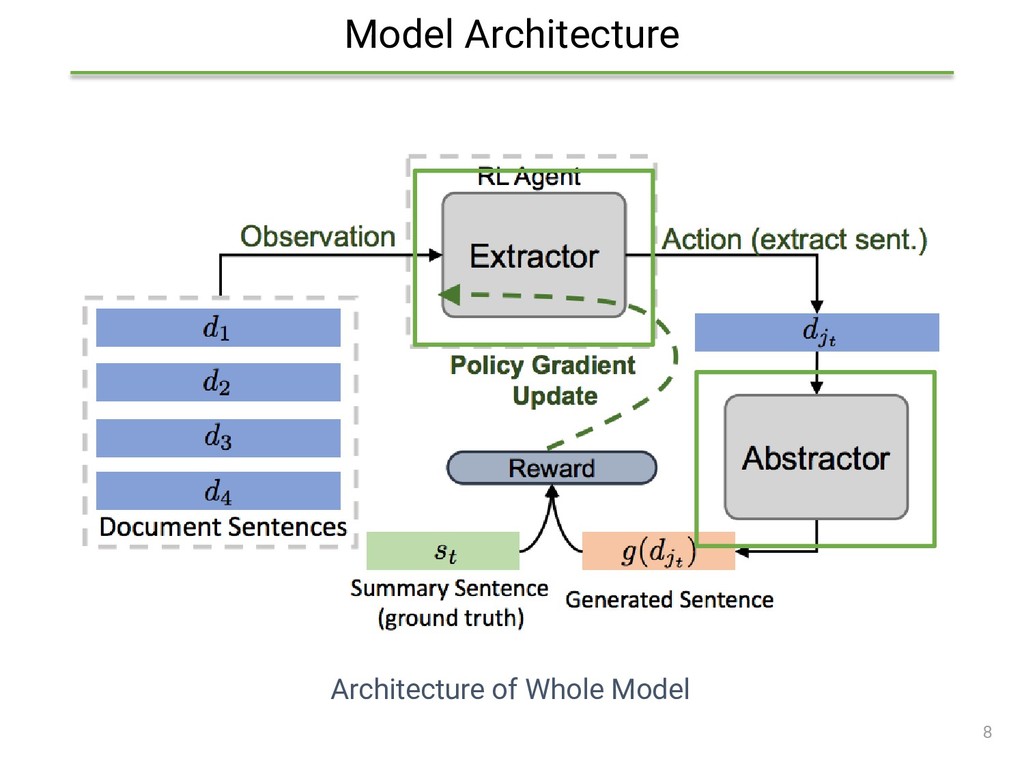
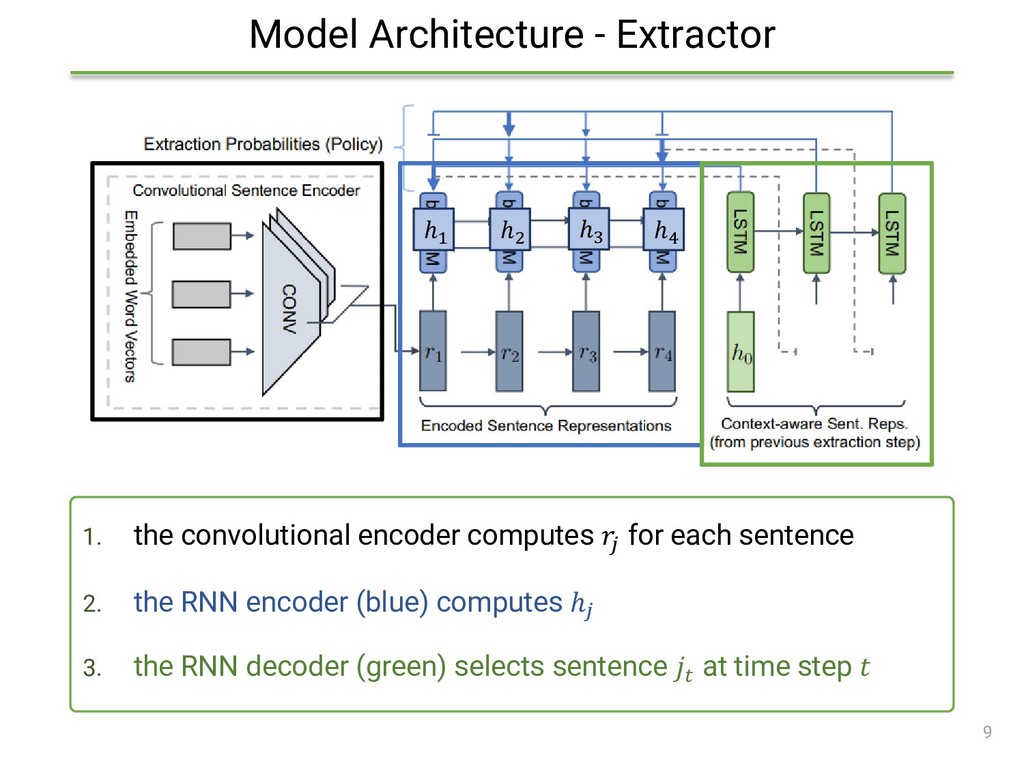
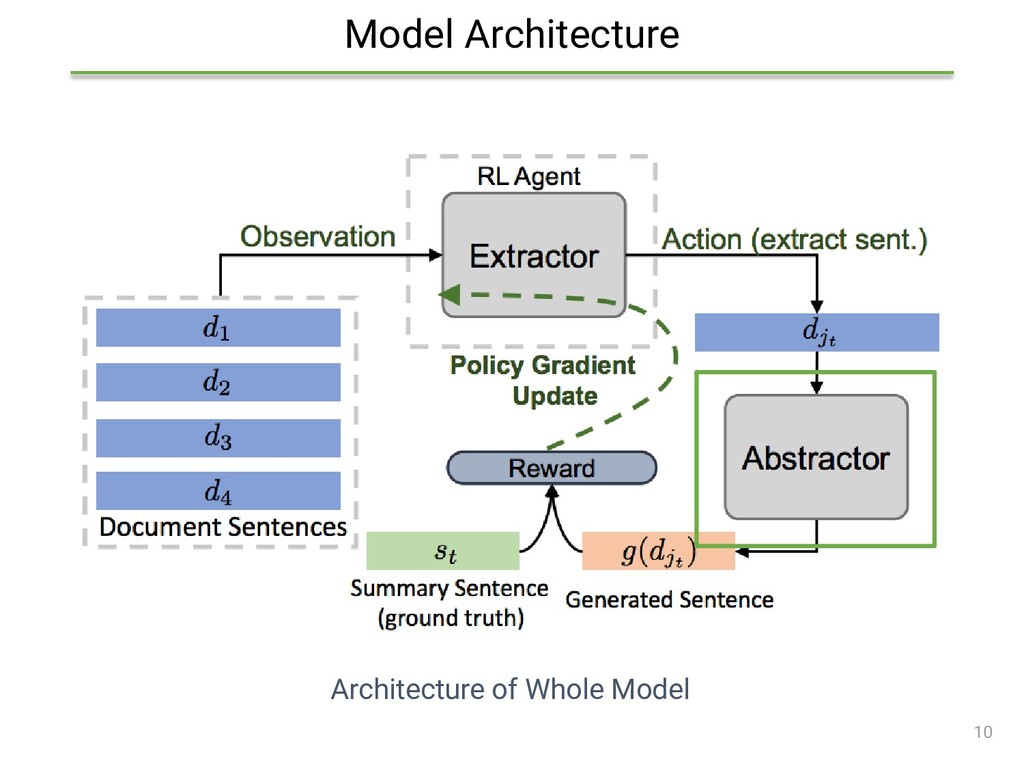
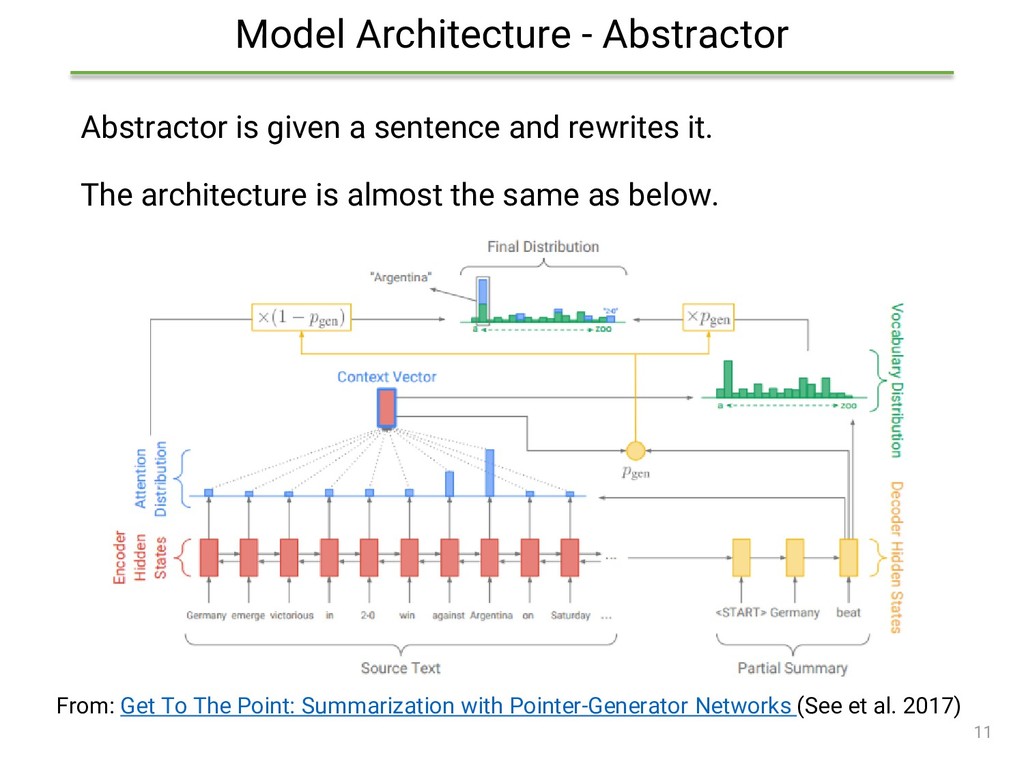
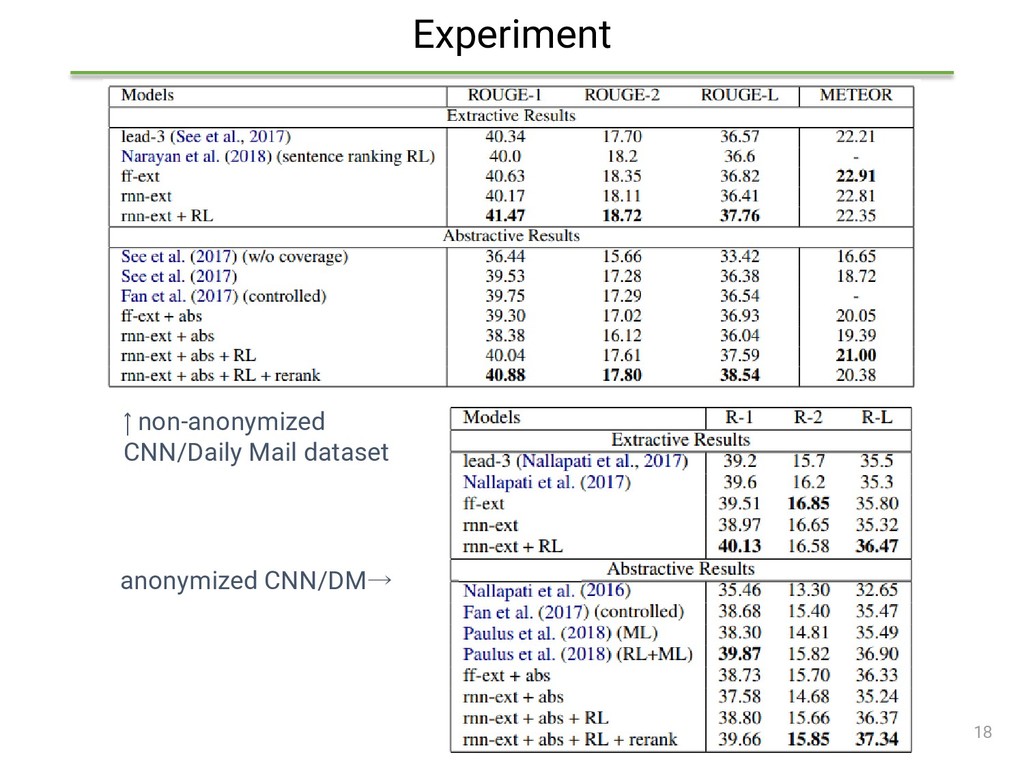
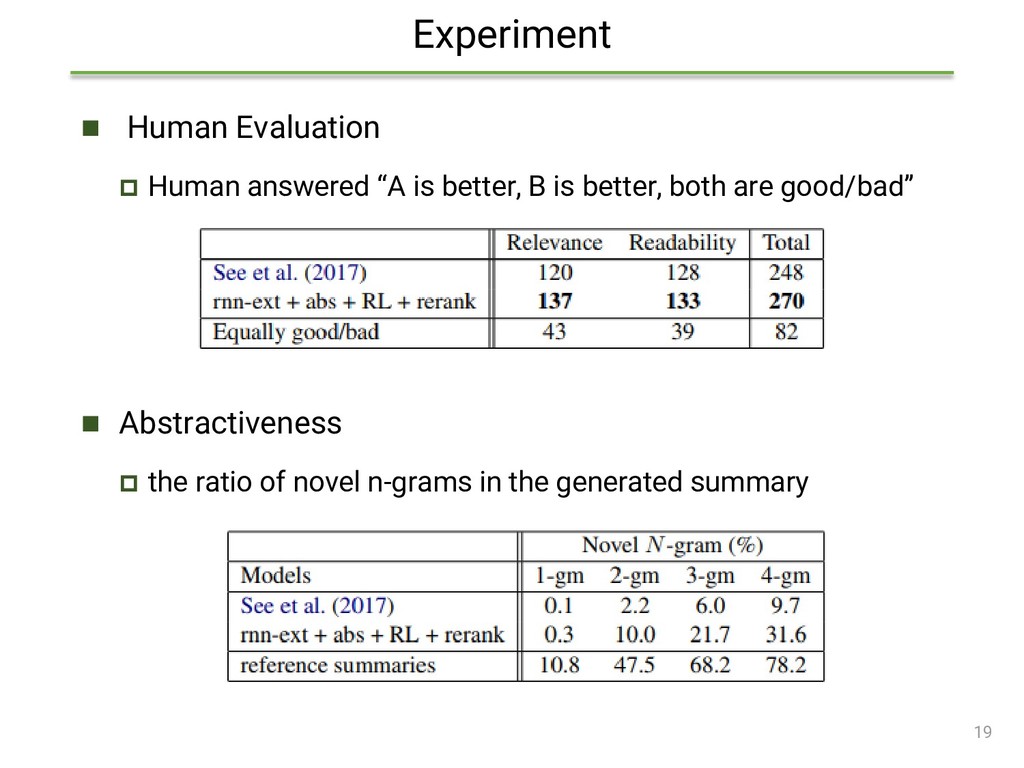
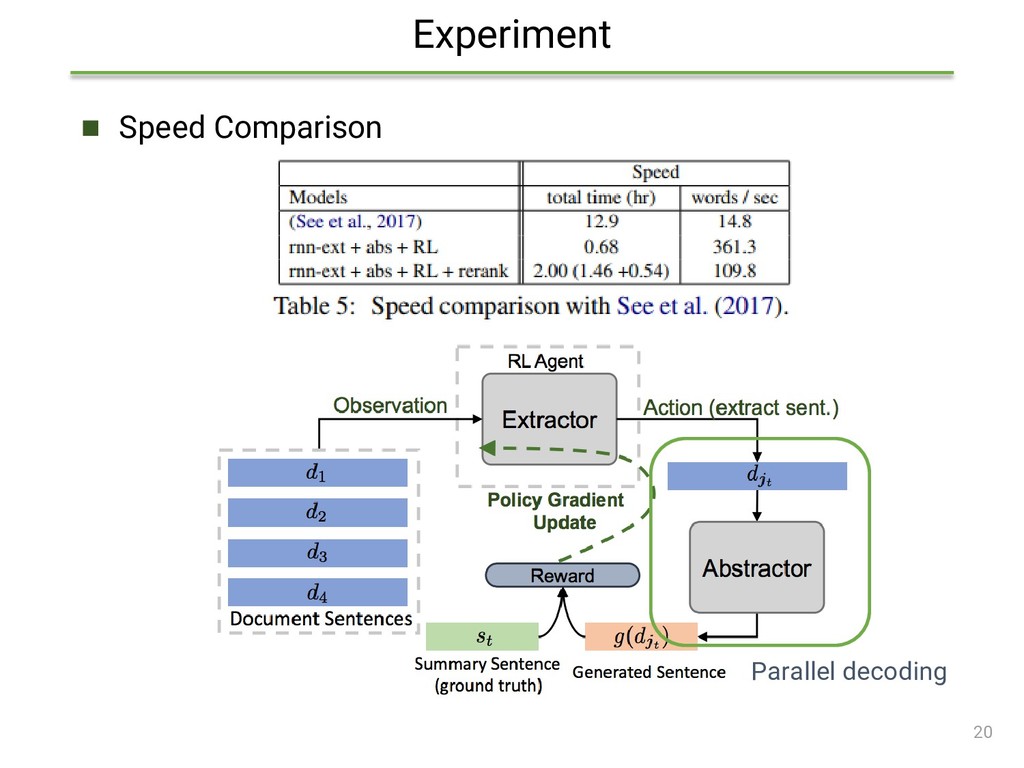
extracts sentences first, then rewrites them Use RL to bridge the nondifferentiable computation ◼ Improve repetition problem At sentence-level, this problem doesn’t occur because model extracts original sentences first At summary, it is improved by Repetition-Avoiding Reranking ◼ Get faster training and inference speed by parallel decoding ◼ SotA on CNN/Daily mail dataset 5
extracts sentences first, then rewrites them Use RL to bridge the nondifferentiable computation ◼ Improve repetition problem At sentence-level, this problem doesn’t occur because model extracts original sentences first At summary, it is improved by Repetition-Avoiding Reranking ◼ Get faster training and inference speed by parallel decoding ◼ SotA on CNN/Daily mail dataset 6
randomly initialized, the extractor would often select sentences that are not relevant, so it would be difficult for the abstractor to learn. Hence, learning is conducted in two phases: 1. Train the Extractor and Abstractor respectively 2. Reinforce-Guided Extraction (train the full model) 12
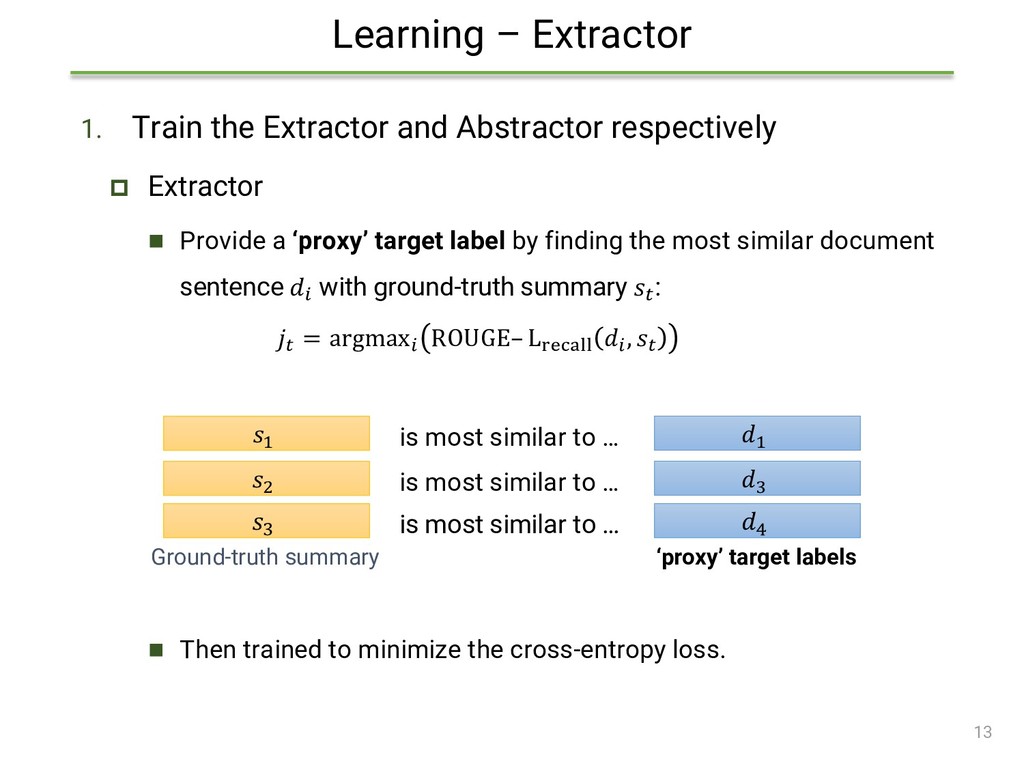
Extractor ◼ Provide a ‘proxy’ target label by finding the most similar document sentence with ground-truth summary : = argmax ROUGE– Lrecall , ◼ Then trained to minimize the cross-entropy loss. 13 1 1 is most similar to … 3 2 is most similar to … 4 3 is most similar to … Ground-truth summary ‘proxy’ target labels
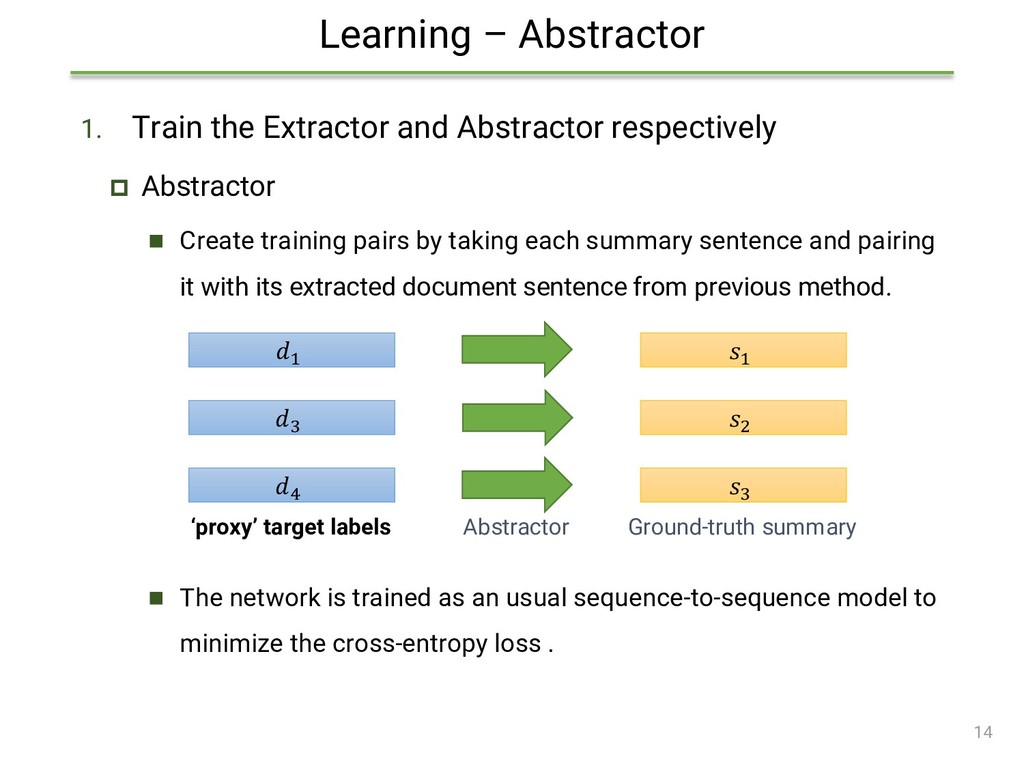
Abstractor ◼ Create training pairs by taking each summary sentence and pairing it with its extracted document sentence from previous method. ◼ The network is trained as an usual sequence-to-sequence model to minimize the cross-entropy loss . 14 1 1 3 2 4 3 Ground-truth summary ‘proxy’ target labels Abstractor
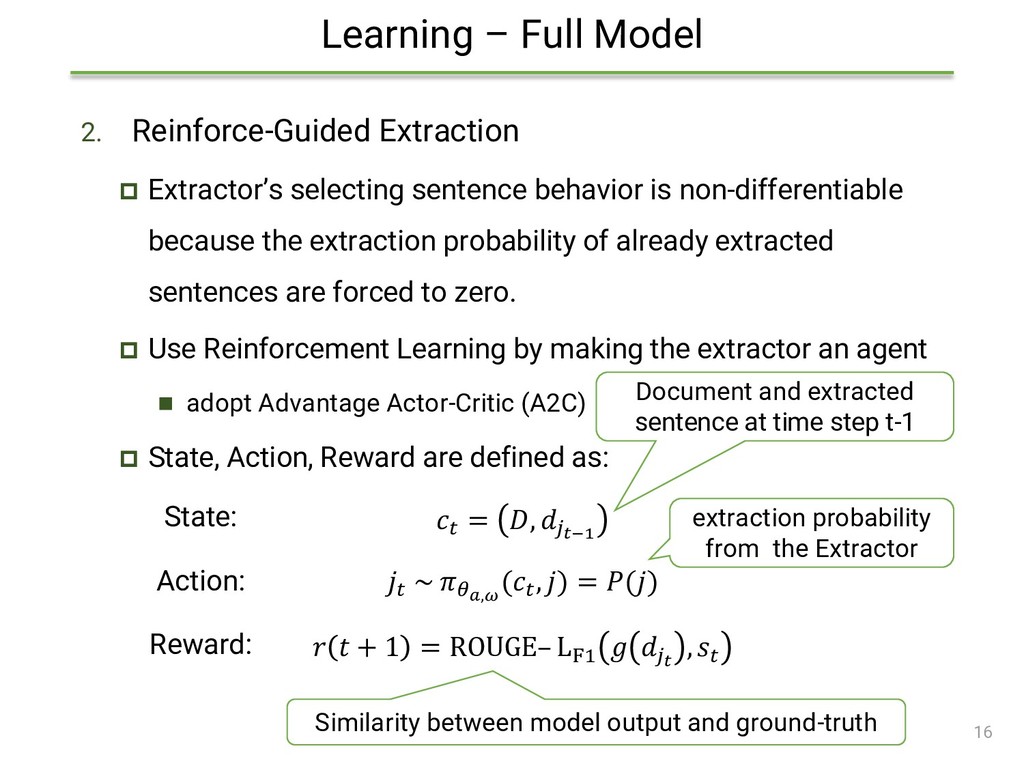
sentence behavior is non-differentiable because the extraction probability of already extracted sentences are forced to zero. Use Reinforcement Learning by making the extractor an agent ◼ adopt Advantage Actor-Critic (A2C) State, Action, Reward are defined as: 16 State: = , −1 Action: ~ , ( , ) = () Reward: + 1 = ROUGE– LF1 , Document and extracted sentence at time step t-1 extraction probability from the Extractor Similarity between model output and ground-truth
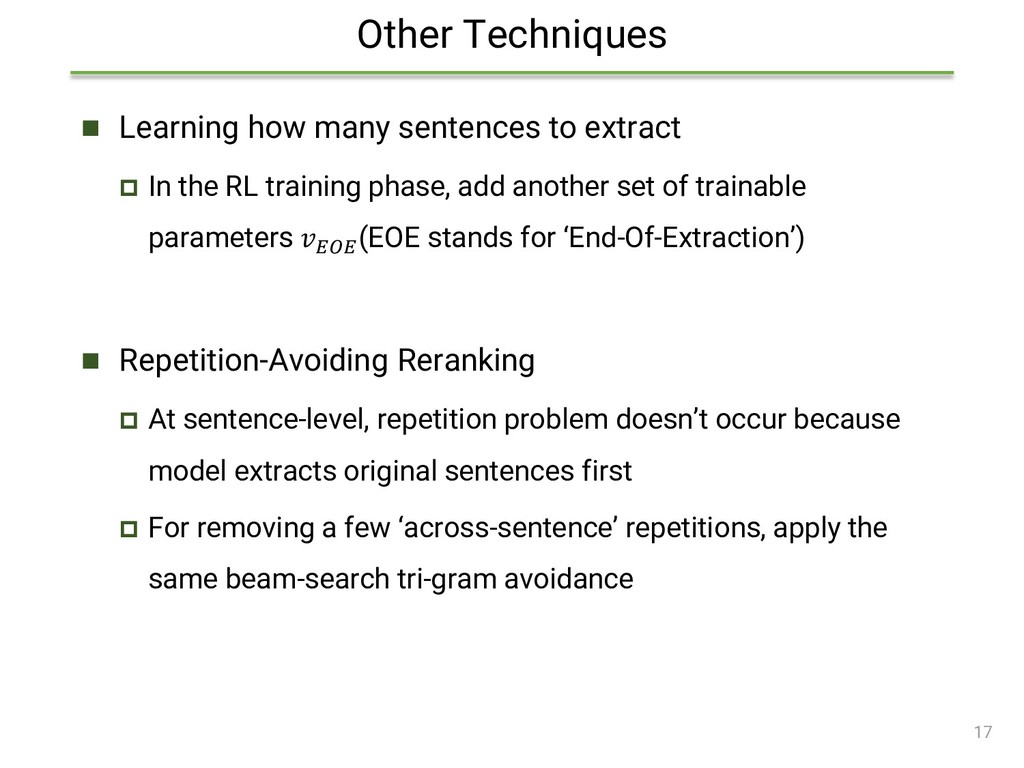
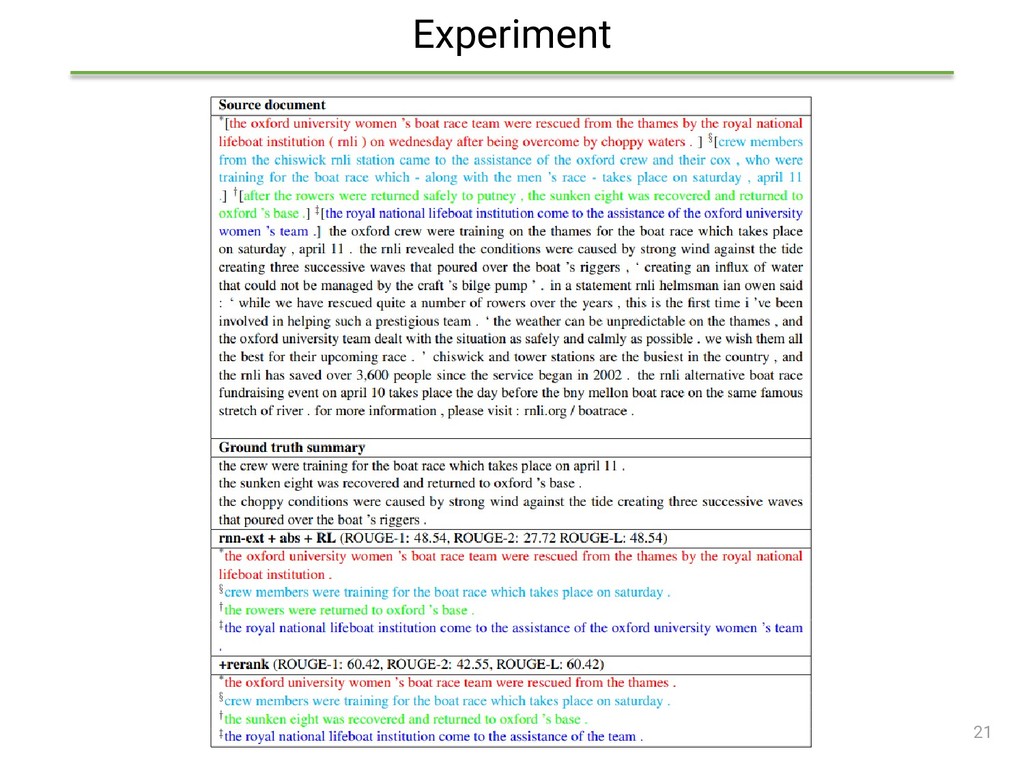
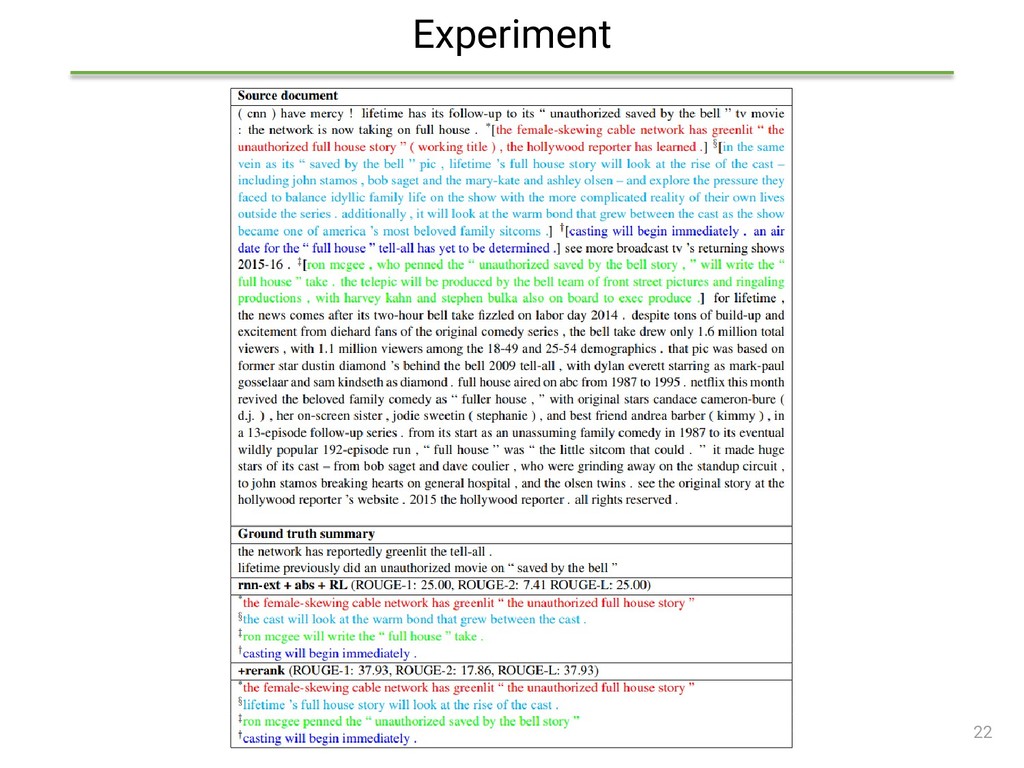
In the RL training phase, add another set of trainable parameters (EOE stands for ‘End-Of-Extraction’) ◼ Repetition-Avoiding Reranking At sentence-level, repetition problem doesn’t occur because model extracts original sentences first For removing a few ‘across-sentence’ repetitions, apply the same beam-search tri-gram avoidance 17


 reokashiwa
 satai
 kzinmr
 mickey_0226
 izumiyama_lab
 shunk031
 corochann
 hisaokatsumi
 youten622
 koide3
 murakawatakuya
 upura
 afnizarnur
 marcduiker
 aemeredith
 tmiket
 raygrieselhuber
 greggifford
 davidcarrasco
 mayunak
 bkeepers
 thoeni
 garrettdimon
 skipperchong