Share
Embed
Salzburg '18: Memory-safe and Efficient Execution of C/C++ on the GraalVM
Talk hosted by Christoph Kirsch at University of Salzburg

Manuel Rigger
May 17, 2018
Transcript
143 slides
-
Memory-safe and Efficient Execution of C/C++ on the GraalVM Manuel
Rigger Johannes Kepler University Linz, Austria Supervisor: Hanspeter Mössenböck University of Salzburg, 17 May 2018 -
Show of Hands Who has heard of GraalVM? 2 Credit:
https://pngtree.com/ -
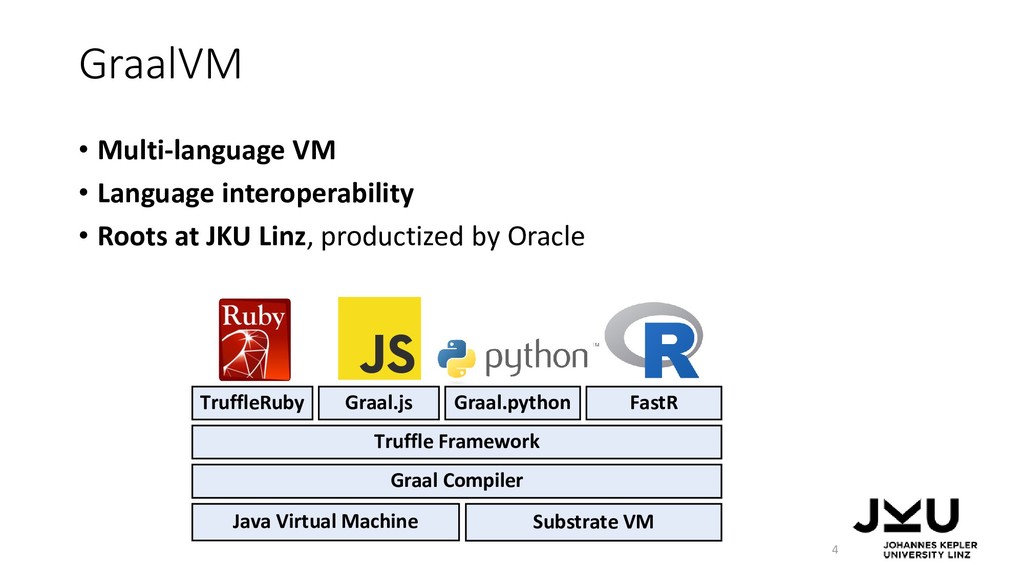
GraalVM • Multi-language VM • Language interoperability • Roots at
JKU Linz, productized by Oracle 4 Java Virtual Machine Graal Compiler Truffle Framework TruffleRuby Graal.js Graal.python FastR Substrate VM -
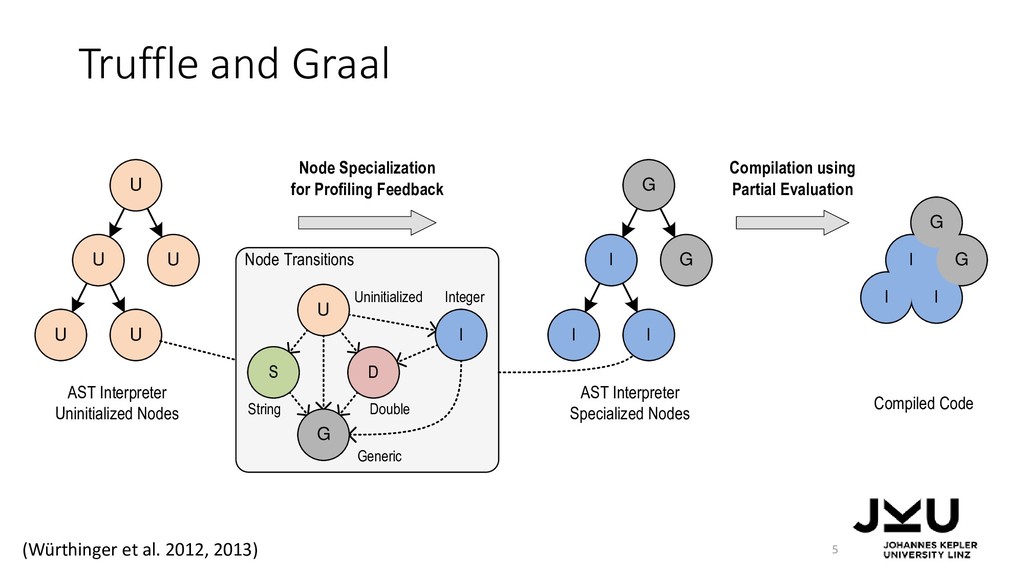
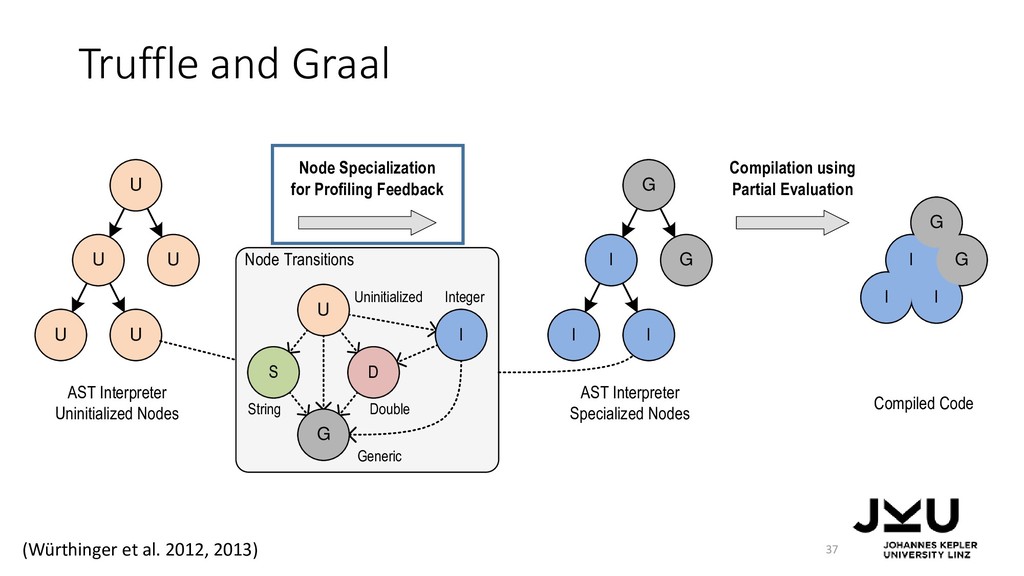
Truffle and Graal 5 U U U U U I
I I G G I I I G G Node Specialization for Profiling Feedback AST Interpreter Specialized Nodes AST Interpreter Uninitialized Nodes Compilation using Partial Evaluation Compiled Code Node Transitions S U I D G Uninitialized Integer Generic Double String (Würthinger et al. 2012, 2013) -
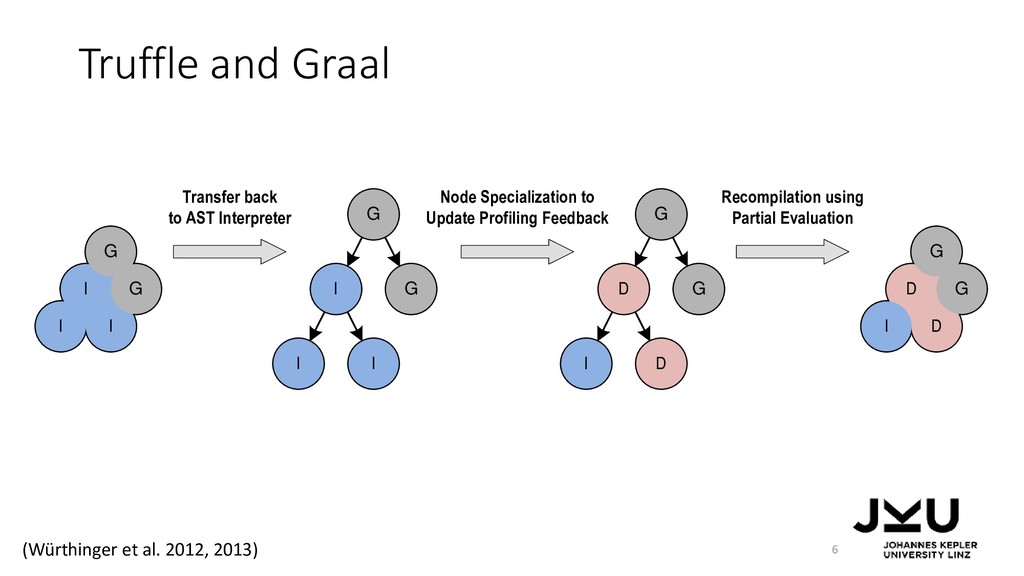
Truffle and Graal 6 I I I G G I
I I G G Transfer back to AST Interpreter D I D G G D I D G G Node Specialization to Update Profiling Feedback Recompilation using Partial Evaluation (Würthinger et al. 2012, 2013) -
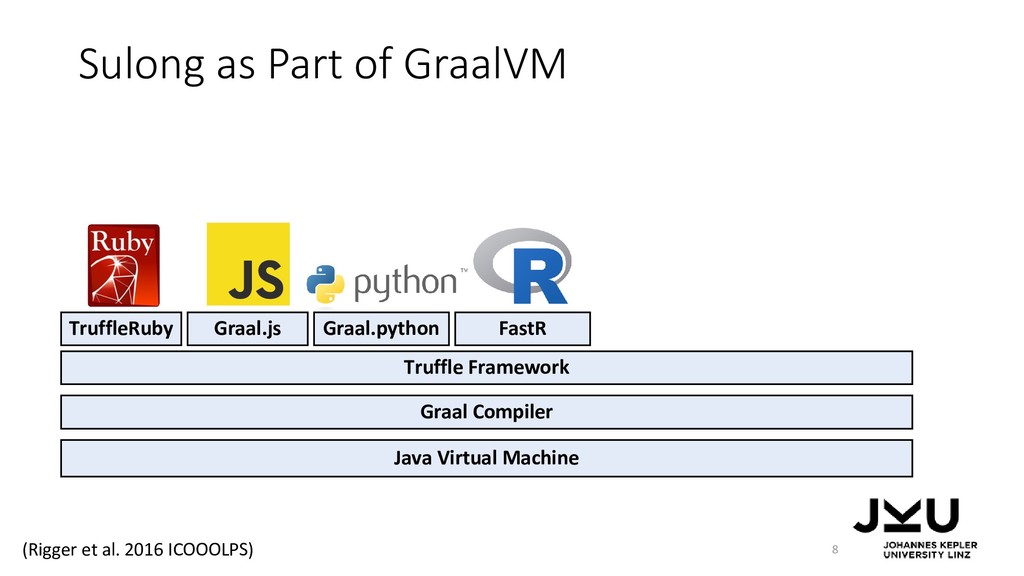
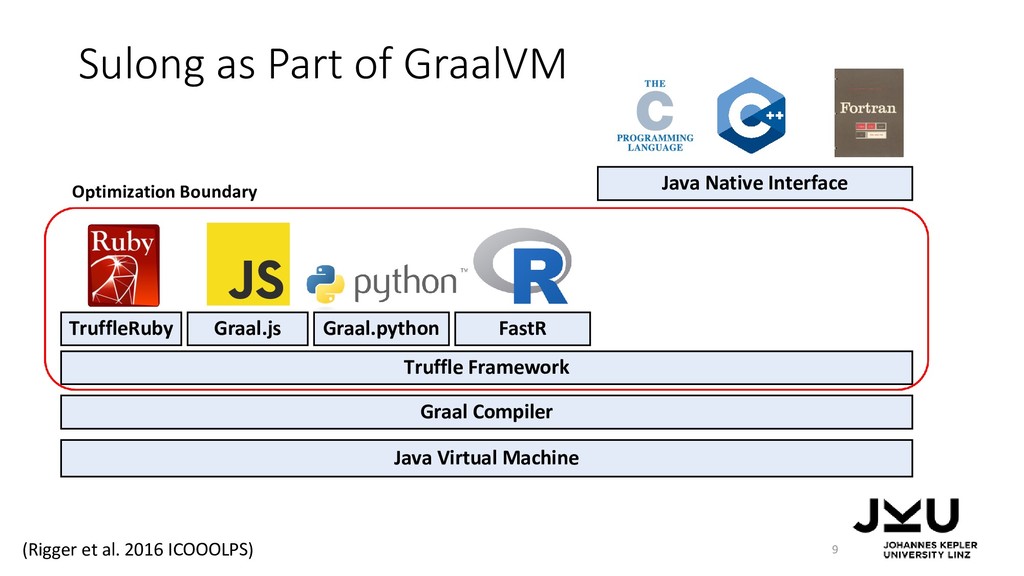
Sulong as Part of GraalVM 8 Java Virtual Machine Graal
Compiler Truffle Framework TruffleRuby Graal.js Graal.python FastR (Rigger et al. 2016 ICOOOLPS) -
Sulong as Part of GraalVM 8 Java Virtual Machine Graal
Compiler Truffle Framework TruffleRuby Graal.js Graal.python FastR Optimization Boundary (Rigger et al. 2016 ICOOOLPS) -
Sulong as Part of GraalVM 9 Java Virtual Machine Graal
Compiler Truffle Framework TruffleRuby Graal.js Graal.python FastR Optimization Boundary Java Native Interface (Rigger et al. 2016 ICOOOLPS) -
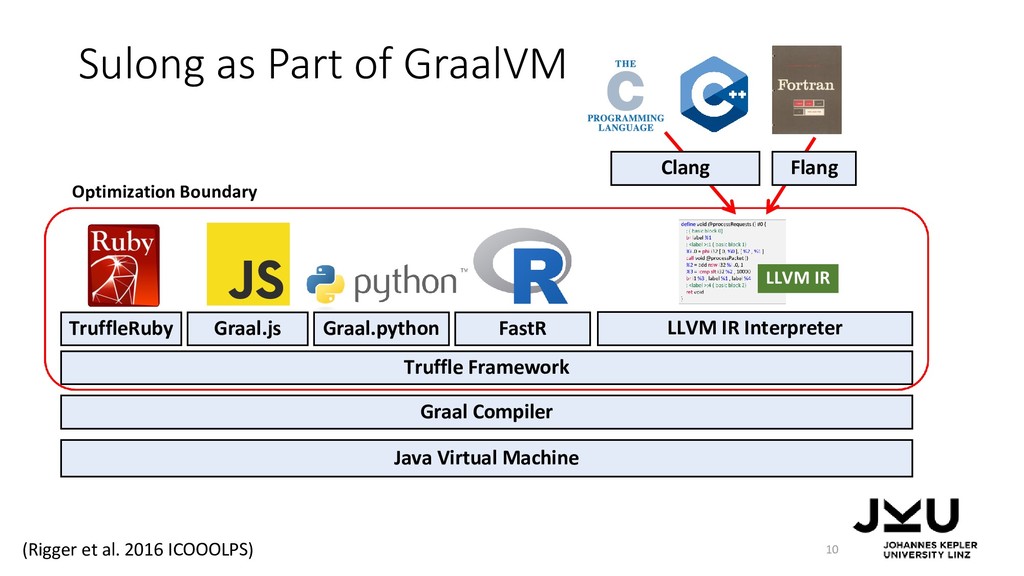
Sulong as Part of GraalVM 10 Java Virtual Machine Graal
Compiler Truffle Framework TruffleRuby Graal.js Graal.python FastR Optimization Boundary LLVM IR Interpreter LLVM IR Clang Flang (Rigger et al. 2016 ICOOOLPS) -
Project Sulong 11 In GraalVM, Sulong is used to implement
native function interfaces -
Project Sulong 12 Can we execute C/C++ safely and efficiently
by abstracting their semantic to Java? -
Buffer Overflows 14 int *arr = malloc(3 * sizeof(int)); arr[5]
= … C Undefined Behavior -
Buffer Overflows 14 int *arr = malloc(3 * sizeof(int)); arr[5]
= … Java C Undefined Behavior ArrayIndexOutOfBoundsException int[] arr = new int[3]; arr[5] = … -
Use-after-free Errors 15 free(arr); arr[0] = … C Undefined Behavior
NullPointerException Java arr = null; arr[0] = -
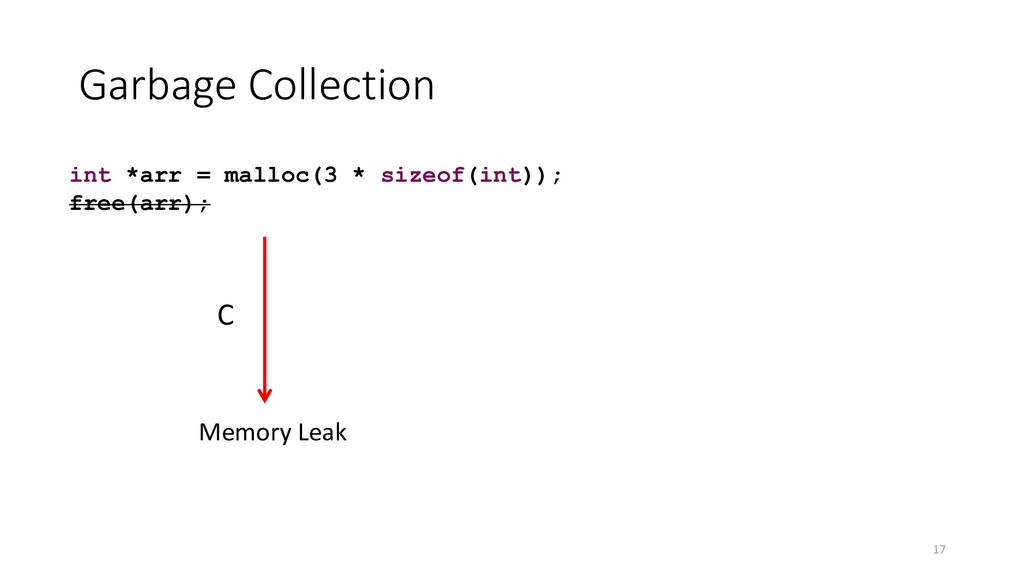
Garbage Collection 17 C int *arr = malloc(3 * sizeof(int));
free(arr); Memory Leak -
Garbage Collection 17 Java C int[] arr = new int[3];
int *arr = malloc(3 * sizeof(int)); free(arr); Memory Leak Collected by the GC -
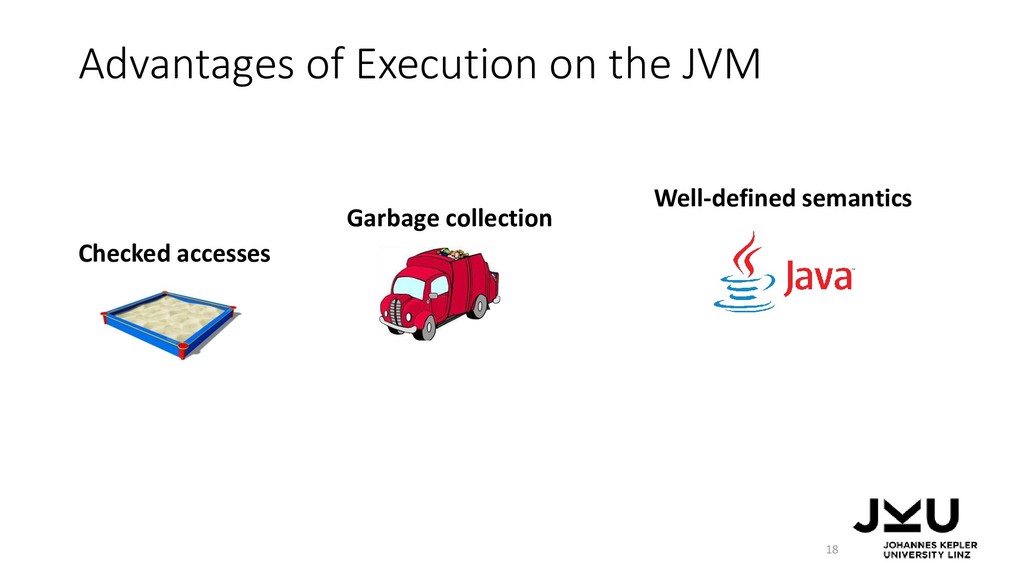
Advantages of Execution on the JVM 18 Checked accesses Garbage
collection Well-defined semantics -
Compiler Optimizations 19 int test(size_t i) { int arr[2] =
{0}; if (i >= 2) { arr[2] = 0xcafe; } return arr[i]; } -
Compiler Optimizations 19 int test(size_t i) { int arr[2] =
{0}; if (i >= 2) { arr[2] = 0xcafe; } return arr[i]; } int test(size_t i) { return 0; } C -
Compiler Optimizations 19 int test(size_t i) { int arr[2] =
{0}; if (i >= 2) { arr[2] = 0xcafe; } return arr[i]; } int test(size_t i) { return 0; } State-of-the-art detection tools fail to detect the out-of-bounds access C -
Compiler Optimizations 20 int test(size_t i) { int arr[2] =
{0}; if (i >= 2) { arr[2] = 0xcafe; } return arr[i]; } -
Compiler Optimizations 20 ArrayIndexOutOfBoundsException int test(size_t i) { int arr[2]
= {0}; if (i >= 2) { arr[2] = 0xcafe; } return arr[i]; } Java -
21 Dynamic Optimizations & Memory Safety Implementation of the Interpreter
Evaluation Unstandardized Elements in C Projects -
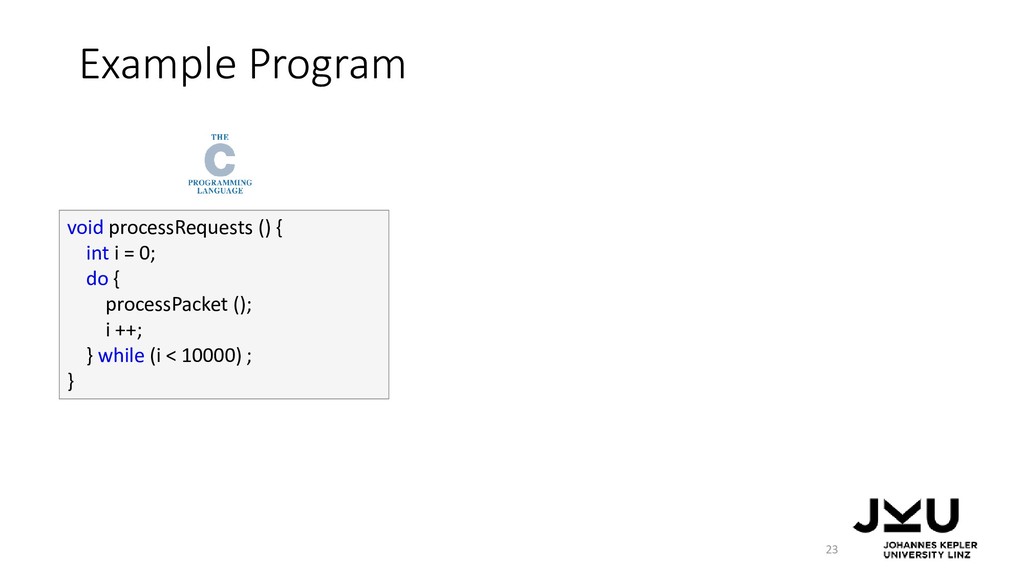
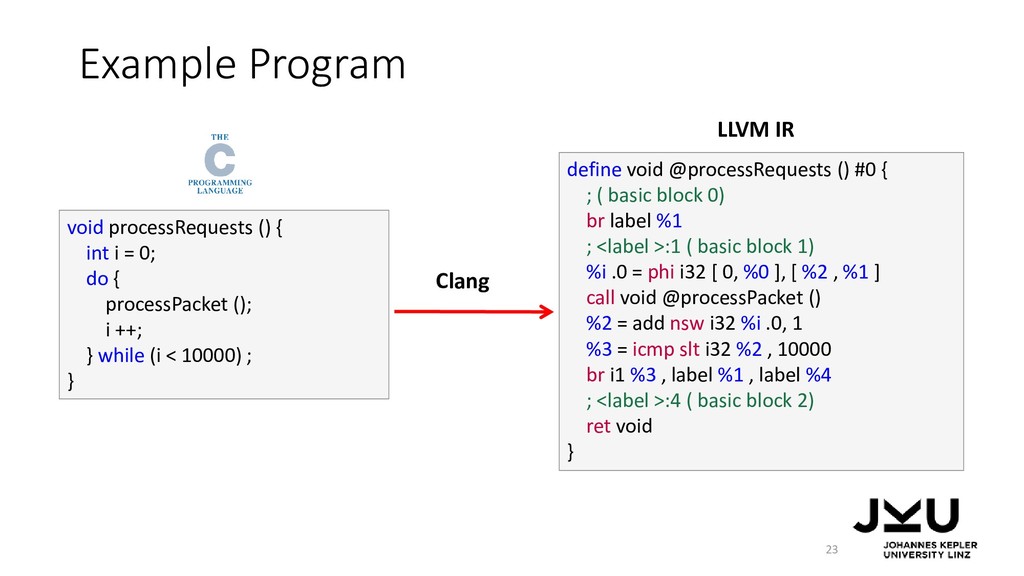
Example Program 23 void processRequests () { int i =
0; do { processPacket (); i ++; } while (i < 10000) ; } -
Example Program 23 void processRequests () { int i =
0; do { processPacket (); i ++; } while (i < 10000) ; } define void @processRequests () #0 { ; ( basic block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR Clang -
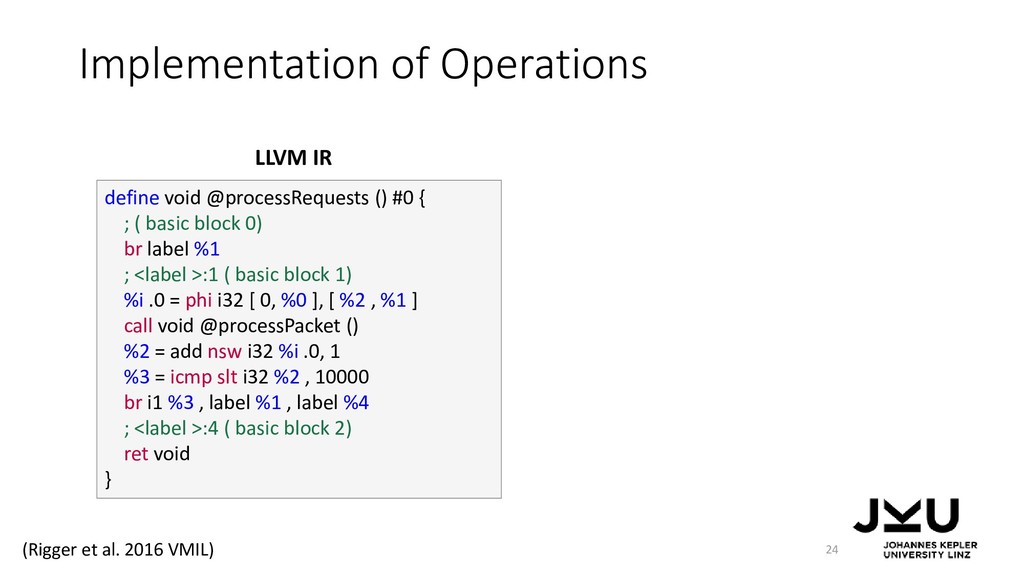
24 define void @processRequests () #0 { ; ( basic
block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR Implementation of Operations (Rigger et al. 2016 VMIL) -
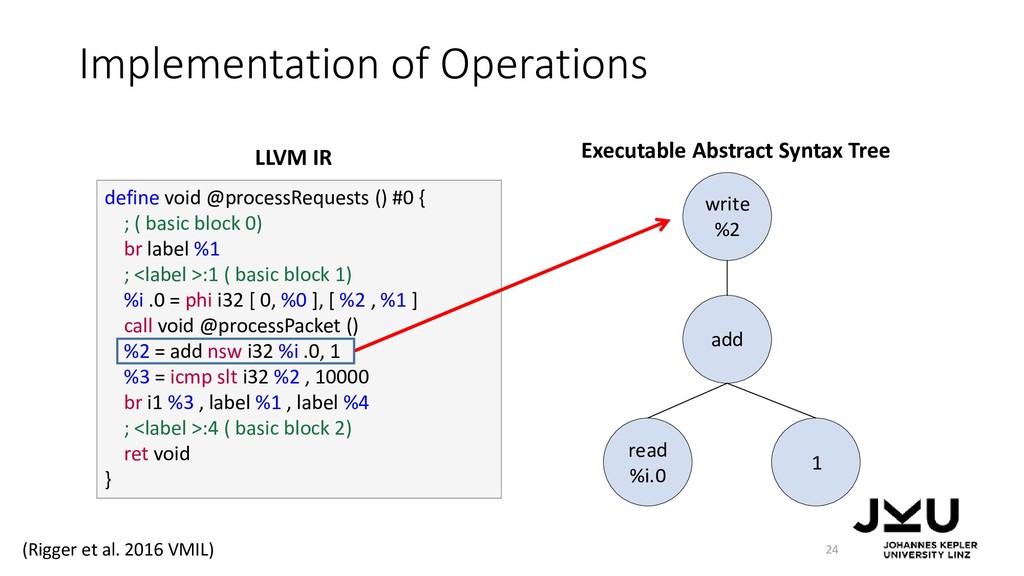
24 define void @processRequests () #0 { ; ( basic
block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR write %2 add read %i.0 1 Executable Abstract Syntax Tree Implementation of Operations (Rigger et al. 2016 VMIL) -
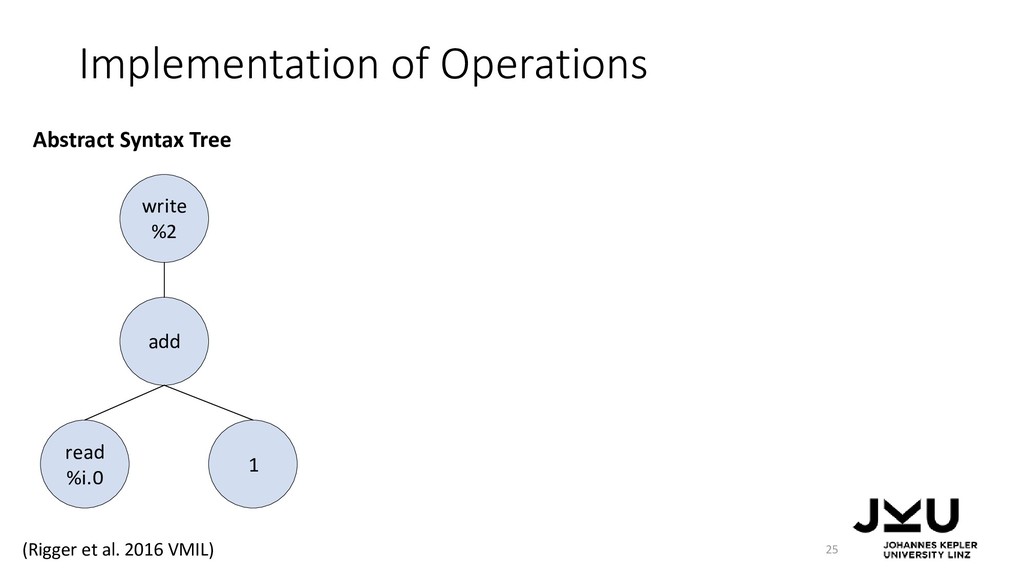
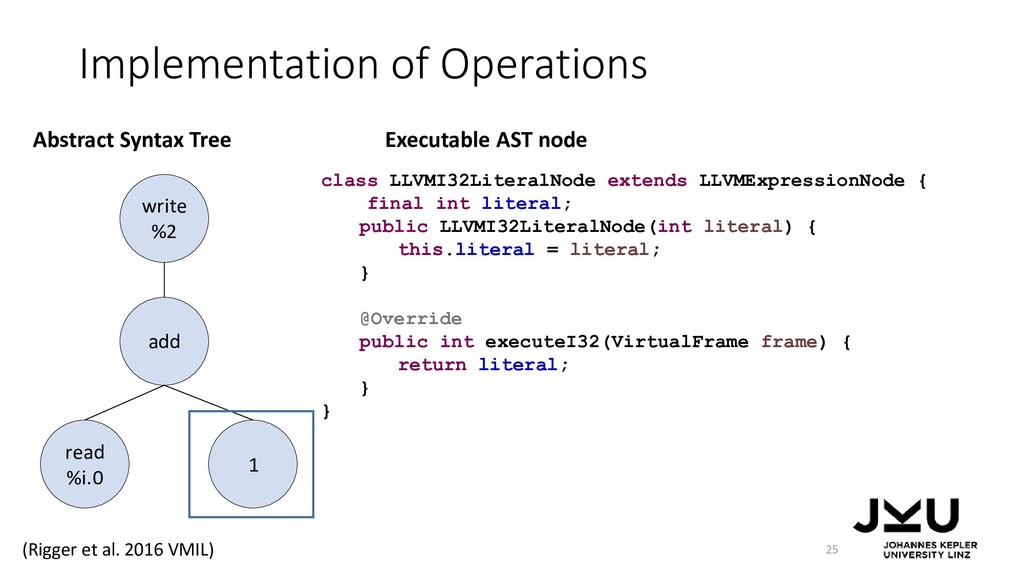
25 write %2 add read %i.0 1 Abstract Syntax Tree
Implementation of Operations (Rigger et al. 2016 VMIL) -
25 write %2 add read %i.0 1 Abstract Syntax Tree
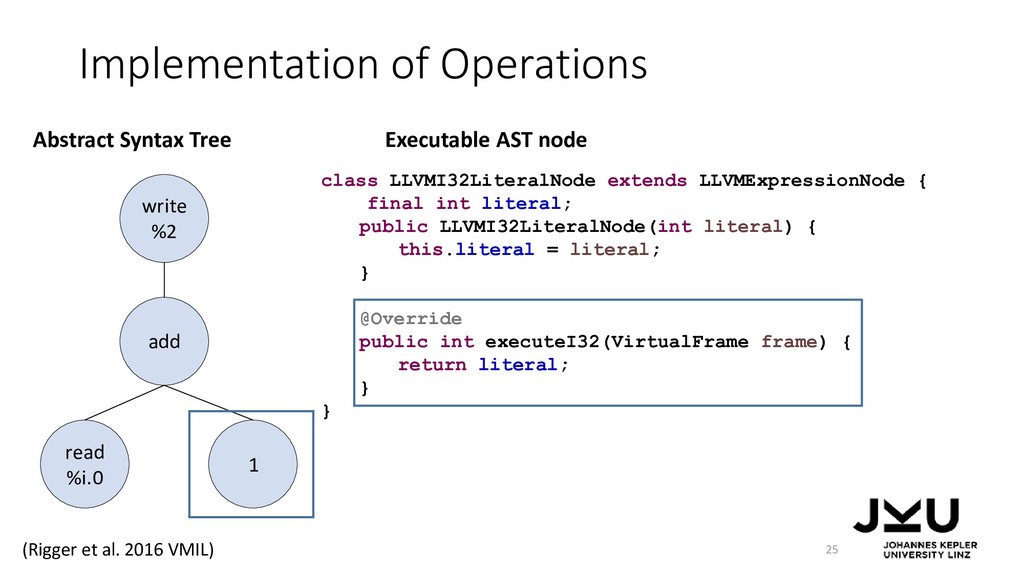
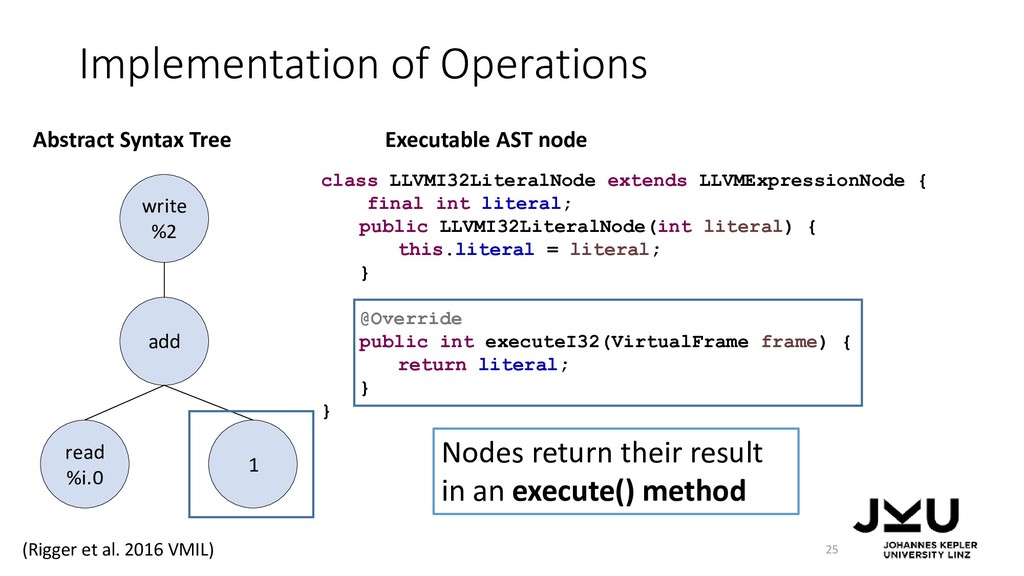
class LLVMI32LiteralNode extends LLVMExpressionNode { final int literal; public LLVMI32LiteralNode(int literal) { this.literal = literal; } @Override public int executeI32(VirtualFrame frame) { return literal; } } Executable AST node Implementation of Operations (Rigger et al. 2016 VMIL) -
25 write %2 add read %i.0 1 Abstract Syntax Tree
class LLVMI32LiteralNode extends LLVMExpressionNode { final int literal; public LLVMI32LiteralNode(int literal) { this.literal = literal; } @Override public int executeI32(VirtualFrame frame) { return literal; } } Executable AST node Implementation of Operations (Rigger et al. 2016 VMIL) -
25 write %2 add read %i.0 1 Abstract Syntax Tree
class LLVMI32LiteralNode extends LLVMExpressionNode { final int literal; public LLVMI32LiteralNode(int literal) { this.literal = literal; } @Override public int executeI32(VirtualFrame frame) { return literal; } } Executable AST node Nodes return their result in an execute() method Implementation of Operations (Rigger et al. 2016 VMIL) -
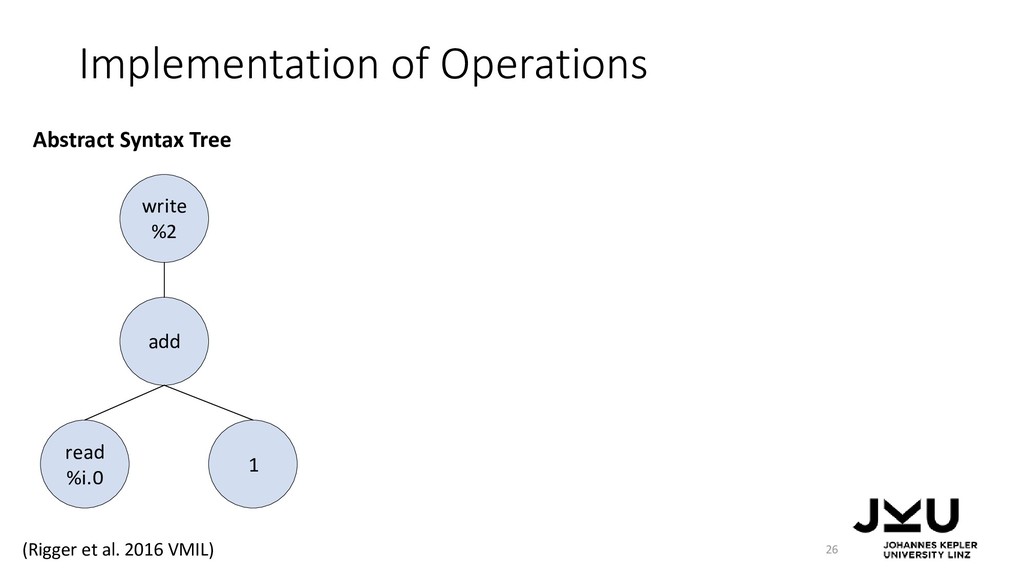
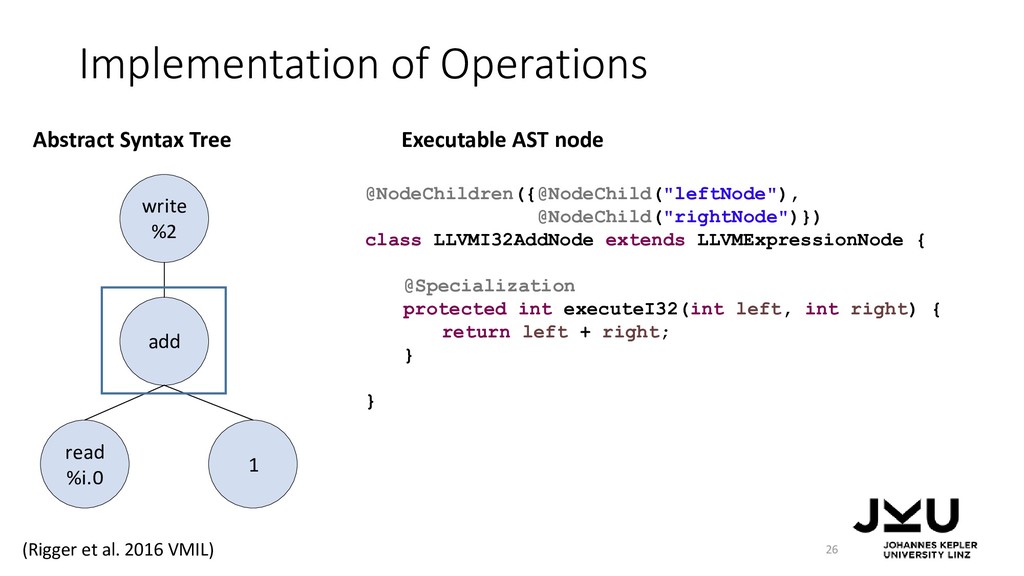
26 Abstract Syntax Tree write %2 add read %i.0 1
Implementation of Operations (Rigger et al. 2016 VMIL) -
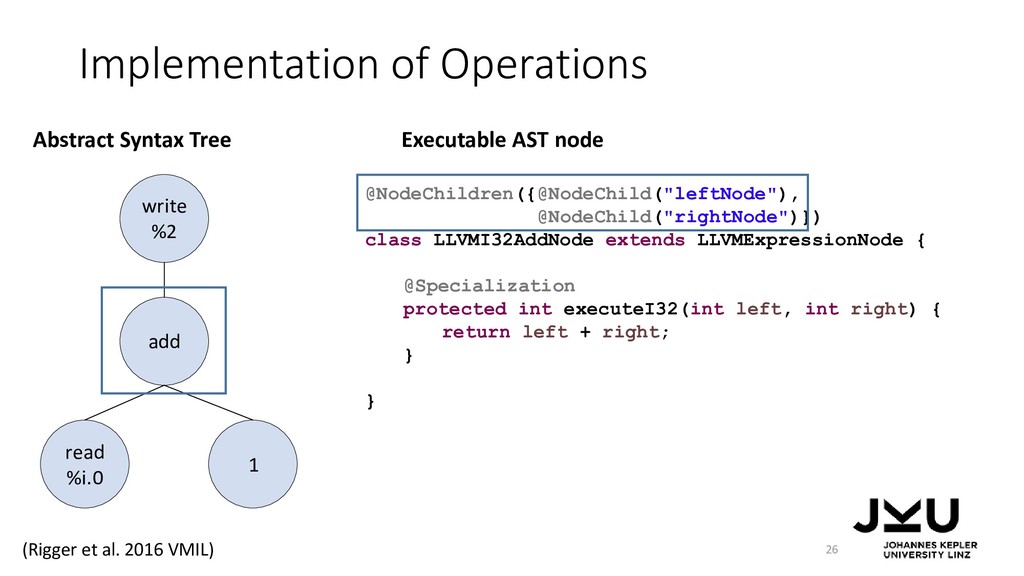
26 Abstract Syntax Tree @NodeChildren({@NodeChild("leftNode"), @NodeChild("rightNode")}) class LLVMI32AddNode extends LLVMExpressionNode
{ @Specialization protected int executeI32(int left, int right) { return left + right; } } Executable AST node write %2 add read %i.0 1 Implementation of Operations (Rigger et al. 2016 VMIL) -
26 Abstract Syntax Tree @NodeChildren({@NodeChild("leftNode"), @NodeChild("rightNode")}) class LLVMI32AddNode extends LLVMExpressionNode
{ @Specialization protected int executeI32(int left, int right) { return left + right; } } Executable AST node write %2 add read %i.0 1 Implementation of Operations (Rigger et al. 2016 VMIL) -
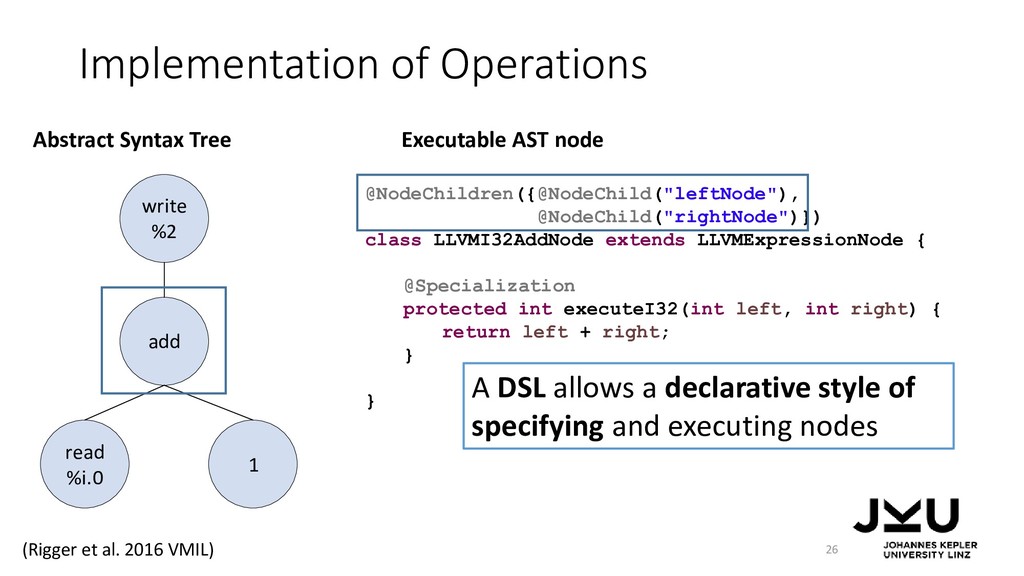
26 Abstract Syntax Tree @NodeChildren({@NodeChild("leftNode"), @NodeChild("rightNode")}) class LLVMI32AddNode extends LLVMExpressionNode
{ @Specialization protected int executeI32(int left, int right) { return left + right; } } Executable AST node write %2 add read %i.0 1 A DSL allows a declarative style of specifying and executing nodes Implementation of Operations (Rigger et al. 2016 VMIL) -
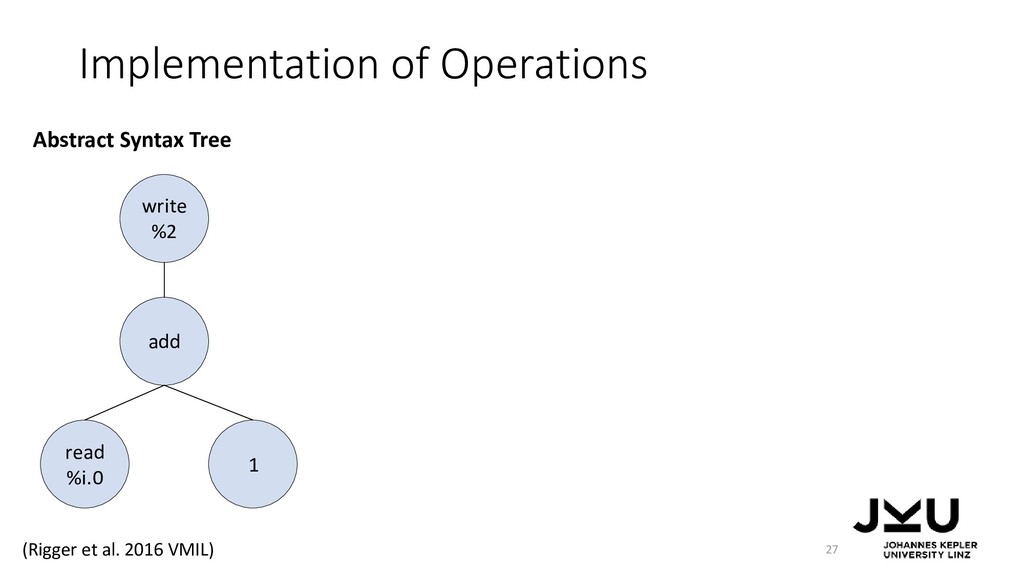
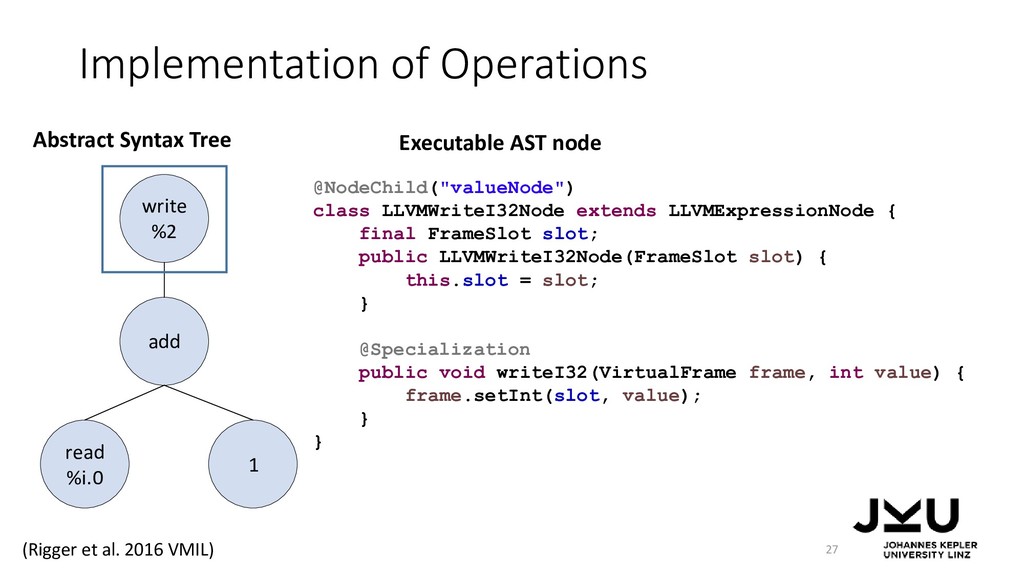
27 Abstract Syntax Tree write %2 add read %i.0 1
Implementation of Operations (Rigger et al. 2016 VMIL) -
27 Abstract Syntax Tree @NodeChild("valueNode") class LLVMWriteI32Node extends LLVMExpressionNode {
final FrameSlot slot; public LLVMWriteI32Node(FrameSlot slot) { this.slot = slot; } @Specialization public void writeI32(VirtualFrame frame, int value) { frame.setInt(slot, value); } } Executable AST node write %2 add read %i.0 1 Implementation of Operations (Rigger et al. 2016 VMIL) -
27 Abstract Syntax Tree @NodeChild("valueNode") class LLVMWriteI32Node extends LLVMExpressionNode {
final FrameSlot slot; public LLVMWriteI32Node(FrameSlot slot) { this.slot = slot; } @Specialization public void writeI32(VirtualFrame frame, int value) { frame.setInt(slot, value); } } Executable AST node write %2 add read %i.0 1 Implementation of Operations (Rigger et al. 2016 VMIL) -
27 Abstract Syntax Tree @NodeChild("valueNode") class LLVMWriteI32Node extends LLVMExpressionNode {
final FrameSlot slot; public LLVMWriteI32Node(FrameSlot slot) { this.slot = slot; } @Specialization public void writeI32(VirtualFrame frame, int value) { frame.setInt(slot, value); } } Executable AST node write %2 add read %i.0 1 Local variables are represented by an array-like VirtualFrame object Implementation of Operations (Rigger et al. 2016 VMIL) -
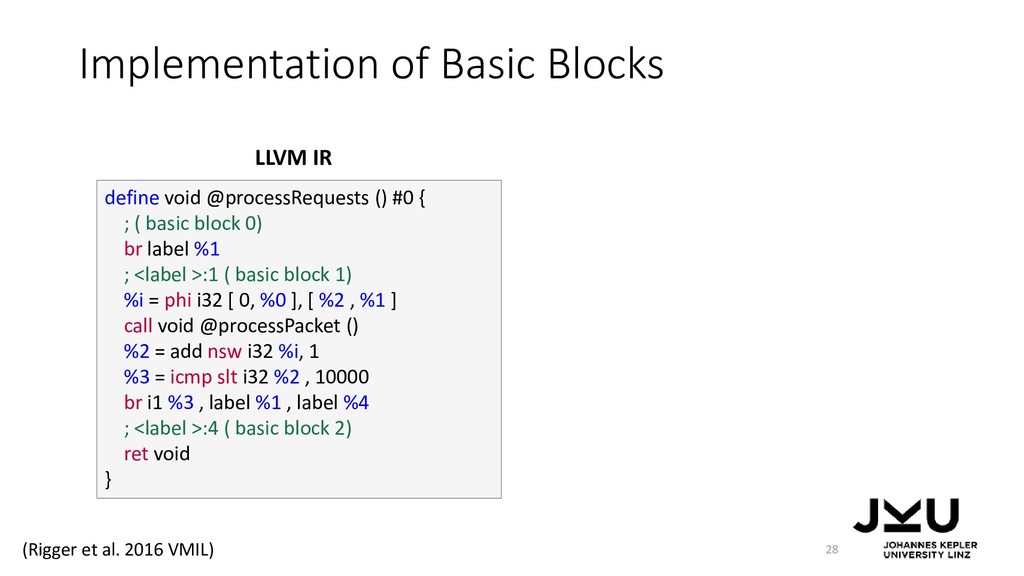
28 define void @processRequests () #0 { ; ( basic
block 0) br label %1 ; <label >:1 ( basic block 1) %i = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR Implementation of Basic Blocks (Rigger et al. 2016 VMIL) -
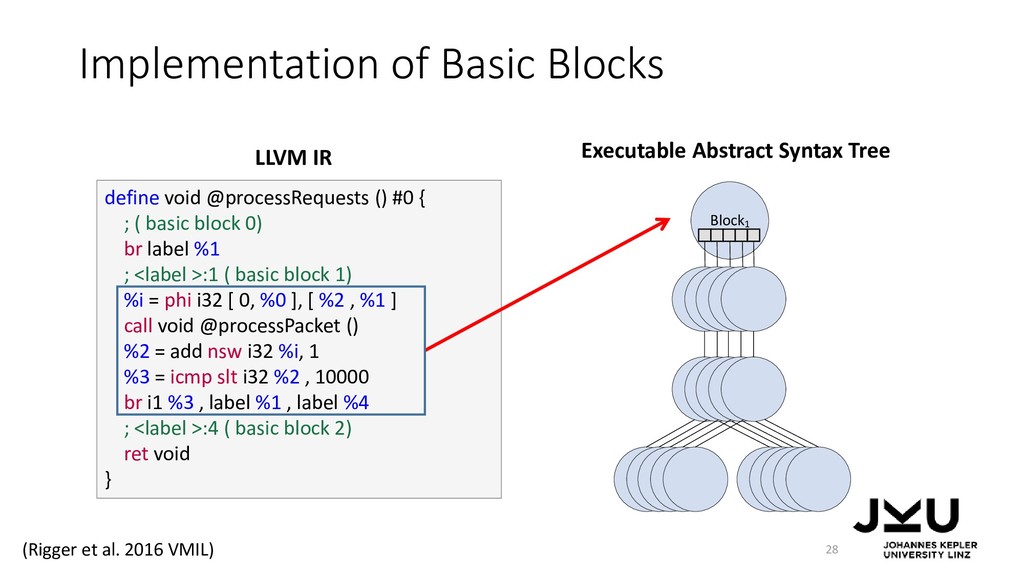
28 define void @processRequests () #0 { ; ( basic
block 0) br label %1 ; <label >:1 ( basic block 1) %i = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR Executable Abstract Syntax Tree Implementation of Basic Blocks Block1 (Rigger et al. 2016 VMIL) -
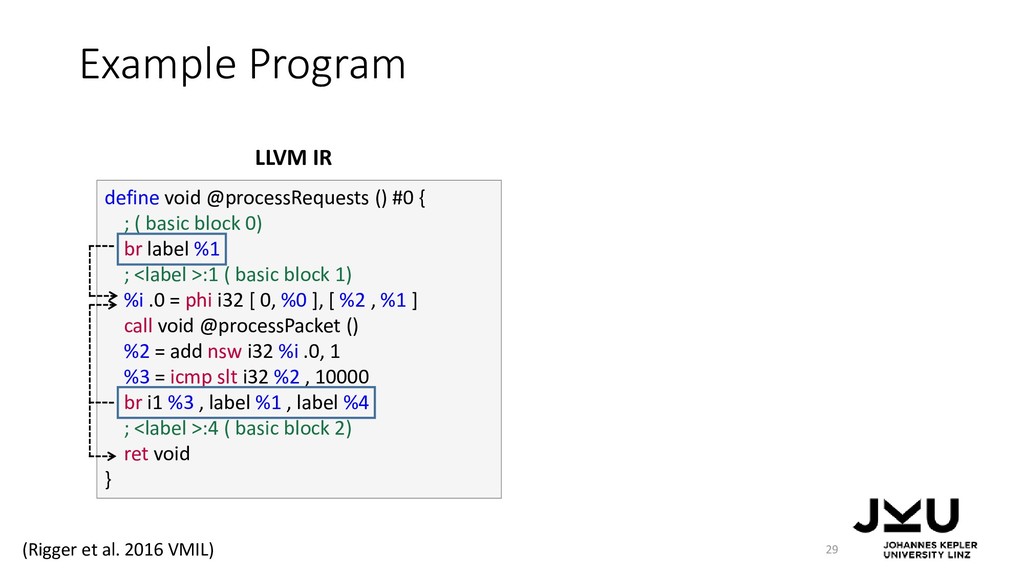
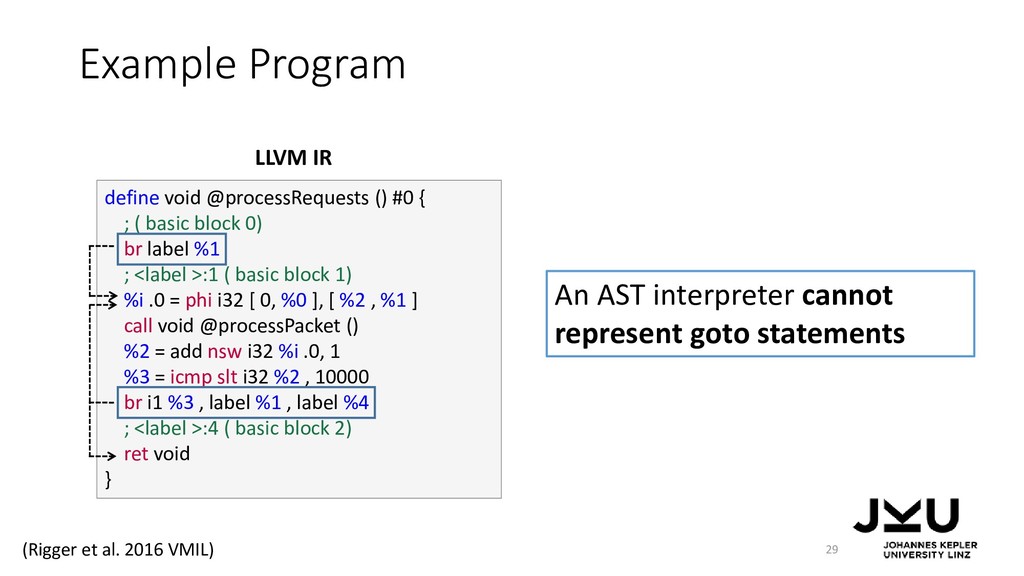
Example Program 29 define void @processRequests () #0 { ;
( basic block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR (Rigger et al. 2016 VMIL) -
Example Program 29 define void @processRequests () #0 { ;
( basic block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } LLVM IR An AST interpreter cannot represent goto statements (Rigger et al. 2016 VMIL) -
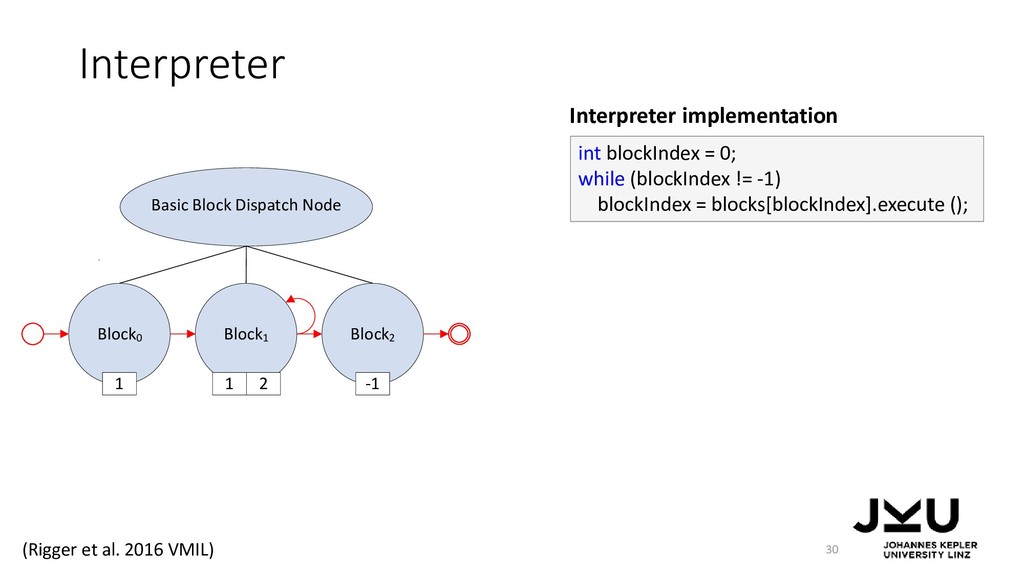
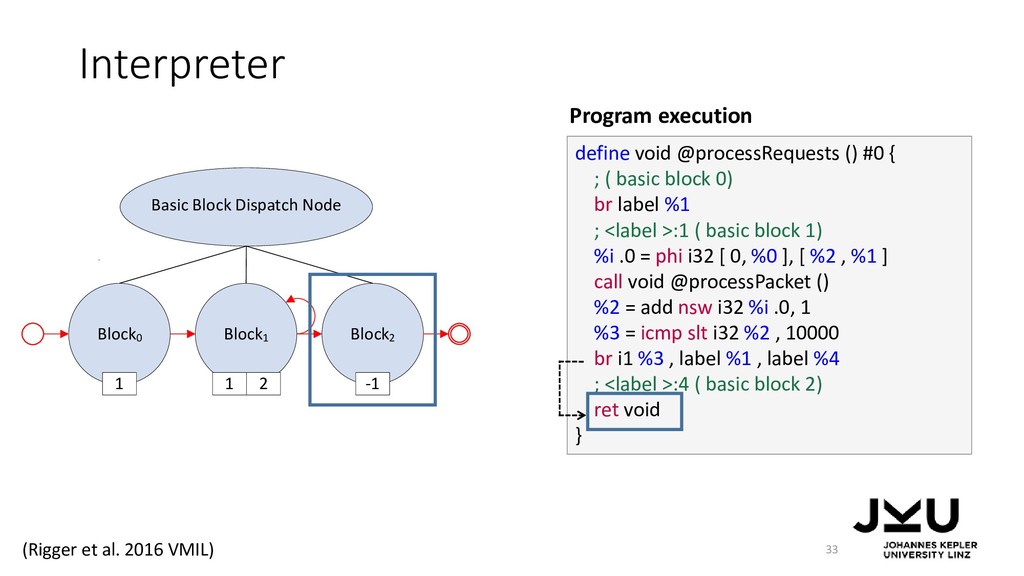
Block0 Block1 Block2 Basic Block Dispatch Node 1 2 -1
1 Interpreter 30 int blockIndex = 0; while (blockIndex != -1) blockIndex = blocks[blockIndex].execute (); Interpreter implementation (Rigger et al. 2016 VMIL) -
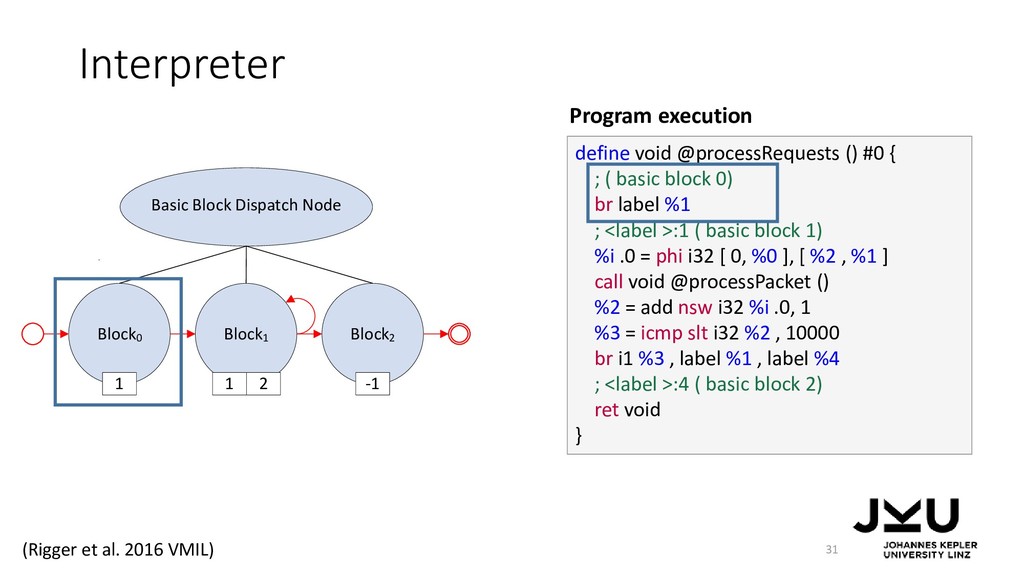
Block0 Block1 Block2 Basic Block Dispatch Node 1 2 -1
1 Interpreter 31 define void @processRequests () #0 { ; ( basic block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } Program execution (Rigger et al. 2016 VMIL) -
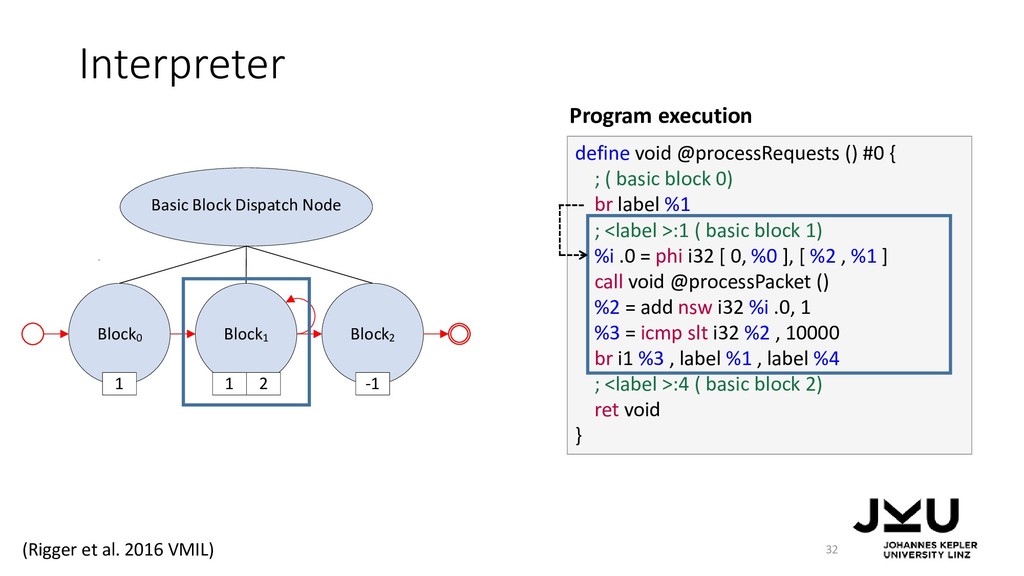
Block0 Block1 Block2 Basic Block Dispatch Node 1 2 -1
1 Interpreter 32 define void @processRequests () #0 { ; ( basic block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } Program execution (Rigger et al. 2016 VMIL) -
Block0 Block1 Block2 Basic Block Dispatch Node 1 2 -1
1 Interpreter 33 define void @processRequests () #0 { ; ( basic block 0) br label %1 ; <label >:1 ( basic block 1) %i .0 = phi i32 [ 0, %0 ], [ %2 , %1 ] call void @processPacket () %2 = add nsw i32 %i .0, 1 %3 = icmp slt i32 %2 , 10000 br i1 %3 , label %1 , label %4 ; <label >:4 ( basic block 2) ret void } Program execution (Rigger et al. 2016 VMIL) -
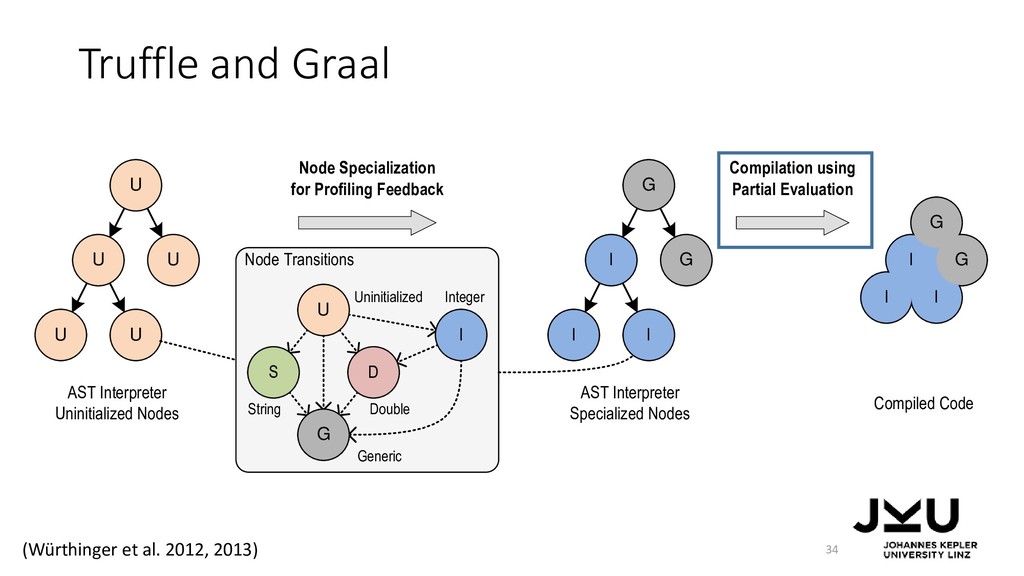
Truffle and Graal 34 U U U U U I
I I G G I I I G G Node Specialization for Profiling Feedback AST Interpreter Specialized Nodes AST Interpreter Uninitialized Nodes Compilation using Partial Evaluation Compiled Code Node Transitions S U I D G Uninitialized Integer Generic Double String (Würthinger et al. 2012, 2013) -
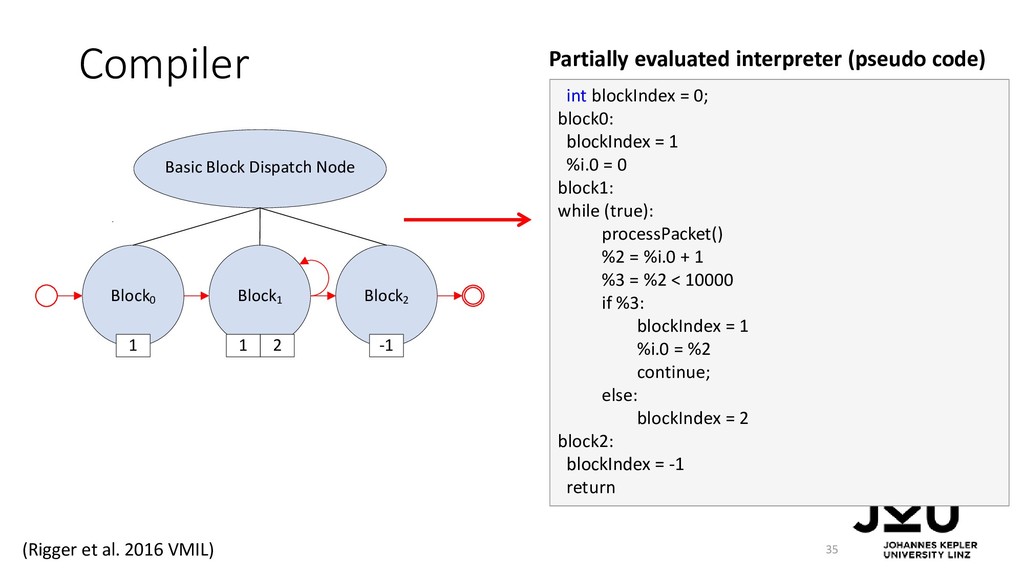
Block0 Block1 Block2 Basic Block Dispatch Node 1 2 -1
1 Compiler 35 int blockIndex = 0; block0: blockIndex = 1 %i.0 = 0 block1: while (true): processPacket() %2 = %i.0 + 1 %3 = %2 < 10000 if %3: blockIndex = 1 %i.0 = %2 continue; else: blockIndex = 2 block2: blockIndex = -1 return Partially evaluated interpreter (pseudo code) (Rigger et al. 2016 VMIL) -
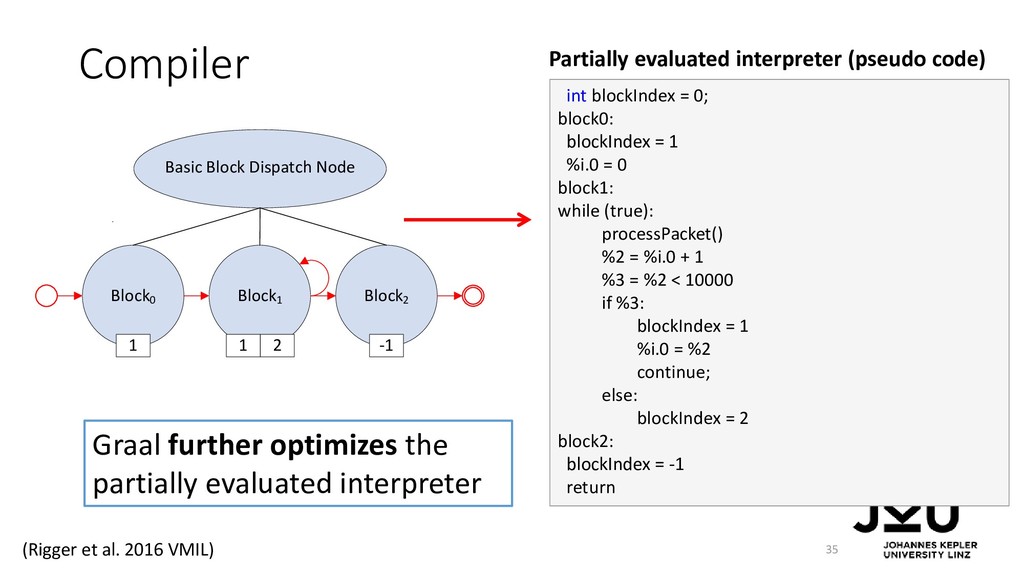
Block0 Block1 Block2 Basic Block Dispatch Node 1 2 -1
1 Compiler 35 int blockIndex = 0; block0: blockIndex = 1 %i.0 = 0 block1: while (true): processPacket() %2 = %i.0 + 1 %3 = %2 < 10000 if %3: blockIndex = 1 %i.0 = %2 continue; else: blockIndex = 2 block2: blockIndex = -1 return Partially evaluated interpreter (pseudo code) Graal further optimizes the partially evaluated interpreter (Rigger et al. 2016 VMIL) -
Truffle and Graal 37 U U U U U I
I I G G I I I G G Node Specialization for Profiling Feedback AST Interpreter Specialized Nodes AST Interpreter Uninitialized Nodes Compilation using Partial Evaluation Compiled Code Node Transitions S U I D G Uninitialized Integer Generic Double String (Würthinger et al. 2012, 2013) -
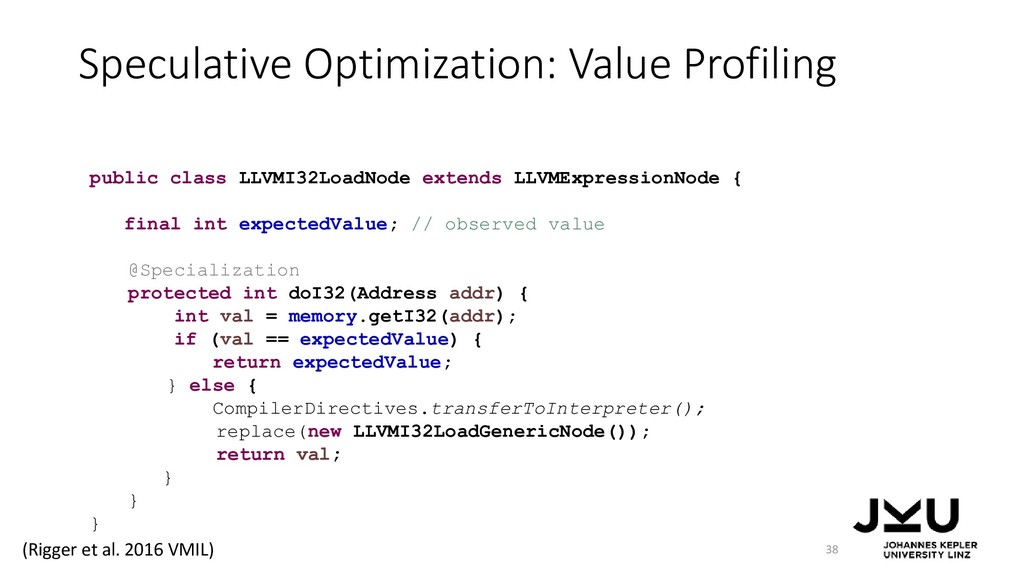
Speculative Optimization: Value Profiling 38 public class LLVMI32LoadNode extends LLVMExpressionNode
{ final int expectedValue; // observed value @Specialization protected int doI32(Address addr) { int val = memory.getI32(addr); if (val == expectedValue) { return expectedValue; } else { CompilerDirectives.transferToInterpreter(); replace(new LLVMI32LoadGenericNode()); return val; } } } (Rigger et al. 2016 VMIL) -
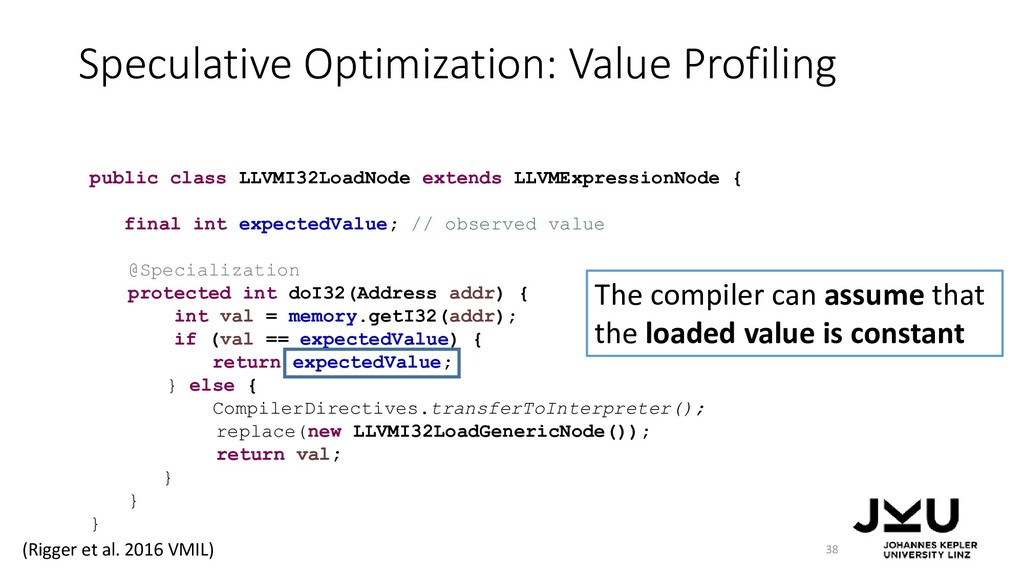
Speculative Optimization: Value Profiling 38 public class LLVMI32LoadNode extends LLVMExpressionNode
{ final int expectedValue; // observed value @Specialization protected int doI32(Address addr) { int val = memory.getI32(addr); if (val == expectedValue) { return expectedValue; } else { CompilerDirectives.transferToInterpreter(); replace(new LLVMI32LoadGenericNode()); return val; } } } The compiler can assume that the loaded value is constant (Rigger et al. 2016 VMIL) -
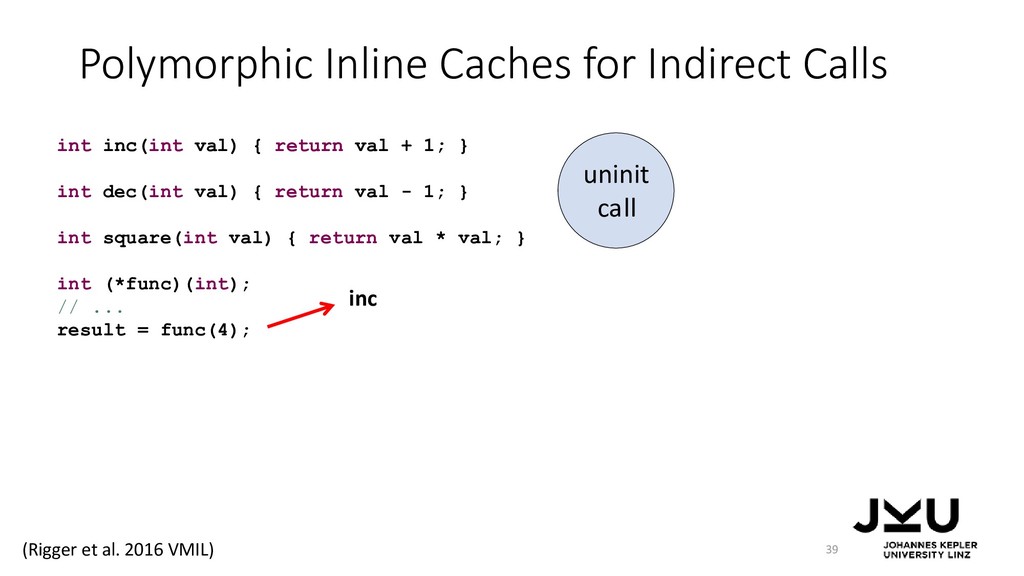
Polymorphic Inline Caches for Indirect Calls 39 int inc(int val)
{ return val + 1; } int dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); uninit call (Rigger et al. 2016 VMIL) -
Polymorphic Inline Caches for Indirect Calls 39 int inc(int val)
{ return val + 1; } int dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); uninit call inc (Rigger et al. 2016 VMIL) -
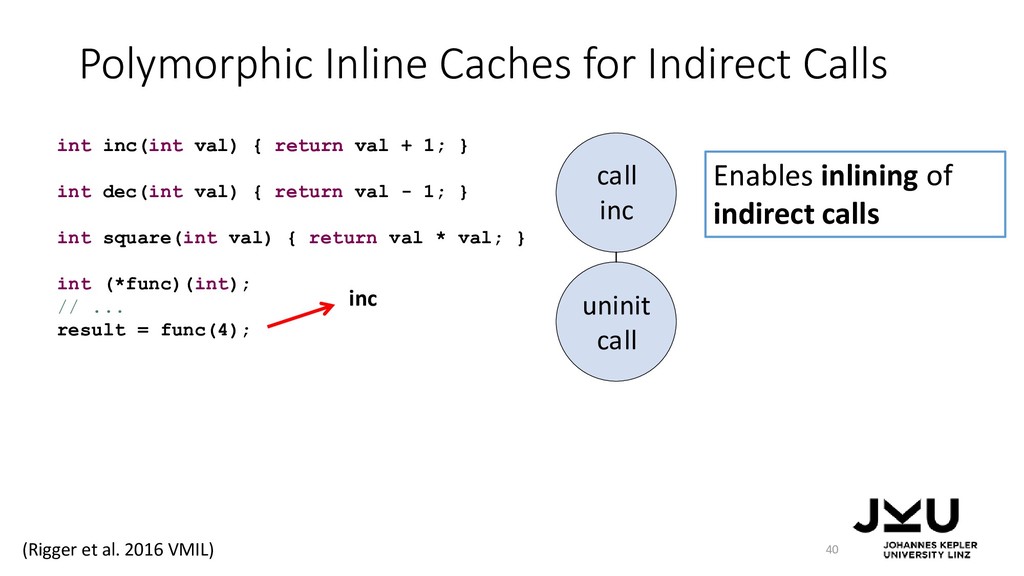
int inc(int val) { return val + 1; } int
dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); Polymorphic Inline Caches for Indirect Calls 40 call inc uninit call inc (Rigger et al. 2016 VMIL) -
int inc(int val) { return val + 1; } int
dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); Polymorphic Inline Caches for Indirect Calls 40 call inc uninit call Enables inlining of indirect calls inc (Rigger et al. 2016 VMIL) -
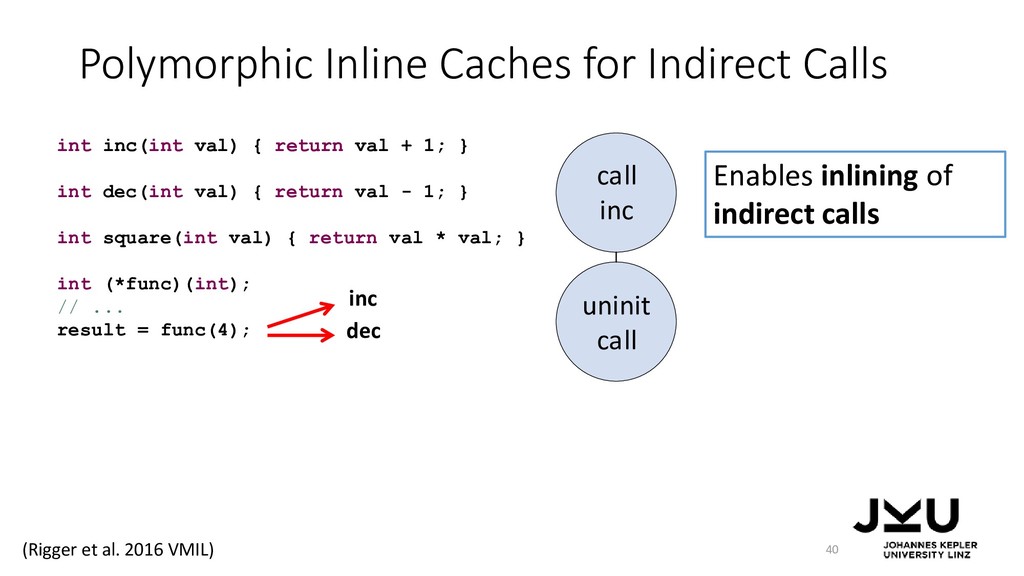
int inc(int val) { return val + 1; } int
dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); Polymorphic Inline Caches for Indirect Calls 40 call inc uninit call Enables inlining of indirect calls inc dec (Rigger et al. 2016 VMIL) -
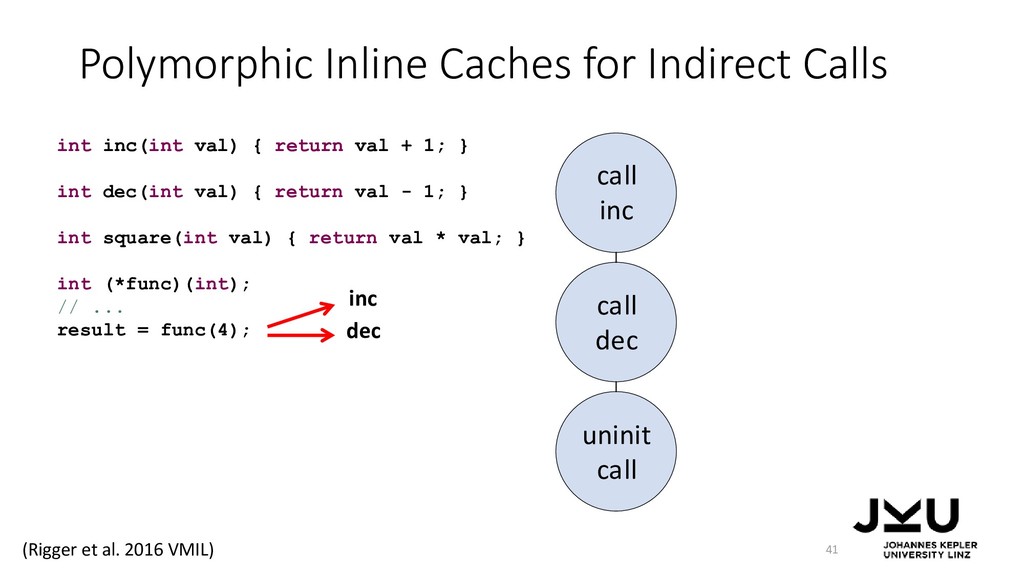
int inc(int val) { return val + 1; } int
dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); call inc call dec uninit call Polymorphic Inline Caches for Indirect Calls 41 inc dec (Rigger et al. 2016 VMIL) -
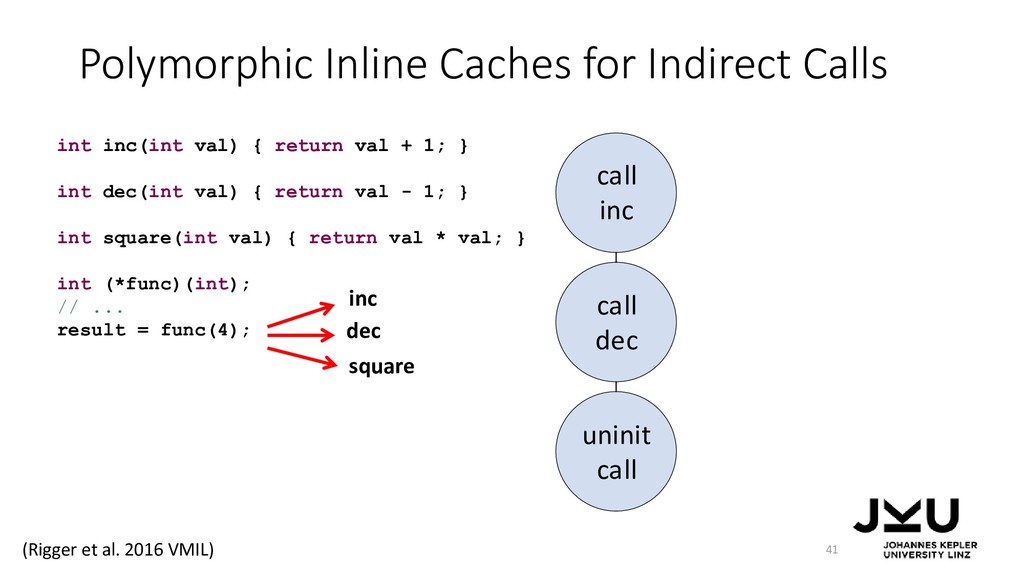
int inc(int val) { return val + 1; } int
dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); call inc call dec uninit call Polymorphic Inline Caches for Indirect Calls 41 inc dec square (Rigger et al. 2016 VMIL) -
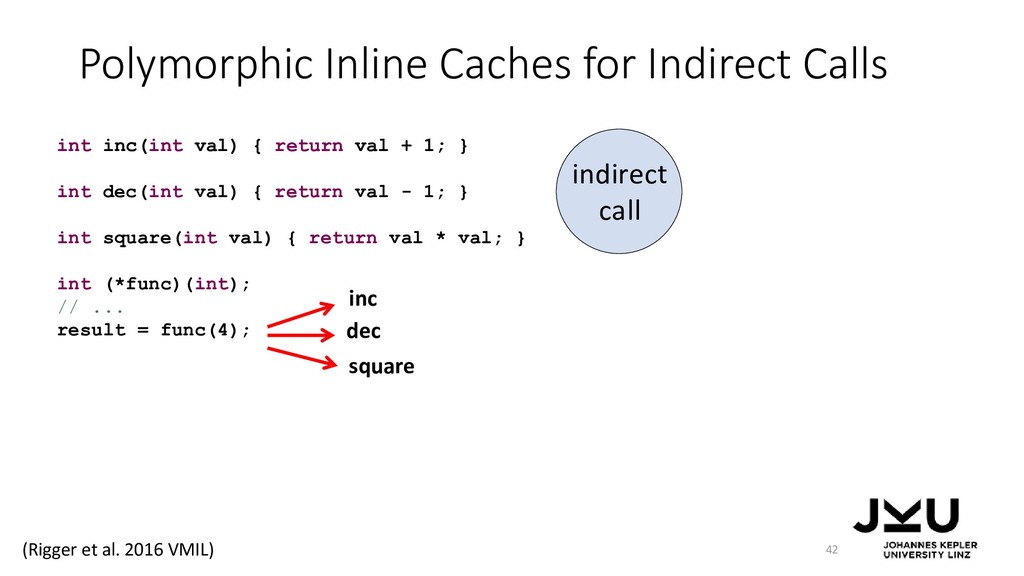
Polymorphic Inline Caches for Indirect Calls 42 indirect call int
inc(int val) { return val + 1; } int dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); inc dec square (Rigger et al. 2016 VMIL) -
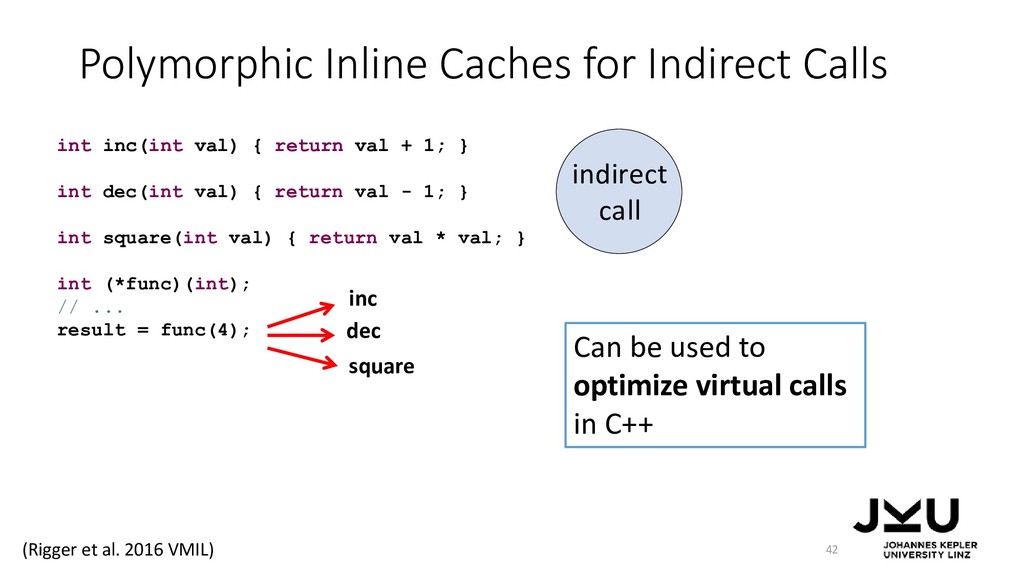
Polymorphic Inline Caches for Indirect Calls 42 indirect call int
inc(int val) { return val + 1; } int dec(int val) { return val - 1; } int square(int val) { return val * val; } int (*func)(int); // ... result = func(4); inc dec square Can be used to optimize virtual calls in C++ (Rigger et al. 2016 VMIL) -
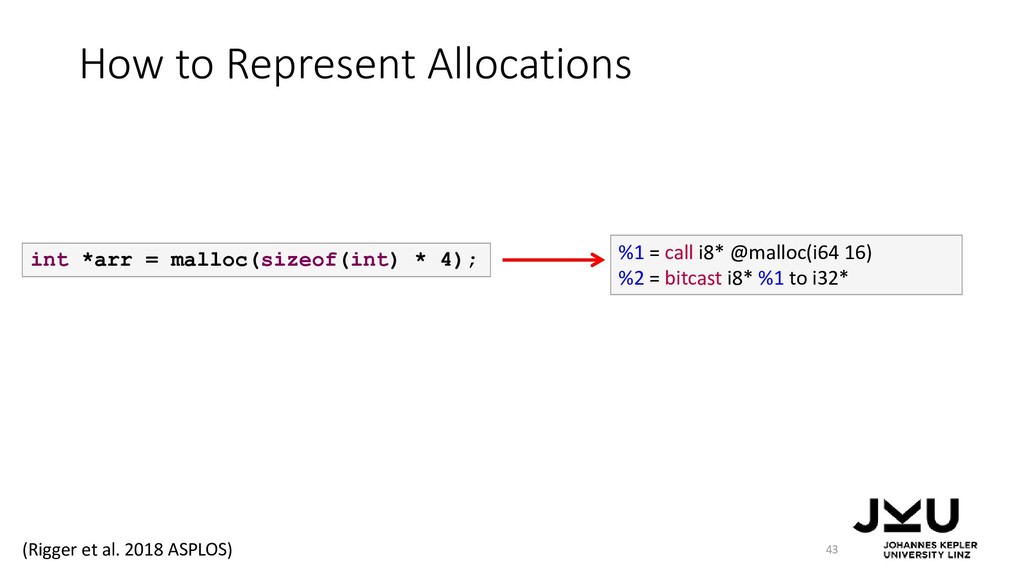
How to Represent Allocations 43 int *arr = malloc(sizeof(int) *
4); %1 = call i8* @malloc(i64 16) %2 = bitcast i8* %1 to i32* (Rigger et al. 2018 ASPLOS) -
How to Represent Allocations 44 %1 = call i8* @malloc(i64
16) %2 = bitcast i8* %1 to i32* Address offset = 0 data UntypedAllocation size=16 (Rigger et al. 2018 ASPLOS) -
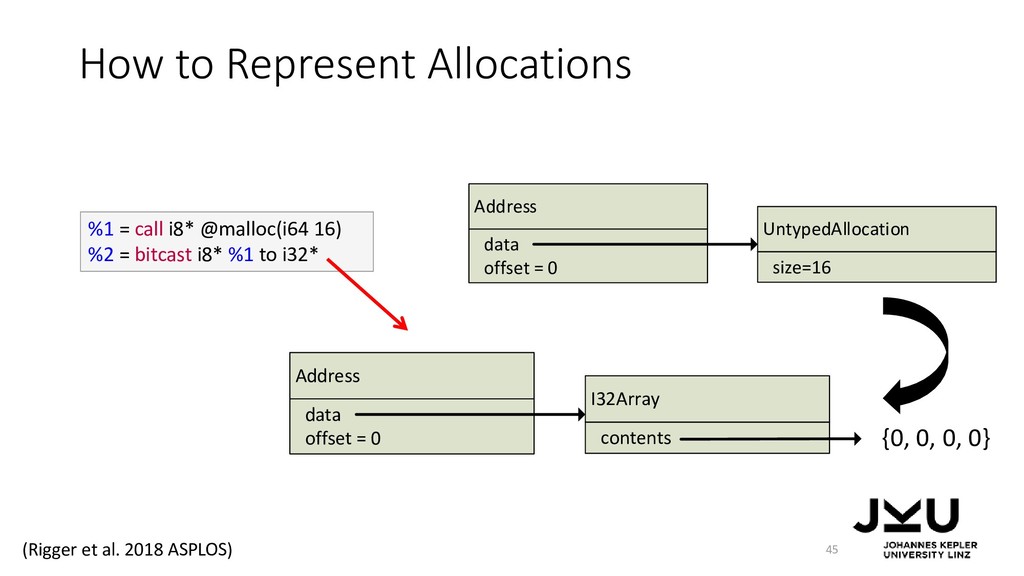
How to Represent Allocations 45 %1 = call i8* @malloc(i64
16) %2 = bitcast i8* %1 to i32* Address offset = 0 data I32Array contents {0, 0, 0, 0} Address offset = 0 data UntypedAllocation size=16 (Rigger et al. 2018 ASPLOS) -
Prevent Out-Of-Bounds Accesses 46 arr[5] = … Address offset =
5 data I32Array contents {0, 0, 0, 0} (Rigger et al. 2018 ASPLOS) -
Prevent Out-Of-Bounds Accesses contents[5] → ArrayIndexOutOfBoundsException 46 arr[5] = …
Address offset = 5 data I32Array contents {0, 0, 0, 0} (Rigger et al. 2018 ASPLOS) -
Prevent Use-After-Free Errors 47 free(arr); arr[0] = … Address offset=0
data I32Array contents {0, 0, 0, 0} (Rigger et al. 2018 ASPLOS) -
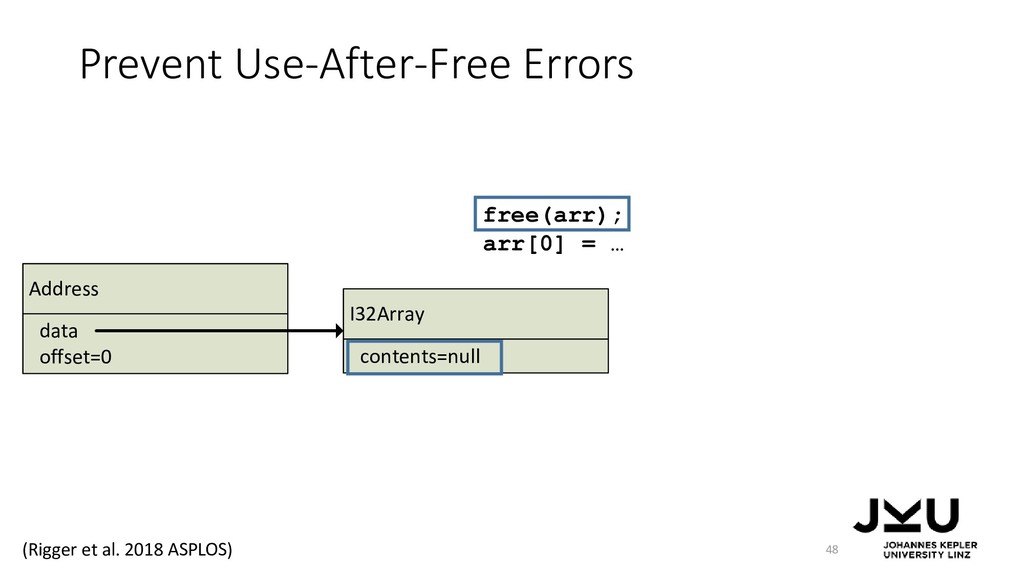
Address offset=0 data I32Array contents=null Prevent Use-After-Free Errors 48 free(arr);
arr[0] = … (Rigger et al. 2018 ASPLOS) -
Address offset=0 data I32Array contents=null Prevent Use-After-Free Errors contents[0]→ NullPointerException
49 free(arr); arr[0] = … (Rigger et al. 2018 ASPLOS) -
Evaluation • Effectiveness • Bug-finding capabilities on open-source projects •
Performance • Warm-up and peak performance • Comparison to state-of-the-art approaches 51 (Rigger et al. 2018 ASPLOS) -
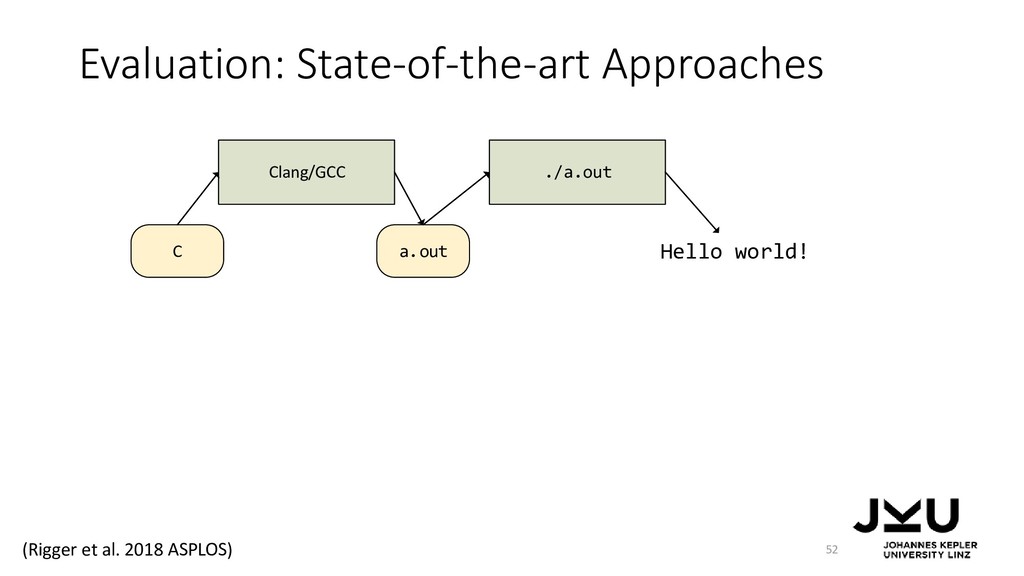
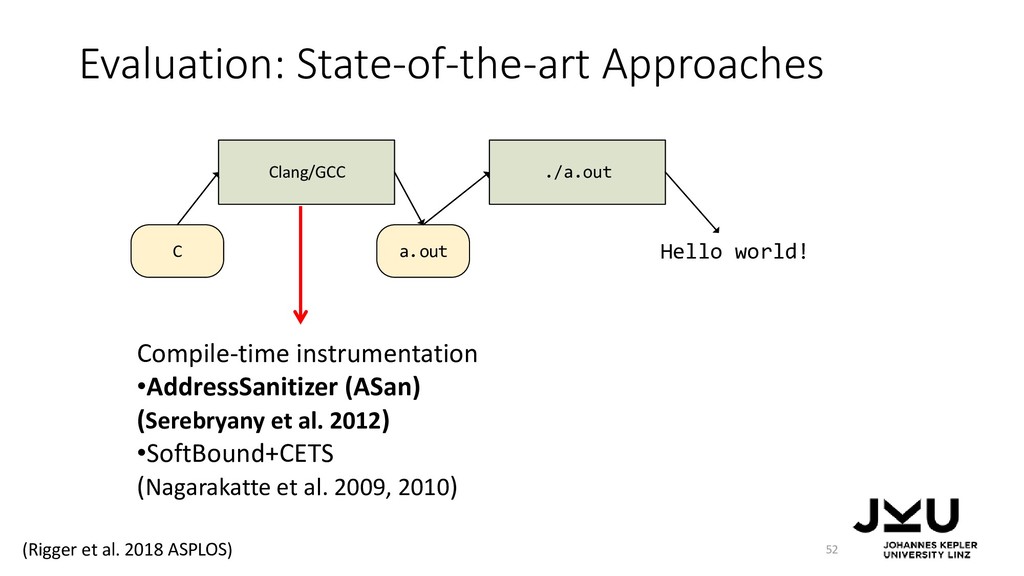
Evaluation: State-of-the-art Approaches 52 a.out Clang/GCC C ./a.out Hello world!
(Rigger et al. 2018 ASPLOS) -
Evaluation: State-of-the-art Approaches 52 Compile-time instrumentation •AddressSanitizer (ASan) (Serebryany et
al. 2012) •SoftBound+CETS (Nagarakatte et al. 2009, 2010) a.out Clang/GCC C ./a.out Hello world! (Rigger et al. 2018 ASPLOS) -
Evaluation: State-of-the-art Approaches 52 Compile-time instrumentation •AddressSanitizer (ASan) (Serebryany et
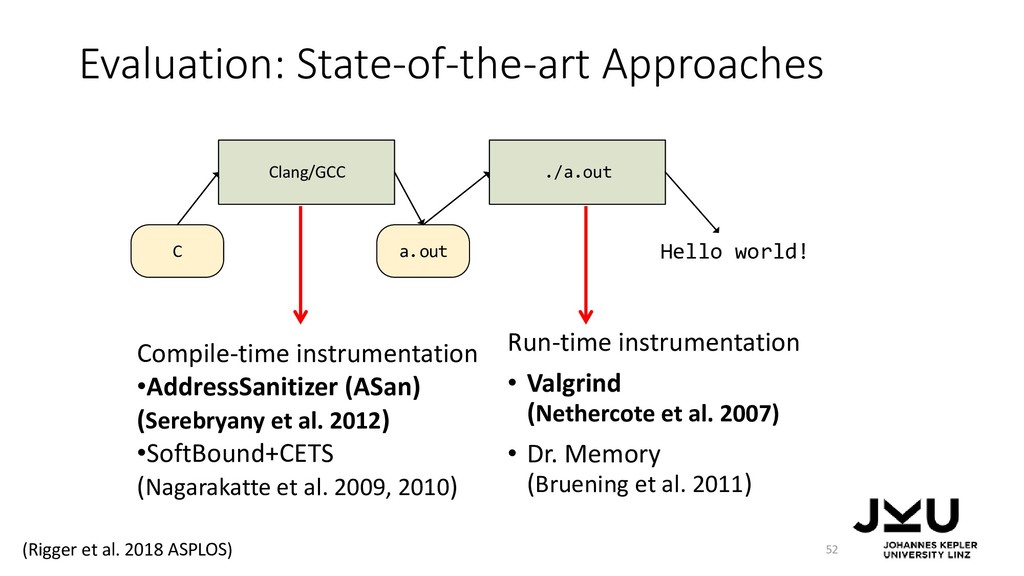
al. 2012) •SoftBound+CETS (Nagarakatte et al. 2009, 2010) a.out Clang/GCC C ./a.out Hello world! Run-time instrumentation • Valgrind (Nethercote et al. 2007) • Dr. Memory (Bruening et al. 2011) (Rigger et al. 2018 ASPLOS) -
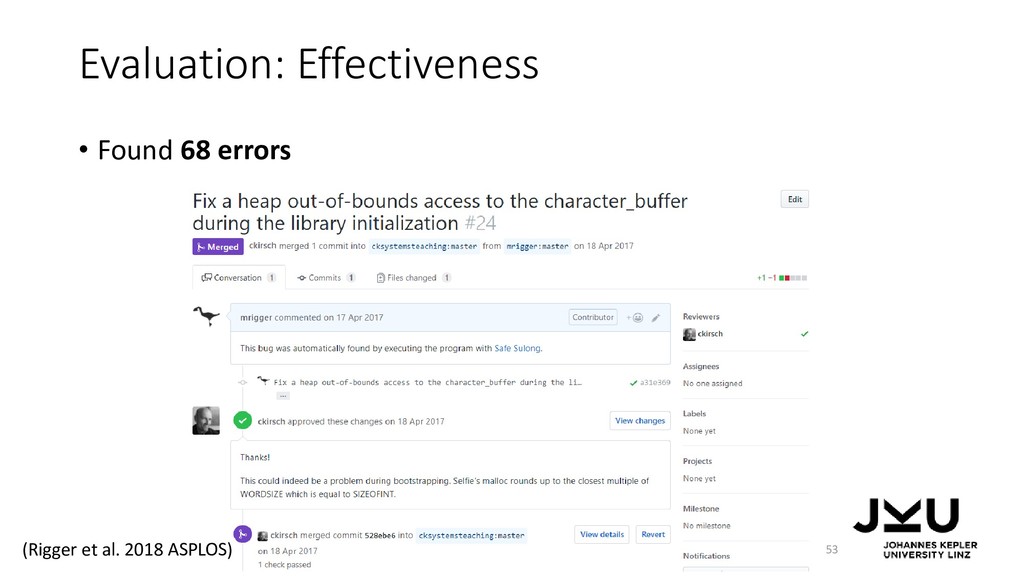
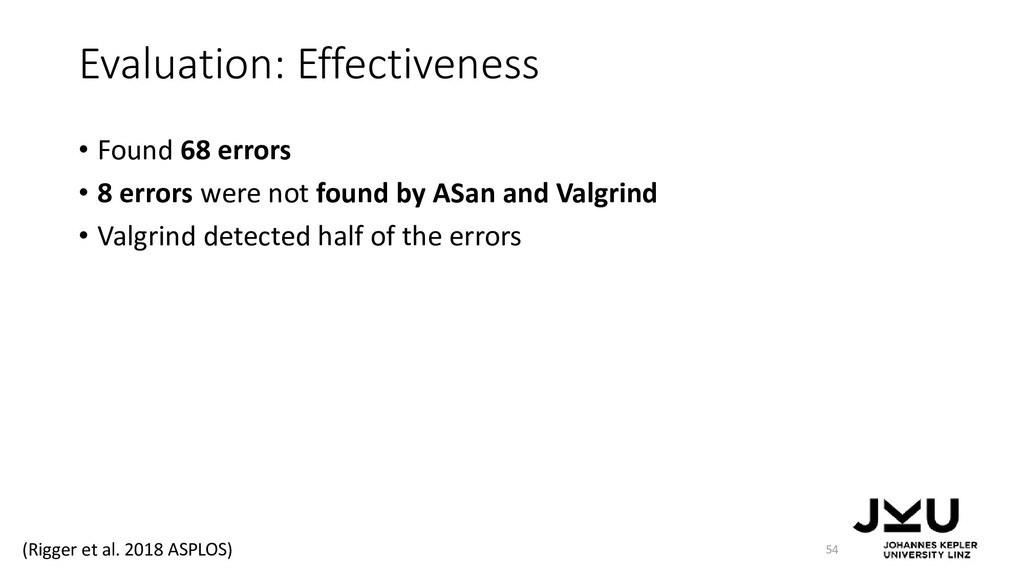
Evaluation: Effectiveness • Found 68 errors • 8 errors were
not found by ASan and Valgrind • Valgrind detected half of the errors 54 (Rigger et al. 2018 ASPLOS) -
Evaluation: Effectiveness 55 int main(int argc, char** argv) { printf("%d
%s\n", argc, argv[100]); } ASan does not instrument the main() arguments since they are allocated by libc https://github.com/google/sanitizers/issues/762 (Rigger et al. 2018 ASPLOS) -
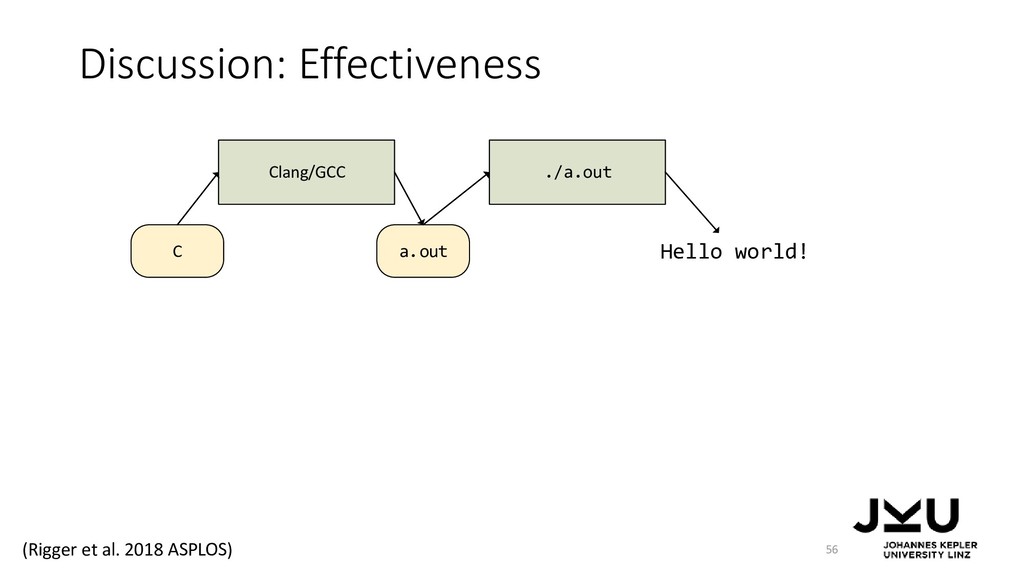
Discussion: Effectiveness 56 a.out Clang/GCC C ./a.out Hello world! (Rigger
et al. 2018 ASPLOS) -
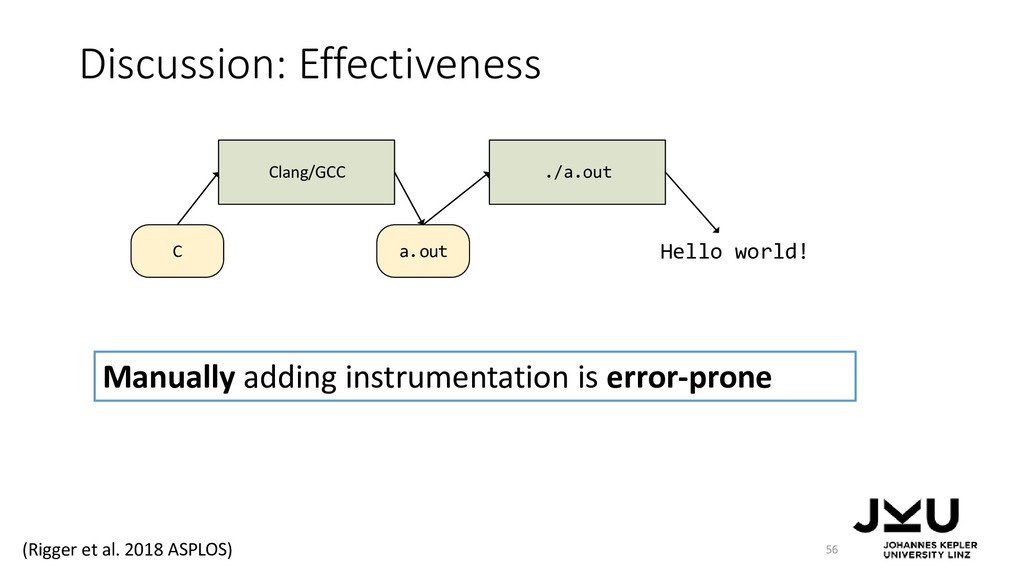
Discussion: Effectiveness 56 Manually adding instrumentation is error-prone a.out Clang/GCC
C ./a.out Hello world! (Rigger et al. 2018 ASPLOS) -
Discussion: Effectiveness • 4 errors not found when optimizations were
turned on 57 (Rigger et al. 2018 ASPLOS) -
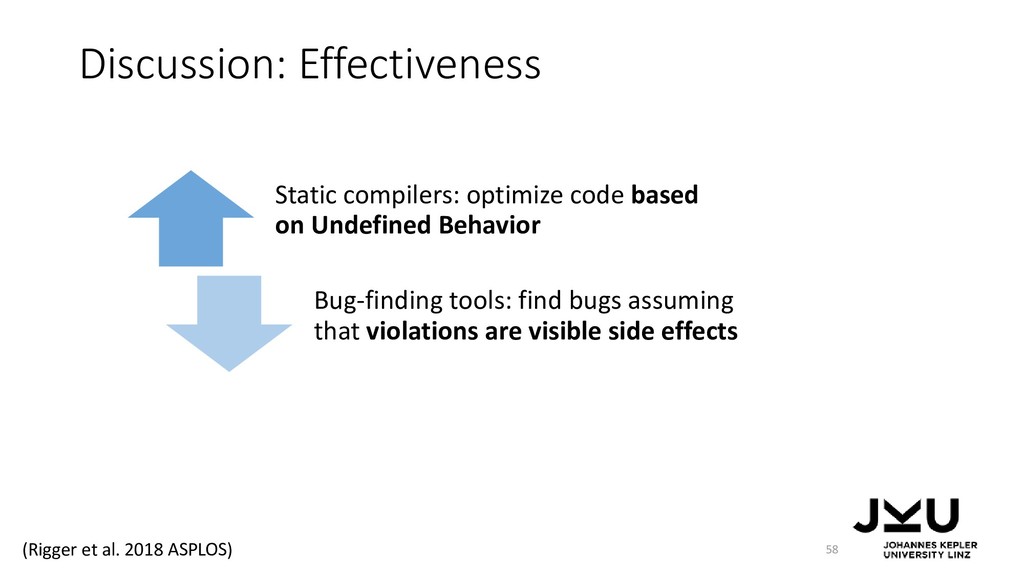
Discussion: Effectiveness 58 Static compilers: optimize code based on Undefined
Behavior Bug-finding tools: find bugs assuming that violations are visible side effects (Rigger et al. 2018 ASPLOS) -
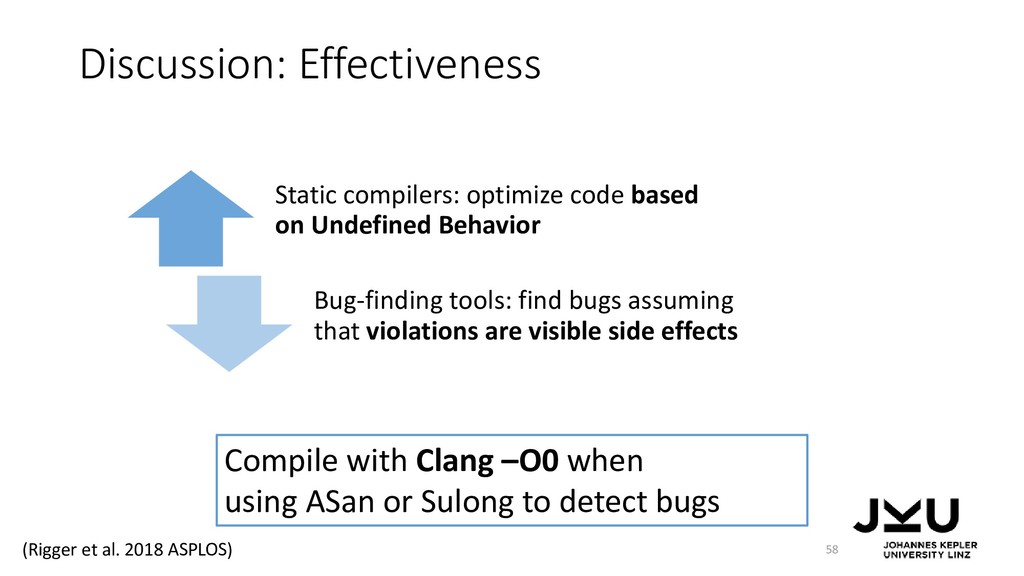
Discussion: Effectiveness 58 Static compilers: optimize code based on Undefined
Behavior Bug-finding tools: find bugs assuming that violations are visible side effects Compile with Clang –O0 when using ASan or Sulong to detect bugs (Rigger et al. 2018 ASPLOS) -
Discussion: Effectiveness 59 ArrayIndexOutOfBoundsException int test(size_t i) { int arr[2]
= {0}; if (i >= 2) { arr[2] = 0xcafe; } return arr[i]; } Java (Rigger et al. 2018 ASPLOS) -
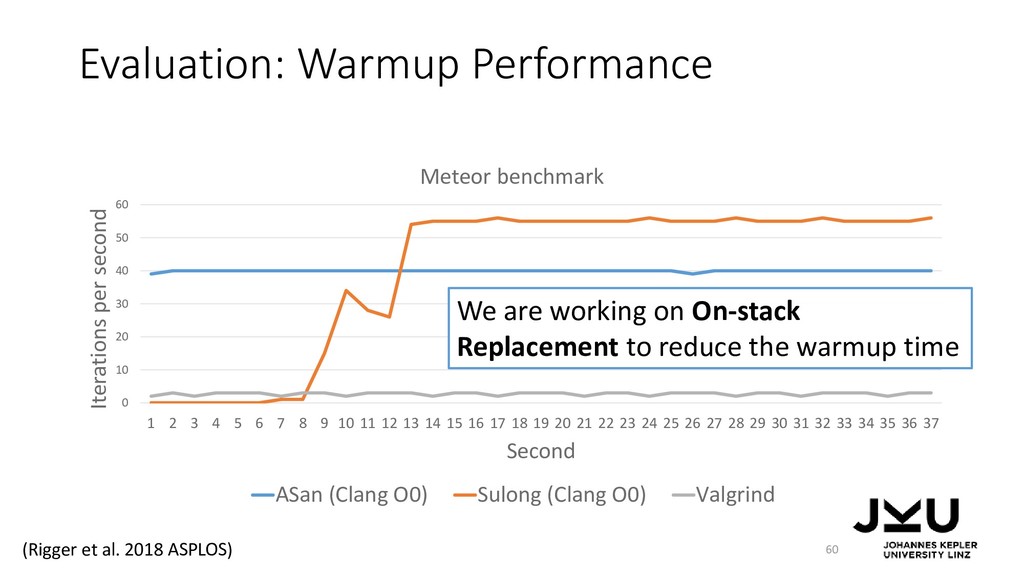
Evaluation: Warmup Performance 60 0 10 20 30 40 50
60 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 Iterations per second Second Meteor benchmark ASan (Clang O0) Sulong (Clang O0) Valgrind (Rigger et al. 2018 ASPLOS) -
Evaluation: Warmup Performance 60 0 10 20 30 40 50
60 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 Iterations per second Second Meteor benchmark ASan (Clang O0) Sulong (Clang O0) Valgrind We are working on On-stack Replacement to reduce the warmup time (Rigger et al. 2018 ASPLOS) -
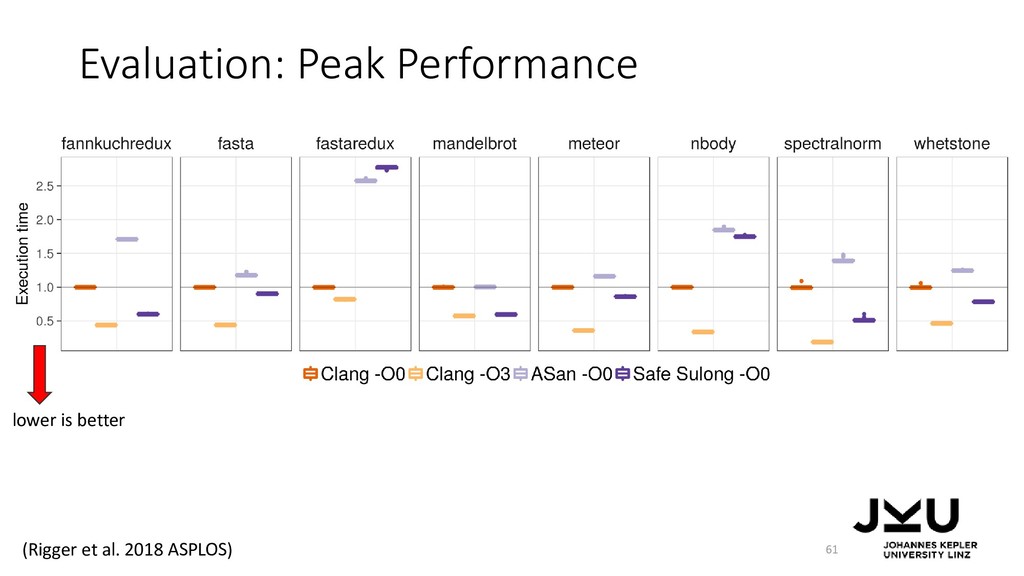
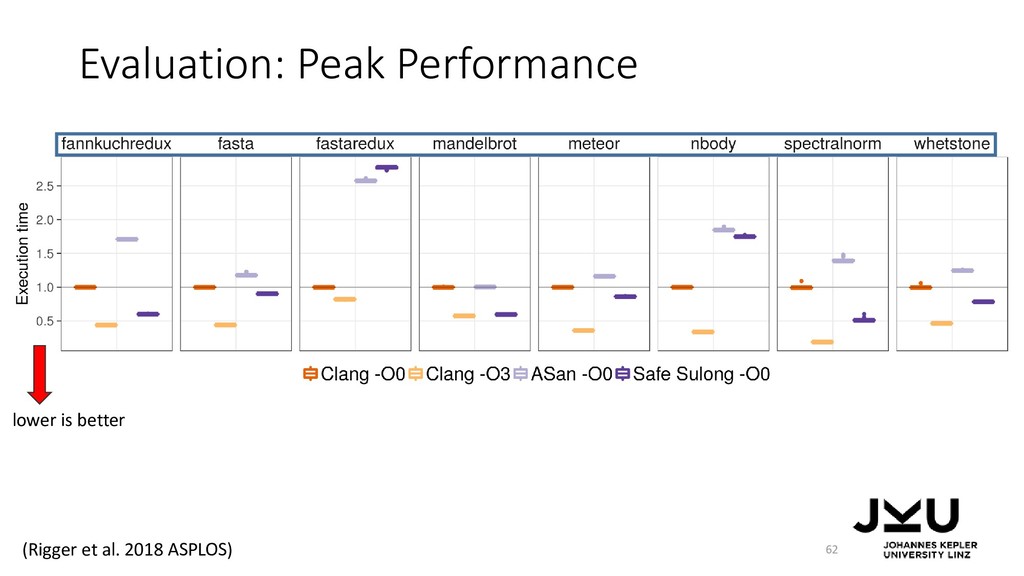
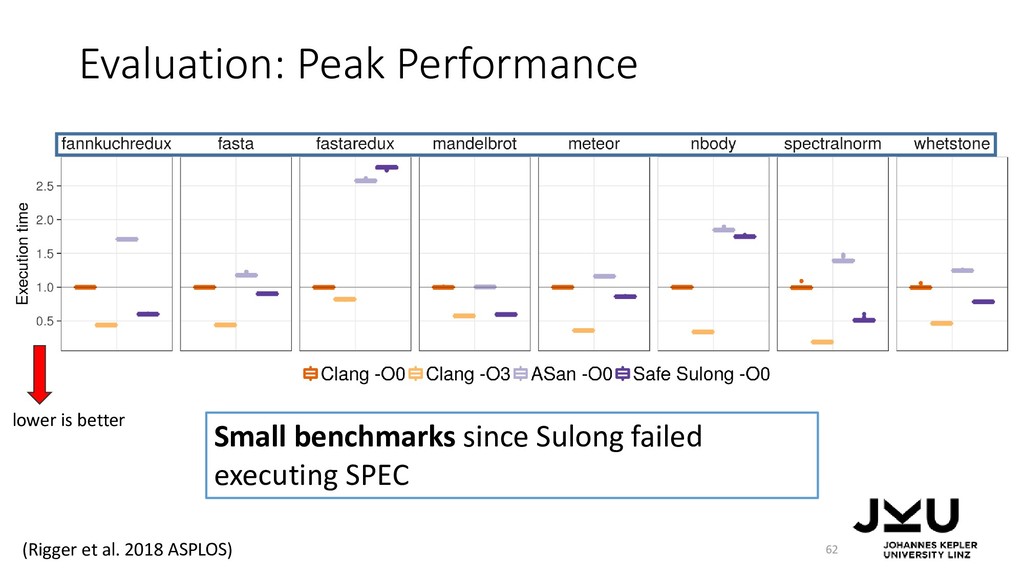
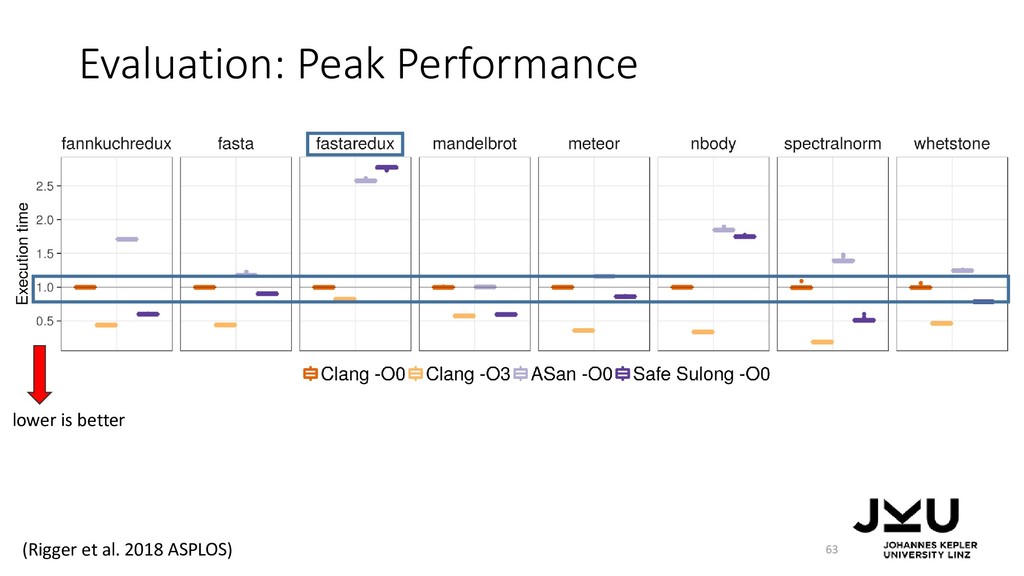
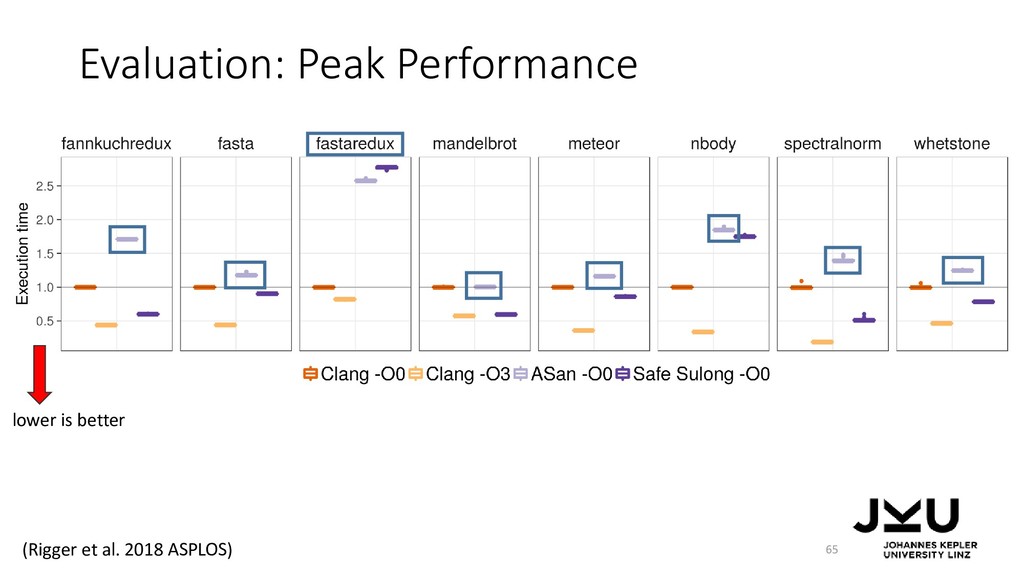
Evaluation: Peak Performance 62 Small benchmarks since Sulong failed executing
SPEC lower is better (Rigger et al. 2018 ASPLOS) -
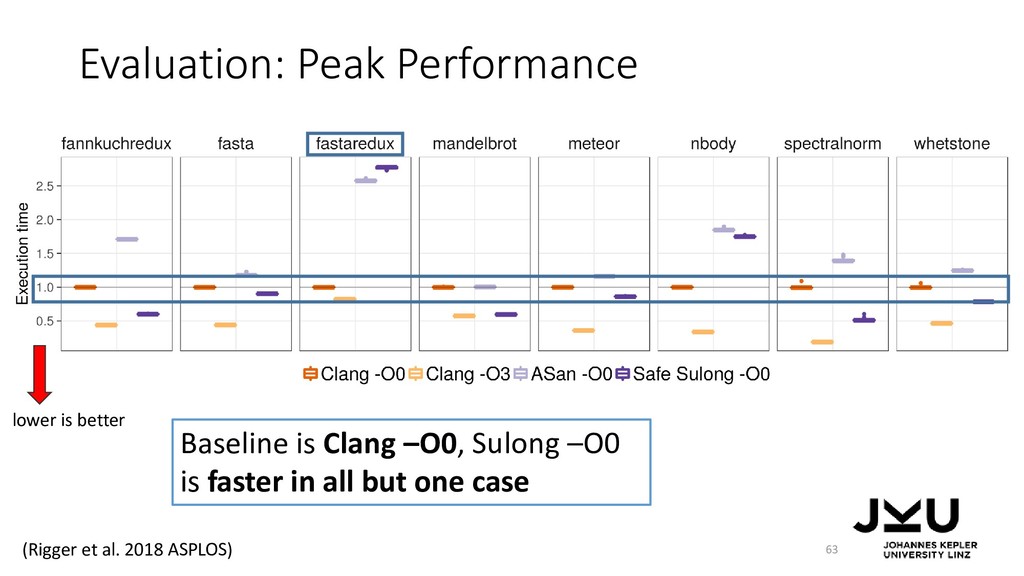
Evaluation: Peak Performance 63 Baseline is Clang –O0, Sulong –O0
is faster in all but one case lower is better (Rigger et al. 2018 ASPLOS) -
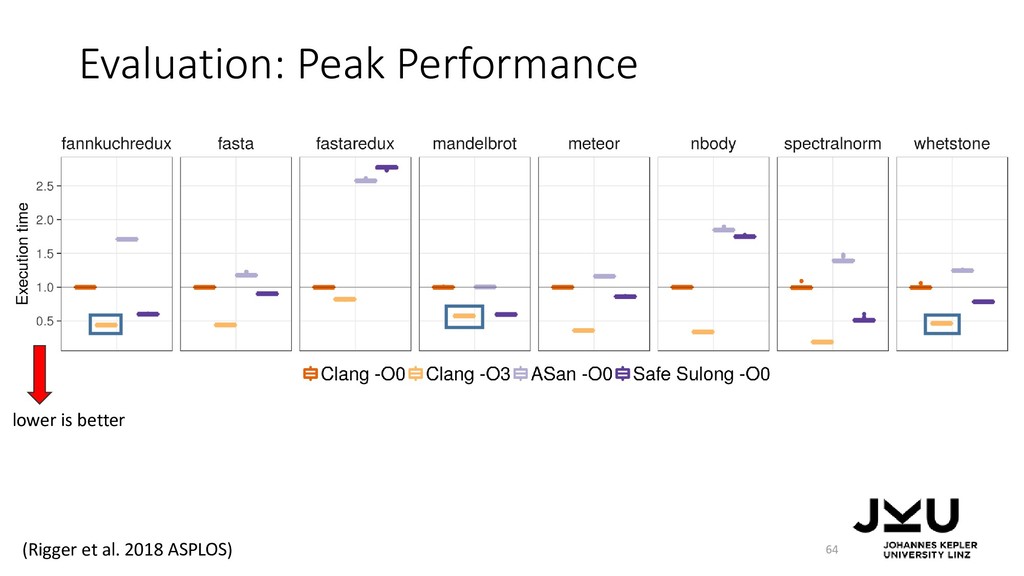
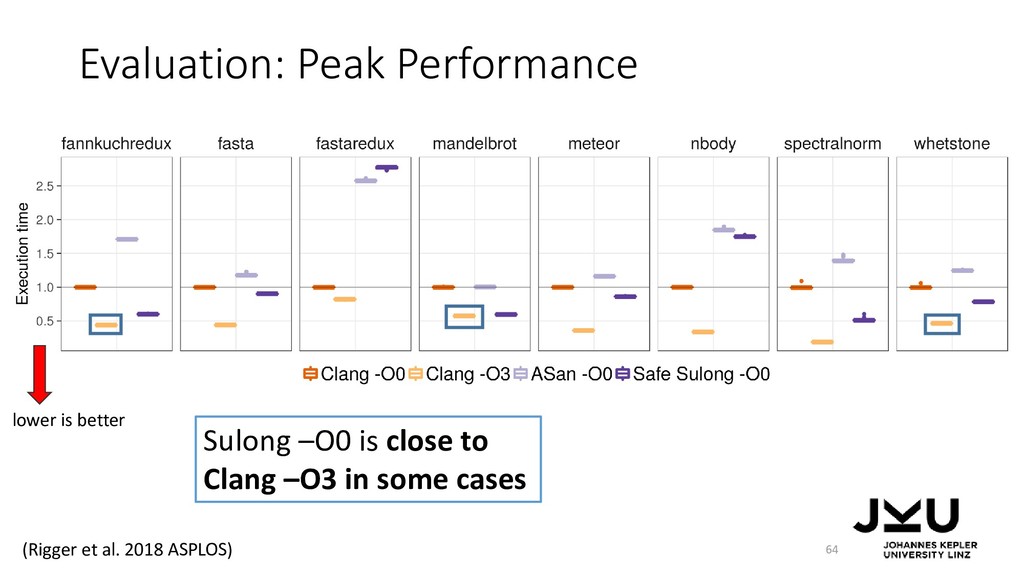
Evaluation: Peak Performance 64 Sulong –O0 is close to Clang
–O3 in some cases lower is better (Rigger et al. 2018 ASPLOS) -
Evaluation: Peak Performance 65 Sulong –O0 is mostly faster than
ASan –O0 lower is better (Rigger et al. 2018 ASPLOS) -
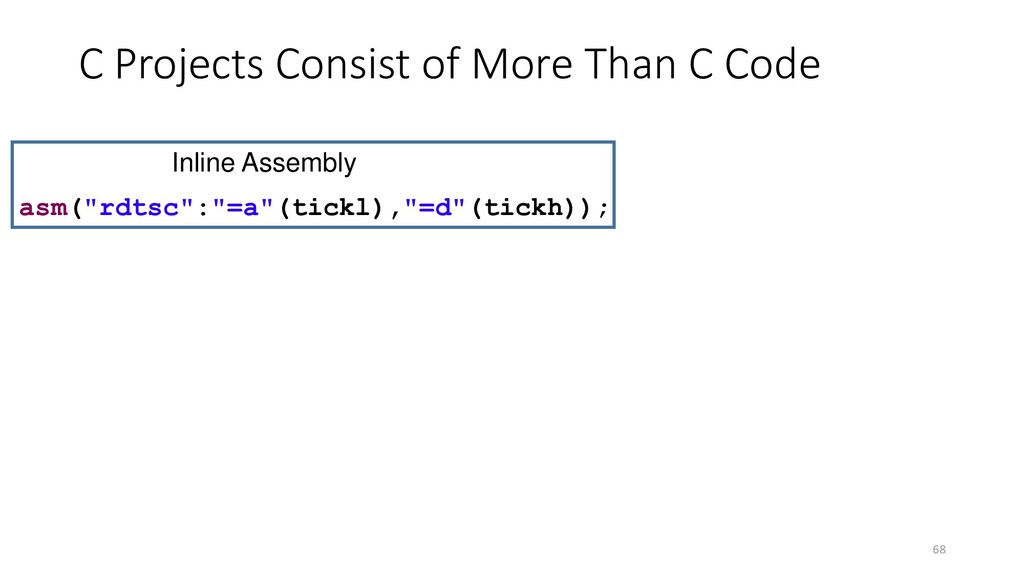
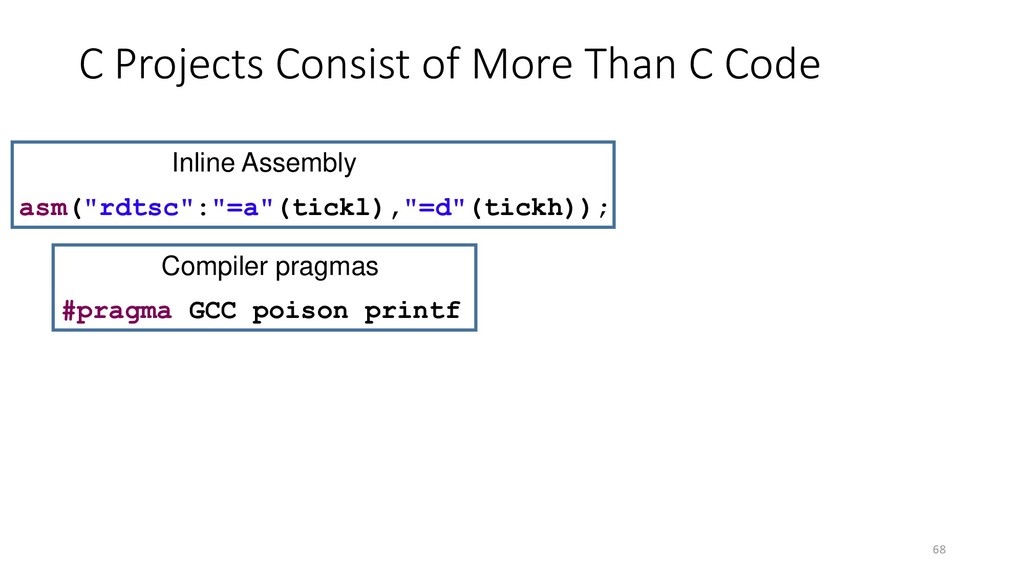
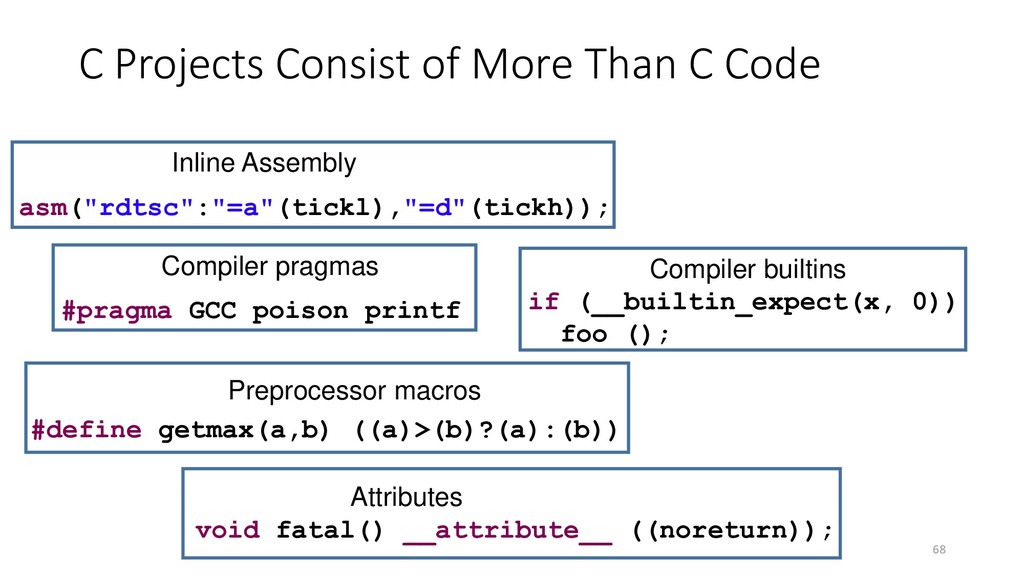
68 asm("rdtsc":"=a"(tickl),"=d"(tickh)); #pragma GCC poison printf Inline Assembly Compiler pragmas
C Projects Consist of More Than C Code -
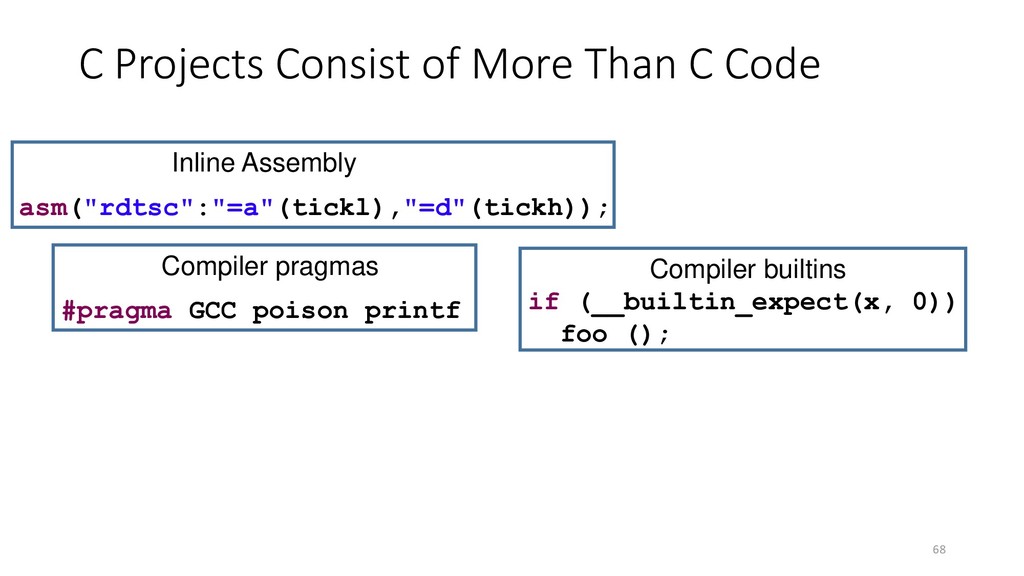
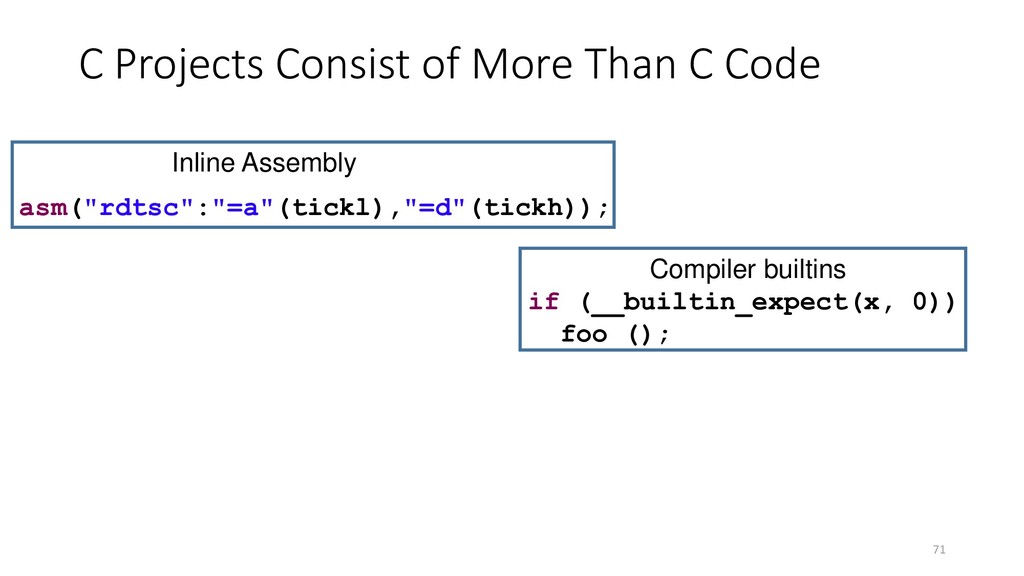
68 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); #pragma GCC poison
printf Inline Assembly Compiler builtins Compiler pragmas C Projects Consist of More Than C Code -
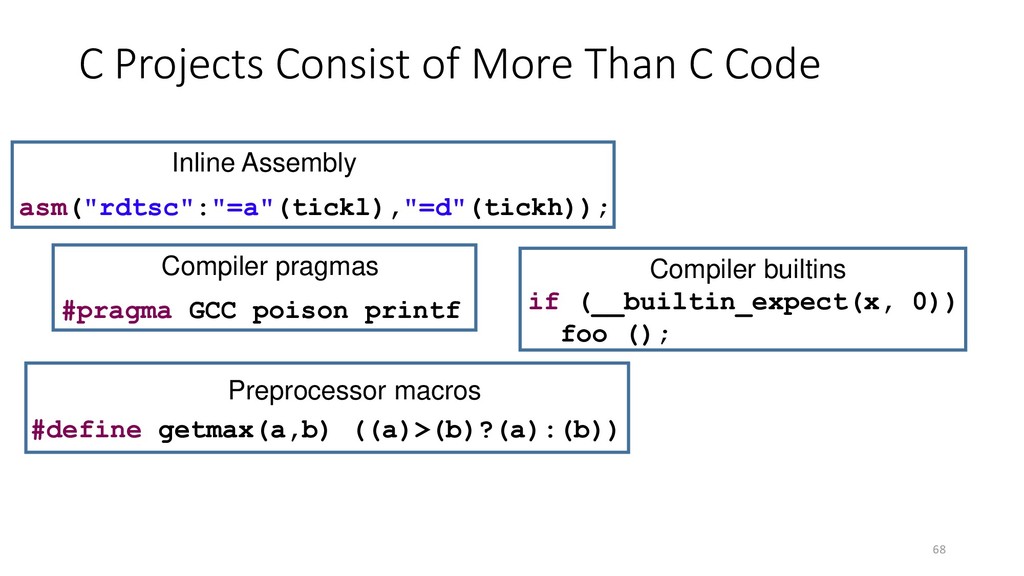
68 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); #pragma GCC poison
printf Inline Assembly Compiler builtins Compiler pragmas #define getmax(a,b) ((a)>(b)?(a):(b)) Preprocessor macros C Projects Consist of More Than C Code -
68 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); #pragma GCC poison
printf Inline Assembly Compiler builtins Compiler pragmas #define getmax(a,b) ((a)>(b)?(a):(b)) Preprocessor macros void fatal() __attribute__ ((noreturn)); Attributes C Projects Consist of More Than C Code -
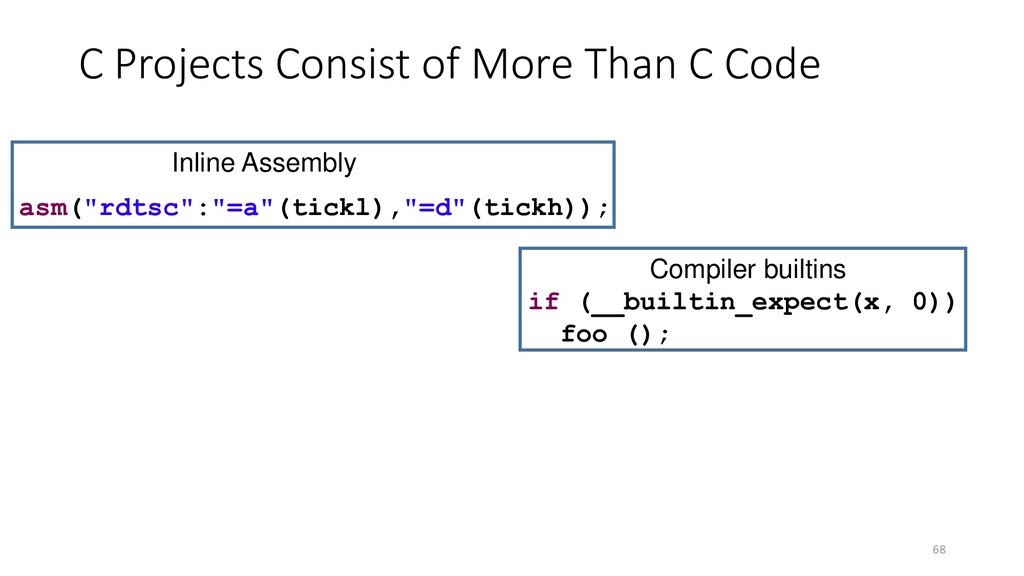
68 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly Compiler
builtins C Projects Consist of More Than C Code -
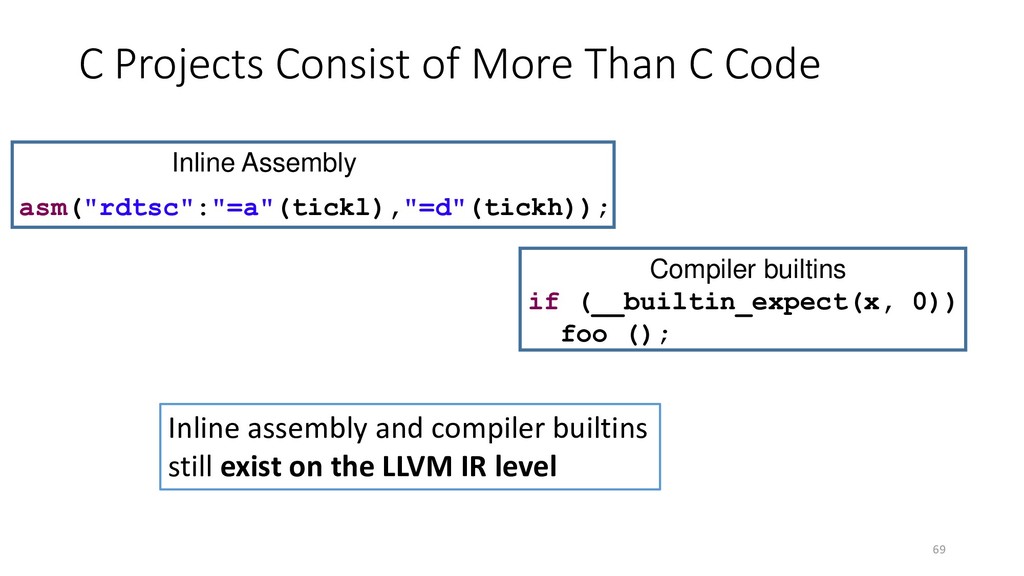
69 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly Compiler
builtins C Projects Consist of More Than C Code -
69 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly Compiler
builtins Inline assembly and compiler builtins still exist on the LLVM IR level C Projects Consist of More Than C Code -
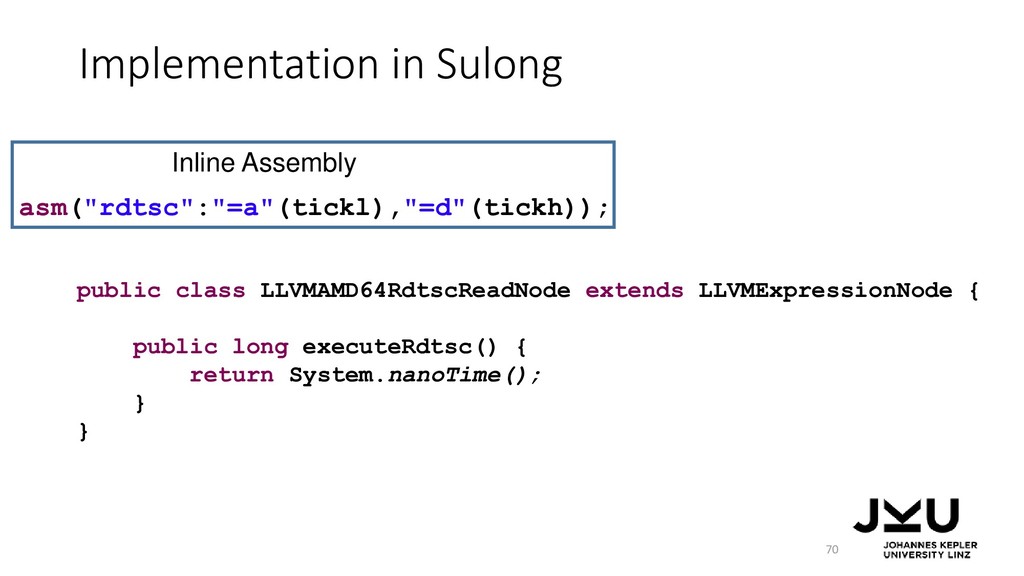
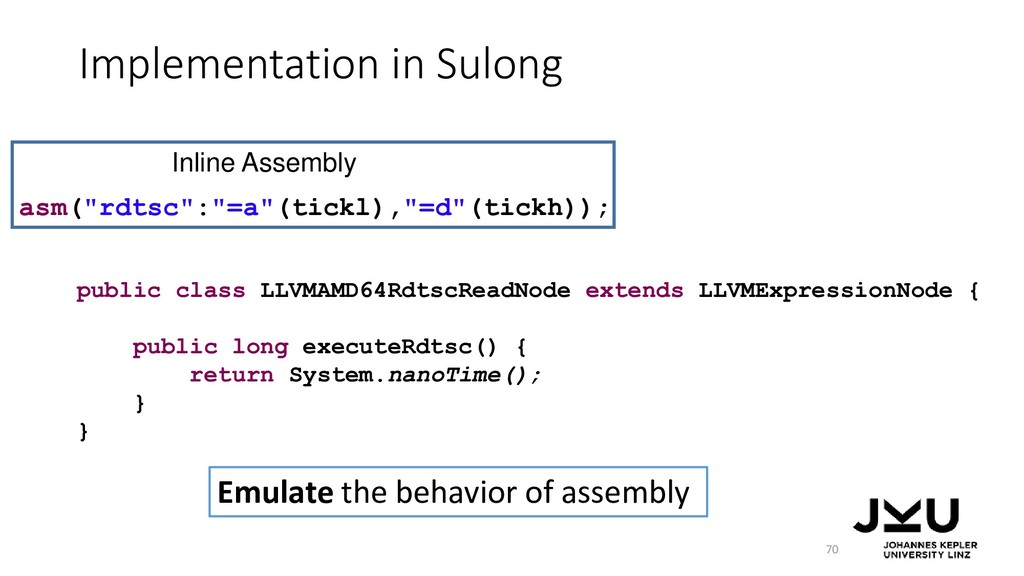
Implementation in Sulong 70 public class LLVMAMD64RdtscReadNode extends LLVMExpressionNode {
public long executeRdtsc() { return System.nanoTime(); } } asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly -
Implementation in Sulong 70 public class LLVMAMD64RdtscReadNode extends LLVMExpressionNode {
public long executeRdtsc() { return System.nanoTime(); } } Emulate the behavior of assembly asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly -
71 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly Compiler
builtins C Projects Consist of More Than C Code -
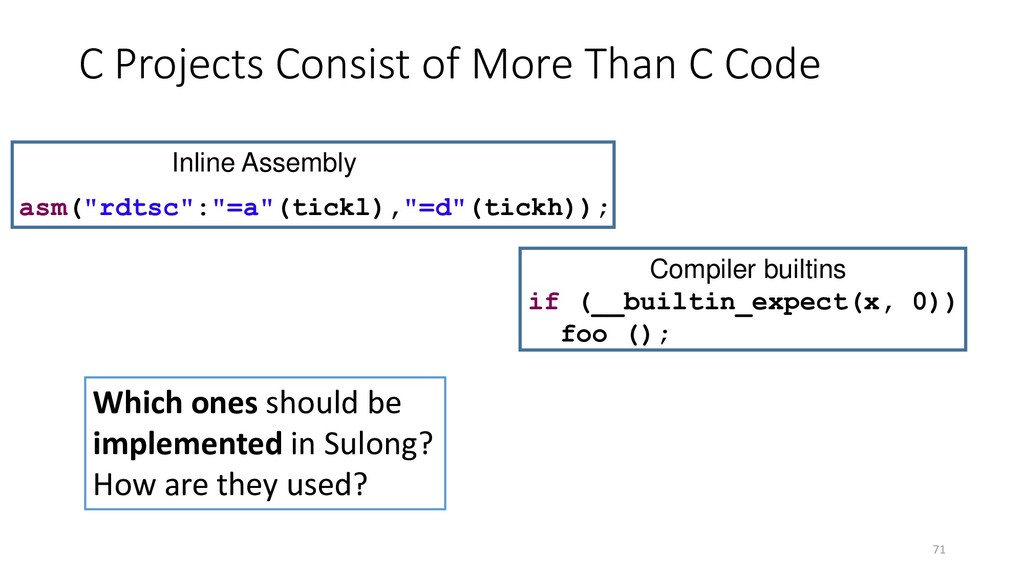
71 if (__builtin_expect(x, 0)) foo (); asm("rdtsc":"=a"(tickl),"=d"(tickh)); Inline Assembly Compiler
builtins Which ones should be implemented in Sulong? How are they used? C Projects Consist of More Than C Code -
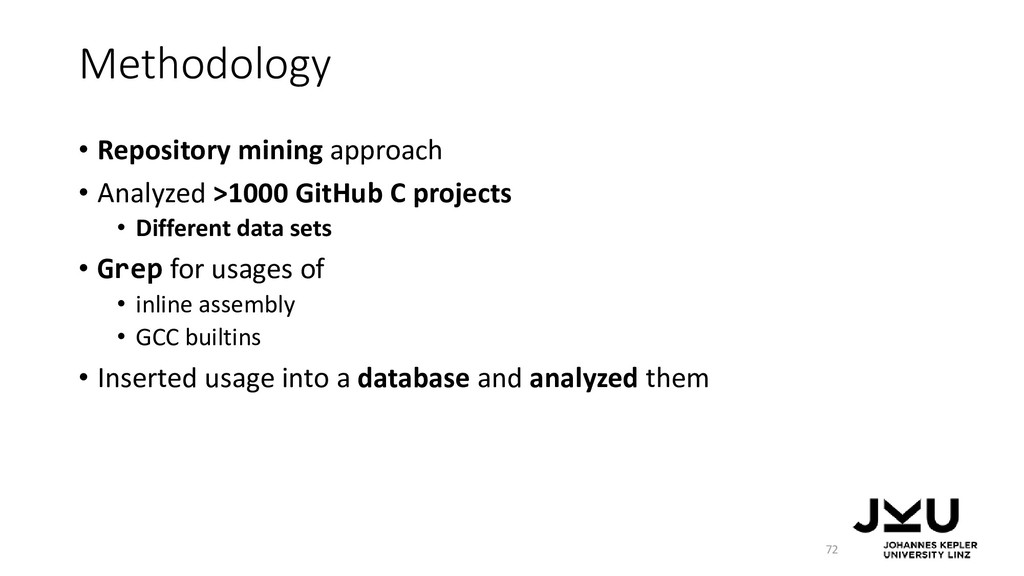
Methodology • Repository mining approach • Analyzed >1000 GitHub C
projects • Different data sets • Grep for usages of • inline assembly • GCC builtins • Inserted usage into a database and analyzed them 72 -
Percentage of Projects 73 28% 37% 0 10 20 30
40 % of projects Popular projects with inline assembly (Popular) projects with GCC builtins (Rigger et al. 2018 VEE) -
Density (occurrence per KLOC) 74 50k 6k 0 10 20
30 40 50 Density (occurrence per KLOC) Popular projects with inline assembly (Popular) projects with GCC builtins (Rigger et al. 2018 VEE) -
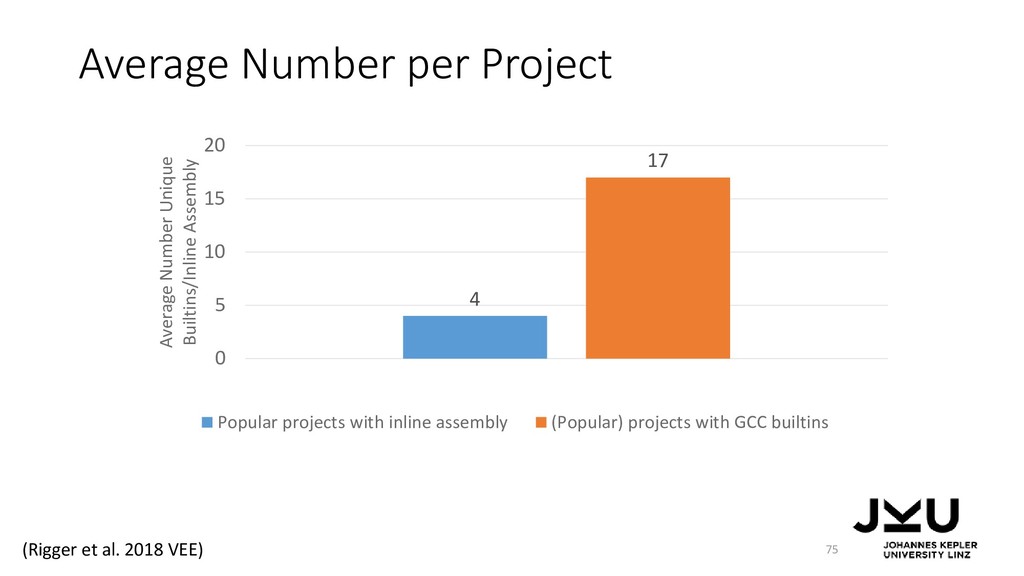
Average Number per Project 75 4 17 0 5 10
15 20 Average Number Unique Builtins/Inline Assembly Popular projects with inline assembly (Popular) projects with GCC builtins (Rigger et al. 2018 VEE) -
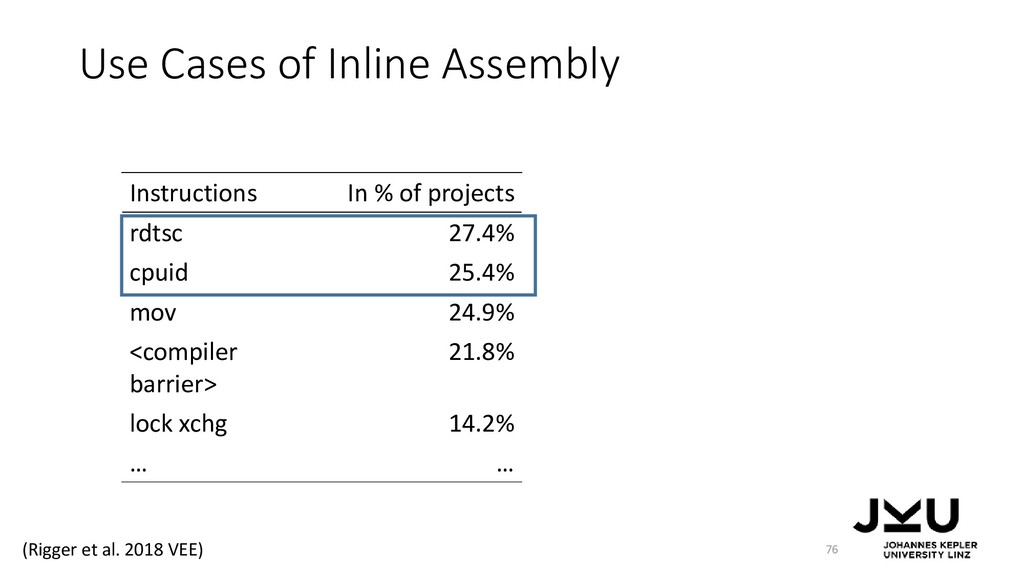
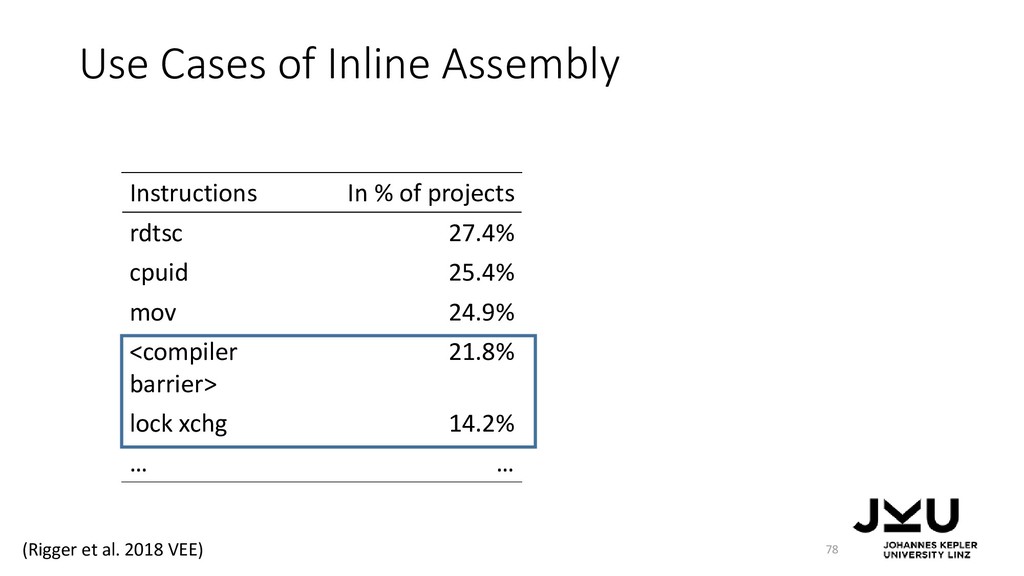
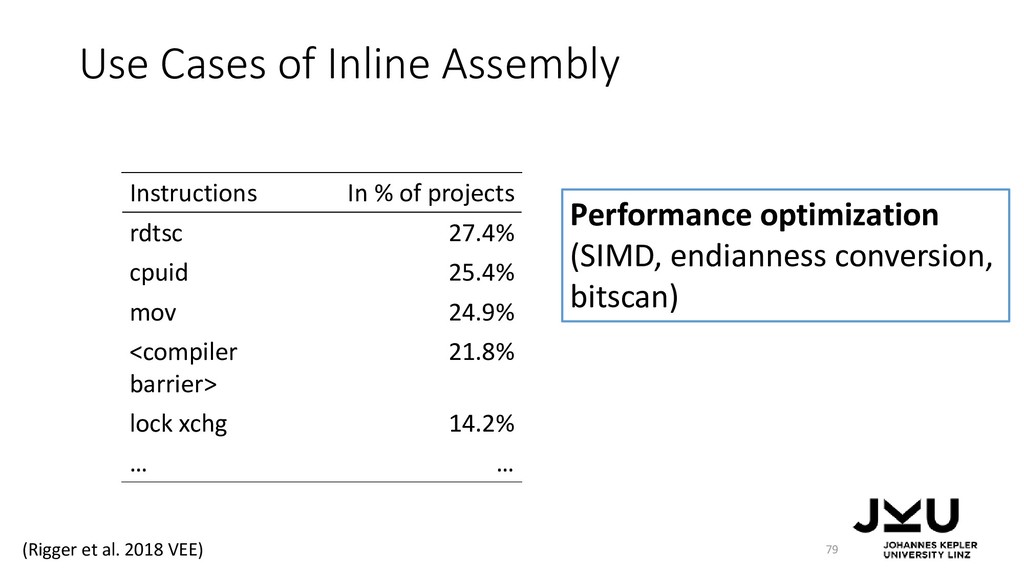
Use Cases of Inline Assembly 76 Instructions In % of
projects rdtsc 27.4% cpuid 25.4% mov 24.9% <compiler barrier> 21.8% lock xchg 14.2% … … (Rigger et al. 2018 VEE) -
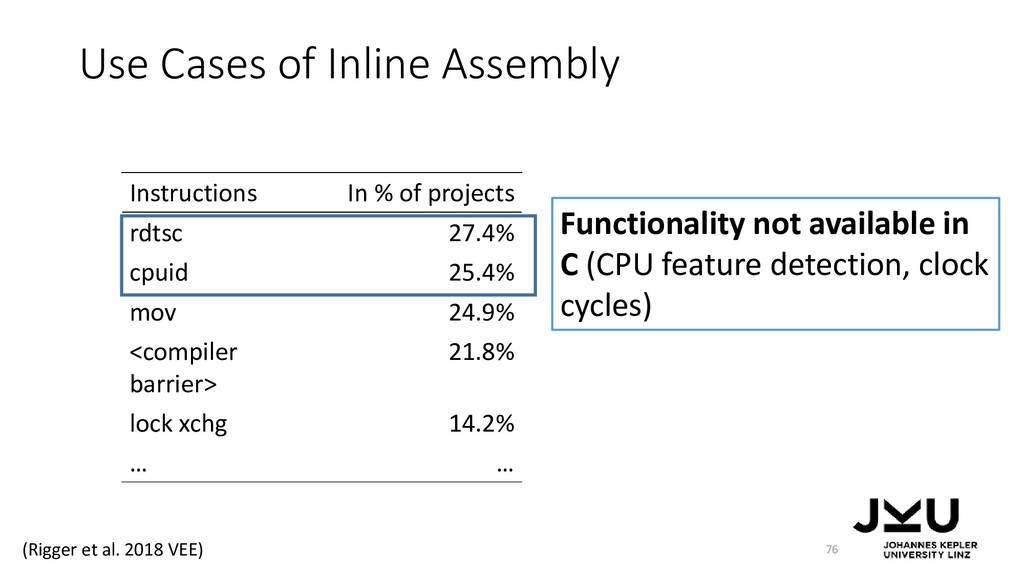
Use Cases of Inline Assembly 76 Instructions In % of
projects rdtsc 27.4% cpuid 25.4% mov 24.9% <compiler barrier> 21.8% lock xchg 14.2% … … Functionality not available in C (CPU feature detection, clock cycles) (Rigger et al. 2018 VEE) -
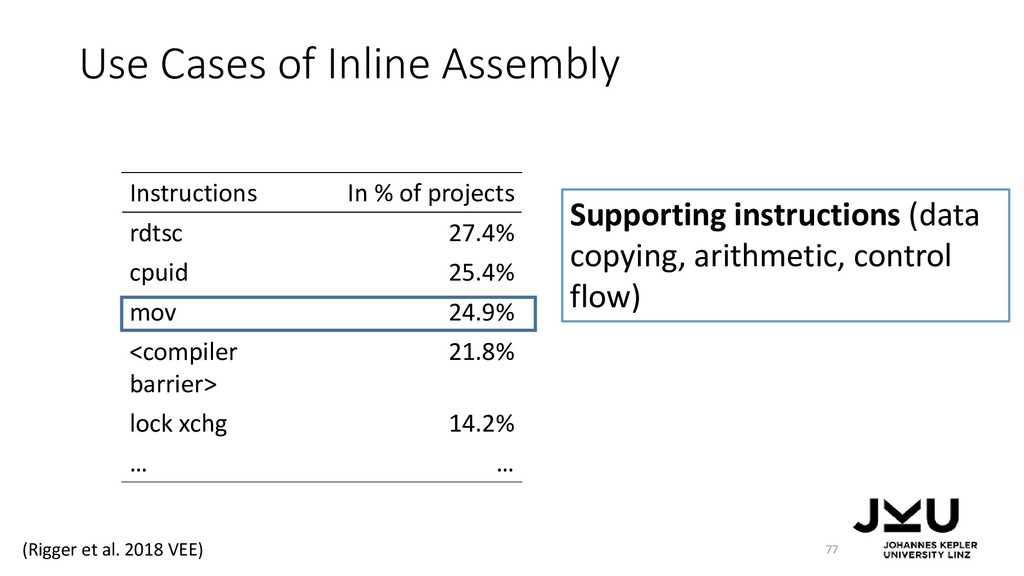
Use Cases of Inline Assembly 77 Instructions In % of
projects rdtsc 27.4% cpuid 25.4% mov 24.9% <compiler barrier> 21.8% lock xchg 14.2% … … Supporting instructions (data copying, arithmetic, control flow) (Rigger et al. 2018 VEE) -
Use Cases of Inline Assembly 78 Instructions In % of
projects rdtsc 27.4% cpuid 25.4% mov 24.9% <compiler barrier> 21.8% lock xchg 14.2% … … (Rigger et al. 2018 VEE) -
Use Cases of Inline Assembly 78 Instructions In % of
projects rdtsc 27.4% cpuid 25.4% mov 24.9% <compiler barrier> 21.8% lock xchg 14.2% … … Instruction order (compiler barriers, memory barriers, atomics) (Rigger et al. 2018 VEE) -
Use Cases of Inline Assembly 79 Instructions In % of
projects rdtsc 27.4% cpuid 25.4% mov 24.9% <compiler barrier> 21.8% lock xchg 14.2% … … Performance optimization (SIMD, endianness conversion, bitscan) (Rigger et al. 2018 VEE) -
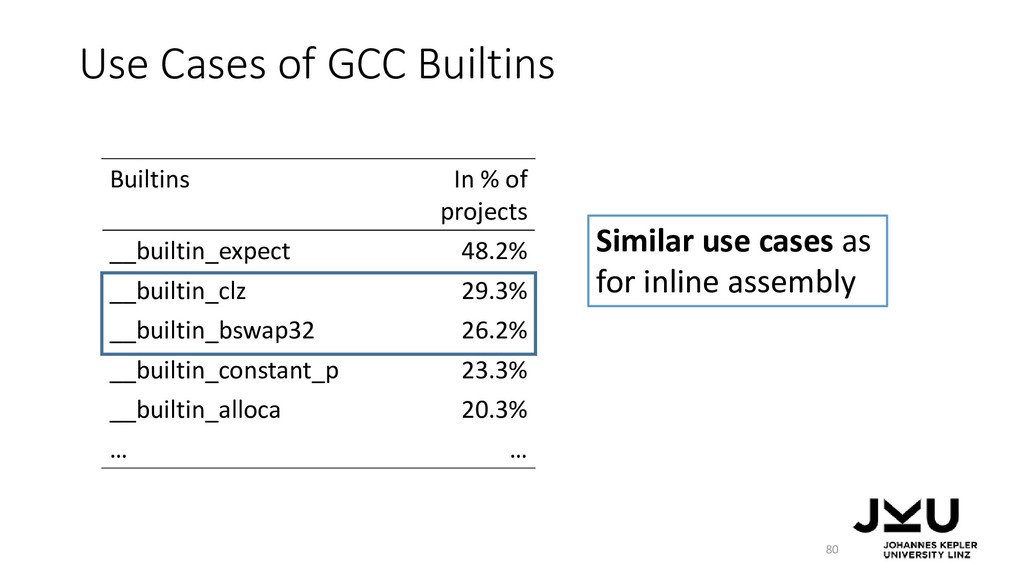
Use Cases of GCC Builtins 80 Builtins In % of
projects __builtin_expect 48.2% __builtin_clz 29.3% __builtin_bswap32 26.2% __builtin_constant_p 23.3% __builtin_alloca 20.3% … … Similar use cases as for inline assembly -
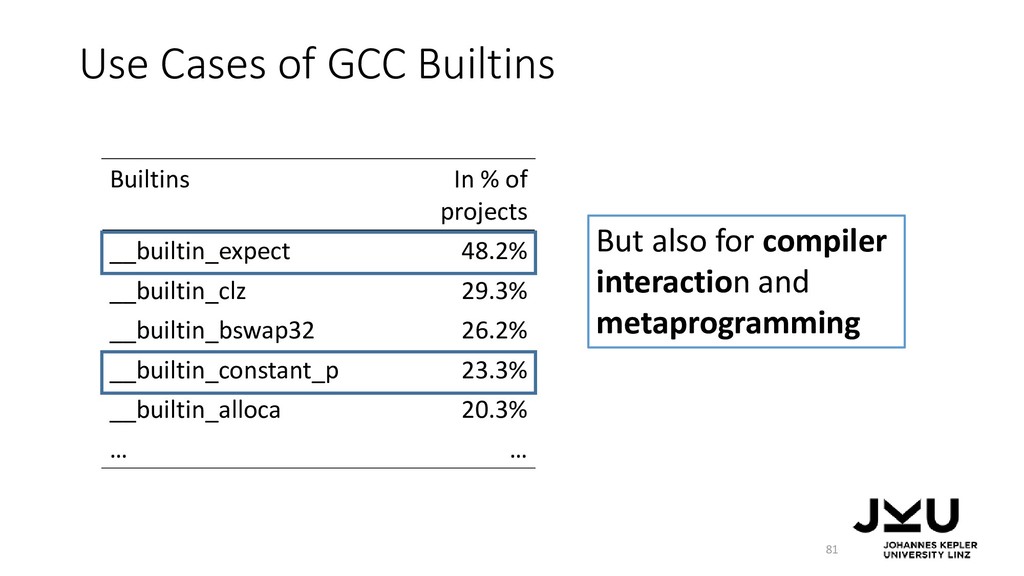
Use Cases of GCC Builtins 81 Builtins In % of
projects __builtin_expect 48.2% __builtin_clz 29.3% __builtin_bswap32 26.2% __builtin_constant_p 23.3% __builtin_alloca 20.3% … … But also for compiler interaction and metaprogramming -
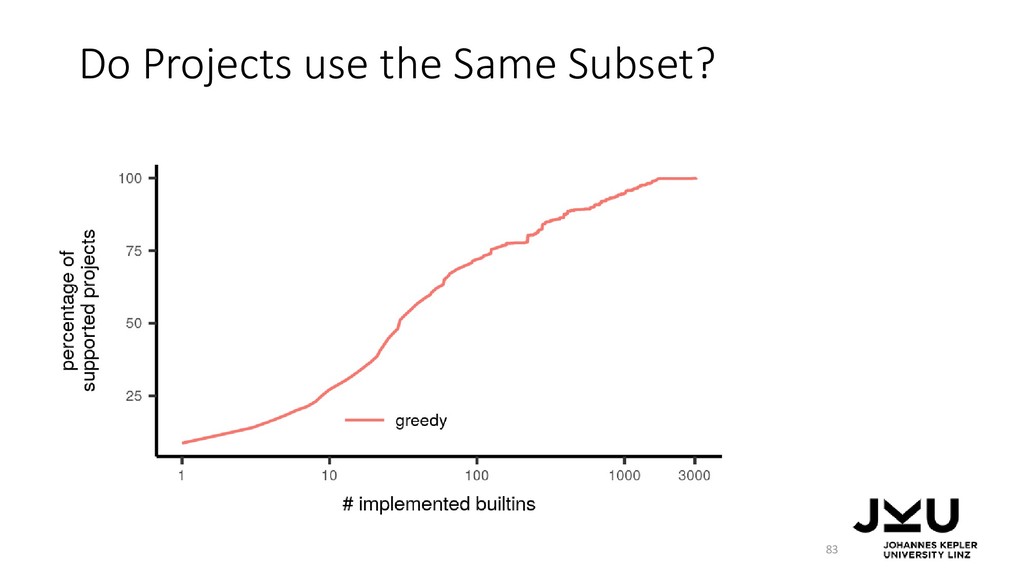
Do Projects use the Same Subset? 82 • How many
projects can be supported by implementing 5% of x86-64’s ~1000 instructions? • At least 64% of projects (we did not analyze some large projects) 0 10 20 30 40 50 60 70 80 90 2 4 13 22 28 31 32 36 46 47 49 50 % of supported projects Number of implemented instructions 77.9% (Rigger et al. 2018 VEE) -
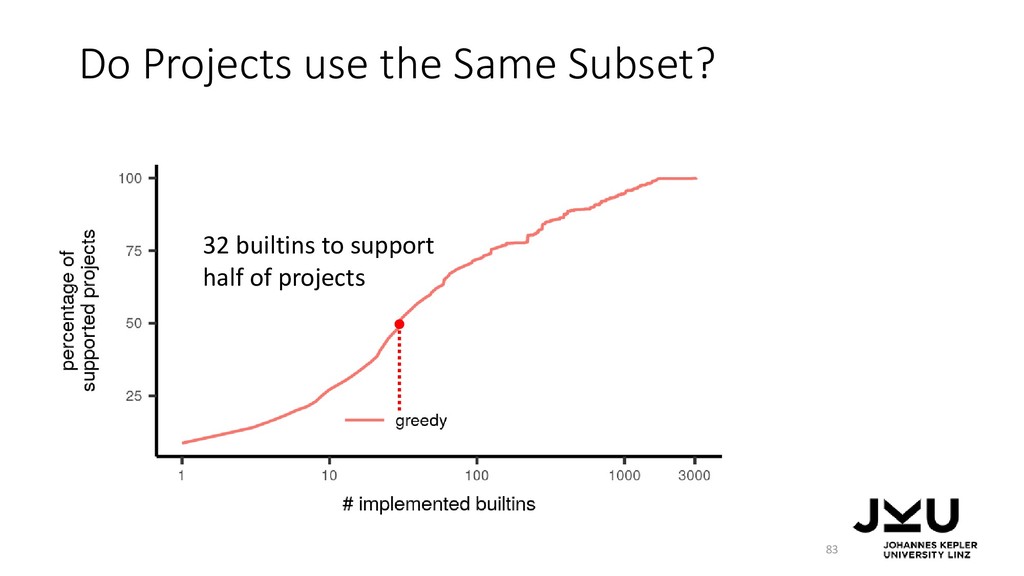
Do Projects use the Same Subset? 83 32 builtins to
support half of projects -
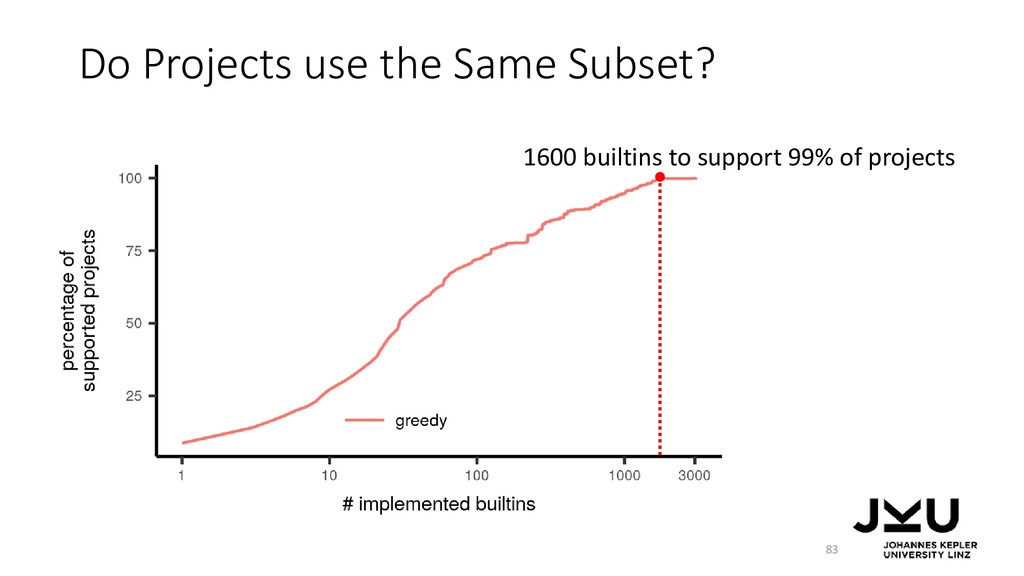
Do Projects use the Same Subset? 83 1600 builtins to
support 99% of projects -
Conclusion 84 @RiggerManuel Sulong and GraalVM Sulong’s LLVM IR Interpreter
Detection of Errors -
Conclusion 84 @RiggerManuel Sulong and GraalVM Sulong’s LLVM IR Interpreter
Detection of Errors Dynamic Optimizations -
Conclusion 84 @RiggerManuel Sulong and GraalVM Sulong’s LLVM IR Interpreter
Detection of Errors Dynamic Optimizations Usage of Unstandardized C Elements -
Bibliography • Thomas Würthinger, Andreas Wöß, Lukas Stadler, Gilles Duboscq,
Doug Simon, and Christian Wimmer. 2012. Self-optimizing AST interpreters. In Proceedings of the 8th symposium on Dynamic languages (DLS '12). ACM, New York, NY, USA, 73-82. DOI=http://dx.doi.org/10.1145/2384577.2384587 • Thomas Würthinger, Christian Wimmer, Andreas Wöß, Lukas Stadler, Gilles Duboscq, Christian Humer, Gregor Richards, Doug Simon, and Mario Wolczko. 2013. One VM to rule them all. In Proceedings of the 2013 ACM international symposium on New ideas, new paradigms, and reflections on programming & software (Onward! 2013). ACM, New York, NY, USA, 187-204. DOI=http://dx.doi.org/10.1145/2509578.2509581 • Manuel Rigger, Matthias Grimmer, and Hanspeter Mössenböck. 2016. Sulong - execution of LLVM-based languages on the JVM: position paper. In Proceedings of the 11th Workshop on Implementation, Compilation, Optimization of Object-Oriented Languages, Programs and Systems (ICOOOLPS '16). ACM, New York, NY, USA, , Article 7 , 4 pages. DOI: https://doi.org/10.1145/3012408.3012416 • Manuel Rigger, Matthias Grimmer, Christian Wimmer, Thomas Würthinger, and Hanspeter Mössenböck. 2016. Bringing low-level languages to the JVM: efficient execution of LLVM IR on Truffle. In Proceedings of the 8th International Workshop on Virtual Machines and Intermediate Languages (VMIL 2016). ACM, New York, NY, USA, 6-15. DOI: https://doi.org/10.1145/2998415.2998416 • Manuel Rigger, Roland Schatz, René Mayrhofer, Matthias Grimmer, and Hanspeter Mössenböck. 2018. Sulong, and Thanks for All the Bugs: Finding Errors in C Programs by Abstracting from the Native Execution Model. In Proceedings of the Twenty-Third International Conference on Architectural Support for Programming Languages and Operating Systems (ASPLOS '18). ACM, New York, NY, USA, 377-391. DOI: https://doi.org/10.1145/3173162.3173174 85
 mrigger
 institutdelelevage
 eumesy
 pomcho555
 sishi
 anikisencyo
 corochann
 takasehideki
 kogoro
 resolutionfoundation
 ept
 rikkabotan7
 chikuwait
 hannesfritz
 addyosmani
 rkendrick25
 inesmontani
 mkilby
 katarinadahlin
 swwweet
 codingconduct
 mclloyd
 nonsquared
 ryanjones