Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Deep Learning at Scale

Deep Learning at Scale

Presented by Alex Kern (CTO and Cofounder at Pavlov) at Big Data Day LA 2016.

The advent of modern deep learning techniques has given organizations new tools to understand, query, and structure their data. However, maintaining complex pipelines, versioning models, and tracking accuracy regressions over time remain ongoing struggles of even the most advanced data engineering teams. This talk presents a simple architecture for deploying machine learning at scale and offer suggestions for how companies can get their feet wet with open source technologies they already deploy.

Avatar for Nikhil Srinivasan

Nikhil Srinivasan

July 09, 2016

Other Decks in Programming

Transcript

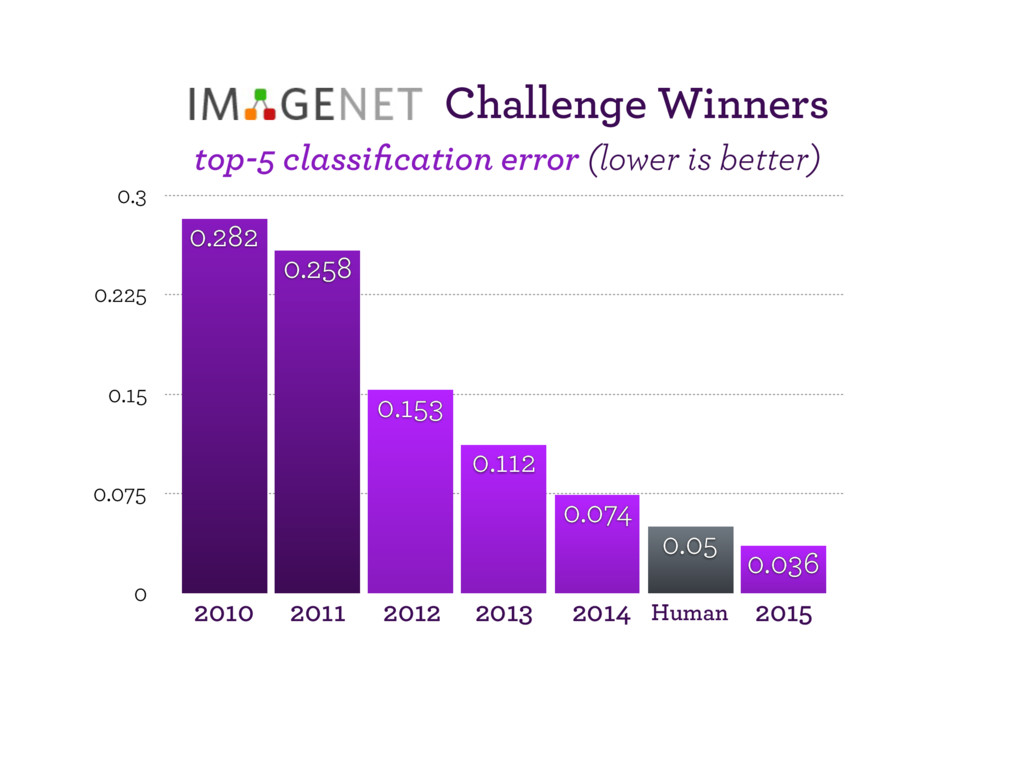
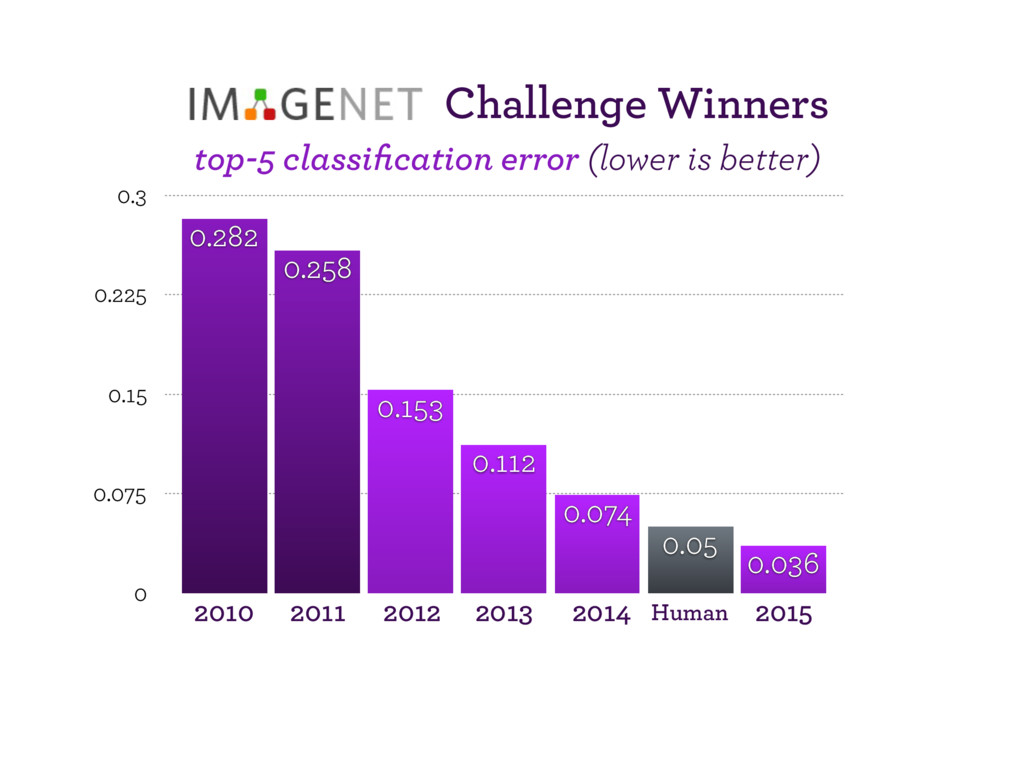
  1. Challenge Winners top-5 classification error (lower is better) 0 0.075

    0.15 0.225 0.3 0.036 0.05 0.074 0.112 0.153 0.258 0.282 2010 2011 2012 2014 2013 Human 2015
  2. 0 0.075 0.15 0.225 0.3 0.036 0.05 0.074 0.112 0.153

    0.258 0.282 2010 2011 2012 2014 2013 Human 2015 Challenge Winners top-5 classification error (lower is better)
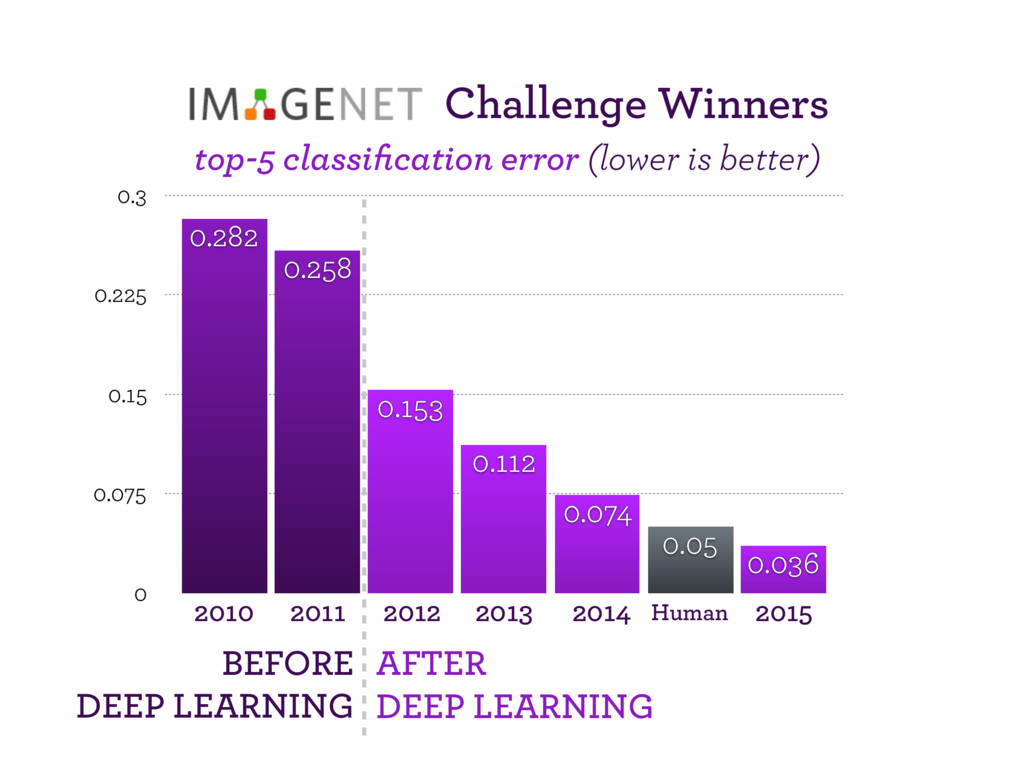
  3. 0 0.075 0.15 0.225 0.3 0.036 0.05 0.074 0.112 0.153

    0.258 0.282 2010 2011 2012 2014 2013 Human 2015 Challenge Winners top-5 classification error (lower is better) BEFORE DEEP LEARNING AFTER DEEP LEARNING
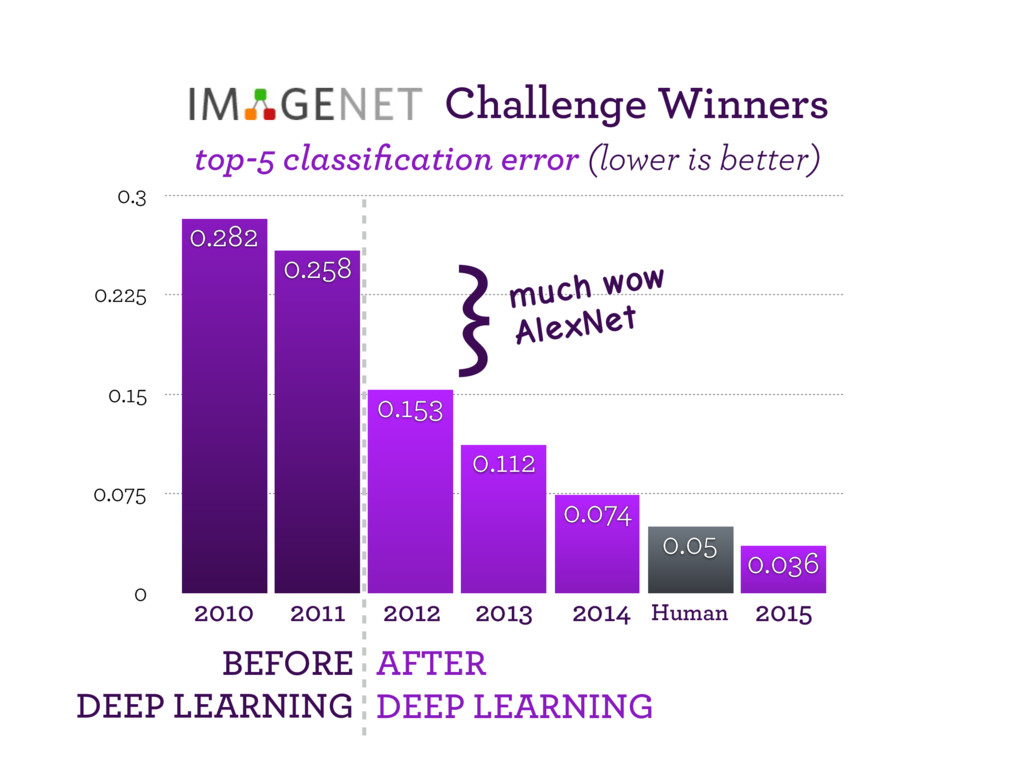
  4. 0 0.075 0.15 0.225 0.3 0.036 0.05 0.074 0.112 0.153

    0.258 0.282 2010 2011 2012 2014 2013 Human 2015 Challenge Winners top-5 classification error (lower is better) }much wow AlexNet BEFORE DEEP LEARNING AFTER DEEP LEARNING
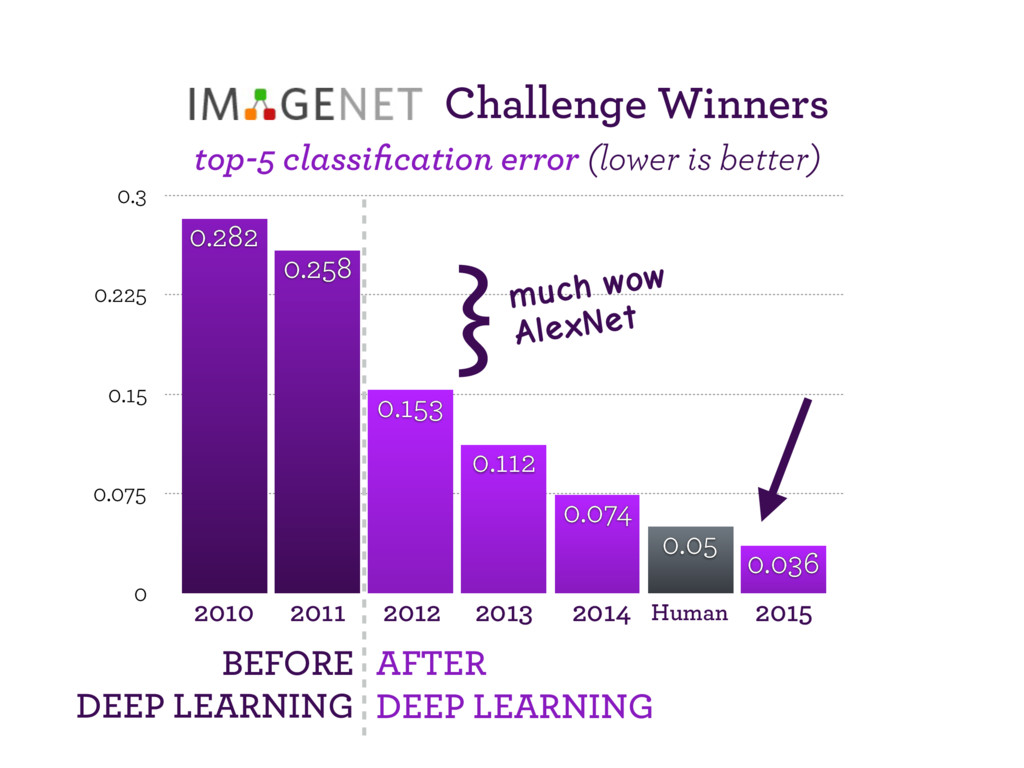
  5. 0 0.075 0.15 0.225 0.3 0.036 0.05 0.074 0.112 0.153

    0.258 0.282 2010 2011 2012 2014 2013 Human 2015 Challenge Winners top-5 classification error (lower is better) }much wow AlexNet BEFORE DEEP LEARNING AFTER DEEP LEARNING
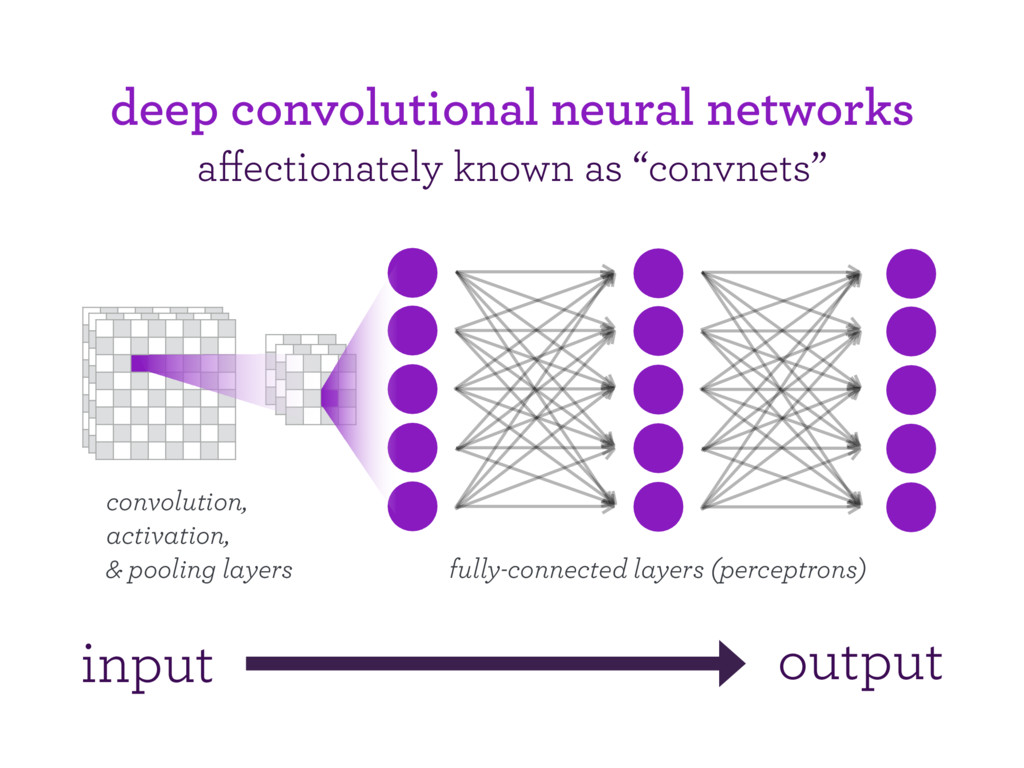
  6. deep convolutional neural networks affectionately known as “convnets” input output
    convolution, activation, & pooling layers fully-connected layers (perceptrons)
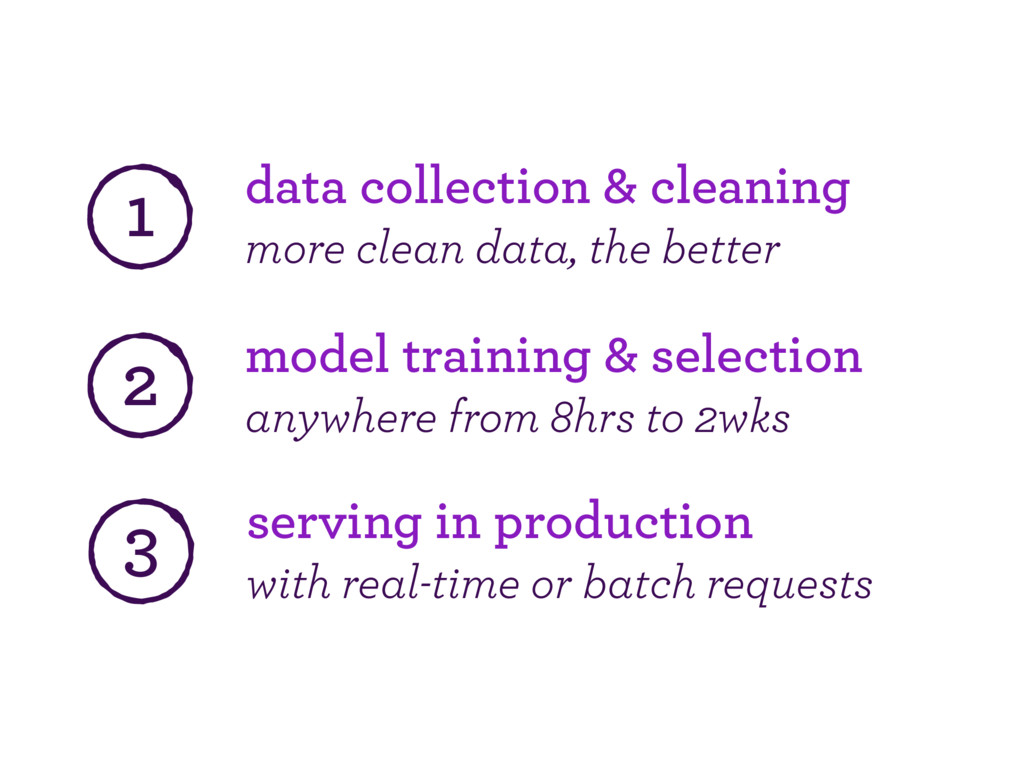
  7. data collection & cleaning more clean data, the better 1

    2 model training & selection anywhere from 8hrs to 2wks
  8. data collection & cleaning more clean data, the better 1

    2 model training & selection anywhere from 8hrs to 2wks 3 serving in production with real-time or batch requests
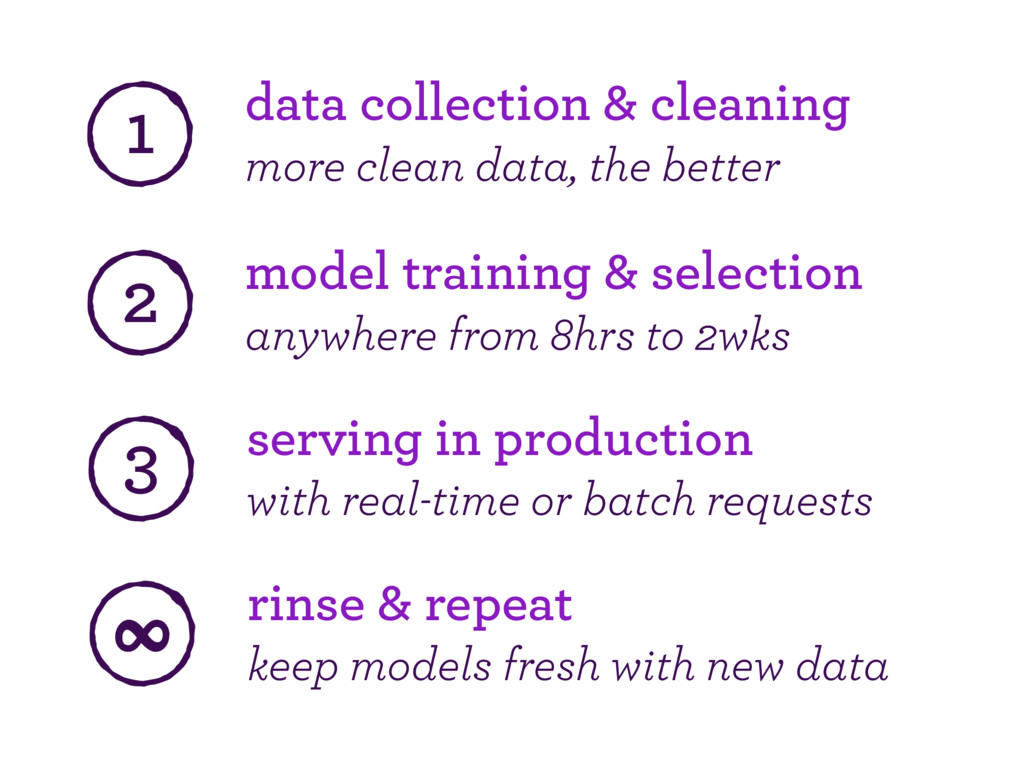
  9. data collection & cleaning more clean data, the better 1

    ∞ rinse & repeat keep models fresh with new data 2 model training & selection anywhere from 8hrs to 2wks 3 serving in production with real-time or batch requests
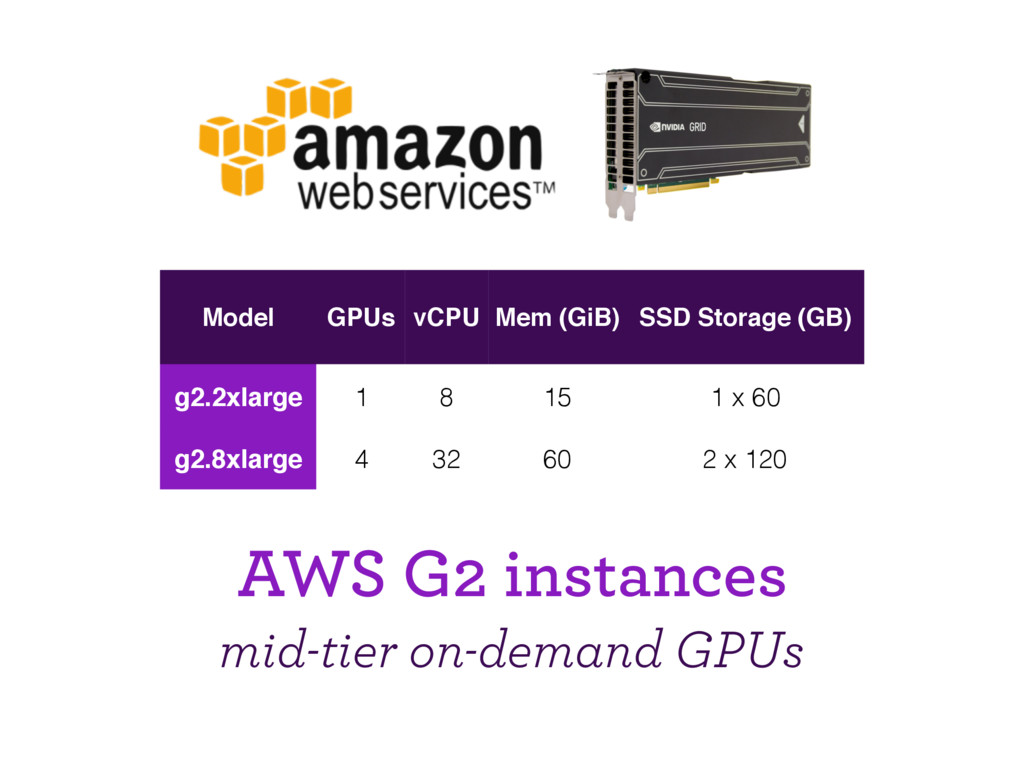
  10. AWS G2 instances mid-tier on-demand GPUs Model GPUs vCPU Mem

    (GiB) SSD Storage (GB) g2.2xlarge 1 8 15 1 x 60 g2.8xlarge 4 32 60 2 x 120
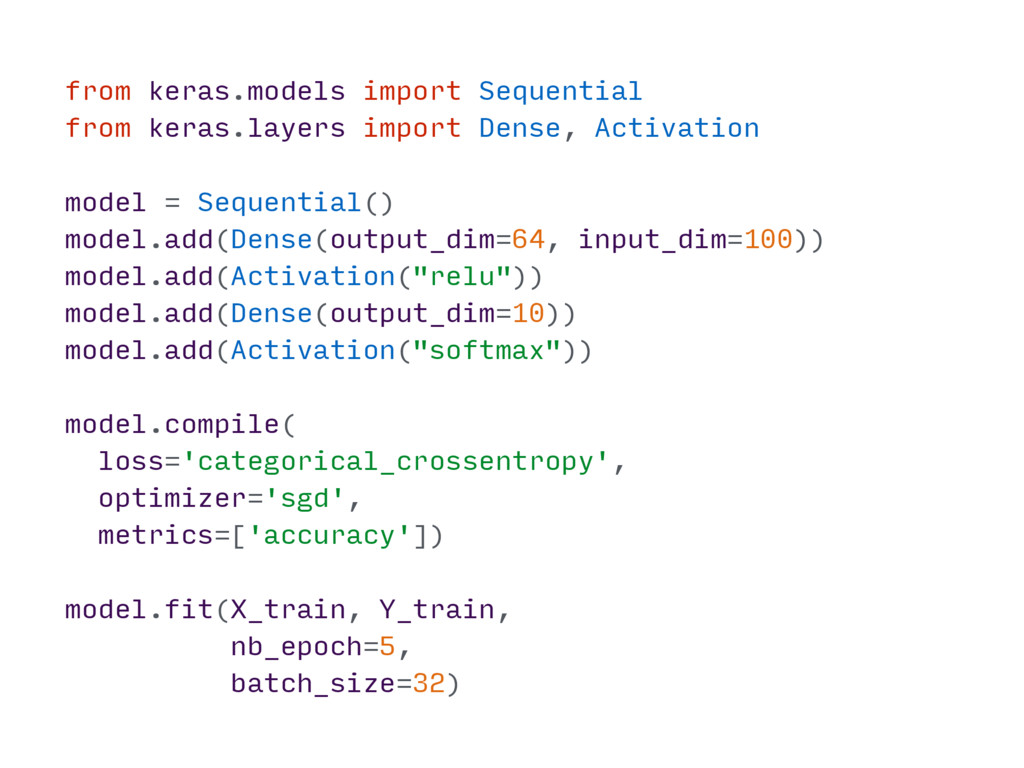
  11. from keras.models import Sequential from keras.layers import Dense, Activation model

    = Sequential() model.add(Dense(output_dim=64, input_dim=100)) model.add(Activation("relu")) model.add(Dense(output_dim=10)) model.add(Activation("softmax")) model.compile( loss='categorical_crossentropy', optimizer='sgd', metrics=['accuracy']) model.fit(X_train, Y_train, nb_epoch=5, batch_size=32)
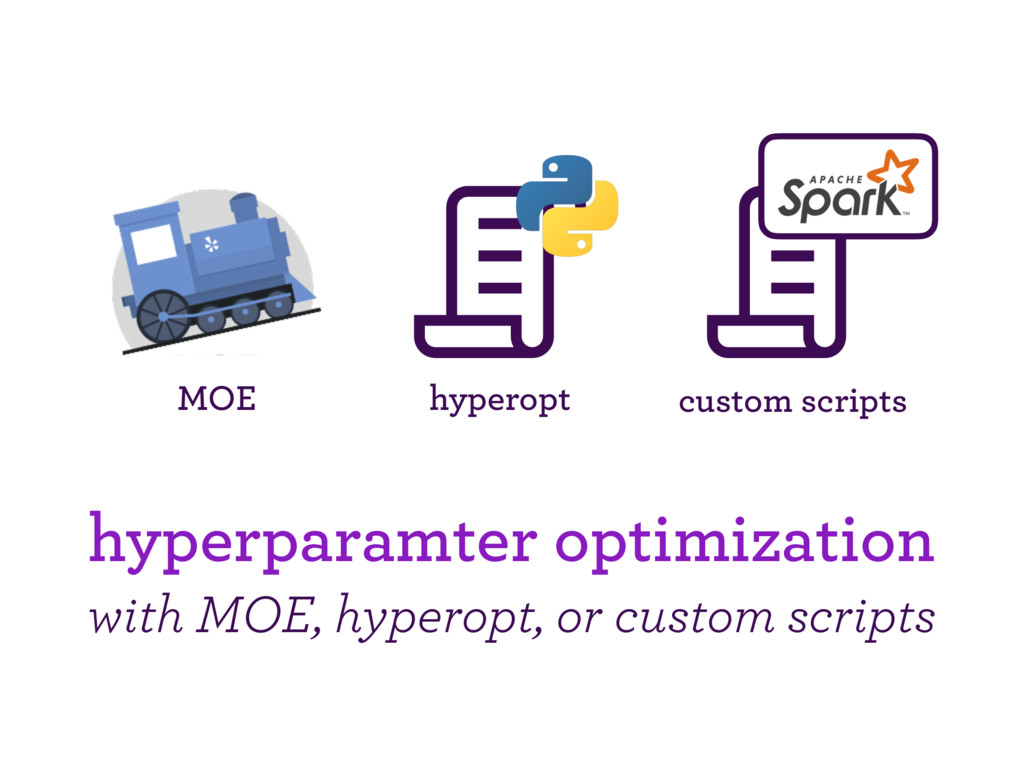
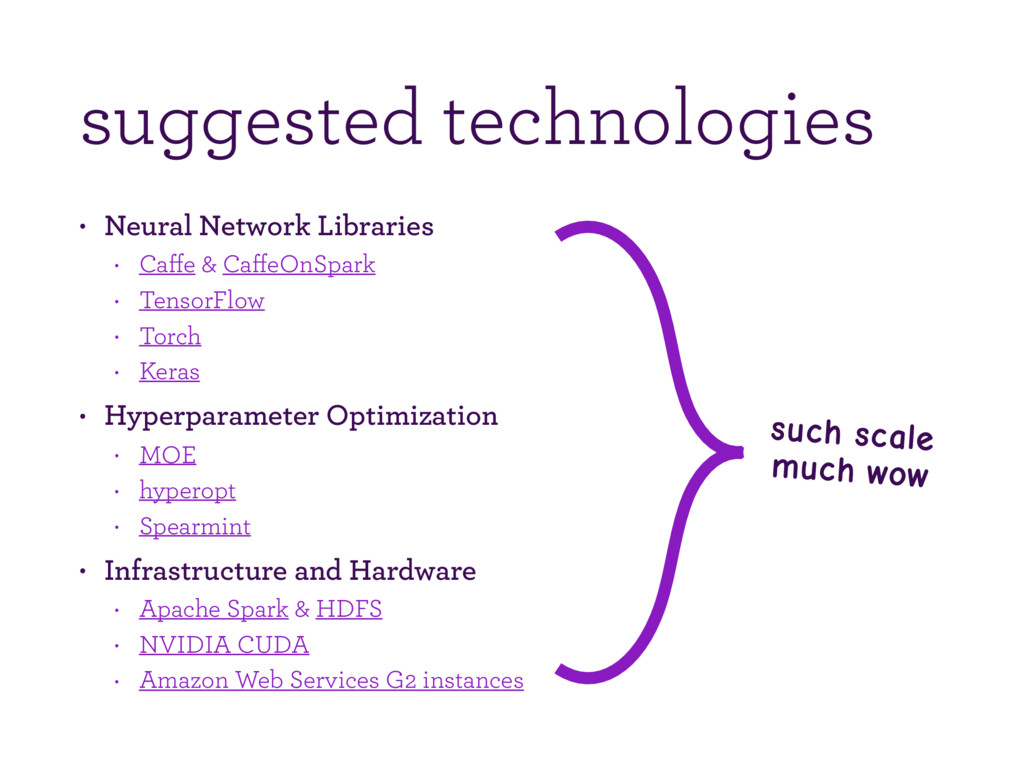
  12. suggested technologies • Neural Network Libraries • Caffe & CaffeOnSpark

    • TensorFlow • Torch • Keras • Hyperparameter Optimization • MOE • hyperopt • Spearmint • Infrastructure and Hardware • Apache Spark & HDFS • NVIDIA CUDA • Amazon Web Services G2 instances such scale much wow
  13. references • icons by John Caserta, Liau Jian Jie, Garrett

    Knoll, Luboš Volkov, Noe Araujo from the Noun Project • images from Andrej Karpathy • Alex Kern, co-founder & CTO of • we help you structure image & video w/ deep learning • @KernCanCode on Twitter • @kern on GitHub about me • deep learning is great for many kinds of media • you can scale a deep learning system on Spark & AWS • get started @ bit.ly/pavlovtensor & bit.ly/pavlov231 in summary