Upgrade to Pro — share decks privately, control downloads, hide ads and more …

PyConZA 2015: "Distributed pub-sub infrastructu...

Sponsored · Your Podcast. Everywhere. Effortlessly. Share. Educate. Inspire. Entertain. You do you. We'll handle the rest. →
Pycon ZA
October 01, 2015

PyConZA 2015: "Distributed pub-sub infrastructure with Apache Kafka" by Carl Scheffler

Apache Kafka is great for building a large scale distributed data bus. Even a small cluster will happily accept and store thousands of messages per second, and make them available to consumers with low latency.

Kafka was chosen as the solution to our publish-subscribe infrastructure at Takealot.com. It supports our event-driven systems on the website, in the warehouses and in the office, as well as our analytics and machine learning projects.

This talk will

* introduce the basic Kafka principles that make things work,
* outline how Kafka fits in with the rest of our architecture,
* cover some of the practicalities of building Python-based Kafka services,
* compare the two main Python libraries for Kafka, namely kafka-python (https://github.com/mumrah/kafka-python) and pykafka (https://github.com/Parsely/pykafka),
* demonstrate some practical applications at Takealot.com.

Join in if you are interested in scalable distributed infrastructure.

Pycon ZA

October 01, 2015

Transcript

15 slides
  1. Apache Kafka • Low latency, high throughput, publish–subscribe messaging •

    Developed by LinkedIn (still used in production) • Open-sourced in 2011 • First-class Apache project in 2012
  2. The Log • append only • sequential / strictly ordered

    • record what happened and “when” (index is primary, not timestamp) • (a queue is just a log that still has to happen) • provides • audit trail • replication (reproduce state) • notification (react to specific messages) • aggregation (produce new data streams / logs)
  3. Partitioned Logs • split up message stream into independent message

    streams • strict ordering within a partition • no ordering between partitions (but you can add timestamps if you’d like) • provides: • horizontal scaling
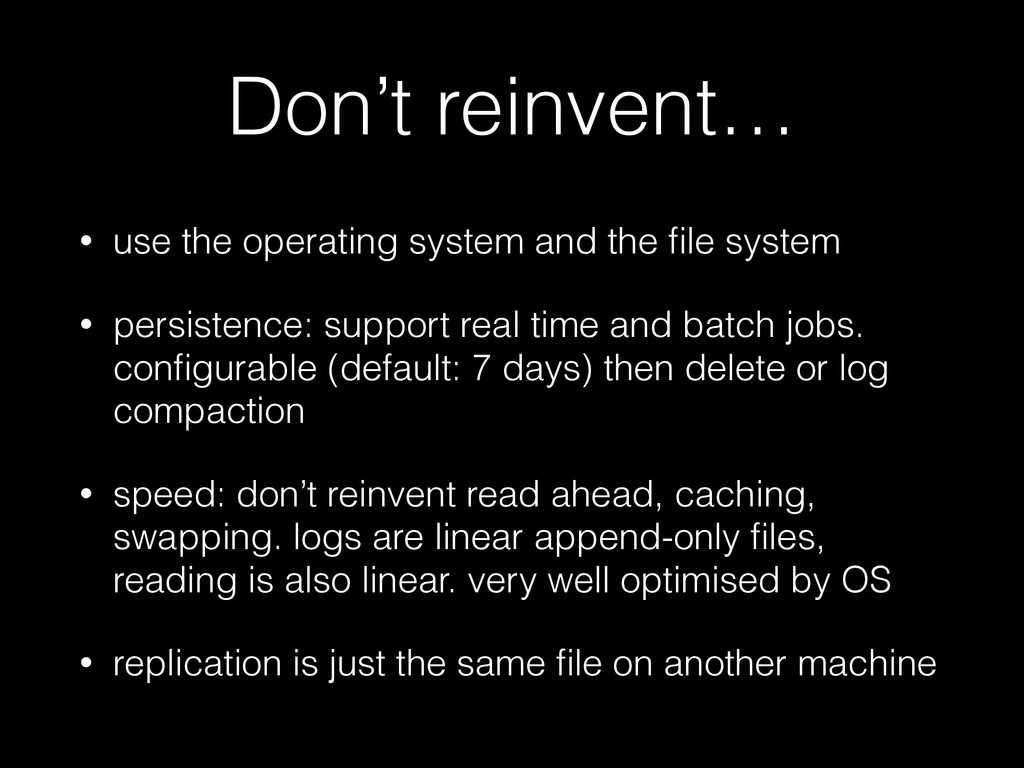
  4. Don’t reinvent… • use the operating system and the file

    system • persistence: support real time and batch jobs. configurable (default: 7 days) then delete or log compaction • speed: don’t reinvent read ahead, caching, swapping. logs are linear append-only files, reading is also linear. very well optimised by OS • replication is just the same file on another machine
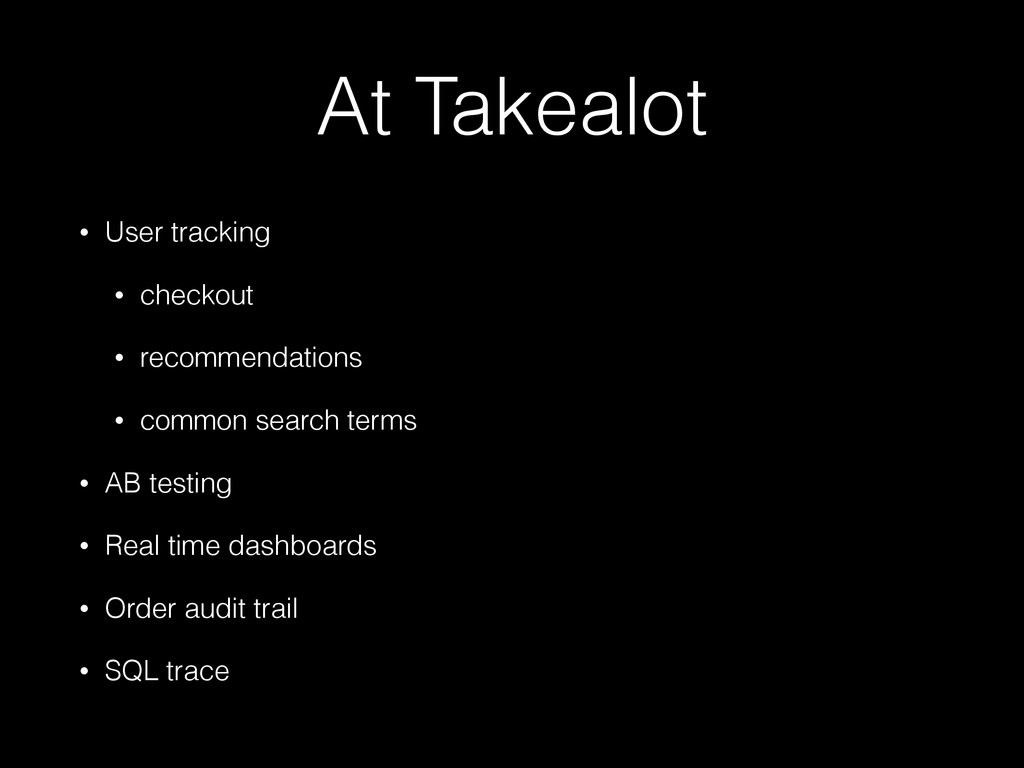
  5. At Takealot • User tracking • checkout • recommendations •

    common search terms • AB testing • Real time dashboards • Order audit trail • SQL trace
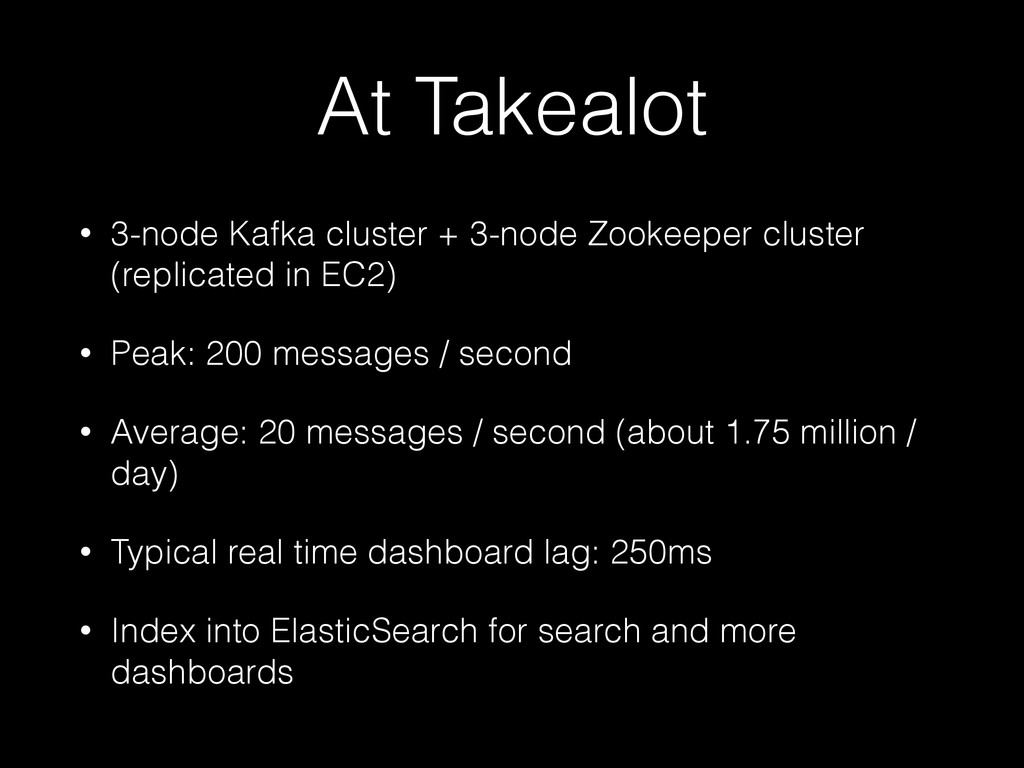
  6. At Takealot • 3-node Kafka cluster + 3-node Zookeeper cluster

    (replicated in EC2) • Peak: 200 messages / second • Average: 20 messages / second (about 1.75 million / day) • Typical real time dashboard lag: 250ms • Index into ElasticSearch for search and more dashboards
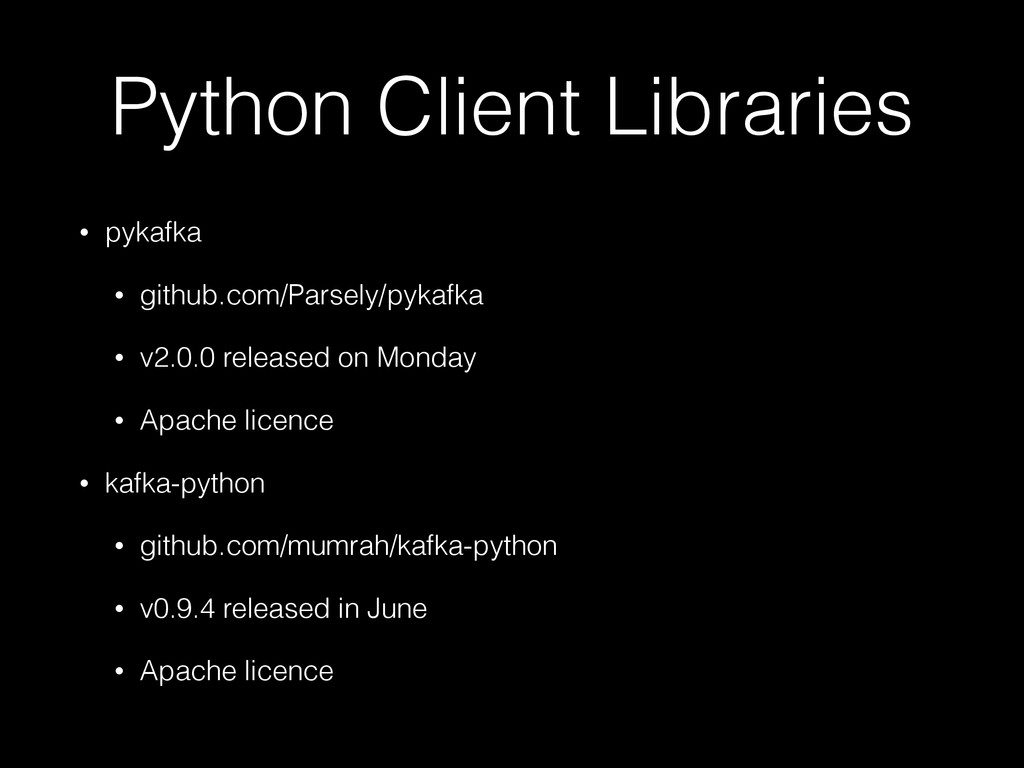
  7. Python Client Libraries • pykafka • github.com/Parsely/pykafka • v2.0.0 released

    on Monday • Apache licence • kafka-python • github.com/mumrah/kafka-python • v0.9.4 released in June • Apache licence
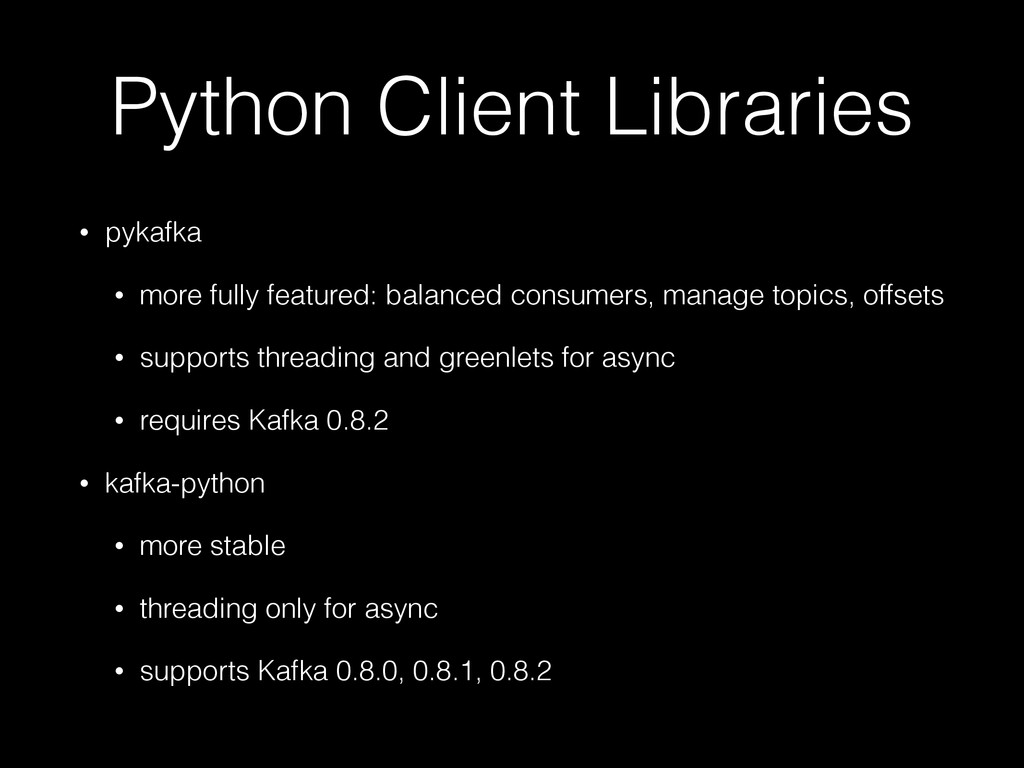
  8. Python Client Libraries • pykafka • more fully featured: balanced

    consumers, manage topics, offsets • supports threading and greenlets for async • requires Kafka 0.8.2 • kafka-python • more stable • threading only for async • supports Kafka 0.8.0, 0.8.1, 0.8.2
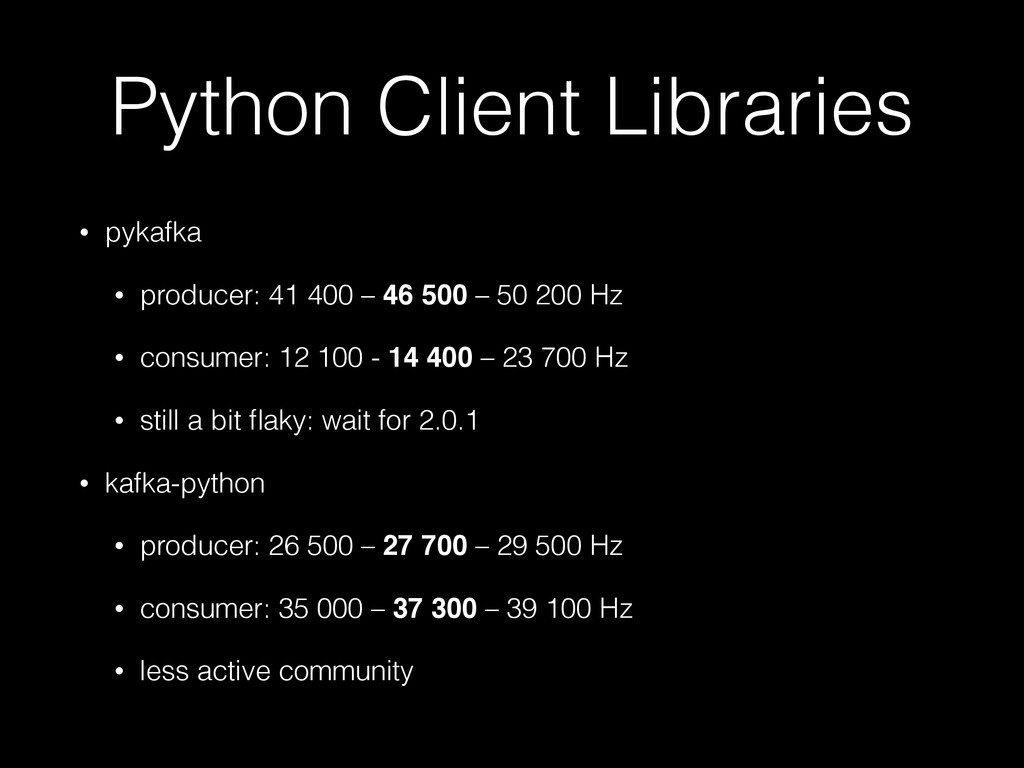
  9. Python Client Libraries • pykafka • producer: 41 400 –

    46 500 – 50 200 Hz • consumer: 12 100 - 14 400 – 23 700 Hz • still a bit flaky: wait for 2.0.1 • kafka-python • producer: 26 500 – 27 700 – 29 500 Hz • consumer: 35 000 – 37 300 – 39 100 Hz • less active community
  10. When you might not want to use Kafka • Persistence

    not needed
 maintaining shared global state (consumer and producer offsets) in Zookeeper is extra overhead • Don’t care so much about resilience
 resilience requires extra disk and network traffic • ØMQ is great for client–server or other common messaging patterns, including straightforward pub–sub
 zeromq.org
  11. Other things to think about • designing topics • metadata

    • message types • schema and validation • monitoring consumers and producers • hide all this from your application developers

More Decks by Pycon ZA

Other Decks in Programming