Share
Embed
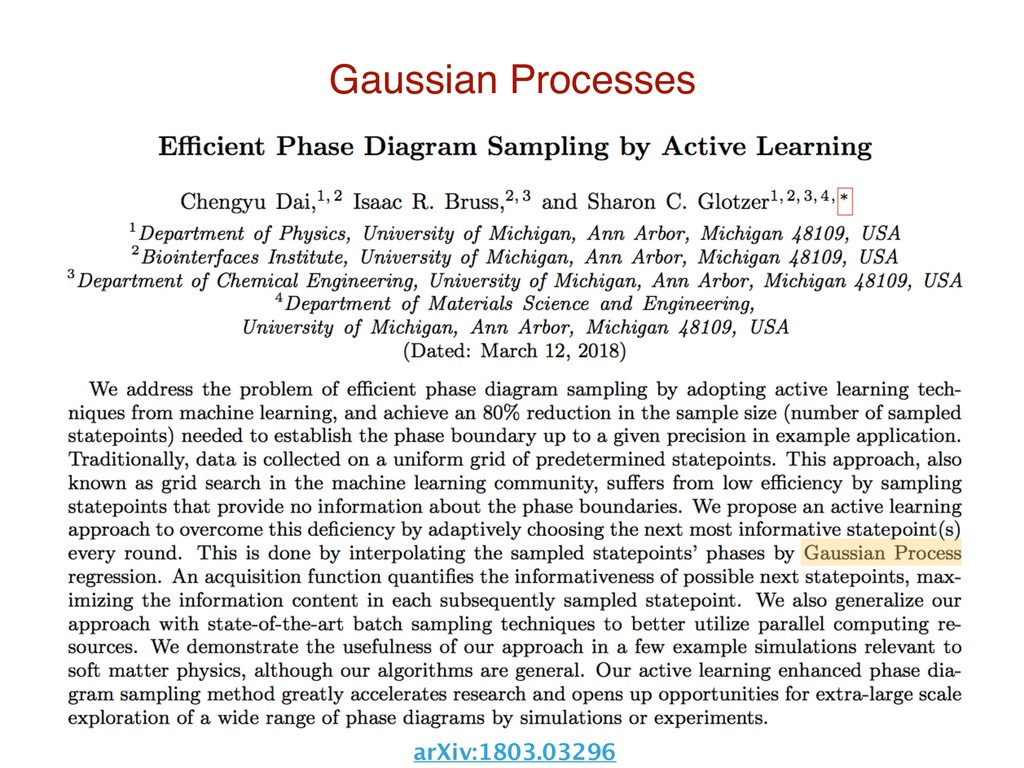
Gaussian Processes
My talk for the stat mech journal club in IMSc, Chennai.
Link to the code on slide 32 - https://github.com/rajeshrinet/compPhy/blob/master/notebooks/2018/GaussianProcesses.ipynb
Gaussian processes provide a principled and tractable approach to solving supervised and unsupervised machine learning problems
Rajesh Singh
March 12, 2018
Transcript
60 slides
-
Machine learning A computer program is said to learn from
experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E. — T. M. Mitchell -
Machine learning A computer program is said to learn from
experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E. — T. M. Mitchell select the best model|code it up|update with new data| learn from data -
Machine learning A computer program is said to learn from
experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E. — T. M. Mitchell select the best model|code it up|update with new data| learn from data Supervised learning infer from training data having input (x) & output (y) Unsupervised learning infer from training data having input (x) alone -
Machine learning A computer program is said to learn from
experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E. — T. M. Mitchell select the best model|code it up|update with new data| learn from data Supervised learning infer from training data having input (x) & output (y) Unsupervised learning infer from training data having input (x) alone Classification discrete output eg: SVM, GP Regression continuous output eg: SVR, GP -
Machine learning A computer program is said to learn from
experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E. — T. M. Mitchell select the best model|code it up|update with new data| learn from data Supervised learning infer from training data having input (x) & output (y) Unsupervised learning infer from training data having input (x) alone Classification discrete output eg: SVM, GP Regression continuous output eg: SVR, GP Clustering discover groups eg: k-means Dim reduction reduce variables eg: GP-LVM -
Bayes theorem betterexplained.com/articles/an-intuitive-and-short-explanation-of-bayes-theorem/ chances of a disease (D) if the
test (T) is positive P(D | T) =? Posterior Evidence Likelihood Prior P (✓|X) = P (X|✓) P (✓) P (X) . -
Bayes theorem betterexplained.com/articles/an-intuitive-and-short-explanation-of-bayes-theorem/ chances of a disease (D) if the
test (T) is positive P(D | T) =? P(T | ˜ D) = 0.096 P(D) = 0.01 P(T | D) = 0.8 knowns Posterior Evidence Likelihood Prior P (✓|X) = P (X|✓) P (✓) P (X) . -
Bayes theorem betterexplained.com/articles/an-intuitive-and-short-explanation-of-bayes-theorem/ chances of a disease (D) if the
test (T) is positive P(D | T) =? P(D | T) = P(T | D) P(D) P(T | D)P(D) + P(T | ˜ D)P( ˜ D) P(T | ˜ D) = 0.096 P(D) = 0.01 P(T | D) = 0.8 knowns Posterior Evidence Likelihood Prior P (✓|X) = P (X|✓) P (✓) P (X) . -
Bayes theorem betterexplained.com/articles/an-intuitive-and-short-explanation-of-bayes-theorem/ chances of a disease (D) if the
test (T) is positive P(D | T) =? P(D | T) = P(T | D) P(D) P(T | D)P(D) + P(T | ˜ D)P( ˜ D) Plug in the numbers to obtain 0.078 for the probability. P(T | ˜ D) = 0.096 P(D) = 0.01 P(T | D) = 0.8 knowns Posterior Evidence Likelihood Prior P (✓|X) = P (X|✓) P (✓) P (X) . -
Regression given noisy data - make predictions! parameters for this?
use a non-parametric approach: fit all possible functions! -
Gaussian Processes At the core of GP is the multivariate
Gaussian distribution http://www.gaussianprocess.org/gpml/ -
Gaussian Processes At the core of GP is the multivariate
Gaussian distribution ‣ Any n-points, (x1, …, xn), in a data set is a point sampled from n-variate Gaussian distribution ‣ GP defines prior over functions (GD), which is then used to compute posterior using training points http://www.gaussianprocess.org/gpml/ -
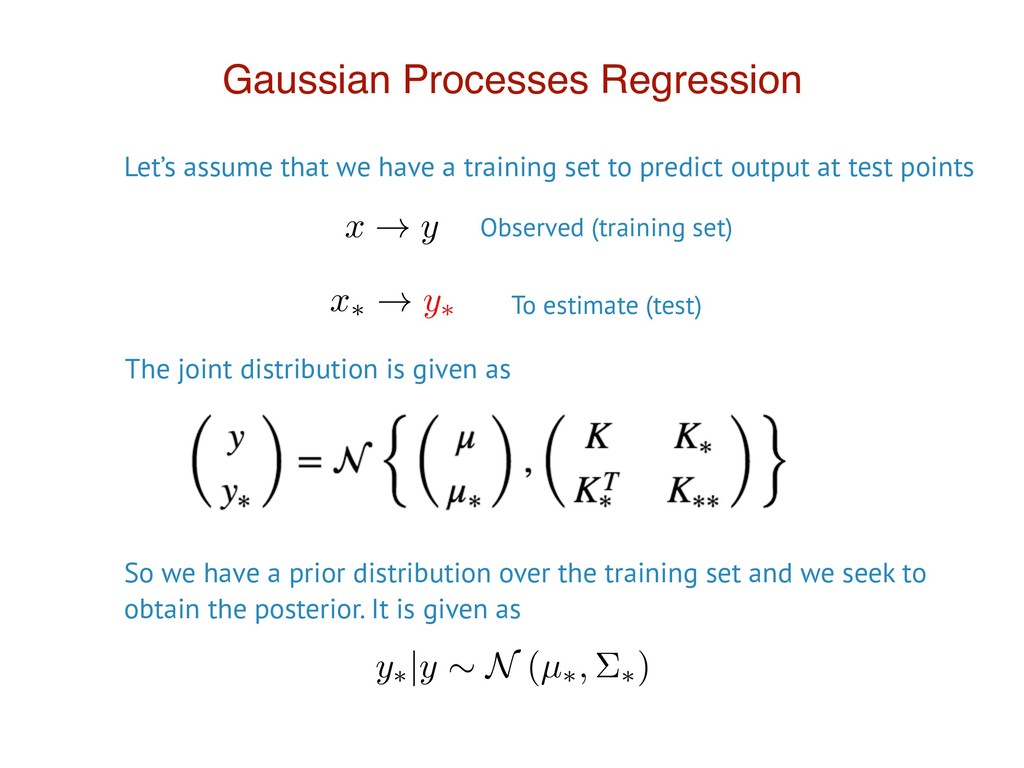
Gaussian Processes Regression Let’s assume that we have a training
set to predict output at test points Observed (training set) To estimate (test) x ! y x⇤ ! y⇤ -
Gaussian Processes Regression Let’s assume that we have a training
set to predict output at test points Observed (training set) To estimate (test) x ! y x⇤ ! y⇤ The joint distribution is given as -
Gaussian Processes Regression Let’s assume that we have a training
set to predict output at test points Observed (training set) To estimate (test) x ! y x⇤ ! y⇤ So we have a prior distribution over the training set and we seek to obtain the posterior. It is given as y⇤ |y ⇠ N (µ⇤, ⌃⇤) The joint distribution is given as -
For a univariate case, we know that x = µ
+ p N(0 , 1) Gaussian Processes Regression -
For a univariate case, we know that x = µ
+ p N(0 , 1) Gaussian Processes Regression Here L is the Cholesky factor of covariance matrix. Similarly, for the multivariate case, we have y⇤ = µ⇤ + LN(0, I), where LLT = ⌃⇤ -
For a univariate case, we know that x = µ
+ p N(0 , 1) Gaussian Processes Regression So the steps are summarized as specify a prior to fix functions to be considered for inferences compute covariance matrix using a specified the kernle K. Let’s have a look at the code now. Here L is the Cholesky factor of covariance matrix. Similarly, for the multivariate case, we have y⇤ = µ⇤ + LN(0, I), where LLT = ⌃⇤ -
Principal component analysis PCA gives orthogonal directions of maximum variance
⌃ij = 1 N X ( xni µi)( xnj µj) https://en.wikipedia.org/wiki/Principal_component_analysis -
Principal component analysis PCA gives orthogonal directions of maximum variance
⌃ij = 1 N X ( xni µi)( xnj µj) ⌃ = ✓ ⌃ xx ⌃ xy ⌃ yx ⌃ yy ◆ https://en.wikipedia.org/wiki/Principal_component_analysis -
Principal component analysis PCA gives orthogonal directions of maximum variance
⌃ij = 1 N X ( xni µi)( xnj µj) ⌃ = ✓ ⌃ xx ⌃ xy ⌃ yx ⌃ yy ◆ ⌃ = ✓ ⌃ xx 0 0 ⌃ yy ◆ https://en.wikipedia.org/wiki/Principal_component_analysis -
Principal component analysis PCA gives orthogonal directions of maximum variance
⌃ij = 1 N X ( xni µi)( xnj µj) ⌃ = ✓ ⌃ xx ⌃ xy ⌃ yx ⌃ yy ◆ ⌃ = ✓ ⌃ xx 0 0 ⌃ yy ◆ Find eigenvalues vk and eigenvectors k of ⌃ . variance of k-th direction https://en.wikipedia.org/wiki/Principal_component_analysis -
Principal component analysis PCA gives orthogonal directions of maximum variance
⌃ij = 1 N X ( xni µi)( xnj µj) ⌃ = ✓ ⌃ xx ⌃ xy ⌃ yx ⌃ yy ◆ ⌃ = ✓ ⌃ xx 0 0 ⌃ yy ◆ Find eigenvalues vk and eigenvectors k of ⌃ . variance of k-th direction Choose some of the eigenvectors based on the problem at hand to obtain a lower set of orthogonal directions. https://en.wikipedia.org/wiki/Principal_component_analysis -
Gaussian Process Latent Variable Model GPLVM, introduced by Lawrence (2004),
generalizes PCA in GP framework where latent input X are obtained from the data Y, when the mapping W is integrated out -
Gaussian Process Latent Variable Model GPLVM, introduced by Lawrence (2004),
generalizes PCA in GP framework where latent input X are obtained from the data Y, when the mapping W is integrated out Y = W X + ⌘ latent variable -
Gaussian Process Latent Variable Model GPLVM, introduced by Lawrence (2004),
generalizes PCA in GP framework where latent input X are obtained from the data Y, when the mapping W is integrated out Y = W X + ⌘ latent variable Define conditional (marginal) probability between the observed data-space Y to a latent data-space X -
Gaussian Process Latent Variable Model GPLVM, introduced by Lawrence (2004),
generalizes PCA in GP framework where latent input X are obtained from the data Y, when the mapping W is integrated out Y = W X + ⌘ latent variable Define conditional (marginal) probability between the observed data-space Y to a latent data-space X Extremize the corresponding log-likelihood to obtain X. -
Model selection Gaussian Processes in Machine Learning, C. E. Rasmussen.,
Advanced Lectures on Machine Learning region of interest -
Model selection Gaussian Processes in Machine Learning, C. E. Rasmussen.,
Advanced Lectures on Machine Learning region of interest P(Y |Mi) = Z P(Y |✓, Mi)P(✓|Mi)d✓. -
Model selection Gaussian Processes in Machine Learning, C. E. Rasmussen.,
Advanced Lectures on Machine Learning region of interest P(Y |Mi) = Z P(Y |✓, Mi)P(✓|Mi)d✓. peaked at most-probable parameter value, and thus, integral becomes -
Model selection Gaussian Processes in Machine Learning, C. E. Rasmussen.,
Advanced Lectures on Machine Learning region of interest P(Y |Mi) = Z P(Y |✓, Mi)P(✓|Mi)d✓. Evidence = Best fit likelihood x Ockham factor P(Y |Mi) ' P(Y |✓⇤, Mi) ⇥ P(✓⇤|Mi) ✓. peaked at most-probable parameter value, and thus, integral becomes -
Model selection Gaussian Processes in Machine Learning, C. E. Rasmussen.,
Advanced Lectures on Machine Learning ‣ Ockham razor: the simpler model is usually the true one! region of interest P(Y |Mi) = Z P(Y |✓, Mi)P(✓|Mi)d✓. Evidence = Best fit likelihood x Ockham factor P(Y |Mi) ' P(Y |✓⇤, Mi) ⇥ P(✓⇤|Mi) ✓. peaked at most-probable parameter value, and thus, integral becomes -
GP provides a systematic and tractable framework for various machine
learning problems Complete probabilistic predictions in GPs - confidence interval, etc. GP extendable to hierarchical formulation In GP covariance matrices are not sparse - O(N3) complexity for matrix inversion - approximate methods essential for large data-sets Summary -
GP provides a systematic and tractable framework for various machine
learning problems Complete probabilistic predictions in GPs - confidence interval, etc. GP extendable to hierarchical formulation In GP covariance matrices are not sparse - O(N3) complexity for matrix inversion - approximate methods essential for large data-sets Summary -
GP provides a systematic and tractable framework for various machine
learning problems Complete probabilistic predictions in GPs - confidence interval, etc. GP extendable to hierarchical formulation In GP covariance matrices are not sparse - O(N3) complexity for matrix inversion - approximate methods essential for large data-sets Summary C. E. Rasmussen and C. K. I. Williams. Gaussian processes for machine learning, MIT press Cambridge, 2006. K. P. Murphy. Machine Learning: A Probabilistic Perspective MIT press Cambridge, 2012. N. D. Lawrence. Gaussian process latent variable models for visualisation of high dimensional data, 2004. D. J. C. MacKay. Information theory, inference and learning algorithms. Cambridge University Press, 2003. http://www.gaussianprocess.org/ -
GP provides a systematic and tractable framework for various machine
learning problems Complete probabilistic predictions in GPs - confidence interval, etc. GP extendable to hierarchical formulation In GP covariance matrices are not sparse - O(N3) complexity for matrix inversion - approximate methods essential for large data-sets Summary Thank You ! C. E. Rasmussen and C. K. I. Williams. Gaussian processes for machine learning, MIT press Cambridge, 2006. K. P. Murphy. Machine Learning: A Probabilistic Perspective MIT press Cambridge, 2012. N. D. Lawrence. Gaussian process latent variable models for visualisation of high dimensional data, 2004. D. J. C. MacKay. Information theory, inference and learning algorithms. Cambridge University Press, 2003. http://www.gaussianprocess.org/ -
Support Vector Machines SVM is classifier which divides the data
by a hyperplane using labeled training datasets (supervised learning) -
Support Vector Machines SVM is classifier which divides the data
by a hyperplane using labeled training datasets (supervised learning) -
Support Vector Machines SVM is classifier which divides the data
by a hyperplane using labeled training datasets (supervised learning) What if the data is not so neat? -
Support Vector Machines SVM is classifier which divides the data
by a hyperplane using labeled training datasets (supervised learning) Transform the data to higher dimensions! What if the data is not so neat?