Share
Embed
Lessons from using Spark to process large volumes of data
Reema
July 16, 2019
Transcript
36 slides
-
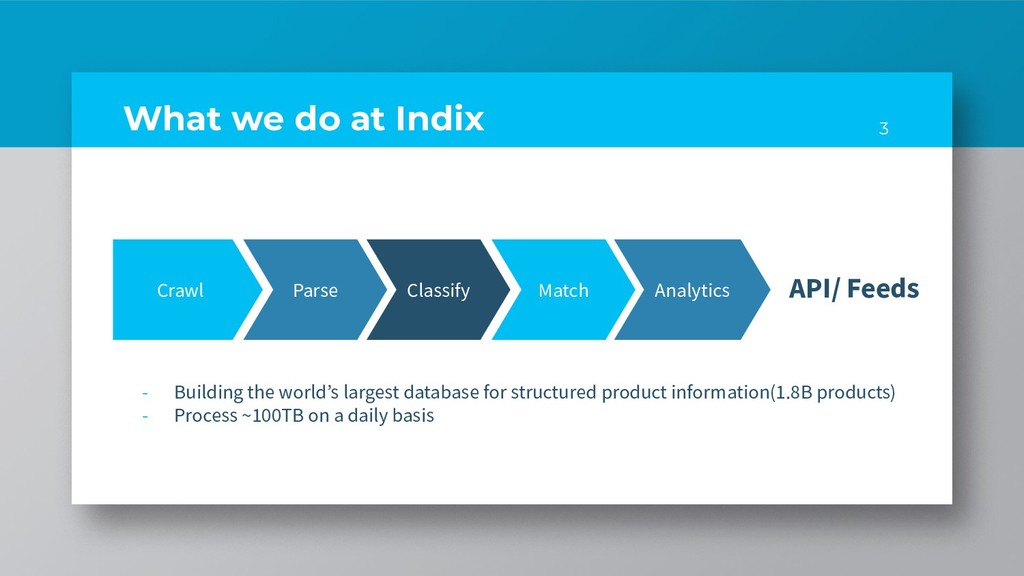
What we do at Indix Crawl Parse Classify 3 Match
Analytics API/ Feeds - Building the world’s largest database for structured product information(1.8B products) - Process ~100TB on a daily basis -
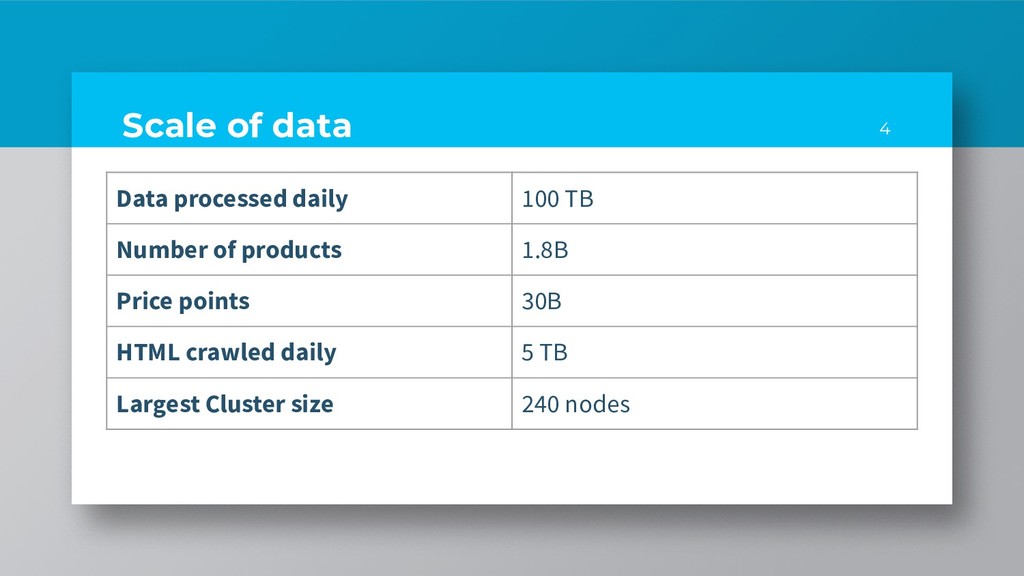
4 Data processed daily 100 TB Number of products 1.8B
Price points 30B HTML crawled daily 5 TB Largest Cluster size 240 nodes Scale of data -
• Alternate to Hadoop’s MapReduce • In memory processing engine
- 100x faster • SQL, MLlib, GraphX • Less disk I/O • Lazy evaluation of tasks - optimises data flow • In-memory caching - when multiple operations/jobs access the same dataset 7 Big Data Processing Engines -
- Data pipeline jobs - Data analysis - ML -
Built an internal eggression tool on top of Spark 8 Where do we use Spark? -
» Started with writing some custom jobs for customers -
feed processing » Early days - (Spark 1.3, 1.4) » Only RDDs were available as part of the Spark API 10 Adhoc jobs -
» Application running out of memory » No space left
on device » Tasks taking too long to run » Network timeouts » Version incompatibilities 11 Pitfalls we encountered -
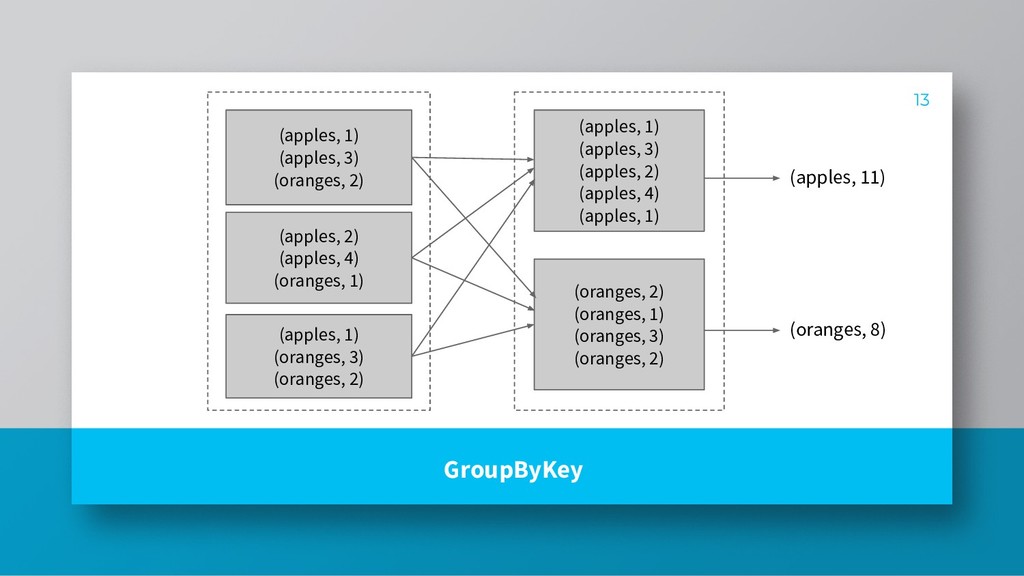
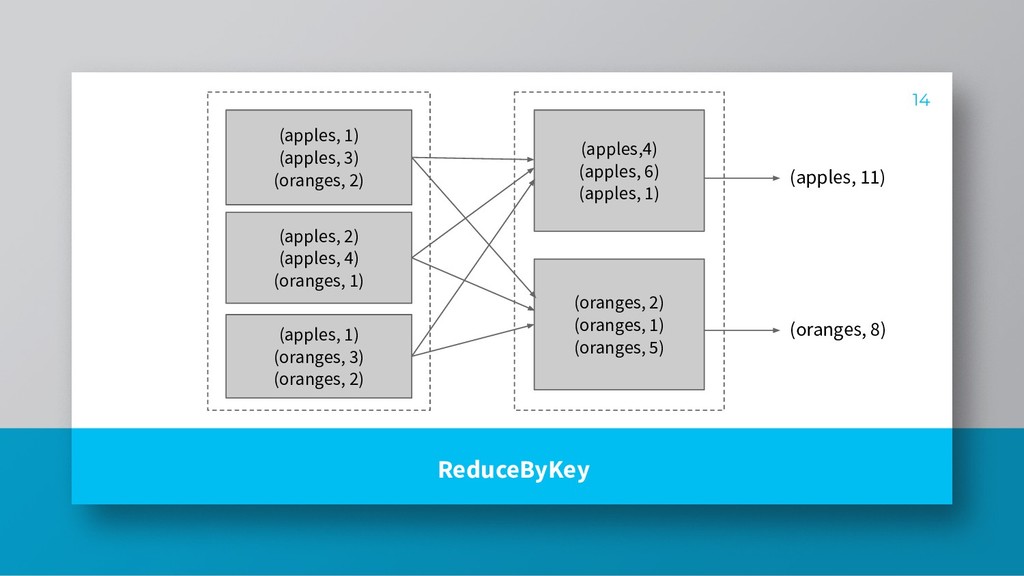
» Using groupByKey instead of reduceByKey - esp. computing stats
» Realized there was too much of shuffle » Would be more beneficial to do map side combines 12 Not using the right transformations -
GroupByKey 13 (apples, 1) (apples, 3) (oranges, 2) (apples, 2)
(apples, 4) (oranges, 1) (apples, 1) (oranges, 3) (oranges, 2) (apples, 1) (apples, 3) (apples, 2) (apples, 4) (apples, 1) (oranges, 2) (oranges, 1) (oranges, 3) (oranges, 2) (apples, 11) (oranges, 8) -
ReduceByKey 14 (apples, 1) (apples, 3) (oranges, 2) (apples, 2)
(apples, 4) (oranges, 1) (apples, 1) (oranges, 3) (oranges, 2) (apples,4) (apples, 6) (apples, 1) (oranges, 2) (oranges, 1) (oranges, 5) (apples, 11) (oranges, 8) -
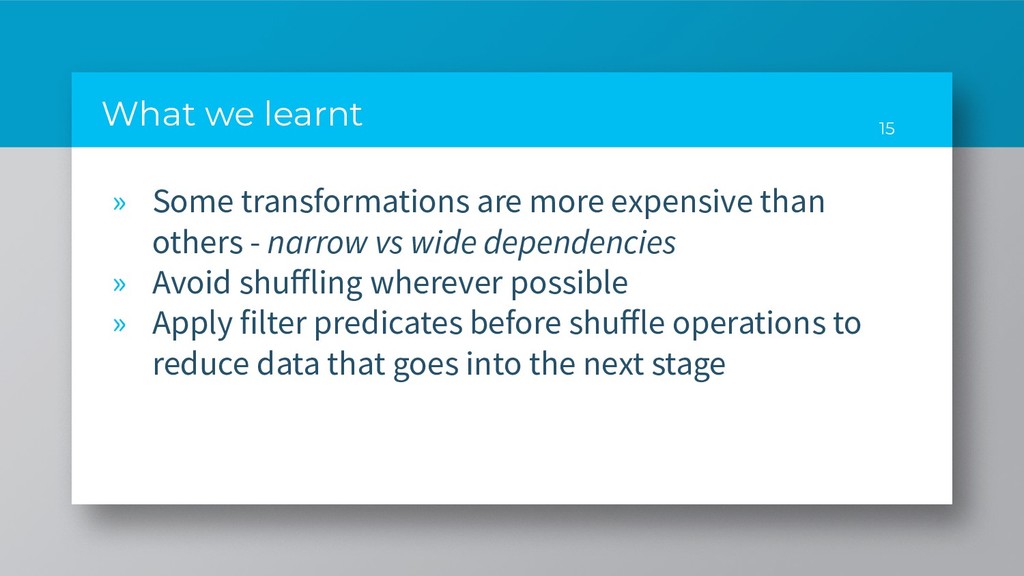
» Some transformations are more expensive than others - narrow
vs wide dependencies » Avoid shuffling wherever possible » Apply filter predicates before shuffle operations to reduce data that goes into the next stage 15 What we learnt -
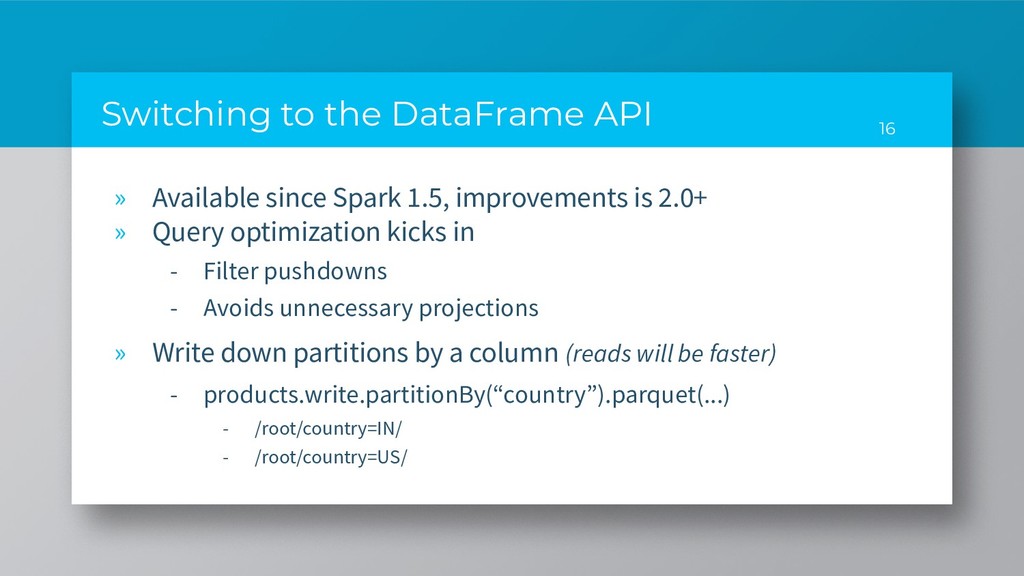
» Available since Spark 1.5, improvements is 2.0+ » Query
optimization kicks in - Filter pushdowns - Avoids unnecessary projections » Write down partitions by a column (reads will be faster) - products.write.partitionBy(“country”).parquet(...) - /root/country=IN/ - /root/country=US/ 16 Switching to the DataFrame API -
» Columnar data storage » 75% data compression on an
average » Push down filters(1.6 onwards) to reduce disk I/O - Filter pushdowns to access only required columns » Use DirectParquetOutputCommitter - Avoids expensive renames 17 Using Parquet as File Format -
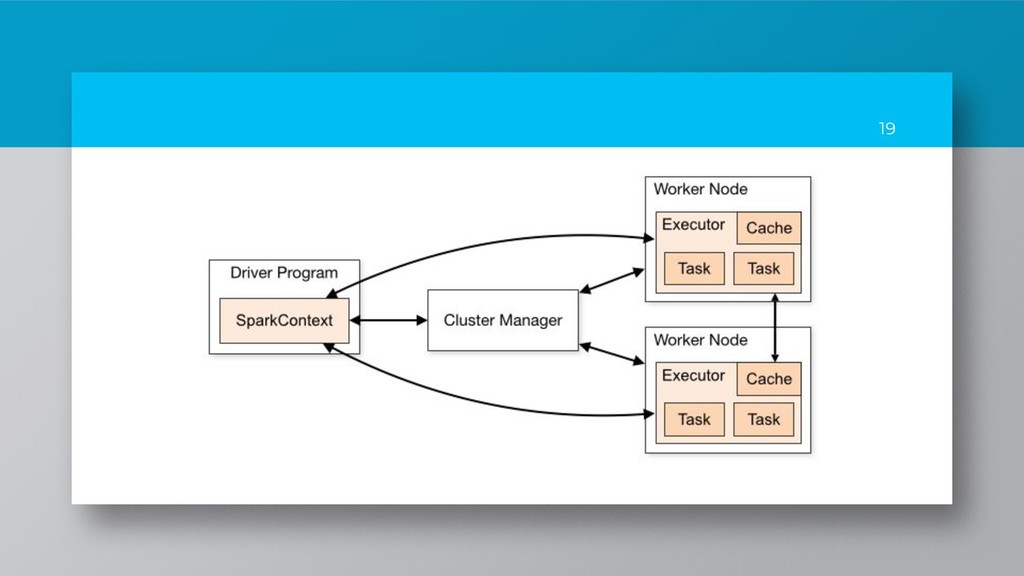
» Driver vs Executor » Identifying the root cause -
Job params - Code change 18 Application running out of memory -
Executor runs out of memory Error messages to look out
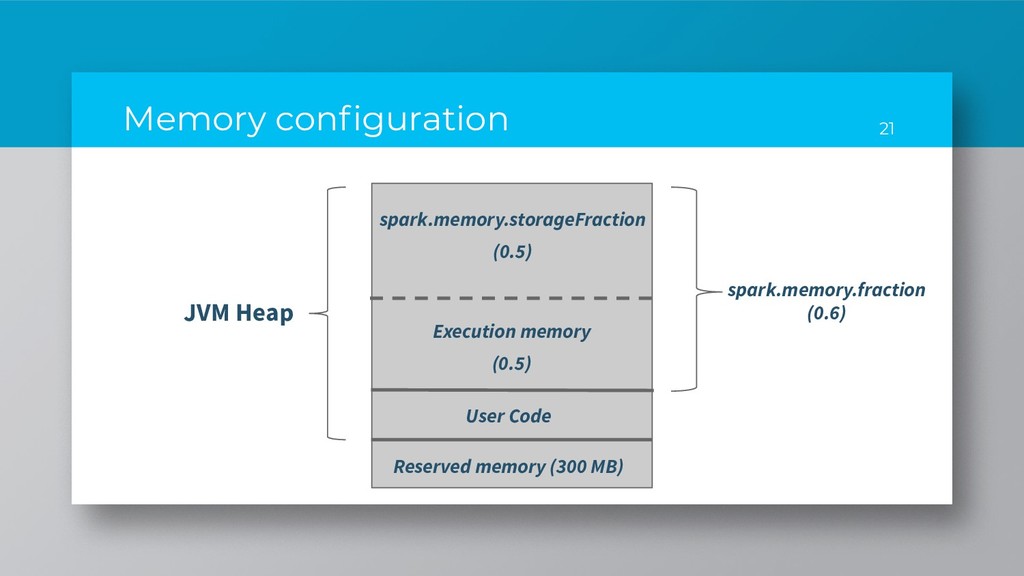
for: java.lang.OutOfMemoryError: Java heap space java.lang.OutOfMemoryError: GC overhead limit exceeded org.apache.spark.shuffle.FetchFailedException: GC overhead limit exceeded 20 Job config that you can tweak: - executor memory - executor memory overhead - spark.memory.fraction -
21 JVM Heap spark.memory.storageFraction (0.5) Execution memory (0.5) spark.memory.fraction (0.6)
User Code Reserved memory (300 MB) Memory configuration -
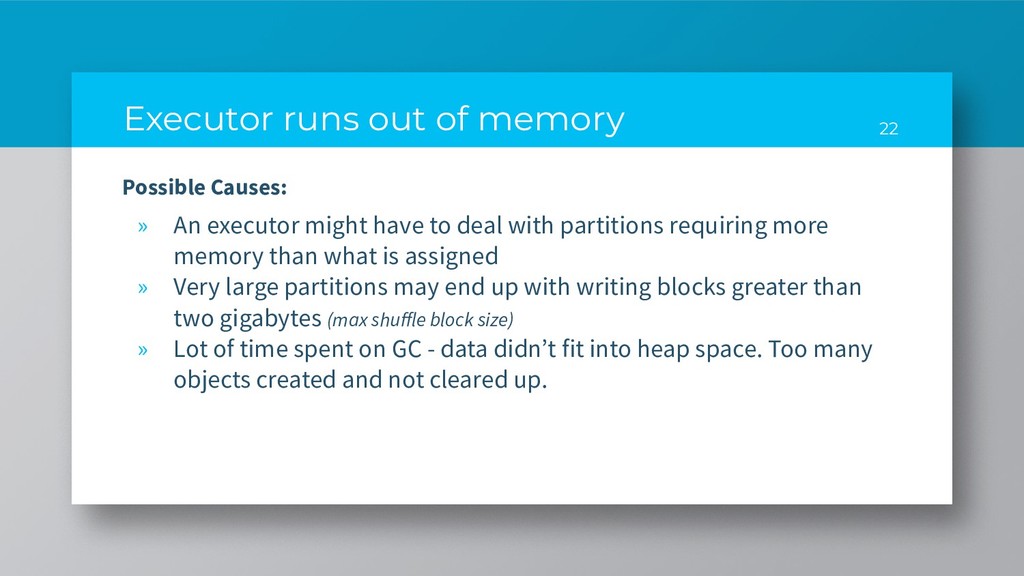
Executor runs out of memory Possible Causes: » An executor
might have to deal with partitions requiring more memory than what is assigned » Very large partitions may end up with writing blocks greater than two gigabytes (max shuffle block size) » Lot of time spent on GC - data didn’t fit into heap space. Too many objects created and not cleared up. 22 -
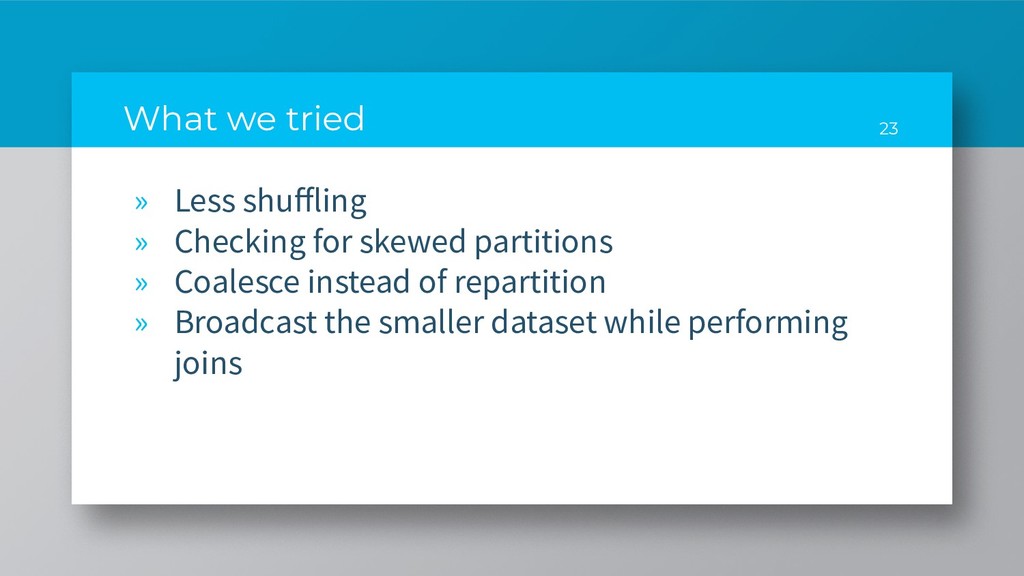
» Less shuffling » Checking for skewed partitions » Coalesce
instead of repartition » Broadcast the smaller dataset while performing joins 23 What we tried -
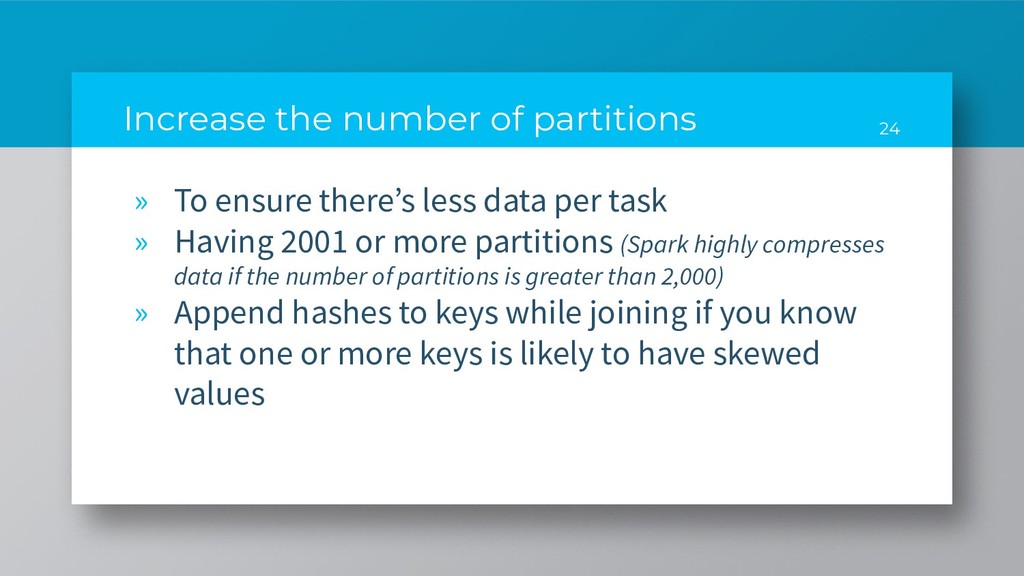
» To ensure there’s less data per task » Having
2001 or more partitions (Spark highly compresses data if the number of partitions is greater than 2,000) » Append hashes to keys while joining if you know that one or more keys is likely to have skewed values 24 Increase the number of partitions -
» Allows for fewer shuffles across the network » Application
will run faster since shuffles happen within a JVM (across processes) » Data Locality 25 Run with more cores per executor -
» Choose one amongst the various GC policies (CMS, ParallelOld
GC,G1GC) that is more suitable for your application. » G1GC is more preferable - Higher throughput and lower latency » Take a heap dump to check for large number of temporary objects created. 26 Choose a suitable GC -
Driver runs out of memory Error messages to look out
for: java.lang.OutOfMemoryError: Java heap space java.lang.OutOfMemoryError: GC overhead limit exceeded 27 Job config that you can tweak: - driver memory - driver memory overhead -
Driver runs out of memory Possible Causes: » Actions that
bring in all the data to the driver - Operations like collect() are unsafe when the driver cannot house all the data in memory » Too many partitions - Large number of map status objects returned by the executors 28 -
» Avoid invoking unsafe operations on the dataset » Preferable
to let the executors write down the output of intermediate files instead of collecting all data to the driver » Do not have too many partitions - lesser map status objects 29 Solutions -
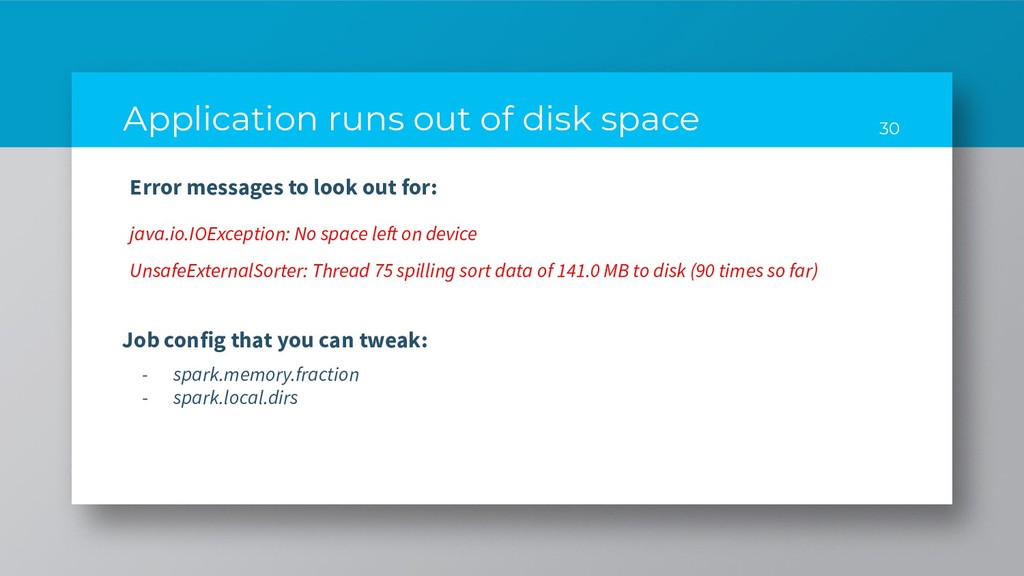
Application runs out of disk space Error messages to look
out for: java.io.IOException: No space left on device UnsafeExternalSorter: Thread 75 spilling sort data of 141.0 MB to disk (90 times so far) 30 Job config that you can tweak: - spark.memory.fraction - spark.local.dirs -
Application runs out of disk space Possible Causes: » Storage
data is continuously evicted to disk » Shuffled data is too large » Cluster size not sufficient for the data being processed 31 -
Solutions » Ensure that the spark.memory.fraction isn’t too low »
Lesser shuffles » Less number of partitions - compression » Add more nodes to the cluster » Mount more disks and specify them in spark.local.dirs 32 -
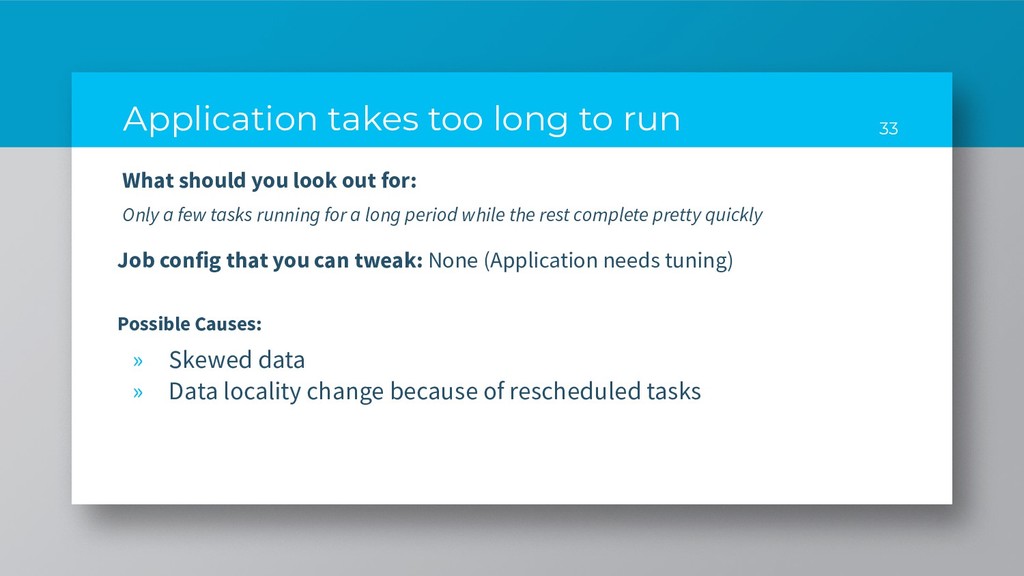
Application takes too long to run What should you look
out for: Only a few tasks running for a long period while the rest complete pretty quickly 33 Job config that you can tweak: None (Application needs tuning) Possible Causes: » Skewed data » Data locality change because of rescheduled tasks -
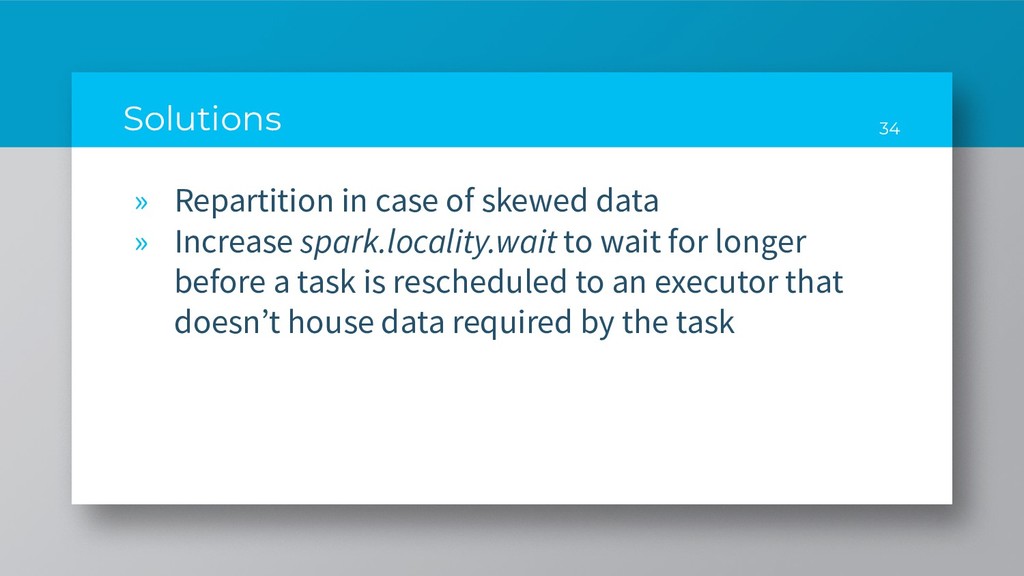
» Repartition in case of skewed data » Increase spark.locality.wait
to wait for longer before a task is rescheduled to an executor that doesn’t house data required by the task 34 Solutions -
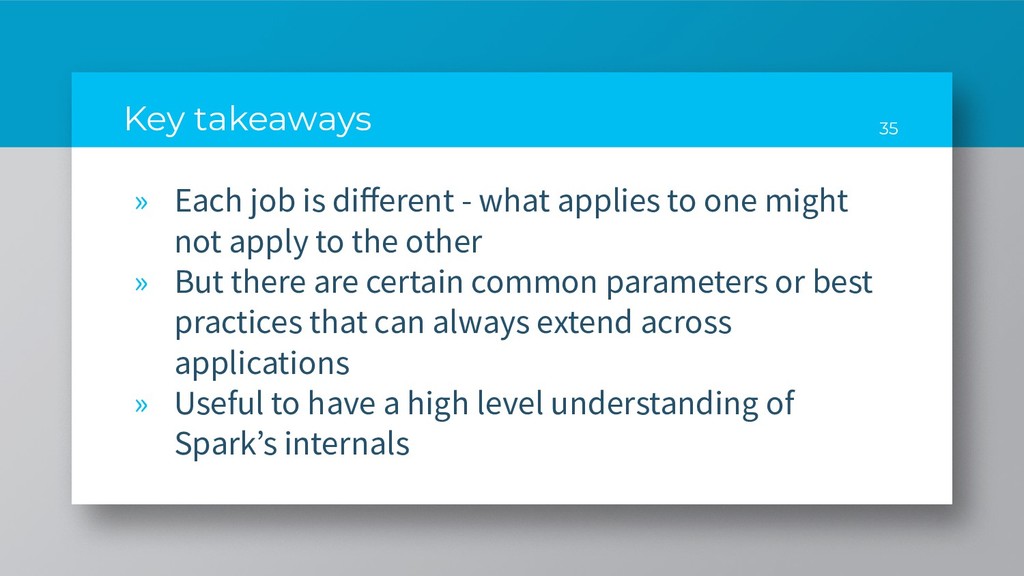
» Each job is different - what applies to one
might not apply to the other » But there are certain common parameters or best practices that can always extend across applications » Useful to have a high level understanding of Spark’s internals 35 Key takeaways