Share
Embed
Spark Workshop
Reema
July 16, 2019
Transcript
22 slides
-
Topics that will be covered - Scala introduction - Overview
of Spark - Spark Framework - Spark Concepts - Hands on Exercises -
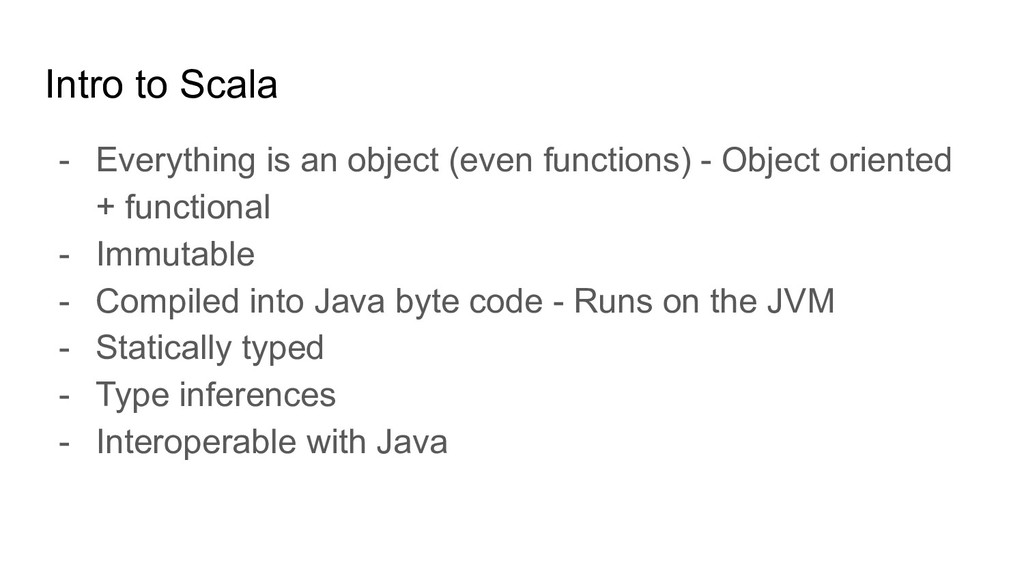
Intro to Scala - Everything is an object (even functions)
- Object oriented + functional - Immutable - Compiled into Java byte code - Runs on the JVM - Statically typed - Type inferences - Interoperable with Java -
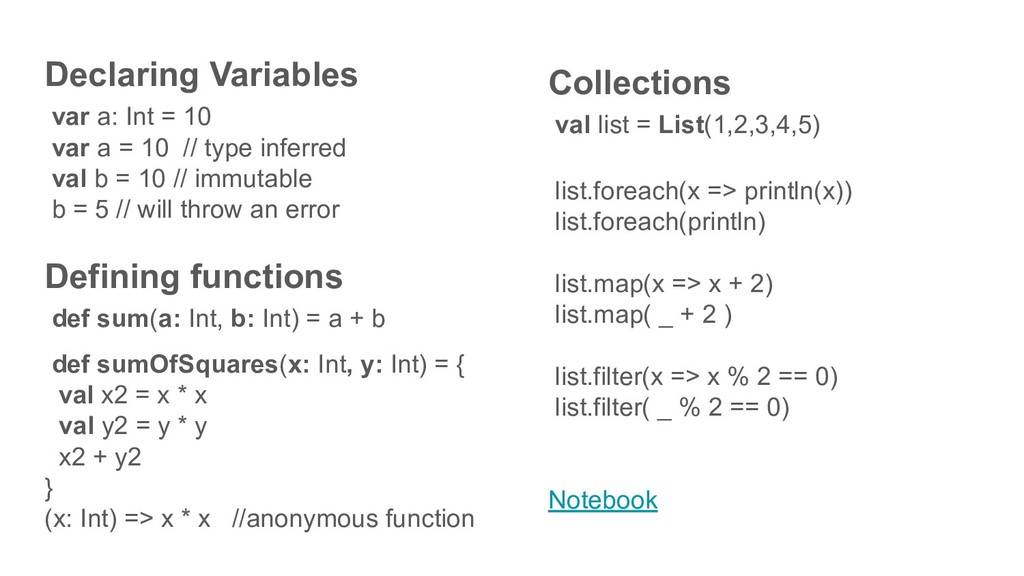
Declaring Variables var a: Int = 10 var a =
10 // type inferred val b = 10 // immutable b = 5 // will throw an error Defining functions def sum(a: Int, b: Int) = a + b def sumOfSquares(x: Int, y: Int) = { val x2 = x * x val y2 = y * y x2 + y2 } (x: Int) => x * x //anonymous function Collections val list = List(1,2,3,4,5) list.foreach(x => println(x)) list.foreach(println) list.map(x => x + 2) list.map( _ + 2 ) list.filter(x => x % 2 == 0) list.filter( _ % 2 == 0) Notebook -
Spark Scala API - More performant than the Python API
- Easier to use than the Java API - Spark is written in Scala - Most of the Spark functions have identical Scala equivalents -
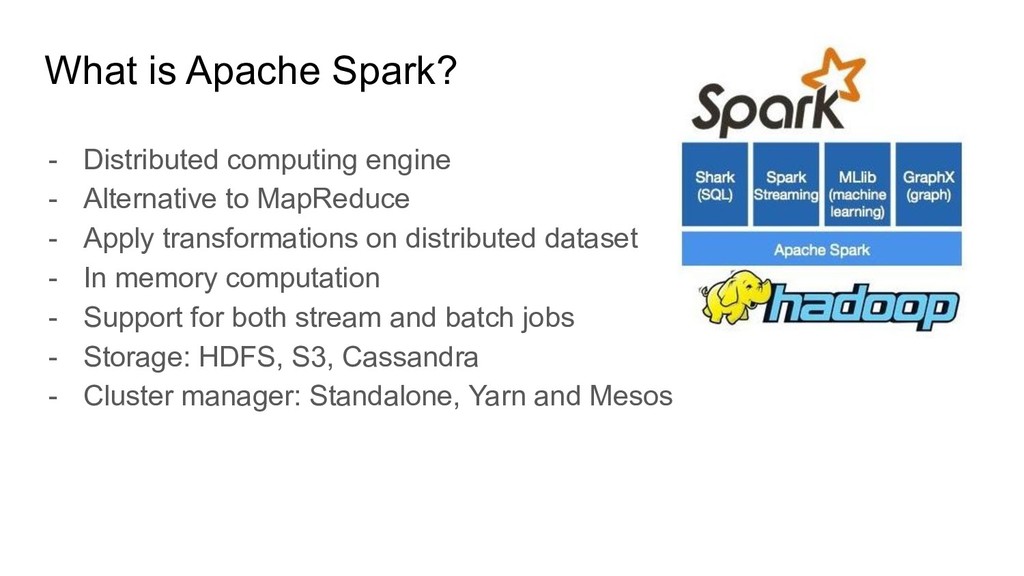
What is Apache Spark? - Distributed computing engine - Alternative
to MapReduce - Apply transformations on distributed dataset - In memory computation - Support for both stream and batch jobs - Storage: HDFS, S3, Cassandra - Cluster manager: Standalone, Yarn and Mesos -
- Collection of partitions across the cluster - each having
data - Partitions needn’t fit on a single machine - Resides on the executors - Can be kept in memory - faster execution - Fault tolerant - recomputed on failure - Operations registered in DAG Resilient Distributed Datasets (RDDs) -
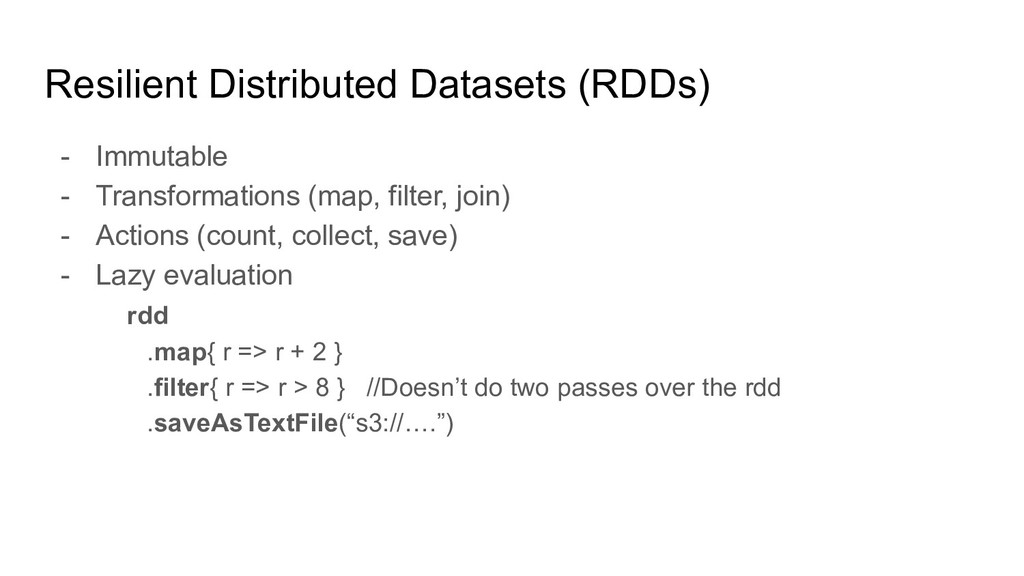
Resilient Distributed Datasets (RDDs) - Immutable - Transformations (map, filter,
join) - Actions (count, collect, save) - Lazy evaluation rdd .map{ r => r + 2 } .filter{ r => r > 8 } //Doesn’t do two passes over the rdd .saveAsTextFile(“s3://….”) -
Example - log mining val lines = sc.textFile("....") val errors
= lines.filter(_.contains("ERROR")) val messages = errors.map(_.split('\t')(2)) messages.cache() messages .filter(_.contains(“parse error”)) // transformation .count() // action - computes the RDD -
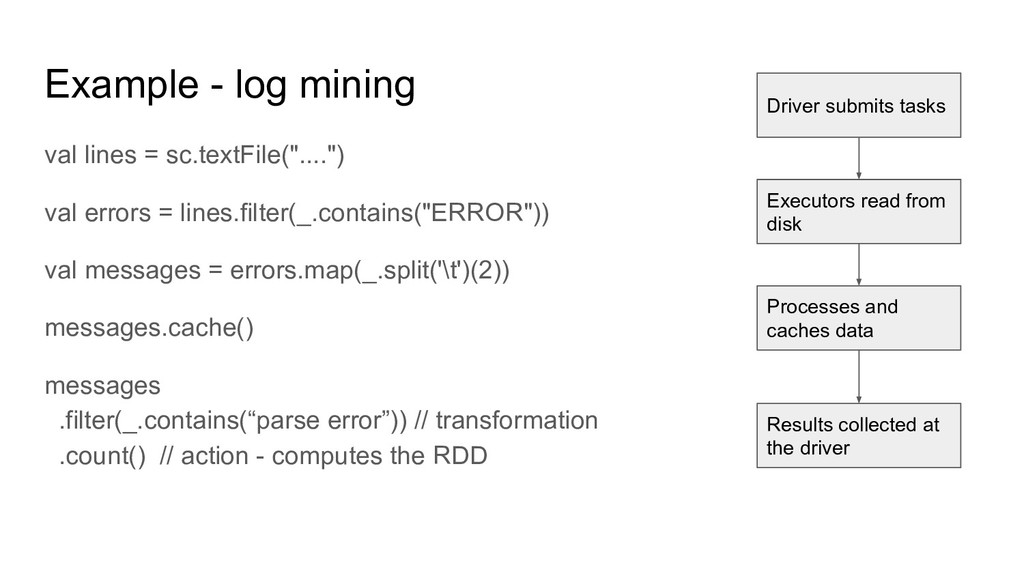
Example - log mining val lines = sc.textFile("....") val errors
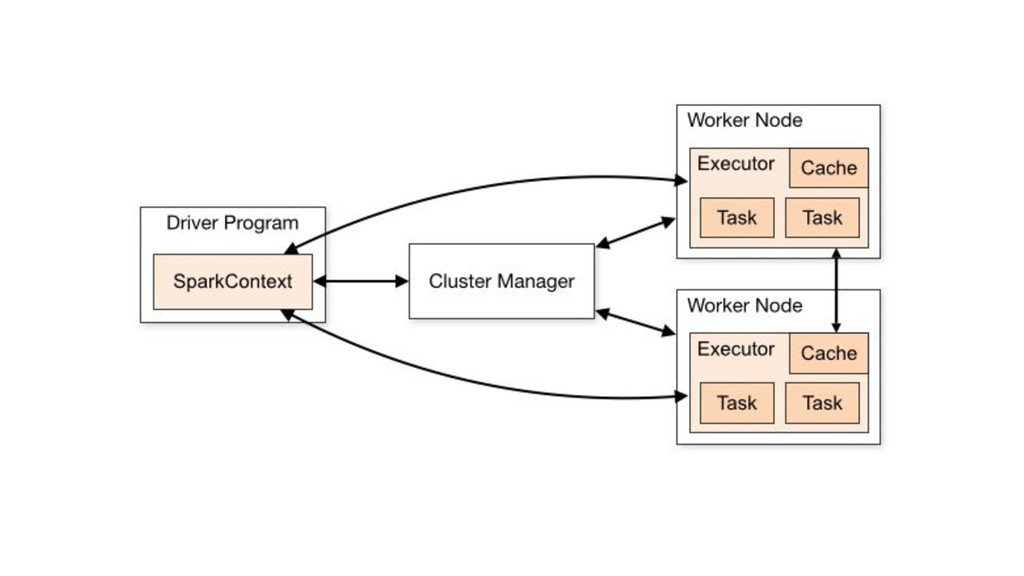
= lines.filter(_.contains("ERROR")) val messages = errors.map(_.split('\t')(2)) messages.cache() messages .filter(_.contains(“parse error”)) // transformation .count() // action - computes the RDD Driver submits tasks Executors read from disk Processes and caches data Results collected at the driver -
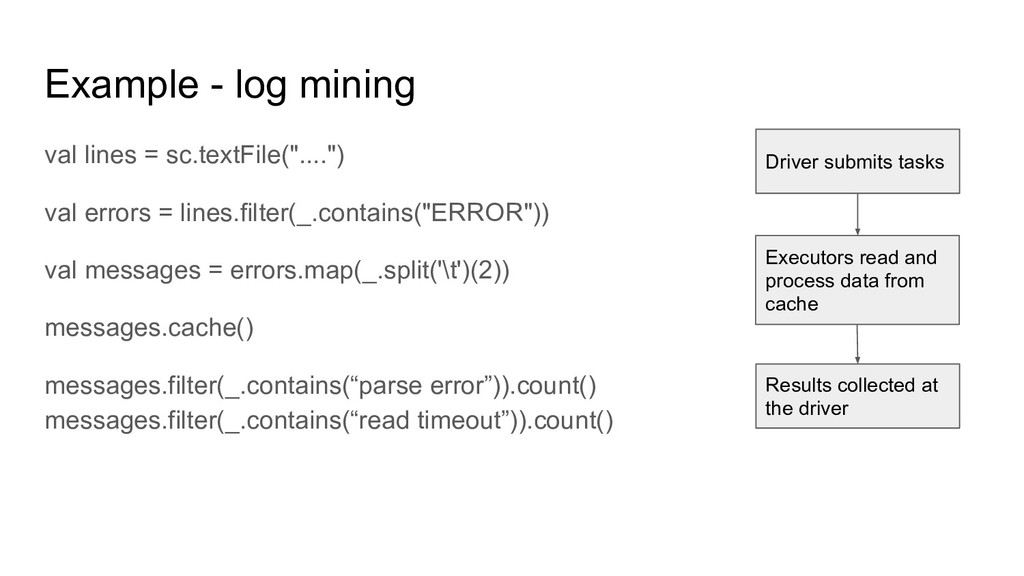
Example - log mining val lines = sc.textFile("....") val errors
= lines.filter(_.contains("ERROR")) val messages = errors.map(_.split('\t')(2)) messages.cache() messages.filter(_.contains(“parse error”)).count() messages.filter(_.contains(“read timeout”)).count() Driver submits tasks Executors read and process data from cache Results collected at the driver -
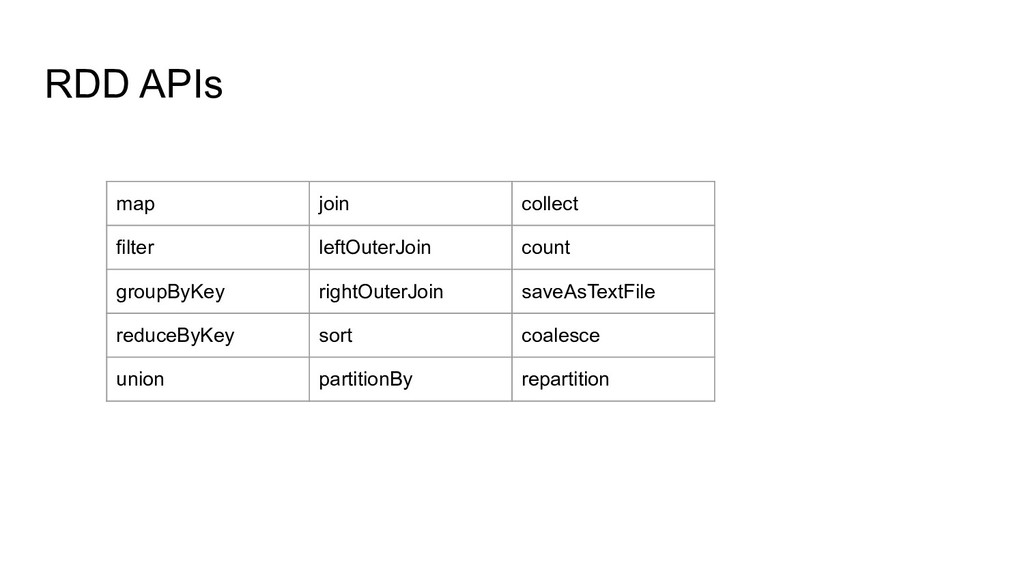
RDD APIs map join collect filter leftOuterJoin count groupByKey rightOuterJoin
saveAsTextFile reduceByKey sort coalesce union partitionBy repartition -
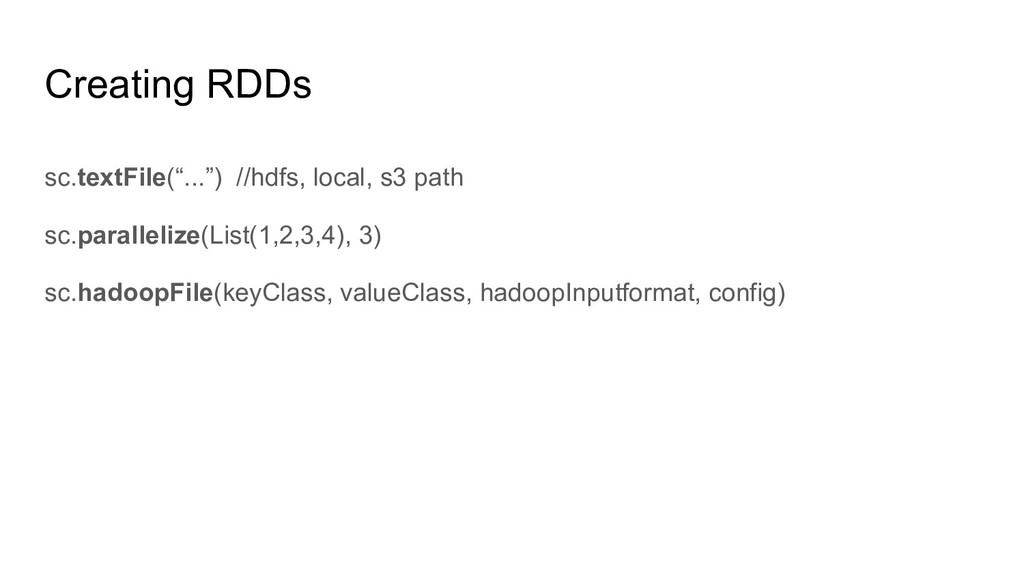
Creating RDDs sc.textFile(“...”) //hdfs, local, s3 path sc.parallelize(List(1,2,3,4), 3) sc.hadoopFile(keyClass,
valueClass, hadoopInputformat, config) -
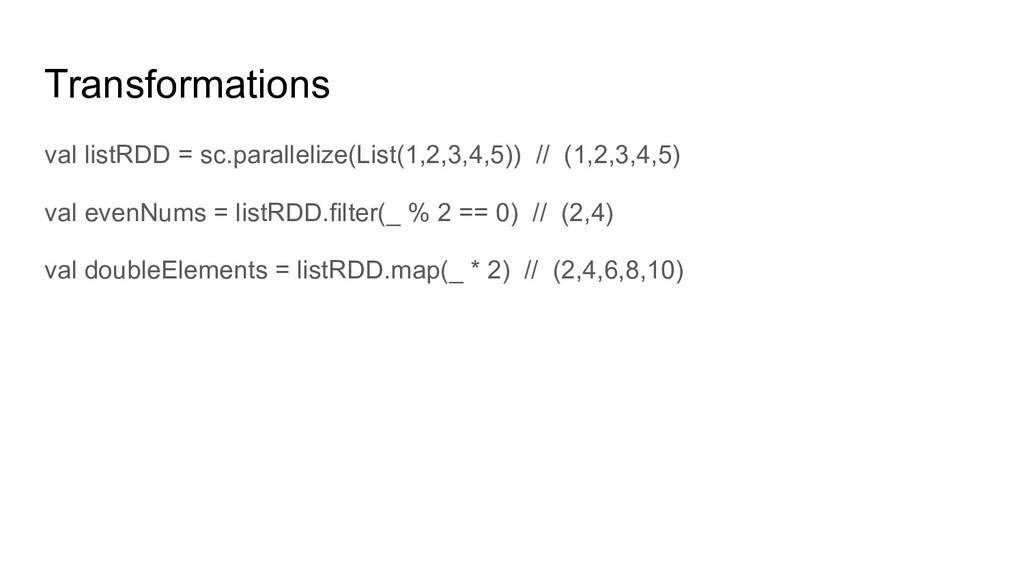
Transformations val listRDD = sc.parallelize(List(1,2,3,4,5)) // (1,2,3,4,5) val evenNums =
listRDD.filter(_ % 2 == 0) // (2,4) val doubleElements = listRDD.map(_ * 2) // (2,4,6,8,10) -
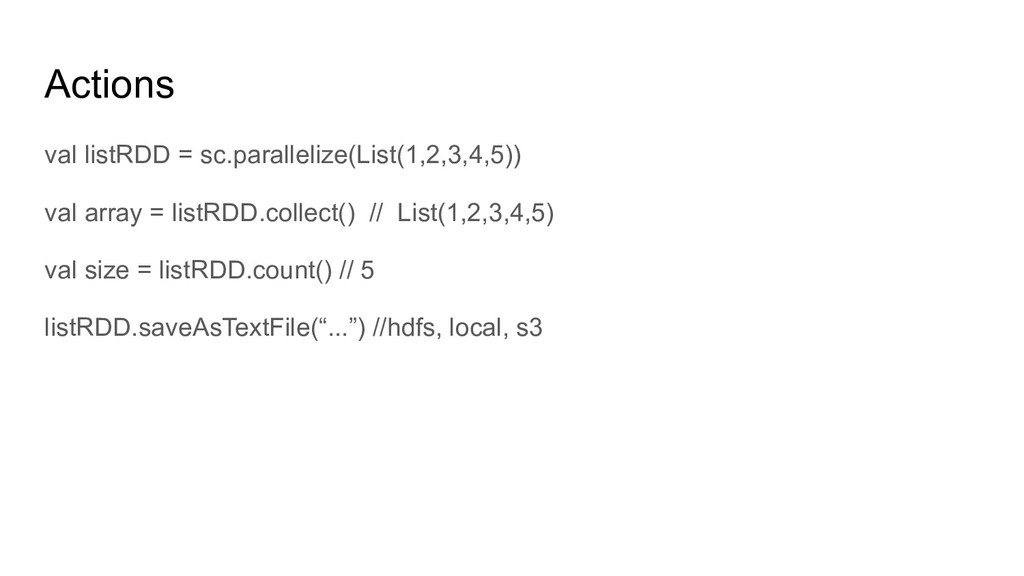
Actions val listRDD = sc.parallelize(List(1,2,3,4,5)) val array = listRDD.collect() //
List(1,2,3,4,5) val size = listRDD.count() // 5 listRDD.saveAsTextFile(“...”) //hdfs, local, s3 -
- Join - GroupBy - ReduceBy - SortBy - Repartition
Shuffle operations -
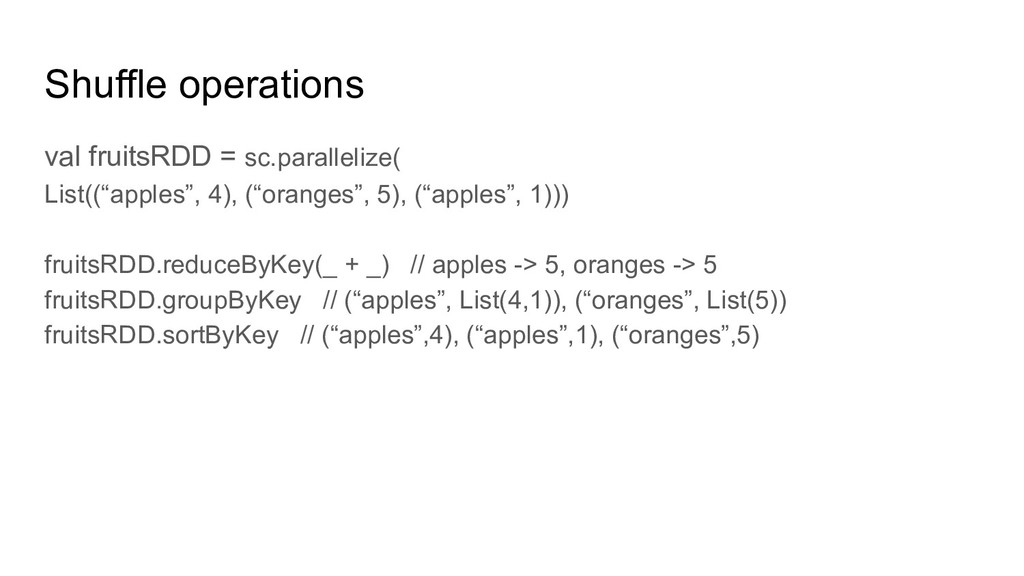
Shuffle operations val fruitsRDD = sc.parallelize( List((“apples”, 4), (“oranges”, 5),
(“apples”, 1))) fruitsRDD.reduceByKey(_ + _) // apples -> 5, oranges -> 5 fruitsRDD.groupByKey // (“apples”, List(4,1)), (“oranges”, List(5)) fruitsRDD.sortByKey // (“apples”,4), (“apples”,1), (“oranges”,5) -
WordCount Example def wordCount(rdd: RDD[String]) = { val words =
rdd.flatMap( _.split(“ “) ) val kvPair = words.map(word => (word, 1)) val wordCounts = kvPair.reduceByKey(_ + _) wordCounts } Notebook -
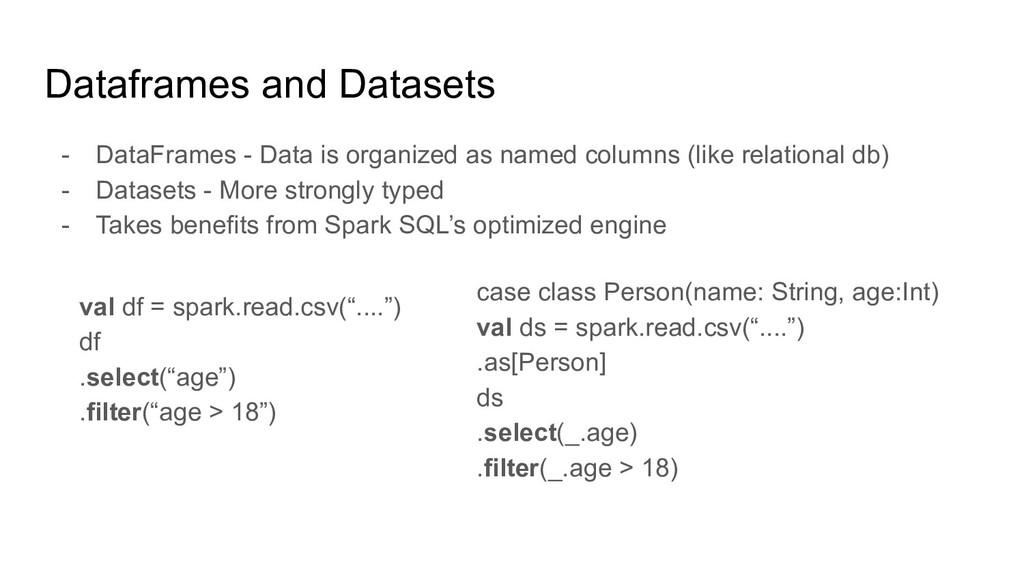
Dataframes and Datasets - DataFrames - Data is organized as
named columns (like relational db) - Datasets - More strongly typed - Takes benefits from Spark SQL’s optimized engine case class Person(name: String, age:Int) val ds = spark.read.csv(“....”) .as[Person] ds .select(_.age) .filter(_.age > 18) val df = spark.read.csv(“....”) df .select(“age”) .filter(“age > 18”) -
Hands On Session - Sign up for the community edition
in databricks.com - Download datasets from github.com/Matild/spark-workshop - Scala setup - www.scala-lang.org/downloads - Scala Cheatsheet - https://learnxinyminutes.com/docs/scala/ -
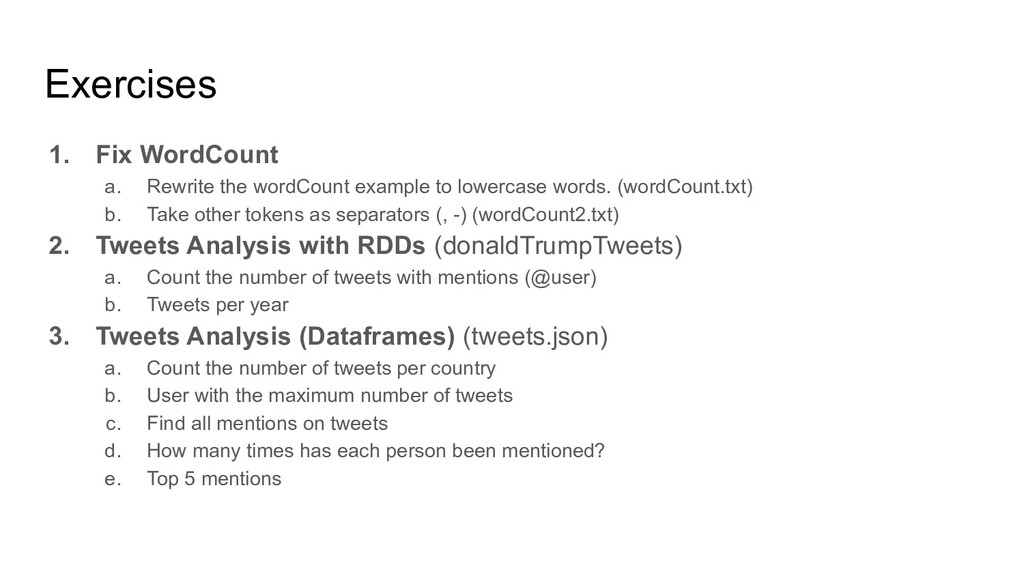
Exercises 1. Fix WordCount a. Rewrite the wordCount example to
lowercase words. (wordCount.txt) b. Take other tokens as separators (, -) (wordCount2.txt) 2. Tweets Analysis with RDDs (donaldTrumpTweets) a. Count the number of tweets with mentions (@user) b. Tweets per year 3. Tweets Analysis (Dataframes) (tweets.json) a. Count the number of tweets per country b. User with the maximum number of tweets c. Find all mentions on tweets d. How many times has each person been mentioned? e. Top 5 mentions