Share
Embed
New Cassandra 3 features that change your (developer) life by DuyHai Doan
Riga Dev Day
March 13, 2016
Transcript
45 slides
-
@doanduyhai New Cassandra 3 features that change your (developer) life
DuyHai DOAN, Apache Cassandra Evangelist -
@doanduyhai Who Am I ? Duy Hai DOAN Apache Cassandra
Evangelist • talks, meetups, confs … • open-source projects (Achilles, Apache Zeppelin ...) • OSS Cassandra point of contact ☞ [email protected] ☞ @doanduyhai 2 -
@doanduyhai Datastax • Founded in April 2010 • We contribute
a lot to Apache Cassandra™ • 400+ customers (25 of the Fortune 100), 400+ employees • Headquarter in San Francisco Bay area • EU headquarter in London, offices in France and Germany • Datastax Enterprise = OSS Cassandra + extra features 3 -
@doanduyhai Agenda 4 • Materialized Views • JSON Support •
User Defined Functions (UDF) and Aggregates (UDA) • New SASI full text search index -
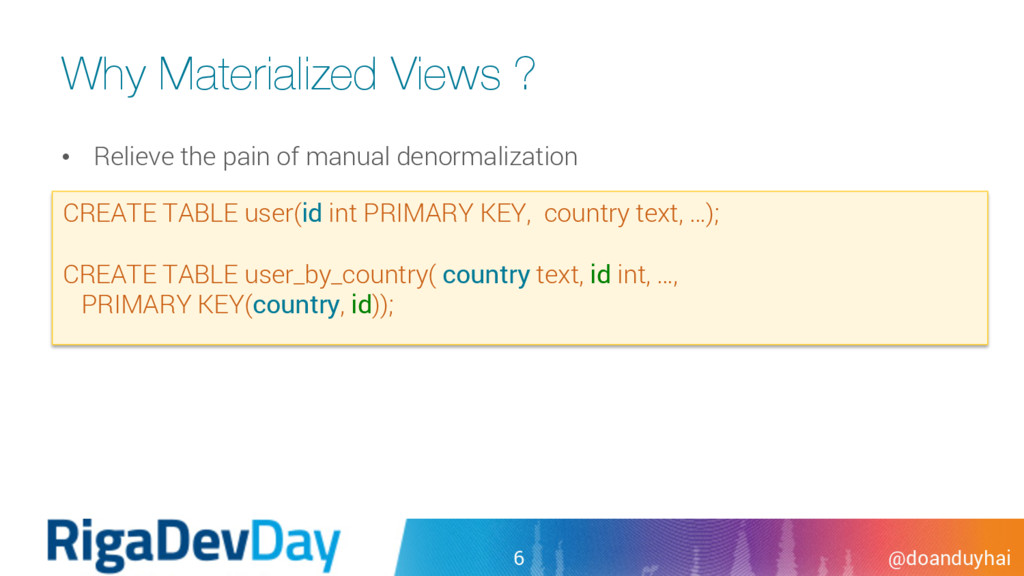
@doanduyhai Why Materialized Views ? • Relieve the pain of
manual denormalization CREATE TABLE user(id int PRIMARY KEY, country text, …); CREATE TABLE user_by_country( country text, id int, …, PRIMARY KEY(country, id)); 6 -
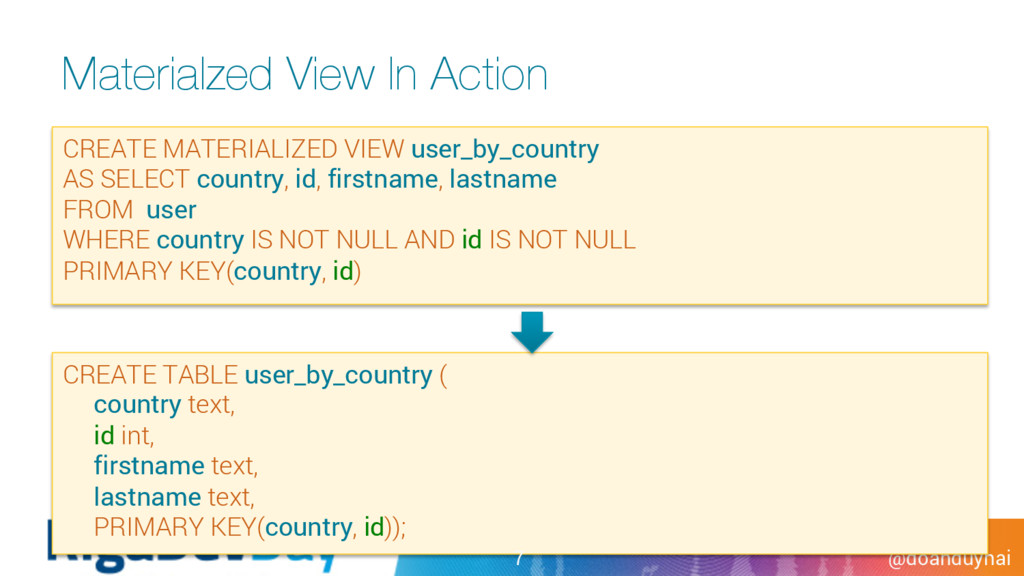
@doanduyhai CREATE TABLE user_by_country ( country text, id int, firstname
text, lastname text, PRIMARY KEY(country, id)); Materialzed View In Action CREATE MATERIALIZED VIEW user_by_country AS SELECT country, id, firstname, lastname FROM user WHERE country IS NOT NULL AND id IS NOT NULL PRIMARY KEY(country, id) 7 -
@doanduyhai Materialized View Performance • Write performance • slower than
normal write • for each base table update, worst case: mv_count x 2 (DELETE + INSERT) extra mutations for the views 9 -
@doanduyhai Materialized View Performance • Write performance vs manual denormalization
• MV better because no client-server network traffic for read-before-write • MV better because less network traffic for multiple views (client-side BATCH) • Makes developer life easier à priceless 10 -
@doanduyhai Materialized View Performance • Read performance vs secondary index
• MV better because single node read (secondary index can hit many nodes) • MV better because single read path (secondary index = read index + read data) 11 -
@doanduyhai Materialized Views Consistency • Consistency level • CL honoured
for base table, ONE for MV + local batchlog • Weaker consistency guarantees for MV than for base table. 12 -
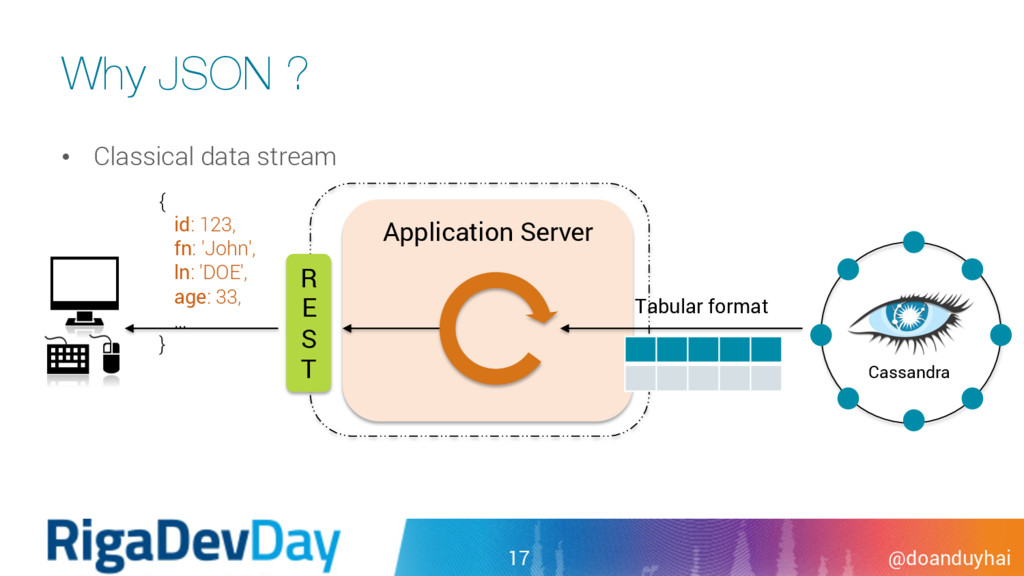
@doanduyhai Why JSON ? 15 • JSON is a terrible
schema à no schema indeed • But … a very good exchange format • REST API • technology agnostic -
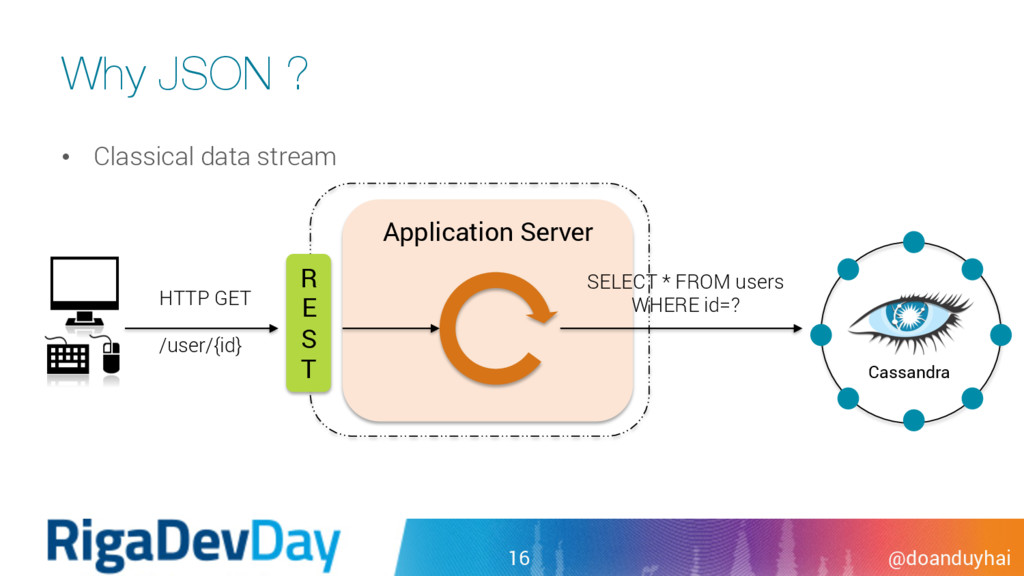
@doanduyhai Why JSON ? 16 • Classical data stream Application
Server Cassandra R E S T HTTP GET /user/{id} SELECT * FROM users WHERE id=? -
@doanduyhai Why JSON ? 17 • Classical data stream Application
Server Cassandra R E S T { id: 123, fn: 'John', ln: 'DOE', age: 33, … } Tabular format -
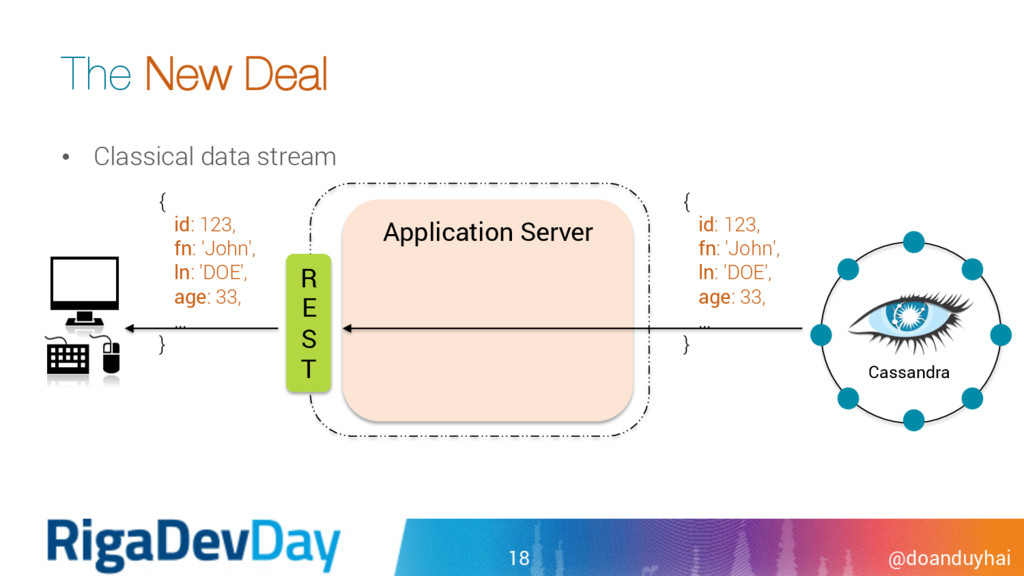
@doanduyhai The New Deal 18 • Classical data stream Application
Server Cassandra R E S T { id: 123, fn: 'John', ln: 'DOE', age: 33, … } { id: 123, fn: 'John', ln: 'DOE', age: 33, … } -
@doanduyhai Rationale • Push computation server-side • save network bandwidth
(1000 nodes!) • simplify client-side code • provide standard & useful function (sum, avg …) • accelerate analytics use-case (pre-aggregation for Spark) 22 -
@doanduyhai How to create an UDF ? CREATE [OR REPLACE]
FUNCTION [IF NOT EXISTS] [keyspace.]functionName (param1 type1 , param2 type2 , …) CALLED ON NULL INPUT | RETURNS NULL ON NULL INPUT RETURNS returnType LANGUAGE language AS $$ // source code here $$; 23 -
@doanduyhai How to create an UDF ? CREATE [OR REPLACE]
FUNCTION [IF NOT EXISTS] [keyspace.]functionName (param1 type1 , param2 type2 , …) CALLED ON NULL INPUT | RETURNS NULL ON NULL INPUT RETURNS returnType LANGUAGE language AS $$ // source code here $$; Param name to refer to in the code Type = Cassandra type 24 -
@doanduyhai How to create an UDF ? CREATE [OR REPLACE]
FUNCTION [IF NOT EXISTS] [keyspace.]functionName (param1 type1 , param2 type2 , …) CALLED ON NULL INPUT | RETURNS NULL ON NULL INPUT RETURNS returnType LANGUAGE language // j AS $$ // source code here $$; Always called Null-check mandatory in code 25 -
@doanduyhai How to create an UDF ? CREATE [OR REPLACE]
FUNCTION [IF NOT EXISTS] [keyspace.]functionName (param1 type1 , param2 type2 , …) CALLED ON NULL INPUT | RETURNS NULL ON NULL INPUT RETURNS returnType LANGUAGE language // jav AS $$ // source code here $$; If any input is null, function execution is skipped and return null 26 -
@doanduyhai How to create an UDF ? CREATE [OR REPLACE]
FUNCTION [IF NOT EXISTS] [keyspace.]functionName (param1 type1 , param2 type2 , …) CALLED ON NULL INPUT | RETURNS NULL ON NULL INPUT RETURNS returnType LANGUAGE language AS $$ // source code here $$; Cassandra types • primitives (boolean, int, …) • collections (list, set, map) • tuples • UDT 27 -
@doanduyhai How to create an UDF ? CREATE [OR REPLACE]
FUNCTION [IF NOT EXISTS] [keyspace.]functionName (param1 type1 , param2 type2 , …) CALLED ON NULL INPUT | RETURNS NULL ON NULL INPUT RETURNS returnType LANGUAGE language AS $$ // source code here $$; JVM supported languages • Java, Scala • Javascript (slow) • Groovy, Jython, JRuby • Clojure ( JSR 223 impl issue) 28 -
@doanduyhai User Defined Aggregates (UDA) • Real use-case for UDF
• Aggregation server-side à huge network bandwidth saving • Provide similar behavior for Group By, Sum, Avg etc … 30 -
@doanduyhai How to create an UDA ? CREATE [OR REPLACE]
AGGREGATE [IF NOT EXISTS] [keyspace.]aggregateName(type1 , type2 , …) SFUNC accumulatorFunction STYPE stateType [FINALFUNC finalFunction] INITCOND initCond; Only type, no param name State type Initial state type 31 -
@doanduyhai How to create an UDA ? CREATE [OR REPLACE]
AGGREGATE [IF NOT EXISTS] [keyspace.]aggregateName(type1 , type2 , …) SFUNC accumulatorFunction STYPE stateType [FINALFUNC finalFunction] INITCOND initCond; Accumulator function. Signature: accumulatorFunction(stateType, type1 , type2 , …) RETURNS stateType 32 -
@doanduyhai How to create an UDA ? CREATE [OR REPLACE]
AGGREGATE [IF NOT EXISTS] [keyspace.]aggregateName(type1 , type2 , …) SFUNC accumulatorFunction STYPE stateType [FINALFUNC finalFunction] INITCOND initCond; Optional final function. Signature: finalFunction(stateType) 33 -
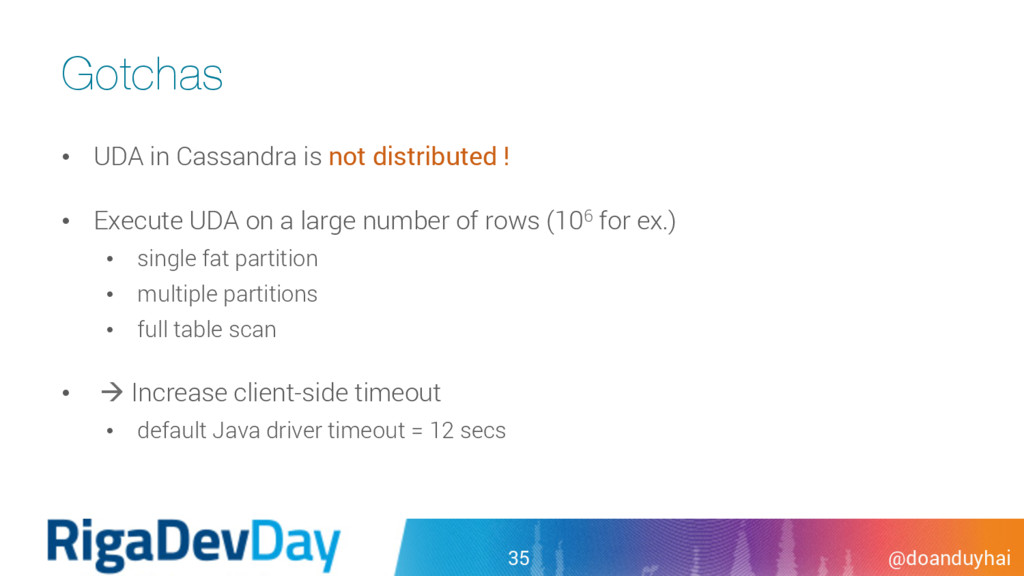
@doanduyhai Gotchas 35 • UDA in Cassandra is not distributed
! • Execute UDA on a large number of rows (106 for ex.) • single fat partition • multiple partitions • full table scan • à Increase client-side timeout • default Java driver timeout = 12 secs -
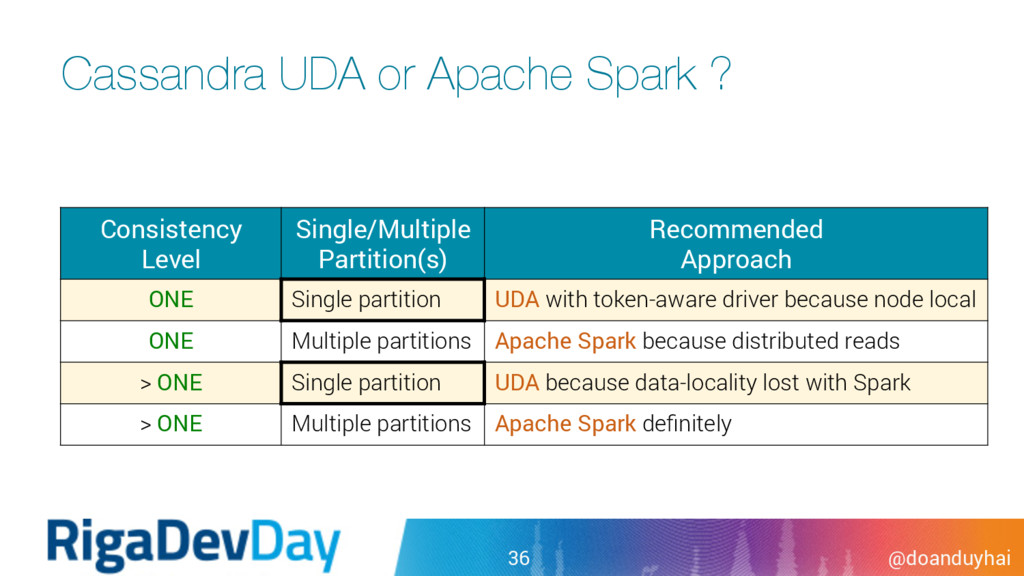
@doanduyhai Cassandra UDA or Apache Spark ? 36 Consistency Level
Single/Multiple Partition(s) Recommended Approach ONE Single partition UDA with token-aware driver because node local ONE Multiple partitions Apache Spark because distributed reads > ONE Single partition UDA because data-locality lost with Spark > ONE Multiple partitions Apache Spark definitely -
@doanduyhai SASI index, the search is over! • Why ?
• How ? • Who ? • Demo ! • When ? -
@doanduyhai Why SASI ? • Searching (and full text search)
was always a pain point for Cassandra • limited search predicates (=, <=, <, > and >= only) • limited scope (only on primary key columns) • Existing secondary index performance is poor • reversed-index • use Cassandra itself as index storage … • limited predicate ( = ). Inequality predicate = full cluster scan 39 -
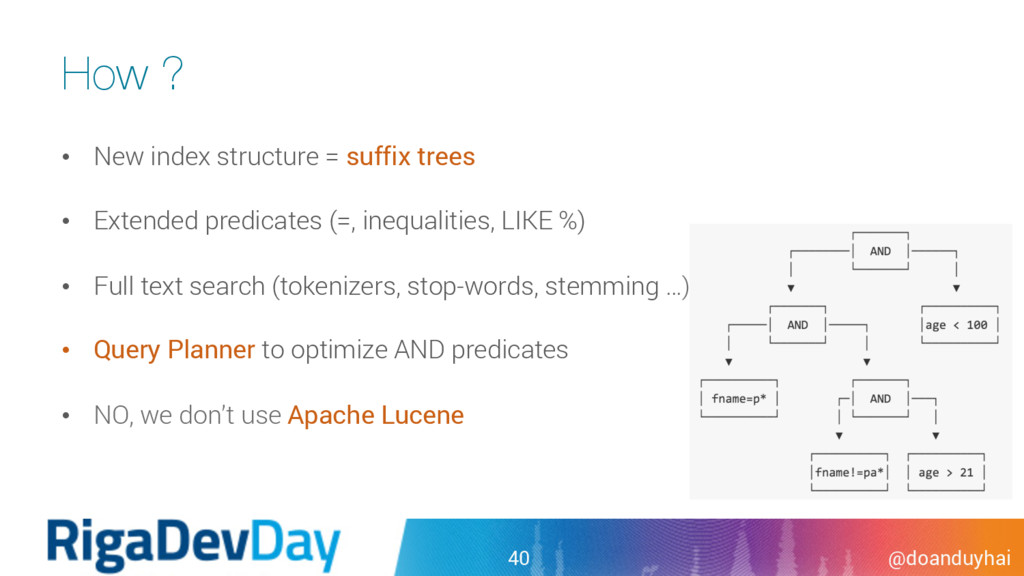
@doanduyhai How ? • New index structure = suffix trees
• Extended predicates (=, inequalities, LIKE %) • Full text search (tokenizers, stop-words, stemming …) • Query Planner to optimize AND predicates • NO, we don’t use Apache Lucene 40 -
@doanduyhai Who ? • Open source contribution by a team
from Apple 41 -
@doanduyhai When ? • Cassandra 3.4 released in March 2016
• Later • support for OR clause : ( aaa OR bbb) AND (ccc OR ddd) • index on collections (Set, List, Map) 43