From Guesswork to Governance: Bringing API Discipline to Data Streaming
Plano, Texas - September 3, 2026
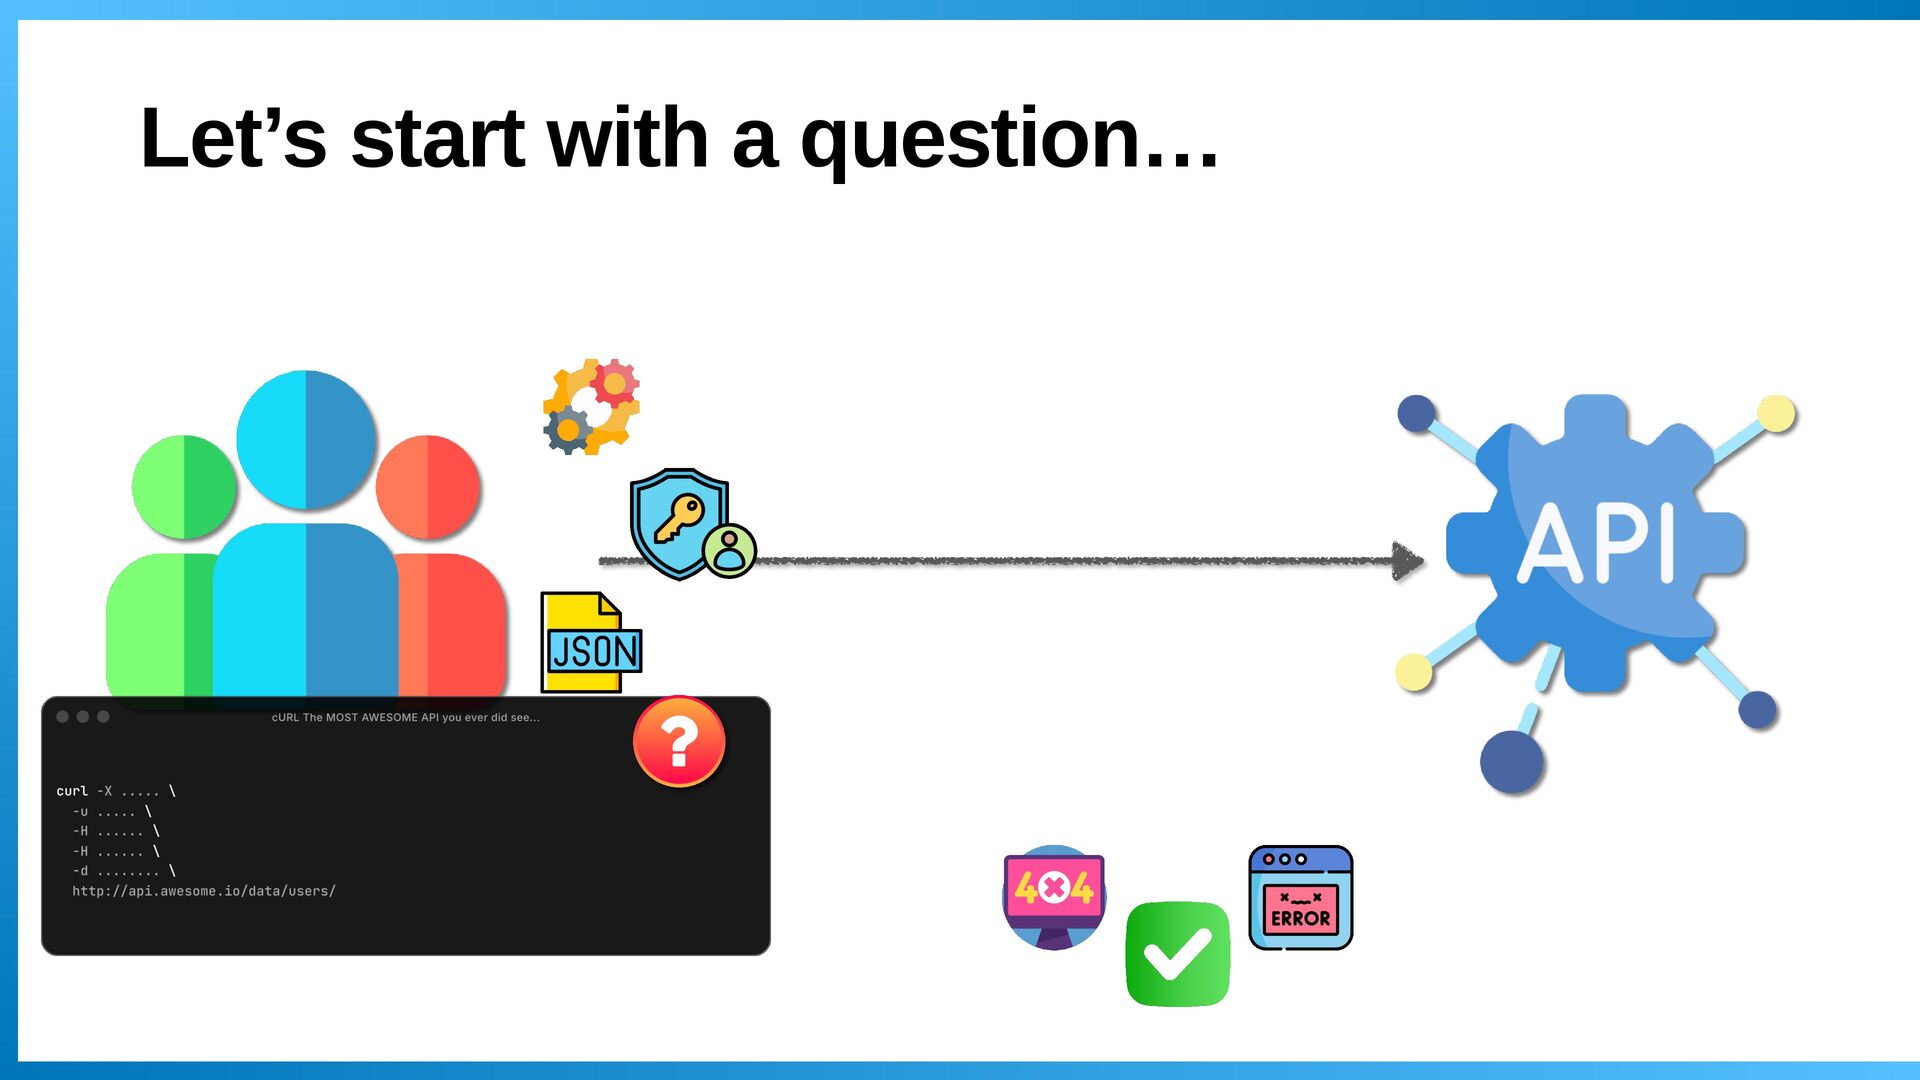
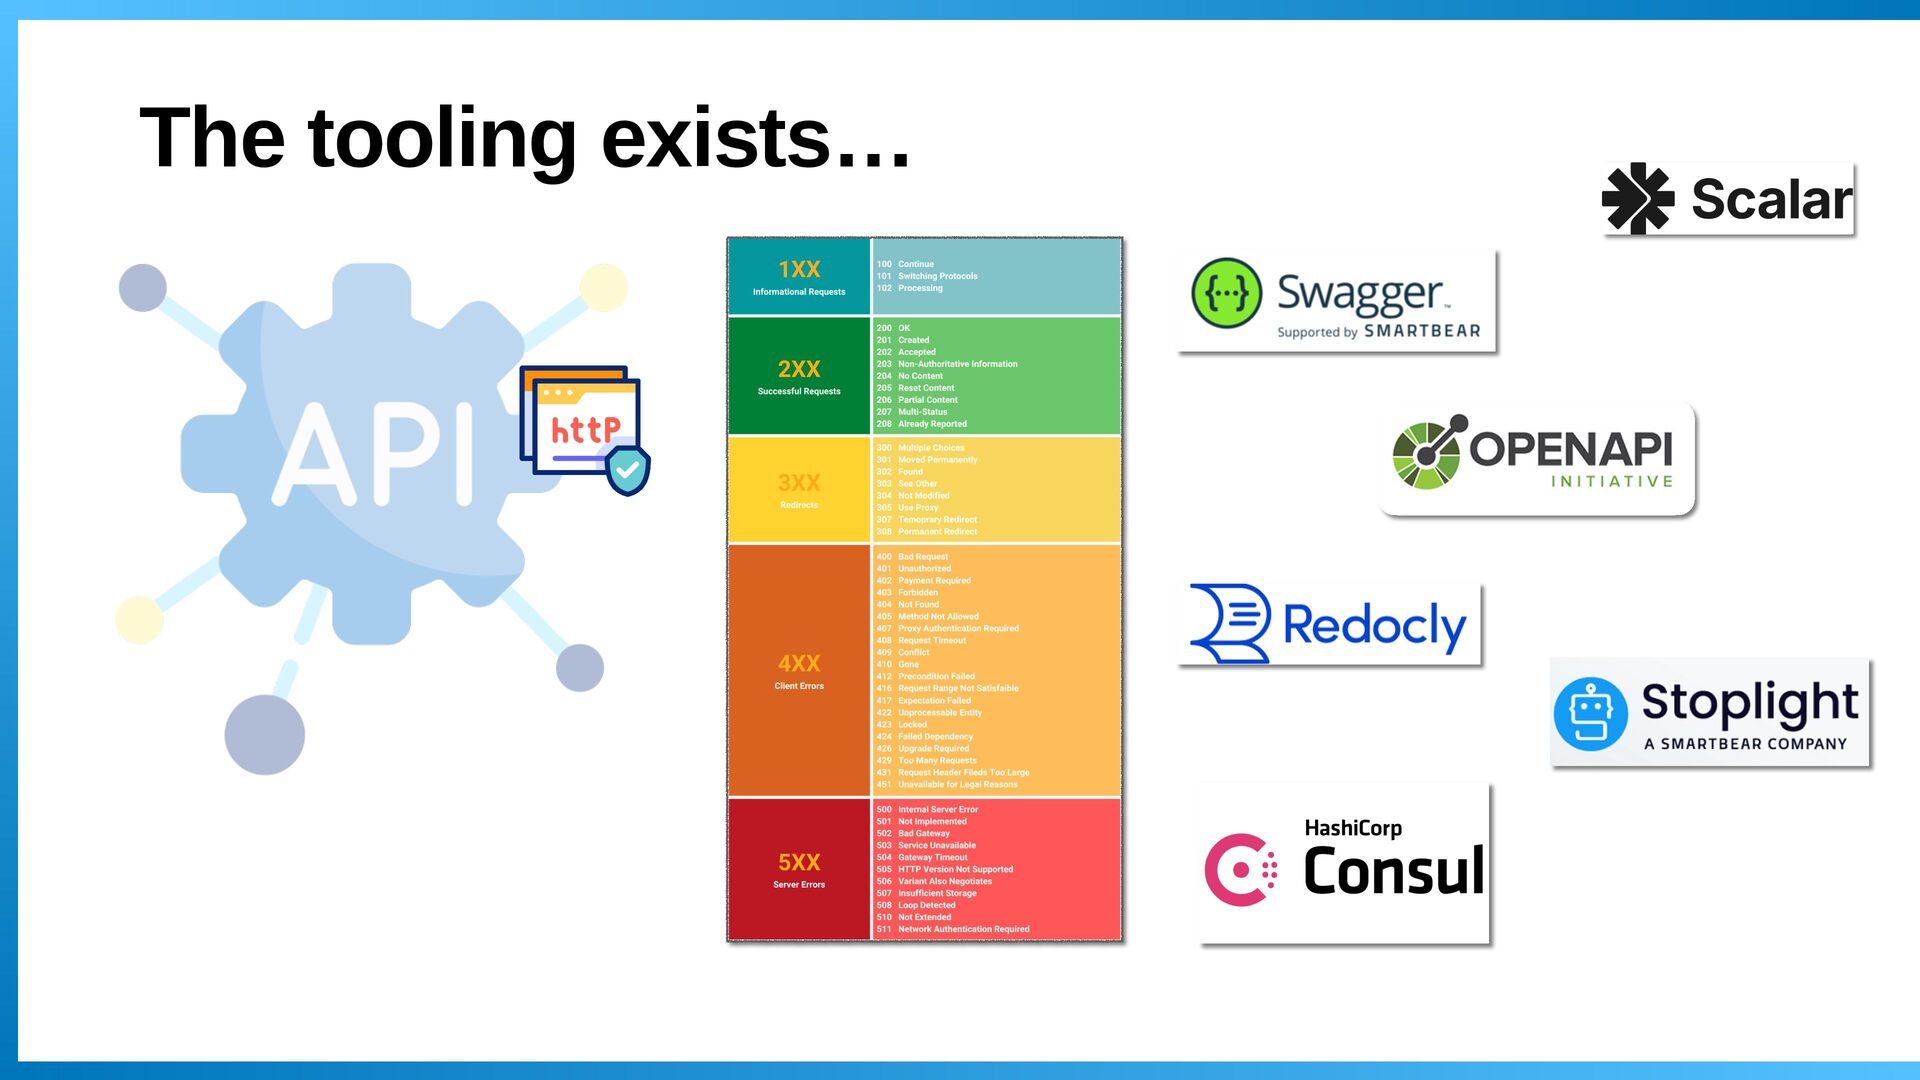
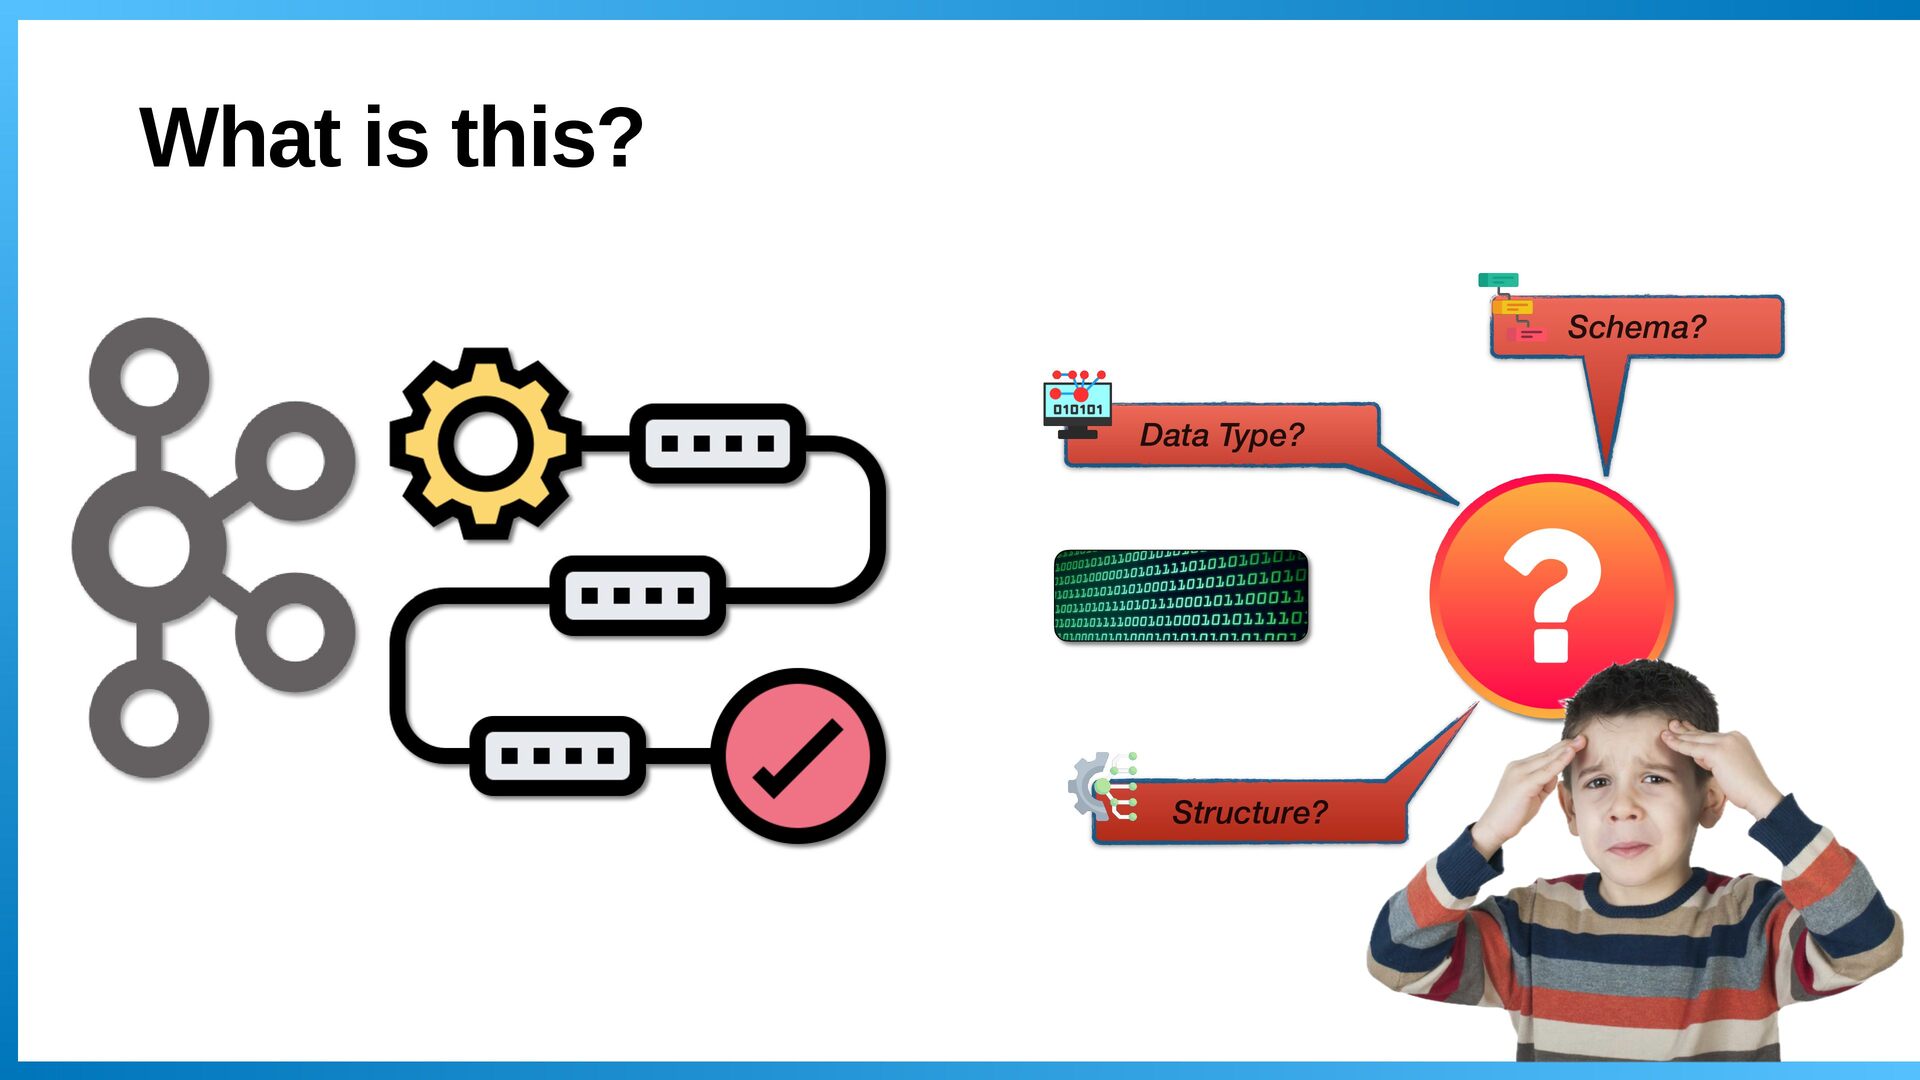
So you’re committed to this path of data streaming with Apache Kafka. But, here’s a question: would you build a REST API and make users guess the request and response formats? Doing so opens a Pandora’s Box…
- What’s the domain model?
- Name the operation… POST? GET? PUT? PATCH?
- What does this error code even mean?
- Is the documentation (if it even exists) accurate and relevant?
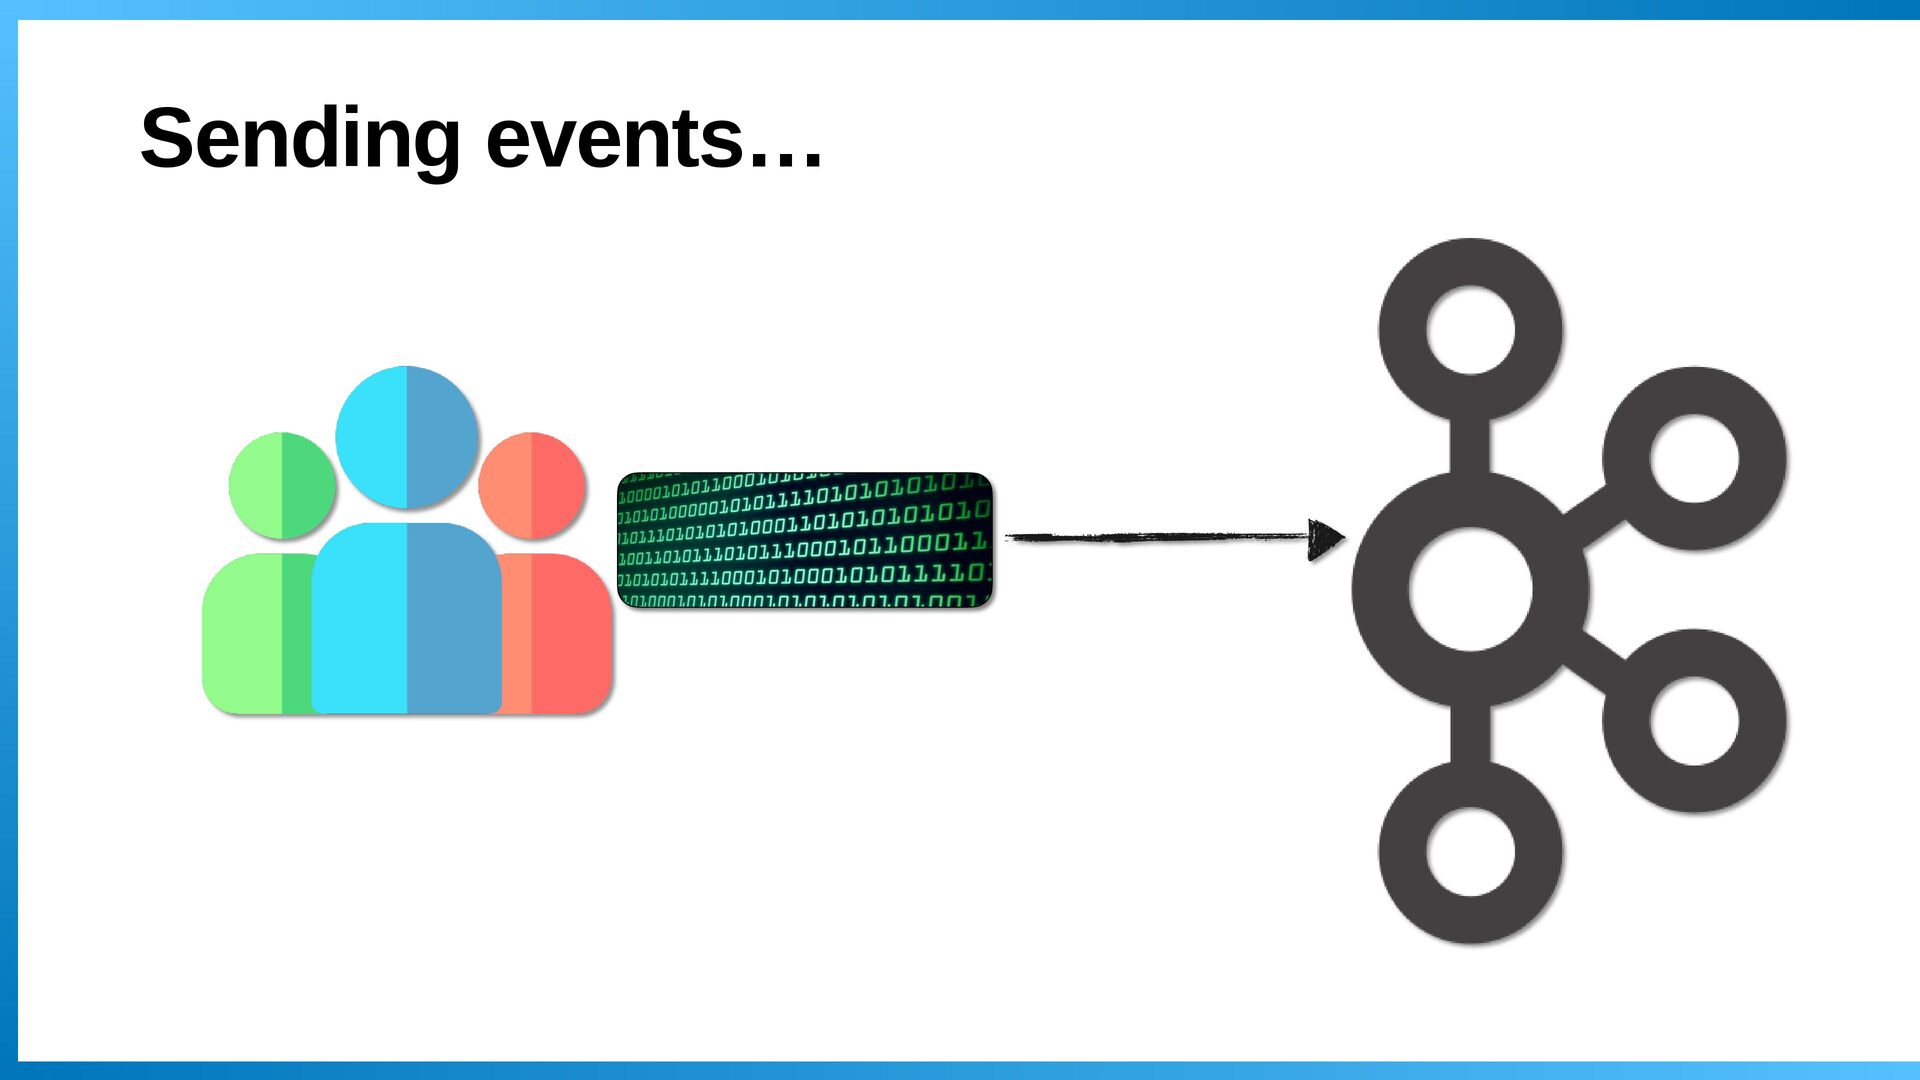
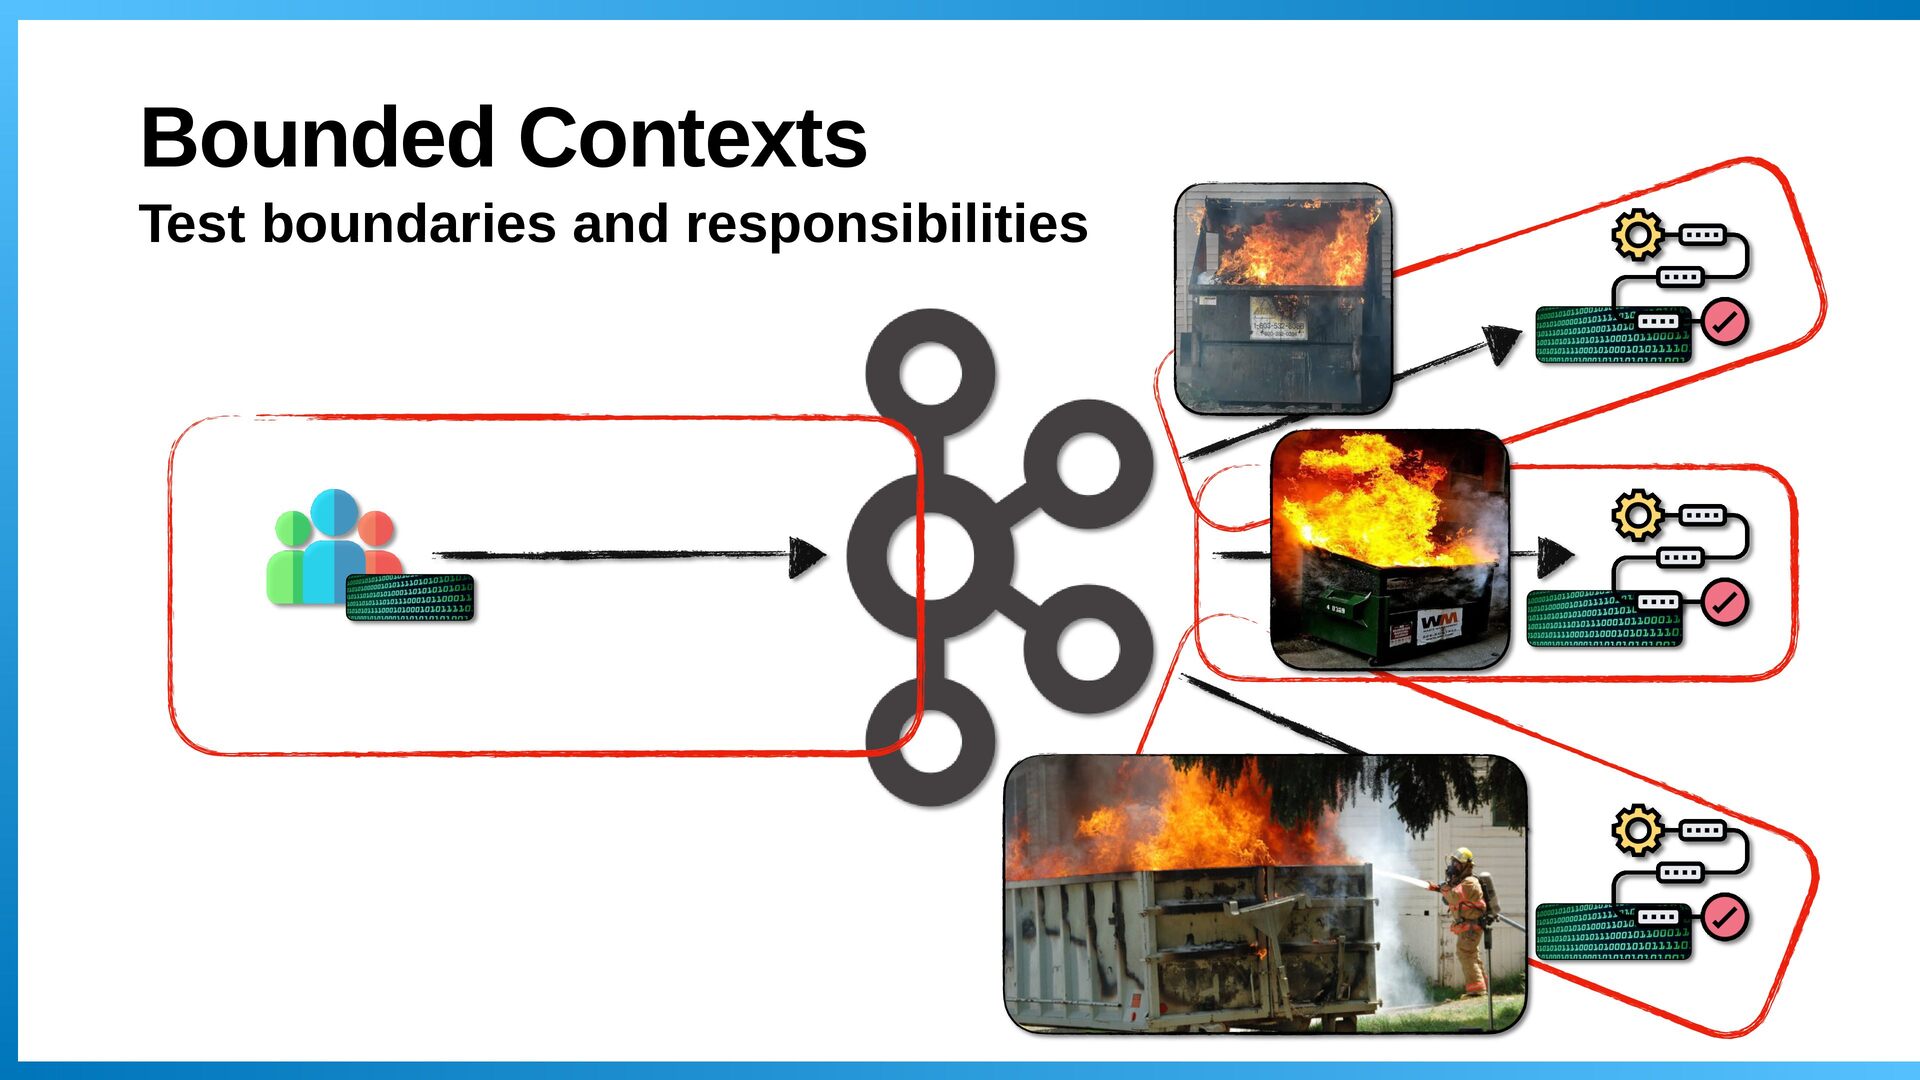
Imagine the complex, repetitive logic every consuming system would need to implement to make sense of it all. In a distributed, asynchronous system, these problems are magnified. Apache Kafka's flexibility - messages as simple bytes - is a huge strength, but it's also a major risk. While your event streams likely consist of some structured data (maybe JSON strings), enforcing structure, managing evolution, and basic validations aren’t a hard requirement. This leaves consumer applications to perform this preprocessing of every event - even if that event has no business value.
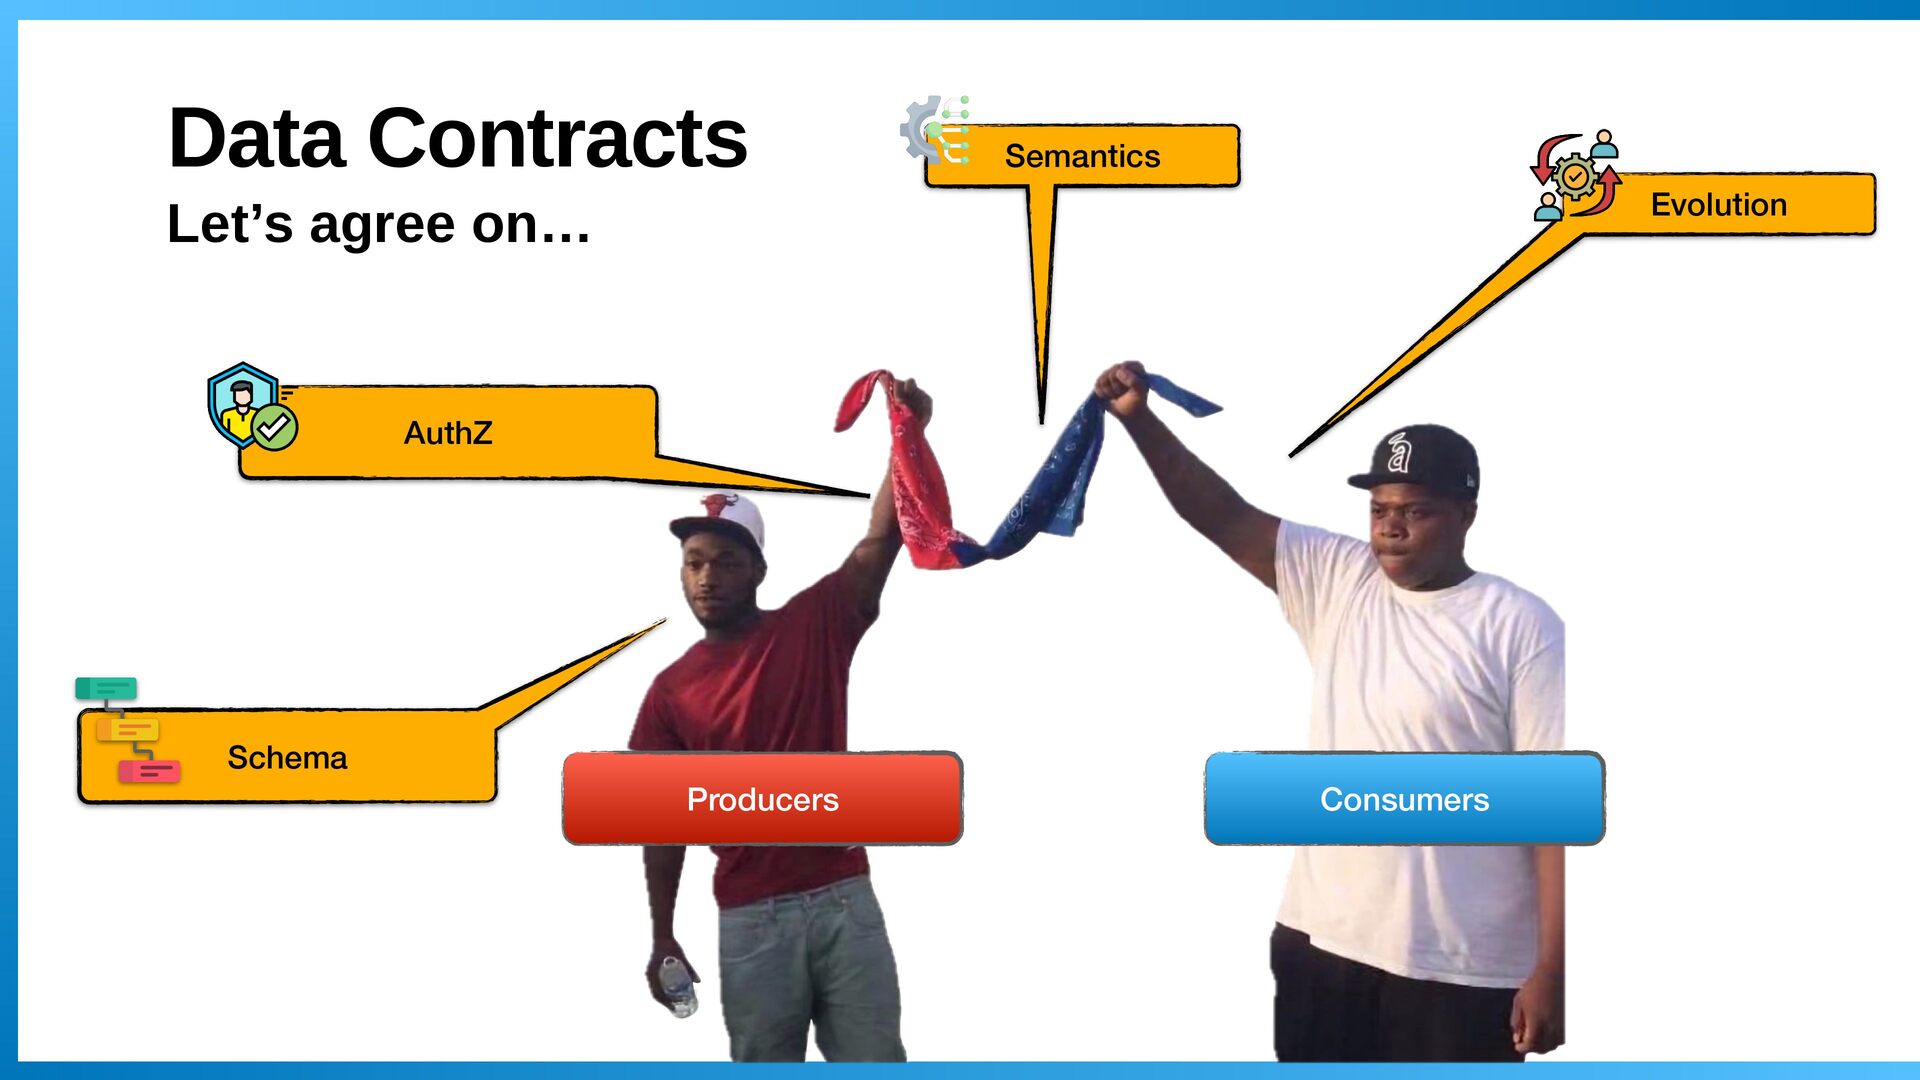
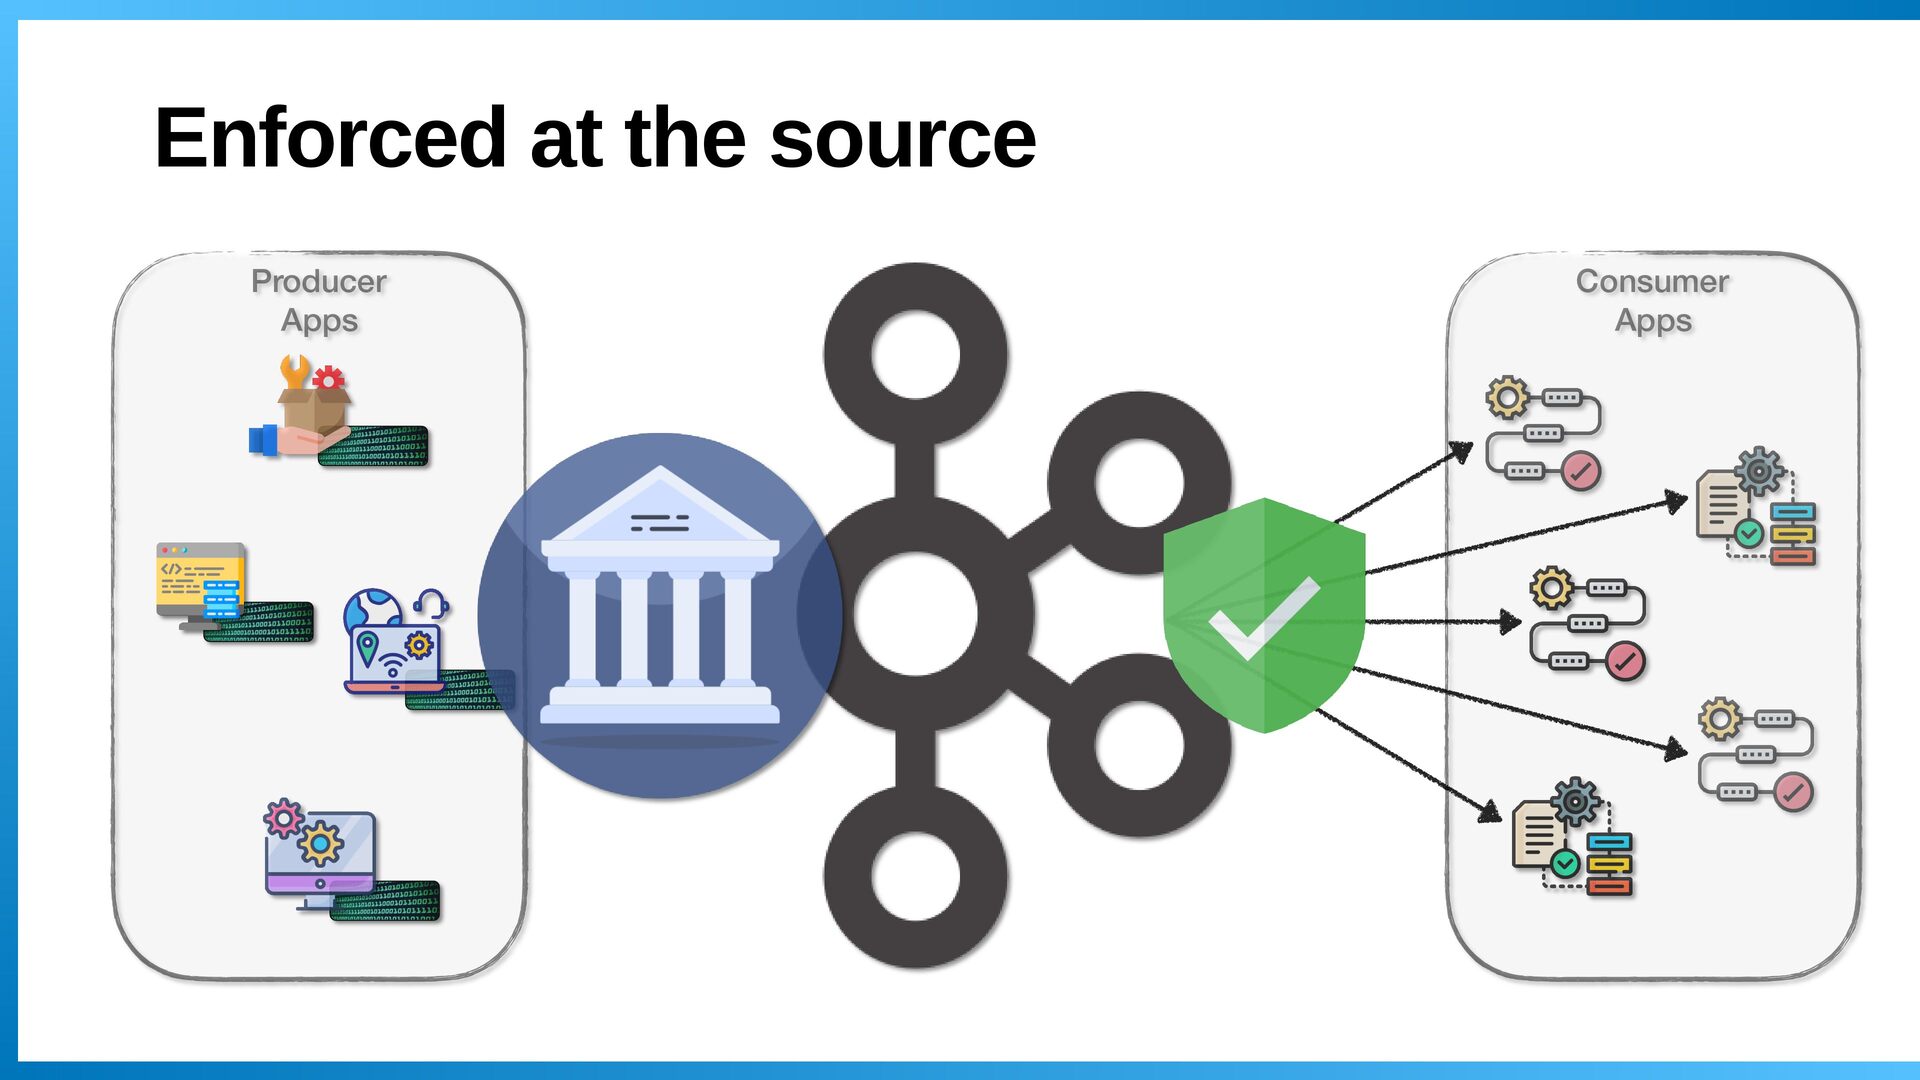
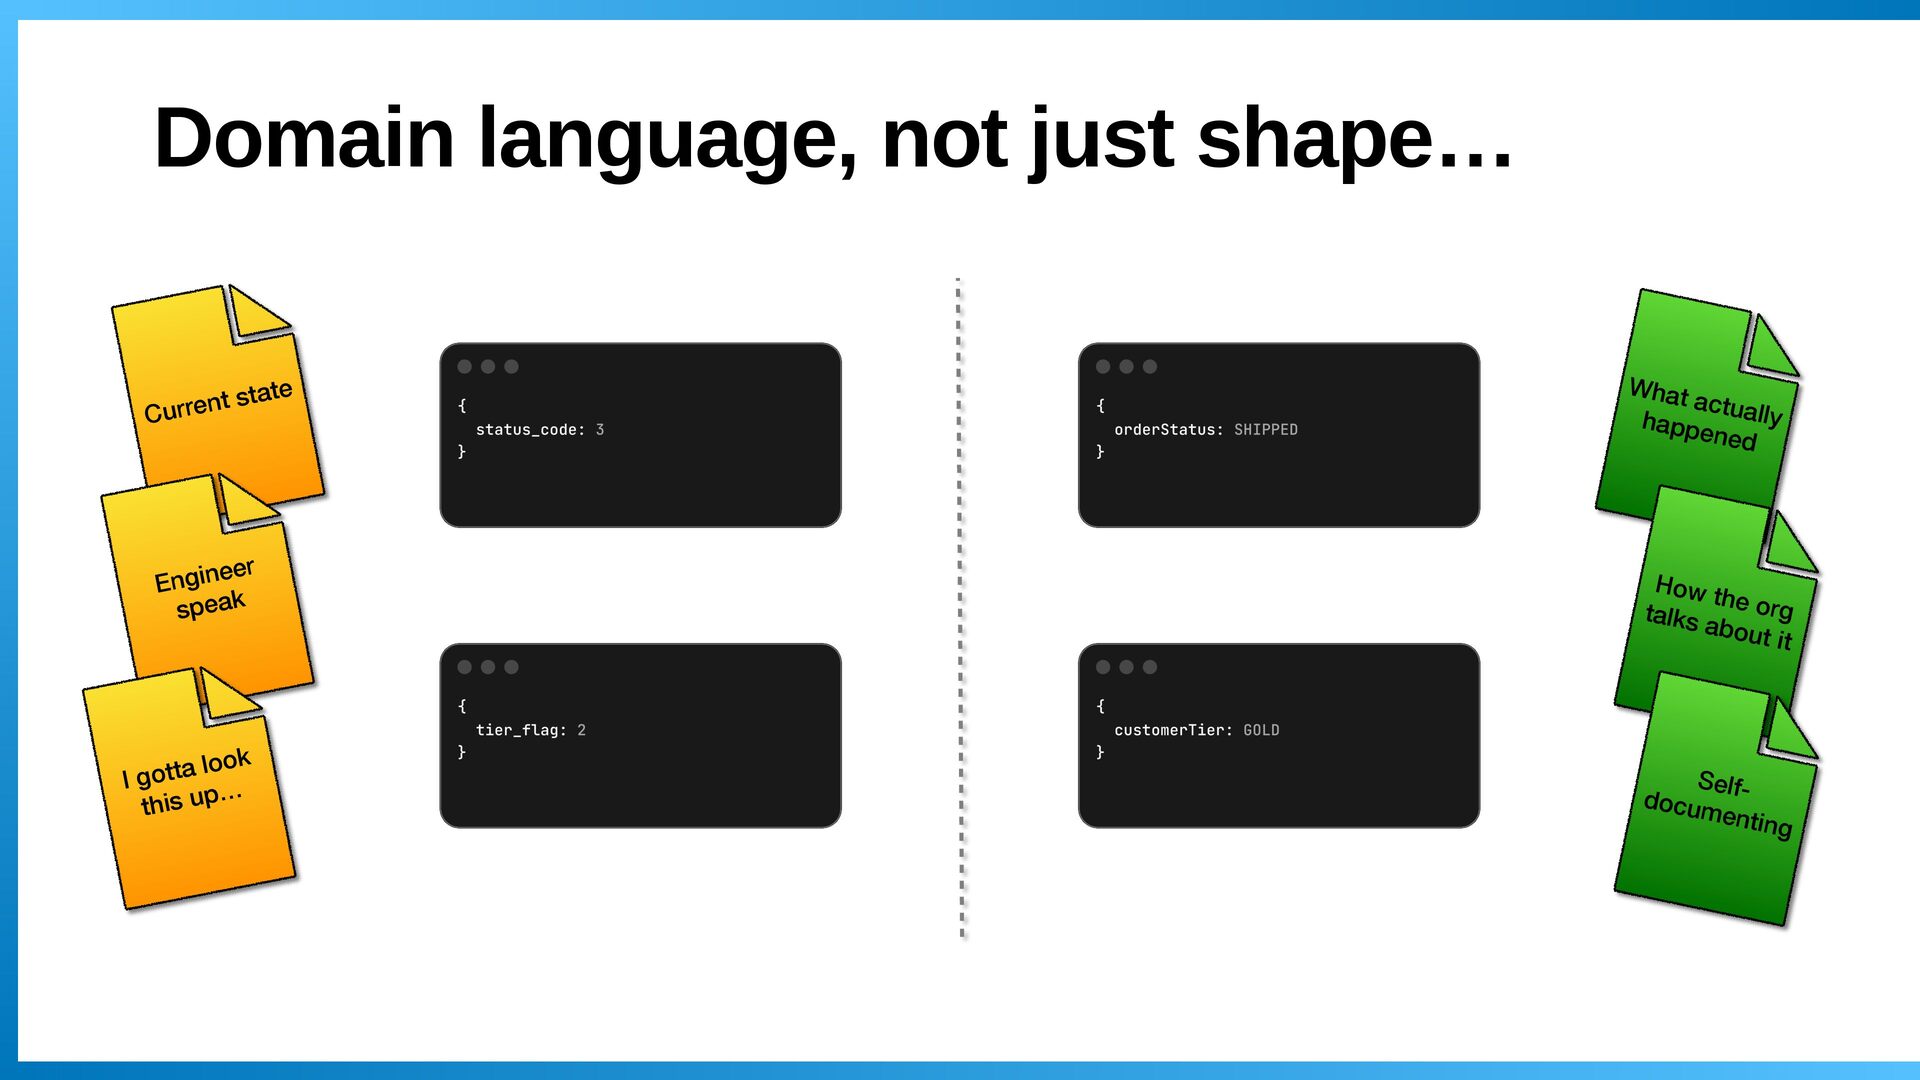
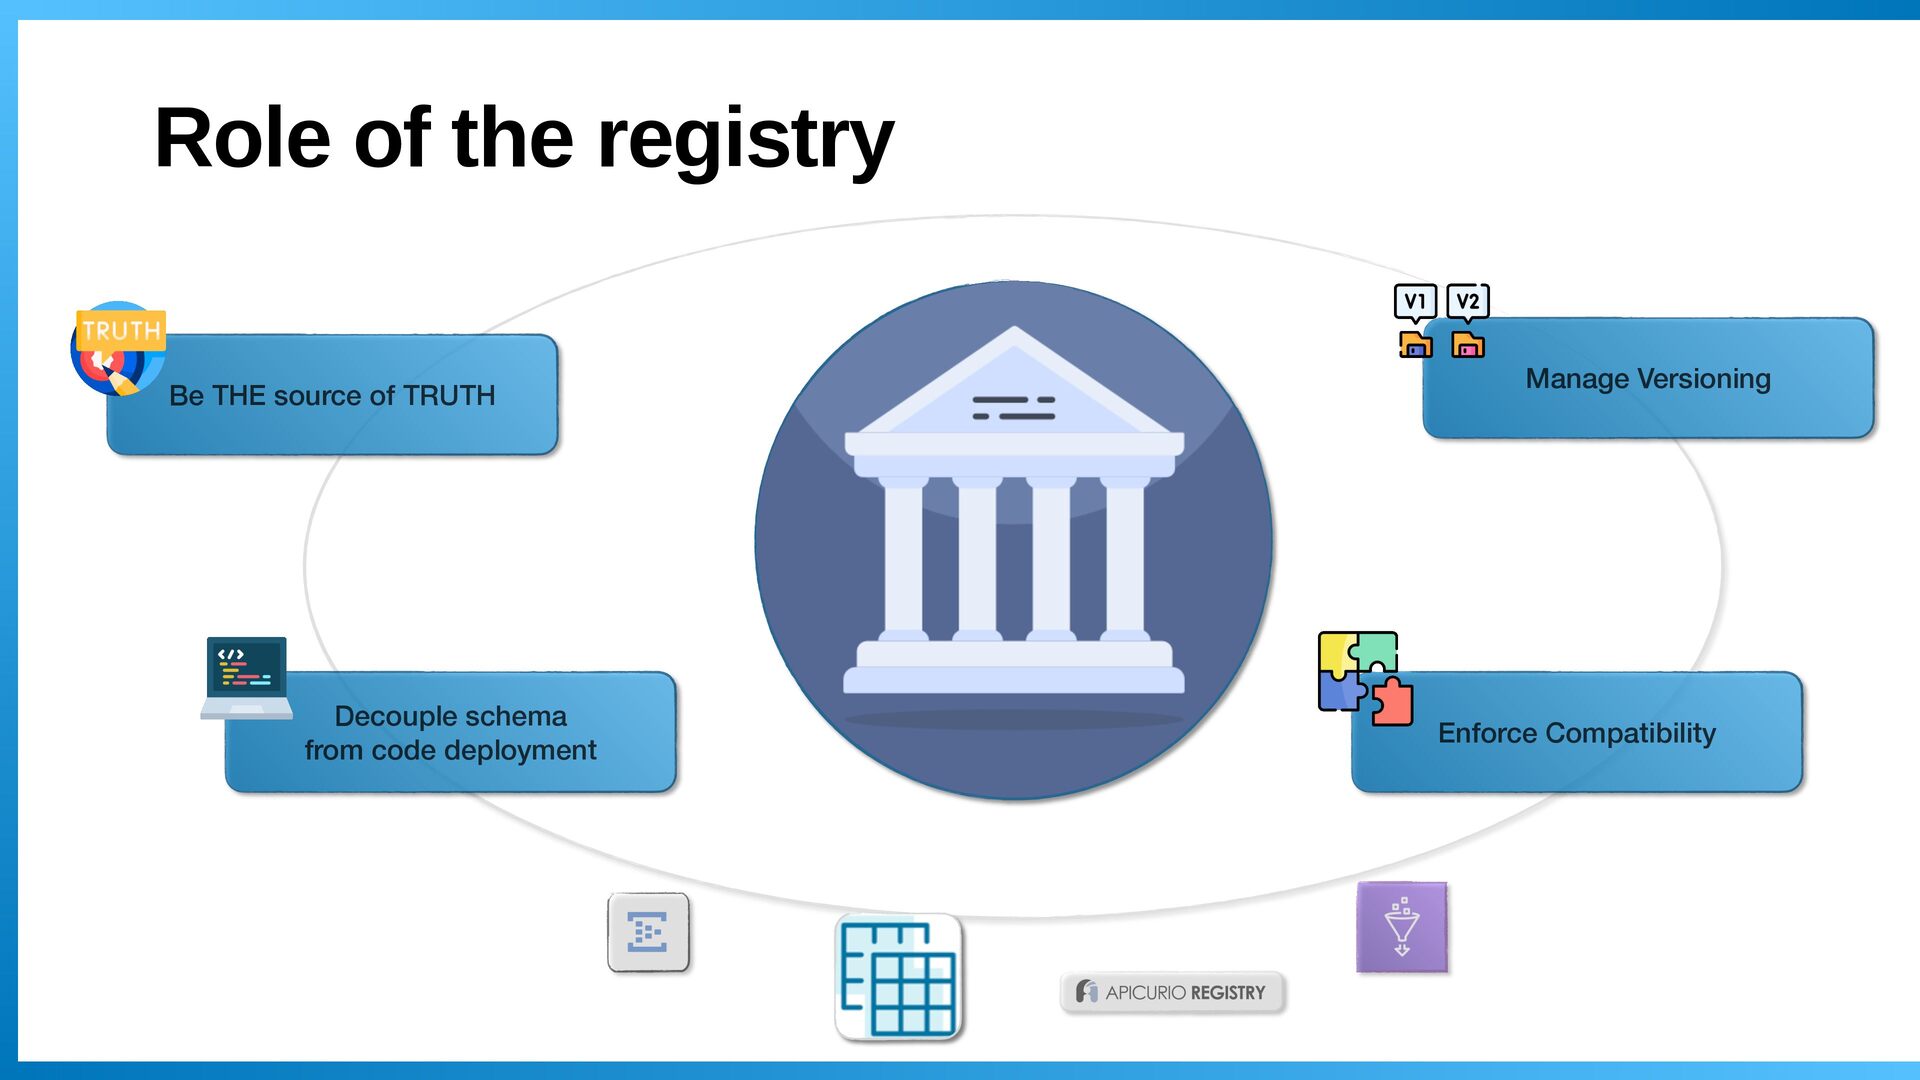
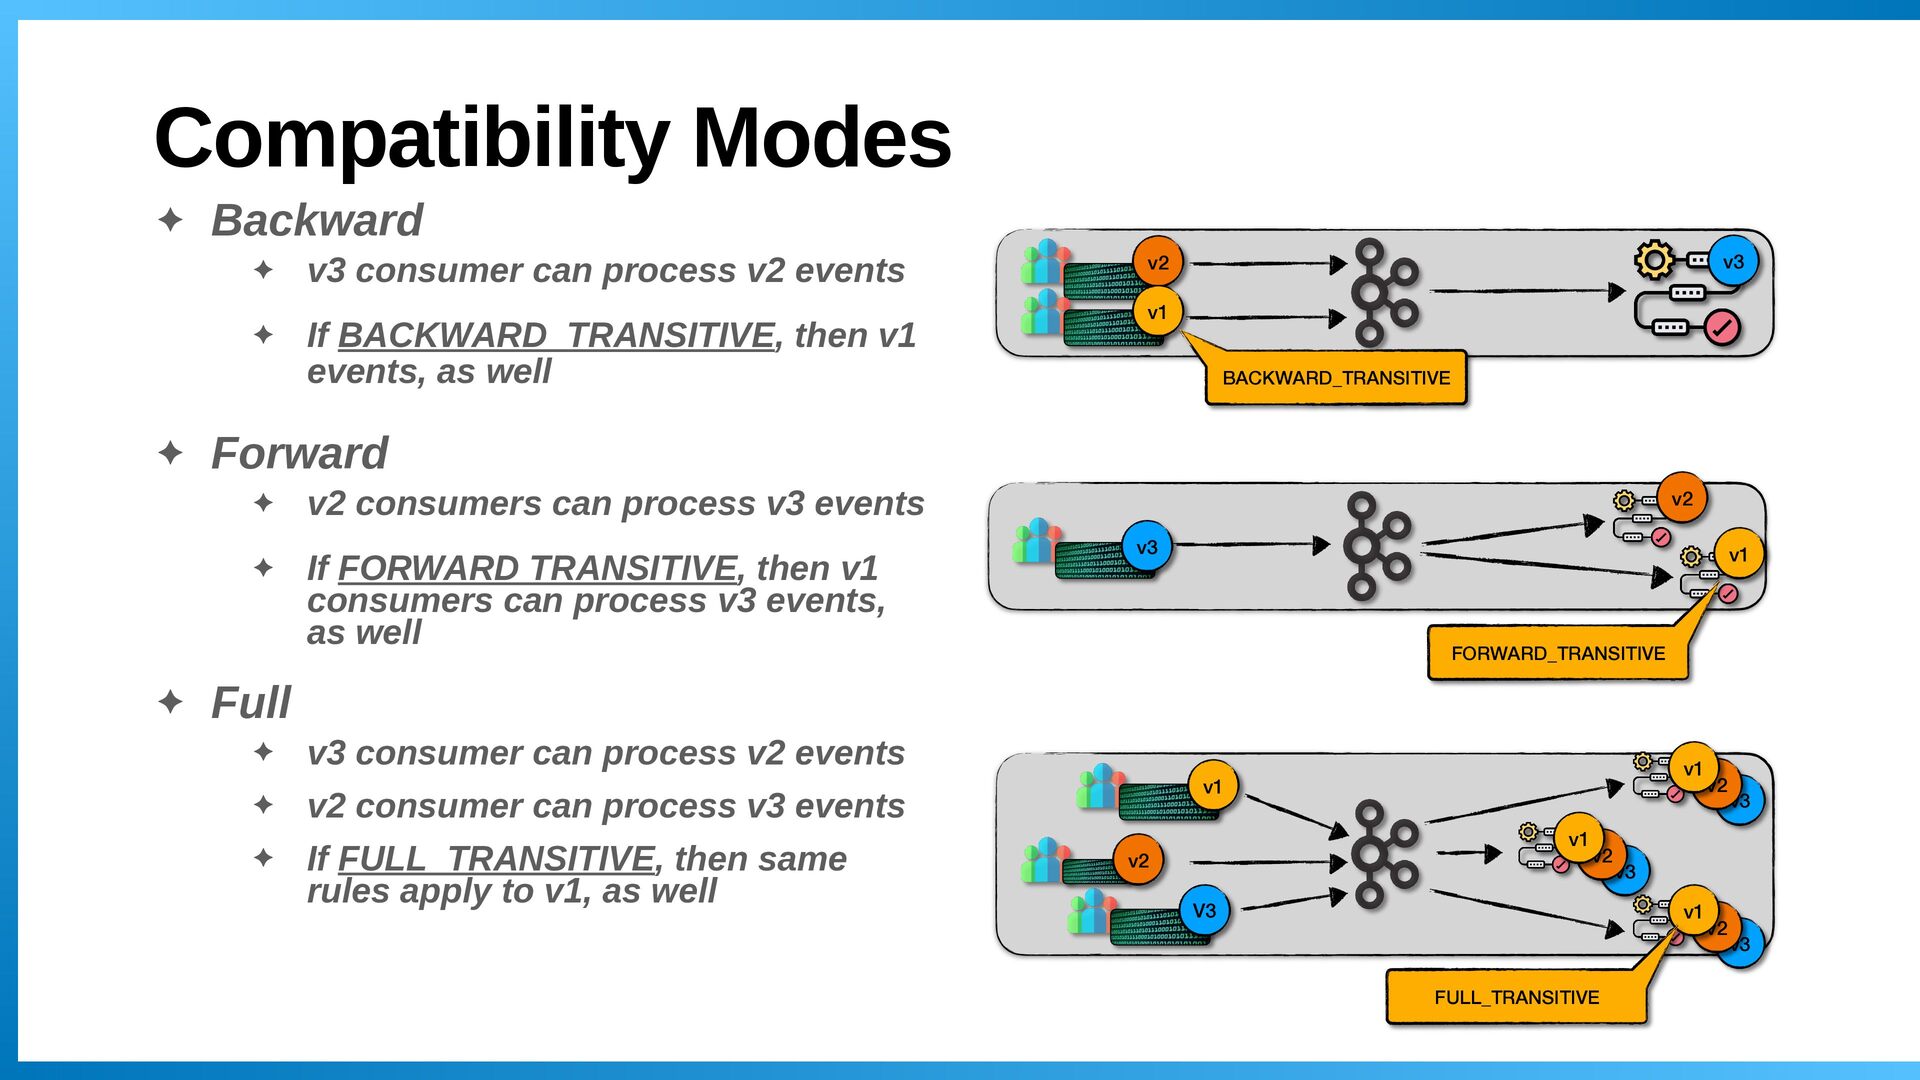
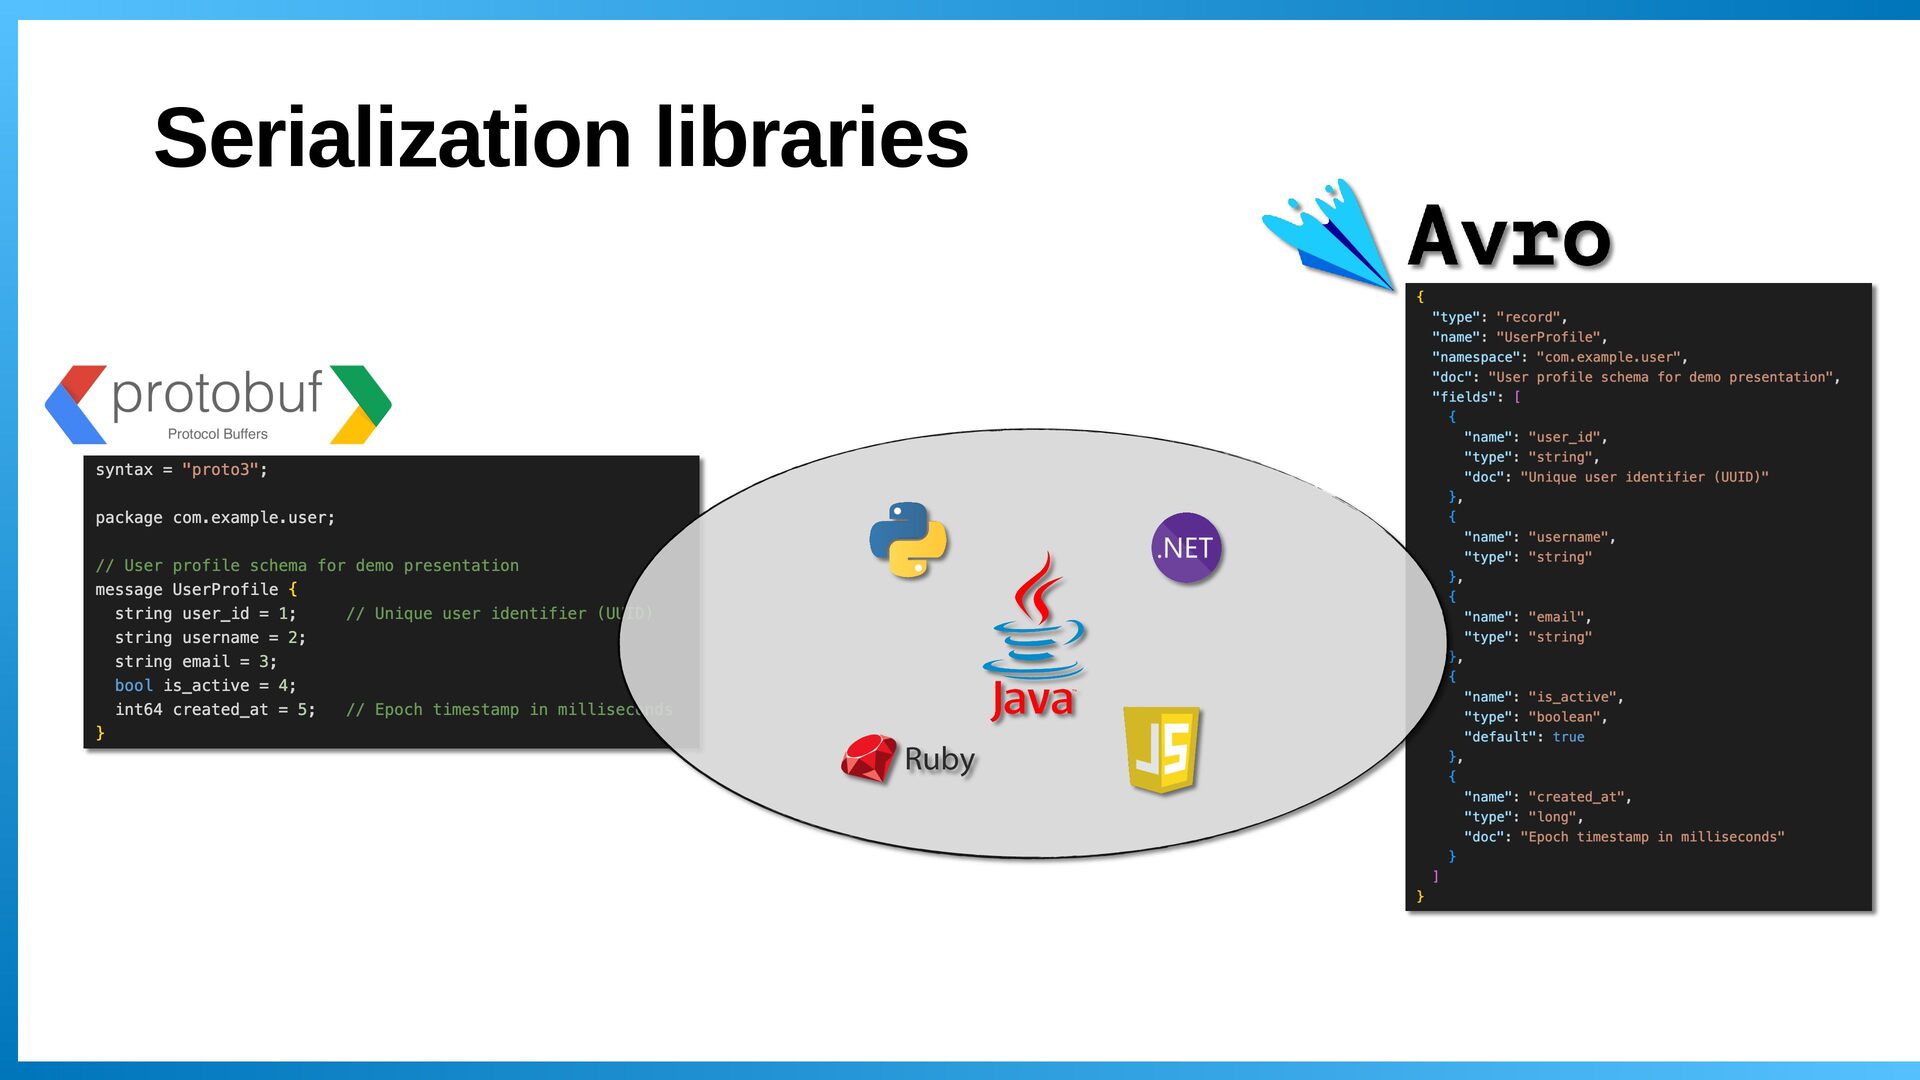
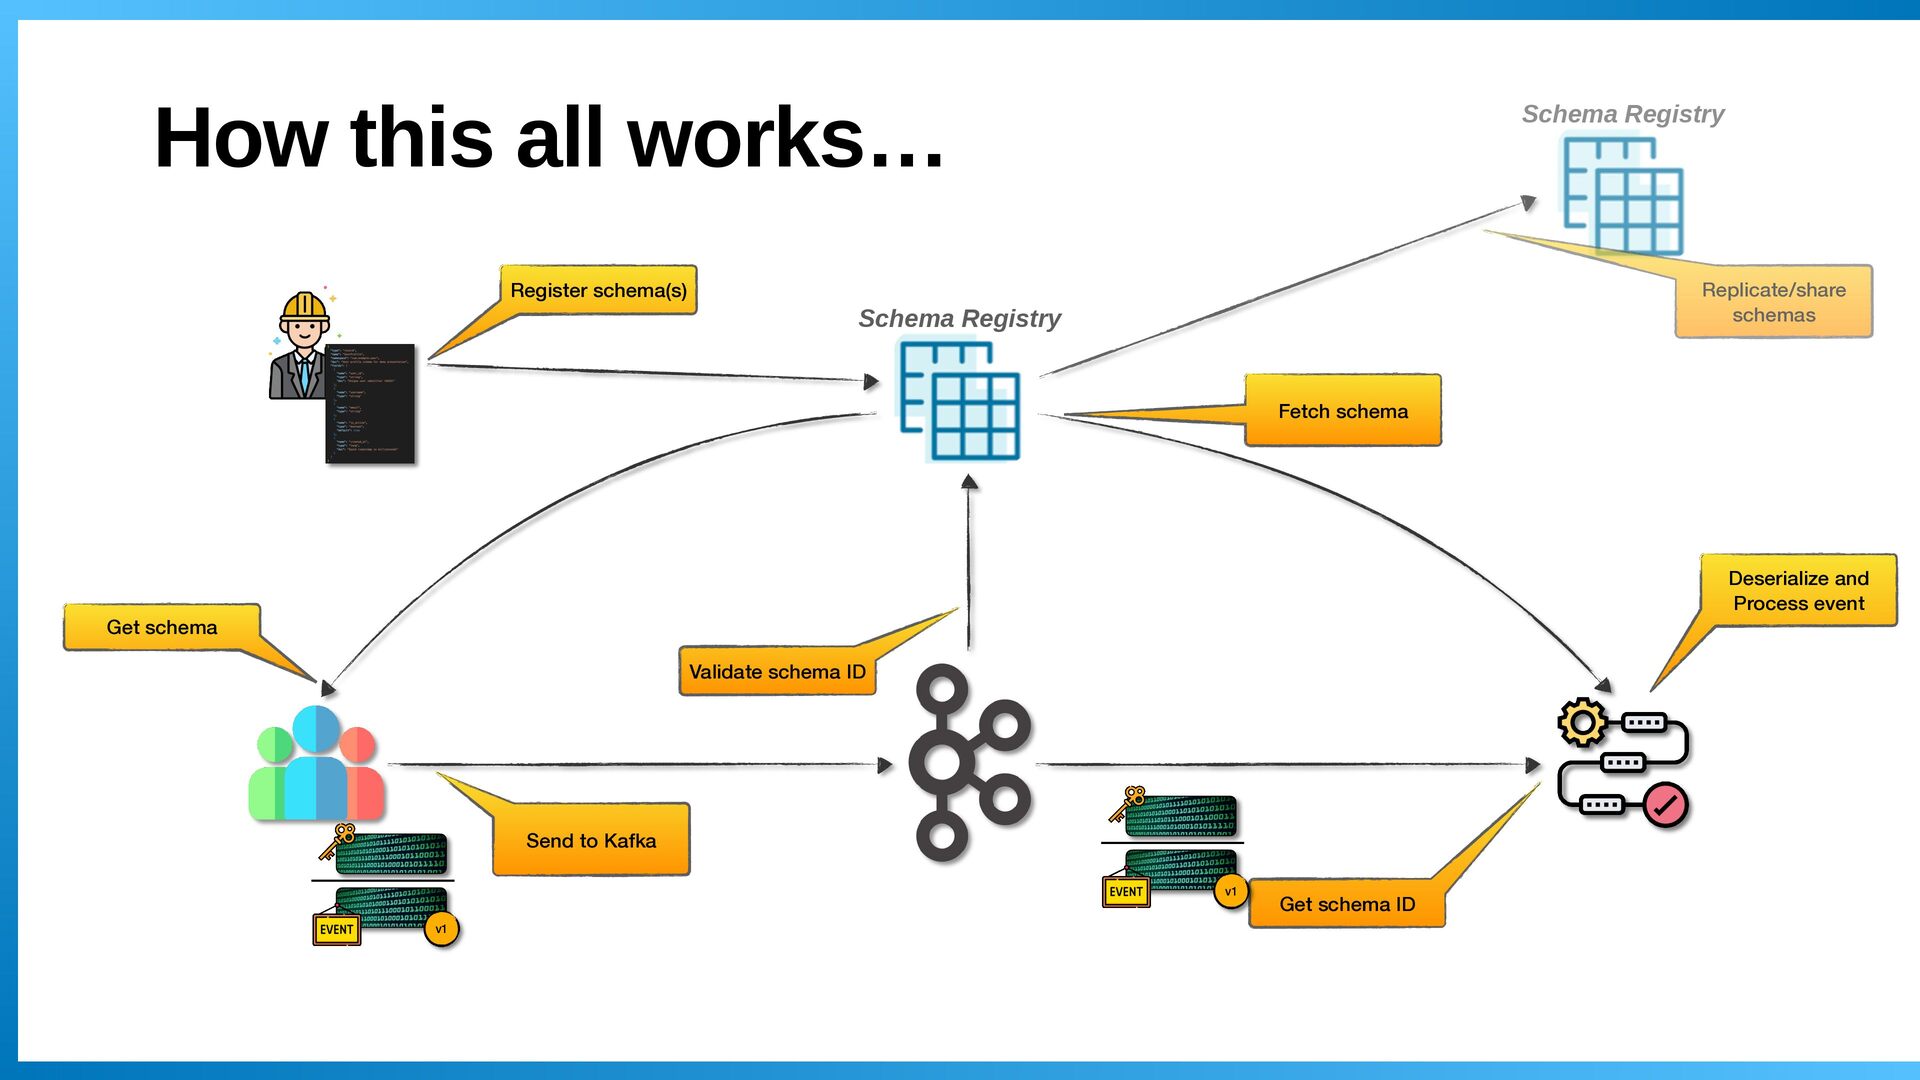
In this session, we'll define data contracts and how to enforce them at the source - the applications that produce events. We’ll cover the practice of using a schema registry - supporting popular serialization formats like Apache Avro and Google Protobuf - to design events in the terminology of our business domain. Because data structures change over time, let’s discuss safe schema evolution practices. Then we’ll utilize these contracts with schema registry-aware producer and consumer code. We’ll end our time by looking at how smart CI/CD pipelines and build-time checks can add an extra layer of defense against the costly problem of poison data. It’s time to stop guessing and start governing.
Join us to learn how to move validation upstream and transform your event streams into high-quality, discoverable data products. You’ll walk away with a practical blueprint for enforcing schema integrity and automating evolution - ensuring your data streams are a trusted asset.


 sandonjacobs
 _mossann_t
 taromatsui_cccmkhd
 minorun365
 ymotongpoo
 k1nakayama
 mu7889yoon
 soudai
 yama3133
 harappa80
 daikiokazaki
 zozotech
 matsuji
 pauljervisheath
 inesmontani
 ianozsvald
 axbom
 keavy
 auna
 carmenintech
 productmarketing
 katarinadahlin
 kimpetersen
 panda_program
 lara