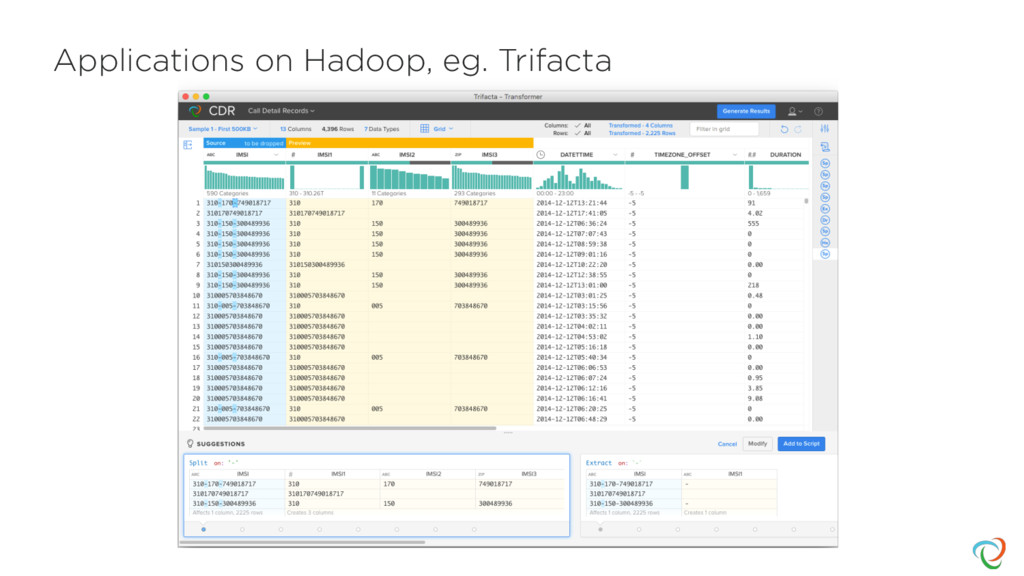
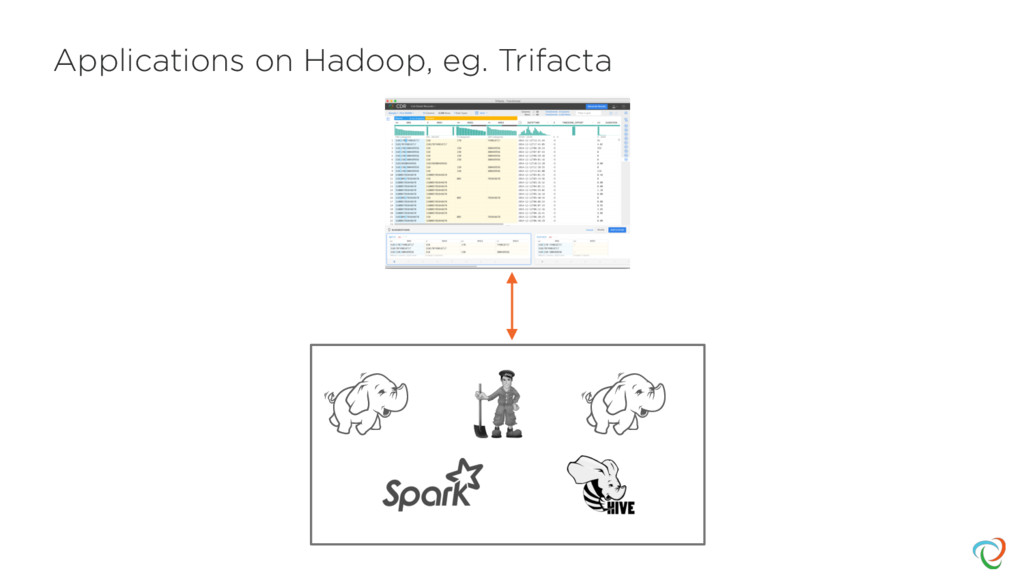
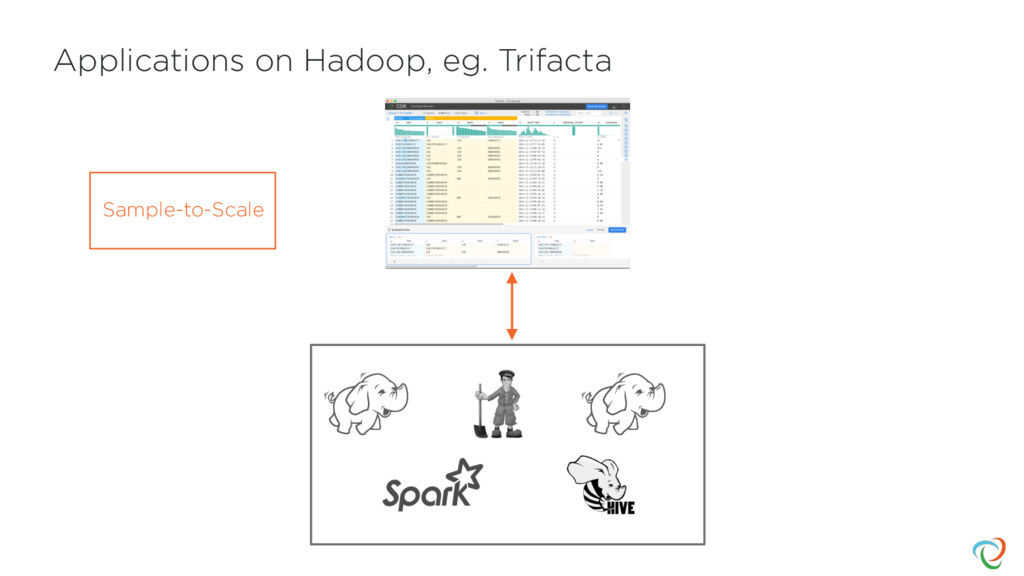
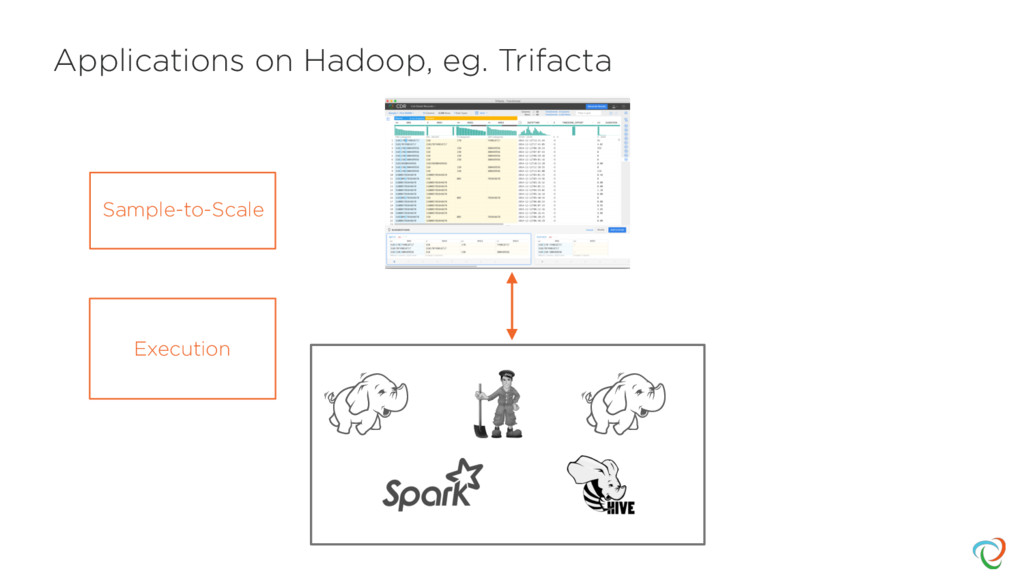
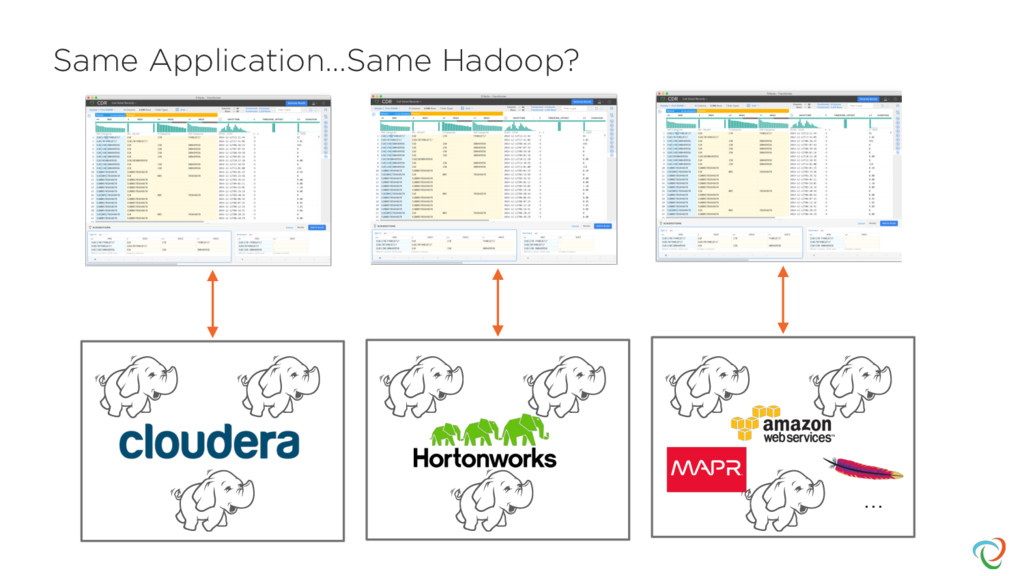
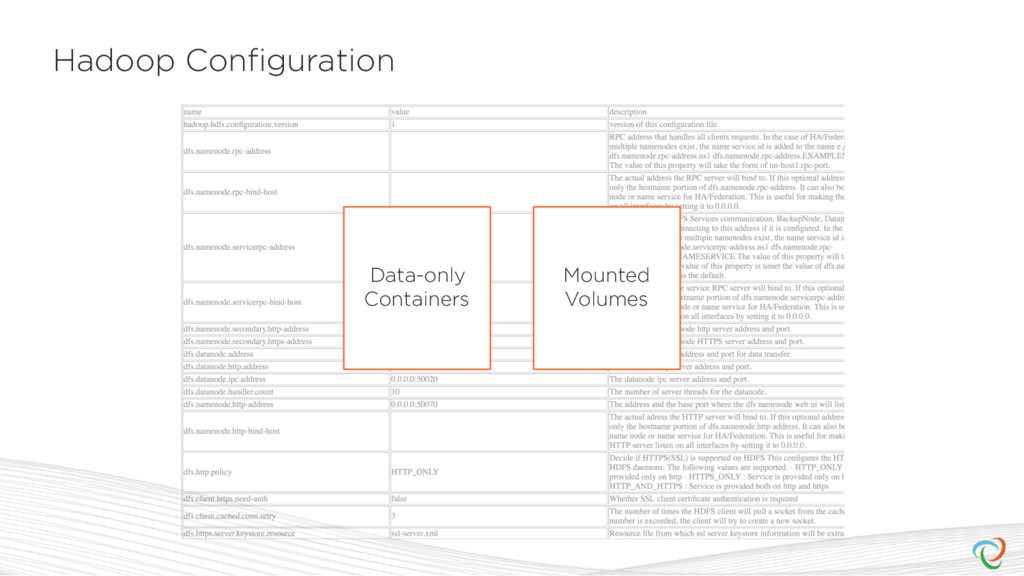
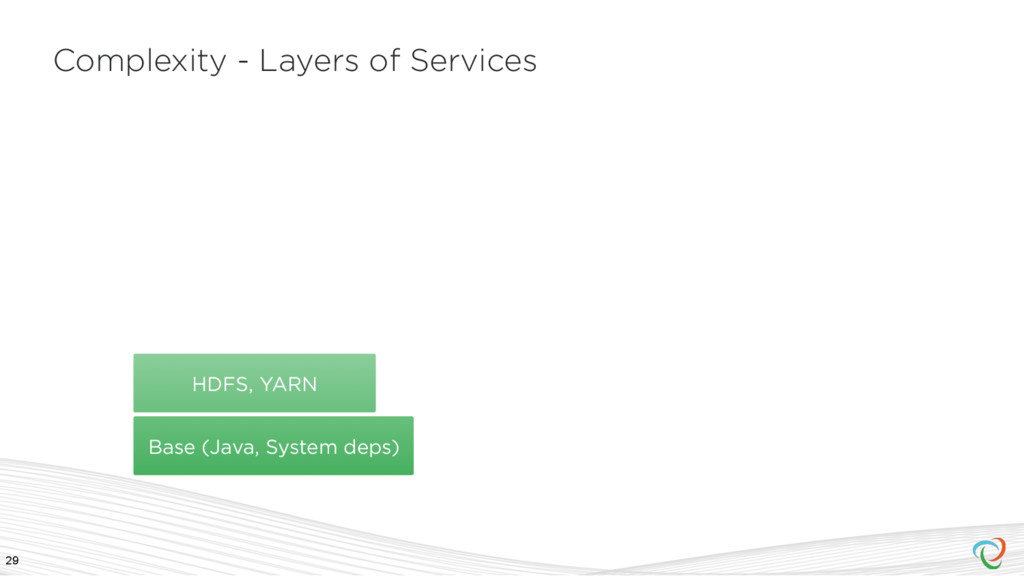
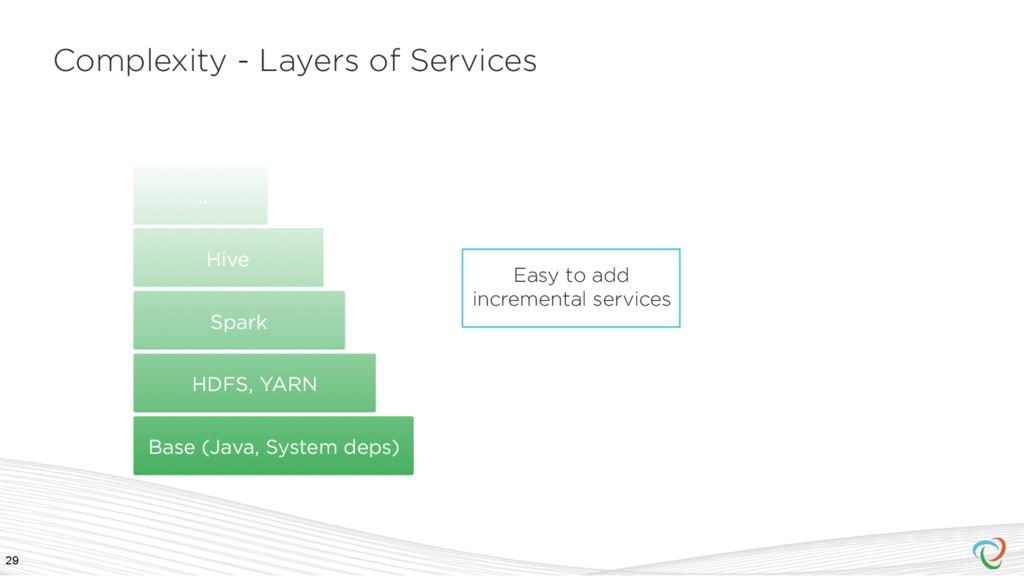
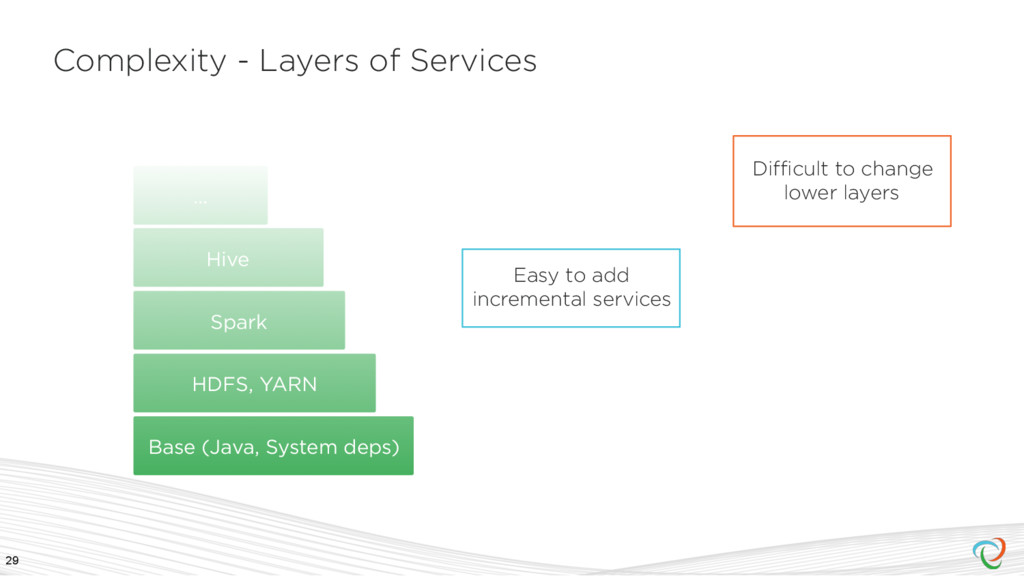
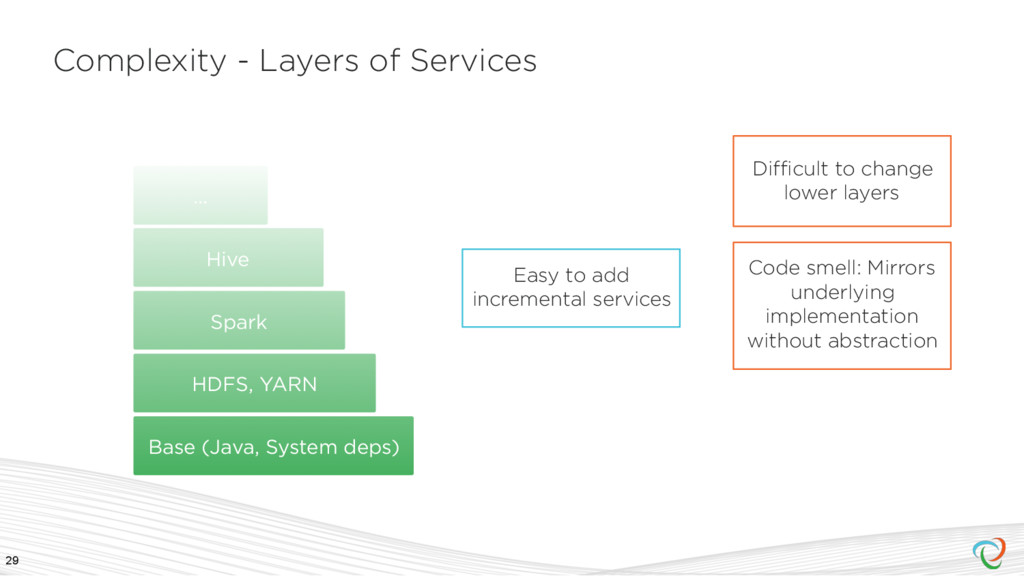
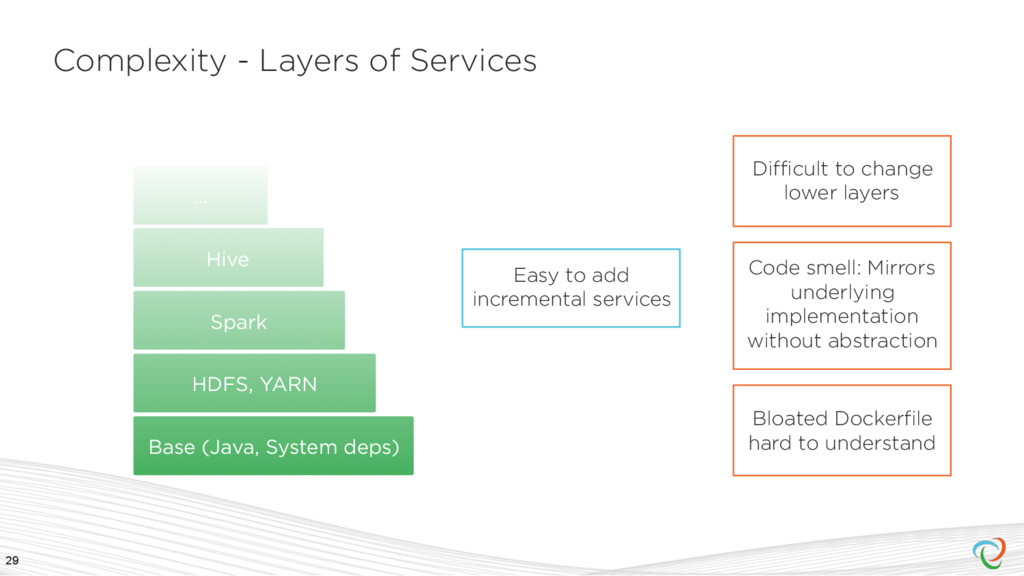
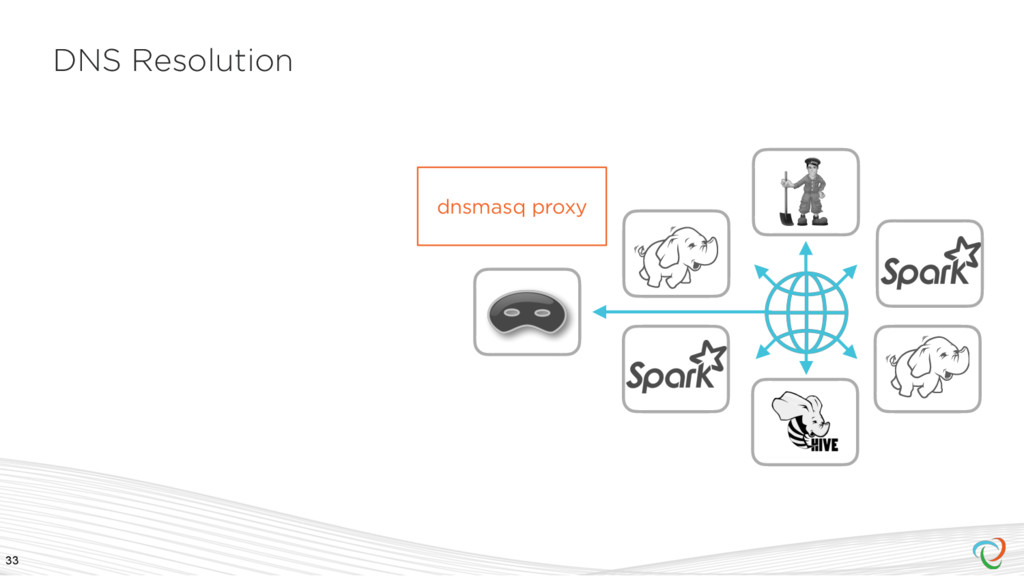
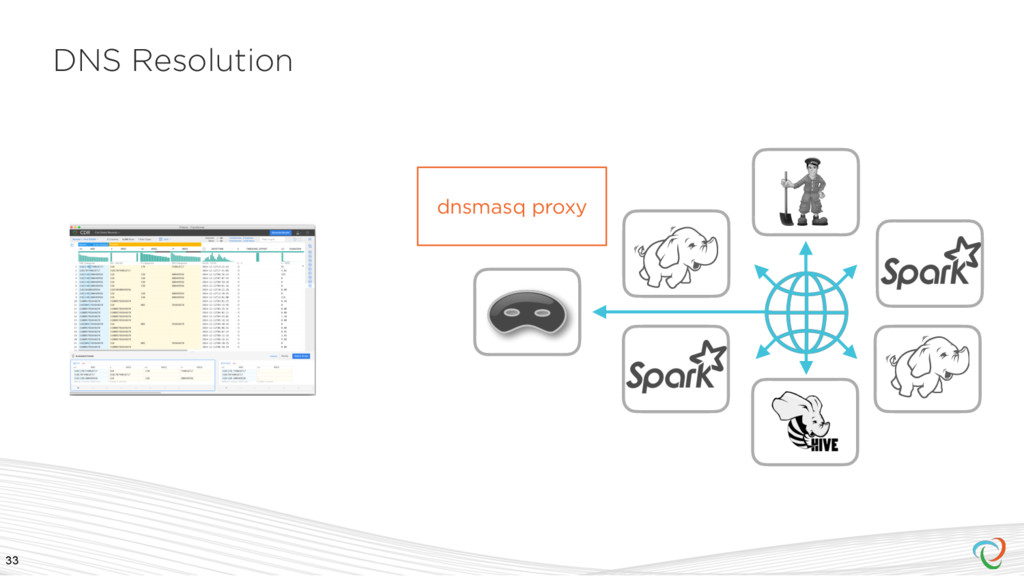
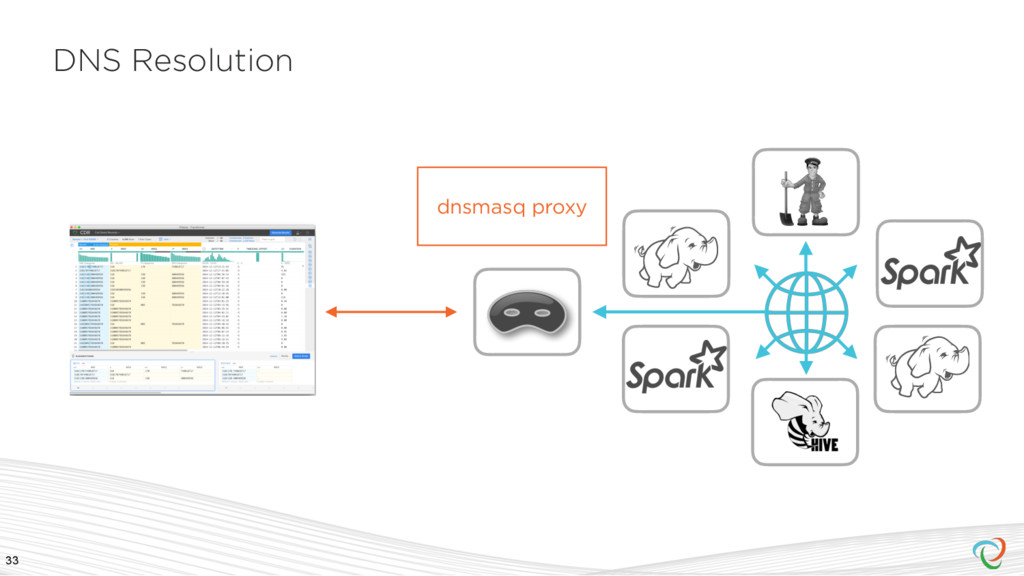
If you are building applications for the big data world, you’ll need access to a variety of big data platform configurations during development and continuous integration. These deployments need to scale down to an individual laptop or scale up to a realistic test cluster, and they need to be interchangeable with quick setup and teardown. Chad Metcalf and Seshadri Mahalingam explore several strategies for meeting this challenge by containerizing and deploying Hadoop services in Docker. Chad and Seshadri share lessons learned from solutions that they built, some which have been open sourced, and dig into topics including how to manage the images lifecycle, configuration, persistent data, multihost networking with Docker Engine and Swarm, and creating different deployment environments with Docker Machine.
http://conferences.oreilly.com/strata/hadoop-big-data-eu/public/schedule/detail/49727


 nealle
 occhi
 grimoh
 kworkdev
 makocchi
 kakehashi
 raspython3
 greenmidori
 nttcom
 persolserverworks
 shuta13
 riyaamemiya
 panda_program
 baasie
 jonoalderson
 eileencodes
 matthewcrist
 kevinliebholz
 mfonobong
 portentint
 asonas
 rkendrick25
 pedronauck