Share
Embed
K8s Pod Autoscaling with Application-Aware AI
How you can use AI to optimize Kubernetes workloads to reduce resources and costs without impacting application performance and reliability. Identify the workload optimal configurations in terms of CPU and memory resources (requests and limits) and HPA scaling thresholds.
Akamas Lightning talk at KubeCon NA 2023
Stefano Doni
November 17, 2023
Transcript
23 slides
-
© 2023 Akamas • All Rights Reserved • Confidential K8s
Pod Autoscaling with Application-Aware AI 1 KubeCon NA 2023 Stefano Doni (Akamas CTO) -
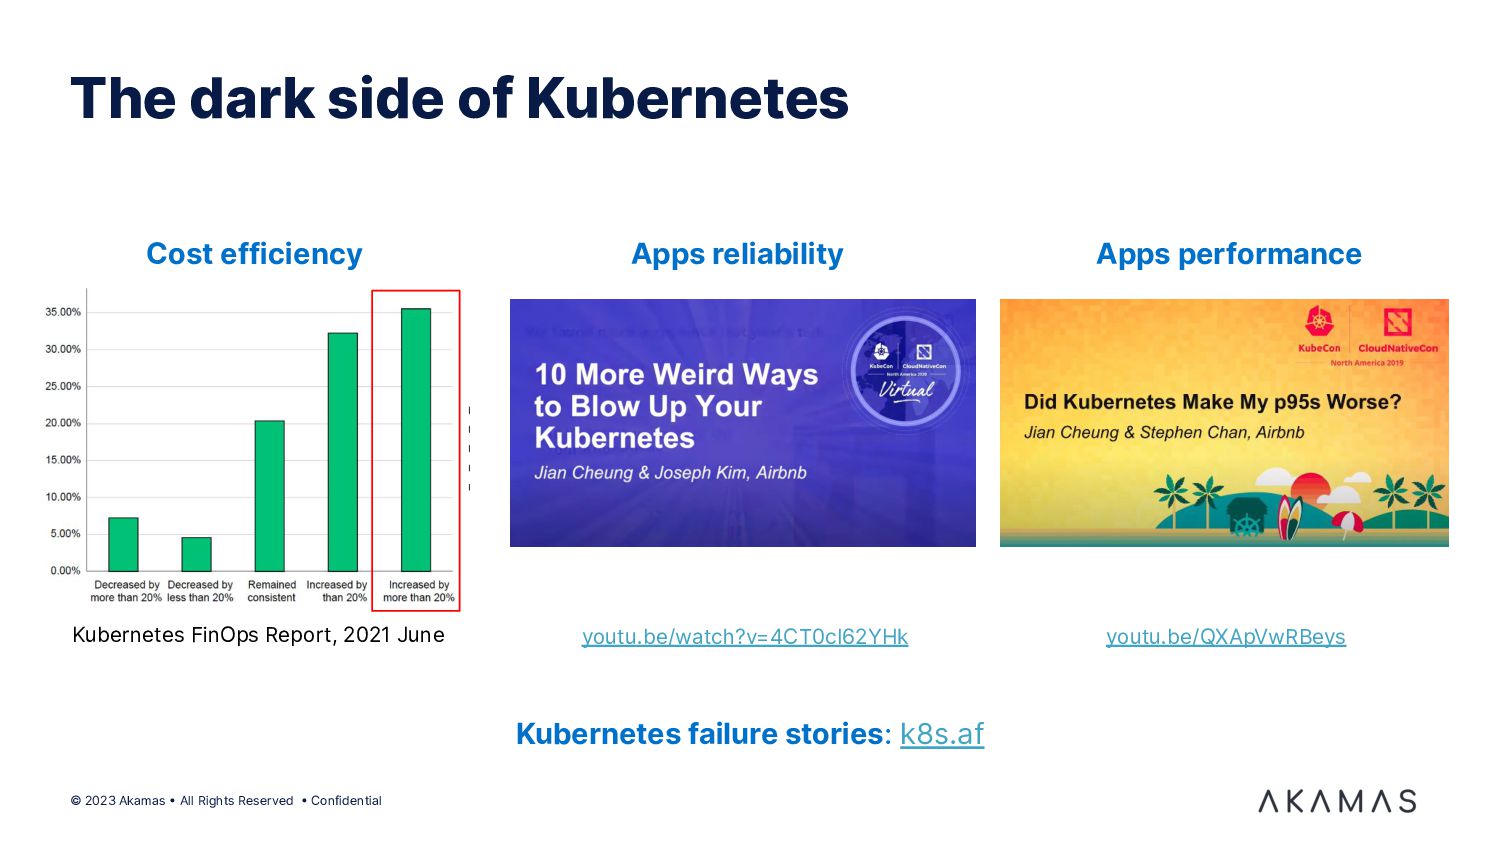
© 2023 Akamas • All Rights Reserved • Confidential The
dark side of Kubernetes youtu.be/watch?v=4CT0cI62YHk youtu.be/QXApVwRBeys Cost efficiency Apps reliability Apps performance Kubernetes FinOps Report, 2021 June Kubernetes failure stories: k8s.af -
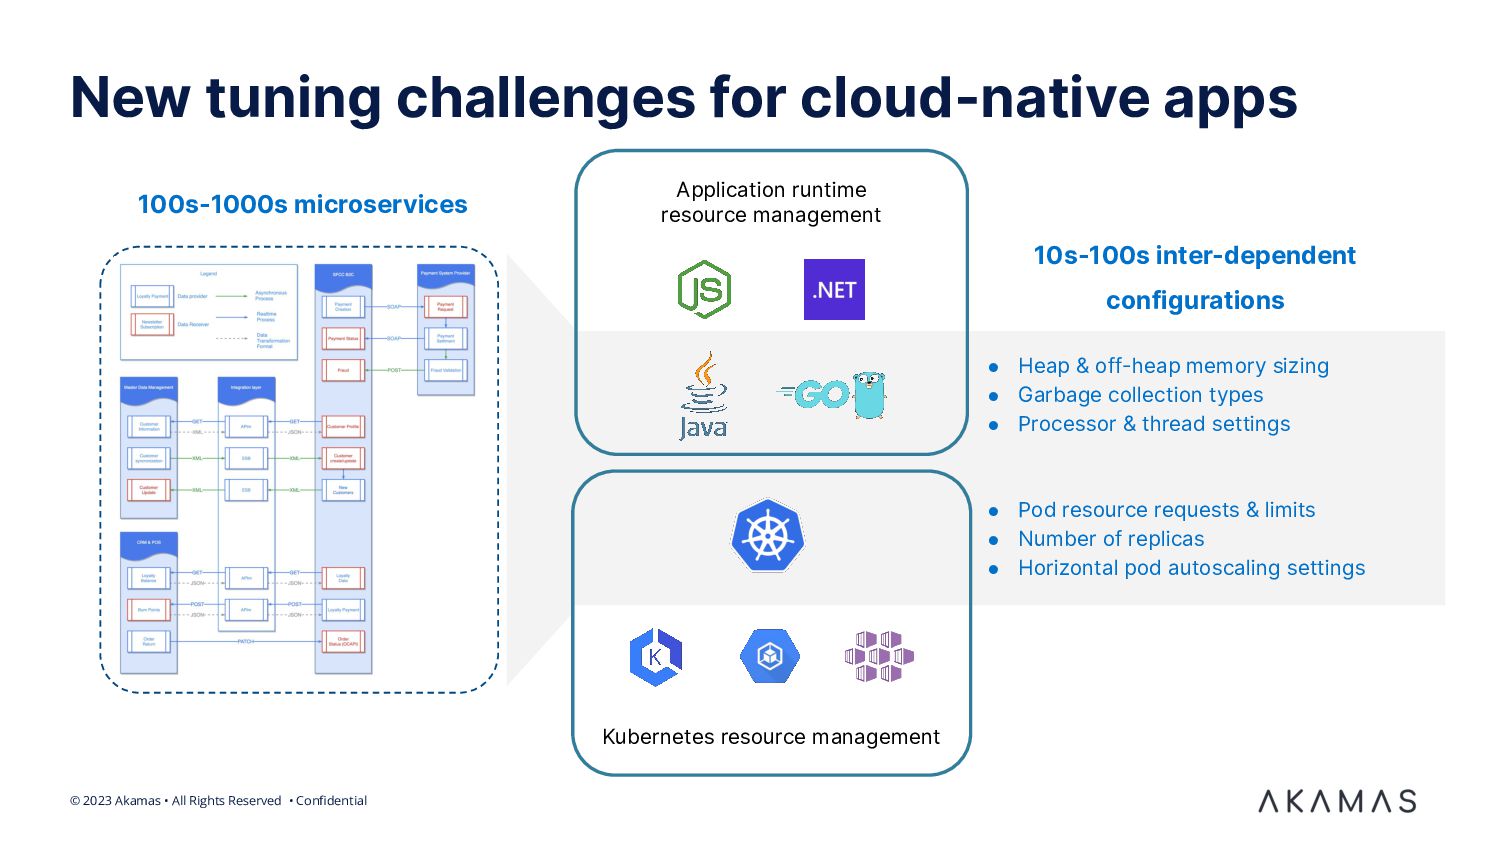
© 2023 Akamas • All Rights Reserved • Confidential Application
runtime resource management Kubernetes resource management • Heap & off-heap memory sizing • Garbage collection types • Processor & thread settings • Pod resource requests & limits • Number of replicas • Horizontal pod autoscaling settings New tuning challenges for cloud-native apps 100s-1000s microservices 10s-100s inter-dependent configurations -
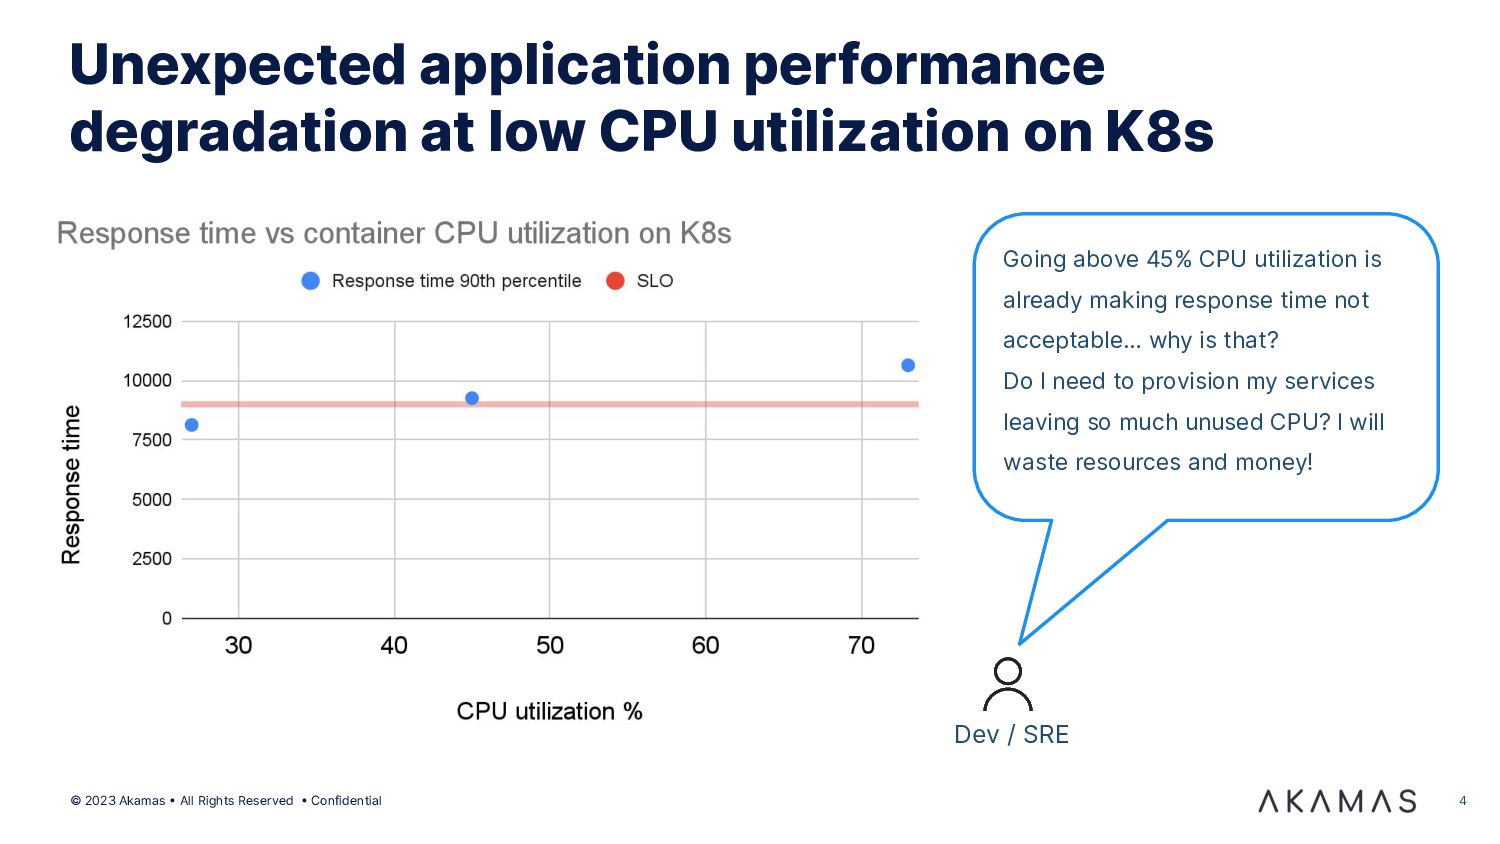
© 2023 Akamas • All Rights Reserved • Confidential Unexpected
application performance degradation at low CPU utilization on K8s 4 Dev / SRE Going above 45% CPU utilization is already making response time not acceptable… why is that? Do I need to provision my services leaving so much unused CPU? I will waste resources and money! -
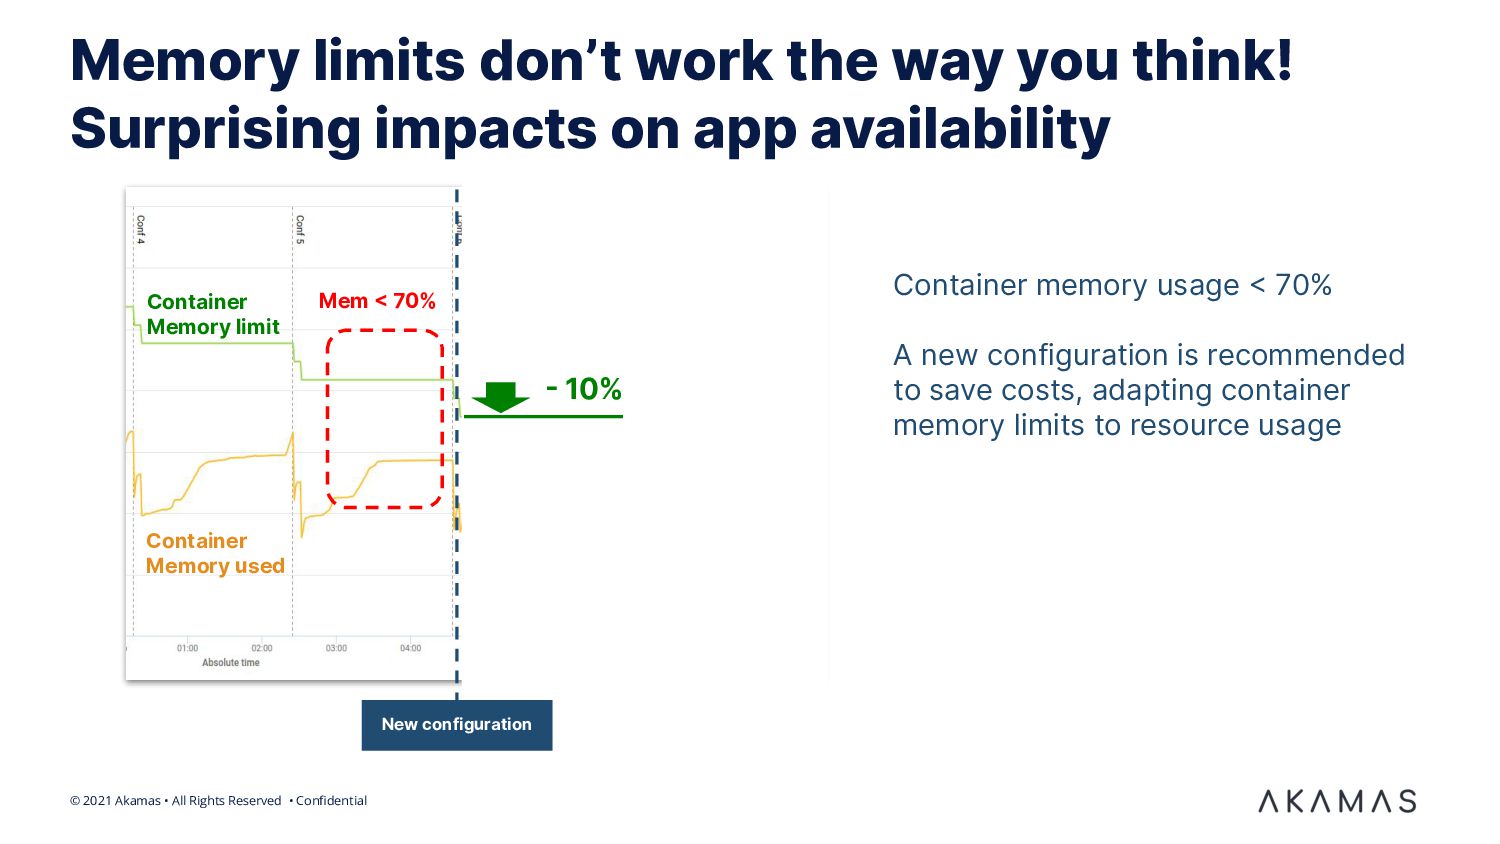
© 2021 Akamas • All Rights Reserved • Confidential Memory
limits don’t work the way you think! Surprising impacts on app availability Container Memory limit Container Memory used Container memory usage < 70% A new configuration is recommended to save costs, adapting container memory limits to resource usage New configuration - 10% Mem < 70% -
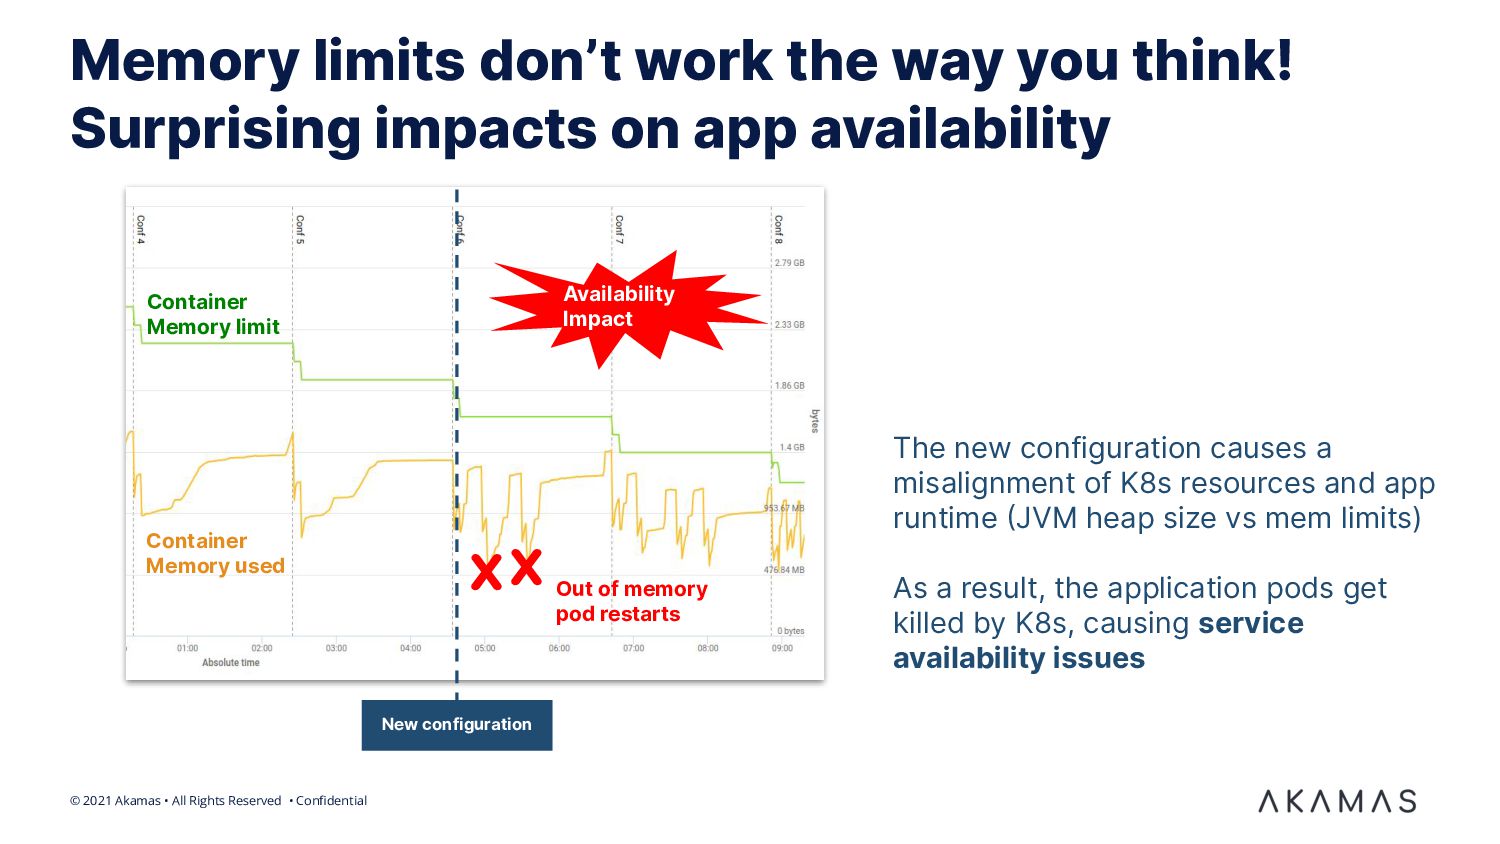
© 2021 Akamas • All Rights Reserved • Confidential Container
Memory limit New configuration XX Out of memory pod restarts The new configuration causes a misalignment of K8s resources and app runtime (JVM heap size vs mem limits) As a result, the application pods get killed by K8s, causing service availability issues Container Memory used Memory limits don’t work the way you think! Surprising impacts on app availability Availability Impact -
© 2023 Akamas • All Rights Reserved • Confidential The
optimization platform -
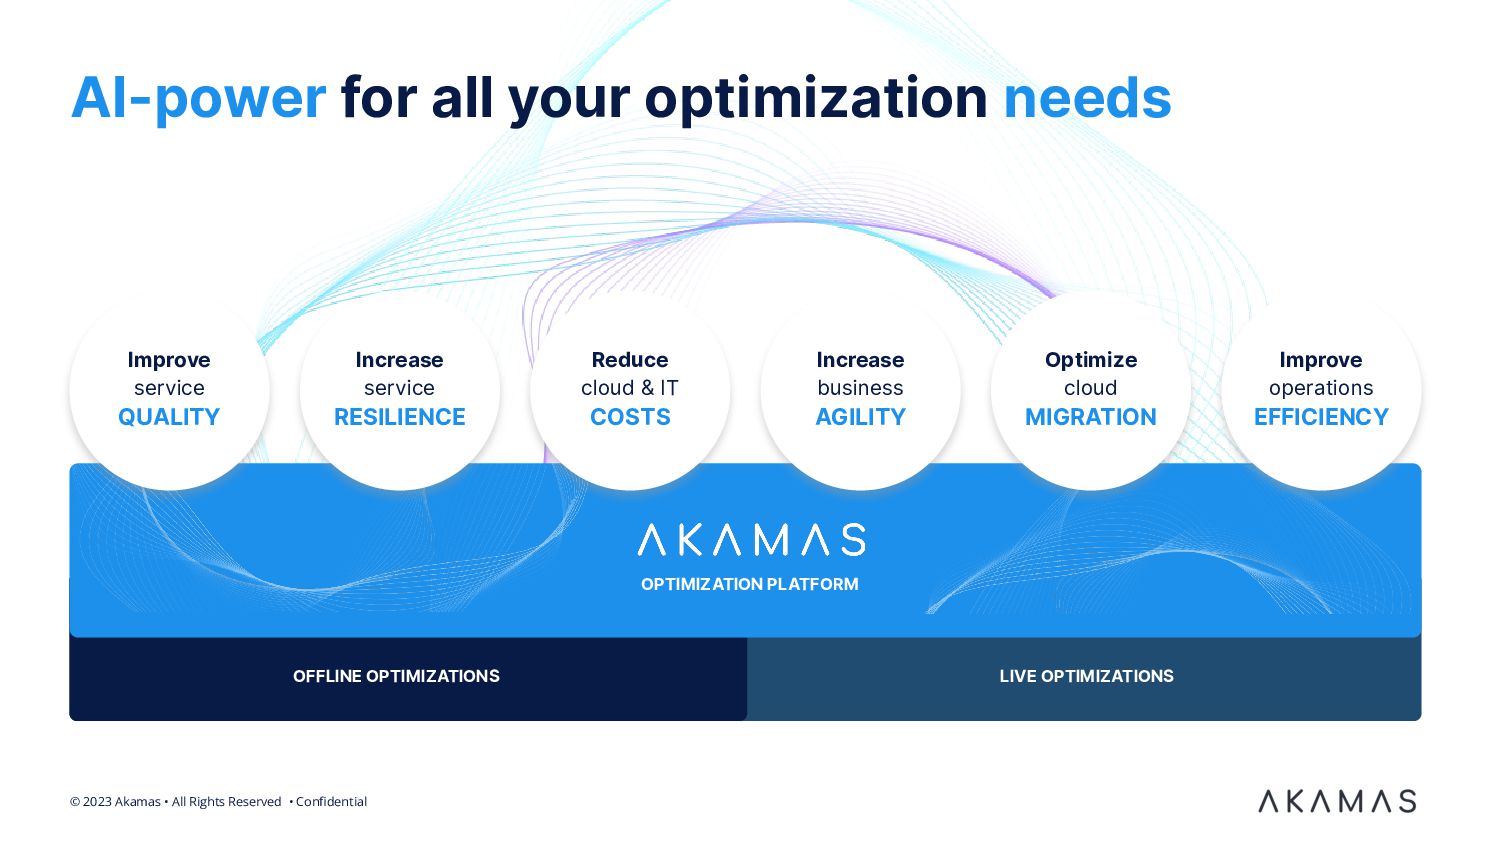
© 2023 Akamas • All Rights Reserved • Confidential LIVE
OPTIMIZATIONS AI-power for all your optimization needs Increase business AGILITY Optimize cloud MIGRATION Improve operations EFFICIENCY Reduce cloud & IT COSTS Improve service QUALITY Increase service RESILIENCE OFFLINE OPTIMIZATIONS OPTIMIZATION PLATFORM -
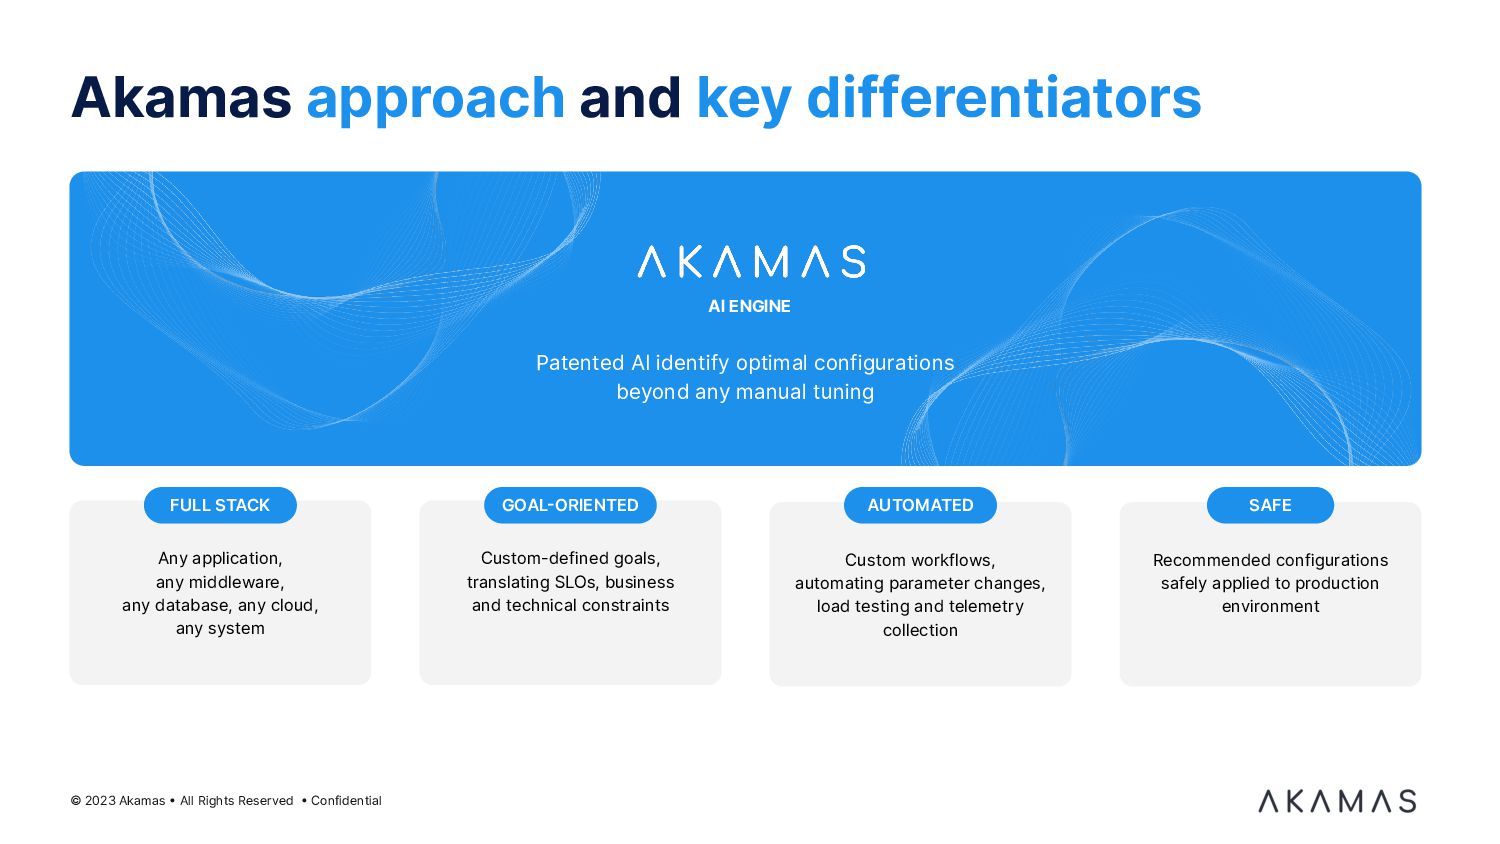
© 2023 Akamas • All Rights Reserved • Confidential Akamas
approach and key differentiators Recommended configurations safely applied to production environment SAFE Custom workflows, automating parameter changes, load testing and telemetry collection AUTOMATED Custom-defined goals, translating SLOs, business and technical constraints GOAL-ORIENTED Any application, any middleware, any database, any cloud, any system FULL STACK Patented AI identify optimal configurations beyond any manual tuning AI ENGINE -
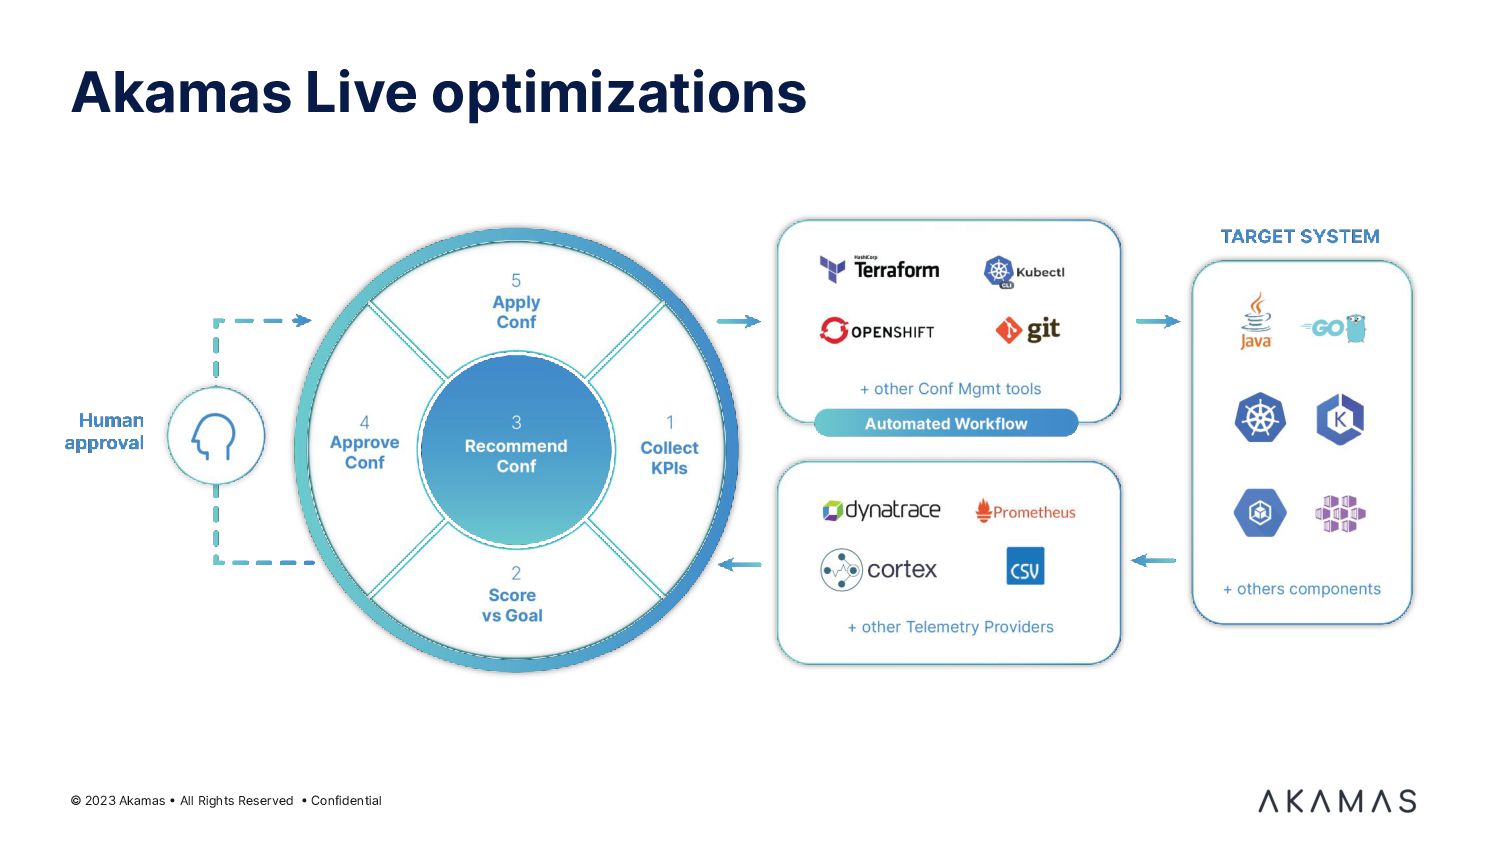
© 2023 Akamas • All Rights Reserved • Confidential Akamas
Live optimizations -
© 2023 Akamas • All Rights Reserved • Confidential Use
cases: Optimizing K8s pod autoscaling with Akamas AI -
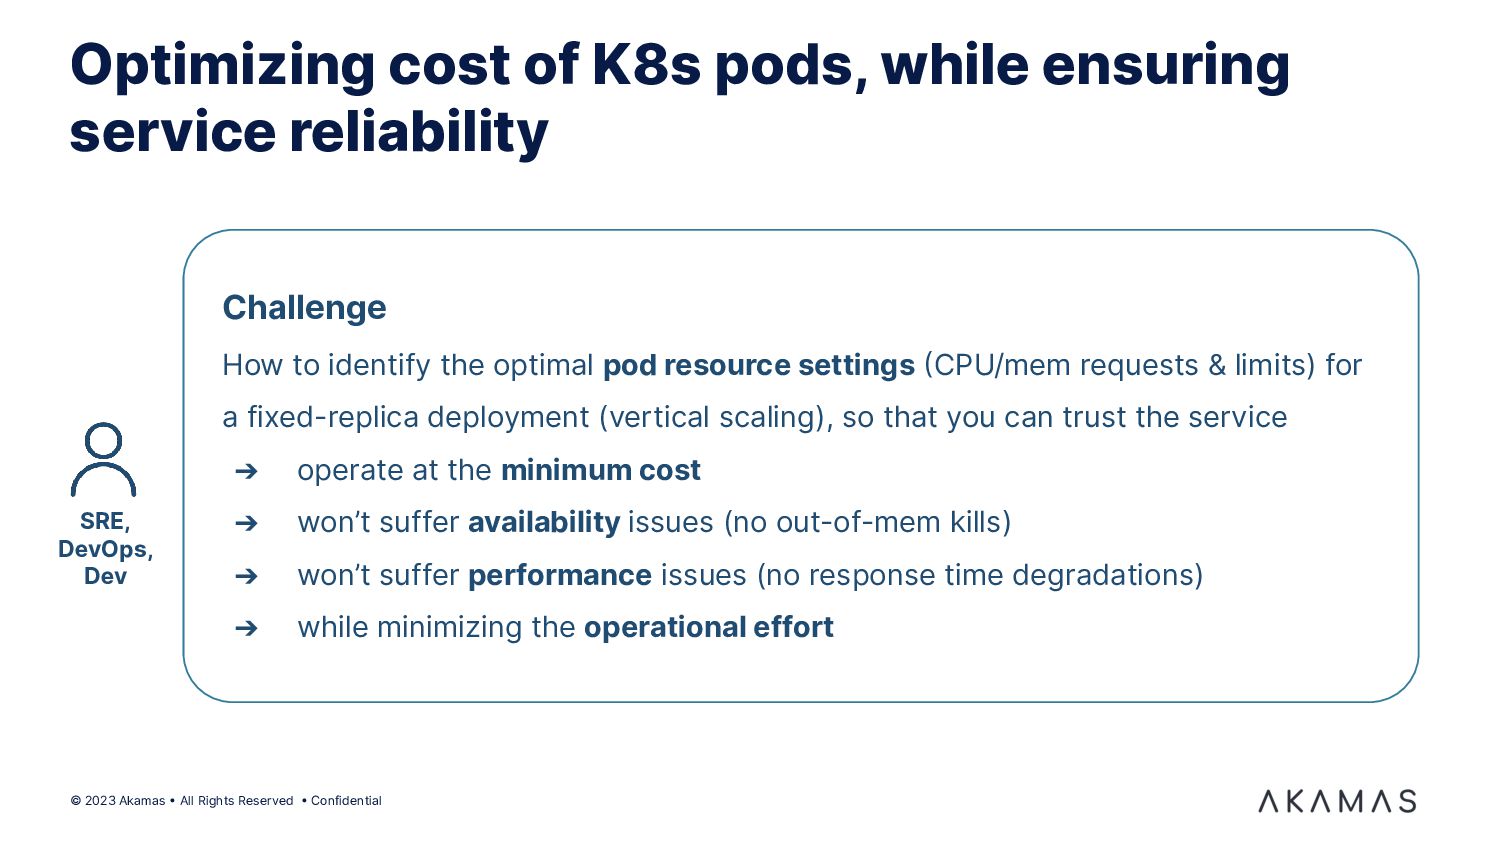
© 2023 Akamas • All Rights Reserved • Confidential Optimizing
cost of K8s pods, while ensuring service reliability Challenge How to identify the optimal pod resource settings (CPU/mem requests & limits) for a fixed-replica deployment (vertical scaling), so that you can trust the service ➔ operate at the minimum cost ➔ won’t suffer availability issues (no out-of-mem kills) ➔ won’t suffer performance issues (no response time degradations) ➔ while minimizing the operational effort SRE, DevOps, Dev -
© 2023 Akamas • All Rights Reserved • Confidential Optimization
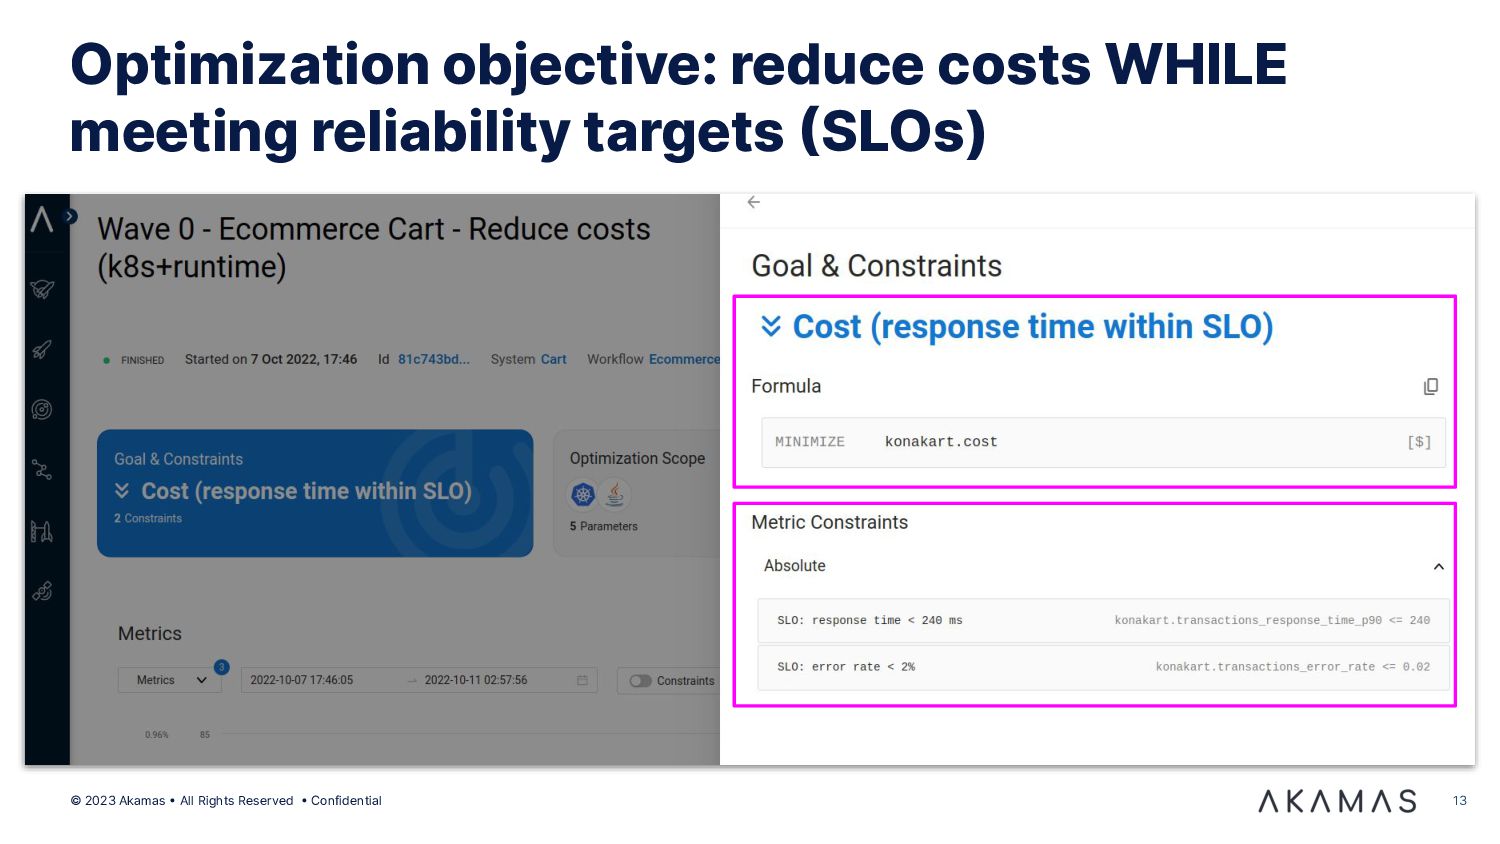
objective: reduce costs WHILE meeting reliability targets (SLOs) 13 -
© 2023 Akamas • All Rights Reserved • Confidential Optimization
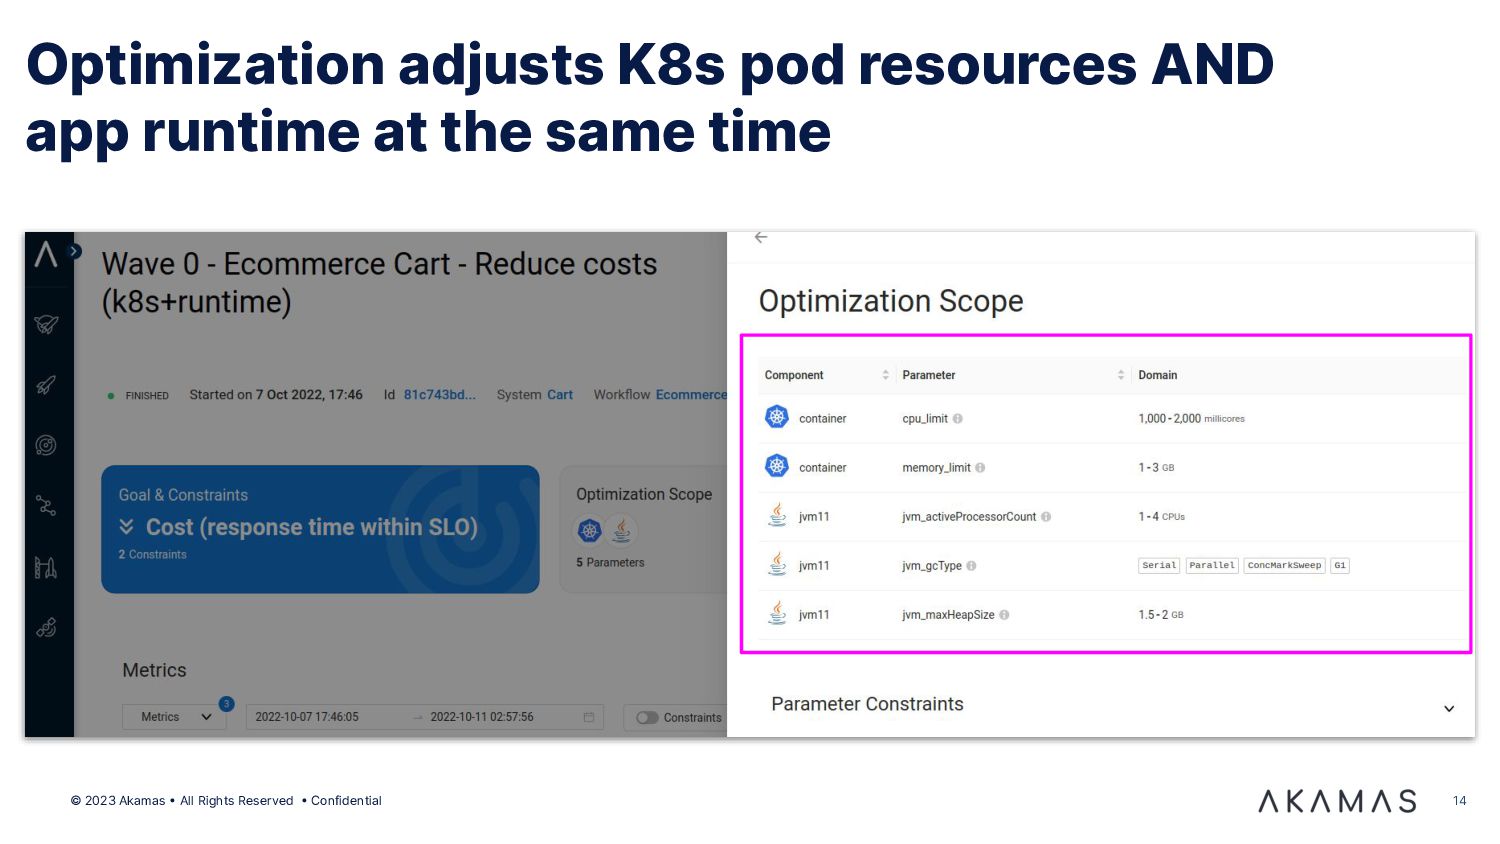
adjusts K8s pod resources AND app runtime at the same time 14 -
© 2023 Akamas • All Rights Reserved • Confidential Result:
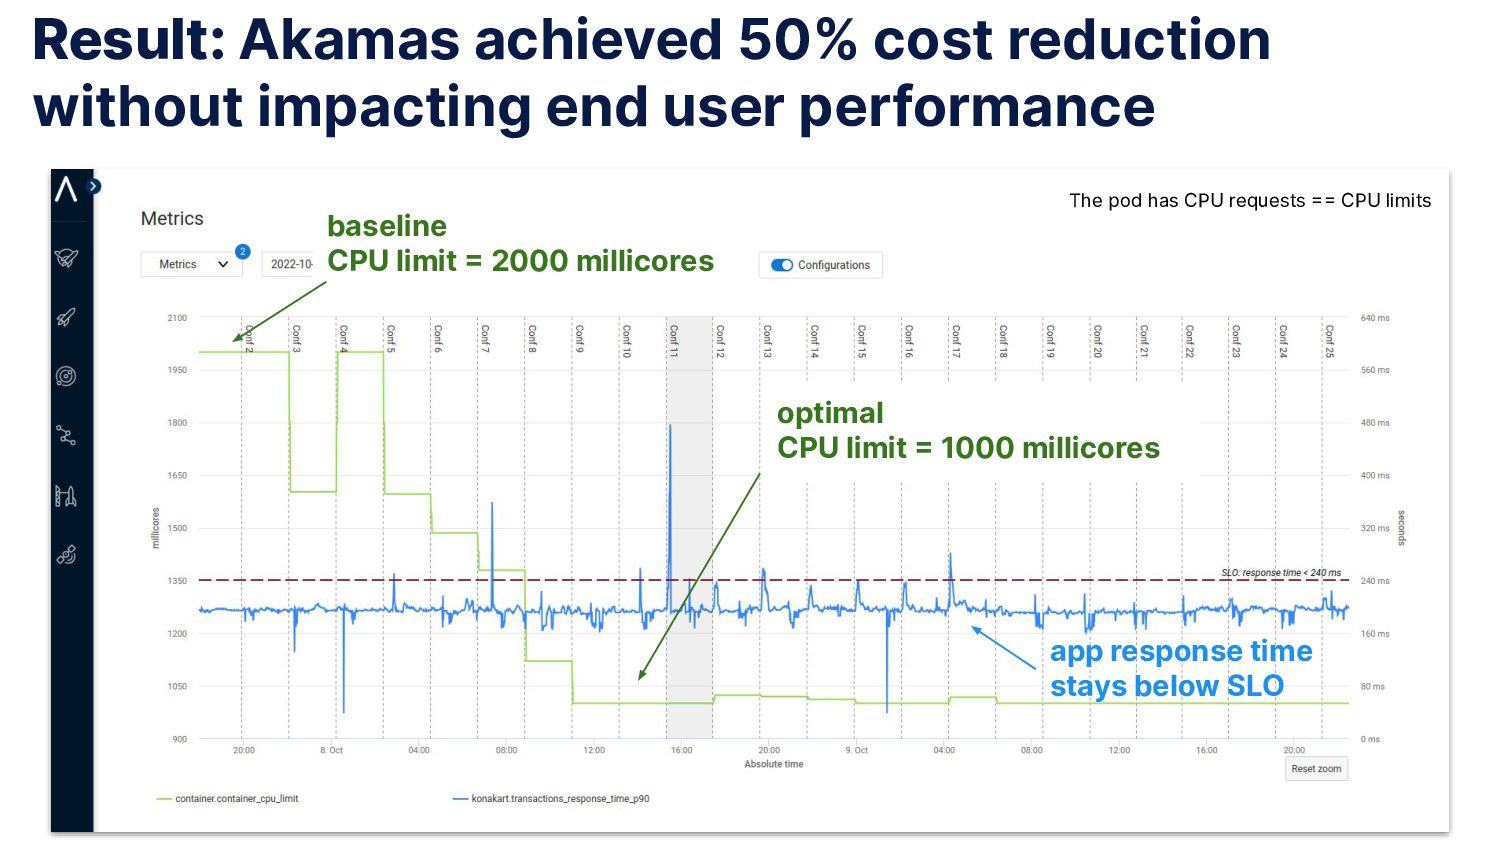
Akamas achieved 50% cost reduction without impacting end user performance baseline CPU limit = 2000 millicores app response time stays below SLO optimal CPU limit = 1000 millicores The pod has CPU requests == CPU limits -
© 2023 Akamas • All Rights Reserved • Confidential 16
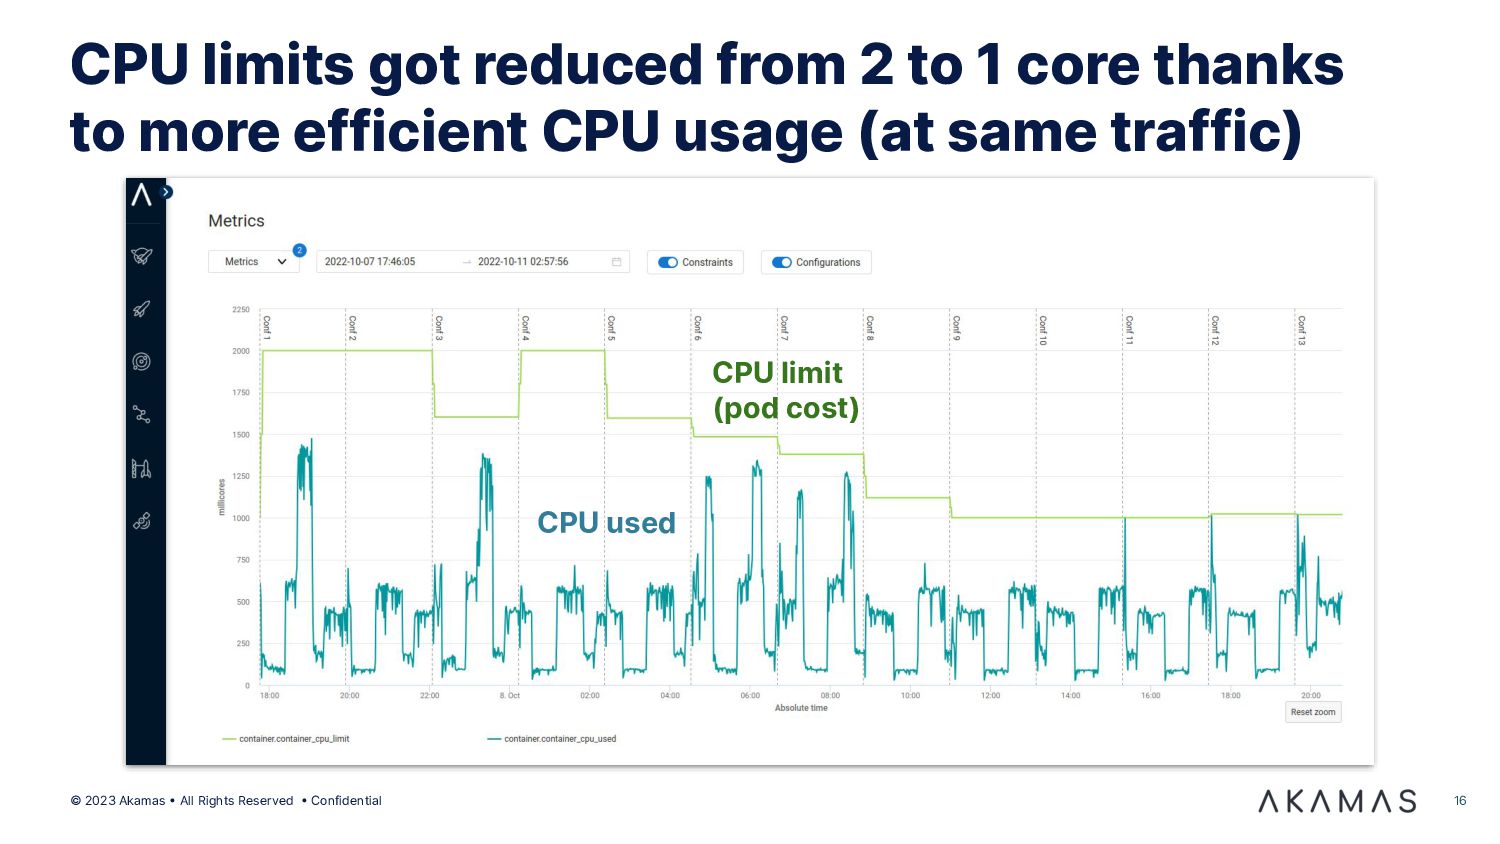
CPU limits got reduced from 2 to 1 core thanks to more efficient CPU usage (at same traffic) CPU limit (pod cost) CPU used -
© 2023 Akamas • All Rights Reserved • Confidential CPU
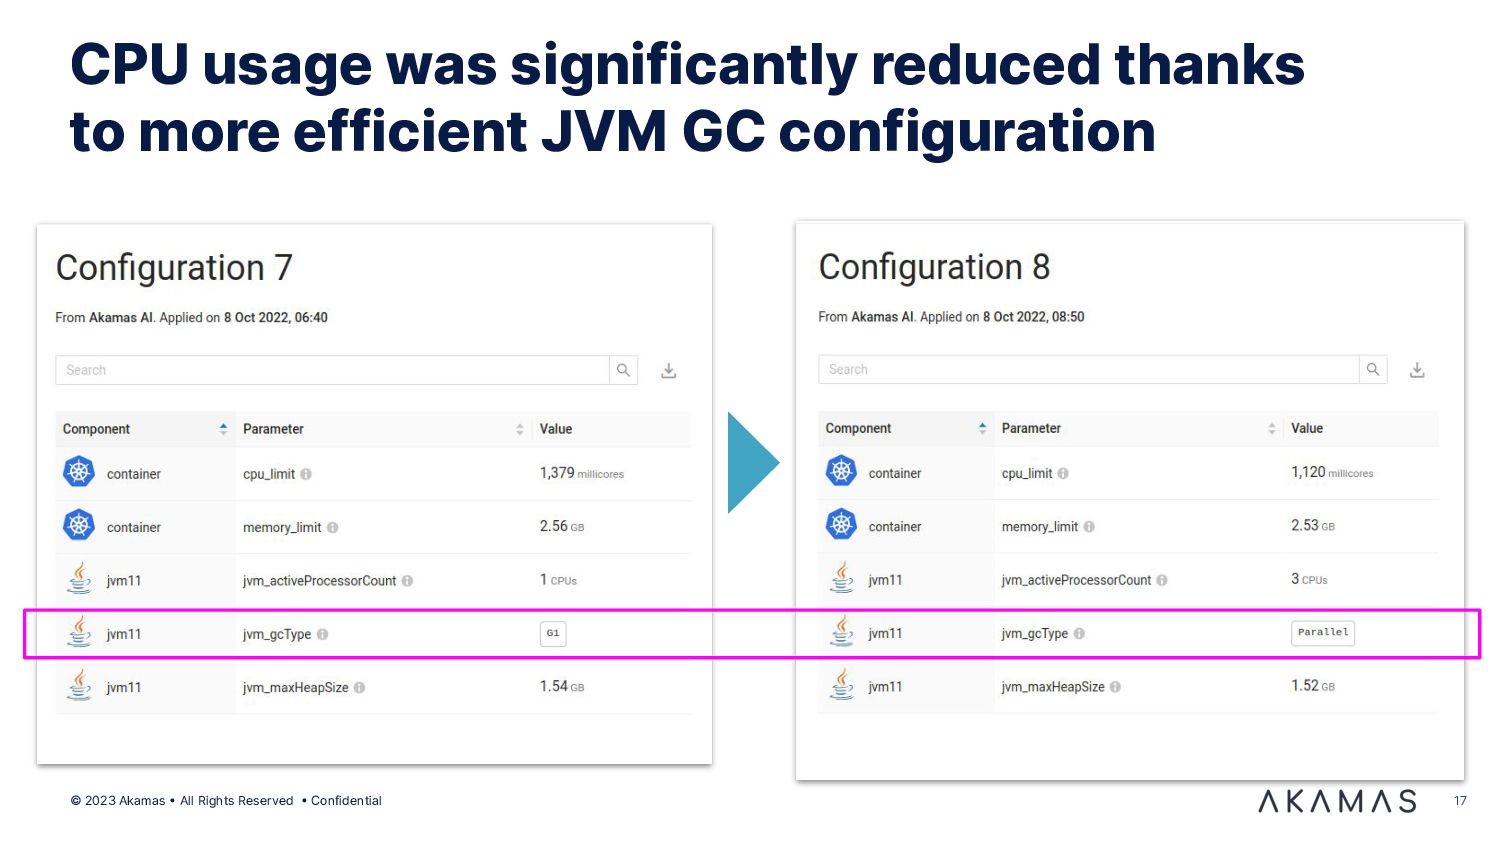
usage was significantly reduced thanks to more efficient JVM GC configuration 17 -
© 2023 Akamas • All Rights Reserved • Confidential Optimizing
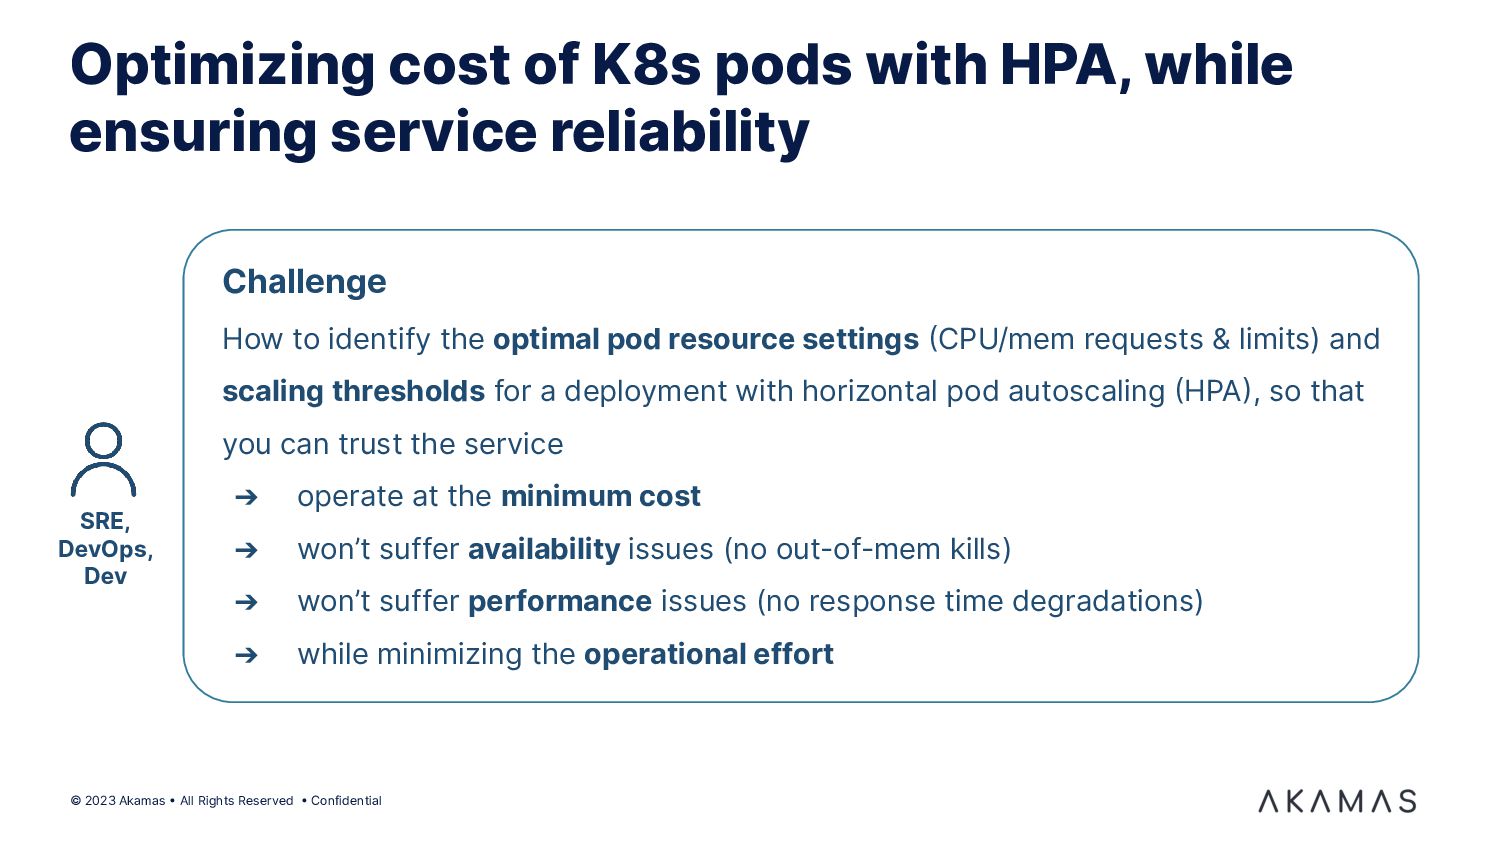
cost of K8s pods with HPA, while ensuring service reliability Challenge How to identify the optimal pod resource settings (CPU/mem requests & limits) and scaling thresholds for a deployment with horizontal pod autoscaling (HPA), so that you can trust the service ➔ operate at the minimum cost ➔ won’t suffer availability issues (no out-of-mem kills) ➔ won’t suffer performance issues (no response time degradations) ➔ while minimizing the operational effort SRE, DevOps, Dev -
© 2023 Akamas • All Rights Reserved • Confidential Akamas
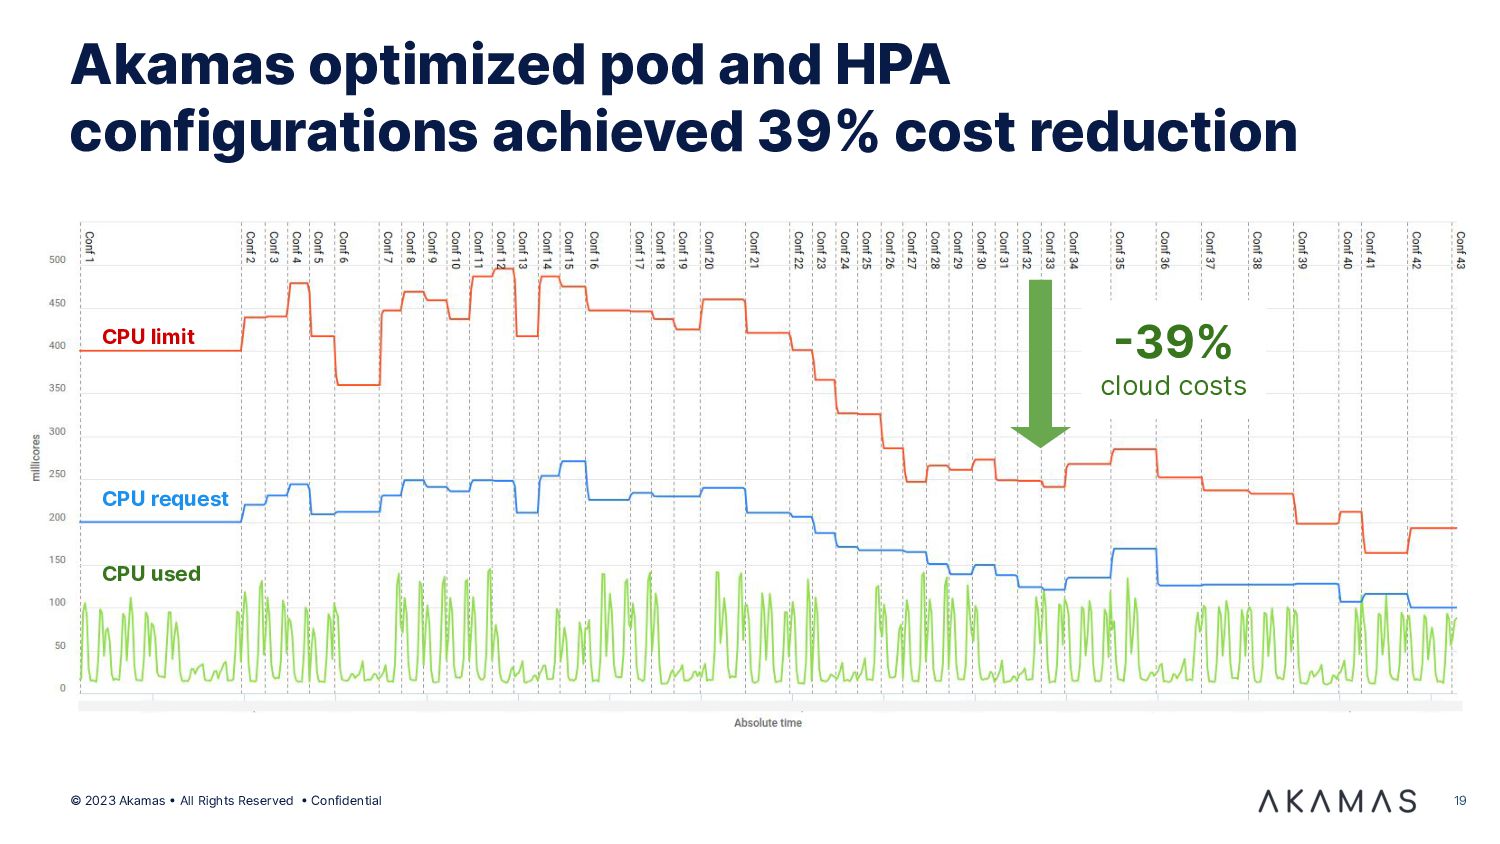
optimized pod and HPA configurations achieved 39% cost reduction 19 CPU request CPU limit CPU used -39% cloud costs -
© 2023 Akamas • All Rights Reserved • Confidential Optimal
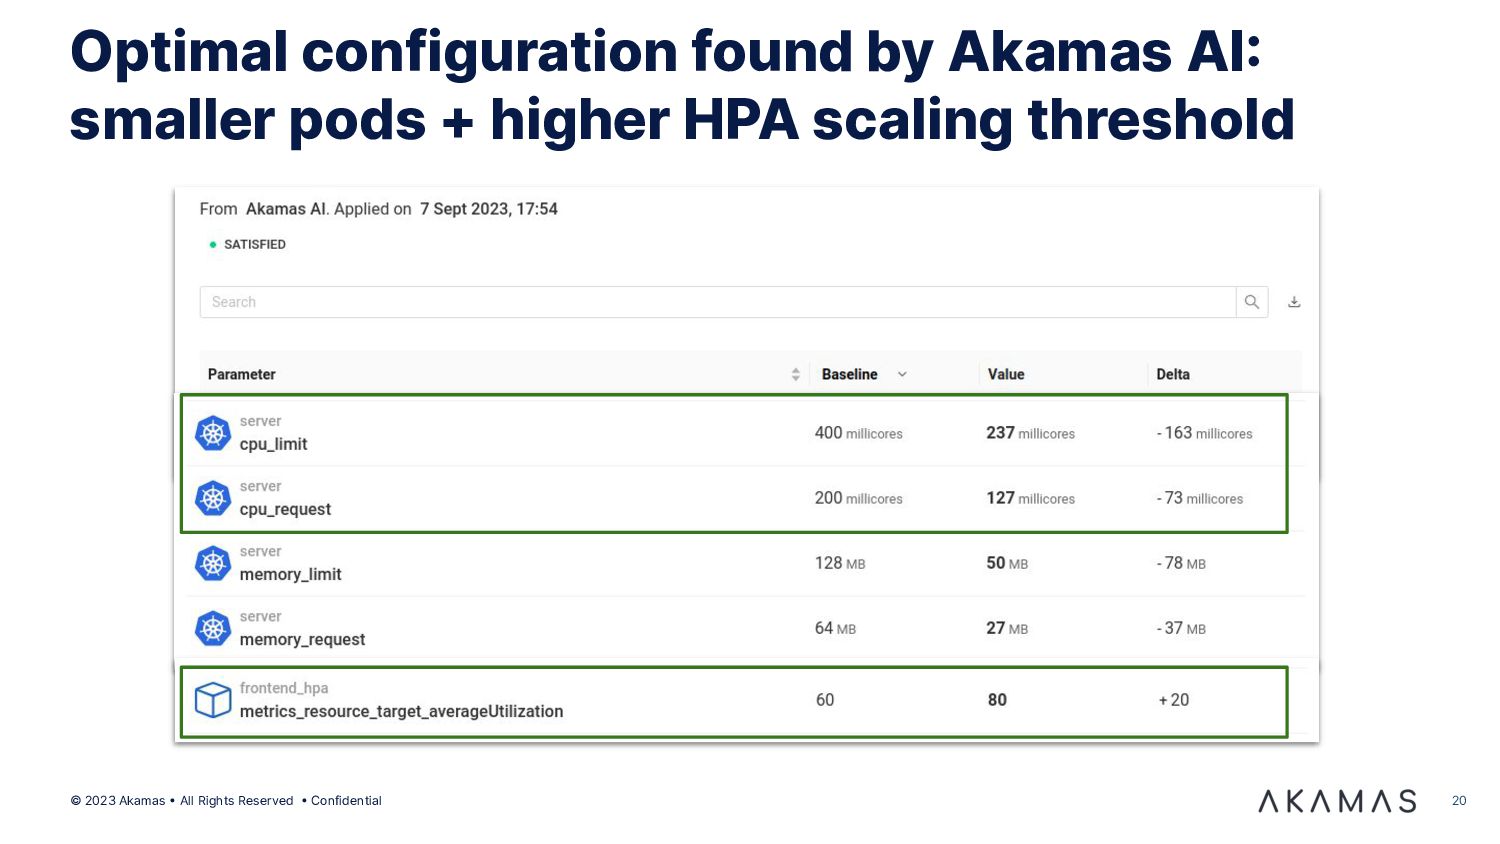
configuration found by Akamas AI: smaller pods + higher HPA scaling threshold 20 -
© 2023 Akamas • All Rights Reserved • Confidential What
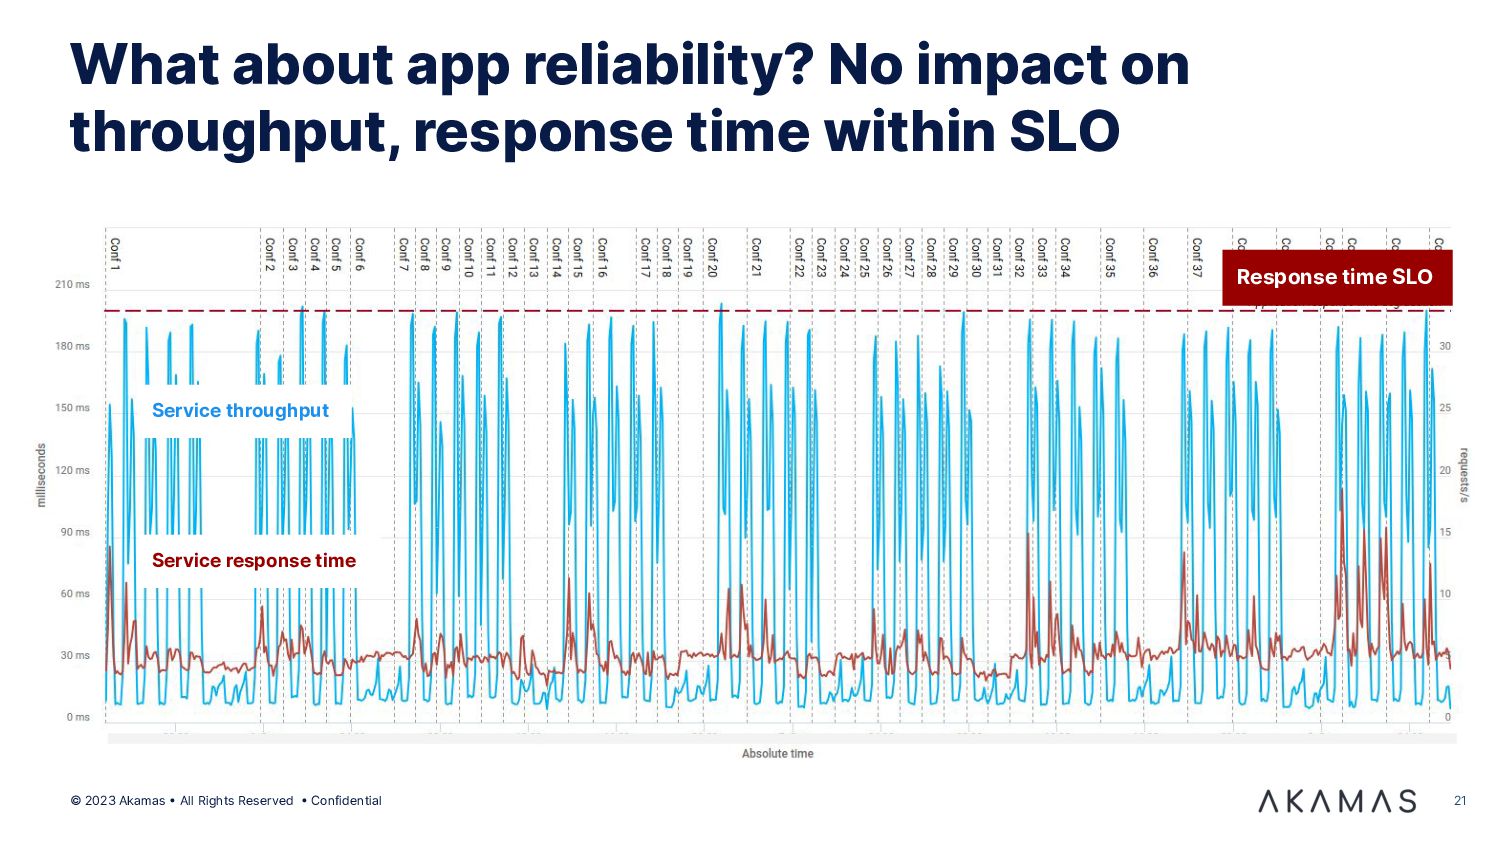
about app reliability? No impact on throughput, response time within SLO 21 Response time SLO Service throughput Service response time -
© 2023 Akamas • All Rights Reserved • Confidential Key
takeaways • K8s enables unprecedented scalability & efficiency, but it’s not automatic • Tuning is your responsibility - if you don’t tune, you don’t save! • The biggest cost & reliability wins lie in K8s workload and app runtime layers (pod sizing + HPA + JVM/Node.js/.NET/Golang configs) • AI-powered optimization enables you to automate tuning and achieve savings at scale 1 2 3 4 -
Contacts [email protected] @AkamasLabs @akamaslabs Italy HQ Via Schiaffino 11 Milan,
20158 +39-02-4951-7001 USA East 211 Congress Street Boston, MA 02110 +1-617-936-0212 Singapore 5 Temasek Blvd Singapore 038985 USA West 12130 Millennium Drive Los Angeles, CA 90094 +1-323-524-0524 LinkedIn Twitter Email © 2023 Akamas • All Rights Reserved • Confidential 23