Share
Fast Failover Using MySQL and ZooKeeper
Presented at Percona Live, April 4, 2014
Fast failover is not just an option for building reliable systems in the cloud - it is a requirement. Unfortunately, it seems like every storage solution out there (whether it's SQL or NoSQL) has its own proprietary monitoring and failover mechanism. In this presentation, we explore Zookeeper as a mechanism for fast, application-driven failover for both MySQL and Redis in the cloud. By using Zookeeper and client-level integration, we can avoid the "magic" of network-level failover (such as elastic IPs) as well as the latency and complexity of proxy-level solutions. We demonstrate that Zookeeper is a practical cross-platform strategy from any language, with examples of failover in Ruby, Java, and Node.js applications.
Sunny Gleason
Transcript
33 slides
-
Fast Failover Using MySQL and ZooKeeper Sunny Gleason Distributed Systems
Engineer, SunnyCloud April 4, 2014 -
Who am I? • Sunny Gleason – Distributed Systems Engineer
– SunnyCloud, Boston MA • Prior Web Services Work – Amazon – Ning • Focus: Scalable, Reliable Storage Systems for Structured & Unstructured Data 2 -
What’s this all about? • As Cloud systems evolve, availability
expectations are getting higher and higher • Fast Failover is a requirement • But, the most common techniques applied for failover can be brittle and overly blunt • Developers seldom know or care about failover mechanics • There has to be a better way! 3 -
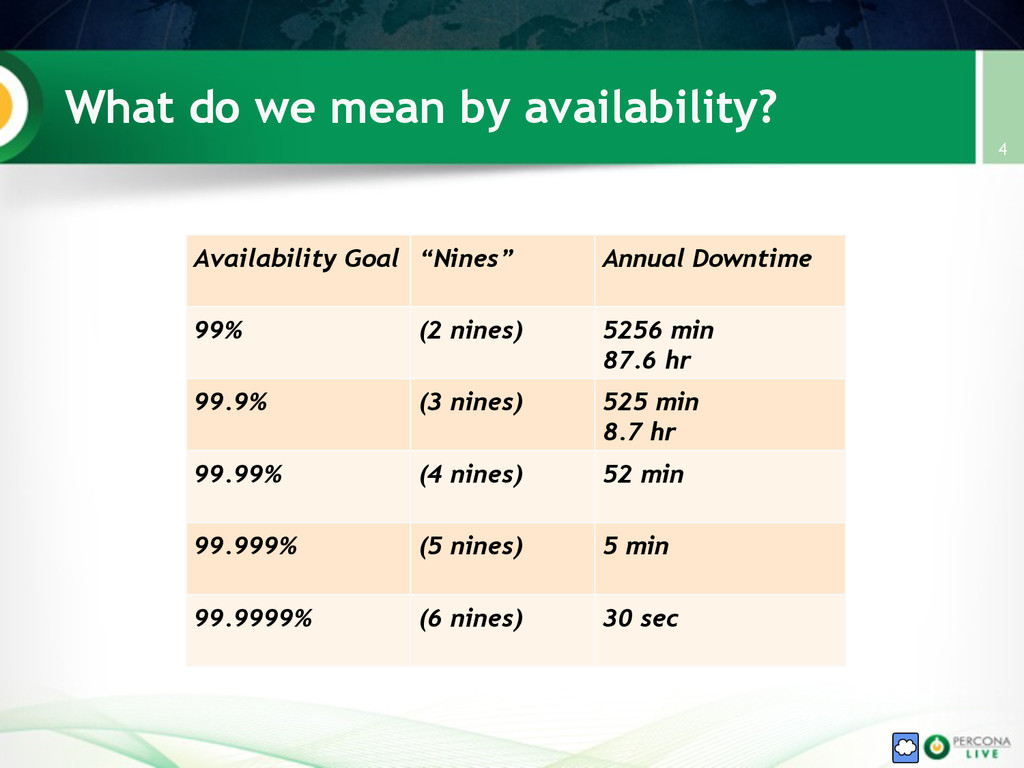
What do we mean by availability? 4 Availability Goal “Nines”
Annual Downtime 99% (2 nines) 5256 min 87.6 hr 99.9% (3 nines) 525 min 8.7 hr 99.99% (4 nines) 52 min 99.999% (5 nines) 5 min 99.9999% (6 nines) 30 sec -
Escalation, Activation & Availability • If failure detection, escalation and
failover take > 15-30 min total, tough to get 4 nines • Goal: minimize time for failure detect & failover (and mitigate perils of auto-failover) • This presentation just focuses on reducing failover time and complexity 5 -
Applying ZooKeeper to Fast Failover • Every datastore has its
own mechanism for service discovery, monitoring, failover • We can use ZooKeeper as a fault-tolerant datastore for service discovery • Use WebSocket or HTTP long-polling instead of making all the apps become ZooKeeper clients • Near-instantaneous results, while avoiding the “magic” of network-level failover 6 Precedent: http://engineering.pinterest.com/post/77933733851/zookeeper-resilience-at-pinterest -
Common MySQL Deployment Scenario • Running Master-Master with Replication configured
in both directions • Writes directed to a single active master • Active master database is identified to application by a DNS name (myapp-db-master.xyz.com) • Name resolves to a virtual IP (VIP) • VIP is “flipped” manually or automatically 7 -
Virtual IPs & DNS Updates • A Virtual IP (VIP)
is an additional IP bound to a network interface • Linux & other operating systems allow VIPs to be bound / unbound dynamically • VIP works b/c MAC address -> IP not 1:1 • AWS EC2 has similar concept of “Elastic IP” — like a VIP, but slower to propagate and and harder to debug • DNS entries have TTLs which can be set low 8 More Info: http://scale-out-blog.blogspot.com/2011/01/virtual-ip-addresses-and-their.html -
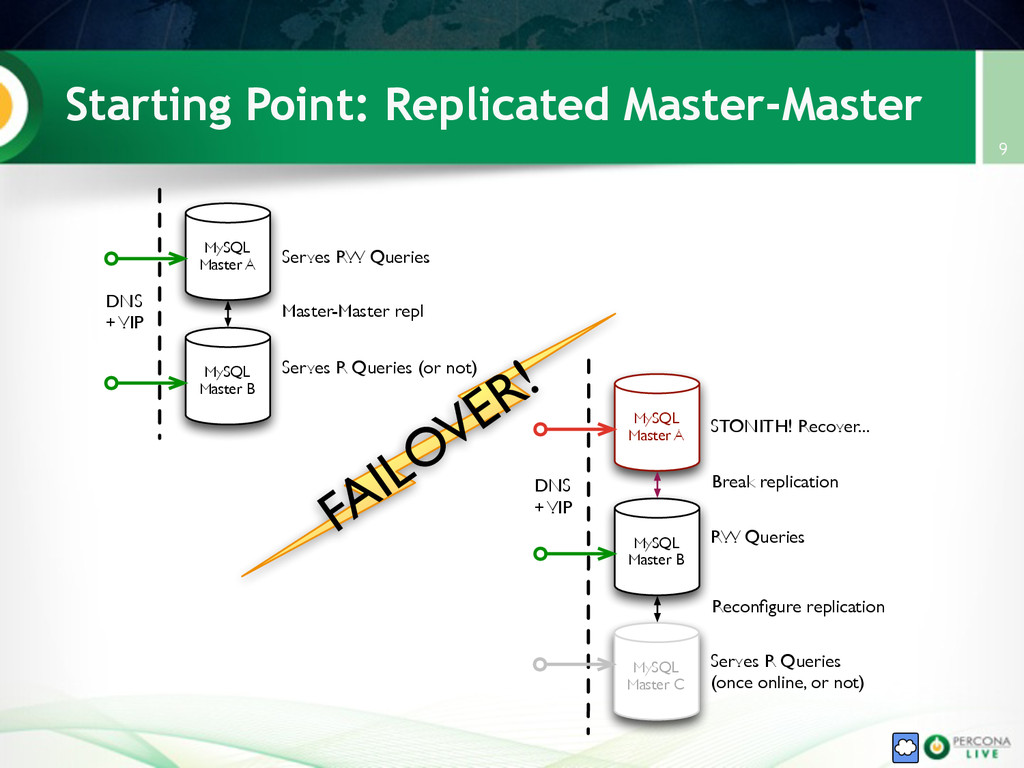
Starting Point: Replicated Master-Master 9 MySQL Master A MySQL Master
B DNS + VIP Serves RW Queries Serves R Queries (or not) FAILOVER! MySQL Master A MySQL Master B DNS + VIP STONITH! Recover... RW Queries Master-Master repl MySQL Master C Serves R Queries (once online, or not) Break replication Reconfigure replication -
Virtual IPs and/or DNS-based Discovery • Heavyweight : affects all
nodes • Complicated : VIP requires coordination, DNS propagation tricky to verify • Slow : ARP cache and DNS have TTL • Error Prone : hardware/OS have ARP quirks, applications don’t honor DNS TTL (Java) • Unidirectional : no feedback channel for service clients 10 -
What if we use a Layer 4 / Layer 7
proxy? • Single point of failure in front of the DBs • Or, multiple points of failure that need to be coordinated • How is the proxy cluster discovered? Round-Robin DNS? VIPs? • Proxy solves fast failover, but not high availability • Can we do better? 12 -
Properties of a Better Solution • Applications embed a standard
callback for configuration changes • Fast : propagate & verify in millis, not minutes • Explicit : not dependent on network “magic”, creates verifiable events at coordinator and client-side • Fine-grained : offers precise control of failover • Bidirectional : provides feedback channel from client back to the coordinator, channel for backpressure • Straightforward : easy for mere mortals to debug & understand, useful on everyday basis 13 -
ZooKeeper Properties • Symmetric distributed “small data” store with automatic,
fast leader election • A minority of cluster cannot make progress, staleness is bounded/configurable • Clients see continuously advancing view of data over time • More info: • ZK Book: http://shop.oreilly.com/product/0636920028901.do • Blog: http://www.sleberknight.com/blog/sleberkn/entry/ distributed_coordination_with_zookeeper_part3 • Fault-Tolerance: http://aphyr.com/posts/291-call-me-maybe-zookeeper 16 -
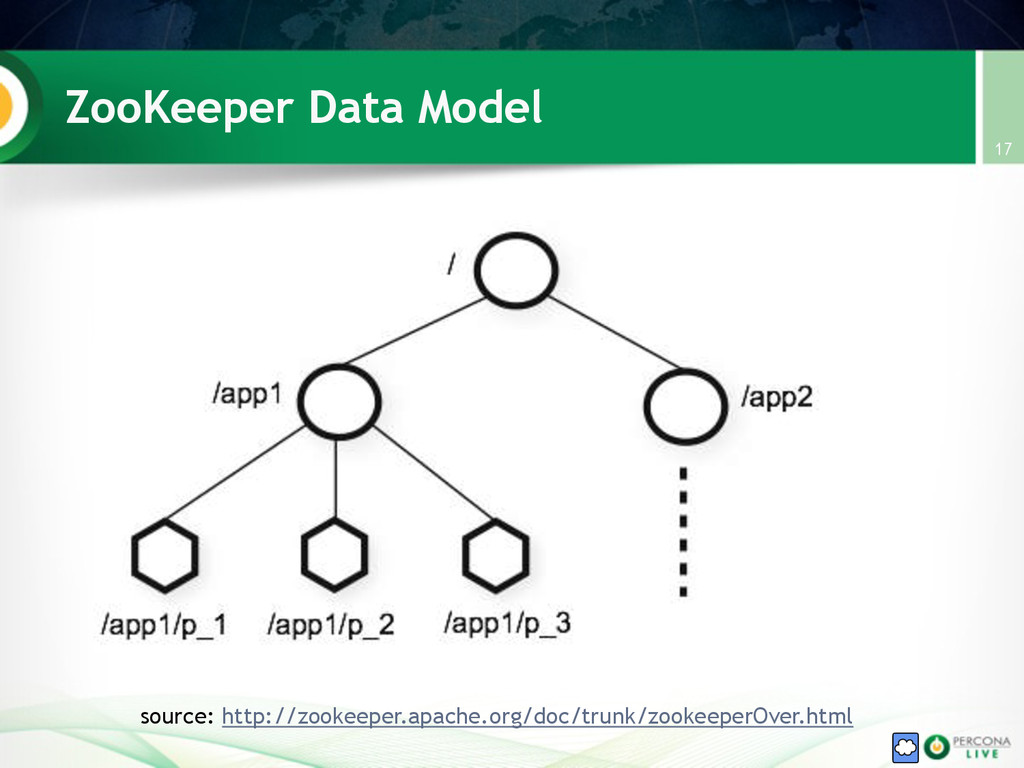
ZooKeeper Data Model • Client connections to ZK are session-based
• Data is a hierarchy of nodes • All nodes are children of the root node • Nodes have single parent, 0 or more children • Nodes may hold up to 1MB of data • Nodes have metadata: version, ctime, mtime • Nodes may be ephemeral, deleted upon session close • Clients can watch nodes for instant change notification 18 -
ZooKeeper Disclaimers • ZooKeeper is not a database • ZooKeeper
is a highly specialized store with specific properties • Protect it from bloat! • Keep data small • Restrict number of direct clients • Write apps so they still function if the cluster becomes unavailable (i.e. during major version upgrades) • Study the ZooKeeper guide closely and certify ZK in production before using it for mission-critical use cases 19 -
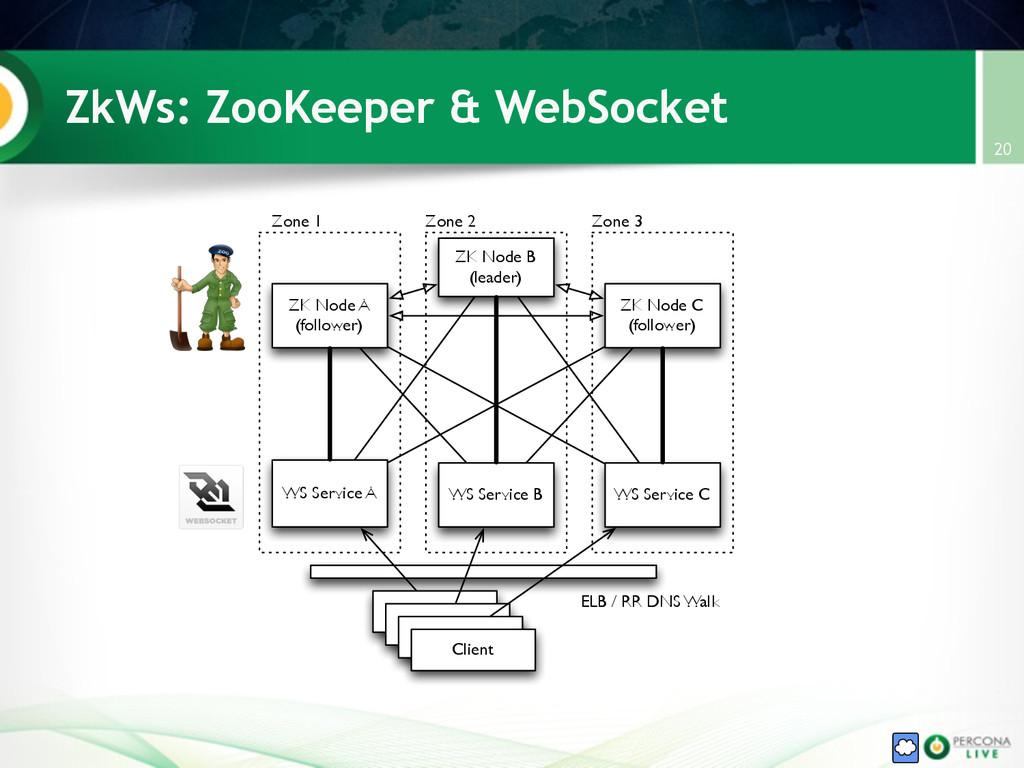
ZkWs: ZooKeeper & WebSocket 20 ZK Node A (follower) ZK
Node B (leader) ZK Node C (follower) WS Service A WS Service B WS Service C Client Client Client Client Zone 1 Zone 2 Zone 3 ELB / RR DNS Walk -
ZkWs: WebSocket & ZooKeeper • Use WebSocket to provide a
simple, HTTP-based protocol on top of ZooKeeper read-only watches • Clients connect to any WS server, watches 1+ ZK paths • WS Service aggregates ZK clients, simplifies client connection pool development • Configuration updates propagate within milliseconds • Client reconnects automatically if connection lost • In progress: client caches latest good settings to reduce impact of config service (allows cluster to be taken down for upgrades) 21 -
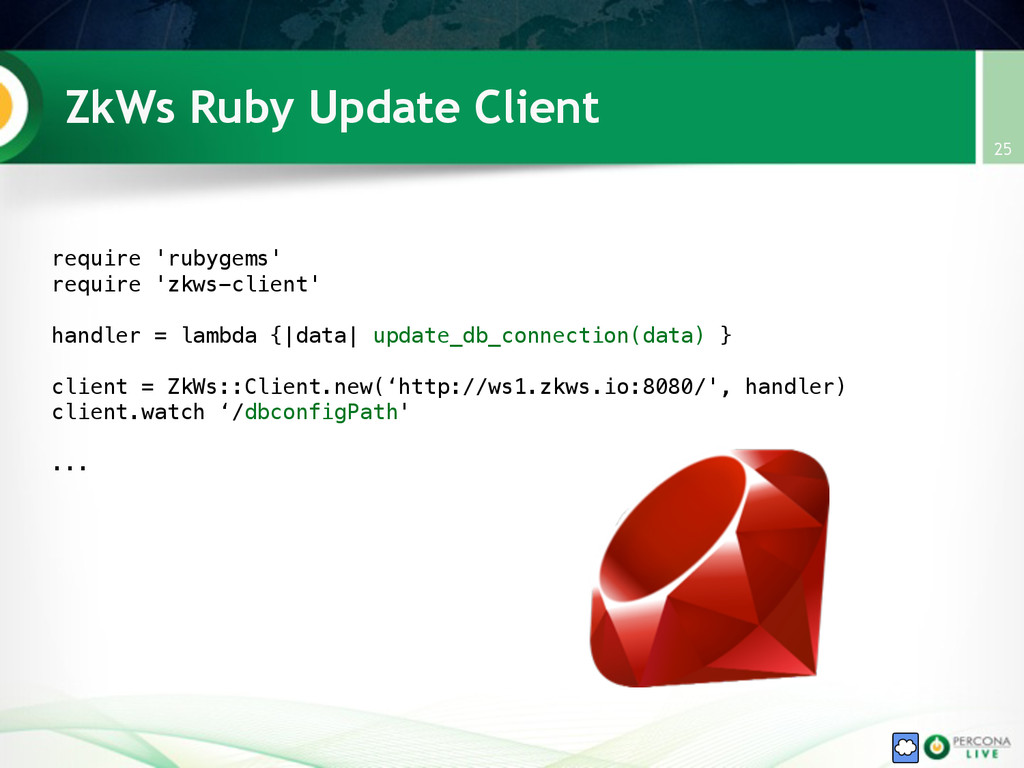
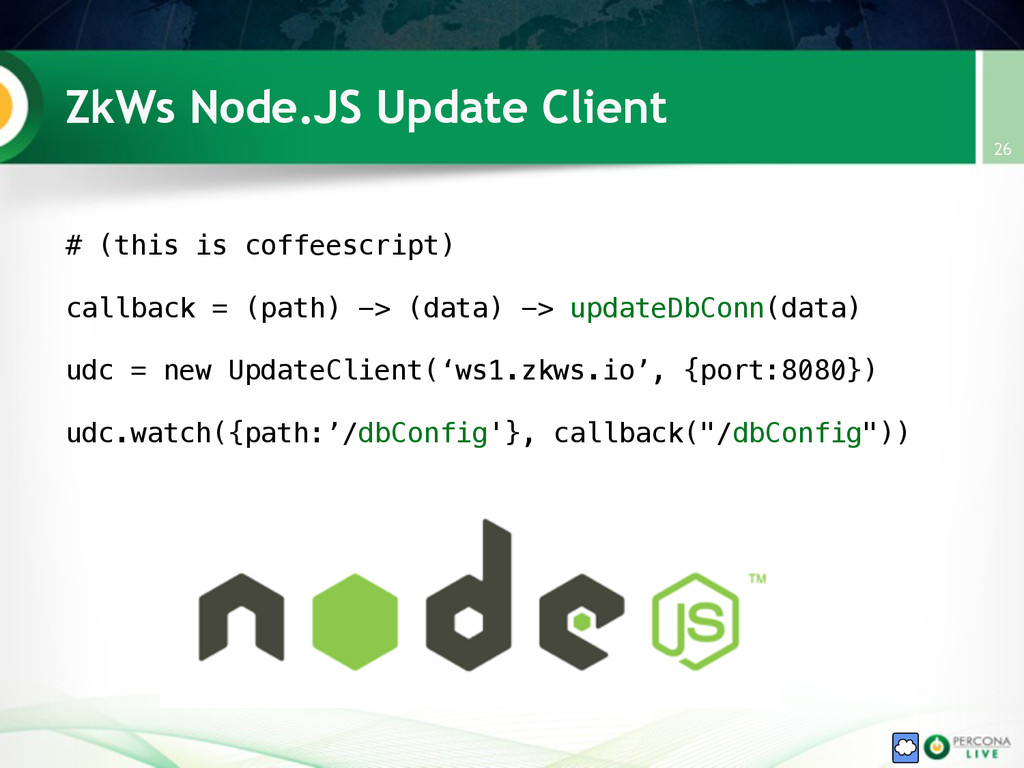
ZkWs Service & Clients • Initial implementation of ZkWs server
is ~35 lines of CoffeeScript • Work is in progress to make it 5k lines of Java • WS-enabled Client Implementations: • Java update client with DataSource wrapper & atomic/transparent activation • Ruby update client • Node.JS update client 22 -
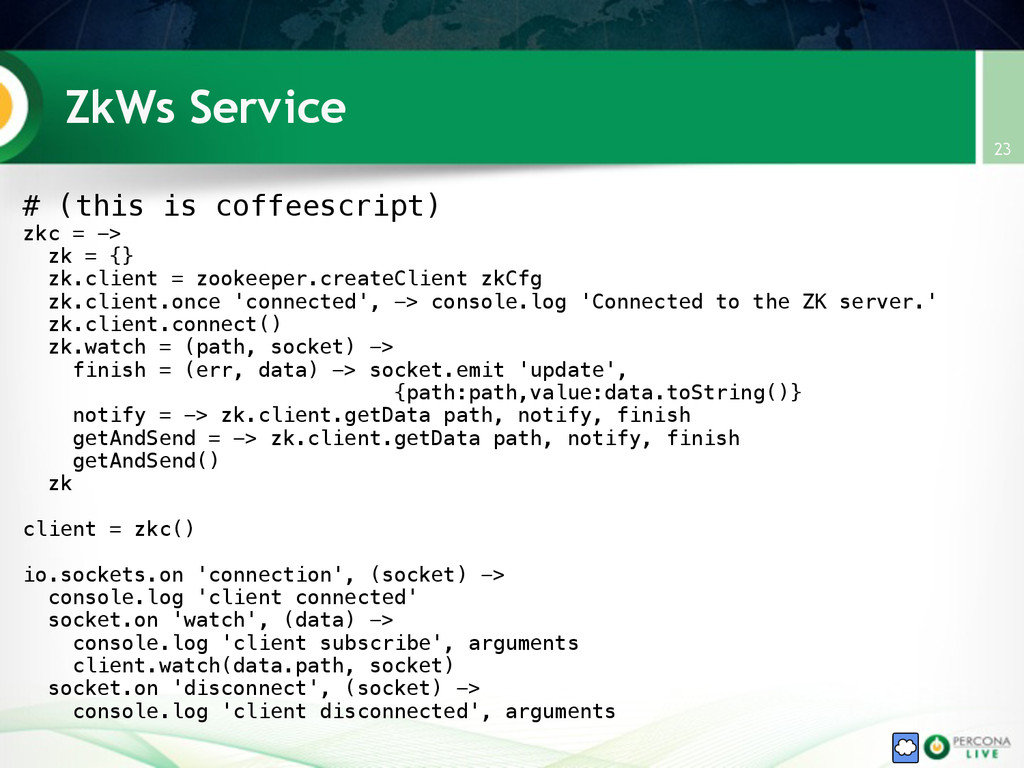
ZkWs Service # (this is coffeescript) zkc = -> zk
= {} zk.client = zookeeper.createClient zkCfg zk.client.once 'connected', -> console.log 'Connected to the ZK server.' zk.client.connect() zk.watch = (path, socket) -> finish = (err, data) -> socket.emit 'update', {path:path,value:data.toString()} notify = -> zk.client.getData path, notify, finish getAndSend = -> zk.client.getData path, notify, finish getAndSend() zk ! client = zkc() ! io.sockets.on 'connection', (socket) -> console.log 'client connected' socket.on 'watch', (data) -> console.log 'client subscribe', arguments client.watch(data.path, socket) socket.on 'disconnect', (socket) -> console.log 'client disconnected', arguments 23 -
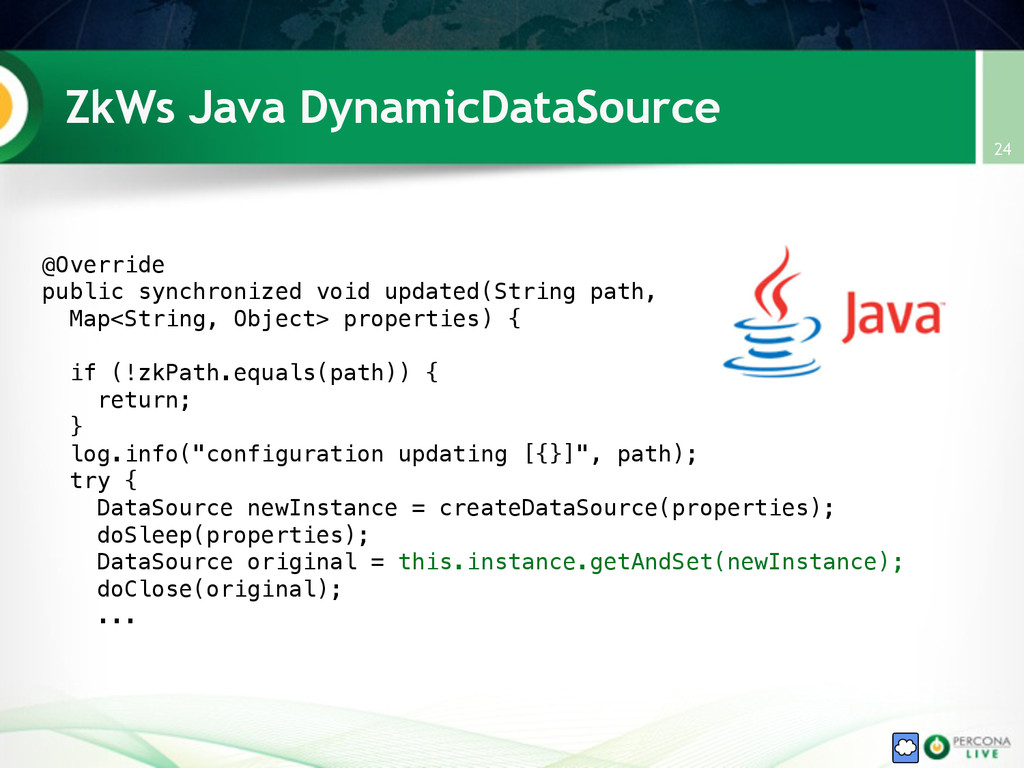
ZkWs Java DynamicDataSource @Override public synchronized void updated(String path, Map<String,
Object> properties) { if (!zkPath.equals(path)) { return; } log.info("configuration updating [{}]", path); try { DataSource newInstance = createDataSource(properties); doSleep(properties); DataSource original = this.instance.getAndSet(newInstance); doClose(original); ... 24 -
ZkWs Ruby Update Client require 'rubygems' require 'zkws-client' ! handler
= lambda {|data| update_db_connection(data) } ! client = ZkWs::Client.new(‘http://ws1.zkws.io:8080/', handler) client.watch ‘/dbconfigPath' ! ... 25 -
ZkWs Node.JS Update Client # (this is coffeescript) ! callback
= (path) -> (data) -> updateDbConn(data) ! udc = new UpdateClient(‘ws1.zkws.io’, {port:8080}) udc.watch({path:’/dbConfig'}, callback("/dbConfig")) 26 -
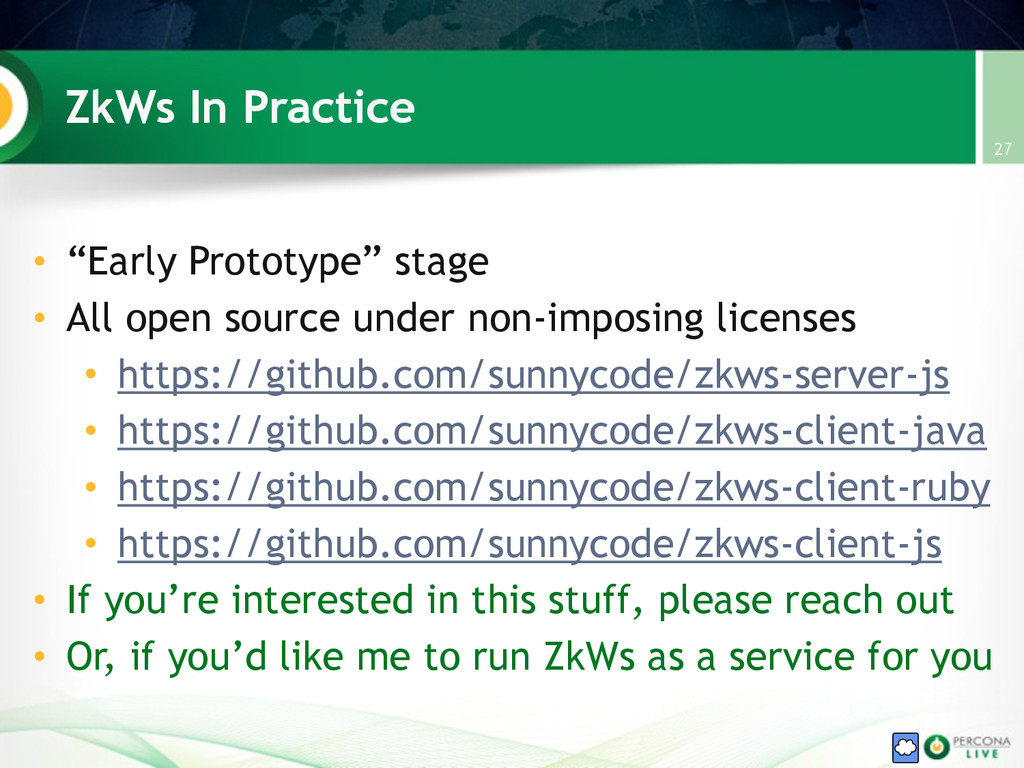
ZkWs In Practice • “Early Prototype” stage • All open
source under non-imposing licenses • https://github.com/sunnycode/zkws-server-js • https://github.com/sunnycode/zkws-client-java • https://github.com/sunnycode/zkws-client-ruby • https://github.com/sunnycode/zkws-client-js • If you’re interested in this stuff, please reach out • Or, if you’d like me to run ZkWs as a service for you 27 -
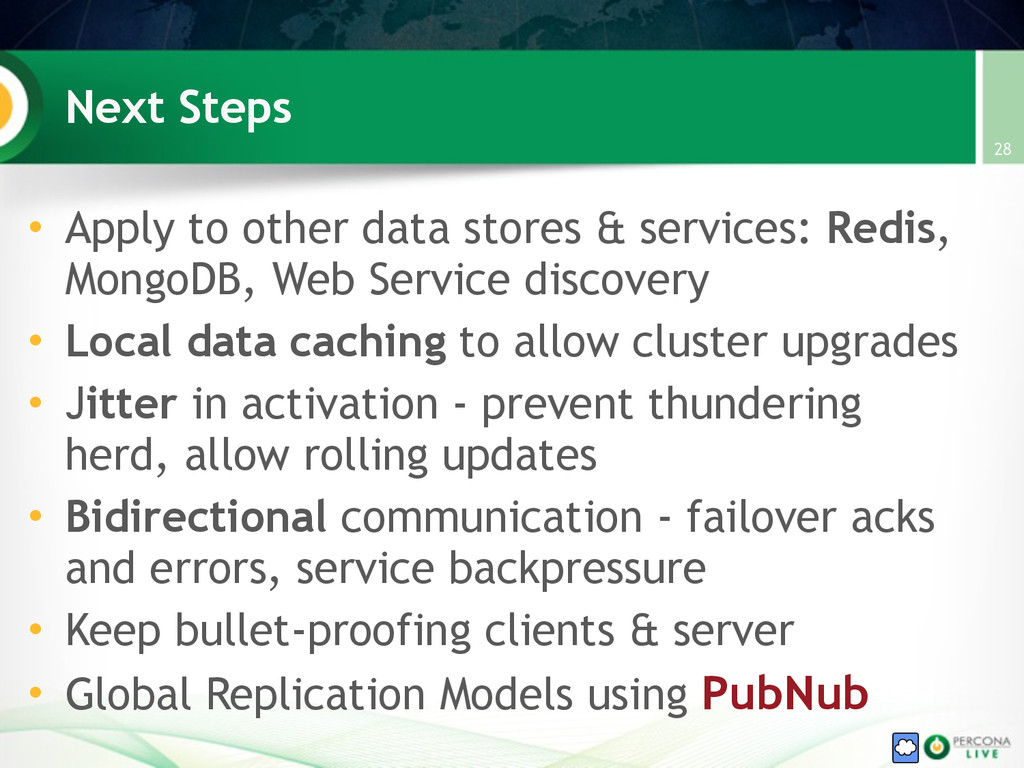
Next Steps • Apply to other data stores & services:
Redis, MongoDB, Web Service discovery • Local data caching to allow cluster upgrades • Jitter in activation - prevent thundering herd, allow rolling updates • Bidirectional communication - failover acks and errors, service backpressure • Keep bullet-proofing clients & server • Global Replication Models using PubNub 28 -
Going Global with PubNub • Easy to set up WebSocket
in AWS Availability Zones in one Region, supporting a small number of servers • What if we wanted to efficiently manage configuration across multiple geo regions? • ZooKeeper latencies scale poorly in a widely-distributed network • PubNub provides infrastructure for fast global real-time communication 29 -
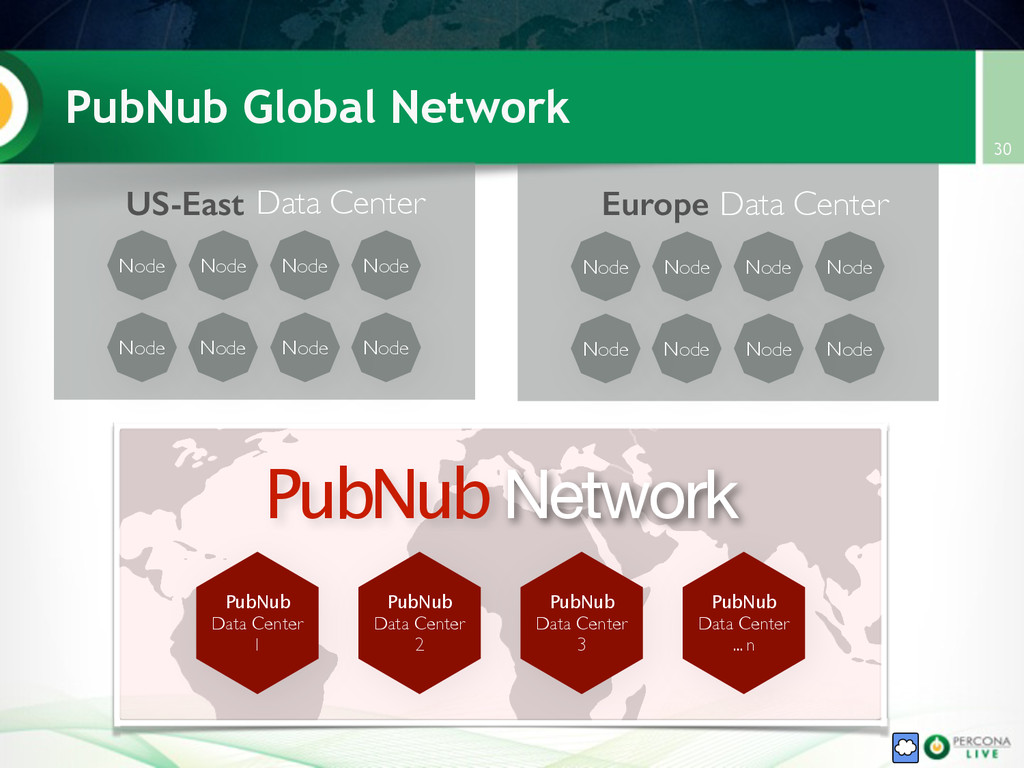
PubNub Global Network 30 PubNub Data Center 1 PubNub Data
Center 2 PubNub Data Center 3 PubNub Data Center ... n PubNub Network Data Center ! ! ! ! Node Node Node Node Node Node Node Node US-East Data Center ! ! ! ! Node Node Node Node Node Node Node Node Europe -
PubNub Benefits • Easy to use Publish/Subscribe API with SocketIO
support (works with ZkWs) • Global Presence • Every AWS Availability Zone, ~1ms latency • Rackspace, Softlayer & Azure • Full worldwide propagation within ~250ms • Proactive message replication & storage - when service connects, messages are already there • Initial target application: global service discovery and failover 31 -
ZkWs Conclusion • Current failover Mechanisms can be: • complicated
• brittle • slow • datastore-specific • With ZkWs, failover can be • fast • precise • simpler & more debuggable for DBAs & Devs • fun! 32