Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
DQNによるポーカーの強化学習/Reinforcement Learning in Poker...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
tasotaku
December 14, 2023
900
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
DQNによるポーカーの強化学習/Reinforcement Learning in Poker with DQN
tasotaku
December 14, 2023
More Decks by tasotaku
See All by tasotaku
duel_masters_RAG
tasotaku
0
120
オセロCPU/Othello CPU
tasotaku
0
210
オセロAI / OthelloAI
tasotaku
0
250
私、ChatGPTがChatGPTを解説するよ! / ChatGPT explains ChatGPT
tasotaku
0
540
機械学習入門
tasotaku
0
530
AIが作る予想外な画像を考える / Consider the unexpected images that AI creates
tasotaku
0
390
Google Colaboratory でStable Diffusionの実装 / Implementation of Stable Diffusion at Google Colaboratory
tasotaku
0
490
Featured
See All Featured
Navigating Team Friction
lara
192
16k
The Limits of Empathy - UXLibs8
cassininazir
1
690
Data-driven link building: lessons from a $708K investment (BrightonSEO talk)
szymonslowik
1
1.3k
Bootstrapping a Software Product
garrettdimon
PRO
306
120k
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
How to Get Subject Matter Experts Bought In and Actively Contributing to SEO & PR Initiatives.
livdayseo
0
200
Everyday Curiosity
cassininazir
0
320
The Psychology of Web Performance [Beyond Tellerrand 2023]
tammyeverts
49
3.6k
Dominate Local Search Results - an insider guide to GBP, reviews, and Local SEO
greggifford
PRO
0
340
DevOps and Value Stream Thinking: Enabling flow, efficiency and business value
helenjbeal
1
390
brightonSEO & MeasureFest 2025 - Christian Goodrich - Winning strategies for Black Friday CRO & PPC
cargoodrich
3
850
SEO in 2025: How to Prepare for the Future of Search
ipullrank
3
3.8k
Transcript
DQNによるポーカーの 強化学習 宮内翼
目次 ◼ DQNとは ⚫ Q学習 ⚫ Q関数とニューラルネットワーク(NN) ⚫ 経験再生 ⚫
ターゲットネットワーク ◼ テキサスホールデムの学習
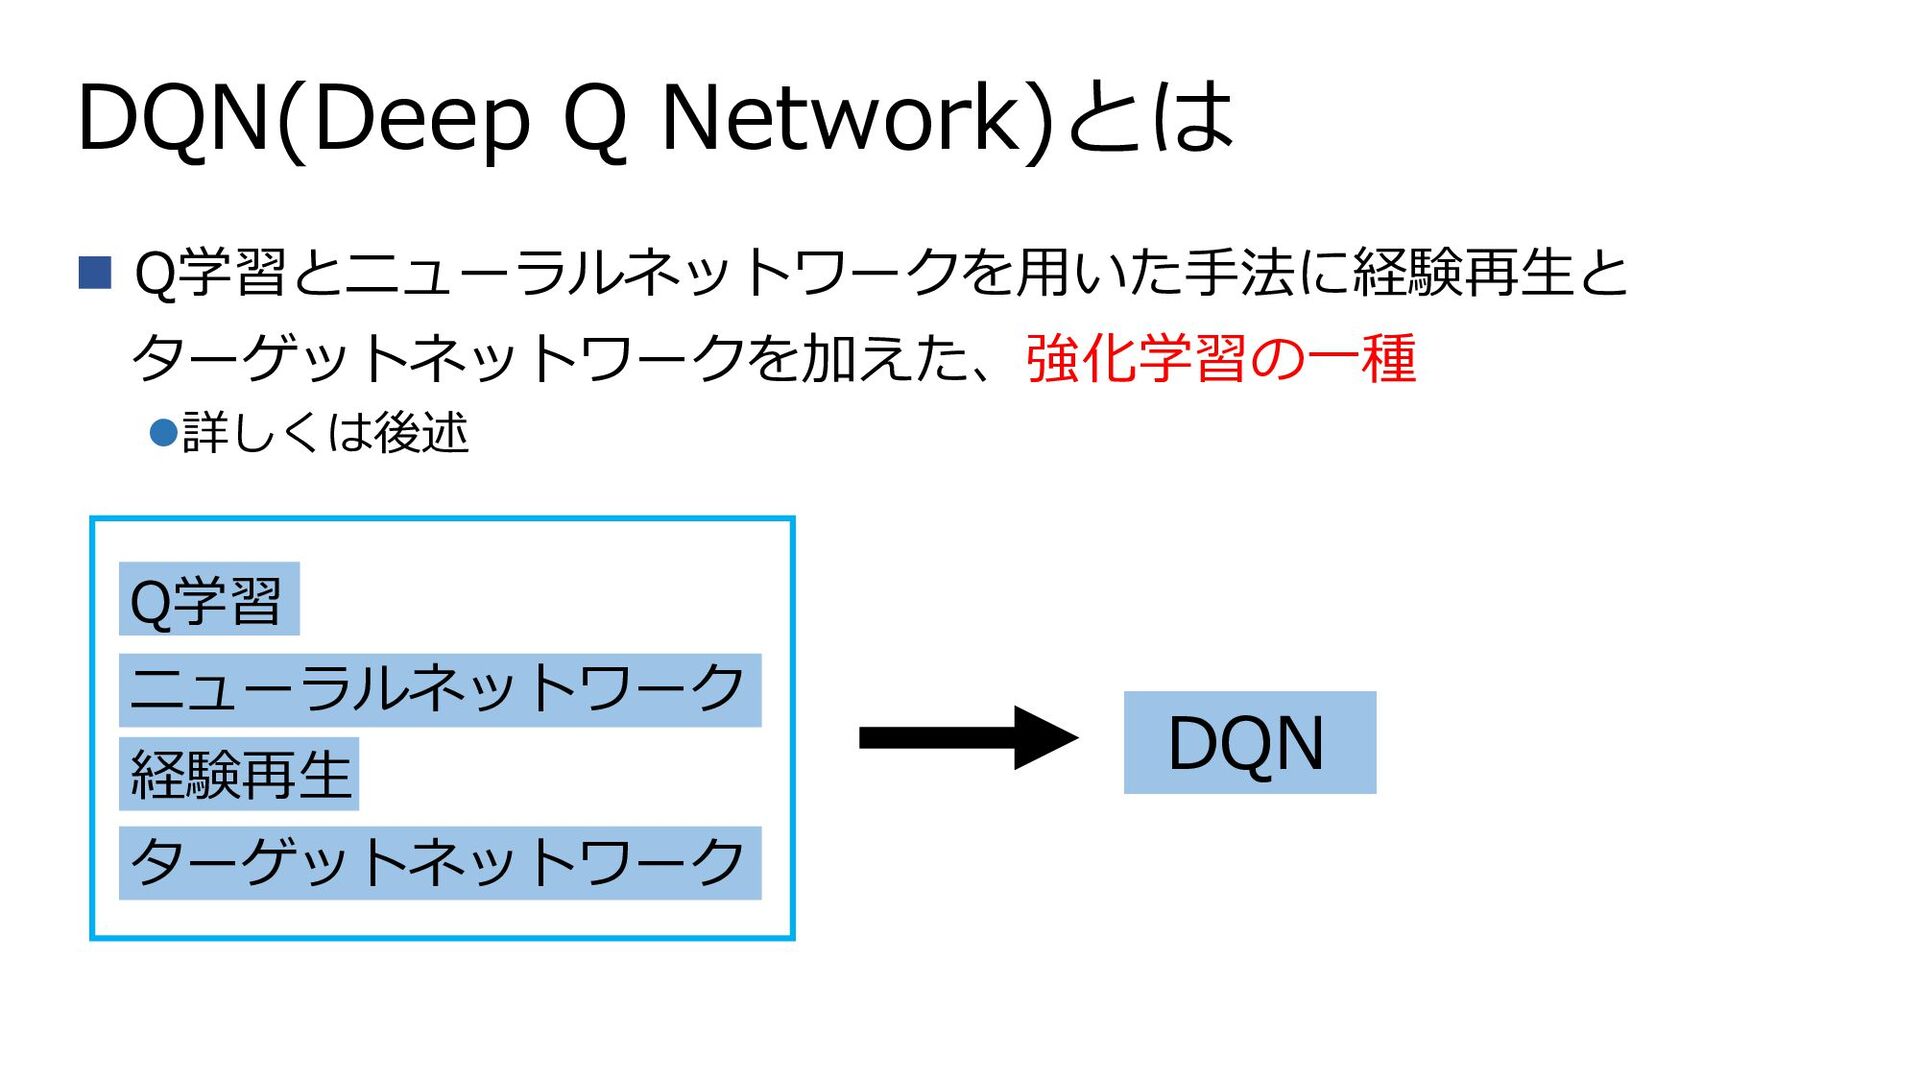
DQN(Deep Q Network)とは ◼ Q学習とニューラルネットワークを用いた手法に経験再生と ターゲットネットワークを加えた、強化学習の一種 ⚫詳しくは後述 Q学習 ニューラルネットワーク 経験再生
ターゲットネットワーク DQN
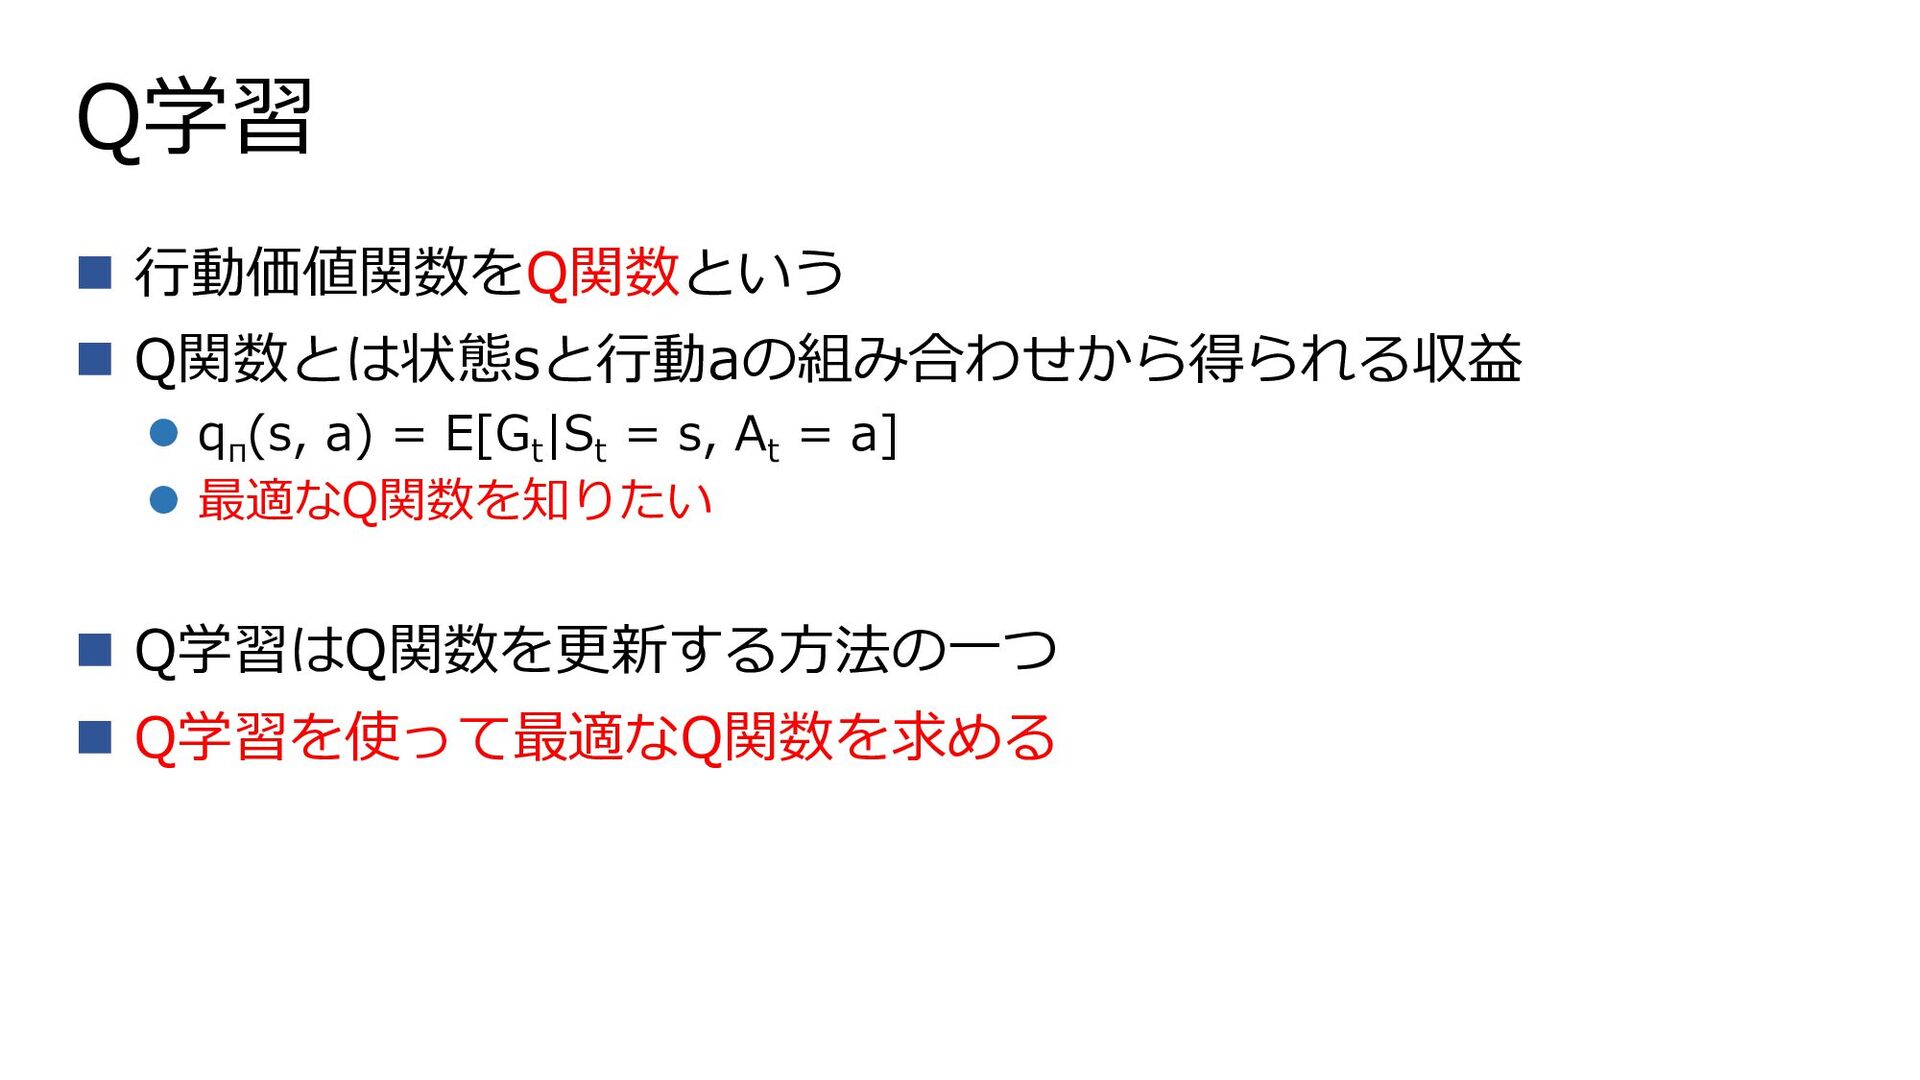
Q学習 ◼ 行動価値関数をQ関数という ◼ Q関数とは状態sと行動aの組み合わせから得られる収益 ⚫ q π (s, a)
= E[G t |S t = s, A t = a] ⚫ 最適なQ関数を知りたい ◼ Q学習はQ関数を更新する方法の一つ ◼ Q学習を使って最適なQ関数を求める
Q関数とニューラルネットワーク(NN) ◼ 例:チェスの駒の並び(状態数)は10の123乗 Q関数の候補は 状態数×行動数で膨大 ニューラルネットワークで近似 なので
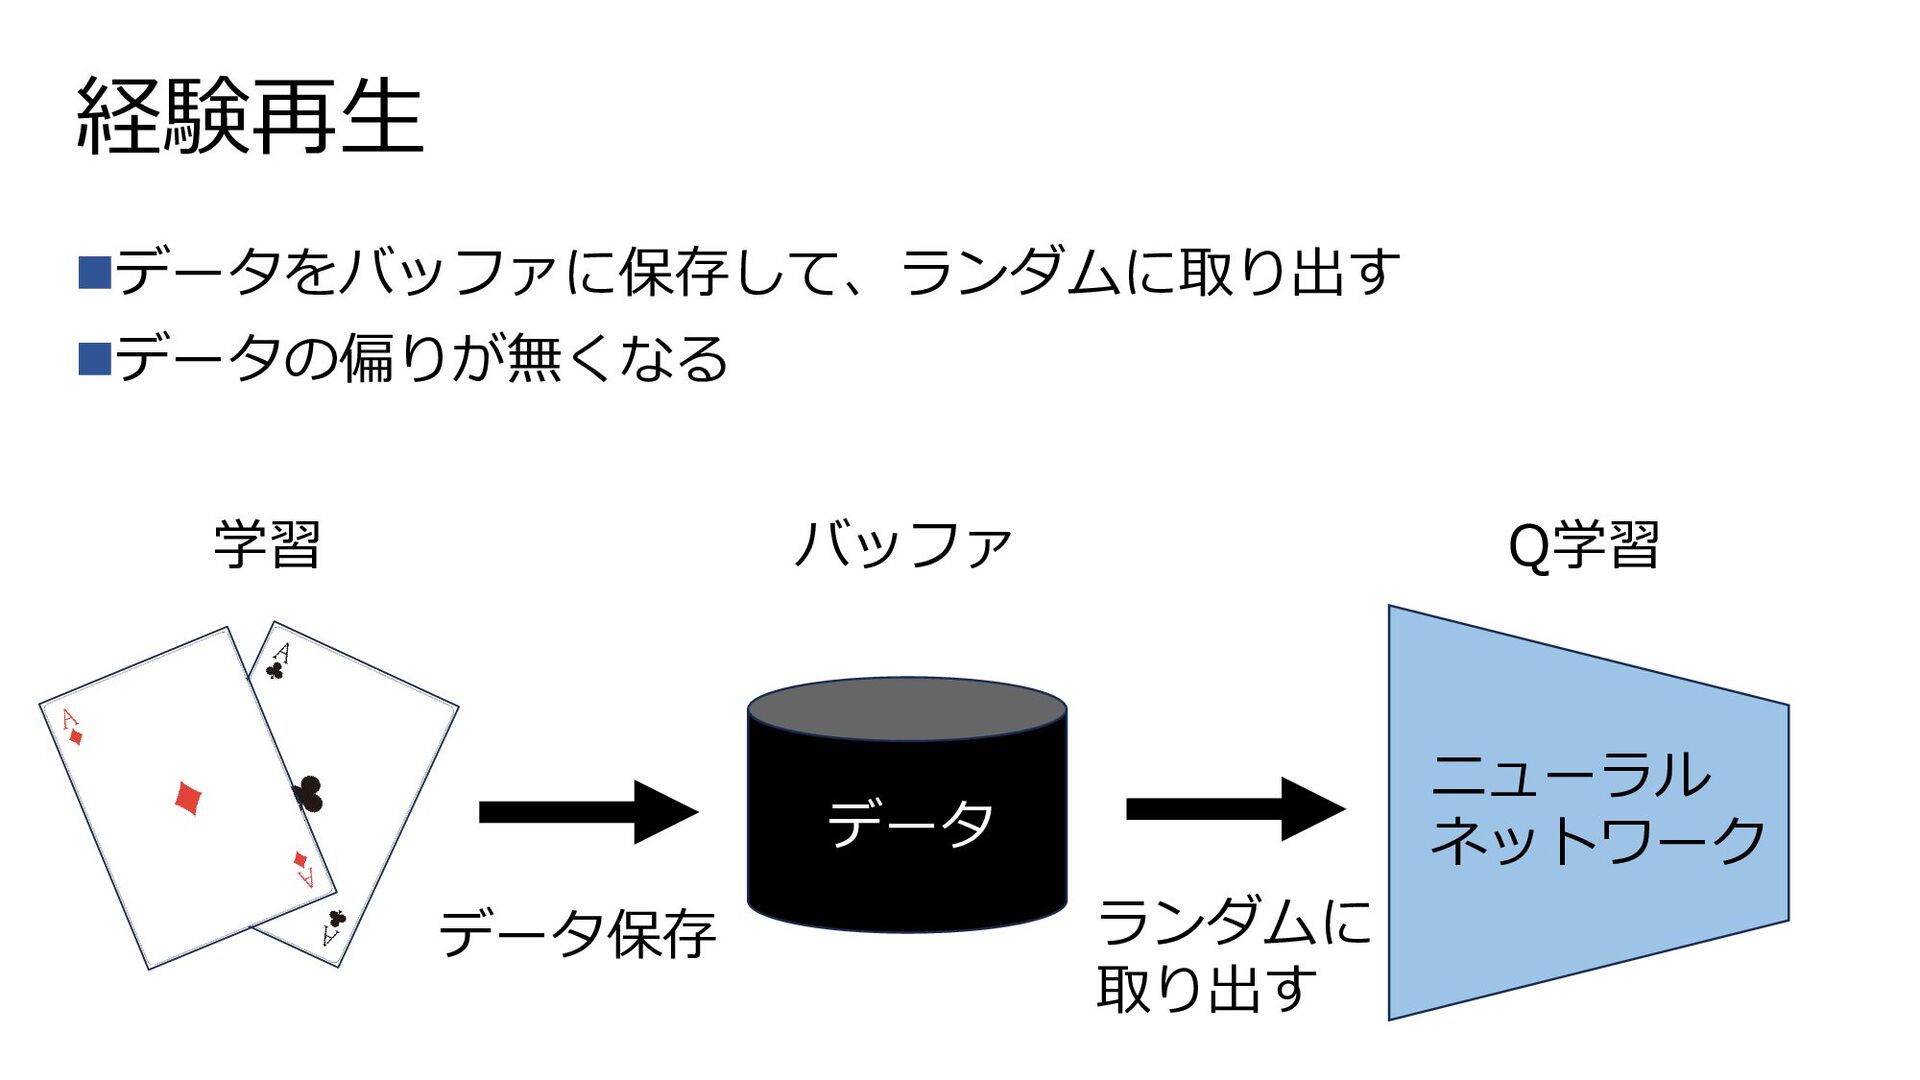
経験再生 データ ニューラル ネットワーク データ保存 Q学習 学習 ランダムに 取り出す ◼データをバッファに保存して、ランダムに取り出す
◼データの偏りが無くなる バッファ
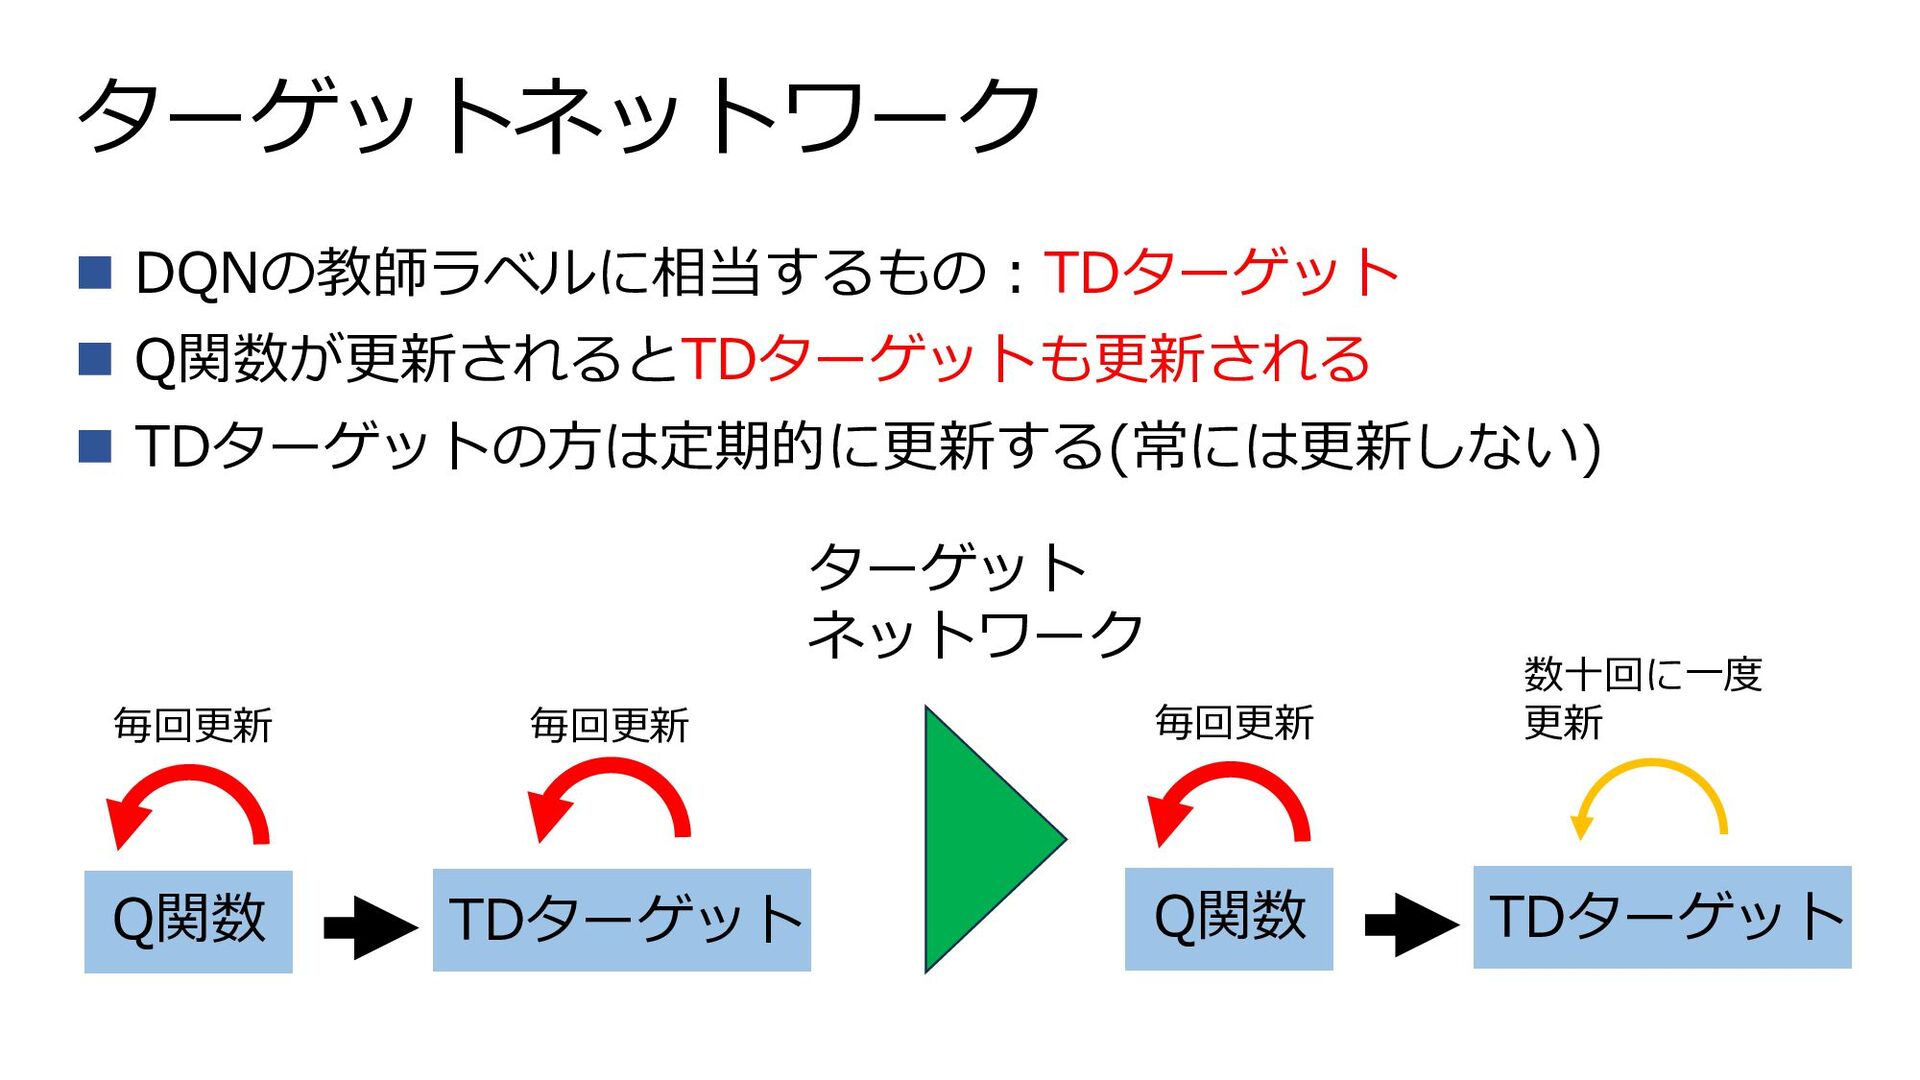
ターゲットネットワーク ◼ DQNの教師ラベルに相当するもの:TDターゲット ◼ Q関数が更新されるとTDターゲットも更新される ◼ TDターゲットの方は定期的に更新する(常には更新しない) Q関数 TDターゲット 毎回更新
毎回更新 ターゲット ネットワーク Q関数 TDターゲット 毎回更新 数十回に一度 更新
テキサスホールデムの学習 ◼ チェスや囲碁などのよく強化学習で扱われるゲームの分類 ⚫ 二人零和有限確定完全情報ゲーム ◼ テキサスホールデムの特徴 ⚫ 確定ではない(トランプのカードはランダム) ⚫
完全情報ではない(相手の手札は見えない)
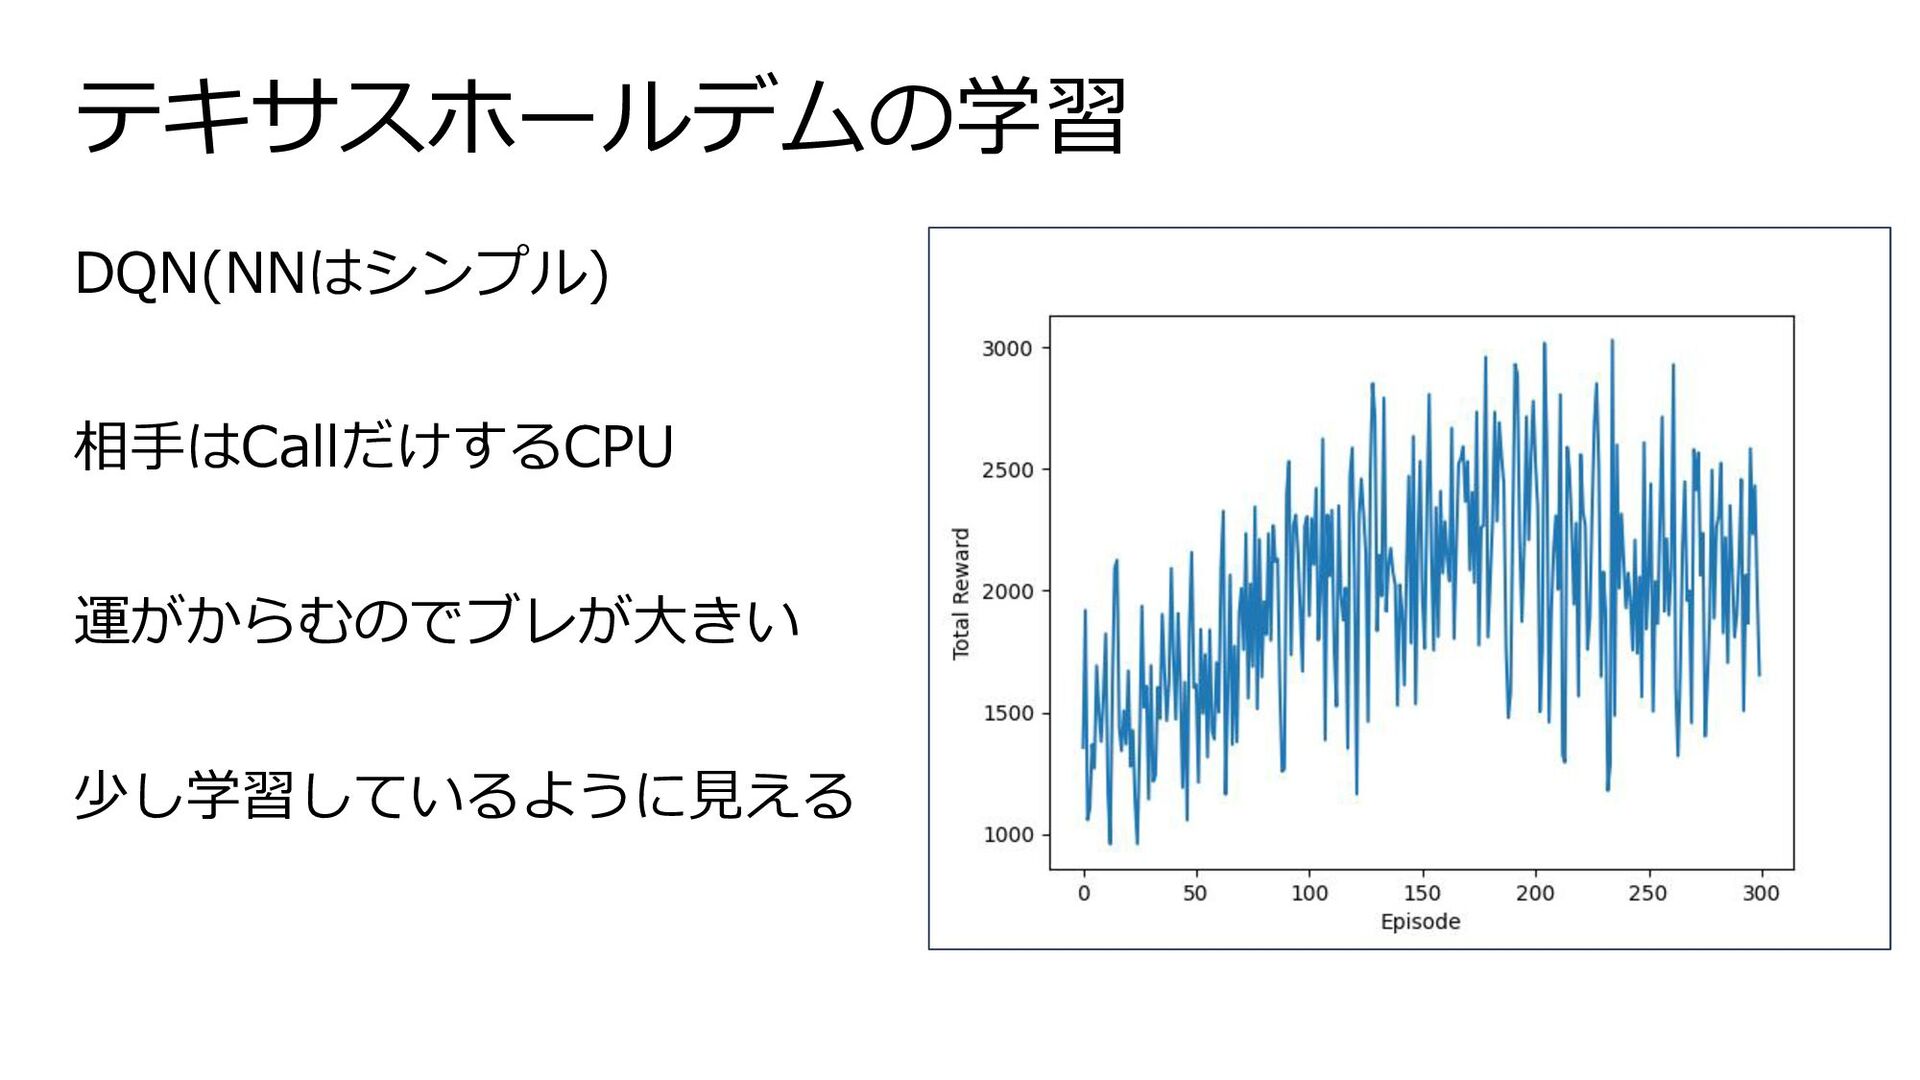
テキサスホールデムの学習 DQN(NNはシンプル) 相手はCallだけするCPU 運がからむのでブレが大きい 少し学習しているように見える
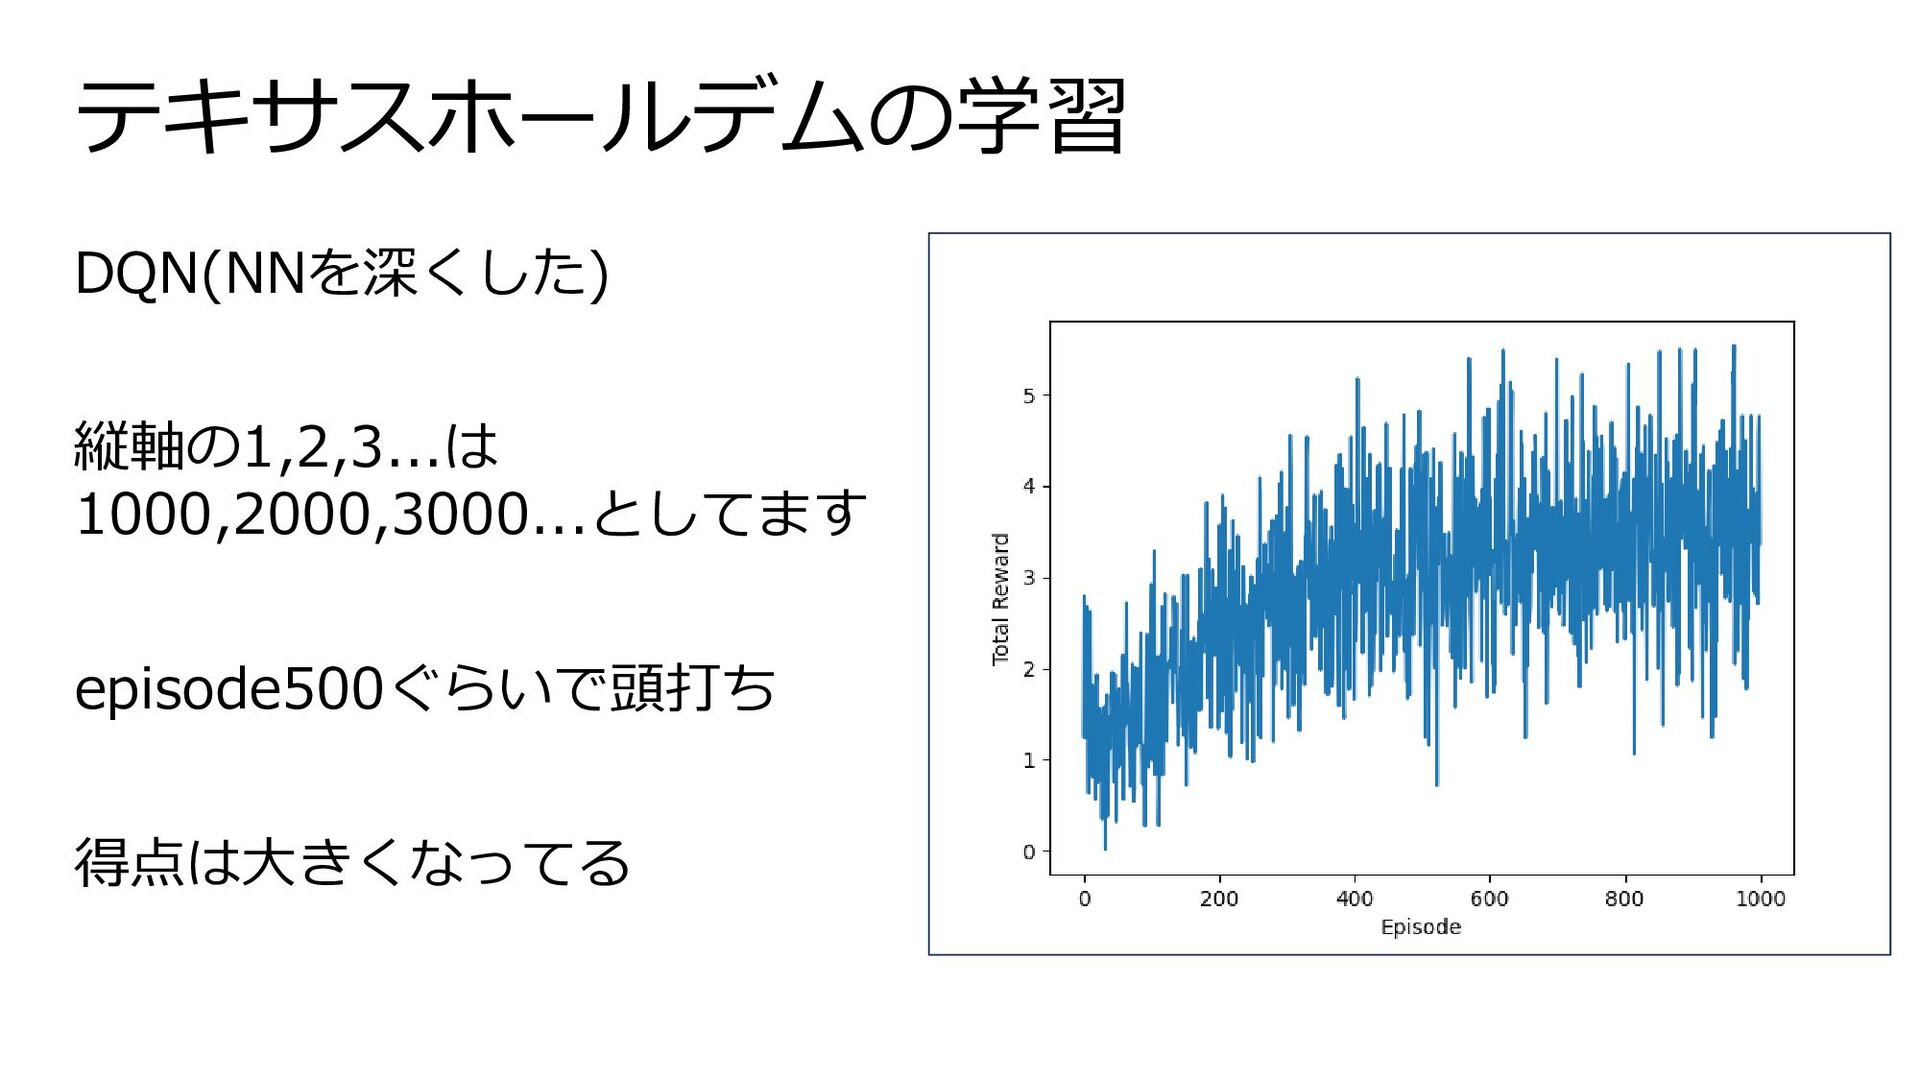
テキサスホールデムの学習 DQN(NNを深くした) 縦軸の1,2,3...は 1000,2000,3000...としてます episode500ぐらいで頭打ち 得点は大きくなってる
まとめ ◼ DQNは強化学習の一種 ◼ テキサスホールデムのような不確定かつ不完全なゲームでも学習は できる

 Your Podcast. Everywhere. Effortlessly.


 tasotaku
 lara
 cassininazir
 szymonslowik
 garrettdimon
 samlambert
 livdayseo
 tammyeverts
 greggifford
 helenjbeal
 cargoodrich
 ipullrank